
A controlled release of coding agents: squid-bot starts agents only as the host, CI and budget can take them, screens every change they make, and merges only verified ones into main, so a repository gets a steady, rolling stream of small improvements that never has to stop.



On GitGalaxy, the repository it runs on, squid-bot has largely automated the production of code. The owner's job is to set goals: an ordered list of issue sets for the fleet to work through. From there the loop runs on its own, around the clock:
- Release agents as resources allow. Every 10 minutes a cheap gate checks the host (CPU, memory and disk pressure), the CI queue, the spend budget, usage limits and connectivity. It starts a new agent only into free capacity, and stops starting them when any of those signals says so.
- Edit in isolation. Each agent works one slice of an issue in its own git worktree and opens a draft PR.
- Screen, then merge. Cheap checks first, the full CI suite after. A failure is classified (real defect, infra noise, flake, broken
main, conflict) and sent back with the exact local repro; only a green PR is squash-merged. - Keep rolling. Finished slices free their slots, the queue refills from the goals, and the next agents start. When only a human can decide something, the question goes to the owner's phone and the fleet carries on with other work.
The aim is a perpetual cycle: no batch to start, no run to finish, just as much verified improvement per day as the machine, the CI pool and the budget allow.
The system itself is still being tuned. The owner adjusts the rules (PR size caps, pacing, retry limits, which goal comes first) and watches the dashboards below to see whether each change helped.
PRs are deliberately small, so PR counts overstate the work. Agents are told to slice an issue into small PRs, touching at most 5 hand-written files each, because small PRs pass review and CI far more often (see the quality chart below). The cost is that one issue usually becomes several PRs. From Oct 19 to Oct 25, promoter-bot merged 926 PRs while closing 193 work items: about 4.8 PRs per item. Read the merged-PR line on the dashboard as throughput of verified changes, not issues solved; the Issues and Cost-per-resolved-issue panels are the better measures of outcome.
The fleet isn't free to run. Since promoter-bot went live on Oct 11, CI runner hours per day and job queue wait have both risen sharply, main goes red a few times a day (each one caught and fixed, but counted), and the agents cost about $2,700 in their first two weeks (about $2 per merged PR, about $11 per resolved issue). All of these are on the dashboard rather than left out of it.
Some things aren't measured yet: the owner's time saved (the real point of the system), host pressure over time, and rework after merge.
Live numbers from the GitHub API for GitGalaxy, refreshed three times a day. Raw data: metrics.json and the fleet's own factory.json.
It's made by this repo's Fleet CI report action. The cards on top show the last finished UTC day against the day before it. Below them, twelve panels run over time, with lines where integrase-bot (Oct 10) and promoter-bot (Oct 11) went live:
| Panel | What it shows | |
|---|---|---|
| 1 | Delivery | Merged PRs per day, by origin (promoter-bot, other agents, people, automation) |
| 2 | CI hours | Runner hours per day |
| 3 | Speed | Job queue wait, p90 |
| 4 | CI load | Runner hours per merged PR |
| 5 | Spend | promoter-bot's dollars, cumulative |
| 6 | Cost per PR | Dollars per merged promoter-bot PR, each day |
| 7 | Efficiency | Run minutes saved by early cancellation vs runs failed |
| 8 | Issues | Opened and closed each day, by who |
| 9 | First-pass rate | promoter-bot PRs merged with no send-back or fix |
| 10 | Change failure | Times main went red, per merged PR |
| 11 | Cost per resolved issue | promoter-bot dollars per issue it resolved |
| 12 | GitHub writes | Busiest hour per account, against the API limit |
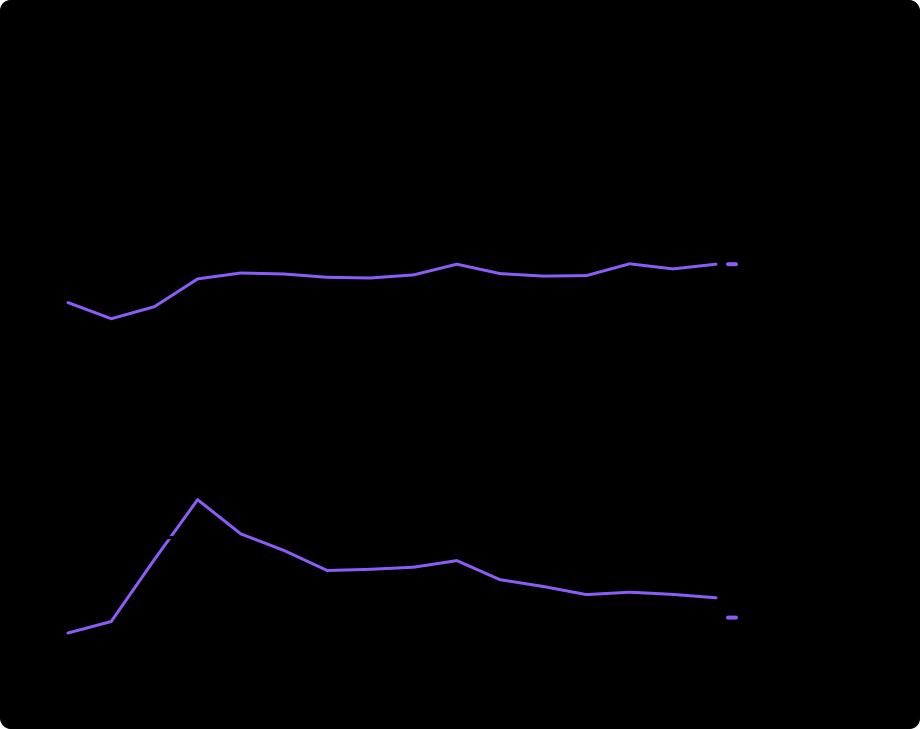
This is the evidence behind the small-PR rule, and we have only just started tracking it (from Oct 10). For every merged promoter-bot PR, the fleet records how many hand-written files it changed and whether it needed a fix before merging: a review send-back or a CI fix run. When it did, a model reads the fix run's own report and labels what broke. So far:
| Hand-written files changed | Merged PRs | Needed a fix |
|---|---|---|
| 1-2 | 113 | 21% |
| 3-4 | 110 | 22% |
| 5 | 37 | 49% |
| 6+ | 18 | 44% |
Up to 4 files, about one PR in five needs a fix; at 5 or more, about half do. The most common causes are a derived file not refreshed (stale), a conflict with main, and main itself being red or flaky. The chart covers every orchestrator host and gains a point each day: each point is the 7 days ending on it, and a size line is drawn only where those 7 days have 5 PRs or more. The tiles score the last 7 days against the 7 before. The 5-file cap stays until the 5+ line comes down to the 3-4 line. The data is in factory.json's quality field.
Left unmanaged, coding agents behave like a plague of grasshoppers: five started at once will take every core, run the box out of memory, back the CI queue up for hours, and time their own tests out. Keeping them inside the host's carrying capacity is half the job. The other half is that a coding fleet is not a swarm competing for grass: many agents are making heritable changes to one shared genome, origin/main, which every future branch inherits.
That is gene editing, and the way labs do it safely is a good model for doing it with agents. In an ex vivo therapy (the way CAR-T cells are made), cells are taken out of the patient, edited in a dish, screened, and only verified cells are returned. squid-bot does the same with code: each issue is a known defect, each agent edits an isolated copy of the genome, CI screens the edited copy, and only a verified edit is integrated into main.
┌──────────────────────────────────────────────────────────────────────────────┐
│                       THE GENOME (origin/main)                               │
│   Known defects to correct and traits to add: the issue backlog              │
│      #4893 loss-of-function bug   ·   #5166 knock-in: new feature            │
└──────────────────────────────────────┬───────────────────────────────────────┘
                                       │
            1. Initiation: promoter-bot switches editing on or off
               • box-status: editor toxicity / host capacity (GREEN/YELLOW/RED)
               • usage limits, connectivity, owner holds: when and how many
               • comms-bot: the owner's sign-off, asked and answered by phone
                                       │
┌──────────────────────────────────────▼───────────────────────────────────────┐
│          THE EDITORS (Claude Code / Gemini / Cursor), one per culture        │
│                                                                              │
│   Each edits an isolated worktree (a cell culture, not the patient) and      │
│   produces an edited clone: a branch + draft PR, sharing cores via           │
│   heavy-run.sh                                                               │
└──────────────────────────────────────┬───────────────────────────────────────┘
                                       │
            2. Screening: is this clone correct, and did it break anything?
               • draft PR: cheap genotyping first, full CI only after
               • ci_digest: genotype a failed clone (real defect vs noise)
                                       │
┌──────────────────────────────────────▼───────────────────────────────────────┐
│            INTEGRATION: integrase-bot (Verified Squash Merge)                │
│                                                                              │
│   Only a screened, green clone is integrated into origin/main. Memory of     │
│   past failures is kept for the next editors (handoffs, lessons-inbox)       │
└──────────────────────────────────────────────────────────────────────────────┘
| Gene editing | squid-bot | What it does |
|---|---|---|
| The genome | origin/main |
The canonical sequence that every future branch inherits. Changes here are heritable. |
| A known defect, or a trait to add | An issue | A bug is a loss-of-function mutation to correct; a feature is a knock-in of a new trait. |
| Inducible promoter driving the editor (Tet-On style: edit only when the signal is present) | promoter-bot | Decides which edits start, when, and how many at once; switches editing off on host stress, usage limits or lost connectivity. |
| Editor toxicity (too much Cas9 kills the cell) | box-status |
Senses host pressure (/proc/pressure/cpu, memory, io) and holds new work before the host collapses. |
| The editor (Cas9 plus its guide RNA) | A coding agent with its brief | The brief is the guide: where to cut and what the corrected sequence should be. |
| Editing in a dish, not in the patient | A git worktree | Every edit happens in an isolated copy; main is never edited directly. |
| Sharing the incubator | heavy-run.sh |
Gives each heavy job a fair share of the cores when it starts. |
| The repair template; HDR vs NHEJ | The PR's diff | A precise, template-guided fix (HDR) versus a quick patch that leaves side effects (NHEJ "indels"). |
| Screening clones; off-target sequencing | CI: draft checks, then the full suite | Does the edit fix the defect, and did it break anything elsewhere (off-target effects = regressions)? |
| Genotyping a failed clone | ci_digest |
Classifies a failure (real / infra / flake / main / dirty) and hands the editor the exact local repro. |
| Integrase (writes a verified sequence into the genome) | integrase-bot (formerly the shepherd) | Merges a green PR into main; holds, reruns and flags the rest. Also: it does Continuous Integration. |
| The physician's sign-off (the clinician who ordered the therapy decides what the lab can't) | comms-bot | Takes the fleet's questions to the owner's phone in plain language, brings the decisions back, and sends a daily lab report. Uses no model tokens. |
| Discarding a failed clone | Closing a broken PR | An edit that cannot be verified never reaches the genome. |
| Two edits at the same locus | Merge conflicts | Caught as dirty and sent back for a rebuild against the current genome. |
| The CRISPR array (bacteria store spacers from past infections to recognise them again) | Handoffs, lessons-inbox.md, the integrase ledger & flake-history |
Memory of past failures carried to the next generation of editors. |
| Host resource | Unregulated editor swarm | With squid-bot |
|---|---|---|
| CPU cores & threads | Every agent spawns nproc workers; load spikes to 60+; clock starvation triggers false regex/test timeouts. |
heavy-run.sh gives each heavy job a fair share of cores (online_cores / active_heavy_slots). |
| Memory & swap | Concurrent AST parsers, JVMs, and containers exhaust RAM; the OOM killer terminates active agent sessions. | box-status senses /proc/pressure/memory stall and holds heavy work (YELLOW / RED). |
| CI runner minutes | Agents push speculative commits to test hypotheses on GitHub Actions, exhausting runner queues. | Draft screening plus ci_digest's local repro: fix locally, push once. |
The shared genome (main) |
Upstream merges invalidate in-flight branches; agents enter rebase loops or chase main failures. |
integrase-bot serializes integration into main and marks shepherd:waiting-on-main while main itself is red. |
flowchart TD
    subgraph INIT["1. Initiation (promoter-bot)"]
        PB["promoter-bot\n(Inducible Promoter: what, when, how many)"]
        BS["box-status\n(Editor-Toxicity Sensor: PSI)"]
        LK["exclusive-lock.sh\n(One Culture per Shared Resource)"]
    end

    subgraph EDIT["2. Editing (isolated worktrees)"]
        A1["Agent 1\n(Worktree A)"]
        A2["Agent 2\n(Worktree B)"]
        A3["Agent 3\n(Worktree C)"]
        HR["heavy-run.sh\n(Fair Core Share)"]
    end

    subgraph SCREEN["3. Screening & Integration (integrase-bot)"]
        GH["shepherd_gh\n(Reads the True PR State)"]
        INT["integrase-bot daemon\n(Release Drafts, Integrate When Green)"]
        DIG["ci_digest\n(Genotype the Failed Clone)"]
    end

    subgraph MEM["4. Memory (the CRISPR array)"]
        HO["handoff-*.md, lessons-inbox,\nledger, flake-history"]
    end

    subgraph SIGN["5. Sign-off (comms-bot)"]
        CB["comms-bot\n(Questions Out, Decisions In)"]
        OWN["Owner's Phone\n(Private Channel)"]
    end

    BS -->|"GREEN / YELLOW / RED"| PB
    PB -->|"Start an Edit"| EDIT
    EDIT -->|"Heavy Jobs"| HR
    EDIT -->|"Edited Clone\n(Draft PR)"| GH
    GH -->|"Release Draft;\nIntegrate When Green"| INT
    GH -->|"Check Failed"| DIG
    DIG -->|"Exact Local Repro"| EDIT
    EDIT -.->|"Session Ends /\nHandoff"| HO
    PB -->|"Owner Question"| CB
    CB <-->|"Buttons / Replies"| OWN
    CB -->|"Owner Decision"| PB
CLI command: box-status
A cell doesn't guess its energy by counting enzymes; it senses actual stall (such as the AMP/ATP ratio). Likewise, instead of crude CPU percentages (which spike deceivingly during brief bursts), box-status reads Linux Pressure Stall Information (PSI) from /proc/pressure/cpu, /proc/pressure/memory, and /proc/pressure/io.
$ box-status
GREEN: headroom
cores 12  load 2.4 / 3.0 / 3.4  cpu-pressure 0.02%  mem-pressure 0.09%
memory available 24.3 / 30.4 GB  swap used 4.9 GB
heavy slots 0/3 held  free for new heavy work: 3
busiest (cores in use, by worktree or command):
   0.08  find
   0.05  agy
disk: io-pressure 1.79% (full 1.57%) tasks blocked on disk 0-
GREEN(editing on): pressure is negligible and heavy slots are open. Agents may start heavy verification sweeps, Docker containers, or parallel gauntlets. -
YELLOW(light work only): heavy slots are occupied, available memory is under 20%, or load exceeds 70% of the core count. Agents down-shift to scouting, narrow unit tests, or code edits. -
RED(editing off): CPU stall pressure$\ge 40%$ , available memory$< 10%$ , or the box is paging. Orchestrators start nothing new and ask active workers to write a handoff checkpoint.
Usage: scripts/heavy-run.sh <command...>
Several cultures share one incubator; none may take all of it. heavy-run.sh sizes compute-intensive builds and test suites once, when each job starts:
- It acquires one of
$N$ shared slots ($N = \text{cores} / 4$ , minimum 1) via kernelflock. - It counts how many other heavy jobs are running.
- It calculates a fair core share for that moment:
$$\text{SQUID_BOT_CORES} = \max\left(1, \frac{\text{online_cores}}{\text{active_heavy_slots}}\right)$$ - It exports
SQUID_BOT_CORESandGG_JOB_CORES, which downstream tools (pytest-xdist, compiler jobs, linters) read to size their internal worker pools.
The share is not revised while the job runs: a job that starts alone gets every core, and jobs started after it get smaller shares, so a staggered start can briefly ask for more cores than exist (about 1.8x with 3 slots). The slot count still caps how many heavy jobs run at once.
Status: runs on GitGalaxy today (formerly churn). Source: squid-protocol/promoter-bot; not yet packaged in this repo.
promoter-bot decides which issues get worked, when, and how many at once, and launches the agents that work them. It runs as a cheap gate every 10 minutes and starts a model session only when something needs judgment:
- Signals that switch editing off:
box-statusRED, a usage limit (paused until its reset, weekly resets included), lost connectivity (workers that died offline are requeued), a run of failing workers, or a stop file. - Dose: at most
max_workersagents at once, only into free heavy slots. - Goals: the owner's ordered list of issue sets. The active goal's issues launch first and lead every refill; later goals follow, then everything else.
- Targets: a tiered queue that refills itself from labelled issues.
- Slicing: a worker takes one slice of an issue, capped at 5 hand-written files, so an issue usually lands as several small PRs. A checklist item that keeps merging partial slices is requeued to be split first.
- Housekeeping and alerts: removes finished worktrees, reaps stale containers, keeps a daily scorecard, and sends phone alerts when it needs a human (through comms-bot's private ntfy server).
CLI command: integrase-bot run --every 600 (also available as squid-bot run and shepherd)
Cellular regulation runs on state equilibrium, not fragile one-shot events. Likewise, GitHub webhook events drop under burst traffic, arrive out of order, or get canceled by concurrency groups, so integrase-bot reconciles the true GitHub state directly on every pass. Its PR labels keep their original shepherd: names:
-
Screen cheaply first (Draft → Ready): agents open PRs as drafts so only cheap, fast checks run. Once those pass, integrase-bot marks the PR ready to trigger the full CI suite, and merges it on a later pass once that suite is green; it never merges a draft in the same step, because a draft's skipped heavy checks read as green. At most
CI_SHEPHERD_MAX_IN_FLIGHT(default 4) drafts are released per pass, so a burst of drafts doesn't flood the CI runners. -
Integrate (
shepherd:merge): the moment all required checks pass and the branch is clean, integrase-bot squash-merges the edit intomain. -
No chasing
main: a PR that is merely behindmainis never updated just to stay current: every push restarts its CI. Leave branch protection's "require branches to be up to date" off and letmain's own CI catch the rare semantic conflict; with it on, a green-but-behind PR waits for a human. -
Reruns for noise:
infrafailures are rerun up to 3 times, 15 minutes apart, andflakefailures once. The budget belongs to the workflow run, not the check: the failing legs of one matrix run share a singlegh run rerun --failed. -
Fixer gating: with
CI_SHEPHERD_FIXERset, arealfailure starts that command (<fixer> <PR> <digest.json>) to repair it. The digest comment posts at once, but the fixer starts only whenbox-statusreadsGREEN, at mostCI_SHEPHERD_MAX_FIXERS(default 1) per pass, and the most useful first: the PR that others wait on (--after), then the one with the fewest failing checks. -
Hold (
shepherd:hold): keeps a PR open for human inspection without merging. -
Full matrix (
shepherd:matrix): runs the full cross-platform OS$\times$ Python suite and gates integration on a clean run. -
Damaged reference (
shepherd:waiting-on-main): applied when a failing check is confirmed to also be failing onorigin/main, so agents don't mutate their own edit to fix a broken genome. -
Needs a fix (
shepherd:needs-fix): applied when a real regression or conflict (dirty) is detected, paired with a structuredci_digestreport.
CLI command: ci-digest <PR_NUMBER>
When CI fails on a PR, dumping 10,000 lines of raw GitHub Actions logs into an agent's context window is toxic. ci_digest genotypes the failed clone instead: it scans the failure, filters out environmental noise, classifies it, and emits the exact local reproduction:
$ ci-digest 4976
#4976 HEAD 5b7f5c5e
  check: full-suite part 3/3 (failure)
  triage: real (code failure)
  failed tests:
    tests/core/test_parser.py::test_utf8_bom_handling
  error:
    AssertionError: assert 'expected' == 'actual'
  local repro:
python -m pytest tests/core/test_parser.py -k test_utf8_bom_handlinginfra: environmental noise (runner disconnects, Docker Hub 429/504s). integrase-bot reruns these up to 3 times, 15 minutes apart.flake: a known timing-sensitive test: listed inFLAKY, or the first attempt of a check thatflake-historylearned is flaky. Retried once automatically; if it fails again it isreal.main: the failure is in the reference genome (origin/main), not the edit. Triggersshepherd:waiting-on-main. Whilemain's newest commit is still running a check, the last finished result of that check onmain(up to 3 commits back) is used, so a PR is not blamed for a failure it inherited in the minutes after a merge.dirty: two edits at the same locus (a merge conflict withmain). Signals the agent to mergeorigin/mainand regenerate derived artifacts.real: a true defect in the edit. Outputs the exact local reproduction command so the agent fixes and verifies locally before pushing once.
CLI command: flake-history [--json] [--file-issues]
GitHub already records the evidence: a rerun workflow run has run_attempt > 1, and its jobs from every attempt are listed. flake-history finds the jobs that failed and then passed on a rerun of the same run over the last 14 days. A job that passed on a rerun at least twice, with at least 80% of its reruns passing, is learned flaky (on GitGalaxy's first 14 days: the four Db2 shards and Muninn, not the broad det and full-suite jobs, whose reruns pass only because a timing flake sits in one of their thousands of tests). In GitGalaxy each job also carries why its first attempt failed, from ci_rerun_stats.py's classifier. integrase-bot refreshes that cache in the background every 6 hours and treats such a check's first failure as a flake. --file-issues opens one cleanup issue per learned-flaky job (once).
CRISPR began as a bacterial immune memory: a cell stores a short spacer from each past infection so it recognises the same invader next time. Coding agents need the same, because sessions end on context compaction, usage limits and preemptions.
squid-bot keeps that memory in structured markdown handoffs (handoff-*.md) and lessons-inbox.md:
- Before a session ends, an agent records its active worktrees, running background PIDs, the verification level reached, and open blockers.
- The next agent picks up that worktree where it stopped, without re-running expensive proofs.
- Lessons learned during a run go to
lessons-inbox.mdand are promoted into permanent agent rules, so the fleet stops repeating a mistake it has already made.
Status: runs privately on GitGalaxy today (added 2026-10-17); not yet packaged in this repo.
In a cell therapy, the lab does the editing, but some calls belong to the physician who ordered it: release this batch, retry that culture, stop. A fleet has the same kind of calls (retry a PR the agents have failed to fix four times today, release a held PR, make a ruling only the owner can make), and until comms-bot its only way to reach the owner was a log nobody was reading. On the day it shipped, the scorecard counted 24 idle ticks, about 2.9 hours with free slots and nothing to launch, all of them waiting on owner decisions.
comms-bot is a two-way channel between the fleet and the owner's phone that uses no model tokens:
- Private by construction: a self-hosted ntfy server reachable only over a private VPN, with no anonymous access. Only the owner's account can post commands and only the box's account can post alerts, so every command is the owner's.
- Plain-language questions: the model that parks an item writes the question at that moment, in a fixed private format (question, context, and what each button will do). Calls the gate makes on its own (for example, the fix-retry cap) get fixed templates, filled in with the PR and issue titles.
- Buttons that mean something: each question comes with buttons that fit it ("Try again / Drop / Pause"). The answer is recorded with exactly what the button promised, and a tick is woken two minutes after the last tap to apply it, so a burst of answers costs one tick.
- Commands and a daily report:
status,owner,pause,resumeandworkers Nfrom the phone, plus a morning digest with merges, spend, evidence levels and crucible cells, and what changed since the last one. - Nothing sensitive on GitHub: a public repo only ever gets a neutral "waiting on an owner decision" / "the owner decided" note; the question itself stays private.
- Linux (with
/procPSI support recommended for admission control). - Python 3.10 or higher.
- GitHub CLI (
gh) authenticated with repository access.
git clone https://github.com/squid-protocol/squid-bot.git
cd squid-bot
pip install -e .Create a squid-bot.toml in your repository root (the section is still named [shepherd]):
[repository]
slug = "owner/repo"

[shepherd]
# Required CI checks before integrase-bot merges a PR labelled shepherd:merge
required_checks = [
    "test",
    "lint",
    "type-check"
]
poll_interval_seconds = 600
state_path = "/tmp/squid-bot/state/shepherd.json"

[supervisor]
lock_dir = "/tmp/squid-bot/locks"
heavy_slots = 3box-status
# Output: GREEN: headroom (cores: 12, load: 2.1, free heavy slots: 3)scripts/heavy-run.sh pytest tests/nohup integrase-bot run --every 600 >> /tmp/squid-bot/shepherd.log 2>&1 &
integrase-bot status # the queue, plus the ledger's most recent events| Environment variable | Default | Effect |
|---|---|---|
CI_SHEPHERD_FIXER |
unset | Command started for a real failure: <fixer> <PR> <digest.json> |
CI_SHEPHERD_MAX_FIXERS |
1 |
Fixers started per pass (only while box-status is GREEN) |
CI_SHEPHERD_MAX_IN_FLIGHT |
4 |
Drafts marked ready per pass |
squid-bot was forged inside GitGalaxy, where it regulates multi-agent editing (4,800+ merged pull requests as of Oct 26, 2026).
To allow continuous evolution inside GitGalaxy while maintaining a clean, generalized open-source package, squid-bot includes a bi-directional sync bridge (scripts/sync.py):
# Check drift between GitGalaxy and squid-bot
python scripts/sync.py status
python scripts/sync.py diff

# Pull recent improvements from GitGalaxy into squid-bot
python scripts/sync.py pull

# Push generalized fixes from squid-bot back to GitGalaxy (see the warning below)
python scripts/sync.py push
The bridge translates paths, abstracts repository slugs, maps package imports, updates lock variables, and adapts test suites. pull is safe. push is not a clean reverse: it writes squid-bot's generalizations into GitGalaxy as well, including the default lock directory, which would split GitGalaxy's heavy-job slots between old and new agents. To move a change into GitGalaxy, git format-patch the commit, rewrite its paths (src/squid_bot/X → tests/tools/[box/]X, tests/test_X → tests/tools/test_X) and git apply it in a fresh GitGalaxy worktree.
A: Because the hard part isn't ordering jobs; it's making heritable changes to one shared genome safely. A queue only orders work. squid-bot regulates the whole edit: it starts edits only when the host can take them (promoter-bot, box-status), edits in isolation (worktrees), sizes each heavy job's share of the cores as it starts (heavy-run.sh), screens cheaply before screening expensively (draft PRs), genotypes failures so they are fixed locally (ci_digest), and integrates only verified edits, never while the reference genome itself is broken (integrase-bot). When only a human can decide, it asks the owner in plain language and waits for the answer (comms-bot).
A: CPU percentages only measure how much time the processor spent on tasks, which spikes deceivingly during momentary bursts. PSI measures task stall time: the percentage of time processes were delayed waiting for CPU, memory, or disk. High PSI is a direct measure of a host under stress.
A: No, it solves a different problem. Merge queues assume developers submit tested code, wait for CI, and read logs in a browser. squid-bot is built for autonomous agents: it regulates the host they run on, eliminates token-burning polling loops, and hands agents structured local repro commands instead of raw logs.
A: scripts/kill-by-cwd.sh reclaims processes tied to orphaned worktrees, and exclusive-lock.sh / heavy-run.sh use POSIX kernel file locks (flock) that release the instant a process exits, so nothing deadlocks. The agent's handoff lets the next one resume its worktree.
MIT License. Copyright (c) 2026 Joe Esquibel / Squid Protocol.