
by SQLStack
Change your SQL, see exactly what will rebuild, and replay it from retained stream history.
Website ·
Demo ·
Playground ·
Get started ·
Docs


SQLTide brings dbt-style authoring and deployment to streaming. Models compile into ClickHouse tables and materialized views, every build shows its plan first, and a change to your logic is rebuilt from retained Kafka history.
uv tool install sqltide        # or: pip install sqltide
sqt playground                 # create an orders project and start it with Docker
sqt playground creates a small orders project you run on your own machine with Docker: plan a
change, build it as a candidate beside the live version, then promote it without changing the
consumer's query. Add --template streaming for the same workflow over live order events from
Redpanda. Each project's README.md walks through every command; see the
playground reference.
To look around the development UI before installing anything, open the UI demo: the same UI in your browser on recorded example data, read-only.
- Typed SQL models. Explicit output types,
__source()and__ref()dependencies, and offline compilation with no warehouse connection. - Replay-aware builds. Affected models are reconstructed from retained stream history.
- Plans before changes.
sqt planis read-only, andsqt buildreplans against current warehouse state before it runs. - Staged deployments. Build virtually, then audit, promote, and roll back.
- Quality built in. SQL tests, audits, sensors, and SQLClean rules and formatting.
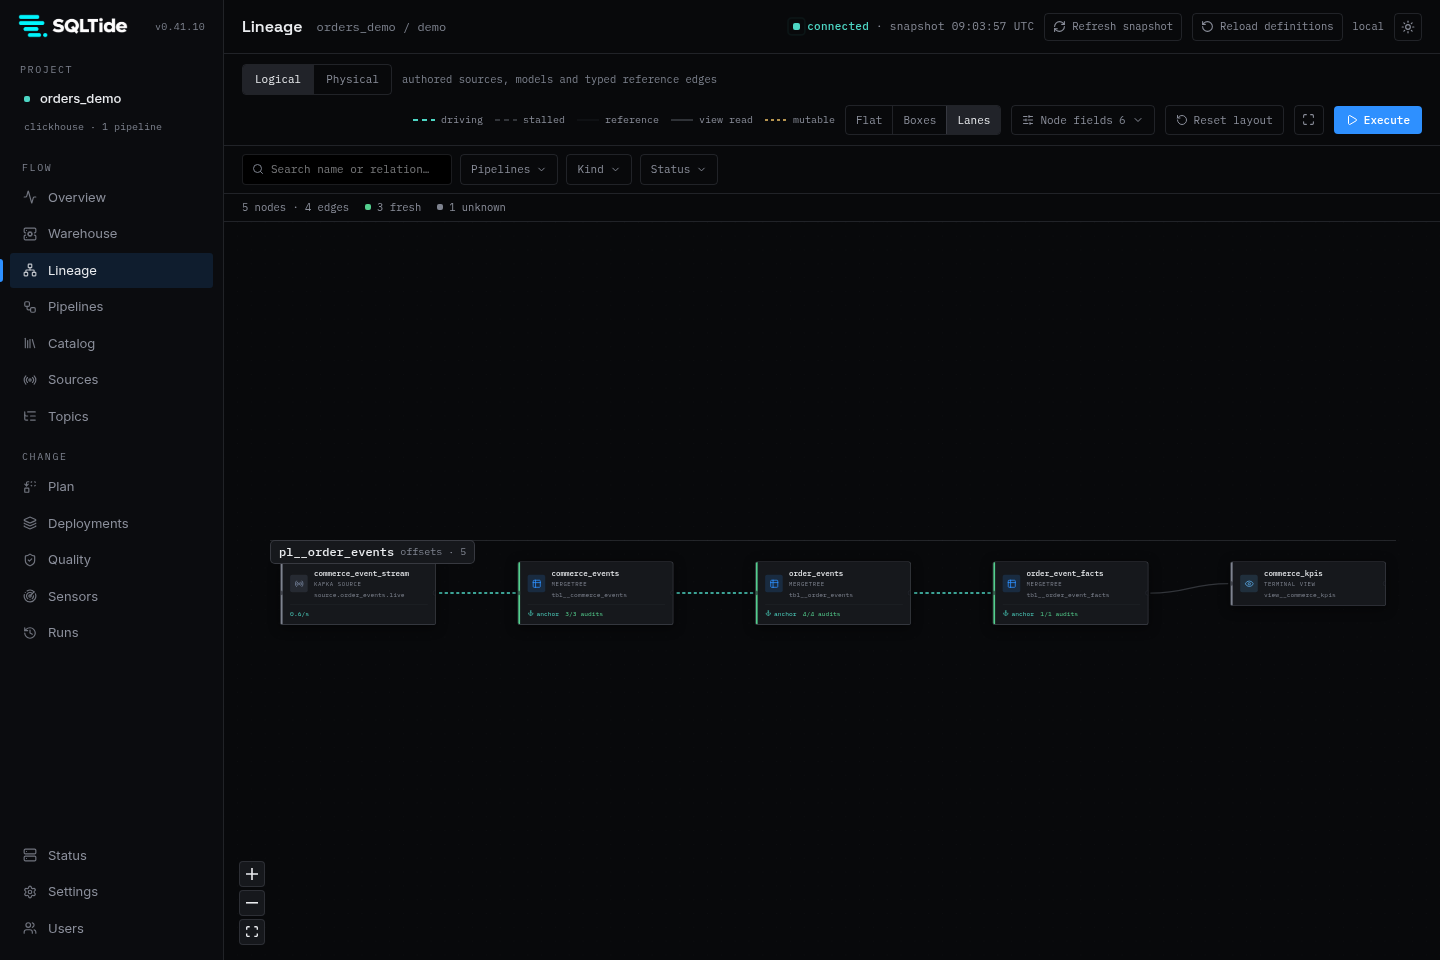
- A UI for operating it. Sources, lag, lineage, plans, runs, and quality in
sqt dev, with trusted-proxy or password authentication for shared installations.
A source and a model:
sources:
  - name: orders
    kind: kafka
    broker_list: kafka:9092
    topic: source.orders
    replay_boundary:
      mode: offsets
MODEL (
engine "MergeTree()",
order_by ["order_id", "_replay_partition", "_replay_offset"],
);
SELECT
order_id::String AS order_id,
_replay_partition::Int32 AS _replay_partition,
_replay_offset::Int64 AS _replay_offset,
_replay_timestamp::DateTime64(3) AS _replay_timestamp
FROM __source("orders")sqt discover # inspect authored resources
sqt compile # validate offline
sqt plan # read-only warehouse plan
sqt build # confirm and execute
sqt test
sqt audit
sqt dev # local UI at 127.0.0.1:8000sqt playground runs this workflow on a ready-made project locally with Docker; the
quickstart walks through it step by step.
- Models and pipelines
- Replay and lineage
- Deployments
- Destructive operations
- Project configuration
- SQL Rules and formatting
- Changelog and contributing
Ask questions and share feedback on Discord.
Apache-2.0