diff --git a/.github/demos/plan-load.gif b/.github/demos/plan-load.gif
index a8b209f61..4accf6009 100644
Binary files a/.github/demos/plan-load.gif and b/.github/demos/plan-load.gif differ
diff --git a/README.md b/README.md
index e2deb5a71..afe427d6e 100644
--- a/README.md
+++ b/README.md
@@ -19,26 +19,29 @@
Benchmarks
-Load Postgres, files, Snowflake, BigQuery, Google Sheets and Python sources into your warehouse.
-SQLLoad is Rust and Arrow end to end, and when your warehouse reads the files itself, rows never
-pass through SQLLoad, so there's no loader bottleneck as your data grows. It's fast, too: faster
-than ingestr and dlt in every [benchmark](https://sqlload.io/docs/benchmarks/) we publish.
+SQLLoad loads databases, files, APIs and Kafka into your warehouse. `sqlload plan` shows every
+table and how it loads before anything moves, and `plan -v` adds each new table's column types and
+the run's memory budget. Decimals keep their precision, a value a column can't hold exactly fails
+its table, naming the column and the value, and each run has one memory budget. Tables with a
+cursor column carry on from the warehouse's own maximum, so there's no state to drift.
```bash
pip install sqlload # or: uv tool install sqlload
```
- 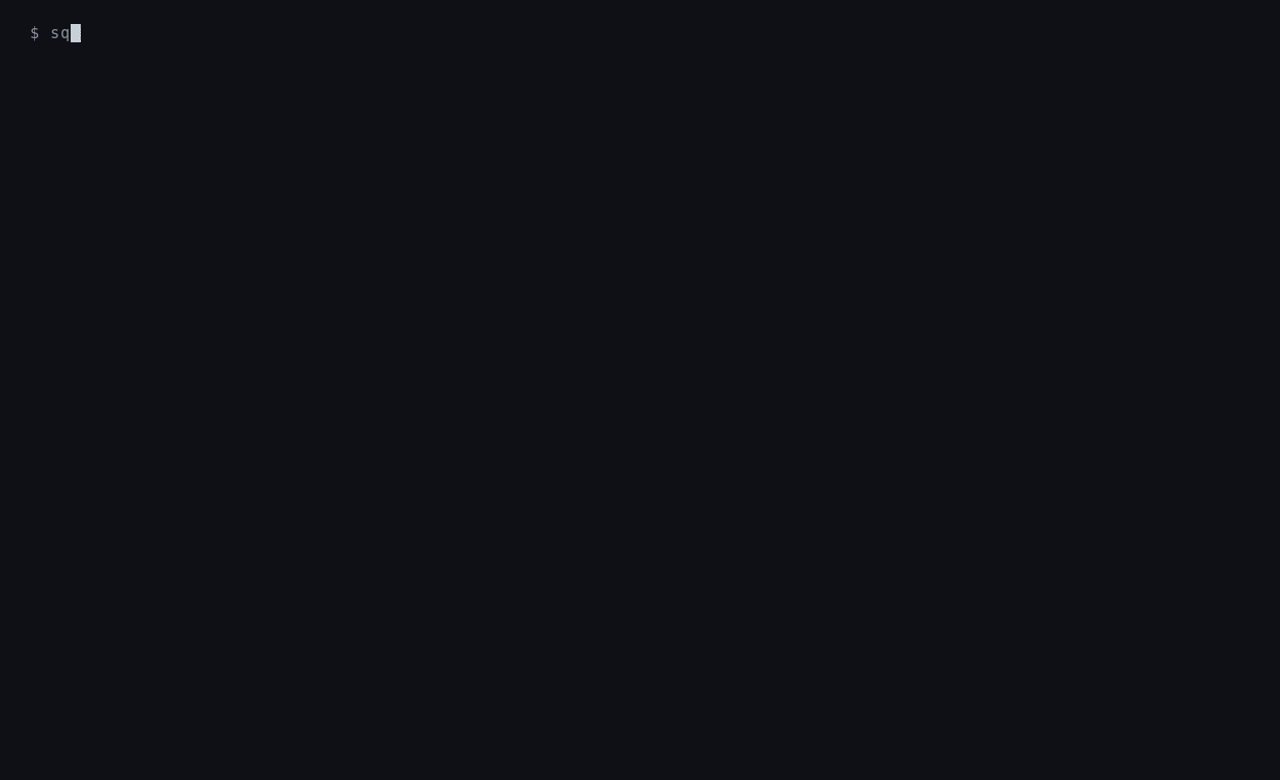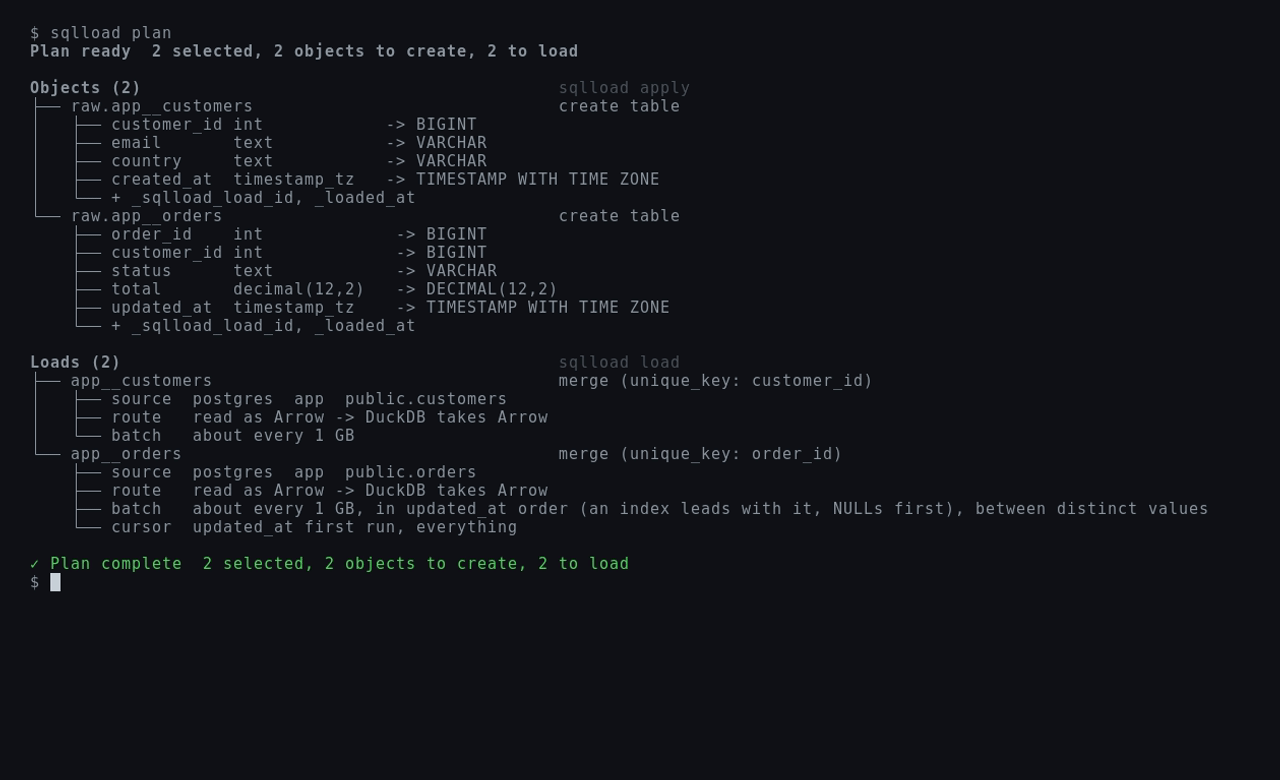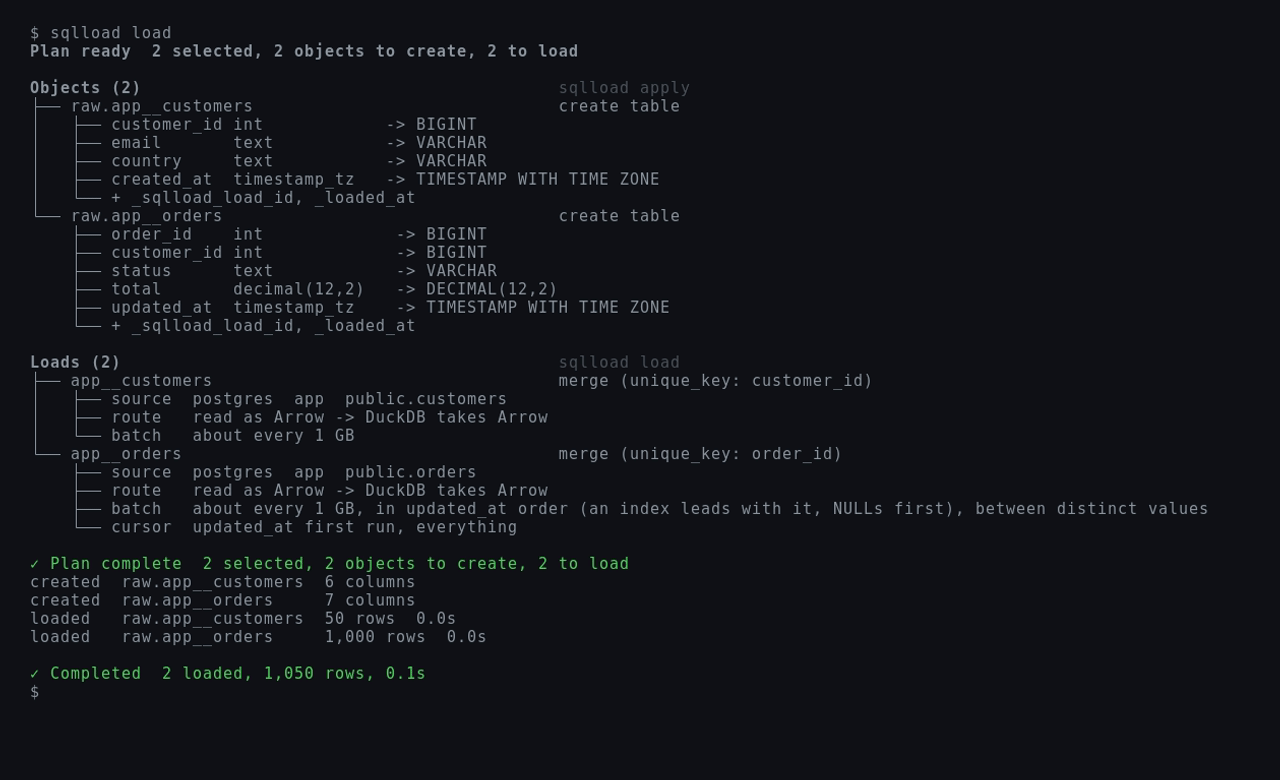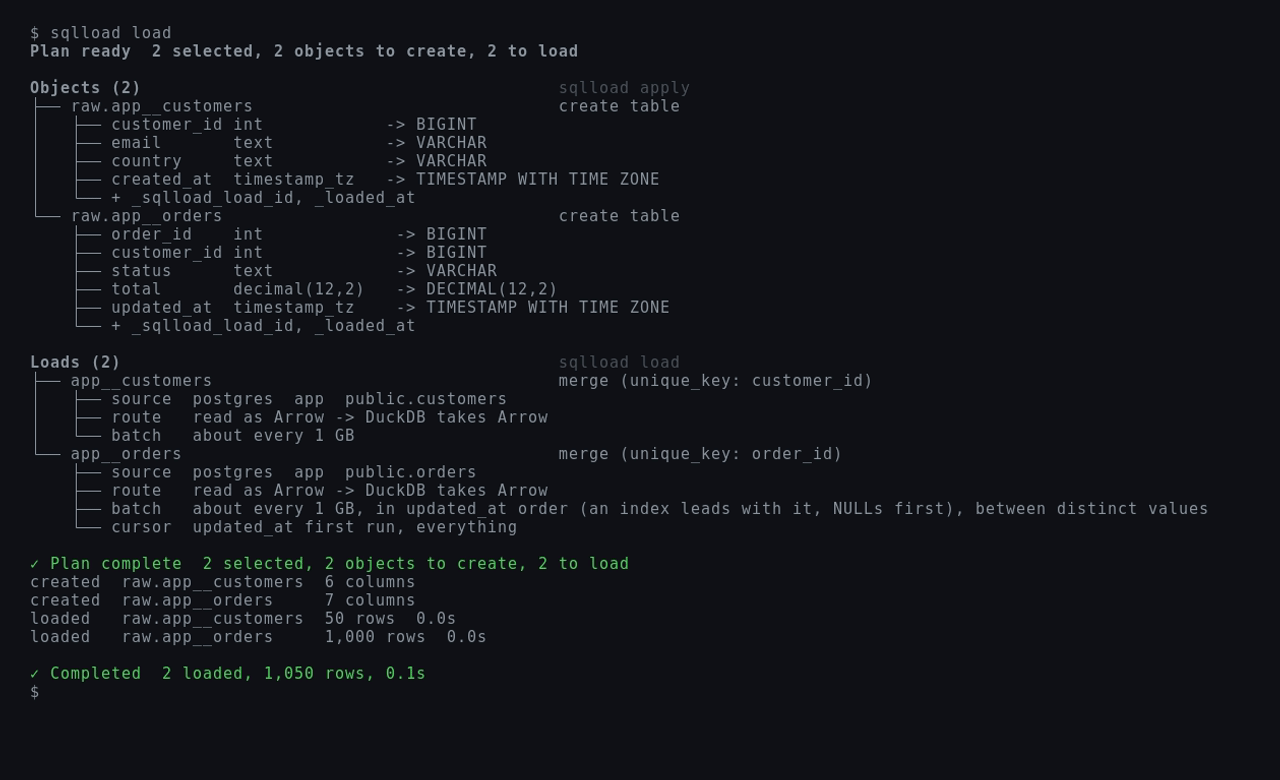 +
-`sqlload plan` shows the tables it will create from Postgres, each column's DuckDB type and how
-each table loads. `sqlload load` then creates and fills them.
+In the [playground](https://sqlload.io/docs/cli/playground/) project, `sqlload plan` shows the
+tables it will create and how each loads, and `sqlload load` creates and fills them. With
+`cursor_column` misspelled, the next load refuses the orders table before touching it, and says
+which column was meant.
## Quick start
```bash
-sqlload plan # every table, column type and route, before anything is created
+sqlload plan # every table and how it loads, before anything is created (-v: column types)
sqlload apply # create the tables
sqlload load # load them
```
@@ -56,7 +59,26 @@ Moving from dlt? [Coming from dlt](https://sqlload.io/docs/guides/from-dlt/) map
write dispositions, incremental loading, `rest_api` and `filesystem`, and keeps the table and column
names dlt gave your tables.
-## Speed
+## Why SQLLoad
+
+- **Exact types.** A source's `decimal(12,2)` loads as `DECIMAL(12,2)` (`NUMBER(12,2)` on
+ Snowflake), timestamps keep their
+ microseconds, and a pinned type narrower than the live column fails `plan` rather than cutting
+ values. See [contracts](https://sqlload.io/docs/concepts/contracts/).
+- **Loud failures.** `plan` names each problem it can find, such as a misspelled column, a
+ narrowing type or a budget too small, and its fix, before anything is created. A commit whose
+ [checks](https://sqlload.io/docs/concepts/checks/) fail publishes none of its rows, every commit
+ lands whole even if a load is killed halfway, and in a warehouse (except a ClickHouse `Ordinary` database) a full refresh swaps in at once,
+ so readers see the old table or the new one, never a mix.
+- **Bounded memory.** A run has one [memory budget](https://sqlload.io/docs/cli/load/#memory-budget),
+ shared out between its tables. A budget too small for even one table is refused before anything
+ loads, and near the limit SQLLoad stops a table, or the run, and rolls back what it was
+ writing, rather than waiting for the operating system to kill it.
+- **No hidden state.** Tables with a `cursor_column` carry on from the
+ [warehouse's own maximum](https://sqlload.io/docs/concepts/cursors/) of the cursor column, so a
+ table you fix or reload by hand never disagrees with a state file.
+
+## Speed and memory
Faster, in a fraction of the memory. The same data loaded by each tool on one 4-vCPU, 8 GB machine;
lower is better:
@@ -77,18 +99,6 @@ peak memory 131 MiB for SQLLoad, 495 MiB for ingestr and 341 MiB for dlt.
See the [benchmarks](https://sqlload.io/docs/benchmarks/) for every scenario, the method, the
versions and how to run them yourself.
-## Why SQLLoad
-
-- **See the plan before any data moves.** `sqlload plan` shows every table, column type, write
- strategy and route before anything is created or loaded, so there are no surprises in your
- warehouse.
-- **Crash-safe loads.** Every commit lands whole, even if a load is killed halfway. A full refresh
- swaps in one go, so your dashboards see the old table or the new one, never a mix.
-- **Postgres change data capture.** A `postgres_cdc` source copies your tables once, then applies
- every insert, update and delete from a logical replication slot, in whole source transactions.
- `sqlload load --follow` keeps streaming. See
- [Postgres CDC](https://sqlload.io/docs/sources/postgres-cdc/).
-
## What it loads
| System | Source | Target |
@@ -98,8 +108,8 @@ versions and how to run them yourself.
| BigQuery (beta) | ✓ | ✓ |
| Databricks (beta) | ✓ | ✓ |
| ClickHouse | | ✓ |
-| DuckDB | | ✓ |
-| MotherDuck (beta) | | ✓ |
+| DuckDB | ✓ | ✓ |
+| MotherDuck (beta) | ✓ | ✓ |
| ODBC | ✓ SQL Server, MySQL, OpenEdge | |
| Files | ✓ Parquet, CSV, JSON, Excel, XML | ✓ Parquet, CSV |
| Google Sheets | ✓ | |
diff --git a/packages/sqlload/README.md b/packages/sqlload/README.md
index 40a451508..afe427d6e 100644
--- a/packages/sqlload/README.md
+++ b/packages/sqlload/README.md
@@ -19,26 +19,29 @@
Benchmarks
-Load Postgres, files, Snowflake, BigQuery, Google Sheets and Python sources into your warehouse.
-SQLLoad is Rust and Arrow end to end, and when your warehouse reads the files itself, rows never
-pass through SQLLoad, so there's no loader bottleneck as your data grows. It's fast, too: faster
-than ingestr and dlt in every [benchmark](https://sqlload.io/docs/benchmarks/) we publish.
+SQLLoad loads databases, files, APIs and Kafka into your warehouse. `sqlload plan` shows every
+table and how it loads before anything moves, and `plan -v` adds each new table's column types and
+the run's memory budget. Decimals keep their precision, a value a column can't hold exactly fails
+its table, naming the column and the value, and each run has one memory budget. Tables with a
+cursor column carry on from the warehouse's own maximum, so there's no state to drift.
```bash
-uv tool install sqlload # or: pip install sqlload
+pip install sqlload # or: uv tool install sqlload
```
-
+
-`sqlload plan` shows the tables it will create from Postgres, each column's DuckDB type and how
-each table loads. `sqlload load` then creates and fills them.
+In the [playground](https://sqlload.io/docs/cli/playground/) project, `sqlload plan` shows the
+tables it will create and how each loads, and `sqlload load` creates and fills them. With
+`cursor_column` misspelled, the next load refuses the orders table before touching it, and says
+which column was meant.
## Quick start
```bash
-sqlload plan # every table, column type and route, before anything is created
+sqlload plan # every table and how it loads, before anything is created (-v: column types)
sqlload apply # create the tables
sqlload load # load them
```
@@ -52,7 +55,30 @@ configuration file:
sqlload copy orders/ duckdb://shop.duckdb#raw.orders
```
-## Speed
+Moving from dlt? [Coming from dlt](https://sqlload.io/docs/guides/from-dlt/) maps sources,
+write dispositions, incremental loading, `rest_api` and `filesystem`, and keeps the table and column
+names dlt gave your tables.
+
+## Why SQLLoad
+
+- **Exact types.** A source's `decimal(12,2)` loads as `DECIMAL(12,2)` (`NUMBER(12,2)` on
+ Snowflake), timestamps keep their
+ microseconds, and a pinned type narrower than the live column fails `plan` rather than cutting
+ values. See [contracts](https://sqlload.io/docs/concepts/contracts/).
+- **Loud failures.** `plan` names each problem it can find, such as a misspelled column, a
+ narrowing type or a budget too small, and its fix, before anything is created. A commit whose
+ [checks](https://sqlload.io/docs/concepts/checks/) fail publishes none of its rows, every commit
+ lands whole even if a load is killed halfway, and in a warehouse (except a ClickHouse `Ordinary` database) a full refresh swaps in at once,
+ so readers see the old table or the new one, never a mix.
+- **Bounded memory.** A run has one [memory budget](https://sqlload.io/docs/cli/load/#memory-budget),
+ shared out between its tables. A budget too small for even one table is refused before anything
+ loads, and near the limit SQLLoad stops a table, or the run, and rolls back what it was
+ writing, rather than waiting for the operating system to kill it.
+- **No hidden state.** Tables with a `cursor_column` carry on from the
+ [warehouse's own maximum](https://sqlload.io/docs/concepts/cursors/) of the cursor column, so a
+ table you fix or reload by hand never disagrees with a state file.
+
+## Speed and memory
Faster, in a fraction of the memory. The same data loaded by each tool on one 4-vCPU, 8 GB machine;
lower is better:
@@ -73,37 +99,22 @@ peak memory 131 MiB for SQLLoad, 495 MiB for ingestr and 341 MiB for dlt.
See the [benchmarks](https://sqlload.io/docs/benchmarks/) for every scenario, the method, the
versions and how to run them yourself.
-## Why SQLLoad
-
-- **See the plan before any data moves.** `sqlload plan` shows every table, column type, write
- strategy and route before anything is created or loaded, so there are no surprises in your
- warehouse.
-- **Crash-safe loads.** Every commit lands whole, even if a load is killed halfway. A full refresh
- swaps in one go, so your dashboards see the old table or the new one, never a mix.
-- **Postgres change data capture.** A `postgres_cdc` source copies your tables once, then applies
- every insert, update and delete from a logical replication slot, in whole source transactions.
- `sqlload load --follow` keeps streaming. See
- [Postgres CDC](https://sqlload.io/docs/sources/postgres-cdc/).
-
## What it loads
| System | Source | Target |
|---|---|---|
-| Postgres | ✓ (incl. CDC) | ✓ |
+| Postgres | ✓ (incl. [CDC](https://sqlload.io/docs/sources/postgres-cdc/)) | ✓ |
| Snowflake | ✓ | ✓ |
-| BigQuery | ✓ | preview |
-| Databricks | | ✓ |
-| ClickHouse | | preview |
-| DuckDB | | ✓ |
-| MotherDuck | | beta² |
-| Files | ✓ Parquet, CSV, JSON (S3, local folder, SFTP) | ✓ Parquet, CSV (S3, local folder) |
+| BigQuery (beta) | ✓ | ✓ |
+| Databricks (beta) | ✓ | ✓ |
+| ClickHouse | | ✓ |
+| DuckDB | ✓ | ✓ |
+| MotherDuck (beta) | ✓ | ✓ |
+| ODBC | ✓ SQL Server, MySQL, OpenEdge | |
+| Files | ✓ Parquet, CSV, JSON, Excel, XML | ✓ Parquet, CSV |
| Google Sheets | ✓ | |
-| HTTP APIs and Python | ✓ | |
-| ODBC databases¹ | ✓ | |
-
-¹ In the published wheels from 0.39.0; before that, in builds with the `odbc` feature.
-
-² From 0.34.0, through a separate DuckDB 1.5 process: install `sqlload[motherduck]`.
+| APIs, Python | ✓ | |
+| Kafka | ✓ to Snowflake, Databricks, BigQuery | |
See [Supported systems](https://sqlload.io/docs/supported-systems/) for every combination and
write strategy.
diff --git a/website/recordings/.gitignore b/website/recordings/.gitignore
new file mode 100644
index 000000000..77f75d7e9
--- /dev/null
+++ b/website/recordings/.gitignore
@@ -0,0 +1,2 @@
+out/
+scratch/
diff --git a/website/recordings/README.md b/website/recordings/README.md
new file mode 100644
index 000000000..eb92f31a9
--- /dev/null
+++ b/website/recordings/README.md
@@ -0,0 +1,35 @@
+# CLI recordings
+
+Terminal recordings of `sqlload` for the README, rendered with
+[VHS](https://github.com/charmbracelet/vhs) from the `.tape` scripts in `tapes/`. The tapes and
+scripts are the source; the rendered GIF, MP4 and PNG files go to `out/`, which is not committed.
+
+| Demo | Shows |
+|------|-------|
+| `plan-load` | In the playground project, `sqlload plan`, then `sqlload load`, then a load that stops on a misspelled `cursor_column`. |
+
+The README uses `plan-load`, copied to `.github/demos/plan-load.gif`. It runs locally on DuckDB,
+with the project `sqlload playground` writes.
+
+## Requirements
+
+- `vhs`, `ttyd` and `ffmpeg` on `PATH`, plus a Chromium or Chrome that VHS can find (it downloads
+ one if none is on `PATH`).
+- DejaVu Sans Mono, the font the tapes use.
+- `sqlload` on `PATH`, or `SQLLOAD_BIN` pointing at a directory that contains the `sqlload` to
+ record. Record with the latest release, so the output matches what users see.
+
+## Record
+
+```bash
+cd website/recordings
+./record.sh plan-load # out/plan-load.gif, out/plan-load.mp4 and out/plan-load.png
+cp out/plan-load.gif ../../.github/demos/
+```
+
+`record.sh` runs `prepare.sh ` to build a clean project under `scratch//`, then renders
+`tapes/.tape`. Shared terminal settings and the colour theme, which matches the website's
+code blocks, are in `tapes/common.tape`.
+
+Look at every frame before publishing a recording: output such as timings and memory changes
+between runs.
diff --git a/website/recordings/prepare.sh b/website/recordings/prepare.sh
new file mode 100755
index 000000000..067c0f558
--- /dev/null
+++ b/website/recordings/prepare.sh
@@ -0,0 +1,20 @@
+#!/usr/bin/env bash
+# Build a clean scratch project for one demo. Usage: prepare.sh
+set -euo pipefail
+demo="$1"
+here="$(cd "$(dirname "$0")" && pwd)"
+dir="$here/scratch/$demo"
+rm -rf "$dir"
+mkdir -p "$dir"
+cd "$dir"
+case "$demo" in
+ plan-load)
+ # The playground project, and a copy of its settings with cursor_column misspelled, which the
+ # tape swaps in after the first load.
+ sqlload playground shop >/dev/null
+ awk '{print} /^unique_key = \["order_id"\]$/ {print "cursor_column = \"updated\""}' shop/sqlload.toml > typo.toml
+ grep -q '^cursor_column = "updated"' typo.toml || { echo "prepare.sh: no unique_key line to add the typo after" >&2; exit 1; } ;;
+ *)
+ echo "unknown demo: $demo" >&2
+ exit 2 ;;
+esac
diff --git a/website/recordings/record.sh b/website/recordings/record.sh
new file mode 100755
index 000000000..dc59bc058
--- /dev/null
+++ b/website/recordings/record.sh
@@ -0,0 +1,14 @@
+#!/usr/bin/env bash
+# Record one demo to out/.gif, out/.mp4 and out/.png. Usage: record.sh
+# Uses the sqlload on PATH; set SQLLOAD_BIN to a directory containing another sqlload to use that instead.
+set -euo pipefail
+demo="$1"
+here="$(cd "$(dirname "$0")" && pwd)"
+if [[ -n "${SQLLOAD_BIN:-}" ]]; then
+ export PATH="$SQLLOAD_BIN:$PATH"
+fi
+"$here/prepare.sh" "$demo"
+mkdir -p "$here/out"
+cd "$here"
+# Headless Chromium's sandbox is unavailable in many containers and CI runners.
+VHS_NO_SANDBOX="${VHS_NO_SANDBOX:-true}" vhs "tapes/$demo.tape"
diff --git a/website/recordings/tapes/common.tape b/website/recordings/tapes/common.tape
new file mode 100644
index 000000000..29e88bfca
--- /dev/null
+++ b/website/recordings/tapes/common.tape
@@ -0,0 +1,13 @@
+Set Shell bash
+Set FontFamily "DejaVu Sans Mono"
+Set FontSize 18
+Set LineHeight 1.0
+Set Width 1200
+Set Height 520
+Set Padding 28
+Set Margin 24
+Set MarginFill "#0d0f12"
+Set BorderRadius 10
+Set WindowBar Colorful
+Set TypingSpeed 40ms
+Set Theme { "name": "SQLLoad", "black": "#5c606b", "red": "#ff5760", "green": "#79c98a", "yellow": "#e3b341", "blue": "#5aa9e6", "magenta": "#c79bf0", "cyan": "#4dd6c4", "white": "#c9cdd4", "brightBlack": "#8a909c", "brightRed": "#ff5760", "brightGreen": "#79c98a", "brightYellow": "#e3b341", "brightBlue": "#5aa9e6", "brightMagenta": "#c79bf0", "brightCyan": "#4dd6c4", "brightWhite": "#e9ebef", "background": "#111418", "foreground": "#c9cdd4", "selection": "#2a2f37", "cursor": "#e9ebef" }
diff --git a/website/recordings/tapes/plan-load.tape b/website/recordings/tapes/plan-load.tape
new file mode 100644
index 000000000..854f41568
--- /dev/null
+++ b/website/recordings/tapes/plan-load.tape
@@ -0,0 +1,36 @@
+Source tapes/common.tape
+Output out/plan-load.gif
+Output out/plan-load.mp4
+Hide
+Type "cd scratch/plan-load/shop && unset NO_COLOR && export PS1='$ ' && clear"
+Enter
+Sleep 500ms
+Show
+Type "sqlload plan"
+Sleep 300ms
+Enter
+Sleep 3.5s
+Hide
+Type "clear"
+Enter
+Sleep 200ms
+Show
+Type "sqlload load"
+Sleep 300ms
+Enter
+Sleep 3.5s
+Hide
+Type "cp ../typo.toml sqlload.toml && clear"
+Enter
+Sleep 200ms
+Show
+Type "grep cursor_column sqlload.toml"
+Sleep 200ms
+Enter
+Sleep 800ms
+Type "sqlload load"
+Sleep 300ms
+Enter
+Sleep 3s
+Screenshot out/plan-load.png
+Sleep 1s
diff --git a/website/src/content/docs/docs/cli/load.mdx b/website/src/content/docs/docs/cli/load.mdx
index e2d4b8ce4..6894b7233 100644
--- a/website/src/content/docs/docs/cli/load.mdx
+++ b/website/src/content/docs/docs/cli/load.mdx
@@ -159,11 +159,11 @@ tables of one run: the table that uses too much stands out. On other systems, `p
## Memory budget
-A run stays under one memory budget, and `plan` shows it first, with where it came
+A run stays under one memory budget, and `plan -v` shows it first, with where it came
from and how it's shared:
```console
-$ sqlload plan --memory-limit 1200MB
+$ sqlload plan -v --memory-limit 1200MB
Memory 1.1 GiB budget (--memory-limit); 39.8 MiB held before loading; DuckDB 488 MiB (memory_limit 244 MiB, 2 threads); 154 MiB per table, 4 at once
Objects (2) sqlload apply