diff --git a/.modrotignore b/.modrotignore
new file mode 100644
index 000000000..222d9cad9
--- /dev/null
+++ b/.modrotignore
@@ -0,0 +1,29 @@
+# Stale dependencies we have looked at and decided to keep. Each entry is on
+# its latest available version, so there is nothing to upgrade to. Re-check any
+# decision older than a year rather than trusting it.
+#
+# modrot matches the module path alone, so a reason has to sit on its own '#'
+# line above the entry. An inline comment stops the entry from matching at all.
+
+# 2026-09-30 keep: latest commit, niche setproctitle binding with no successor
+github.com/ErikDubbelboer/gspt
+
+# 2026-09-30 keep: latest commit, James Hunt's own libraries, which shield was
+# written around. 41 files import go-ansi and 14 import go-table, so replacing
+# either is a port rather than a dependency bump.
+github.com/jhunt/go-ansi
+
+# 2026-09-30 keep: latest commit, 2 call sites, no successor
+github.com/jhunt/go-envirotron
+
+# 2026-09-30 keep: latest commit, see the go-ansi note above
+github.com/jhunt/go-table
+
+# 2026-09-30 keep: latest tag v1.2.1. github.com/google/uuid is the maintained
+# successor and is already in the tree indirectly, but its Parse returns
+# (UUID, error) where pborman's returns a nil UUID, so swapping it across 14
+# files changes error handling rather than just an import path.
+github.com/pborman/uuid
+
+# 2026-09-30 keep: latest tag v1.0.6, 1 call site, no successor
+github.com/thanhpk/randstr
diff --git a/core/auth_provider_okta.go b/core/auth_provider_okta.go
index e50be8383..78e2de12b 100644
--- a/core/auth_provider_okta.go
+++ b/core/auth_provider_okta.go
@@ -16,7 +16,7 @@ import (
"github.com/pborman/uuid"
"github.com/thanhpk/randstr"
- verifier "github.com/okta/okta-jwt-verifier-golang"
+ verifier "github.com/okta/okta-jwt-verifier-golang/v2"
)
type OktaAuthProvider struct {
@@ -308,7 +308,10 @@ func (p *OktaAuthProvider) verifyToken(t string, category string) (*verifier.Jwt
ClaimsToValidate: toValidate,
}
- verifier := jwtVerifierSetup.New()
+ verifier, err := jwtVerifierSetup.New()
+ if err != nil {
+ return nil, fmt.Errorf("could not set up %s token verifier: %s", category, err)
+ }
if category == "id" {
token, err := verifier.VerifyIdToken(t)
diff --git a/go.mod b/go.mod
index 375d20b51..cac265752 100644
--- a/go.mod
+++ b/go.mod
@@ -4,62 +4,61 @@ go 1.27.1
require (
github.com/ErikDubbelboer/gspt v0.0.0-20210805194459-ce36a5128377
- github.com/aws/aws-sdk-go-v2 v1.47.0
- github.com/aws/aws-sdk-go-v2/config v1.33.4
- github.com/aws/aws-sdk-go-v2/credentials v1.20.4
- github.com/aws/aws-sdk-go-v2/service/s3 v1.113.0
+ github.com/aws/aws-sdk-go-v2 v1.47.1
+ github.com/aws/aws-sdk-go-v2/config v1.33.6
+ github.com/aws/aws-sdk-go-v2/credentials v1.20.6
+ github.com/aws/aws-sdk-go-v2/service/s3 v1.114.0
github.com/cloudfoundry-community/vaultkv v0.7.2
github.com/fsouza/go-dockerclient v1.13.3
github.com/go-sql-driver/mysql v1.10.1
github.com/goccy/go-yaml v1.19.2
- github.com/google/go-github/v76 v76.0.0
+ github.com/google/go-github/v92 v92.0.0
github.com/gorilla/websocket v1.5.3
- github.com/hashicorp/consul/api v1.34.4
+ github.com/hashicorp/consul/api/v2 v2.0.0
github.com/jackc/pgx/v5 v5.11.0
github.com/jhunt/go-ansi v0.0.0-20181127194324-5fd839f108b6
github.com/jhunt/go-envirotron v0.0.0-20191007155228-c8f2a184ad0f
github.com/jhunt/go-table v0.0.0-20181127210244-68a841ca53dc
github.com/mattn/go-isatty v0.0.24
- github.com/mattn/go-shellwords v1.0.14
+ github.com/mattn/go-shellwords v1.0.15
github.com/mattn/go-sqlite3 v1.14.52
- github.com/ncw/swift v1.0.53
- github.com/okta/okta-jwt-verifier-golang v1.3.1
- github.com/onsi/ginkgo/v2 v2.32.2
- github.com/onsi/gomega v1.43.0
+ github.com/ncw/swift/v2 v2.0.5
+ github.com/okta/okta-jwt-verifier-golang/v2 v2.1.1
+ github.com/onsi/ginkgo/v2 v2.33.0
+ github.com/onsi/gomega v1.44.0
github.com/pborman/uuid v1.2.1
github.com/prometheus/client_golang v1.24.1
github.com/spf13/cobra v1.10.2
github.com/thanhpk/randstr v1.0.6
- go.etcd.io/etcd/client/v3 v3.7.1
+ go.etcd.io/etcd/client/v3 v3.7.2
golang.org/x/crypto v0.57.0
golang.org/x/net v0.59.0
golang.org/x/oauth2 v0.37.0
- google.golang.org/api v0.297.0
+ google.golang.org/api v0.299.0
)
require (
- cloud.google.com/go/auth v0.23.2 // indirect
- cloud.google.com/go/auth/oauth2adapt v0.2.8 // indirect
- cloud.google.com/go/compute/metadata v0.9.0 // indirect
+ cloud.google.com/go/auth v0.24.0 // indirect
+ cloud.google.com/go/auth/oauth2adapt v0.3.0 // indirect
+ cloud.google.com/go/compute/metadata v0.10.0 // indirect
filippo.io/edwards25519 v1.2.0 // indirect
- github.com/Azure/go-ansiterm v0.0.0-20250102033503-faa5f7b0171c // indirect
+ github.com/Azure/go-ansiterm v0.0.0-20260917205352-e937bb47801a // indirect
github.com/Masterminds/semver/v3 v3.5.0 // indirect
github.com/Microsoft/go-winio v0.6.3-0.20251027160822-ad3df93bed29 // indirect
- github.com/armon/go-metrics v0.4.1 // indirect
github.com/aws/aws-sdk-go-v2/aws/protocol/eventstream v1.7.20 // indirect
- github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.0 // indirect
- github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.3 // indirect
- github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.3 // indirect
- github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.3 // indirect
+ github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.1 // indirect
+ github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.4 // indirect
+ github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.4 // indirect
+ github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.4 // indirect
github.com/aws/aws-sdk-go-v2/service/internal/accept-encoding v1.13.19 // indirect
- github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.3 // indirect
- github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.3 // indirect
- github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.3 // indirect
- github.com/aws/aws-sdk-go-v2/service/signin v1.10.0 // indirect
- github.com/aws/aws-sdk-go-v2/service/sso v1.38.0 // indirect
- github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.0 // indirect
- github.com/aws/aws-sdk-go-v2/service/sts v1.50.0 // indirect
- github.com/aws/smithy-go v1.28.1 // indirect
+ github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.5 // indirect
+ github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.4 // indirect
+ github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.4 // indirect
+ github.com/aws/aws-sdk-go-v2/service/signin v1.10.1 // indirect
+ github.com/aws/aws-sdk-go-v2/service/sso v1.38.1 // indirect
+ github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.1 // indirect
+ github.com/aws/aws-sdk-go-v2/service/sts v1.51.1 // indirect
+ github.com/aws/smithy-go v1.28.2 // indirect
github.com/beorn7/perks v1.0.1 // indirect
github.com/cespare/xxhash/v2 v2.3.0 // indirect
github.com/containerd/log v0.2.0 // indirect
@@ -74,41 +73,41 @@ require (
github.com/go-logr/stdr v1.2.2 // indirect
github.com/go-task/slim-sprig/v3 v3.0.0 // indirect
github.com/go-viper/mapstructure/v2 v2.5.0 // indirect
- github.com/goccy/go-json v0.10.6 // indirect
+ github.com/goccy/go-json v0.11.2 // indirect
github.com/golang/protobuf v1.5.4 // indirect
github.com/google/go-cmp v0.7.0 // indirect
github.com/google/go-querystring v1.2.0 // indirect
- github.com/google/pprof v0.0.0-20260906184651-6331bc6350fe // indirect
- github.com/google/s2a-go v0.1.9 // indirect
+ github.com/google/pprof v0.0.0-20260926063103-aaccee046517 // indirect
+ github.com/google/s2a-go v0.1.10 // indirect
github.com/google/uuid v1.6.0 // indirect
github.com/googleapis/enterprise-certificate-proxy v0.3.22 // indirect
- github.com/googleapis/gax-go/v2 v2.24.1 // indirect
- github.com/grpc-ecosystem/grpc-gateway/v2 v2.30.0 // indirect
- github.com/hashicorp/cap v0.13.0 // indirect
+ github.com/googleapis/gax-go/v2 v2.26.2 // indirect
+ github.com/grpc-ecosystem/grpc-gateway/v2 v2.31.0 // indirect
+ github.com/hashicorp/cap v0.14.0 // indirect
github.com/hashicorp/errwrap v1.1.0 // indirect
github.com/hashicorp/go-cleanhttp v0.5.2 // indirect
github.com/hashicorp/go-hclog v1.6.3 // indirect
github.com/hashicorp/go-immutable-radix v1.3.1 // indirect
- github.com/hashicorp/go-metrics v0.6.1 // indirect
+ github.com/hashicorp/go-metrics v0.7.0 // indirect
github.com/hashicorp/go-multierror v1.1.1 // indirect
github.com/hashicorp/go-rootcerts v1.0.2 // indirect
github.com/hashicorp/go-secure-stdlib/base62 v0.1.2 // indirect
- github.com/hashicorp/go-uuid v1.0.3 // indirect
+ github.com/hashicorp/go-uuid v1.0.4 // indirect
+ github.com/hashicorp/go-version v1.9.0 // indirect
github.com/hashicorp/golang-lru v1.0.2 // indirect
- github.com/hashicorp/serf v0.10.4 // indirect
+ github.com/hashicorp/serf v0.11.0 // indirect
github.com/inconshreveable/mousetrap v1.1.0 // indirect
github.com/jackc/pgpassfile v1.0.0 // indirect
github.com/jackc/pgservicefile v0.0.0-20240606120523-5a60cdf6a761 // indirect
github.com/jackc/puddle/v2 v2.2.2 // indirect
- github.com/klauspost/compress v1.20.0 // indirect
- github.com/lestrrat-go/backoff/v2 v2.0.8 // indirect
+ github.com/klauspost/compress v1.20.1 // indirect
github.com/lestrrat-go/blackmagic v1.0.4 // indirect
github.com/lestrrat-go/httpcc v1.0.1 // indirect
+ github.com/lestrrat-go/httprc v1.0.6 // indirect
github.com/lestrrat-go/iter v1.0.2 // indirect
- github.com/lestrrat-go/jwx v1.2.31 // indirect
+ github.com/lestrrat-go/jwx/v2 v2.1.4 // indirect
github.com/lestrrat-go/option v1.0.1 // indirect
github.com/mattn/go-colorable v0.1.15 // indirect
- github.com/miekg/dns v1.1.73 // indirect
github.com/mitchellh/go-homedir v1.1.0 // indirect
github.com/moby/go-archive v0.3.3 // indirect
github.com/moby/moby/api v1.56.0 // indirect
@@ -122,14 +121,14 @@ require (
github.com/opencontainers/go-digest v1.0.0 // indirect
github.com/opencontainers/image-spec v1.1.1 // indirect
github.com/patrickmn/go-cache v2.1.0+incompatible // indirect
- github.com/pkg/errors v0.9.1 // indirect
github.com/prometheus/client_model v0.6.3 // indirect
- github.com/prometheus/common v0.71.0 // indirect
+ github.com/prometheus/common v0.72.0 // indirect
github.com/prometheus/procfs v0.22.0 // indirect
+ github.com/segmentio/asm v1.2.0 // indirect
github.com/sirupsen/logrus v1.10.2 // indirect
github.com/spf13/pflag v1.0.10 // indirect
- go.etcd.io/etcd/api/v3 v3.7.1 // indirect
- go.etcd.io/etcd/client/pkg/v3 v3.7.1 // indirect
+ go.etcd.io/etcd/api/v3 v3.7.2 // indirect
+ go.etcd.io/etcd/client/pkg/v3 v3.7.2 // indirect
go.opentelemetry.io/auto/sdk v1.2.1 // indirect
go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp v0.71.0 // indirect
go.opentelemetry.io/otel v1.46.0 // indirect
@@ -146,8 +145,8 @@ require (
golang.org/x/text v0.42.0 // indirect
golang.org/x/tools v0.50.0 // indirect
google.golang.org/genproto v0.0.0-20260825221802-da73d73af1c5 // indirect
- google.golang.org/genproto/googleapis/api v0.0.0-20260908043556-f8649ddbbfe6 // indirect
- google.golang.org/genproto/googleapis/rpc v0.0.0-20260908043556-f8649ddbbfe6 // indirect
- google.golang.org/grpc v1.83.2 // indirect
+ google.golang.org/genproto/googleapis/api v0.0.0-20260928230214-8a89bd6388cc // indirect
+ google.golang.org/genproto/googleapis/rpc v0.0.0-20260928230214-8a89bd6388cc // indirect
+ google.golang.org/grpc v1.84.0 // indirect
google.golang.org/protobuf v1.36.12 // indirect
)
diff --git a/go.sum b/go.sum
index ee97b1363..df10a88f2 100644
--- a/go.sum
+++ b/go.sum
@@ -1,73 +1,61 @@
-cloud.google.com/go/auth v0.23.2 h1:pxSCpfiji41hpzpPdMCftEUCezpgpqmmDdYiAjCKXxo=
-cloud.google.com/go/auth v0.23.2/go.mod h1:4DhBRcqvtljQN3dJ57qtqbib5ZGCYE5f2crfiiC2EM0=
-cloud.google.com/go/auth/oauth2adapt v0.2.8 h1:keo8NaayQZ6wimpNSmW5OPc283g65QNIiLpZnkHRbnc=
-cloud.google.com/go/auth/oauth2adapt v0.2.8/go.mod h1:XQ9y31RkqZCcwJWNSx2Xvric3RrU88hAYYbjDWYDL+c=
-cloud.google.com/go/compute/metadata v0.9.0 h1:pDUj4QMoPejqq20dK0Pg2N4yG9zIkYGdBtwLoEkH9Zs=
-cloud.google.com/go/compute/metadata v0.9.0/go.mod h1:E0bWwX5wTnLPedCKqk3pJmVgCBSM6qQI1yTBdEb3C10=
+cloud.google.com/go/auth v0.24.0 h1:UYMbF8otPZnLAkNJ5/LYQYOq0ARcJS1P4JqTeMKbCYU=
+cloud.google.com/go/auth v0.24.0/go.mod h1:IFG/AMA1VWfuTrdbieEsB2GcpJyJV/phGAvogkOoPR4=
+cloud.google.com/go/auth/oauth2adapt v0.3.0 h1:FY8oSZpCYoUNv6QxVODuMjQz4IlSOVeiQtZ08vLPz88=
+cloud.google.com/go/auth/oauth2adapt v0.3.0/go.mod h1:7+2uCm7++XFO+/lN06c2HXpDXb/NMNn2/UwyBPbTnkk=
+cloud.google.com/go/compute/metadata v0.10.0 h1:pyKMUQSwchgkIBBJGdILqQbs/BNJXqwSA7Ej6LAvvtY=
+cloud.google.com/go/compute/metadata v0.10.0/go.mod h1:rGFHRrIif570kSibjFTMbt6/4/tzgJWFGI/HVol4GIk=
filippo.io/edwards25519 v1.2.0 h1:crnVqOiS4jqYleHd9vaKZ+HKtHfllngJIiOpNpoJsjo=
filippo.io/edwards25519 v1.2.0/go.mod h1:xzAOLCNug/yB62zG1bQ8uziwrIqIuxhctzJT18Q77mc=
github.com/AdaLogics/go-fuzz-headers v0.0.0-20240806141605-e8a1dd7889d6 h1:He8afgbRMd7mFxO99hRNu+6tazq8nFF9lIwo9JFroBk=
github.com/AdaLogics/go-fuzz-headers v0.0.0-20240806141605-e8a1dd7889d6/go.mod h1:8o94RPi1/7XTJvwPpRSzSUedZrtlirdB3r9Z20bi2f8=
-github.com/Azure/go-ansiterm v0.0.0-20250102033503-faa5f7b0171c h1:udKWzYgxTojEKWjV8V+WSxDXJ4NFATAsZjh8iIbsQIg=
-github.com/Azure/go-ansiterm v0.0.0-20250102033503-faa5f7b0171c/go.mod h1:xomTg63KZ2rFqZQzSB4Vz2SUXa1BpHTVz9L5PTmPC4E=
-github.com/DataDog/datadog-go v3.2.0+incompatible/go.mod h1:LButxg5PwREeZtORoXG3tL4fMGNddJ+vMq1mwgfaqoQ=
+github.com/Azure/go-ansiterm v0.0.0-20260917205352-e937bb47801a h1:4hxax9ktNjSDoFn1tZSeL6gXMTRMpO0FzjdKfT01jgY=
+github.com/Azure/go-ansiterm v0.0.0-20260917205352-e937bb47801a/go.mod h1:3EWSSOZ50kb+arhww0qIaEXHToib/3FjBj9Jj5lcP5g=
github.com/ErikDubbelboer/gspt v0.0.0-20210805194459-ce36a5128377 h1:Mb5TnfGwwshqu2BNNJnk6gkXbdvbNCi8FeWEW/jAqtI=
github.com/ErikDubbelboer/gspt v0.0.0-20210805194459-ce36a5128377/go.mod h1:01yGrV5aDnYieX2hSBoKGMaRiqHvnLoUy4ngWGZ/owg=
github.com/Masterminds/semver/v3 v3.5.0 h1:kQceYJfbupGfZOKZQg0kou0DgAKhzDg2NZPAwZ/2OOE=
github.com/Masterminds/semver/v3 v3.5.0/go.mod h1:4V+yj/TJE1HU9XfppCwVMZq3I84lprf4nC11bSS5beM=
github.com/Microsoft/go-winio v0.6.3-0.20251027160822-ad3df93bed29 h1:0kQAzHq8vLs7Pptv+7TxjdETLf/nIqJpIB4oC6Ba4vY=
github.com/Microsoft/go-winio v0.6.3-0.20251027160822-ad3df93bed29/go.mod h1:ZWa7ssZJT30CCDGJ7fk/2SBTq9BIQrrVjrcss0UW2s0=
-github.com/alecthomas/template v0.0.0-20160405071501-a0175ee3bccc/go.mod h1:LOuyumcjzFXgccqObfd/Ljyb9UuFJ6TxHnclSeseNhc=
-github.com/alecthomas/template v0.0.0-20190718012654-fb15b899a751/go.mod h1:LOuyumcjzFXgccqObfd/Ljyb9UuFJ6TxHnclSeseNhc=
-github.com/alecthomas/units v0.0.0-20151022065526-2efee857e7cf/go.mod h1:ybxpYRFXyAe+OPACYpWeL0wqObRcbAqCMya13uyzqw0=
-github.com/alecthomas/units v0.0.0-20190717042225-c3de453c63f4/go.mod h1:ybxpYRFXyAe+OPACYpWeL0wqObRcbAqCMya13uyzqw0=
-github.com/armon/go-metrics v0.4.1 h1:hR91U9KYmb6bLBYLQjyM+3j+rcd/UhE+G78SFnF8gJA=
-github.com/armon/go-metrics v0.4.1/go.mod h1:E6amYzXo6aW1tqzoZGT755KkbgrJsSdpwZ+3JqfkOG4=
-github.com/aws/aws-sdk-go-v2 v1.47.0 h1:0jsHallhJCeaU0Ko48c/3FK1ctOQ7NpzggxriJOQ8MQ=
-github.com/aws/aws-sdk-go-v2 v1.47.0/go.mod h1:bttEH6JqnUL8LepvDVfdrds/fZ5bCIxzpe3abyUrhDU=
+github.com/aws/aws-sdk-go-v2 v1.47.1 h1:uOIZnp4PK3ZhKI0dNrJrhTEsLxbpXHTAJlwoS1pvAtw=
+github.com/aws/aws-sdk-go-v2 v1.47.1/go.mod h1:bttEH6JqnUL8LepvDVfdrds/fZ5bCIxzpe3abyUrhDU=
github.com/aws/aws-sdk-go-v2/aws/protocol/eventstream v1.7.20 h1:GPRlPwz40I2B2VrBEASOA3Bi77NyeqejNLkifosX0rs=
github.com/aws/aws-sdk-go-v2/aws/protocol/eventstream v1.7.20/go.mod h1:g7PNzKcsOKWb4fkSRBA7BZVAS6Y8IcxzN+nRohhQ1Q8=
-github.com/aws/aws-sdk-go-v2/config v1.33.4 h1:FzvkXKSzwqHni4U7nDigHg4jjtqMpVUuHgmZfSoJVQ0=
-github.com/aws/aws-sdk-go-v2/config v1.33.4/go.mod h1:VZqGZnZsCWVfK/iGPptJIyNIX3XEX6iQU2Rel4sLrr8=
-github.com/aws/aws-sdk-go-v2/credentials v1.20.4 h1:hTvrJJseKbvw32kmiE0G+u/9ZqpqscjDrTigHIXP2qs=
-github.com/aws/aws-sdk-go-v2/credentials v1.20.4/go.mod h1:gWp9O1ZBWwpcIrgV+mVHk4gZUurAEDkgypu/OXOlIaw=
-github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.0 h1:AM4hHjww+PSFtt6E+UrBrPlZkWsePCLEt9AjkfQX+yM=
-github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.0/go.mod h1:3x/yXezeQjpOvBb4jEMxrS8SXvpdvJ5abv6l5c1gWM8=
-github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.3 h1:Hp/VgjP0BysR3OgLlR057Vz2LcbbVnoWeJ+3qWiS/fY=
-github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.3/go.mod h1:nwGV5qw7F1IZPgxCvA/ph8N2TAuz+BkRG/bXn808qMA=
-github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.3 h1:MUaM4f+kj1ZIBPZfUS8cxP1GKXXZtHJjAthy93AN7SM=
-github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.3/go.mod h1:6YmVmEVRI5ZZzRjCSsb9SryKH0hAlMRdgA7kG9aDvBU=
-github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.3 h1:fuSCw4Z2qfRCztMPO3GXJNSiEp6Wee+WOLwrHHUMy9c=
-github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.3/go.mod h1:6SxcHheD1pPR5+kWm1wGvjlL/YqUsh267sAfEmN4K7A=
+github.com/aws/aws-sdk-go-v2/config v1.33.6 h1:MBjkSTLczek/UgiK+EYPIoRTqE7gP8vtW3OFbFo7Nug=
+github.com/aws/aws-sdk-go-v2/config v1.33.6/go.mod h1:grRAFzdAZJrwcbasJRg2MPvIrVjtlfXllHssN6+E1JE=
+github.com/aws/aws-sdk-go-v2/credentials v1.20.6 h1:NpAFXCU7NzXNkdGK3zQTtsRJ+3v9tZQV0xcdRw8uBdw=
+github.com/aws/aws-sdk-go-v2/credentials v1.20.6/go.mod h1:mcZCoiPnyMvP8VMNbygNX5lLqSlkYJIMPODylQMurOk=
+github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.1 h1:8gALAAmacnIXh+z6VkdDanv4/IkG5APdg4DZLDTmLog=
+github.com/aws/aws-sdk-go-v2/feature/ec2/imds v1.20.1/go.mod h1:Z7IJhJU+poOdJjUR2wpyY21ossQ1XS/R3Lk9Msq5kM4=
+github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.4 h1:CLq4+8UHCI+ZZYl/EuJxXovaIVN2xeeT8JV+dsApQ5E=
+github.com/aws/aws-sdk-go-v2/internal/configsources v1.5.4/go.mod h1:Wv4q5sAM04xAMkoOedxLx2inVf6K5FdxYp+A61L+q/0=
+github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.4 h1:dD4MR81I7YkpEBRk6UP9rocC2QnT3qVuXwzlYTtfGEs=
+github.com/aws/aws-sdk-go-v2/internal/endpoints/v2 v2.8.4/go.mod h1:EcXV1kAFd5XwSkDHlj94gnF3q5CkJyYiIJfH8N0VmrE=
+github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.4 h1:7Wo47d/xn/7KttCSBd8EGYeZ7ULRFRkUHr6vkZPBzVQ=
+github.com/aws/aws-sdk-go-v2/internal/v4a v1.5.4/go.mod h1:tDB2IVC1xC3vX8o+6uRlzhTxP3g1b77CZXFX/oD2FnQ=
github.com/aws/aws-sdk-go-v2/service/internal/accept-encoding v1.13.19 h1:bAdDl/HkGCcGPoe25ToSHEw23VIxt6CT5fLcg111BKg=
github.com/aws/aws-sdk-go-v2/service/internal/accept-encoding v1.13.19/go.mod h1:KaUzbLxv4CeSxh6ZCl9B4m7CuFenS8kUEaDs+f/DQr4=
-github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.3 h1:BHKCSX4QXERe8So8rbWqaM7owqOmDJxATXgJwGng22A=
-github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.3/go.mod h1:GqWeeKfYfezihA2KfFL9l7ohEdZWe1tuFWh3GfyNSnE=
-github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.3 h1:bON1rJf67TSTDCKg816AAIE4xSTtoo9tl0XRkO72R+I=
-github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.3/go.mod h1:c5BBpjJcQXpfeq9iASyVKA3T6vX6B6LEXY4mL/gklDY=
-github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.3 h1:L8vIOxylma91TcR96NFTEC07G3JDwSl+CvK2b+IODms=
-github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.3/go.mod h1:fmPIZQzTExYuBNWFyi1P7IoDjvskgphXqK1yObMzusM=
-github.com/aws/aws-sdk-go-v2/service/s3 v1.113.0 h1:0slwIjBv1sEigSUW4EfTtNw9mbHl0PlOUPX9Y1C/eLE=
-github.com/aws/aws-sdk-go-v2/service/s3 v1.113.0/go.mod h1:/uA+2Qj4jd5qBWagVC1AyzzDFXVK997E7U04w7Kw0wI=
-github.com/aws/aws-sdk-go-v2/service/signin v1.10.0 h1:ZD5qFpWcaOKdTuhBi431pIDkCgrMkMlMT6jlpSPoIRI=
-github.com/aws/aws-sdk-go-v2/service/signin v1.10.0/go.mod h1:8Nuuf+tR346PjJ3MvZPh9pekbLiLQFWJhzMXfwy7alA=
-github.com/aws/aws-sdk-go-v2/service/sso v1.38.0 h1:JGeeBcMlhg1xtOXYpeCaTQBZObtXMPQCUqBcmr65NRA=
-github.com/aws/aws-sdk-go-v2/service/sso v1.38.0/go.mod h1:XwteswG9EOMRFm73UT0t+MbTwyLxMrEXkU6e+v92Lzo=
-github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.0 h1:obhahQXDEdVEv8y5bTKXR30LVaxYe1kyYM0L7l2Iq+k=
-github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.0/go.mod h1:6twZZ/aXHNy1vXUO8koUbp++MYzMASkOgEBdkbJYmO0=
-github.com/aws/aws-sdk-go-v2/service/sts v1.50.0 h1:khXV3+K5D3f4e8xtplaRdSFn1bEg3gj5EBHQvbCOZbQ=
-github.com/aws/aws-sdk-go-v2/service/sts v1.50.0/go.mod h1:/8JRcdTt//hG0Q4BTmGbuOplT7ABe+5rdtqUHqXvYIM=
-github.com/aws/smithy-go v1.28.1 h1:R/nXH00c8qcfCzQVELtRw+eLQWtzv+VAIEFJ1/xxXlQ=
-github.com/aws/smithy-go v1.28.1/go.mod h1:YE2RhdIuDbA5E5bTdciG9KrW3+TiEONeUWCqxX9i1Fc=
-github.com/beorn7/perks v0.0.0-20180321164747-3a771d992973/go.mod h1:Dwedo/Wpr24TaqPxmxbtue+5NUziq4I4S80YR8gNf3Q=
-github.com/beorn7/perks v1.0.0/go.mod h1:KWe93zE9D1o94FZ5RNwFwVgaQK1VOXiVxmqh+CedLV8=
+github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.5 h1:/TYsZXdA8UTa+WCtCYSAJIr1vwl0+eho6TUgJGwFFO8=
+github.com/aws/aws-sdk-go-v2/service/internal/checksum v1.11.5/go.mod h1:qPqp1Uwd/BqdhPufv6oem9j5J7HNsgc2V22dUiDPn+s=
+github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.4 h1:29SvnfGhXjTl8ONxFwbj2rs6lbhiFXD2CgFQmbT/bXY=
+github.com/aws/aws-sdk-go-v2/service/internal/presigned-url v1.14.4/go.mod h1:wm04I5DMuNVvZHFe/dHnUxincvNbbK7AiNBbYsQivek=
+github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.4 h1:pPiWfgeNxqluKEph7hvU88kuGKBPOWzO+Dk9t2zqqNs=
+github.com/aws/aws-sdk-go-v2/service/internal/s3shared v1.20.4/go.mod h1:YlwGoIUDG/3kBQbdNOVs/xKZ9J01G8e/6D1mRBj9uTk=
+github.com/aws/aws-sdk-go-v2/service/s3 v1.114.0 h1:VMAdYqr4Jn/8ATs9BHC5riwrs0d6m1Z2ohFriSwZwm0=
+github.com/aws/aws-sdk-go-v2/service/s3 v1.114.0/go.mod h1:9APRWGLFITKD+xzWSIyT9V7QV4bNlEuIieWlzXgGFlI=
+github.com/aws/aws-sdk-go-v2/service/signin v1.10.1 h1:DzCCWLzcIRQ77F3DEUljud7bEjTgFOIKXP52NmVRyhU=
+github.com/aws/aws-sdk-go-v2/service/signin v1.10.1/go.mod h1:xpo/geVldu8payT375WekctUzopG/hBU7miiqItMUlw=
+github.com/aws/aws-sdk-go-v2/service/sso v1.38.1 h1:Umtl/0YZhng4xndfW3lKJrYYP7NLEjI6bGXVomwLcs0=
+github.com/aws/aws-sdk-go-v2/service/sso v1.38.1/go.mod h1:rRD/dnm7q0HYE/I5TMaPgkWyyUGLcwuxHLABsLnQ3e0=
+github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.1 h1:orIWdNiLgzrhu/11RcPPKO/SBzUUymbUQuZbSPImghg=
+github.com/aws/aws-sdk-go-v2/service/ssooidc v1.43.1/go.mod h1:skwM/xsbR/1ReUTesv9BhpJp1VjajR7DWQnuVLwiXsQ=
+github.com/aws/aws-sdk-go-v2/service/sts v1.51.1 h1:0HOqZXRvMytH6bFHVIc0oJX07sZjfhz0zXtjs6gdE8s=
+github.com/aws/aws-sdk-go-v2/service/sts v1.51.1/go.mod h1:26zA0GhDrLo+yiLI2yXWxqB1PdsShfLikoI7GOEgugM=
+github.com/aws/smithy-go v1.28.2 h1:myhcykQcatTul2B/zITjDk203G7t0awUAs1hVry5Bvg=
+github.com/aws/smithy-go v1.28.2/go.mod h1:YE2RhdIuDbA5E5bTdciG9KrW3+TiEONeUWCqxX9i1Fc=
github.com/beorn7/perks v1.0.1 h1:VlbKKnNfV8bJzeqoa4cOKqO6bYr3WgKZxO8Z16+hsOM=
github.com/beorn7/perks v1.0.1/go.mod h1:G2ZrVWU2WbWT9wwq4/hrbKbnv/1ERSJQ0ibhJ6rlkpw=
-github.com/cespare/xxhash/v2 v2.1.1/go.mod h1:VGX0DQ3Q6kWi7AoAeZDth3/j3BFtOZR5XLFGgcrjCOs=
github.com/cespare/xxhash/v2 v2.3.0 h1:UL815xU9SqsFlibzuggzjXhog7bL6oX9BbNZnL2UFvs=
github.com/cespare/xxhash/v2 v2.3.0/go.mod h1:VGX0DQ3Q6kWi7AoAeZDth3/j3BFtOZR5XLFGgcrjCOs=
-github.com/circonus-labs/circonus-gometrics v2.3.1+incompatible/go.mod h1:nmEj6Dob7S7YxXgwXpfOuvO54S+tGdZdw9fuRZt25Ag=
-github.com/circonus-labs/circonusllhist v0.1.3/go.mod h1:kMXHVDlOchFAehlya5ePtbp5jckzBHf4XRpQvBOLI+I=
github.com/cloudfoundry-community/vaultkv v0.7.2 h1:vZlBaA8CD/kJEGD9eGqDHZYsbvr0upAxotaNpRiw8NE=
github.com/cloudfoundry-community/vaultkv v0.7.2/go.mod h1:nJcdg3lic4/xUqew2LKvWAv7LnSfHEPNKdSDT8vlREw=
github.com/containerd/log v0.2.0 h1:BewD/umNgVnoczglOpX8eRMyEy5t5iPlu5AIpnWDONc=
@@ -81,8 +69,6 @@ github.com/creack/pty v1.1.24 h1:bJrF4RRfyJnbTJqzRLHzcGaZK1NeM5kTC9jGgovnR1s=
github.com/creack/pty v1.1.24/go.mod h1:08sCNb52WyoAwi2QDyzUCTgcvVFhUzewun7wtTfvcwE=
github.com/davecgh/go-spew v1.1.0/go.mod h1:J7Y8YcW2NihsgmVo/mv3lAwl/skON4iLHjSsI+c5H38=
github.com/davecgh/go-spew v1.1.1/go.mod h1:J7Y8YcW2NihsgmVo/mv3lAwl/skON4iLHjSsI+c5H38=
-github.com/decred/dcrd/crypto/blake256 v1.0.0/go.mod h1:sQl2p6Y26YV+ZOcSTP6thNdn47hh8kt6rqSlvmrXFAc=
-github.com/decred/dcrd/dcrec/secp256k1/v4 v4.0.0-20210816181553-5444fa50b93d/go.mod h1:tmAIfUFEirG/Y8jhZ9M+h36obRZAk/1fcSpXwAVlfqE=
github.com/decred/dcrd/dcrec/secp256k1/v4 v4.4.1 h1:5RVFMOWjMyRy8cARdy79nAmgYw3hK/4HUq48LQ6Wwqo=
github.com/decred/dcrd/dcrec/secp256k1/v4 v4.4.1/go.mod h1:ZXNYxsqcloTdSy/rNShjYzMhyjf0LaoftYK0p+A3h40=
github.com/docker/go-units v0.5.0 h1:69rxXcBk27SvSaaxTtLh/8llcHD8vYHT7WSdRZ/jvr4=
@@ -102,10 +88,6 @@ github.com/gkampitakis/go-diff v1.3.2 h1:Qyn0J9XJSDTgnsgHRdz9Zp24RaJeKMUHg2+PDZZ
github.com/gkampitakis/go-diff v1.3.2/go.mod h1:LLgOrpqleQe26cte8s36HTWcTmMEur6OPYerdAAS9tk=
github.com/gkampitakis/go-snaps v0.5.15 h1:amyJrvM1D33cPHwVrjo9jQxX8g/7E2wYdZ+01KS3zGE=
github.com/gkampitakis/go-snaps v0.5.15/go.mod h1:HNpx/9GoKisdhw9AFOBT1N7DBs9DiHo/hGheFGBZ+mc=
-github.com/go-kit/kit v0.8.0/go.mod h1:xBxKIO96dXMWWy0MnWVtmwkA9/13aqxPnvrjFYMA2as=
-github.com/go-kit/kit v0.9.0/go.mod h1:xBxKIO96dXMWWy0MnWVtmwkA9/13aqxPnvrjFYMA2as=
-github.com/go-logfmt/logfmt v0.3.0/go.mod h1:Qt1PoO58o5twSAckw1HlFXLmHsOX5/0LbT9GBnD5lWE=
-github.com/go-logfmt/logfmt v0.4.0/go.mod h1:3RMwSq7FuexP4Kalkev3ejPJsZTpXXBr9+V4qmtdjCk=
github.com/go-logr/logr v1.2.2/go.mod h1:jdQByPbusPIv2/zmleS9BjJVeZ6kBagPoEUsqbVz/1A=
github.com/go-logr/logr v1.4.4 h1:tG4xh9yMsRCAiodLVTxyrkzSZ9+o0L1Kg/+cPVcbP/8=
github.com/go-logr/logr v1.4.4/go.mod h1:9T104GzyrTigFIr8wt5mBrctHMim0Nb2HLGrmQ40KvY=
@@ -113,73 +95,62 @@ github.com/go-logr/stdr v1.2.2 h1:hSWxHoqTgW2S2qGc0LTAI563KZ5YKYRhT3MFKZMbjag=
github.com/go-logr/stdr v1.2.2/go.mod h1:mMo/vtBO5dYbehREoey6XUKy/eSumjCCveDpRre4VKE=
github.com/go-sql-driver/mysql v1.10.1 h1:arlSnNLq6a5yxGxV7qg9lF4j0C+KwD6NbQyKr9QL6ME=
github.com/go-sql-driver/mysql v1.10.1/go.mod h1:M+cqaI7+xxXGG9swrdeUIoPG3Y3KCkF0pZej+SK+nWk=
-github.com/go-stack/stack v1.8.0/go.mod h1:v0f6uXyyMGvRgIKkXu+yp6POWl0qKG85gN/melR3HDY=
github.com/go-task/slim-sprig/v3 v3.0.0 h1:sUs3vkvUymDpBKi3qH1YSqBQk9+9D/8M2mN1vB6EwHI=
github.com/go-task/slim-sprig/v3 v3.0.0/go.mod h1:W848ghGpv3Qj3dhTPRyJypKRiqCdHZiAzKg9hl15HA8=
github.com/go-viper/mapstructure/v2 v2.5.0 h1:vM5IJoUAy3d7zRSVtIwQgBj7BiWtMPfmPEgAXnvj1Ro=
github.com/go-viper/mapstructure/v2 v2.5.0/go.mod h1:oJDH3BJKyqBA2TXFhDsKDGDTlndYOZ6rGS0BRZIxGhM=
-github.com/goccy/go-json v0.9.4/go.mod h1:6MelG93GURQebXPDq3khkgXZkazVtN9CRI+MGFi0w8I=
-github.com/goccy/go-json v0.10.6 h1:p8HrPJzOakx/mn/bQtjgNjdTcN+/S6FcG2CTtQOrHVU=
-github.com/goccy/go-json v0.10.6/go.mod h1:oq7eo15ShAhp70Anwd5lgX2pLfOS3QCiwU/PULtXL6M=
+github.com/goccy/go-json v0.11.2 h1:jdZv93Tt4ioR8yW1CoNsvSxrcZlCXAUU1aZXN7gpXUA=
+github.com/goccy/go-json v0.11.2/go.mod h1:3NdmfEkZlB7YI5UFw/qdFKq8XN1aiWR0YyRPWZNQltY=
github.com/goccy/go-yaml v1.19.2 h1:PmFC1S6h8ljIz6gMRBopkjP1TVT7xuwrButHID66PoM=
github.com/goccy/go-yaml v1.19.2/go.mod h1:XBurs7gK8ATbW4ZPGKgcbrY1Br56PdM69F7LkFRi1kA=
-github.com/gogo/protobuf v1.1.1/go.mod h1:r8qH/GZQm5c6nD/R0oafs1akxWv10x8SbQlK7atdtwQ=
-github.com/golang/protobuf v1.2.0/go.mod h1:6lQm79b+lXiMfvg/cZm0SGofjICqVBUtrP5yJMmIC1U=
-github.com/golang/protobuf v1.3.1/go.mod h1:6lQm79b+lXiMfvg/cZm0SGofjICqVBUtrP5yJMmIC1U=
-github.com/golang/protobuf v1.3.2/go.mod h1:6lQm79b+lXiMfvg/cZm0SGofjICqVBUtrP5yJMmIC1U=
github.com/golang/protobuf v1.5.4 h1:i7eJL8qZTpSEXOPTxNKhASYpMn+8e5Q6AdndVa1dWek=
github.com/golang/protobuf v1.5.4/go.mod h1:lnTiLA8Wa4RWRcIUkrtSVa5nRhsEGBg48fD6rSs7xps=
github.com/google/btree v1.1.3 h1:CVpQJjYgC4VbzxeGVHfvZrv1ctoYCAI8vbl07Fcxlyg=
github.com/google/btree v1.1.3/go.mod h1:qOPhT0dTNdNzV6Z/lhRX0YXUafgPLFUh+gZMl761Gm4=
-github.com/google/go-cmp v0.3.1/go.mod h1:8QqcDgzrUqlUb/G2PQTWiueGozuR1884gddMywk6iLU=
-github.com/google/go-cmp v0.4.0/go.mod h1:v8dTdLbMG2kIc/vJvl+f65V22dbkXbowE6jgT/gNBxE=
github.com/google/go-cmp v0.6.0/go.mod h1:17dUlkBOakJ0+DkrSSNjCkIjxS6bF9zb3elmeNGIjoY=
github.com/google/go-cmp v0.7.0 h1:wk8382ETsv4JYUZwIsn6YpYiWiBsYLSJiTsyBybVuN8=
github.com/google/go-cmp v0.7.0/go.mod h1:pXiqmnSA92OHEEa9HXL2W4E7lf9JzCmGVUdgjX3N/iU=
-github.com/google/go-github/v76 v76.0.0 h1:MCa9VQn+VG5GG7Y7BAkBvSRUN3o+QpaEOuZwFPJmdFA=
-github.com/google/go-github/v76 v76.0.0/go.mod h1:38+d/8pYDO4fBLYfBhXF5EKO0wA3UkXBjfmQapFsNCQ=
+github.com/google/go-github/v92 v92.0.0 h1:4vW4RVffwIvoEfIA4RX09mRSB47qQX557/2+HgeWRRg=
+github.com/google/go-github/v92 v92.0.0/go.mod h1:w3CH62ZcmRfvW1cdXpyTztSOVMtdjxtKpgo0GouLmjY=
github.com/google/go-querystring v1.2.0 h1:yhqkPbu2/OH+V9BfpCVPZkNmUXhb2gBxJArfhIxNtP0=
github.com/google/go-querystring v1.2.0/go.mod h1:8IFJqpSRITyJ8QhQ13bmbeMBDfmeEJZD5A0egEOmkqU=
-github.com/google/gofuzz v1.0.0/go.mod h1:dBl0BpW6vV/+mYPU4Po3pmUjxk6FQPldtuIdl/M65Eg=
-github.com/google/pprof v0.0.0-20260906184651-6331bc6350fe h1:QAinXoAFJdGQYztXn3VpFey7KCwpedbZ/EkzbplQ0cY=
-github.com/google/pprof v0.0.0-20260906184651-6331bc6350fe/go.mod h1:jl5iWTm0/hd5PjEYEOuwAJ57L/CibdZfrqZ5XA5GrCk=
-github.com/google/s2a-go v0.1.9 h1:LGD7gtMgezd8a/Xak7mEWL0PjoTQFvpRudN895yqKW0=
-github.com/google/s2a-go v0.1.9/go.mod h1:YA0Ei2ZQL3acow2O62kdp9UlnvMmU7kA6Eutn0dXayM=
+github.com/google/pprof v0.0.0-20260926063103-aaccee046517 h1:joNby64wfCIWh0HXBMrjZc6ii70nntnG9u3CQSXXwiA=
+github.com/google/pprof v0.0.0-20260926063103-aaccee046517/go.mod h1:jl5iWTm0/hd5PjEYEOuwAJ57L/CibdZfrqZ5XA5GrCk=
+github.com/google/s2a-go v0.1.10 h1:EMp+aOuXN6l8cE/gjF5Bt+vyZxsUuyCWe9chDWR/+uU=
+github.com/google/s2a-go v0.1.10/go.mod h1:pz4tyvwXvJLLbyrkh6FW1eS2zPUXMaTmyNhYtyP2tNw=
github.com/google/uuid v1.0.0/go.mod h1:TIyPZe4MgqvfeYDBFedMoGGpEw/LqOeaOT+nhxU+yHo=
github.com/google/uuid v1.6.0 h1:NIvaJDMOsjHA8n1jAhLSgzrAzy1Hgr+hNrb57e+94F0=
github.com/google/uuid v1.6.0/go.mod h1:TIyPZe4MgqvfeYDBFedMoGGpEw/LqOeaOT+nhxU+yHo=
github.com/googleapis/enterprise-certificate-proxy v0.3.22 h1:NU4XpII6jD+Dxcot94fqjE+AfJoE/lQP9q3faYGzC/c=
github.com/googleapis/enterprise-certificate-proxy v0.3.22/go.mod h1:L3D/IQExI6LqEjBdXcZQ1WluSgigQmSwBboFstVPM4w=
-github.com/googleapis/gax-go/v2 v2.24.1 h1:AtqTN21IXMMWo99LiEVAiBfNNQmO40d8xUfZI640mc0=
-github.com/googleapis/gax-go/v2 v2.24.1/go.mod h1:bWeBei0NVwaNZKb2y1HUBS7gLXIF3/Tu3pq7j8D2Tb0=
+github.com/googleapis/gax-go/v2 v2.26.2 h1:ydkmNXxj7bEmmeK5AihkKnWxyOyBR9TDebvp5L5izk8=
+github.com/googleapis/gax-go/v2 v2.26.2/go.mod h1:sMKqnMesnKH+3wiRJROcttA+cJoZoGbZl1vDQ8XYtGk=
github.com/gorilla/websocket v1.5.3 h1:saDtZ6Pbx/0u+bgYQ3q96pZgCzfhKXGPqt7kZ72aNNg=
github.com/gorilla/websocket v1.5.3/go.mod h1:YR8l580nyteQvAITg2hZ9XVh4b55+EU/adAjf1fMHhE=
-github.com/grpc-ecosystem/grpc-gateway/v2 v2.30.0 h1:/Tnpcb2E0Pz/tN9s3bfEY2Q8ePCEX9iuS+cneUwncnw=
-github.com/grpc-ecosystem/grpc-gateway/v2 v2.30.0/go.mod h1:zOBXOsUaBSjKgmH4OGzV1esUpR3oUSCPYVd2cUBjKYY=
-github.com/hashicorp/cap v0.13.0 h1:bzLS1er9am6hOiw//TEjmwZ3t975iFfRfvXY6VRLKEw=
-github.com/hashicorp/cap v0.13.0/go.mod h1:Kbu5owAOJzQ/HH4Ba/76wsIXN2tRiJgToJKBO2MAEFE=
-github.com/hashicorp/consul/api v1.34.4 h1:0U4YZ1Yp7K9WK9ex0gTJraFim26l02wCvsmf2ukalVE=
-github.com/hashicorp/consul/api v1.34.4/go.mod h1:vz5gBNeycefpAAVNVbLBFObUu3isju6EK8UVZjXSTWc=
-github.com/hashicorp/consul/sdk v0.18.1 h1:RDTeBvAeOveI2xI86sV+8WkaN7OkP4zz+cG3fOobDCM=
-github.com/hashicorp/consul/sdk v0.18.1/go.mod h1:XdP2tEJmAvlK4jgoKTTtohGkRJlS4mU44mv9/sjU21s=
+github.com/grpc-ecosystem/grpc-gateway/v2 v2.31.0 h1:Bd7KaOxzULLxtZ/K5s1aLbWhR0+5RToO65TXHsf3bqQ=
+github.com/grpc-ecosystem/grpc-gateway/v2 v2.31.0/go.mod h1:nN7ts3dFXKtCZWc//yfkpcQNKJABg16/uDVAZpLDalo=
+github.com/hashicorp/cap v0.14.0 h1:IPWX/ewgw8tQPl0qpnCuNf6BFXOCz7ijSM5ikX27cNg=
+github.com/hashicorp/cap v0.14.0/go.mod h1:Kbu5owAOJzQ/HH4Ba/76wsIXN2tRiJgToJKBO2MAEFE=
+github.com/hashicorp/consul/api/v2 v2.0.0 h1:FBzxiwnP8kJoHL2ByDUSvaItbc7jF7LxZLTnHtO75wA=
+github.com/hashicorp/consul/api/v2 v2.0.0/go.mod h1:1gEhzpcnl4X4ui7JFpFQvn7QRYQ60IFm6BxBXjrv0dg=
+github.com/hashicorp/consul/sdk/v2 v2.0.0 h1:3KJ7oqP5ZY0OGmUUMTTafPNM1CscXw9NMJ329UMMgcs=
+github.com/hashicorp/consul/sdk/v2 v2.0.0/go.mod h1:Si3zN9Zw40NHtow0yrGpgJ0wMsL9O2RWDevEzmKzbps=
github.com/hashicorp/errwrap v1.0.0/go.mod h1:YH+1FKiLXxHSkmPseP+kNlulaMuP3n2brvKWEqk/Jc4=
github.com/hashicorp/errwrap v1.1.0 h1:OxrOeh75EUXMY8TBjag2fzXGZ40LB6IKw45YeGUDY2I=
github.com/hashicorp/errwrap v1.1.0/go.mod h1:YH+1FKiLXxHSkmPseP+kNlulaMuP3n2brvKWEqk/Jc4=
-github.com/hashicorp/go-cleanhttp v0.5.0/go.mod h1:JpRdi6/HCYpAwUzNwuwqhbovhLtngrth3wmdIIUrZ80=
github.com/hashicorp/go-cleanhttp v0.5.2 h1:035FKYIWjmULyFRBKPs8TBQoi0x6d9G4xc9neXJWAZQ=
github.com/hashicorp/go-cleanhttp v0.5.2/go.mod h1:kO/YDlP8L1346E6Sodw+PrpBSV4/SoxCXGY6BqNFT48=
github.com/hashicorp/go-hclog v1.6.3 h1:Qr2kF+eVWjTiYmU7Y31tYlP1h0q/X3Nl3tPGdaB11/k=
github.com/hashicorp/go-hclog v1.6.3/go.mod h1:W4Qnvbt70Wk/zYJryRzDRU/4r0kIg0PVHBcfoyhpF5M=
-github.com/hashicorp/go-immutable-radix v1.0.0/go.mod h1:0y9vanUI8NX6FsYoO3zeMjhV/C5i9g4Q3DwcSNZ4P60=
github.com/hashicorp/go-immutable-radix v1.3.1 h1:DKHmCUm2hRBK510BaiZlwvpD40f8bJFeZnpfm2KLowc=
github.com/hashicorp/go-immutable-radix v1.3.1/go.mod h1:0y9vanUI8NX6FsYoO3zeMjhV/C5i9g4Q3DwcSNZ4P60=
-github.com/hashicorp/go-metrics v0.6.1 h1:V7j9cgHTXl4OebnX3y0l6ZSoO5dTp0VI0K8Y7JfRsS4=
-github.com/hashicorp/go-metrics v0.6.1/go.mod h1:XOozbQKeJz12GG8cCcQb/E5vNVeTdJt0aHbM+uHnL1M=
+github.com/hashicorp/go-metrics v0.7.0 h1:lLWieZTcbzZT+rY0zrqKbyryXG8RIajdUjmM0+R79eg=
+github.com/hashicorp/go-metrics v0.7.0/go.mod h1:8T/Es8FPTfQvY7azBPGyrwXwwg7mbA9/TmQ1/lWfxb4=
+github.com/hashicorp/go-msgpack v0.5.5 h1:i9R9JSrqIz0QVLz3sz+i3YJdT7TTSLcfLLzJi9aZTuI=
github.com/hashicorp/go-msgpack/v2 v2.1.5 h1:Ue879bPnutj/hXfmUk6s/jtIK90XxgiUIcXRl656T44=
github.com/hashicorp/go-msgpack/v2 v2.1.5/go.mod h1:bjCsRXpZ7NsJdk45PoCQnzRGDaK8TKm5ZnDI/9y3J4M=
github.com/hashicorp/go-multierror v1.1.1 h1:H5DkEtf6CXdFp0N0Em5UCwQpXMWke8IA0+lD48awMYo=
github.com/hashicorp/go-multierror v1.1.1/go.mod h1:iw975J/qwKPdAO1clOe2L8331t/9/fmwbPZ6JB6eMoM=
-github.com/hashicorp/go-retryablehttp v0.5.3/go.mod h1:9B5zBasrRhHXnJnui7y6sL7es7NDiJgTc6Er0maI1Xs=
github.com/hashicorp/go-rootcerts v1.0.2 h1:jzhAVGtqPKbwpyCPELlgNWhE1znq+qwJtW5Oi2viEzc=
github.com/hashicorp/go-rootcerts v1.0.2/go.mod h1:pqUvnprVnM5bf7AOirdbb01K4ccR319Vf4pU3K5EGc8=
github.com/hashicorp/go-secure-stdlib/base62 v0.1.2 h1:ET4pqyjiGmY09R5y+rSd70J2w45CtbWDNvGqWp/R3Ng=
@@ -188,17 +159,17 @@ github.com/hashicorp/go-sockaddr v1.0.7 h1:G+pTkSO01HpR5qCxg7lxfsFEZaG+C0VssTy/9
github.com/hashicorp/go-sockaddr v1.0.7/go.mod h1:FZQbEYa1pxkQ7WLpyXJ6cbjpT8q0YgQaK/JakXqGyWw=
github.com/hashicorp/go-uuid v1.0.0/go.mod h1:6SBZvOh/SIDV7/2o3Jml5SYk/TvGqwFJ/bN7x4byOro=
github.com/hashicorp/go-uuid v1.0.2/go.mod h1:6SBZvOh/SIDV7/2o3Jml5SYk/TvGqwFJ/bN7x4byOro=
-github.com/hashicorp/go-uuid v1.0.3 h1:2gKiV6YVmrJ1i2CKKa9obLvRieoRGviZFL26PcT/Co8=
-github.com/hashicorp/go-uuid v1.0.3/go.mod h1:6SBZvOh/SIDV7/2o3Jml5SYk/TvGqwFJ/bN7x4byOro=
+github.com/hashicorp/go-uuid v1.0.4 h1:ZrN80XjMzpRYk+2FxMDy2A2zz0d5QjJ7GMFSkZLj12A=
+github.com/hashicorp/go-uuid v1.0.4/go.mod h1:x2Ds7vSkQ2n/yQj8Synnxmt0zt1l26uCAjxIhChisLU=
github.com/hashicorp/go-version v1.9.0 h1:CeOIz6k+LoN3qX9Z0tyQrPtiB1DFYRPfCIBtaXPSCnA=
github.com/hashicorp/go-version v1.9.0/go.mod h1:fltr4n8CU8Ke44wwGCBoEymUuxUHl09ZGVZPK5anwXA=
github.com/hashicorp/golang-lru v0.5.0/go.mod h1:/m3WP610KZHVQ1SGc6re/UDhFvYD7pJ4Ao+sR/qLZy8=
github.com/hashicorp/golang-lru v1.0.2 h1:dV3g9Z/unq5DpblPpw+Oqcv4dU/1omnb4Ok8iPY6p1c=
github.com/hashicorp/golang-lru v1.0.2/go.mod h1:iADmTwqILo4mZ8BN3D2Q6+9jd8WM5uGBxy+E8yxSoD4=
-github.com/hashicorp/memberlist v0.6.0 h1:hhVDLQUzWkLaitLLSrxLLqSD2l2+qiOz1DMr5zb9EQQ=
-github.com/hashicorp/memberlist v0.6.0/go.mod h1:a2lqh8KICpm8JibWOmuld7DaA+9QU1YcUtTTTMAtt/M=
-github.com/hashicorp/serf v0.10.4 h1:TCQOrJXHZ1Xf80c4WBhMM9OwUFgDaIP0R+YvoQUKadI=
-github.com/hashicorp/serf v0.10.4/go.mod h1:l+s5Q1OSPWU6b9l9m7ODJzTp7mLevSaVzAI03Nka2F0=
+github.com/hashicorp/memberlist v0.7.0 h1:JfqTDFUIAzDEYKMhSc3Gpwe05zvSU3/cYtiZ3yW59TM=
+github.com/hashicorp/memberlist v0.7.0/go.mod h1:Qar5D5CgaQAb74gk8Ph/jVcATn4epSDOHOvbSKOLHwg=
+github.com/hashicorp/serf v0.11.0 h1:8PbIr0pQOHs5hpBAkbX0teVLckuLvG3qIZm7hZJO0gc=
+github.com/hashicorp/serf v0.11.0/go.mod h1:k7zXXBvdNnDT5F1xrC0uMJB/0FWf6erElwZNQq/SsBA=
github.com/inconshreveable/mousetrap v1.1.0 h1:wN+x4NVGpMsO7ErUn/mUI3vEoE6Jt13X2s0bqwp9tc8=
github.com/inconshreveable/mousetrap v1.1.0/go.mod h1:vpF70FUmC8bwa3OWnCshd2FqLfsEA9PFc4w1p2J65bw=
github.com/jackc/pgpassfile v1.0.0 h1:/6Hmqy13Ss2zCq62VdNG8tM1wchn8zjSGOBJ6icpsIM=
@@ -209,6 +180,8 @@ github.com/jackc/pgx/v5 v5.11.0 h1:IzBBtyK9AHqf98cctWFifYSci2hgQR/cd56wB4p+ogg=
github.com/jackc/pgx/v5 v5.11.0/go.mod h1:mal1tBGAFfLHvZzaYh77YS/eC6IX9OWbRV1QIIM0Jn4=
github.com/jackc/puddle/v2 v2.2.2 h1:PR8nw+E/1w0GLuRFSmiioY6UooMp6KJv0/61nB7icHo=
github.com/jackc/puddle/v2 v2.2.2/go.mod h1:vriiEXHvEE654aYKXXjOvZM39qJ0q+azkZFrfEOc3H4=
+github.com/jarcoal/httpmock v1.1.0 h1:F47ChZj1Y2zFsCXxNkBPwNNKnAyOATcdQibk0qEdVCE=
+github.com/jarcoal/httpmock v1.1.0/go.mod h1:ATjnClrvW/3tijVmpL/va5Z3aAyGvqU3gCT8nX0Txik=
github.com/jhunt/go-ansi v0.0.0-20181127194324-5fd839f108b6 h1:qAlBkfBj+4aW68SdlhlAiWx+hy7vmchlcAZQRAJFhFI=
github.com/jhunt/go-ansi v0.0.0-20181127194324-5fd839f108b6/go.mod h1:zx5sSmwzYAXhfPcRBU7SuiAwK+8vC/LTgAoHyJiclzI=
github.com/jhunt/go-envirotron v0.0.0-20191007155228-c8f2a184ad0f h1:C2Z+D/WhnixDp/q8+MoyqUlhZIAJvFhWwsGOjJqBG2s=
@@ -217,42 +190,26 @@ github.com/jhunt/go-table v0.0.0-20181127210244-68a841ca53dc h1:znV4/dwO+LmbQGSe
github.com/jhunt/go-table v0.0.0-20181127210244-68a841ca53dc/go.mod h1:ws87Lzc/NsPhH1MRRNk2IBANVMHsaQws0NqstHrveaE=
github.com/joshdk/go-junit v1.0.0 h1:S86cUKIdwBHWwA6xCmFlf3RTLfVXYQfvanM5Uh+K6GE=
github.com/joshdk/go-junit v1.0.0/go.mod h1:TiiV0PqkaNfFXjEiyjWM3XXrhVyCa1K4Zfga6W52ung=
-github.com/json-iterator/go v1.1.6/go.mod h1:+SdeFBvtyEkXs7REEP0seUULqWtbJapLOCVDaaPEHmU=
-github.com/json-iterator/go v1.1.9/go.mod h1:KdQUCv79m/52Kvf8AW2vK1V8akMuk1QjK/uOdHXbAo4=
-github.com/julienschmidt/httprouter v1.2.0/go.mod h1:SYymIcj16QtmaHHD7aYtjjsJG7VTCxuUUipMqKk8s4w=
-github.com/klauspost/compress v1.20.0 h1:a3C1ke2ohxFymNlb2HWAHjDeKCI90scRskErZkR0ezA=
-github.com/klauspost/compress v1.20.0/go.mod h1:LUdAzn7YLVvxLpc7y3V1m40wESHTgc1422pwwBSKYuI=
-github.com/konsorten/go-windows-terminal-sequences v1.0.1/go.mod h1:T0+1ngSBFLxvqU3pZ+m/2kptfBszLMUkC4ZK/EgS/cQ=
-github.com/kr/logfmt v0.0.0-20140226030751-b84e30acd515/go.mod h1:+0opPa2QZZtGFBFZlji/RkVcI2GknAs/DXo4wKdlNEc=
-github.com/kr/pretty v0.1.0/go.mod h1:dAy3ld7l9f0ibDNOQOHHMYYIIbhfbHSm3C4ZsoJORNo=
+github.com/klauspost/compress v1.20.1 h1:T7kKElXUMXrUJ2E9QhQhxFtcK5rPyLdsGZvdbLMPdiQ=
+github.com/klauspost/compress v1.20.1/go.mod h1:LUdAzn7YLVvxLpc7y3V1m40wESHTgc1422pwwBSKYuI=
github.com/kr/pretty v0.3.1 h1:flRD4NNwYAUpkphVc1HcthR4KEIFJ65n8Mw5qdRn3LE=
github.com/kr/pretty v0.3.1/go.mod h1:hoEshYVHaxMs3cyo3Yncou5ZscifuDolrwPKZanG3xk=
-github.com/kr/pty v1.1.1/go.mod h1:pFQYn66WHrOpPYNljwOMqo10TkYh1fy3cYio2l3bCsQ=
-github.com/kr/text v0.1.0/go.mod h1:4Jbv+DJW3UT/LiOwJeYQe1efqtUx/iVham/4vfdArNI=
github.com/kr/text v0.2.0 h1:5Nx0Ya0ZqY2ygV366QzturHI13Jq95ApcVaJBhpS+AY=
github.com/kr/text v0.2.0/go.mod h1:eLer722TekiGuMkidMxC/pM04lWEeraHUUmBw8l2grE=
github.com/kylelemons/godebug v1.1.0 h1:RPNrshWIDI6G2gRW9EHilWtl7Z6Sb1BR0xunSBf0SNc=
github.com/kylelemons/godebug v1.1.0/go.mod h1:9/0rRGxNHcop5bhtWyNeEfOS8JIWk580+fNqagV/RAw=
-github.com/lestrrat-go/backoff/v2 v2.0.8 h1:oNb5E5isby2kiro9AgdHLv5N5tint1AnDVVf2E2un5A=
-github.com/lestrrat-go/backoff/v2 v2.0.8/go.mod h1:rHP/q/r9aT27n24JQLa7JhSQZCKBBOiM/uP402WwN8Y=
-github.com/lestrrat-go/blackmagic v1.0.0/go.mod h1:TNgH//0vYSs8VXDCfkZLgIrVTTXQELZffUV0tz3MtdQ=
github.com/lestrrat-go/blackmagic v1.0.4 h1:IwQibdnf8l2KoO+qC3uT4OaTWsW7tuRQXy9TRN9QanA=
github.com/lestrrat-go/blackmagic v1.0.4/go.mod h1:6AWFyKNNj0zEXQYfTMPfZrAXUWUfTIZ5ECEUEJaijtw=
-github.com/lestrrat-go/codegen v1.0.0/go.mod h1:JhJw6OQAuPEfVKUCLItpaVLumDGWQznd1VaXrBk9TdM=
-github.com/lestrrat-go/httpcc v1.0.0/go.mod h1:tGS/u00Vh5N6FHNkExqGGNId8e0Big+++0Gf8MBnAvE=
github.com/lestrrat-go/httpcc v1.0.1 h1:ydWCStUeJLkpYyjLDHihupbn2tYmZ7m22BGkcvZZrIE=
github.com/lestrrat-go/httpcc v1.0.1/go.mod h1:qiltp3Mt56+55GPVCbTdM9MlqhvzyuL6W/NMDA8vA5E=
-github.com/lestrrat-go/iter v1.0.1/go.mod h1:zIdgO1mRKhn8l9vrZJZz9TUMMFbQbLeTsbqPDrJ/OJc=
+github.com/lestrrat-go/httprc v1.0.6 h1:qgmgIRhpvBqexMJjA/PmwSvhNk679oqD1RbovdCGW8k=
+github.com/lestrrat-go/httprc v1.0.6/go.mod h1:mwwz3JMTPBjHUkkDv/IGJ39aALInZLrhBp0X7KGUZlo=
github.com/lestrrat-go/iter v1.0.2 h1:gMXo1q4c2pHmC3dn8LzRhJfP1ceCbgSiT9lUydIzltI=
github.com/lestrrat-go/iter v1.0.2/go.mod h1:Momfcq3AnRlRjI5b5O8/G5/BvpzrhoFTZcn06fEOPt4=
-github.com/lestrrat-go/jwx v1.2.18/go.mod h1:bWTBO7IHHVMtNunM8so9MT8wD+euEY1PzGEyCnuI2qM=
-github.com/lestrrat-go/jwx v1.2.31 h1:/OM9oNl/fzyldpv5HKZ9m7bTywa7COUfg8gujd9nJ54=
-github.com/lestrrat-go/jwx v1.2.31/go.mod h1:eQJKoRwWcLg4PfD5CFA5gIZGxhPgoPYq9pZISdxLf0c=
-github.com/lestrrat-go/option v0.0.0-20210103042652-6f1ecfceda35/go.mod h1:5ZHFbivi4xwXxhxY9XHDe2FHo6/Z7WWmtT7T5nBBp3I=
-github.com/lestrrat-go/option v1.0.0/go.mod h1:5ZHFbivi4xwXxhxY9XHDe2FHo6/Z7WWmtT7T5nBBp3I=
+github.com/lestrrat-go/jwx/v2 v2.1.4 h1:uBCMmJX8oRZStmKuMMOFb0Yh9xmEMgNJLgjuKKt4/qc=
+github.com/lestrrat-go/jwx/v2 v2.1.4/go.mod h1:nWRbDFR1ALG2Z6GJbBXzfQaYyvn751KuuyySN2yR6is=
github.com/lestrrat-go/option v1.0.1 h1:oAzP2fvZGQKWkvHa1/SAcFolBEca1oN+mQ7eooNBEYU=
github.com/lestrrat-go/option v1.0.1/go.mod h1:5ZHFbivi4xwXxhxY9XHDe2FHo6/Z7WWmtT7T5nBBp3I=
-github.com/lestrrat-go/pdebug/v3 v3.0.1/go.mod h1:za+m+Ve24yCxTEhR59N7UlnJomWwCiIqbJRmKeiADU4=
github.com/maruel/natural v1.1.1 h1:Hja7XhhmvEFhcByqDoHz9QZbkWey+COd9xWfCfn1ioo=
github.com/maruel/natural v1.1.1/go.mod h1:v+Rfd79xlw1AgVBjbO0BEQmptqb5HvL/k9GRHB7ZKEg=
github.com/mattn/go-colorable v0.1.9/go.mod h1:u6P/XSegPjTcexA+o6vUJrdnUu04hMope9wVRipJSqc=
@@ -263,11 +220,10 @@ github.com/mattn/go-isatty v0.0.12/go.mod h1:cbi8OIDigv2wuxKPP5vlRcQ1OAZbq2CE4Ky
github.com/mattn/go-isatty v0.0.14/go.mod h1:7GGIvUiUoEMVVmxf/4nioHXj79iQHKdU27kJ6hsGG94=
github.com/mattn/go-isatty v0.0.24 h1:tGZZoVgT/KiqK1c8ocVLeDS8BSWMRd47J3Lbz7vsReI=
github.com/mattn/go-isatty v0.0.24/go.mod h1:nMCL3Zebbrt45jsMDgnfIwz6ydEQApk5oEI3HqDio6A=
-github.com/mattn/go-shellwords v1.0.14 h1:yUKzIgsCnosndOASY6/enly1EAuaXeFSQ7cdyA3OuYg=
-github.com/mattn/go-shellwords v1.0.14/go.mod h1:EZzvwXDESEeg03EKmM+RmDnNOPKG4lLtQsUlTZDWQ8Y=
+github.com/mattn/go-shellwords v1.0.15 h1:rx0n8+ZdM9JWZMlr2BMPAjtLU0rfluLNtwMC2FJOTtY=
+github.com/mattn/go-shellwords v1.0.15/go.mod h1:EZzvwXDESEeg03EKmM+RmDnNOPKG4lLtQsUlTZDWQ8Y=
github.com/mattn/go-sqlite3 v1.14.52 h1:wVbm2Qnf4OXkqhBTSPuCRZDRnxfbVrrmiCEroVdog8U=
github.com/mattn/go-sqlite3 v1.14.52/go.mod h1:6JTjA44L93a0QCyJef5YvlPoKXntQPjzWv5gtm9sB6w=
-github.com/matttproud/golang_protobuf_extensions v1.0.1/go.mod h1:D8He9yQNgCq6Z5Ld7szi9bcBfOoFv/3dc6xSMkL2PC0=
github.com/mfridman/tparse v0.18.0 h1:wh6dzOKaIwkUGyKgOntDW4liXSo37qg5AXbIhkMV3vE=
github.com/mfridman/tparse v0.18.0/go.mod h1:gEvqZTuCgEhPbYk/2lS3Kcxg1GmTxxU7kTC8DvP0i/A=
github.com/miekg/dns v1.1.73 h1:uhT8nJxmTrPJYClxVxTCX+CVn6qnzSiybRk72Z6DgrE=
@@ -294,58 +250,37 @@ github.com/moby/sys/userns v0.2.1 h1:4OvdM7BcPkASbuouHsbW3aeMJSFlYDldBRnXVZhaRk8
github.com/moby/sys/userns v0.2.1/go.mod h1:IHUYgu/kao6N8YZlp9Cf444ySSvCmDlmzUcYfDHOl28=
github.com/moby/term v0.5.2 h1:6qk3FJAFDs6i/q3W/pQ97SX192qKfZgGjCQqfCJkgzQ=
github.com/moby/term v0.5.2/go.mod h1:d3djjFCrjnB+fl8NJux+EJzu0msscUP+f8it8hPkFLc=
-github.com/modern-go/concurrent v0.0.0-20180228061459-e0a39a4cb421/go.mod h1:6dJC0mAP4ikYIbvyc7fijjWJddQyLn8Ig3JB5CqoB9Q=
-github.com/modern-go/concurrent v0.0.0-20180306012644-bacd9c7ef1dd/go.mod h1:6dJC0mAP4ikYIbvyc7fijjWJddQyLn8Ig3JB5CqoB9Q=
-github.com/modern-go/reflect2 v0.0.0-20180701023420-4b7aa43c6742/go.mod h1:bx2lNnkwVCuqBIxFjflWJWanXIb3RllmbCylyMrvgv0=
-github.com/modern-go/reflect2 v1.0.1/go.mod h1:bx2lNnkwVCuqBIxFjflWJWanXIb3RllmbCylyMrvgv0=
github.com/munnerz/goautoneg v0.0.0-20191010083416-a7dc8b61c822 h1:C3w9PqII01/Oq1c1nUAm88MOHcQC9l5mIlSMApZMrHA=
github.com/munnerz/goautoneg v0.0.0-20191010083416-a7dc8b61c822/go.mod h1:+n7T8mK8HuQTcFwEeznm/DIxMOiR9yIdICNftLE1DvQ=
-github.com/mwitkow/go-conntrack v0.0.0-20161129095857-cc309e4a2223/go.mod h1:qRWi+5nqEBWmkhHvq77mSJWrCKwh8bxhgT7d/eI7P4U=
-github.com/ncw/swift v1.0.53 h1:luHjjTNtekIEvHg5KdAFIBaH7bWfNkefwFnpDffSIks=
-github.com/ncw/swift v1.0.53/go.mod h1:23YIA4yWVnGwv2dQlN4bB7egfYX6YLn0Yo/S6zZO/ZM=
+github.com/ncw/swift/v2 v2.0.5 h1:9o5Gsd7bInAFEqsGPcaUdsboMbqf8lnNtxqWKFT9iz8=
+github.com/ncw/swift/v2 v2.0.5/go.mod h1:cbAO76/ZwcFrFlHdXPjaqWZ9R7Hdar7HpjRXBfbjigk=
github.com/nxadm/tail v1.4.8 h1:nPr65rt6Y5JFSKQO7qToXr7pePgD6Gwiw05lkbyAQTE=
github.com/nxadm/tail v1.4.8/go.mod h1:+ncqLTQzXmGhMZNUePPaPqPvBxHAIsmXswZKocGu+AU=
-github.com/okta/okta-jwt-verifier-golang v1.3.1 h1:V+9W5KD3nG7xN0UYtnzXtkurGcs71bLwzPFuUGNMwdE=
-github.com/okta/okta-jwt-verifier-golang v1.3.1/go.mod h1:cHffA777f7Yi4K+yDzUp89sGD5v8sk04Pc3CiT1OMR8=
+github.com/okta/okta-jwt-verifier-golang/v2 v2.1.1 h1:0Z/lJ5P9FGix5/MasMU0iB/2HR+JHRYY500JC/w3x74=
+github.com/okta/okta-jwt-verifier-golang/v2 v2.1.1/go.mod h1:F12fuValkJzGay51EClq8sSyKT5cYJIzq6jO3mdztEA=
github.com/onsi/ginkgo v1.16.5 h1:8xi0RTUf59SOSfEtZMvwTvXYMzG4gV23XVHOZiXNtnE=
github.com/onsi/ginkgo v1.16.5/go.mod h1:+E8gABHa3K6zRBolWtd+ROzc/U5bkGt0FwiG042wbpU=
-github.com/onsi/ginkgo/v2 v2.32.2 h1:2o6vyFvR6snrJWgRVztC+OwuqqPEMI1UzYl2s2iU7Cg=
-github.com/onsi/ginkgo/v2 v2.32.2/go.mod h1:+aXOY+vzZ5mu2iI2HpTZUPmM//oQfsNFX6gU9kNcA44=
-github.com/onsi/gomega v1.43.0 h1:VlG/1FxqNxhSO+lq/OHBNaaqwiBK/mO8JbVkX9Y+FeU=
-github.com/onsi/gomega v1.43.0/go.mod h1:REff/hsDsodHoKlWsP2mAPhu1+5/6hVYNf9rIEBpeSg=
+github.com/onsi/ginkgo/v2 v2.33.0 h1:C8gBA6Uc2ZEubiV+SXiu5tZnMTwEmXHgkJwGozKtZf8=
+github.com/onsi/ginkgo/v2 v2.33.0/go.mod h1:+aXOY+vzZ5mu2iI2HpTZUPmM//oQfsNFX6gU9kNcA44=
+github.com/onsi/gomega v1.44.0 h1:eAiGl3Pw5jz5GQdDff0BcxYpAX1JxW8xD7mFUuwNfZQ=
+github.com/onsi/gomega v1.44.0/go.mod h1:e/C2HwaZ1DhvjzXXuFhcR7hY7Sh9pl7MmoWKEjzwcdA=
github.com/opencontainers/go-digest v1.0.0 h1:apOUWs51W5PlhuyGyz9FCeeBIOUDA/6nW8Oi/yOhh5U=
github.com/opencontainers/go-digest v1.0.0/go.mod h1:0JzlMkj0TRzQZfJkVvzbP0HBR3IKzErnv2BNG4W4MAM=
github.com/opencontainers/image-spec v1.1.1 h1:y0fUlFfIZhPF1W537XOLg0/fcx6zcHCJwooC2xJA040=
github.com/opencontainers/image-spec v1.1.1/go.mod h1:qpqAh3Dmcf36wStyyWU+kCeDgrGnAve2nCC8+7h8Q0M=
-github.com/pascaldekloe/goe v0.1.0 h1:cBOtyMzM9HTpWjXfbbunk26uA6nG3a8n06Wieeh0MwY=
-github.com/pascaldekloe/goe v0.1.0/go.mod h1:lzWF7FIEvWOWxwDKqyGYQf6ZUaNfKdP144TG7ZOy1lc=
-github.com/patrickmn/go-cache v0.0.0-20180815053127-5633e0862627/go.mod h1:3Qf8kWWT7OJRJbdiICTKqZju1ZixQ/KpMGzzAfe6+WQ=
github.com/patrickmn/go-cache v2.1.0+incompatible h1:HRMgzkcYKYpi3C8ajMPV8OFXaaRUnok+kx1WdO15EQc=
github.com/patrickmn/go-cache v2.1.0+incompatible/go.mod h1:3Qf8kWWT7OJRJbdiICTKqZju1ZixQ/KpMGzzAfe6+WQ=
github.com/pborman/uuid v1.2.1 h1:+ZZIw58t/ozdjRaXh/3awHfmWRbzYxJoAdNJxe/3pvw=
github.com/pborman/uuid v1.2.1/go.mod h1:X/NO0urCmaxf9VXbdlT7C2Yzkj2IKimNn4k+gtPdI/k=
-github.com/pkg/errors v0.8.0/go.mod h1:bwawxfHBFNV+L2hUp1rHADufV3IMtnDRdf1r5NINEl0=
-github.com/pkg/errors v0.8.1/go.mod h1:bwawxfHBFNV+L2hUp1rHADufV3IMtnDRdf1r5NINEl0=
github.com/pkg/errors v0.9.1 h1:FEBLx1zS214owpjy7qsBeixbURkuhQAwrK5UwLGTwt4=
github.com/pkg/errors v0.9.1/go.mod h1:bwawxfHBFNV+L2hUp1rHADufV3IMtnDRdf1r5NINEl0=
github.com/pmezard/go-difflib v1.0.0/go.mod h1:iKH77koFhYxTK1pcRnkKkqfTogsbg7gZNVY4sRDYZ/4=
-github.com/prometheus/client_golang v0.9.1/go.mod h1:7SWBe2y4D6OKWSNQJUaRYU/AaXPKyh/dDVn+NZz0KFw=
-github.com/prometheus/client_golang v1.0.0/go.mod h1:db9x61etRT2tGnBNRi70OPL5FsnadC4Ky3P0J6CfImo=
-github.com/prometheus/client_golang v1.4.0/go.mod h1:e9GMxYsXl05ICDXkRhurwBS4Q3OK1iX/F2sw+iXX5zU=
github.com/prometheus/client_golang v1.24.1 h1:JnJkREXzWxUdCuPFpIWZiPispT9xVV59uiuyR2bPlnU=
github.com/prometheus/client_golang v1.24.1/go.mod h1:F+oSRECHg4sse5ucfYpYDeIv/hu68Zo0uoHKetWnzcE=
-github.com/prometheus/client_model v0.0.0-20180712105110-5c3871d89910/go.mod h1:MbSGuTsp3dbXC40dX6PRTWyKYBIrTGTE9sqQNg2J8bo=
-github.com/prometheus/client_model v0.0.0-20190129233127-fd36f4220a90/go.mod h1:xMI15A0UPsDsEKsMN9yxemIoYk6Tm2C1GtYGdfGttqA=
-github.com/prometheus/client_model v0.2.0/go.mod h1:xMI15A0UPsDsEKsMN9yxemIoYk6Tm2C1GtYGdfGttqA=
github.com/prometheus/client_model v0.6.3 h1:O0jaTVAYNxTHYInEPFJt5I3+sN8zqBtVMPTB1qyxiEo=
github.com/prometheus/client_model v0.6.3/go.mod h1:gpN5P9S7Rr6Yr92PiQ+Ixvhf6JZEkF1dnxsYL2aPBEM=
-github.com/prometheus/common v0.4.1/go.mod h1:TNfzLD0ON7rHzMJeJkieUDPYmFC7Snx/y86RQel1bk4=
-github.com/prometheus/common v0.9.1/go.mod h1:yhUN8i9wzaXS3w1O07YhxHEBxD+W35wd8bs7vj7HSQ4=
-github.com/prometheus/common v0.71.0 h1:9KDAKb7Mj3HEVKyFCK6Dc/HIwlBzZIN2l7/lrHl3KK8=
-github.com/prometheus/common v0.71.0/go.mod h1:CLJ5H8TEsGX8bl31BdMkfhIZ+QmZ9tBPPotUxUbfcmk=
-github.com/prometheus/procfs v0.0.0-20181005140218-185b4288413d/go.mod h1:c3At6R/oaqEKCNdg8wHV1ftS6bRYblBhIjjI8uT2IGk=
-github.com/prometheus/procfs v0.0.2/go.mod h1:TjEm7ze935MbeOT/UhFTIMYKhuLP4wbCsTZCD3I8kEA=
-github.com/prometheus/procfs v0.0.8/go.mod h1:7Qr8sr6344vo1JqZ6HhLceV9o3AJ1Ff+GxbHq6oeK9A=
+github.com/prometheus/common v0.72.0 h1:tAYsE+sPJxIncDAobm4H5aQjmox9ZxEIIqPbiffa8G4=
+github.com/prometheus/common v0.72.0/go.mod h1:77NWqAQ2tXT7BIK40qjJdw5Acrsrg1TlHAnsQi3i6mk=
github.com/prometheus/procfs v0.22.0 h1:6q9+/JL9IKAPbCmBrv9n5O5Ty3NKnciV5X7YGw0oics=
github.com/prometheus/procfs v0.22.0/go.mod h1:CvmFr/GVhIjIvWJZW3tgkODBQMRIf0EyWMQLHCHab58=
github.com/rogpeppe/go-internal v1.14.1 h1:UQB4HGPB6osV0SQTLymcB4TgvyWu6ZyliaW0tI/otEQ=
@@ -353,8 +288,8 @@ github.com/rogpeppe/go-internal v1.14.1/go.mod h1:MaRKkUm5W0goXpeCfT7UZI6fk/L7L7
github.com/russross/blackfriday/v2 v2.1.0/go.mod h1:+Rmxgy9KzJVeS9/2gXHxylqXiyQDYRxCVz55jmeOWTM=
github.com/sean-/seed v0.0.0-20170313163322-e2103e2c3529 h1:nn5Wsu0esKSJiIVhscUtVbo7ada43DJhG55ua/hjS5I=
github.com/sean-/seed v0.0.0-20170313163322-e2103e2c3529/go.mod h1:DxrIzT+xaE7yg65j358z/aeFdxmN0P9QXhEzd20vsDc=
-github.com/sirupsen/logrus v1.2.0/go.mod h1:LxeOpSwHxABJmUn/MG1IvRgCAasNZTLOkJPxbbu5VWo=
-github.com/sirupsen/logrus v1.4.2/go.mod h1:tLMulIdttU9McNUspp0xgXVQah82FyeX6MwdIuYE2rE=
+github.com/segmentio/asm v1.2.0 h1:9BQrFxC+YOHJlTlHGkTrFWf59nbL3XnCoFLTwDCI7ys=
+github.com/segmentio/asm v1.2.0/go.mod h1:BqMnlJP91P8d+4ibuonYZw9mfnzI9HfxselHZr5aAcs=
github.com/sirupsen/logrus v1.10.2 h1:G2SED73/qrAu6YwbdxOD6peLkCBI3z7L+ykJFTXJBBo=
github.com/sirupsen/logrus v1.10.2/go.mod h1:SLEg8TqYulVKKfIGHldVp2K2aYz2DKSVBq4g/H5bR7Q=
github.com/spf13/cobra v1.10.2 h1:DMTTonx5m65Ic0GOoRY2c16WCbHxOOw6xxezuLaBpcU=
@@ -363,13 +298,9 @@ github.com/spf13/pflag v1.0.9/go.mod h1:McXfInJRrz4CZXVZOBLb0bTZqETkiAhM9Iw0y3An
github.com/spf13/pflag v1.0.10 h1:4EBh2KAYBwaONj6b2Ye1GiHfwjqyROoF4RwYO+vPwFk=
github.com/spf13/pflag v1.0.10/go.mod h1:McXfInJRrz4CZXVZOBLb0bTZqETkiAhM9Iw0y3An2Bg=
github.com/stretchr/objx v0.1.0/go.mod h1:HFkY916IF+rwdDfMAkV7OtwuqBVzrE8GR6GFx+wExME=
-github.com/stretchr/objx v0.1.1/go.mod h1:HFkY916IF+rwdDfMAkV7OtwuqBVzrE8GR6GFx+wExME=
-github.com/stretchr/objx v0.5.2 h1:xuMeJ0Sdp5ZMRXx/aWO6RZxdr3beISkG5/G/aIRr3pY=
-github.com/stretchr/objx v0.5.2/go.mod h1:FRsXN1f5AsAjCGJKqEizvkpNtU+EGNCLh3NxZ/8L+MA=
-github.com/stretchr/testify v1.2.2/go.mod h1:a8OnRcib4nhh0OaRAV+Yts87kKdq0PP7pXfy6kDkUVs=
+github.com/stretchr/objx v0.5.3 h1:jmXUvGomnU1o3W/V5h2VEradbpJDwGrzugQQvL0POH4=
+github.com/stretchr/objx v0.5.3/go.mod h1:rDQraq+vQZU7Fde9LOZLr8Tax6zZvy4kuNKF+QYS+U0=
github.com/stretchr/testify v1.3.0/go.mod h1:M5WIy9Dh21IEIfnGCwXGc5bZfKNJtfHm1UVUgZn+9EI=
-github.com/stretchr/testify v1.4.0/go.mod h1:j7eGeouHqKxXV5pUuKE4zz7dFj8WfuZ+81PSLYec5m4=
-github.com/stretchr/testify v1.5.1/go.mod h1:5W2xD1RspED5o8YsWQXVCued0rvSQ+mT+I5cxcmMvtA=
github.com/stretchr/testify v1.6.1/go.mod h1:6Fq8oRcR53rry900zMqJjRRixrwX3KX962/h/Wwjteg=
github.com/stretchr/testify v1.7.0/go.mod h1:6Fq8oRcR53rry900zMqJjRRixrwX3KX962/h/Wwjteg=
github.com/stretchr/testify v1.7.1/go.mod h1:6Fq8oRcR53rry900zMqJjRRixrwX3KX962/h/Wwjteg=
@@ -386,14 +317,12 @@ github.com/tidwall/pretty v1.2.1 h1:qjsOFOWWQl+N3RsoF5/ssm1pHmJJwhjlSbZ51I6wMl4=
github.com/tidwall/pretty v1.2.1/go.mod h1:ITEVvHYasfjBbM0u2Pg8T2nJnzm8xPwvNhhsoaGGjNU=
github.com/tidwall/sjson v1.2.5 h1:kLy8mja+1c9jlljvWTlSazM7cKDRfJuR/bOJhcY5NcY=
github.com/tidwall/sjson v1.2.5/go.mod h1:Fvgq9kS/6ociJEDnK0Fk1cpYF4FIW6ZF7LAe+6jwd28=
-github.com/tv42/httpunix v0.0.0-20150427012821-b75d8614f926/go.mod h1:9ESjWnEqriFuLhtthL60Sar/7RFoluCcXsuvEwTV5KM=
-github.com/yuin/goldmark v1.2.1/go.mod h1:3hX8gzYuyVAZsxl0MRgGTJEmQBFcNTphYh9decYSb74=
-go.etcd.io/etcd/api/v3 v3.7.1 h1:KJG0/DcWGfe3Y1otDf/fsBf0TSSgpxZ5RO/L8SFt73E=
-go.etcd.io/etcd/api/v3 v3.7.1/go.mod h1:8bXIpCMeV7E3/XL0Ix123ATn3dB+0V7d9zklHbB0m78=
-go.etcd.io/etcd/client/pkg/v3 v3.7.1 h1:rKYsj3pRkR0eK3yjT3XOgrhqfmIfj9pzNgxjh7mfFv4=
-go.etcd.io/etcd/client/pkg/v3 v3.7.1/go.mod h1:cnzZGIUzSfjEwLC6UBVsSXlEK1eepS/JUD7wE6PLRT0=
-go.etcd.io/etcd/client/v3 v3.7.1 h1:0PEMMC0KuZmVIN+RAbdqfkZ45pYTgKVtmBEbRCvZFUg=
-go.etcd.io/etcd/client/v3 v3.7.1/go.mod h1:ffNqALa8tRCYhYo1F9oR489y23K39Gz+BSR3ApAGYq0=
+go.etcd.io/etcd/api/v3 v3.7.2 h1:xgt/6el1LsPWWYNLkhMAK4tZm6dF+1sCqDecpE5gdbk=
+go.etcd.io/etcd/api/v3 v3.7.2/go.mod h1:RoRCBRt9BfBff1pIGZLUVMiz7wu3bY+b2qLysGu1HY4=
+go.etcd.io/etcd/client/pkg/v3 v3.7.2 h1:SVtlR7tiSVAYOQ4nWPIyFXb4RMgEcnzeAG9RQ8MoNDU=
+go.etcd.io/etcd/client/pkg/v3 v3.7.2/go.mod h1:HsSux/B3ahgyw/D5+d4YbZqicOi0mEbuxm6lIUdjAoI=
+go.etcd.io/etcd/client/v3 v3.7.2 h1:Z66GqDQDI7zPDfVSsIBqGSK4mJYLtv8ESwXa4mPf+wY=
+go.etcd.io/etcd/client/v3 v3.7.2/go.mod h1:x03t1qMs4tGZirCDJlMuzPBJdQffXJImIyEjLhNBCsY=
go.opentelemetry.io/auto/sdk v1.2.1 h1:jXsnJ4Lmnqd11kwkBV2LgLoFMZKizbCi5fNZ/ipaZ64=
go.opentelemetry.io/auto/sdk v1.2.1/go.mod h1:KRTj+aOaElaLi+wW1kO/DZRXwkF4C5xPbEe3ZiIhN7Y=
go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp v0.71.0 h1:3g7B90UzBltIDKq1/5mrTGxTnOFDV0ICOhLoxiZ8jlg=
@@ -419,94 +348,49 @@ go.yaml.in/yaml/v2 v2.4.4/go.mod h1:gMZqIpDtDqOfM0uNfy0SkpRhvUryYH0Z6wdMYcacYXQ=
go.yaml.in/yaml/v3 v3.0.4/go.mod h1:DhzuOOF2ATzADvBadXxruRBLzYTpT36CKvDb3+aBEFg=
go.yaml.in/yaml/v3 v3.0.5 h1:N6y/pJk8buWs9NY5ERU2HSMfm+IuD/OtfdAnq6kESPw=
go.yaml.in/yaml/v3 v3.0.5/go.mod h1:HVTZu1O7/Vkt2N+BFy8Zza+lnLsABggaTM2ZpNIGuKg=
-golang.org/x/crypto v0.0.0-20180904163835-0709b304e793/go.mod h1:6SG95UA2DQfeDnfUPMdvaQW0Q7yPrPDi9nlGo2tz2b4=
-golang.org/x/crypto v0.0.0-20190308221718-c2843e01d9a2/go.mod h1:djNgcEr1/C05ACkg1iLfiJU5Ep61QUkGW8qpdssI0+w=
-golang.org/x/crypto v0.0.0-20191011191535-87dc89f01550/go.mod h1:yigFU9vqHzYiE8UmvKecakEJjdnWj3jj499lnFckfCI=
-golang.org/x/crypto v0.0.0-20200622213623-75b288015ac9/go.mod h1:LzIPMQfyMNhhGPhUkYOs5KpL4U8rLKemX1yGLhDgUto=
-golang.org/x/crypto v0.0.0-20201217014255-9d1352758620/go.mod h1:jdWPYTVW3xRLrWPugEBEK3UY2ZEsg3UU495nc5E+M+I=
golang.org/x/crypto v0.57.0 h1:3ZVCjf8Ggz7zneR/EHRVx68Ctf+2pmIMP2UFhh9cC6M=
golang.org/x/crypto v0.57.0/go.mod h1:Fdz0i5U6CoizGwLda9DttjSk6qlZo25zYNtR+ycvuZA=
golang.org/x/exp v0.0.0-20260908205506-85c1c2202aba h1:Ck8QetSgk912qxWLMCKxd0in+aiyBQyDSMae6e/xmpU=
golang.org/x/exp v0.0.0-20260908205506-85c1c2202aba/go.mod h1:50RgIsmK7OwqzTTeqcSXQW8SswW0o8fRcDxmqGluJ8E=
-golang.org/x/mod v0.3.0/go.mod h1:s0Qsj1ACt9ePp/hMypM3fl4fZqREWJwdYDEqhRiZZUA=
-golang.org/x/mod v0.4.1/go.mod h1:s0Qsj1ACt9ePp/hMypM3fl4fZqREWJwdYDEqhRiZZUA=
golang.org/x/mod v0.41.0 h1:qJmnOUb4YB+FsEuM3HcWucdZASCPGhsX6uljO6pog0c=
golang.org/x/mod v0.41.0/go.mod h1:Ek9pY8RKWXwsWvd3rQiHYtMqkjSUV+s1Rj7j4H5Ur6o=
-golang.org/x/net v0.0.0-20181114220301-adae6a3d119a/go.mod h1:mL1N/T3taQHkDXs73rZJwtUhF3w3ftmwwsq0BUmARs4=
-golang.org/x/net v0.0.0-20190404232315-eb5bcb51f2a3/go.mod h1:t9HGtf8HONx5eT2rtn7q6eTqICYqUVnKs3thJo3Qplg=
-golang.org/x/net v0.0.0-20190613194153-d28f0bde5980/go.mod h1:z5CRVTTTmAJ677TzLLGU+0bjPO0LkuOLi4/5GtJWs/s=
-golang.org/x/net v0.0.0-20190620200207-3b0461eec859/go.mod h1:z5CRVTTTmAJ677TzLLGU+0bjPO0LkuOLi4/5GtJWs/s=
-golang.org/x/net v0.0.0-20200822124328-c89045814202/go.mod h1:/O7V0waA8r7cgGh81Ro3o1hOxt32SMVPicZroKQ2sZA=
-golang.org/x/net v0.0.0-20201021035429-f5854403a974/go.mod h1:sp8m0HH+o8qH0wwXwYZr8TS3Oi6o0r6Gce1SSxlDquU=
golang.org/x/net v0.59.0 h1:5zfYln+w5XCxwrnMMJPufRgNoXEaGxl0wo5GqPXyues=
golang.org/x/net v0.59.0/go.mod h1:2DA/G1UfVbCpQPeWTmMPGY7Cs2PkBkwu743bVX5PIVg=
golang.org/x/oauth2 v0.37.0 h1:JUlcxA8oAtauLfiH8FX2/FkAWHAdi0QtGCGc+hofE98=
golang.org/x/oauth2 v0.37.0/go.mod h1:IxwZNxUULJmpBFf9K/9NTMSIfZZuvuTy1gGxhigP/58=
-golang.org/x/sync v0.0.0-20181108010431-42b317875d0f/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
-golang.org/x/sync v0.0.0-20181221193216-37e7f081c4d4/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
-golang.org/x/sync v0.0.0-20190423024810-112230192c58/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
-golang.org/x/sync v0.0.0-20190911185100-cd5d95a43a6e/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
-golang.org/x/sync v0.0.0-20200625203802-6e8e738ad208/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
-golang.org/x/sync v0.0.0-20201020160332-67f06af15bc9/go.mod h1:RxMgew5VJxzue5/jJTE5uejpjVlOe/izrB70Jof72aM=
golang.org/x/sync v0.23.0 h1:KameEIfc1IkluZyXWLn39Wd4tURc6GbCiISGiZm2bQk=
golang.org/x/sync v0.23.0/go.mod h1:sUUOizhqBxiL6pEWpqNLUiaJn1ShEbZ6BBqskPbjZm0=
-golang.org/x/sys v0.0.0-20180905080454-ebe1bf3edb33/go.mod h1:STP8DvDyc/dI5b8T5hshtkjS+E42TnysNCUPdjciGhY=
-golang.org/x/sys v0.0.0-20181116152217-5ac8a444bdc5/go.mod h1:STP8DvDyc/dI5b8T5hshtkjS+E42TnysNCUPdjciGhY=
-golang.org/x/sys v0.0.0-20190215142949-d0b11bdaac8a/go.mod h1:STP8DvDyc/dI5b8T5hshtkjS+E42TnysNCUPdjciGhY=
-golang.org/x/sys v0.0.0-20190412213103-97732733099d/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20190422165155-953cdadca894/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20191026070338-33540a1f6037/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
golang.org/x/sys v0.0.0-20200116001909-b77594299b42/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20200122134326-e047566fdf82/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
golang.org/x/sys v0.0.0-20200223170610-d5e6a3e2c0ae/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20200323222414-85ca7c5b95cd/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20200930185726-fdedc70b468f/go.mod h1:h1NjWce9XRLGQEsW7wpKNCjG9DtNlClVuFLEZdDNbEs=
-golang.org/x/sys v0.0.0-20210616094352-59db8d763f22/go.mod h1:oPkhp1MJrh7nUepCBck5+mAzfO9JrbApNNgaTdGDITg=
golang.org/x/sys v0.0.0-20210630005230-0f9fa26af87c/go.mod h1:oPkhp1MJrh7nUepCBck5+mAzfO9JrbApNNgaTdGDITg=
golang.org/x/sys v0.0.0-20210927094055-39ccf1dd6fa6/go.mod h1:oPkhp1MJrh7nUepCBck5+mAzfO9JrbApNNgaTdGDITg=
+golang.org/x/sys v0.0.0-20220412211240-33da011f77ad/go.mod h1:oPkhp1MJrh7nUepCBck5+mAzfO9JrbApNNgaTdGDITg=
golang.org/x/sys v0.0.0-20220503163025-988cb79eb6c6/go.mod h1:oPkhp1MJrh7nUepCBck5+mAzfO9JrbApNNgaTdGDITg=
golang.org/x/sys v0.48.0 h1:bbX/i/6MgT9BVLM9RT1thmxL04yeTAhbEz4SyadbXoo=
golang.org/x/sys v0.48.0/go.mod h1:hNLxWAXmnKAxqDtdwIYC4bM9oQPEecfsnNMuSxOs3og=
-golang.org/x/term v0.0.0-20201117132131-f5c789dd3221/go.mod h1:Nr5EML6q2oocZ2LXRh80K7BxOlk5/8JxuGnuhpl+muw=
golang.org/x/term v0.46.0 h1:3+OXuTbaKDgwk8jTi3aSLHRlmWqHEUDUtxnbFigO4YE=
golang.org/x/term v0.46.0/go.mod h1:+K02xbkittuwc0Am4abfA3Fc+XRGXkvBXNO88NCXPoc=
-golang.org/x/text v0.3.0/go.mod h1:NqM8EUOU14njkJ3fqMW+pc6Ldnwhi/IjpwHt7yyuwOQ=
-golang.org/x/text v0.3.3/go.mod h1:5Zoc/QRtKVWzQhOtBMvqHzDpF6irO9z98xDceosuGiQ=
golang.org/x/text v0.42.0 h1:JbOZXgfeCPU9gacVtYliJqOhD+zhrEqK4LfdpmlUZqI=
golang.org/x/text v0.42.0/go.mod h1:ojzP1Z+2QtioaF8DTtO8K5q7JWVVYwZKenzujK0Zd0E=
-golang.org/x/tools v0.0.0-20180917221912-90fa682c2a6e/go.mod h1:n7NCudcB/nEzxVGmLbDWY5pfWTLqBcC2KZ6jyYvM4mQ=
-golang.org/x/tools v0.0.0-20191119224855-298f0cb1881e/go.mod h1:b+2E5dAYhXwXZwtnZ6UAqBI28+e2cm9otk0dWdXHAEo=
-golang.org/x/tools v0.0.0-20200918232735-d647fc253266/go.mod h1:z6u4i615ZeAfBE4XtMziQW1fSVJXACjjbWkB/mvPzlU=
-golang.org/x/tools v0.0.0-20210114065538-d78b04bdf963/go.mod h1:emZCQorbCU4vsT4fOWvOPXz4eW1wZW4PmDk9uLelYpA=
golang.org/x/tools v0.50.0 h1:c2ifzfcuY7L90lZ2aKd8S4K2NpASF08SZx9ZuJkHmSU=
golang.org/x/tools v0.50.0/go.mod h1:7ulVMw3831Mwi5EZD6RomGyffr4VFjuNYXf2BbCEAV0=
-golang.org/x/xerrors v0.0.0-20190717185122-a985d3407aa7/go.mod h1:I/5z698sn9Ka8TeJc9MKroUUfqBBauWjQqLJ2OPfmY0=
-golang.org/x/xerrors v0.0.0-20191011141410-1b5146add898/go.mod h1:I/5z698sn9Ka8TeJc9MKroUUfqBBauWjQqLJ2OPfmY0=
-golang.org/x/xerrors v0.0.0-20191204190536-9bdfabe68543/go.mod h1:I/5z698sn9Ka8TeJc9MKroUUfqBBauWjQqLJ2OPfmY0=
-golang.org/x/xerrors v0.0.0-20200804184101-5ec99f83aff1/go.mod h1:I/5z698sn9Ka8TeJc9MKroUUfqBBauWjQqLJ2OPfmY0=
gonum.org/v1/gonum v0.17.0 h1:VbpOemQlsSMrYmn7T2OUvQ4dqxQXU+ouZFQsZOx50z4=
gonum.org/v1/gonum v0.17.0/go.mod h1:El3tOrEuMpv2UdMrbNlKEh9vd86bmQ6vqIcDwxEOc1E=
-google.golang.org/api v0.297.0 h1:WktxTsnnx0yZNnsR6j0q6hR21RnnK81FHTOPy/ux4OE=
-google.golang.org/api v0.297.0/go.mod h1:S4m8x0M6OkQpkOzGk1y9JG2sm4fFQrMh6dxzjCTszhE=
+google.golang.org/api v0.299.0 h1:b3K+ydSMd0kh6TQI6bJyApRQfqQX2MfSOaVkpM59mJw=
+google.golang.org/api v0.299.0/go.mod h1:zlR3GVA8b2R5nv5Ij9UWe37StVB3cxDD7DBFi4ZFsHw=
google.golang.org/genproto v0.0.0-20260825221802-da73d73af1c5 h1:jPP56YzdY899KJ5W7efXHt/CkjlVfAaoFOwdi/IEAFA=
google.golang.org/genproto v0.0.0-20260825221802-da73d73af1c5/go.mod h1:gutZdP0DwAHp4vu5WaXgEK7tjsJ77ZEqzlOFWGZGziE=
-google.golang.org/genproto/googleapis/api v0.0.0-20260908043556-f8649ddbbfe6 h1:O4Tjo2vlGeGM3+tNgwJrGj5fQHO2V71gDkFqbm328C8=
-google.golang.org/genproto/googleapis/api v0.0.0-20260908043556-f8649ddbbfe6/go.mod h1:r4KD2hOq82JBWpTWkJ9NZLf6EwmRvAPIFmk7hPNtd+0=
-google.golang.org/genproto/googleapis/rpc v0.0.0-20260908043556-f8649ddbbfe6 h1:ieEbjQ6lzbvntOXUB9nMx9uH+yIU/HbgkNDjnk/mJuk=
-google.golang.org/genproto/googleapis/rpc v0.0.0-20260908043556-f8649ddbbfe6/go.mod h1:DjtHYE8FKJLivXcBEjGwndXfIC23G0VpXiXKqG179uA=
-google.golang.org/grpc v1.83.2 h1:EManeRomTObA0BU7I8vXgg/78uE5MJ9M8B39EX2WscU=
-google.golang.org/grpc v1.83.2/go.mod h1:YPI1hK3kDked6iHvgX3tR0y+nX/qpMFKhPgFsokw1S8=
+google.golang.org/genproto/googleapis/api v0.0.0-20260928230214-8a89bd6388cc h1:rZHRz0ogq4Pid1IKtA/ivHi8XONVF5tqUQXA2TtgpkE=
+google.golang.org/genproto/googleapis/api v0.0.0-20260928230214-8a89bd6388cc/go.mod h1:K/n0XLazCJHjD73YuMyNJsN38BPPy1kfFnKxUXaThFU=
+google.golang.org/genproto/googleapis/rpc v0.0.0-20260928230214-8a89bd6388cc h1:4bNTbnb44EqGVy9HaQxSY2jnafSUdgV3qHtedvNpDKg=
+google.golang.org/genproto/googleapis/rpc v0.0.0-20260928230214-8a89bd6388cc/go.mod h1:OaIUM3+LpYcK2GXM4FTmhWoIq371Owdr+Cc7/BsYHHc=
+google.golang.org/grpc v1.84.0 h1:soMyaPJ8pAak5PIQ0DGBUir0XRo2fRoMqhNWMLlLxO0=
+google.golang.org/grpc v1.84.0/go.mod h1:ljCht0DrxQrXBDRTZp52Qxh3Ffk8CdYm2sj4O2QN2C0=
google.golang.org/protobuf v1.36.12 h1:pJOKDDOyeXErUroCihFAd5LQuwXBSpVnKGrj5o/fwxc=
google.golang.org/protobuf v1.36.12/go.mod h1:HTf+CrKn2C3g5S8VImy6tdcUvCska2kB7j23XfzDpco=
-gopkg.in/alecthomas/kingpin.v2 v2.2.6/go.mod h1:FMv+mEhP44yOT+4EoQTLFTRgOQ1FBLkstjWtayDeSgw=
gopkg.in/check.v1 v0.0.0-20161208181325-20d25e280405/go.mod h1:Co6ibVJAznAaIkqp8huTwlJQCZ016jof/cbN4VW5Yz0=
-gopkg.in/check.v1 v1.0.0-20190902080502-41f04d3bba15/go.mod h1:Co6ibVJAznAaIkqp8huTwlJQCZ016jof/cbN4VW5Yz0=
gopkg.in/tomb.v1 v1.0.0-20141024135613-dd632973f1e7 h1:uRGJdciOHaEIrze2W8Q3AKkepLTh2hOroT7a+7czfdQ=
gopkg.in/tomb.v1 v1.0.0-20141024135613-dd632973f1e7/go.mod h1:dt/ZhP58zS4L8KSrWDmTeBkI65Dw0HsyUHuEVlX15mw=
-gopkg.in/yaml.v2 v2.2.1/go.mod h1:hI93XBmqTisBFMUTm0b8Fm+jr3Dg1NNxqwp+5A1VGuI=
-gopkg.in/yaml.v2 v2.2.2/go.mod h1:hI93XBmqTisBFMUTm0b8Fm+jr3Dg1NNxqwp+5A1VGuI=
-gopkg.in/yaml.v2 v2.2.4/go.mod h1:hI93XBmqTisBFMUTm0b8Fm+jr3Dg1NNxqwp+5A1VGuI=
-gopkg.in/yaml.v2 v2.2.5/go.mod h1:hI93XBmqTisBFMUTm0b8Fm+jr3Dg1NNxqwp+5A1VGuI=
gopkg.in/yaml.v3 v3.0.0-20200313102051-9f266ea9e77c/go.mod h1:K4uyk7z7BCEPqu6E+C64Yfv1cQ7kz7rIZviUmN+EgEM=
gopkg.in/yaml.v3 v3.0.1 h1:fxVm/GzAzEWqLHuvctI91KS9hhNmmWOoWu0XTYJS7CA=
gopkg.in/yaml.v3 v3.0.1/go.mod h1:K4uyk7z7BCEPqu6E+C64Yfv1cQ7kz7rIZviUmN+EgEM=
diff --git a/lib/github/github.go b/lib/github/github.go
index 4d8a42073..5d5ba0a96 100644
--- a/lib/github/github.go
+++ b/lib/github/github.go
@@ -3,9 +3,8 @@ package github
import (
"context"
"fmt"
- "net/url"
- "github.com/google/go-github/v76/github"
+ "github.com/google/go-github/v92/github"
)
type Client struct {
@@ -13,14 +12,14 @@ type Client struct {
}
func NewClient(api, token string) (*Client, error) {
- gh := github.NewClient(nil).WithAuthToken(token)
-
+ opts := []github.ClientOptionsFunc{github.WithAuthToken(token)}
if api != "" {
- u, err := url.Parse(api)
- if err != nil {
- return nil, err
- }
- gh.BaseURL = u
+ opts = append(opts, github.WithURLs(&api, nil))
+ }
+
+ gh, err := github.NewClient(opts...)
+ if err != nil {
+ return nil, err
}
return &Client{gh: gh}, nil
}
diff --git a/plugin/consul/plugin.go b/plugin/consul/plugin.go
index 615d4f7b2..b4b9931a1 100644
--- a/plugin/consul/plugin.go
+++ b/plugin/consul/plugin.go
@@ -5,7 +5,7 @@ import (
"io"
"os"
- "github.com/hashicorp/consul/api"
+ "github.com/hashicorp/consul/api/v2"
fmt "github.com/jhunt/go-ansi"
"github.com/shieldproject/shield/plugin"
diff --git a/plugin/swift/plugin.go b/plugin/swift/plugin.go
index 9d53f6e68..04128c015 100644
--- a/plugin/swift/plugin.go
+++ b/plugin/swift/plugin.go
@@ -4,13 +4,14 @@ package main
import (
"bufio"
+ "context"
"io/ioutil"
"os"
"strings"
"time"
fmt "github.com/jhunt/go-ansi"
- "github.com/ncw/swift"
+ "github.com/ncw/swift/v2"
"github.com/shieldproject/shield/plugin"
)
@@ -161,7 +162,9 @@ func (p SwiftPlugin) Store(endpoint plugin.ShieldEndpoint) (string, int64, error
return "", 0, err
}
- conn, err := swift.Connect()
+ ctx := context.Background()
+
+ conn, err := swift.Connect(ctx)
if err != nil {
return "", 0, err
}
@@ -175,7 +178,7 @@ func (p SwiftPlugin) Store(endpoint plugin.ShieldEndpoint) (string, int64, error
return "", 0, err
}
- if err := conn.ObjectPutBytes(swift.Container, path, contents, ""); err != nil {
+ if err := conn.ObjectPutBytes(ctx, swift.Container, path, contents, ""); err != nil {
return "", 0, err
}
@@ -188,12 +191,14 @@ func (p SwiftPlugin) Retrieve(endpoint plugin.ShieldEndpoint, file string) error
return err
}
- conn, err := swift.Connect()
+ ctx := context.Background()
+
+ conn, err := swift.Connect(ctx)
if err != nil {
return err
}
- contents, err := conn.ObjectGetBytes(swift.Container, file)
+ contents, err := conn.ObjectGetBytes(ctx, swift.Container, file)
if err != nil {
return err
}
@@ -211,12 +216,14 @@ func (p SwiftPlugin) Purge(endpoint plugin.ShieldEndpoint, file string) error {
return err
}
- conn, err := swift.Connect()
+ ctx := context.Background()
+
+ conn, err := swift.Connect(ctx)
if err != nil {
return err
}
- return conn.ObjectDelete(swift.Container, file)
+ return conn.ObjectDelete(ctx, swift.Container, file)
}
func getConnInfo(e plugin.ShieldEndpoint) (info *SwiftConnectionInfo, err error) {
@@ -271,7 +278,7 @@ func (info SwiftConnectionInfo) genBackupPath() string {
return path
}
-func (info SwiftConnectionInfo) Connect() (*swift.Connection, error) {
+func (info SwiftConnectionInfo) Connect(ctx context.Context) (*swift.Connection, error) {
conn := &swift.Connection{
UserName: info.Username,
ApiKey: info.Password,
@@ -280,7 +287,7 @@ func (info SwiftConnectionInfo) Connect() (*swift.Connection, error) {
Tenant: info.ProjectName,
}
- if err := conn.Authenticate(); err != nil {
+ if err := conn.Authenticate(ctx); err != nil {
return nil, err
}
diff --git a/vendor/cloud.google.com/go/auth/CHANGES.md b/vendor/cloud.google.com/go/auth/CHANGES.md
index 51c2683ef..a194a7ba5 100644
--- a/vendor/cloud.google.com/go/auth/CHANGES.md
+++ b/vendor/cloud.google.com/go/auth/CHANGES.md
@@ -1,5 +1,25 @@
# Changes
+## [0.24.0](https://github.com/googleapis/google-cloud-go/compare/auth/v0.23.3...auth/v0.24.0) (2026-09-23)
+
+
+### Features
+
+* **all:** Update supported go versions ([#20520](https://github.com/googleapis/google-cloud-go/issues/20520)) ([90413d3](https://github.com/googleapis/google-cloud-go/commit/90413d3e9d381ef4b92e3c496d98b023c5b2d8cc))
+
+
+### Bug Fixes
+
+* **auth:** Honor DisableAsyncRefresh and EarlyTokenRefresh consistently ([#20564](https://github.com/googleapis/google-cloud-go/issues/20564)) ([39f0ea5](https://github.com/googleapis/google-cloud-go/commit/39f0ea51dcbcae2bef1e8c900bdf2e675a19199c)), refs [#20563](https://github.com/googleapis/google-cloud-go/issues/20563)
+
+## [0.23.3](https://github.com/googleapis/google-cloud-go/compare/auth/v0.23.2...auth/v0.23.3) (2026-09-17)
+
+
+### Bug Fixes
+
+* Handle secureconnect helper failures gracefully ([c2794c6](https://github.com/googleapis/google-cloud-go/commit/c2794c6bdf267278489af42591f3c3549ae8fcba))
+* Handle secureconnect helper failures gracefully ([#20443](https://github.com/googleapis/google-cloud-go/issues/20443)) ([c2794c6](https://github.com/googleapis/google-cloud-go/commit/c2794c6bdf267278489af42591f3c3549ae8fcba))
+
## [0.23.2](https://github.com/googleapis/google-cloud-go/compare/auth/v0.23.1...auth/v0.23.2) (2026-08-20)
diff --git a/vendor/cloud.google.com/go/auth/auth.go b/vendor/cloud.google.com/go/auth/auth.go
index c6d801583..fd6a11ddf 100644
--- a/vendor/cloud.google.com/go/auth/auth.go
+++ b/vendor/cloud.google.com/go/auth/auth.go
@@ -386,7 +386,7 @@ func (c *cachedTokenProvider) tokenBlocking(ctx context.Context) (*Token, error)
c.mu.Lock()
defer c.mu.Unlock()
c.isRefreshErr = false
- if c.cachedToken.IsValid() || (!c.autoRefresh && !c.cachedToken.isEmpty()) {
+ if c.cachedToken.isValidWithEarlyExpiry(c.expireEarly) || (!c.autoRefresh && !c.cachedToken.isEmpty()) {
return c.cachedToken, nil
}
t, err := c.tp.Token(ctx)
diff --git a/vendor/cloud.google.com/go/auth/credentials/detect.go b/vendor/cloud.google.com/go/auth/credentials/detect.go
index 9ce369d79..f79cca4dc 100644
--- a/vendor/cloud.google.com/go/auth/credentials/detect.go
+++ b/vendor/cloud.google.com/go/auth/credentials/detect.go
@@ -458,16 +458,17 @@ func clientCredConfigFromJSON(b []byte, opts *DetectOptions) *auth.Options3LO {
}
}
return &auth.Options3LO{
- ClientID: c.ClientID,
- ClientSecret: c.ClientSecret,
- RedirectURL: c.RedirectURIs[0],
- Scopes: opts.scopes(),
- AuthURL: c.AuthURI,
- TokenURL: c.TokenURI,
- Client: opts.client(),
- Logger: opts.logger(),
- EarlyTokenExpiry: opts.EarlyTokenRefresh,
- AuthHandlerOpts: handleOpts,
+ ClientID: c.ClientID,
+ ClientSecret: c.ClientSecret,
+ RedirectURL: c.RedirectURIs[0],
+ Scopes: opts.scopes(),
+ AuthURL: c.AuthURI,
+ TokenURL: c.TokenURI,
+ Client: opts.client(),
+ Logger: opts.logger(),
+ EarlyTokenExpiry: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
+ AuthHandlerOpts: handleOpts,
// TODO(codyoss): refactor this out. We need to add in auto-detection
// for this use case.
AuthStyle: auth.StyleInParams,
diff --git a/vendor/cloud.google.com/go/auth/credentials/filetypes.go b/vendor/cloud.google.com/go/auth/credentials/filetypes.go
index a82995582..59932fc6d 100644
--- a/vendor/cloud.google.com/go/auth/credentials/filetypes.go
+++ b/vendor/cloud.google.com/go/auth/credentials/filetypes.go
@@ -109,7 +109,8 @@ func fileCredentials(b []byte, opts *DetectOptions) (*auth.Credentials, error) {
}
return auth.NewCredentials(&auth.CredentialsOptions{
TokenProvider: auth.NewCachedTokenProvider(tp, &auth.CachedTokenProviderOptions{
- ExpireEarly: opts.EarlyTokenRefresh,
+ ExpireEarly: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
}),
JSON: b,
ProjectIDProvider: internalauth.StaticCredentialsProperty(projectID),
@@ -172,16 +173,17 @@ func handleServiceAccount(f *credsfile.ServiceAccountFile, opts *DetectOptions)
func handleUserCredential(f *credsfile.UserCredentialsFile, opts *DetectOptions) (auth.TokenProvider, error) {
opts3LO := &auth.Options3LO{
- ClientID: f.ClientID,
- ClientSecret: f.ClientSecret,
- Scopes: opts.scopes(),
- AuthURL: googleAuthURL,
- TokenURL: opts.tokenURL(),
- AuthStyle: auth.StyleInParams,
- EarlyTokenExpiry: opts.EarlyTokenRefresh,
- RefreshToken: f.RefreshToken,
- Client: opts.client(),
- Logger: opts.logger(),
+ ClientID: f.ClientID,
+ ClientSecret: f.ClientSecret,
+ Scopes: opts.scopes(),
+ AuthURL: googleAuthURL,
+ TokenURL: opts.tokenURL(),
+ AuthStyle: auth.StyleInParams,
+ EarlyTokenExpiry: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
+ RefreshToken: f.RefreshToken,
+ Client: opts.client(),
+ Logger: opts.logger(),
}
return auth.New3LOTokenProvider(opts3LO)
}
@@ -199,6 +201,8 @@ func handleExternalAccount(f *credsfile.ExternalAccountFile, opts *DetectOptions
QuotaProjectID: f.QuotaProjectID,
Scopes: opts.scopes(),
WorkforcePoolUserProject: f.WorkforcePoolUserProject,
+ EarlyTokenRefresh: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
Client: opts.client(),
Logger: opts.logger(),
IsDefaultClient: opts.Client == nil,
@@ -243,15 +247,17 @@ func handleExternalAccount(f *credsfile.ExternalAccountFile, opts *DetectOptions
func handleExternalAccountAuthorizedUser(f *credsfile.ExternalAccountAuthorizedUserFile, opts *DetectOptions) (auth.TokenProvider, error) {
externalOpts := &externalaccountuser.Options{
- Audience: f.Audience,
- RefreshToken: f.RefreshToken,
- TokenURL: f.TokenURL,
- TokenInfoURL: f.TokenInfoURL,
- ClientID: f.ClientID,
- ClientSecret: f.ClientSecret,
- Scopes: opts.scopes(),
- Client: opts.client(),
- Logger: opts.logger(),
+ Audience: f.Audience,
+ RefreshToken: f.RefreshToken,
+ TokenURL: f.TokenURL,
+ TokenInfoURL: f.TokenInfoURL,
+ ClientID: f.ClientID,
+ ClientSecret: f.ClientSecret,
+ Scopes: opts.scopes(),
+ EarlyTokenRefresh: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
+ Client: opts.client(),
+ Logger: opts.logger(),
}
tp, err := externalaccountuser.NewTokenProvider(externalOpts)
if err != nil {
diff --git a/vendor/cloud.google.com/go/auth/credentials/internal/externalaccount/externalaccount.go b/vendor/cloud.google.com/go/auth/credentials/internal/externalaccount/externalaccount.go
index f4f49f175..ae38487fa 100644
--- a/vendor/cloud.google.com/go/auth/credentials/internal/externalaccount/externalaccount.go
+++ b/vendor/cloud.google.com/go/auth/credentials/internal/externalaccount/externalaccount.go
@@ -100,6 +100,13 @@ type Options struct {
// for AWS credentials. One of SubjectTokenProvider,
// AWSSecurityCredentialProvider or CredentialSource must be provided. Optional.
AwsSecurityCredentialsProvider AwsSecurityCredentialsProvider
+ // EarlyTokenRefresh configures how early before a token expires that it
+ // should be refreshed. If unset, the default value is 3 minutes and 45
+ // seconds. Optional.
+ EarlyTokenRefresh time.Duration
+ // DisableAsyncRefresh configures a synchronous workflow that refreshes
+ // stale tokens while blocking. The default is false. Optional.
+ DisableAsyncRefresh bool
// Client for token request.
Client *http.Client
// IsDefaultClient marks whether the client passed in is a default client that can be overriden.
@@ -249,8 +256,12 @@ func NewTokenProvider(opts *Options) (auth.TokenProvider, error) {
logger: logger,
}
+ cacheOpts := &auth.CachedTokenProviderOptions{
+ ExpireEarly: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
+ }
if opts.ServiceAccountImpersonationURL == "" {
- return auth.NewCachedTokenProvider(tp, nil), nil
+ return auth.NewCachedTokenProvider(tp, cacheOpts), nil
}
scopes := make([]string, len(opts.Scopes))
@@ -261,14 +272,14 @@ func NewTokenProvider(opts *Options) (auth.TokenProvider, error) {
Client: client,
URL: opts.ServiceAccountImpersonationURL,
Scopes: scopes,
- Tp: auth.NewCachedTokenProvider(tp, nil),
+ Tp: auth.NewCachedTokenProvider(tp, cacheOpts),
TokenLifetimeSeconds: opts.ServiceAccountImpersonationLifetimeSeconds,
Logger: logger,
})
if err != nil {
return nil, err
}
- return auth.NewCachedTokenProvider(imp, nil), nil
+ return auth.NewCachedTokenProvider(imp, cacheOpts), nil
}
type subjectTokenProvider interface {
diff --git a/vendor/cloud.google.com/go/auth/credentials/internal/externalaccountuser/externalaccountuser.go b/vendor/cloud.google.com/go/auth/credentials/internal/externalaccountuser/externalaccountuser.go
index ae39206e5..e4a34b1e5 100644
--- a/vendor/cloud.google.com/go/auth/credentials/internal/externalaccountuser/externalaccountuser.go
+++ b/vendor/cloud.google.com/go/auth/credentials/internal/externalaccountuser/externalaccountuser.go
@@ -51,6 +51,14 @@ type Options struct {
// Scopes contains the desired scopes for the returned access token.
Scopes []string
+ // EarlyTokenRefresh configures how early before a token expires that it
+ // should be refreshed. If unset, the default value is 3 minutes and 45
+ // seconds. Optional.
+ EarlyTokenRefresh time.Duration
+ // DisableAsyncRefresh configures a synchronous workflow that refreshes
+ // stale tokens while blocking. The default is false. Optional.
+ DisableAsyncRefresh bool
+
// Client for token request.
Client *http.Client
// Logger for logging.
@@ -71,7 +79,10 @@ func NewTokenProvider(opts *Options) (auth.TokenProvider, error) {
tp := &tokenProvider{
o: opts,
}
- return auth.NewCachedTokenProvider(tp, nil), nil
+ return auth.NewCachedTokenProvider(tp, &auth.CachedTokenProviderOptions{
+ ExpireEarly: opts.EarlyTokenRefresh,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
+ }), nil
}
type tokenProvider struct {
diff --git a/vendor/cloud.google.com/go/auth/internal/transport/cert/secureconnect_cert.go b/vendor/cloud.google.com/go/auth/internal/transport/cert/secureconnect_cert.go
index 738cb2161..206317404 100644
--- a/vendor/cloud.google.com/go/auth/internal/transport/cert/secureconnect_cert.go
+++ b/vendor/cloud.google.com/go/auth/internal/transport/cert/secureconnect_cert.go
@@ -76,9 +76,17 @@ func NewSecureConnectProvider(configFilePath string) (Provider, error) {
if err := validateMetadata(metadata); err != nil {
return nil, fmt.Errorf("cert: invalid config in %q: %w", configFilePath, err)
}
- return (&secureConnectSource{
+ source := &secureConnectSource{
metadata: metadata,
- }).getClientCertificate, nil
+ }
+ cert, err := source.getClientCertificate(nil)
+ if err != nil {
+ return nil, err
+ }
+ if cert == nil {
+ return nil, errSourceUnavailable
+ }
+ return source.getClientCertificate, nil
}
func validateMetadata(metadata secureConnectMetadata) error {
@@ -101,7 +109,9 @@ func (s *secureConnectSource) getClientCertificate(info *tls.CertificateRequestI
command := s.metadata.Cmd
data, err := exec.Command(command[0], command[1:]...).Output()
if err != nil {
- return nil, err
+ // Intentionally return nil, nil when the helper fails so the probe in
+ // NewSecureConnectProvider can recognize the source as unavailable.
+ return nil, nil
}
cert, err := tls.X509KeyPair(data, data)
if err != nil {
diff --git a/vendor/cloud.google.com/go/auth/internal/transport/transport.go b/vendor/cloud.google.com/go/auth/internal/transport/transport.go
index fb0a8a1e0..c4f4c26b7 100644
--- a/vendor/cloud.google.com/go/auth/internal/transport/transport.go
+++ b/vendor/cloud.google.com/go/auth/internal/transport/transport.go
@@ -67,15 +67,16 @@ func CloneDetectOptions(oldDo *credentials.DetectOptions) *credentials.DetectOpt
}
newDo := &credentials.DetectOptions{
// Simple types
- TokenBindingType: oldDo.TokenBindingType,
- Audience: oldDo.Audience,
- Subject: oldDo.Subject,
- EarlyTokenRefresh: oldDo.EarlyTokenRefresh,
- TokenURL: oldDo.TokenURL,
- STSAudience: oldDo.STSAudience,
- CredentialsFile: oldDo.CredentialsFile,
- UseSelfSignedJWT: oldDo.UseSelfSignedJWT,
- UniverseDomain: oldDo.UniverseDomain,
+ TokenBindingType: oldDo.TokenBindingType,
+ Audience: oldDo.Audience,
+ Subject: oldDo.Subject,
+ EarlyTokenRefresh: oldDo.EarlyTokenRefresh,
+ DisableAsyncRefresh: oldDo.DisableAsyncRefresh,
+ TokenURL: oldDo.TokenURL,
+ STSAudience: oldDo.STSAudience,
+ CredentialsFile: oldDo.CredentialsFile,
+ UseSelfSignedJWT: oldDo.UseSelfSignedJWT,
+ UniverseDomain: oldDo.UniverseDomain,
// These fields are pointer types that we just want to use exactly as
// the user set, copy the ref
diff --git a/vendor/cloud.google.com/go/auth/internal/version.go b/vendor/cloud.google.com/go/auth/internal/version.go
index 146f6c768..eda0ad9f8 100644
--- a/vendor/cloud.google.com/go/auth/internal/version.go
+++ b/vendor/cloud.google.com/go/auth/internal/version.go
@@ -17,4 +17,4 @@
package internal
// Version is the current tagged release of the library.
-const Version = "0.23.2"
+const Version = "0.24.0"
diff --git a/vendor/cloud.google.com/go/auth/oauth2adapt/CHANGES.md b/vendor/cloud.google.com/go/auth/oauth2adapt/CHANGES.md
index 42716752e..4332fc2a8 100644
--- a/vendor/cloud.google.com/go/auth/oauth2adapt/CHANGES.md
+++ b/vendor/cloud.google.com/go/auth/oauth2adapt/CHANGES.md
@@ -1,4 +1,11 @@
-# Changelog
+# Changes
+
+## [0.3.0](https://github.com/googleapis/google-cloud-go/compare/auth/oauth2adapt/v0.2.8...auth/oauth2adapt/v0.3.0) (2026-09-23)
+
+
+### Features
+
+* **all:** Update supported go versions ([#20520](https://github.com/googleapis/google-cloud-go/issues/20520)) ([90413d3](https://github.com/googleapis/google-cloud-go/commit/90413d3e9d381ef4b92e3c496d98b023c5b2d8cc))
## [0.2.8](https://github.com/googleapis/google-cloud-go/compare/auth/oauth2adapt/v0.2.7...auth/oauth2adapt/v0.2.8) (2025-03-17)
diff --git a/vendor/cloud.google.com/go/auth/threelegged.go b/vendor/cloud.google.com/go/auth/threelegged.go
index 07804dc16..9a9d02657 100644
--- a/vendor/cloud.google.com/go/auth/threelegged.go
+++ b/vendor/cloud.google.com/go/auth/threelegged.go
@@ -67,6 +67,9 @@ type Options3LO struct {
// refreshed. If not set the default value is 3 minutes and 45 seconds.
// Optional.
EarlyTokenExpiry time.Duration
+ // DisableAsyncRefresh configures a synchronous workflow that refreshes
+ // stale tokens while blocking. The default is false. Optional.
+ DisableAsyncRefresh bool
// AuthHandlerOpts provides a set of options for doing a
// 3-legged OAuth2 flow with a custom [AuthorizationHandler]. Optional.
@@ -192,7 +195,8 @@ func New3LOTokenProvider(opts *Options3LO) (TokenProvider, error) {
return new3LOTokenProviderWithAuthHandler(opts), nil
}
return NewCachedTokenProvider(&tokenProvider3LO{opts: opts, refreshToken: opts.RefreshToken, client: opts.client()}, &CachedTokenProviderOptions{
- ExpireEarly: opts.EarlyTokenExpiry,
+ ExpireEarly: opts.EarlyTokenExpiry,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
}), nil
}
@@ -211,7 +215,8 @@ type AuthorizationHandlerOptions struct {
func new3LOTokenProviderWithAuthHandler(opts *Options3LO) TokenProvider {
return NewCachedTokenProvider(&tokenProviderWithHandler{opts: opts, state: opts.AuthHandlerOpts.State}, &CachedTokenProviderOptions{
- ExpireEarly: opts.EarlyTokenExpiry,
+ ExpireEarly: opts.EarlyTokenExpiry,
+ DisableAsyncRefresh: opts.DisableAsyncRefresh,
})
}
diff --git a/vendor/cloud.google.com/go/compute/metadata/.repo-metadata.json b/vendor/cloud.google.com/go/compute/metadata/.repo-metadata.json
new file mode 100644
index 000000000..d64bf6cc1
--- /dev/null
+++ b/vendor/cloud.google.com/go/compute/metadata/.repo-metadata.json
@@ -0,0 +1,10 @@
+{
+ "api_shortname": "compute-metadata",
+ "client_documentation": "https://cloud.google.com/go/docs/reference/cloud.google.com/go/compute/latest/metadata",
+ "client_library_type": "manual",
+ "description": "Service Metadata API",
+ "distribution_name": "cloud.google.com/go/compute/metadata",
+ "language": "go",
+ "library_type": "CORE",
+ "release_level": "stable"
+}
\ No newline at end of file
diff --git a/vendor/cloud.google.com/go/compute/metadata/CHANGES.md b/vendor/cloud.google.com/go/compute/metadata/CHANGES.md
index e384683c5..f03d5cd38 100644
--- a/vendor/cloud.google.com/go/compute/metadata/CHANGES.md
+++ b/vendor/cloud.google.com/go/compute/metadata/CHANGES.md
@@ -1,5 +1,19 @@
# Changes
+## [0.10.0](https://github.com/googleapis/google-cloud-go/compare/compute/metadata/v0.9.1...compute/metadata/v0.10.0) (2026-09-23)
+
+
+### Features
+
+* **all:** Update supported go versions ([#20520](https://github.com/googleapis/google-cloud-go/issues/20520)) ([90413d3](https://github.com/googleapis/google-cloud-go/commit/90413d3e9d381ef4b92e3c496d98b023c5b2d8cc))
+
+## [0.9.1](https://github.com/googleapis/google-cloud-go/compare/compute/metadata/v0.9.0...compute/metadata/v0.9.1) (2026-09-17)
+
+
+### Bug Fixes
+
+* **compute/metadata:** Timeout initial metadata subscriber GET request ([#20488](https://github.com/googleapis/google-cloud-go/issues/20488)) ([f06f6b3](https://github.com/googleapis/google-cloud-go/commit/f06f6b35e4b7ae8b48a3f9d1715229fe81cb2ebd)), refs [#20487](https://github.com/googleapis/google-cloud-go/issues/20487)
+
## [0.9.0](https://github.com/googleapis/google-cloud-go/compare/compute/metadata/v0.8.4...compute/metadata/v0.9.0) (2025-09-24)
diff --git a/vendor/cloud.google.com/go/compute/metadata/metadata.go b/vendor/cloud.google.com/go/compute/metadata/metadata.go
index 6bd189166..918231e3b 100644
--- a/vendor/cloud.google.com/go/compute/metadata/metadata.go
+++ b/vendor/cloud.google.com/go/compute/metadata/metadata.go
@@ -889,7 +889,9 @@ func (c *Client) SubscribeWithContext(ctx context.Context, suffix string, fn fun
const failedSubscribeSleep = time.Second * 5
// First check to see if the metadata value exists at all.
- val, lastETag, err := c.getETagWithSubClient(ctx, suffix, true)
+ initCtx, cancel := context.WithTimeout(ctx, 5*time.Second)
+ val, lastETag, err := c.getETagWithSubClient(initCtx, suffix, true)
+ cancel()
if err != nil {
return err
}
diff --git a/vendor/github.com/Azure/go-ansiterm/csi_entry_state.go b/vendor/github.com/Azure/go-ansiterm/csi_entry_state.go
index bcbe00d0c..01c9519c3 100644
--- a/vendor/github.com/Azure/go-ansiterm/csi_entry_state.go
+++ b/vendor/github.com/Azure/go-ansiterm/csi_entry_state.go
@@ -26,7 +26,7 @@ func (csiState csiEntryState) Handle(b byte) (s state, e error) {
func (csiState csiEntryState) Transition(s state) error {
csiState.parser.logf("CsiEntry::Transition %s --> %s", csiState.Name(), s.Name())
- csiState.baseState.Transition(s)
+ _ = csiState.baseState.Transition(s)
switch s {
case csiState.parser.ground:
@@ -34,9 +34,9 @@ func (csiState csiEntryState) Transition(s state) error {
case csiState.parser.csiParam:
switch {
case sliceContains(csiParams, csiState.parser.context.currentChar):
- csiState.parser.collectParam()
+ _ = csiState.parser.collectParam()
case sliceContains(intermeds, csiState.parser.context.currentChar):
- csiState.parser.collectInter()
+ _ = csiState.parser.collectInter()
}
}
diff --git a/vendor/github.com/Azure/go-ansiterm/csi_param_state.go b/vendor/github.com/Azure/go-ansiterm/csi_param_state.go
index 7ed5e01c3..88146e6fe 100644
--- a/vendor/github.com/Azure/go-ansiterm/csi_param_state.go
+++ b/vendor/github.com/Azure/go-ansiterm/csi_param_state.go
@@ -16,8 +16,7 @@ func (csiState csiParamState) Handle(b byte) (s state, e error) {
case sliceContains(alphabetics, b):
return csiState.parser.ground, nil
case sliceContains(csiCollectables, b):
- csiState.parser.collectParam()
- return csiState, nil
+ return csiState, csiState.parser.collectParam()
case sliceContains(executors, b):
return csiState, csiState.parser.execute()
}
@@ -27,7 +26,7 @@ func (csiState csiParamState) Handle(b byte) (s state, e error) {
func (csiState csiParamState) Transition(s state) error {
csiState.parser.logf("CsiParam::Transition %s --> %s", csiState.Name(), s.Name())
- csiState.baseState.Transition(s)
+ _ = csiState.baseState.Transition(s)
switch s {
case csiState.parser.ground:
diff --git a/vendor/github.com/Azure/go-ansiterm/escape_intermediate_state.go b/vendor/github.com/Azure/go-ansiterm/escape_intermediate_state.go
index 1c719db9e..88429690f 100644
--- a/vendor/github.com/Azure/go-ansiterm/escape_intermediate_state.go
+++ b/vendor/github.com/Azure/go-ansiterm/escape_intermediate_state.go
@@ -25,7 +25,7 @@ func (escState escapeIntermediateState) Handle(b byte) (s state, e error) {
func (escState escapeIntermediateState) Transition(s state) error {
escState.parser.logf("escapeIntermediateState::Transition %s --> %s", escState.Name(), s.Name())
- escState.baseState.Transition(s)
+ _ = escState.baseState.Transition(s)
switch s {
case escState.parser.ground:
diff --git a/vendor/github.com/Azure/go-ansiterm/escape_state.go b/vendor/github.com/Azure/go-ansiterm/escape_state.go
index 6390abd23..854e3812a 100644
--- a/vendor/github.com/Azure/go-ansiterm/escape_state.go
+++ b/vendor/github.com/Azure/go-ansiterm/escape_state.go
@@ -29,7 +29,7 @@ func (escState escapeState) Handle(b byte) (s state, e error) {
func (escState escapeState) Transition(s state) error {
escState.parser.logf("Escape::Transition %s --> %s", escState.Name(), s.Name())
- escState.baseState.Transition(s)
+ _ = escState.baseState.Transition(s)
switch s {
case escState.parser.ground:
diff --git a/vendor/github.com/Azure/go-ansiterm/parser.go b/vendor/github.com/Azure/go-ansiterm/parser.go
index 03cec7ada..2e8ef80fb 100644
--- a/vendor/github.com/Azure/go-ansiterm/parser.go
+++ b/vendor/github.com/Azure/go-ansiterm/parser.go
@@ -113,16 +113,13 @@ func (ap *AnsiParser) handle(b byte) error {
if newState == nil {
ap.logf("WARNING: newState is nil")
- return errors.New("New state of 'nil' is invalid.")
+ return errors.New("new state of 'nil' is invalid")
}
- if newState != ap.currState {
- if err := ap.changeState(newState); err != nil {
- return err
- }
+ if newState == ap.currState {
+ return nil
}
-
- return nil
+ return ap.changeState(newState)
}
func (ap *AnsiParser) changeState(newState state) error {
@@ -136,7 +133,7 @@ func (ap *AnsiParser) changeState(newState state) error {
// Perform transition action
if err := ap.currState.Transition(newState); err != nil {
- ap.logf("Transition from '%s' to '%s' failed with: '%v'", ap.currState.Name(), newState.Name, err)
+ ap.logf("Transition from '%s' to '%s' failed with: '%v'", ap.currState.Name(), newState.Name(), err)
return err
}
diff --git a/vendor/github.com/Azure/go-ansiterm/parser_action_helpers.go b/vendor/github.com/Azure/go-ansiterm/parser_action_helpers.go
index de0a1f9cd..dc001532a 100644
--- a/vendor/github.com/Azure/go-ansiterm/parser_action_helpers.go
+++ b/vendor/github.com/Azure/go-ansiterm/parser_action_helpers.go
@@ -4,9 +4,9 @@ import (
"strconv"
)
-func parseParams(bytes []byte) ([]string, error) {
- paramBuff := make([]byte, 0, 0)
- params := []string{}
+func parseParams(bytes []byte) []string {
+ var paramBuff []byte
+ var params []string
for _, v := range bytes {
if v == ';' {
@@ -14,7 +14,7 @@ func parseParams(bytes []byte) ([]string, error) {
// Completed parameter, append it to the list
s := string(paramBuff)
params = append(params, s)
- paramBuff = make([]byte, 0, 0)
+ paramBuff = paramBuff[:0]
}
} else {
paramBuff = append(paramBuff, v)
@@ -27,11 +27,7 @@ func parseParams(bytes []byte) ([]string, error) {
params = append(params, s)
}
- return params, nil
-}
-
-func parseCmd(context ansiContext) (string, error) {
- return string(context.currentChar), nil
+ return params
}
func getInt(params []string, dflt int) int {
diff --git a/vendor/github.com/Azure/go-ansiterm/parser_actions.go b/vendor/github.com/Azure/go-ansiterm/parser_actions.go
index 0bb5e51e9..2aee10159 100644
--- a/vendor/github.com/Azure/go-ansiterm/parser_actions.go
+++ b/vendor/github.com/Azure/go-ansiterm/parser_actions.go
@@ -15,10 +15,9 @@ func (ap *AnsiParser) collectInter() error {
}
func (ap *AnsiParser) escDispatch() error {
- cmd, _ := parseCmd(*ap.context)
- intermeds := ap.context.interBuffer
+ cmd := string(ap.context.currentChar)
ap.logf("escDispatch currentChar: %#x", ap.context.currentChar)
- ap.logf("escDispatch: %v(%v)", cmd, intermeds)
+ ap.logf("escDispatch: %s(%q)", cmd, string(ap.context.interBuffer))
switch cmd {
case "D": // IND
@@ -31,14 +30,14 @@ func (ap *AnsiParser) escDispatch() error {
return err
case "M": // RI
return ap.eventHandler.RI()
+ default:
+ return nil
}
-
- return nil
}
func (ap *AnsiParser) csiDispatch() error {
- cmd, _ := parseCmd(*ap.context)
- params, _ := parseParams(ap.context.paramBuffer)
+ cmd := string(ap.context.currentChar)
+ params := parseParams(ap.context.paramBuffer)
ap.logf("Parsed params: %v with length: %d", params, len(params))
ap.logf("csiDispatch: %v(%v)", cmd, params)
@@ -109,9 +108,8 @@ func (ap *AnsiParser) print() error {
return ap.eventHandler.Print(ap.context.currentChar)
}
-func (ap *AnsiParser) clear() error {
+func (ap *AnsiParser) clear() {
ap.context = &ansiContext{}
- return nil
}
func (ap *AnsiParser) execute() error {
diff --git a/vendor/github.com/Azure/go-ansiterm/states.go b/vendor/github.com/Azure/go-ansiterm/states.go
index f2ea1fcd1..cf7269226 100644
--- a/vendor/github.com/Azure/go-ansiterm/states.go
+++ b/vendor/github.com/Azure/go-ansiterm/states.go
@@ -1,7 +1,5 @@
package ansiterm
-type stateID int
-
type state interface {
Enter() error
Exit() error
diff --git a/vendor/github.com/Azure/go-ansiterm/utilities.go b/vendor/github.com/Azure/go-ansiterm/utilities.go
index 392114493..d94dd3a34 100644
--- a/vendor/github.com/Azure/go-ansiterm/utilities.go
+++ b/vendor/github.com/Azure/go-ansiterm/utilities.go
@@ -1,9 +1,5 @@
package ansiterm
-import (
- "strconv"
-)
-
func sliceContains(bytes []byte, b byte) bool {
for _, v := range bytes {
if v == b {
@@ -13,9 +9,3 @@ func sliceContains(bytes []byte, b byte) bool {
return false
}
-
-func convertBytesToInteger(bytes []byte) int {
- s := string(bytes)
- i, _ := strconv.Atoi(s)
- return i
-}
diff --git a/vendor/github.com/Azure/go-ansiterm/winterm/ansi.go b/vendor/github.com/Azure/go-ansiterm/winterm/ansi.go
index 5599082ae..c6cc027a7 100644
--- a/vendor/github.com/Azure/go-ansiterm/winterm/ansi.go
+++ b/vendor/github.com/Azure/go-ansiterm/winterm/ansi.go
@@ -5,12 +5,9 @@ package winterm
import (
"fmt"
"os"
- "strconv"
- "strings"
"syscall"
- "github.com/Azure/go-ansiterm"
- windows "golang.org/x/sys/windows"
+ "golang.org/x/sys/windows"
)
// Windows keyboard constants
@@ -55,100 +52,6 @@ const (
ENHANCED_KEY = 0x0100
)
-type ansiCommand struct {
- CommandBytes []byte
- Command string
- Parameters []string
- IsSpecial bool
-}
-
-func newAnsiCommand(command []byte) *ansiCommand {
-
- if isCharacterSelectionCmdChar(command[1]) {
- // Is Character Set Selection commands
- return &ansiCommand{
- CommandBytes: command,
- Command: string(command),
- IsSpecial: true,
- }
- }
-
- // last char is command character
- lastCharIndex := len(command) - 1
-
- ac := &ansiCommand{
- CommandBytes: command,
- Command: string(command[lastCharIndex]),
- IsSpecial: false,
- }
-
- // more than a single escape
- if lastCharIndex != 0 {
- start := 1
- // skip if double char escape sequence
- if command[0] == ansiterm.ANSI_ESCAPE_PRIMARY && command[1] == ansiterm.ANSI_ESCAPE_SECONDARY {
- start++
- }
- // convert this to GetNextParam method
- ac.Parameters = strings.Split(string(command[start:lastCharIndex]), ansiterm.ANSI_PARAMETER_SEP)
- }
-
- return ac
-}
-
-func (ac *ansiCommand) paramAsSHORT(index int, defaultValue int16) int16 {
- if index < 0 || index >= len(ac.Parameters) {
- return defaultValue
- }
-
- param, err := strconv.ParseInt(ac.Parameters[index], 10, 16)
- if err != nil {
- return defaultValue
- }
-
- return int16(param)
-}
-
-func (ac *ansiCommand) String() string {
- return fmt.Sprintf("0x%v \"%v\" (\"%v\")",
- bytesToHex(ac.CommandBytes),
- ac.Command,
- strings.Join(ac.Parameters, "\",\""))
-}
-
-// isAnsiCommandChar returns true if the passed byte falls within the range of ANSI commands.
-// See http://manpages.ubuntu.com/manpages/intrepid/man4/console_codes.4.html.
-func isAnsiCommandChar(b byte) bool {
- switch {
- case ansiterm.ANSI_COMMAND_FIRST <= b && b <= ansiterm.ANSI_COMMAND_LAST && b != ansiterm.ANSI_ESCAPE_SECONDARY:
- return true
- case b == ansiterm.ANSI_CMD_G1 || b == ansiterm.ANSI_CMD_OSC || b == ansiterm.ANSI_CMD_DECPAM || b == ansiterm.ANSI_CMD_DECPNM:
- // non-CSI escape sequence terminator
- return true
- case b == ansiterm.ANSI_CMD_STR_TERM || b == ansiterm.ANSI_BEL:
- // String escape sequence terminator
- return true
- }
- return false
-}
-
-func isXtermOscSequence(command []byte, current byte) bool {
- return (len(command) >= 2 && command[0] == ansiterm.ANSI_ESCAPE_PRIMARY && command[1] == ansiterm.ANSI_CMD_OSC && current != ansiterm.ANSI_BEL)
-}
-
-func isCharacterSelectionCmdChar(b byte) bool {
- return (b == ansiterm.ANSI_CMD_G0 || b == ansiterm.ANSI_CMD_G1 || b == ansiterm.ANSI_CMD_G2 || b == ansiterm.ANSI_CMD_G3)
-}
-
-// bytesToHex converts a slice of bytes to a human-readable string.
-func bytesToHex(b []byte) string {
- hex := make([]string, len(b))
- for i, ch := range b {
- hex[i] = fmt.Sprintf("%X", ch)
- }
- return strings.Join(hex, "")
-}
-
// ensureInRange adjusts the passed value, if necessary, to ensure it is within
// the passed min / max range.
func ensureInRange(n int16, min int16, max int16) int16 {
diff --git a/vendor/github.com/armon/go-metrics/.gitignore b/vendor/github.com/armon/go-metrics/.gitignore
deleted file mode 100644
index e5750f572..000000000
--- a/vendor/github.com/armon/go-metrics/.gitignore
+++ /dev/null
@@ -1,26 +0,0 @@
-# Compiled Object files, Static and Dynamic libs (Shared Objects)
-*.o
-*.a
-*.so
-
-# Folders
-_obj
-_test
-
-# Architecture specific extensions/prefixes
-*.[568vq]
-[568vq].out
-
-*.cgo1.go
-*.cgo2.c
-_cgo_defun.c
-_cgo_gotypes.go
-_cgo_export.*
-
-_testmain.go
-
-*.exe
-
-/metrics.out
-
-.idea
diff --git a/vendor/github.com/armon/go-metrics/.travis.yml b/vendor/github.com/armon/go-metrics/.travis.yml
deleted file mode 100644
index 87d230c8d..000000000
--- a/vendor/github.com/armon/go-metrics/.travis.yml
+++ /dev/null
@@ -1,13 +0,0 @@
-language: go
-
-go:
- - "1.x"
-
-env:
- - GO111MODULE=on
-
-install:
- - go get ./...
-
-script:
- - go test ./...
diff --git a/vendor/github.com/armon/go-metrics/LICENSE b/vendor/github.com/armon/go-metrics/LICENSE
deleted file mode 100644
index 106569e54..000000000
--- a/vendor/github.com/armon/go-metrics/LICENSE
+++ /dev/null
@@ -1,20 +0,0 @@
-The MIT License (MIT)
-
-Copyright (c) 2013 Armon Dadgar
-
-Permission is hereby granted, free of charge, to any person obtaining a copy of
-this software and associated documentation files (the "Software"), to deal in
-the Software without restriction, including without limitation the rights to
-use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of
-the Software, and to permit persons to whom the Software is furnished to do so,
-subject to the following conditions:
-
-The above copyright notice and this permission notice shall be included in all
-copies or substantial portions of the Software.
-
-THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
-IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS
-FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR
-COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER
-IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN
-CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
diff --git a/vendor/github.com/armon/go-metrics/README.md b/vendor/github.com/armon/go-metrics/README.md
deleted file mode 100644
index aa73348c0..000000000
--- a/vendor/github.com/armon/go-metrics/README.md
+++ /dev/null
@@ -1,91 +0,0 @@
-go-metrics
-==========
-
-This library provides a `metrics` package which can be used to instrument code,
-expose application metrics, and profile runtime performance in a flexible manner.
-
-Current API: [](https://godoc.org/github.com/armon/go-metrics)
-
-Sinks
------
-
-The `metrics` package makes use of a `MetricSink` interface to support delivery
-to any type of backend. Currently the following sinks are provided:
-
-* StatsiteSink : Sinks to a [statsite](https://github.com/armon/statsite/) instance (TCP)
-* StatsdSink: Sinks to a [StatsD](https://github.com/etsy/statsd/) / statsite instance (UDP)
-* PrometheusSink: Sinks to a [Prometheus](http://prometheus.io/) metrics endpoint (exposed via HTTP for scrapes)
-* InmemSink : Provides in-memory aggregation, can be used to export stats
-* FanoutSink : Sinks to multiple sinks. Enables writing to multiple statsite instances for example.
-* BlackholeSink : Sinks to nowhere
-
-In addition to the sinks, the `InmemSignal` can be used to catch a signal,
-and dump a formatted output of recent metrics. For example, when a process gets
-a SIGUSR1, it can dump to stderr recent performance metrics for debugging.
-
-Labels
-------
-
-Most metrics do have an equivalent ending with `WithLabels`, such methods
-allow to push metrics with labels and use some features of underlying Sinks
-(ex: translated into Prometheus labels).
-
-Since some of these labels may increase greatly cardinality of metrics, the
-library allow to filter labels using a blacklist/whitelist filtering system
-which is global to all metrics.
-
-* If `Config.AllowedLabels` is not nil, then only labels specified in this value will be sent to underlying Sink, otherwise, all labels are sent by default.
-* If `Config.BlockedLabels` is not nil, any label specified in this value will not be sent to underlying Sinks.
-
-By default, both `Config.AllowedLabels` and `Config.BlockedLabels` are nil, meaning that
-no tags are filetered at all, but it allow to a user to globally block some tags with high
-cardinality at application level.
-
-Examples
---------
-
-Here is an example of using the package:
-
-```go
-func SlowMethod() {
- // Profiling the runtime of a method
- defer metrics.MeasureSince([]string{"SlowMethod"}, time.Now())
-}
-
-// Configure a statsite sink as the global metrics sink
-sink, _ := metrics.NewStatsiteSink("statsite:8125")
-metrics.NewGlobal(metrics.DefaultConfig("service-name"), sink)
-
-// Emit a Key/Value pair
-metrics.EmitKey([]string{"questions", "meaning of life"}, 42)
-```
-
-Here is an example of setting up a signal handler:
-
-```go
-// Setup the inmem sink and signal handler
-inm := metrics.NewInmemSink(10*time.Second, time.Minute)
-sig := metrics.DefaultInmemSignal(inm)
-metrics.NewGlobal(metrics.DefaultConfig("service-name"), inm)
-
-// Run some code
-inm.SetGauge([]string{"foo"}, 42)
-inm.EmitKey([]string{"bar"}, 30)
-
-inm.IncrCounter([]string{"baz"}, 42)
-inm.IncrCounter([]string{"baz"}, 1)
-inm.IncrCounter([]string{"baz"}, 80)
-
-inm.AddSample([]string{"method", "wow"}, 42)
-inm.AddSample([]string{"method", "wow"}, 100)
-inm.AddSample([]string{"method", "wow"}, 22)
-
-....
-```
-
-When a signal comes in, output like the following will be dumped to stderr:
-
- [2014-01-28 14:57:33.04 -0800 PST][G] 'foo': 42.000
- [2014-01-28 14:57:33.04 -0800 PST][P] 'bar': 30.000
- [2014-01-28 14:57:33.04 -0800 PST][C] 'baz': Count: 3 Min: 1.000 Mean: 41.000 Max: 80.000 Stddev: 39.509
- [2014-01-28 14:57:33.04 -0800 PST][S] 'method.wow': Count: 3 Min: 22.000 Mean: 54.667 Max: 100.000 Stddev: 40.513
\ No newline at end of file
diff --git a/vendor/github.com/armon/go-metrics/const_unix.go b/vendor/github.com/armon/go-metrics/const_unix.go
deleted file mode 100644
index 31098dd57..000000000
--- a/vendor/github.com/armon/go-metrics/const_unix.go
+++ /dev/null
@@ -1,12 +0,0 @@
-// +build !windows
-
-package metrics
-
-import (
- "syscall"
-)
-
-const (
- // DefaultSignal is used with DefaultInmemSignal
- DefaultSignal = syscall.SIGUSR1
-)
diff --git a/vendor/github.com/armon/go-metrics/const_windows.go b/vendor/github.com/armon/go-metrics/const_windows.go
deleted file mode 100644
index 38136af3e..000000000
--- a/vendor/github.com/armon/go-metrics/const_windows.go
+++ /dev/null
@@ -1,13 +0,0 @@
-// +build windows
-
-package metrics
-
-import (
- "syscall"
-)
-
-const (
- // DefaultSignal is used with DefaultInmemSignal
- // Windows has no SIGUSR1, use SIGBREAK
- DefaultSignal = syscall.Signal(21)
-)
diff --git a/vendor/github.com/armon/go-metrics/inmem.go b/vendor/github.com/armon/go-metrics/inmem.go
deleted file mode 100644
index 7c427aca9..000000000
--- a/vendor/github.com/armon/go-metrics/inmem.go
+++ /dev/null
@@ -1,339 +0,0 @@
-package metrics
-
-import (
- "bytes"
- "fmt"
- "math"
- "net/url"
- "strings"
- "sync"
- "time"
-)
-
-var spaceReplacer = strings.NewReplacer(" ", "_")
-
-// InmemSink provides a MetricSink that does in-memory aggregation
-// without sending metrics over a network. It can be embedded within
-// an application to provide profiling information.
-type InmemSink struct {
- // How long is each aggregation interval
- interval time.Duration
-
- // Retain controls how many metrics interval we keep
- retain time.Duration
-
- // maxIntervals is the maximum length of intervals.
- // It is retain / interval.
- maxIntervals int
-
- // intervals is a slice of the retained intervals
- intervals []*IntervalMetrics
- intervalLock sync.RWMutex
-
- rateDenom float64
-}
-
-// IntervalMetrics stores the aggregated metrics
-// for a specific interval
-type IntervalMetrics struct {
- sync.RWMutex
-
- // The start time of the interval
- Interval time.Time
-
- // Gauges maps the key to the last set value
- Gauges map[string]GaugeValue
-
- // Points maps the string to the list of emitted values
- // from EmitKey
- Points map[string][]float32
-
- // Counters maps the string key to a sum of the counter
- // values
- Counters map[string]SampledValue
-
- // Samples maps the key to an AggregateSample,
- // which has the rolled up view of a sample
- Samples map[string]SampledValue
-
- // done is closed when this interval has ended, and a new IntervalMetrics
- // has been created to receive any future metrics.
- done chan struct{}
-}
-
-// NewIntervalMetrics creates a new IntervalMetrics for a given interval
-func NewIntervalMetrics(intv time.Time) *IntervalMetrics {
- return &IntervalMetrics{
- Interval: intv,
- Gauges: make(map[string]GaugeValue),
- Points: make(map[string][]float32),
- Counters: make(map[string]SampledValue),
- Samples: make(map[string]SampledValue),
- done: make(chan struct{}),
- }
-}
-
-// AggregateSample is used to hold aggregate metrics
-// about a sample
-type AggregateSample struct {
- Count int // The count of emitted pairs
- Rate float64 // The values rate per time unit (usually 1 second)
- Sum float64 // The sum of values
- SumSq float64 `json:"-"` // The sum of squared values
- Min float64 // Minimum value
- Max float64 // Maximum value
- LastUpdated time.Time `json:"-"` // When value was last updated
-}
-
-// Computes a Stddev of the values
-func (a *AggregateSample) Stddev() float64 {
- num := (float64(a.Count) * a.SumSq) - math.Pow(a.Sum, 2)
- div := float64(a.Count * (a.Count - 1))
- if div == 0 {
- return 0
- }
- return math.Sqrt(num / div)
-}
-
-// Computes a mean of the values
-func (a *AggregateSample) Mean() float64 {
- if a.Count == 0 {
- return 0
- }
- return a.Sum / float64(a.Count)
-}
-
-// Ingest is used to update a sample
-func (a *AggregateSample) Ingest(v float64, rateDenom float64) {
- a.Count++
- a.Sum += v
- a.SumSq += (v * v)
- if v < a.Min || a.Count == 1 {
- a.Min = v
- }
- if v > a.Max || a.Count == 1 {
- a.Max = v
- }
- a.Rate = float64(a.Sum) / rateDenom
- a.LastUpdated = time.Now()
-}
-
-func (a *AggregateSample) String() string {
- if a.Count == 0 {
- return "Count: 0"
- } else if a.Stddev() == 0 {
- return fmt.Sprintf("Count: %d Sum: %0.3f LastUpdated: %s", a.Count, a.Sum, a.LastUpdated)
- } else {
- return fmt.Sprintf("Count: %d Min: %0.3f Mean: %0.3f Max: %0.3f Stddev: %0.3f Sum: %0.3f LastUpdated: %s",
- a.Count, a.Min, a.Mean(), a.Max, a.Stddev(), a.Sum, a.LastUpdated)
- }
-}
-
-// NewInmemSinkFromURL creates an InmemSink from a URL. It is used
-// (and tested) from NewMetricSinkFromURL.
-func NewInmemSinkFromURL(u *url.URL) (MetricSink, error) {
- params := u.Query()
-
- interval, err := time.ParseDuration(params.Get("interval"))
- if err != nil {
- return nil, fmt.Errorf("Bad 'interval' param: %s", err)
- }
-
- retain, err := time.ParseDuration(params.Get("retain"))
- if err != nil {
- return nil, fmt.Errorf("Bad 'retain' param: %s", err)
- }
-
- return NewInmemSink(interval, retain), nil
-}
-
-// NewInmemSink is used to construct a new in-memory sink.
-// Uses an aggregation interval and maximum retention period.
-func NewInmemSink(interval, retain time.Duration) *InmemSink {
- rateTimeUnit := time.Second
- i := &InmemSink{
- interval: interval,
- retain: retain,
- maxIntervals: int(retain / interval),
- rateDenom: float64(interval.Nanoseconds()) / float64(rateTimeUnit.Nanoseconds()),
- }
- i.intervals = make([]*IntervalMetrics, 0, i.maxIntervals)
- return i
-}
-
-func (i *InmemSink) SetGauge(key []string, val float32) {
- i.SetGaugeWithLabels(key, val, nil)
-}
-
-func (i *InmemSink) SetGaugeWithLabels(key []string, val float32, labels []Label) {
- k, name := i.flattenKeyLabels(key, labels)
- intv := i.getInterval()
-
- intv.Lock()
- defer intv.Unlock()
- intv.Gauges[k] = GaugeValue{Name: name, Value: val, Labels: labels}
-}
-
-func (i *InmemSink) EmitKey(key []string, val float32) {
- k := i.flattenKey(key)
- intv := i.getInterval()
-
- intv.Lock()
- defer intv.Unlock()
- vals := intv.Points[k]
- intv.Points[k] = append(vals, val)
-}
-
-func (i *InmemSink) IncrCounter(key []string, val float32) {
- i.IncrCounterWithLabels(key, val, nil)
-}
-
-func (i *InmemSink) IncrCounterWithLabels(key []string, val float32, labels []Label) {
- k, name := i.flattenKeyLabels(key, labels)
- intv := i.getInterval()
-
- intv.Lock()
- defer intv.Unlock()
-
- agg, ok := intv.Counters[k]
- if !ok {
- agg = SampledValue{
- Name: name,
- AggregateSample: &AggregateSample{},
- Labels: labels,
- }
- intv.Counters[k] = agg
- }
- agg.Ingest(float64(val), i.rateDenom)
-}
-
-func (i *InmemSink) AddSample(key []string, val float32) {
- i.AddSampleWithLabels(key, val, nil)
-}
-
-func (i *InmemSink) AddSampleWithLabels(key []string, val float32, labels []Label) {
- k, name := i.flattenKeyLabels(key, labels)
- intv := i.getInterval()
-
- intv.Lock()
- defer intv.Unlock()
-
- agg, ok := intv.Samples[k]
- if !ok {
- agg = SampledValue{
- Name: name,
- AggregateSample: &AggregateSample{},
- Labels: labels,
- }
- intv.Samples[k] = agg
- }
- agg.Ingest(float64(val), i.rateDenom)
-}
-
-// Data is used to retrieve all the aggregated metrics
-// Intervals may be in use, and a read lock should be acquired
-func (i *InmemSink) Data() []*IntervalMetrics {
- // Get the current interval, forces creation
- i.getInterval()
-
- i.intervalLock.RLock()
- defer i.intervalLock.RUnlock()
-
- n := len(i.intervals)
- intervals := make([]*IntervalMetrics, n)
-
- copy(intervals[:n-1], i.intervals[:n-1])
- current := i.intervals[n-1]
-
- // make its own copy for current interval
- intervals[n-1] = &IntervalMetrics{}
- copyCurrent := intervals[n-1]
- current.RLock()
- *copyCurrent = *current
- // RWMutex is not safe to copy, so create a new instance on the copy
- copyCurrent.RWMutex = sync.RWMutex{}
-
- copyCurrent.Gauges = make(map[string]GaugeValue, len(current.Gauges))
- for k, v := range current.Gauges {
- copyCurrent.Gauges[k] = v
- }
- // saved values will be not change, just copy its link
- copyCurrent.Points = make(map[string][]float32, len(current.Points))
- for k, v := range current.Points {
- copyCurrent.Points[k] = v
- }
- copyCurrent.Counters = make(map[string]SampledValue, len(current.Counters))
- for k, v := range current.Counters {
- copyCurrent.Counters[k] = v.deepCopy()
- }
- copyCurrent.Samples = make(map[string]SampledValue, len(current.Samples))
- for k, v := range current.Samples {
- copyCurrent.Samples[k] = v.deepCopy()
- }
- current.RUnlock()
-
- return intervals
-}
-
-// getInterval returns the current interval. A new interval is created if no
-// previous interval exists, or if the current time is beyond the window for the
-// current interval.
-func (i *InmemSink) getInterval() *IntervalMetrics {
- intv := time.Now().Truncate(i.interval)
-
- // Attempt to return the existing interval first, because it only requires
- // a read lock.
- i.intervalLock.RLock()
- n := len(i.intervals)
- if n > 0 && i.intervals[n-1].Interval == intv {
- defer i.intervalLock.RUnlock()
- return i.intervals[n-1]
- }
- i.intervalLock.RUnlock()
-
- i.intervalLock.Lock()
- defer i.intervalLock.Unlock()
-
- // Re-check for an existing interval now that the lock is re-acquired.
- n = len(i.intervals)
- if n > 0 && i.intervals[n-1].Interval == intv {
- return i.intervals[n-1]
- }
-
- current := NewIntervalMetrics(intv)
- i.intervals = append(i.intervals, current)
- if n > 0 {
- close(i.intervals[n-1].done)
- }
-
- n++
- // Prune old intervals if the count exceeds the max.
- if n >= i.maxIntervals {
- copy(i.intervals[0:], i.intervals[n-i.maxIntervals:])
- i.intervals = i.intervals[:i.maxIntervals]
- }
- return current
-}
-
-// Flattens the key for formatting, removes spaces
-func (i *InmemSink) flattenKey(parts []string) string {
- buf := &bytes.Buffer{}
-
- joined := strings.Join(parts, ".")
-
- spaceReplacer.WriteString(buf, joined)
-
- return buf.String()
-}
-
-// Flattens the key for formatting along with its labels, removes spaces
-func (i *InmemSink) flattenKeyLabels(parts []string, labels []Label) (string, string) {
- key := i.flattenKey(parts)
- buf := bytes.NewBufferString(key)
-
- for _, label := range labels {
- spaceReplacer.WriteString(buf, fmt.Sprintf(";%s=%s", label.Name, label.Value))
- }
-
- return buf.String(), key
-}
diff --git a/vendor/github.com/armon/go-metrics/inmem_endpoint.go b/vendor/github.com/armon/go-metrics/inmem_endpoint.go
deleted file mode 100644
index 24eefa963..000000000
--- a/vendor/github.com/armon/go-metrics/inmem_endpoint.go
+++ /dev/null
@@ -1,162 +0,0 @@
-package metrics
-
-import (
- "context"
- "fmt"
- "net/http"
- "sort"
- "time"
-)
-
-// MetricsSummary holds a roll-up of metrics info for a given interval
-type MetricsSummary struct {
- Timestamp string
- Gauges []GaugeValue
- Points []PointValue
- Counters []SampledValue
- Samples []SampledValue
-}
-
-type GaugeValue struct {
- Name string
- Hash string `json:"-"`
- Value float32
-
- Labels []Label `json:"-"`
- DisplayLabels map[string]string `json:"Labels"`
-}
-
-type PointValue struct {
- Name string
- Points []float32
-}
-
-type SampledValue struct {
- Name string
- Hash string `json:"-"`
- *AggregateSample
- Mean float64
- Stddev float64
-
- Labels []Label `json:"-"`
- DisplayLabels map[string]string `json:"Labels"`
-}
-
-// deepCopy allocates a new instance of AggregateSample
-func (source *SampledValue) deepCopy() SampledValue {
- dest := *source
- if source.AggregateSample != nil {
- dest.AggregateSample = &AggregateSample{}
- *dest.AggregateSample = *source.AggregateSample
- }
- return dest
-}
-
-// DisplayMetrics returns a summary of the metrics from the most recent finished interval.
-func (i *InmemSink) DisplayMetrics(resp http.ResponseWriter, req *http.Request) (interface{}, error) {
- data := i.Data()
-
- var interval *IntervalMetrics
- n := len(data)
- switch {
- case n == 0:
- return nil, fmt.Errorf("no metric intervals have been initialized yet")
- case n == 1:
- // Show the current interval if it's all we have
- interval = data[0]
- default:
- // Show the most recent finished interval if we have one
- interval = data[n-2]
- }
-
- return newMetricSummaryFromInterval(interval), nil
-}
-
-func newMetricSummaryFromInterval(interval *IntervalMetrics) MetricsSummary {
- interval.RLock()
- defer interval.RUnlock()
-
- summary := MetricsSummary{
- Timestamp: interval.Interval.Round(time.Second).UTC().String(),
- Gauges: make([]GaugeValue, 0, len(interval.Gauges)),
- Points: make([]PointValue, 0, len(interval.Points)),
- }
-
- // Format and sort the output of each metric type, so it gets displayed in a
- // deterministic order.
- for name, points := range interval.Points {
- summary.Points = append(summary.Points, PointValue{name, points})
- }
- sort.Slice(summary.Points, func(i, j int) bool {
- return summary.Points[i].Name < summary.Points[j].Name
- })
-
- for hash, value := range interval.Gauges {
- value.Hash = hash
- value.DisplayLabels = make(map[string]string)
- for _, label := range value.Labels {
- value.DisplayLabels[label.Name] = label.Value
- }
- value.Labels = nil
-
- summary.Gauges = append(summary.Gauges, value)
- }
- sort.Slice(summary.Gauges, func(i, j int) bool {
- return summary.Gauges[i].Hash < summary.Gauges[j].Hash
- })
-
- summary.Counters = formatSamples(interval.Counters)
- summary.Samples = formatSamples(interval.Samples)
-
- return summary
-}
-
-func formatSamples(source map[string]SampledValue) []SampledValue {
- output := make([]SampledValue, 0, len(source))
- for hash, sample := range source {
- displayLabels := make(map[string]string)
- for _, label := range sample.Labels {
- displayLabels[label.Name] = label.Value
- }
-
- output = append(output, SampledValue{
- Name: sample.Name,
- Hash: hash,
- AggregateSample: sample.AggregateSample,
- Mean: sample.AggregateSample.Mean(),
- Stddev: sample.AggregateSample.Stddev(),
- DisplayLabels: displayLabels,
- })
- }
- sort.Slice(output, func(i, j int) bool {
- return output[i].Hash < output[j].Hash
- })
-
- return output
-}
-
-type Encoder interface {
- Encode(interface{}) error
-}
-
-// Stream writes metrics using encoder.Encode each time an interval ends. Runs
-// until the request context is cancelled, or the encoder returns an error.
-// The caller is responsible for logging any errors from encoder.
-func (i *InmemSink) Stream(ctx context.Context, encoder Encoder) {
- interval := i.getInterval()
-
- for {
- select {
- case <-interval.done:
- summary := newMetricSummaryFromInterval(interval)
- if err := encoder.Encode(summary); err != nil {
- return
- }
-
- // update interval to the next one
- interval = i.getInterval()
- case <-ctx.Done():
- return
- }
- }
-}
diff --git a/vendor/github.com/armon/go-metrics/inmem_signal.go b/vendor/github.com/armon/go-metrics/inmem_signal.go
deleted file mode 100644
index 0937f4aed..000000000
--- a/vendor/github.com/armon/go-metrics/inmem_signal.go
+++ /dev/null
@@ -1,117 +0,0 @@
-package metrics
-
-import (
- "bytes"
- "fmt"
- "io"
- "os"
- "os/signal"
- "strings"
- "sync"
- "syscall"
-)
-
-// InmemSignal is used to listen for a given signal, and when received,
-// to dump the current metrics from the InmemSink to an io.Writer
-type InmemSignal struct {
- signal syscall.Signal
- inm *InmemSink
- w io.Writer
- sigCh chan os.Signal
-
- stop bool
- stopCh chan struct{}
- stopLock sync.Mutex
-}
-
-// NewInmemSignal creates a new InmemSignal which listens for a given signal,
-// and dumps the current metrics out to a writer
-func NewInmemSignal(inmem *InmemSink, sig syscall.Signal, w io.Writer) *InmemSignal {
- i := &InmemSignal{
- signal: sig,
- inm: inmem,
- w: w,
- sigCh: make(chan os.Signal, 1),
- stopCh: make(chan struct{}),
- }
- signal.Notify(i.sigCh, sig)
- go i.run()
- return i
-}
-
-// DefaultInmemSignal returns a new InmemSignal that responds to SIGUSR1
-// and writes output to stderr. Windows uses SIGBREAK
-func DefaultInmemSignal(inmem *InmemSink) *InmemSignal {
- return NewInmemSignal(inmem, DefaultSignal, os.Stderr)
-}
-
-// Stop is used to stop the InmemSignal from listening
-func (i *InmemSignal) Stop() {
- i.stopLock.Lock()
- defer i.stopLock.Unlock()
-
- if i.stop {
- return
- }
- i.stop = true
- close(i.stopCh)
- signal.Stop(i.sigCh)
-}
-
-// run is a long running routine that handles signals
-func (i *InmemSignal) run() {
- for {
- select {
- case <-i.sigCh:
- i.dumpStats()
- case <-i.stopCh:
- return
- }
- }
-}
-
-// dumpStats is used to dump the data to output writer
-func (i *InmemSignal) dumpStats() {
- buf := bytes.NewBuffer(nil)
-
- data := i.inm.Data()
- // Skip the last period which is still being aggregated
- for j := 0; j < len(data)-1; j++ {
- intv := data[j]
- intv.RLock()
- for _, val := range intv.Gauges {
- name := i.flattenLabels(val.Name, val.Labels)
- fmt.Fprintf(buf, "[%v][G] '%s': %0.3f\n", intv.Interval, name, val.Value)
- }
- for name, vals := range intv.Points {
- for _, val := range vals {
- fmt.Fprintf(buf, "[%v][P] '%s': %0.3f\n", intv.Interval, name, val)
- }
- }
- for _, agg := range intv.Counters {
- name := i.flattenLabels(agg.Name, agg.Labels)
- fmt.Fprintf(buf, "[%v][C] '%s': %s\n", intv.Interval, name, agg.AggregateSample)
- }
- for _, agg := range intv.Samples {
- name := i.flattenLabels(agg.Name, agg.Labels)
- fmt.Fprintf(buf, "[%v][S] '%s': %s\n", intv.Interval, name, agg.AggregateSample)
- }
- intv.RUnlock()
- }
-
- // Write out the bytes
- i.w.Write(buf.Bytes())
-}
-
-// Flattens the key for formatting along with its labels, removes spaces
-func (i *InmemSignal) flattenLabels(name string, labels []Label) string {
- buf := bytes.NewBufferString(name)
- replacer := strings.NewReplacer(" ", "_", ":", "_")
-
- for _, label := range labels {
- replacer.WriteString(buf, ".")
- replacer.WriteString(buf, label.Value)
- }
-
- return buf.String()
-}
diff --git a/vendor/github.com/armon/go-metrics/metrics.go b/vendor/github.com/armon/go-metrics/metrics.go
deleted file mode 100644
index 36642a429..000000000
--- a/vendor/github.com/armon/go-metrics/metrics.go
+++ /dev/null
@@ -1,299 +0,0 @@
-package metrics
-
-import (
- "runtime"
- "strings"
- "time"
-
- iradix "github.com/hashicorp/go-immutable-radix"
-)
-
-type Label struct {
- Name string
- Value string
-}
-
-func (m *Metrics) SetGauge(key []string, val float32) {
- m.SetGaugeWithLabels(key, val, nil)
-}
-
-func (m *Metrics) SetGaugeWithLabels(key []string, val float32, labels []Label) {
- if m.HostName != "" {
- if m.EnableHostnameLabel {
- labels = append(labels, Label{"host", m.HostName})
- } else if m.EnableHostname {
- key = insert(0, m.HostName, key)
- }
- }
- if m.EnableTypePrefix {
- key = insert(0, "gauge", key)
- }
- if m.ServiceName != "" {
- if m.EnableServiceLabel {
- labels = append(labels, Label{"service", m.ServiceName})
- } else {
- key = insert(0, m.ServiceName, key)
- }
- }
- allowed, labelsFiltered := m.allowMetric(key, labels)
- if !allowed {
- return
- }
- m.sink.SetGaugeWithLabels(key, val, labelsFiltered)
-}
-
-func (m *Metrics) EmitKey(key []string, val float32) {
- if m.EnableTypePrefix {
- key = insert(0, "kv", key)
- }
- if m.ServiceName != "" {
- key = insert(0, m.ServiceName, key)
- }
- allowed, _ := m.allowMetric(key, nil)
- if !allowed {
- return
- }
- m.sink.EmitKey(key, val)
-}
-
-func (m *Metrics) IncrCounter(key []string, val float32) {
- m.IncrCounterWithLabels(key, val, nil)
-}
-
-func (m *Metrics) IncrCounterWithLabels(key []string, val float32, labels []Label) {
- if m.HostName != "" && m.EnableHostnameLabel {
- labels = append(labels, Label{"host", m.HostName})
- }
- if m.EnableTypePrefix {
- key = insert(0, "counter", key)
- }
- if m.ServiceName != "" {
- if m.EnableServiceLabel {
- labels = append(labels, Label{"service", m.ServiceName})
- } else {
- key = insert(0, m.ServiceName, key)
- }
- }
- allowed, labelsFiltered := m.allowMetric(key, labels)
- if !allowed {
- return
- }
- m.sink.IncrCounterWithLabels(key, val, labelsFiltered)
-}
-
-func (m *Metrics) AddSample(key []string, val float32) {
- m.AddSampleWithLabels(key, val, nil)
-}
-
-func (m *Metrics) AddSampleWithLabels(key []string, val float32, labels []Label) {
- if m.HostName != "" && m.EnableHostnameLabel {
- labels = append(labels, Label{"host", m.HostName})
- }
- if m.EnableTypePrefix {
- key = insert(0, "sample", key)
- }
- if m.ServiceName != "" {
- if m.EnableServiceLabel {
- labels = append(labels, Label{"service", m.ServiceName})
- } else {
- key = insert(0, m.ServiceName, key)
- }
- }
- allowed, labelsFiltered := m.allowMetric(key, labels)
- if !allowed {
- return
- }
- m.sink.AddSampleWithLabels(key, val, labelsFiltered)
-}
-
-func (m *Metrics) MeasureSince(key []string, start time.Time) {
- m.MeasureSinceWithLabels(key, start, nil)
-}
-
-func (m *Metrics) MeasureSinceWithLabels(key []string, start time.Time, labels []Label) {
- if m.HostName != "" && m.EnableHostnameLabel {
- labels = append(labels, Label{"host", m.HostName})
- }
- if m.EnableTypePrefix {
- key = insert(0, "timer", key)
- }
- if m.ServiceName != "" {
- if m.EnableServiceLabel {
- labels = append(labels, Label{"service", m.ServiceName})
- } else {
- key = insert(0, m.ServiceName, key)
- }
- }
- allowed, labelsFiltered := m.allowMetric(key, labels)
- if !allowed {
- return
- }
- now := time.Now()
- elapsed := now.Sub(start)
- msec := float32(elapsed.Nanoseconds()) / float32(m.TimerGranularity)
- m.sink.AddSampleWithLabels(key, msec, labelsFiltered)
-}
-
-// UpdateFilter overwrites the existing filter with the given rules.
-func (m *Metrics) UpdateFilter(allow, block []string) {
- m.UpdateFilterAndLabels(allow, block, m.AllowedLabels, m.BlockedLabels)
-}
-
-// UpdateFilterAndLabels overwrites the existing filter with the given rules.
-func (m *Metrics) UpdateFilterAndLabels(allow, block, allowedLabels, blockedLabels []string) {
- m.filterLock.Lock()
- defer m.filterLock.Unlock()
-
- m.AllowedPrefixes = allow
- m.BlockedPrefixes = block
-
- if allowedLabels == nil {
- // Having a white list means we take only elements from it
- m.allowedLabels = nil
- } else {
- m.allowedLabels = make(map[string]bool)
- for _, v := range allowedLabels {
- m.allowedLabels[v] = true
- }
- }
- m.blockedLabels = make(map[string]bool)
- for _, v := range blockedLabels {
- m.blockedLabels[v] = true
- }
- m.AllowedLabels = allowedLabels
- m.BlockedLabels = blockedLabels
-
- m.filter = iradix.New()
- for _, prefix := range m.AllowedPrefixes {
- m.filter, _, _ = m.filter.Insert([]byte(prefix), true)
- }
- for _, prefix := range m.BlockedPrefixes {
- m.filter, _, _ = m.filter.Insert([]byte(prefix), false)
- }
-}
-
-func (m *Metrics) Shutdown() {
- if ss, ok := m.sink.(ShutdownSink); ok {
- ss.Shutdown()
- }
-}
-
-// labelIsAllowed return true if a should be included in metric
-// the caller should lock m.filterLock while calling this method
-func (m *Metrics) labelIsAllowed(label *Label) bool {
- labelName := (*label).Name
- if m.blockedLabels != nil {
- _, ok := m.blockedLabels[labelName]
- if ok {
- // If present, let's remove this label
- return false
- }
- }
- if m.allowedLabels != nil {
- _, ok := m.allowedLabels[labelName]
- return ok
- }
- // Allow by default
- return true
-}
-
-// filterLabels return only allowed labels
-// the caller should lock m.filterLock while calling this method
-func (m *Metrics) filterLabels(labels []Label) []Label {
- if labels == nil {
- return nil
- }
- toReturn := []Label{}
- for _, label := range labels {
- if m.labelIsAllowed(&label) {
- toReturn = append(toReturn, label)
- }
- }
- return toReturn
-}
-
-// Returns whether the metric should be allowed based on configured prefix filters
-// Also return the applicable labels
-func (m *Metrics) allowMetric(key []string, labels []Label) (bool, []Label) {
- m.filterLock.RLock()
- defer m.filterLock.RUnlock()
-
- if m.filter == nil || m.filter.Len() == 0 {
- return m.Config.FilterDefault, m.filterLabels(labels)
- }
-
- _, allowed, ok := m.filter.Root().LongestPrefix([]byte(strings.Join(key, ".")))
- if !ok {
- return m.Config.FilterDefault, m.filterLabels(labels)
- }
-
- return allowed.(bool), m.filterLabels(labels)
-}
-
-// Periodically collects runtime stats to publish
-func (m *Metrics) collectStats() {
- for {
- time.Sleep(m.ProfileInterval)
- m.EmitRuntimeStats()
- }
-}
-
-// Emits various runtime statsitics
-func (m *Metrics) EmitRuntimeStats() {
- // Export number of Goroutines
- numRoutines := runtime.NumGoroutine()
- m.SetGauge([]string{"runtime", "num_goroutines"}, float32(numRoutines))
-
- // Export memory stats
- var stats runtime.MemStats
- runtime.ReadMemStats(&stats)
- m.SetGauge([]string{"runtime", "alloc_bytes"}, float32(stats.Alloc))
- m.SetGauge([]string{"runtime", "sys_bytes"}, float32(stats.Sys))
- m.SetGauge([]string{"runtime", "malloc_count"}, float32(stats.Mallocs))
- m.SetGauge([]string{"runtime", "free_count"}, float32(stats.Frees))
- m.SetGauge([]string{"runtime", "heap_objects"}, float32(stats.HeapObjects))
- m.SetGauge([]string{"runtime", "total_gc_pause_ns"}, float32(stats.PauseTotalNs))
- m.SetGauge([]string{"runtime", "total_gc_runs"}, float32(stats.NumGC))
-
- // Export info about the last few GC runs
- num := stats.NumGC
-
- // Handle wrap around
- if num < m.lastNumGC {
- m.lastNumGC = 0
- }
-
- // Ensure we don't scan more than 256
- if num-m.lastNumGC >= 256 {
- m.lastNumGC = num - 255
- }
-
- for i := m.lastNumGC; i < num; i++ {
- pause := stats.PauseNs[i%256]
- m.AddSample([]string{"runtime", "gc_pause_ns"}, float32(pause))
- }
- m.lastNumGC = num
-}
-
-// Creates a new slice with the provided string value as the first element
-// and the provided slice values as the remaining values.
-// Ordering of the values in the provided input slice is kept in tact in the output slice.
-func insert(i int, v string, s []string) []string {
- // Allocate new slice to avoid modifying the input slice
- newS := make([]string, len(s)+1)
-
- // Copy s[0, i-1] into newS
- for j := 0; j < i; j++ {
- newS[j] = s[j]
- }
-
- // Insert provided element at index i
- newS[i] = v
-
- // Copy s[i, len(s)-1] into newS starting at newS[i+1]
- for j := i; j < len(s); j++ {
- newS[j+1] = s[j]
- }
-
- return newS
-}
diff --git a/vendor/github.com/armon/go-metrics/sink.go b/vendor/github.com/armon/go-metrics/sink.go
deleted file mode 100644
index 6f4108ff4..000000000
--- a/vendor/github.com/armon/go-metrics/sink.go
+++ /dev/null
@@ -1,132 +0,0 @@
-package metrics
-
-import (
- "fmt"
- "net/url"
-)
-
-// The MetricSink interface is used to transmit metrics information
-// to an external system
-type MetricSink interface {
- // A Gauge should retain the last value it is set to
- SetGauge(key []string, val float32)
- SetGaugeWithLabels(key []string, val float32, labels []Label)
-
- // Should emit a Key/Value pair for each call
- EmitKey(key []string, val float32)
-
- // Counters should accumulate values
- IncrCounter(key []string, val float32)
- IncrCounterWithLabels(key []string, val float32, labels []Label)
-
- // Samples are for timing information, where quantiles are used
- AddSample(key []string, val float32)
- AddSampleWithLabels(key []string, val float32, labels []Label)
-}
-
-type ShutdownSink interface {
- MetricSink
-
- // Shutdown the metric sink, flush metrics to storage, and cleanup resources.
- // Called immediately prior to application exit. Implementations must block
- // until metrics are flushed to storage.
- Shutdown()
-}
-
-// BlackholeSink is used to just blackhole messages
-type BlackholeSink struct{}
-
-func (*BlackholeSink) SetGauge(key []string, val float32) {}
-func (*BlackholeSink) SetGaugeWithLabels(key []string, val float32, labels []Label) {}
-func (*BlackholeSink) EmitKey(key []string, val float32) {}
-func (*BlackholeSink) IncrCounter(key []string, val float32) {}
-func (*BlackholeSink) IncrCounterWithLabels(key []string, val float32, labels []Label) {}
-func (*BlackholeSink) AddSample(key []string, val float32) {}
-func (*BlackholeSink) AddSampleWithLabels(key []string, val float32, labels []Label) {}
-
-// FanoutSink is used to sink to fanout values to multiple sinks
-type FanoutSink []MetricSink
-
-func (fh FanoutSink) SetGauge(key []string, val float32) {
- fh.SetGaugeWithLabels(key, val, nil)
-}
-
-func (fh FanoutSink) SetGaugeWithLabels(key []string, val float32, labels []Label) {
- for _, s := range fh {
- s.SetGaugeWithLabels(key, val, labels)
- }
-}
-
-func (fh FanoutSink) EmitKey(key []string, val float32) {
- for _, s := range fh {
- s.EmitKey(key, val)
- }
-}
-
-func (fh FanoutSink) IncrCounter(key []string, val float32) {
- fh.IncrCounterWithLabels(key, val, nil)
-}
-
-func (fh FanoutSink) IncrCounterWithLabels(key []string, val float32, labels []Label) {
- for _, s := range fh {
- s.IncrCounterWithLabels(key, val, labels)
- }
-}
-
-func (fh FanoutSink) AddSample(key []string, val float32) {
- fh.AddSampleWithLabels(key, val, nil)
-}
-
-func (fh FanoutSink) AddSampleWithLabels(key []string, val float32, labels []Label) {
- for _, s := range fh {
- s.AddSampleWithLabels(key, val, labels)
- }
-}
-
-func (fh FanoutSink) Shutdown() {
- for _, s := range fh {
- if ss, ok := s.(ShutdownSink); ok {
- ss.Shutdown()
- }
- }
-}
-
-// sinkURLFactoryFunc is an generic interface around the *SinkFromURL() function provided
-// by each sink type
-type sinkURLFactoryFunc func(*url.URL) (MetricSink, error)
-
-// sinkRegistry supports the generic NewMetricSink function by mapping URL
-// schemes to metric sink factory functions
-var sinkRegistry = map[string]sinkURLFactoryFunc{
- "statsd": NewStatsdSinkFromURL,
- "statsite": NewStatsiteSinkFromURL,
- "inmem": NewInmemSinkFromURL,
-}
-
-// NewMetricSinkFromURL allows a generic URL input to configure any of the
-// supported sinks. The scheme of the URL identifies the type of the sink, the
-// and query parameters are used to set options.
-//
-// "statsd://" - Initializes a StatsdSink. The host and port are passed through
-// as the "addr" of the sink
-//
-// "statsite://" - Initializes a StatsiteSink. The host and port become the
-// "addr" of the sink
-//
-// "inmem://" - Initializes an InmemSink. The host and port are ignored. The
-// "interval" and "duration" query parameters must be specified with valid
-// durations, see NewInmemSink for details.
-func NewMetricSinkFromURL(urlStr string) (MetricSink, error) {
- u, err := url.Parse(urlStr)
- if err != nil {
- return nil, err
- }
-
- sinkURLFactoryFunc := sinkRegistry[u.Scheme]
- if sinkURLFactoryFunc == nil {
- return nil, fmt.Errorf(
- "cannot create metric sink, unrecognized sink name: %q", u.Scheme)
- }
-
- return sinkURLFactoryFunc(u)
-}
diff --git a/vendor/github.com/armon/go-metrics/start.go b/vendor/github.com/armon/go-metrics/start.go
deleted file mode 100644
index 38976f8dc..000000000
--- a/vendor/github.com/armon/go-metrics/start.go
+++ /dev/null
@@ -1,158 +0,0 @@
-package metrics
-
-import (
- "os"
- "sync"
- "sync/atomic"
- "time"
-
- iradix "github.com/hashicorp/go-immutable-radix"
-)
-
-// Config is used to configure metrics settings
-type Config struct {
- ServiceName string // Prefixed with keys to separate services
- HostName string // Hostname to use. If not provided and EnableHostname, it will be os.Hostname
- EnableHostname bool // Enable prefixing gauge values with hostname
- EnableHostnameLabel bool // Enable adding hostname to labels
- EnableServiceLabel bool // Enable adding service to labels
- EnableRuntimeMetrics bool // Enables profiling of runtime metrics (GC, Goroutines, Memory)
- EnableTypePrefix bool // Prefixes key with a type ("counter", "gauge", "timer")
- TimerGranularity time.Duration // Granularity of timers.
- ProfileInterval time.Duration // Interval to profile runtime metrics
-
- AllowedPrefixes []string // A list of metric prefixes to allow, with '.' as the separator
- BlockedPrefixes []string // A list of metric prefixes to block, with '.' as the separator
- AllowedLabels []string // A list of metric labels to allow, with '.' as the separator
- BlockedLabels []string // A list of metric labels to block, with '.' as the separator
- FilterDefault bool // Whether to allow metrics by default
-}
-
-// Metrics represents an instance of a metrics sink that can
-// be used to emit
-type Metrics struct {
- Config
- lastNumGC uint32
- sink MetricSink
- filter *iradix.Tree
- allowedLabels map[string]bool
- blockedLabels map[string]bool
- filterLock sync.RWMutex // Lock filters and allowedLabels/blockedLabels access
-}
-
-// Shared global metrics instance
-var globalMetrics atomic.Value // *Metrics
-
-func init() {
- // Initialize to a blackhole sink to avoid errors
- globalMetrics.Store(&Metrics{sink: &BlackholeSink{}})
-}
-
-// Default returns the shared global metrics instance.
-func Default() *Metrics {
- return globalMetrics.Load().(*Metrics)
-}
-
-// DefaultConfig provides a sane default configuration
-func DefaultConfig(serviceName string) *Config {
- c := &Config{
- ServiceName: serviceName, // Use client provided service
- HostName: "",
- EnableHostname: true, // Enable hostname prefix
- EnableRuntimeMetrics: true, // Enable runtime profiling
- EnableTypePrefix: false, // Disable type prefix
- TimerGranularity: time.Millisecond, // Timers are in milliseconds
- ProfileInterval: time.Second, // Poll runtime every second
- FilterDefault: true, // Don't filter metrics by default
- }
-
- // Try to get the hostname
- name, _ := os.Hostname()
- c.HostName = name
- return c
-}
-
-// New is used to create a new instance of Metrics
-func New(conf *Config, sink MetricSink) (*Metrics, error) {
- met := &Metrics{}
- met.Config = *conf
- met.sink = sink
- met.UpdateFilterAndLabels(conf.AllowedPrefixes, conf.BlockedPrefixes, conf.AllowedLabels, conf.BlockedLabels)
-
- // Start the runtime collector
- if conf.EnableRuntimeMetrics {
- go met.collectStats()
- }
- return met, nil
-}
-
-// NewGlobal is the same as New, but it assigns the metrics object to be
-// used globally as well as returning it.
-func NewGlobal(conf *Config, sink MetricSink) (*Metrics, error) {
- metrics, err := New(conf, sink)
- if err == nil {
- globalMetrics.Store(metrics)
- }
- return metrics, err
-}
-
-// Proxy all the methods to the globalMetrics instance
-func SetGauge(key []string, val float32) {
- globalMetrics.Load().(*Metrics).SetGauge(key, val)
-}
-
-func SetGaugeWithLabels(key []string, val float32, labels []Label) {
- globalMetrics.Load().(*Metrics).SetGaugeWithLabels(key, val, labels)
-}
-
-func EmitKey(key []string, val float32) {
- globalMetrics.Load().(*Metrics).EmitKey(key, val)
-}
-
-func IncrCounter(key []string, val float32) {
- globalMetrics.Load().(*Metrics).IncrCounter(key, val)
-}
-
-func IncrCounterWithLabels(key []string, val float32, labels []Label) {
- globalMetrics.Load().(*Metrics).IncrCounterWithLabels(key, val, labels)
-}
-
-func AddSample(key []string, val float32) {
- globalMetrics.Load().(*Metrics).AddSample(key, val)
-}
-
-func AddSampleWithLabels(key []string, val float32, labels []Label) {
- globalMetrics.Load().(*Metrics).AddSampleWithLabels(key, val, labels)
-}
-
-func MeasureSince(key []string, start time.Time) {
- globalMetrics.Load().(*Metrics).MeasureSince(key, start)
-}
-
-func MeasureSinceWithLabels(key []string, start time.Time, labels []Label) {
- globalMetrics.Load().(*Metrics).MeasureSinceWithLabels(key, start, labels)
-}
-
-func UpdateFilter(allow, block []string) {
- globalMetrics.Load().(*Metrics).UpdateFilter(allow, block)
-}
-
-// UpdateFilterAndLabels set allow/block prefixes of metrics while allowedLabels
-// and blockedLabels - when not nil - allow filtering of labels in order to
-// block/allow globally labels (especially useful when having large number of
-// values for a given label). See README.md for more information about usage.
-func UpdateFilterAndLabels(allow, block, allowedLabels, blockedLabels []string) {
- globalMetrics.Load().(*Metrics).UpdateFilterAndLabels(allow, block, allowedLabels, blockedLabels)
-}
-
-// Shutdown disables metric collection, then blocks while attempting to flush metrics to storage.
-// WARNING: Not all MetricSink backends support this functionality, and calling this will cause them to leak resources.
-// This is intended for use immediately prior to application exit.
-func Shutdown() {
- m := globalMetrics.Load().(*Metrics)
- // Swap whatever MetricSink is currently active with a BlackholeSink. Callers must not have a
- // reason to expect that calls to the library will successfully collect metrics after Shutdown
- // has been called.
- globalMetrics.Store(&Metrics{sink: &BlackholeSink{}})
- m.Shutdown()
-}
diff --git a/vendor/github.com/armon/go-metrics/statsd.go b/vendor/github.com/armon/go-metrics/statsd.go
deleted file mode 100644
index 1bfffce46..000000000
--- a/vendor/github.com/armon/go-metrics/statsd.go
+++ /dev/null
@@ -1,184 +0,0 @@
-package metrics
-
-import (
- "bytes"
- "fmt"
- "log"
- "net"
- "net/url"
- "strings"
- "time"
-)
-
-const (
- // statsdMaxLen is the maximum size of a packet
- // to send to statsd
- statsdMaxLen = 1400
-)
-
-// StatsdSink provides a MetricSink that can be used
-// with a statsite or statsd metrics server. It uses
-// only UDP packets, while StatsiteSink uses TCP.
-type StatsdSink struct {
- addr string
- metricQueue chan string
-}
-
-// NewStatsdSinkFromURL creates an StatsdSink from a URL. It is used
-// (and tested) from NewMetricSinkFromURL.
-func NewStatsdSinkFromURL(u *url.URL) (MetricSink, error) {
- return NewStatsdSink(u.Host)
-}
-
-// NewStatsdSink is used to create a new StatsdSink
-func NewStatsdSink(addr string) (*StatsdSink, error) {
- s := &StatsdSink{
- addr: addr,
- metricQueue: make(chan string, 4096),
- }
- go s.flushMetrics()
- return s, nil
-}
-
-// Close is used to stop flushing to statsd
-func (s *StatsdSink) Shutdown() {
- close(s.metricQueue)
-}
-
-func (s *StatsdSink) SetGauge(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|g\n", flatKey, val))
-}
-
-func (s *StatsdSink) SetGaugeWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|g\n", flatKey, val))
-}
-
-func (s *StatsdSink) EmitKey(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|kv\n", flatKey, val))
-}
-
-func (s *StatsdSink) IncrCounter(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|c\n", flatKey, val))
-}
-
-func (s *StatsdSink) IncrCounterWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|c\n", flatKey, val))
-}
-
-func (s *StatsdSink) AddSample(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|ms\n", flatKey, val))
-}
-
-func (s *StatsdSink) AddSampleWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|ms\n", flatKey, val))
-}
-
-// Flattens the key for formatting, removes spaces
-func (s *StatsdSink) flattenKey(parts []string) string {
- joined := strings.Join(parts, ".")
- return strings.Map(func(r rune) rune {
- switch r {
- case ':':
- fallthrough
- case ' ':
- return '_'
- default:
- return r
- }
- }, joined)
-}
-
-// Flattens the key along with labels for formatting, removes spaces
-func (s *StatsdSink) flattenKeyLabels(parts []string, labels []Label) string {
- for _, label := range labels {
- parts = append(parts, label.Value)
- }
- return s.flattenKey(parts)
-}
-
-// Does a non-blocking push to the metrics queue
-func (s *StatsdSink) pushMetric(m string) {
- select {
- case s.metricQueue <- m:
- default:
- }
-}
-
-// Flushes metrics
-func (s *StatsdSink) flushMetrics() {
- var sock net.Conn
- var err error
- var wait <-chan time.Time
- ticker := time.NewTicker(flushInterval)
- defer ticker.Stop()
-
-CONNECT:
- // Create a buffer
- buf := bytes.NewBuffer(nil)
-
- // Attempt to connect
- sock, err = net.Dial("udp", s.addr)
- if err != nil {
- log.Printf("[ERR] Error connecting to statsd! Err: %s", err)
- goto WAIT
- }
-
- for {
- select {
- case metric, ok := <-s.metricQueue:
- // Get a metric from the queue
- if !ok {
- goto QUIT
- }
-
- // Check if this would overflow the packet size
- if len(metric)+buf.Len() > statsdMaxLen {
- _, err := sock.Write(buf.Bytes())
- buf.Reset()
- if err != nil {
- log.Printf("[ERR] Error writing to statsd! Err: %s", err)
- goto WAIT
- }
- }
-
- // Append to the buffer
- buf.WriteString(metric)
-
- case <-ticker.C:
- if buf.Len() == 0 {
- continue
- }
-
- _, err := sock.Write(buf.Bytes())
- buf.Reset()
- if err != nil {
- log.Printf("[ERR] Error flushing to statsd! Err: %s", err)
- goto WAIT
- }
- }
- }
-
-WAIT:
- // Wait for a while
- wait = time.After(time.Duration(5) * time.Second)
- for {
- select {
- // Dequeue the messages to avoid backlog
- case _, ok := <-s.metricQueue:
- if !ok {
- goto QUIT
- }
- case <-wait:
- goto CONNECT
- }
- }
-QUIT:
- s.metricQueue = nil
-}
diff --git a/vendor/github.com/armon/go-metrics/statsite.go b/vendor/github.com/armon/go-metrics/statsite.go
deleted file mode 100644
index 6c0d284d2..000000000
--- a/vendor/github.com/armon/go-metrics/statsite.go
+++ /dev/null
@@ -1,172 +0,0 @@
-package metrics
-
-import (
- "bufio"
- "fmt"
- "log"
- "net"
- "net/url"
- "strings"
- "time"
-)
-
-const (
- // We force flush the statsite metrics after this period of
- // inactivity. Prevents stats from getting stuck in a buffer
- // forever.
- flushInterval = 100 * time.Millisecond
-)
-
-// NewStatsiteSinkFromURL creates an StatsiteSink from a URL. It is used
-// (and tested) from NewMetricSinkFromURL.
-func NewStatsiteSinkFromURL(u *url.URL) (MetricSink, error) {
- return NewStatsiteSink(u.Host)
-}
-
-// StatsiteSink provides a MetricSink that can be used with a
-// statsite metrics server
-type StatsiteSink struct {
- addr string
- metricQueue chan string
-}
-
-// NewStatsiteSink is used to create a new StatsiteSink
-func NewStatsiteSink(addr string) (*StatsiteSink, error) {
- s := &StatsiteSink{
- addr: addr,
- metricQueue: make(chan string, 4096),
- }
- go s.flushMetrics()
- return s, nil
-}
-
-// Close is used to stop flushing to statsite
-func (s *StatsiteSink) Shutdown() {
- close(s.metricQueue)
-}
-
-func (s *StatsiteSink) SetGauge(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|g\n", flatKey, val))
-}
-
-func (s *StatsiteSink) SetGaugeWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|g\n", flatKey, val))
-}
-
-func (s *StatsiteSink) EmitKey(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|kv\n", flatKey, val))
-}
-
-func (s *StatsiteSink) IncrCounter(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|c\n", flatKey, val))
-}
-
-func (s *StatsiteSink) IncrCounterWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|c\n", flatKey, val))
-}
-
-func (s *StatsiteSink) AddSample(key []string, val float32) {
- flatKey := s.flattenKey(key)
- s.pushMetric(fmt.Sprintf("%s:%f|ms\n", flatKey, val))
-}
-
-func (s *StatsiteSink) AddSampleWithLabels(key []string, val float32, labels []Label) {
- flatKey := s.flattenKeyLabels(key, labels)
- s.pushMetric(fmt.Sprintf("%s:%f|ms\n", flatKey, val))
-}
-
-// Flattens the key for formatting, removes spaces
-func (s *StatsiteSink) flattenKey(parts []string) string {
- joined := strings.Join(parts, ".")
- return strings.Map(func(r rune) rune {
- switch r {
- case ':':
- fallthrough
- case ' ':
- return '_'
- default:
- return r
- }
- }, joined)
-}
-
-// Flattens the key along with labels for formatting, removes spaces
-func (s *StatsiteSink) flattenKeyLabels(parts []string, labels []Label) string {
- for _, label := range labels {
- parts = append(parts, label.Value)
- }
- return s.flattenKey(parts)
-}
-
-// Does a non-blocking push to the metrics queue
-func (s *StatsiteSink) pushMetric(m string) {
- select {
- case s.metricQueue <- m:
- default:
- }
-}
-
-// Flushes metrics
-func (s *StatsiteSink) flushMetrics() {
- var sock net.Conn
- var err error
- var wait <-chan time.Time
- var buffered *bufio.Writer
- ticker := time.NewTicker(flushInterval)
- defer ticker.Stop()
-
-CONNECT:
- // Attempt to connect
- sock, err = net.Dial("tcp", s.addr)
- if err != nil {
- log.Printf("[ERR] Error connecting to statsite! Err: %s", err)
- goto WAIT
- }
-
- // Create a buffered writer
- buffered = bufio.NewWriter(sock)
-
- for {
- select {
- case metric, ok := <-s.metricQueue:
- // Get a metric from the queue
- if !ok {
- goto QUIT
- }
-
- // Try to send to statsite
- _, err := buffered.Write([]byte(metric))
- if err != nil {
- log.Printf("[ERR] Error writing to statsite! Err: %s", err)
- goto WAIT
- }
- case <-ticker.C:
- if err := buffered.Flush(); err != nil {
- log.Printf("[ERR] Error flushing to statsite! Err: %s", err)
- goto WAIT
- }
- }
- }
-
-WAIT:
- // Wait for a while
- wait = time.After(time.Duration(5) * time.Second)
- for {
- select {
- // Dequeue the messages to avoid backlog
- case _, ok := <-s.metricQueue:
- if !ok {
- goto QUIT
- }
- case <-wait:
- goto CONNECT
- }
- }
-QUIT:
- s.metricQueue = nil
-}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/aws/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/aws/go_module_metadata.go
index cd8dfbc25..f0392825a 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/aws/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/aws/go_module_metadata.go
@@ -3,4 +3,4 @@
package aws
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.47.0"
+const goModuleVersion = "1.47.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/config/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/config/CHANGELOG.md
index b9c8341c5..c16921415 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/config/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/config/CHANGELOG.md
@@ -1,3 +1,11 @@
+# v1.33.6 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.33.5 (2026-09-14)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.33.4 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/config/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/config/go_module_metadata.go
index ae91d0371..c47c1625a 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/config/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/config/go_module_metadata.go
@@ -3,4 +3,4 @@
package config
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.33.4"
+const goModuleVersion = "1.33.6"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/credentials/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/credentials/CHANGELOG.md
index cb4745e9c..59c2310b9 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/credentials/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/credentials/CHANGELOG.md
@@ -1,3 +1,11 @@
+# v1.20.6 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.20.5 (2026-09-14)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.20.4 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/credentials/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/credentials/go_module_metadata.go
index 4188b9e09..00d49733b 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/credentials/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/credentials/go_module_metadata.go
@@ -3,4 +3,4 @@
package credentials
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.20.4"
+const goModuleVersion = "1.20.6"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/CHANGELOG.md
index 9e560547b..f15072b68 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.20.1 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.20.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/go_module_metadata.go
index c53f4079b..baf15c947 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/feature/ec2/imds/go_module_metadata.go
@@ -3,4 +3,4 @@
package imds
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.20.0"
+const goModuleVersion = "1.20.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/CHANGELOG.md
index 613d88e02..8f6c18348 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.5.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.5.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/go_module_metadata.go
index 7f07b4782..744363f1e 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/configsources/go_module_metadata.go
@@ -3,4 +3,4 @@
package configsources
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.5.3"
+const goModuleVersion = "1.5.4"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/CHANGELOG.md
index 446a0cc85..538b0e872 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v2.8.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v2.8.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/go_module_metadata.go
index 5d26e7bec..a9a325b93 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/endpoints/v2/go_module_metadata.go
@@ -3,4 +3,4 @@
package endpoints
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "2.8.3"
+const goModuleVersion = "2.8.4"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/CHANGELOG.md
index 4900beadd..2058fadb1 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.5.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.5.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/go_module_metadata.go
index dc8e20908..b10d86aa6 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/internal/v4a/go_module_metadata.go
@@ -3,4 +3,4 @@
package v4a
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.5.3"
+const goModuleVersion = "1.5.4"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/CHANGELOG.md
index 5e3a680ed..ccacce9e8 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/CHANGELOG.md
@@ -1,3 +1,11 @@
+# v1.11.5 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.11.4 (2026-09-23)
+
+* **Bug Fix**: Checksum non-200 http responses
+
# v1.11.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/go_module_metadata.go
index c681eeb0b..8129c3ad9 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/go_module_metadata.go
@@ -3,4 +3,4 @@
package checksum
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.11.3"
+const goModuleVersion = "1.11.5"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/middleware_validate_output.go b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/middleware_validate_output.go
index 65dd4c1ef..454cf8b4d 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/middleware_validate_output.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/checksum/middleware_validate_output.go
@@ -78,12 +78,12 @@ func (m *validateOutputPayloadChecksum) HandleDeserialize(
}
}
- // this runs BEFORE the deserializer, so we have to preemptively check for
- // non-200, in which case there is no checksum to validate
- if response.StatusCode != 200 {
- return out, metadata, err
- }
-
+ // Validation is gated on the presence of a supported, non-composite checksum
+ // header (the "no checksum" branch below). Responses without one — error
+ // responses (4xx/5xx) and arbitrary Range GETs — are not validated.
+ // Successful partial-content responses (206) from partNumber or whole-object
+ // Range GETs do carry a validatable checksum covering exactly the returned
+ // bytes, and are validated.
var expectedChecksum string
var algorithmToUse Algorithm
for _, algorithm := range m.Algorithms {
@@ -100,10 +100,13 @@ func (m *validateOutputPayloadChecksum) HandleDeserialize(
// Skip validation if no checksum algorithm or checksum is available.
if len(expectedChecksum) == 0 || len(algorithmToUse) == 0 {
- if response.Body != http.NoBody && m.LogValidationSkipped {
+ // Only log for successful responses. Error responses (4xx/5xx) carry an
+ // error document rather than an object payload and legitimately have no
+ // checksum, so logging there is just noise.
+ if response.StatusCode < 400 && response.Body != http.NoBody && m.LogValidationSkipped {
// TODO this probably should have more information about the
// operation output that won't be validated.
- logger.Logf(logging.Warn,
+ logger.Logf(logging.Debug,
"Response has no supported checksum. Not validating response payload.")
}
return out, metadata, nil
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/CHANGELOG.md
index 3e6ab8f02..0d7ac987a 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.14.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.14.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/go_module_metadata.go
index 1112596ff..05dc98848 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/presigned-url/go_module_metadata.go
@@ -3,4 +3,4 @@
package presignedurl
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.14.3"
+const goModuleVersion = "1.14.4"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/CHANGELOG.md
index baa5eab97..553a19563 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.20.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.20.3 (2026-09-09)
* **Dependency Update**: Updated to the latest SDK module versions
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/go_module_metadata.go
index c34cc3a94..b06168be6 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/internal/s3shared/go_module_metadata.go
@@ -3,4 +3,4 @@
package s3shared
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.20.3"
+const goModuleVersion = "1.20.4"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/CHANGELOG.md
index f6df38396..70a691f1b 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/CHANGELOG.md
@@ -1,3 +1,23 @@
+# v1.114.0 (2026-09-30)
+
+* **Feature**: Amazon S3 adds a new optional S3 Inventory field, IntelligentTieringReferenceDate, reporting the reference date S3 Intelligent-Tiering uses to evaluate an object's tier-transition eligibility. The value is populated for objects in the Intelligent-Tiering storage class and left blank for others.
+
+# v1.113.4 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.113.3 (2026-09-23)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.113.2 (2026-09-21)
+
+* **Bug Fix**: Expand S3 operations that check for an error inside an HTTP 200 response (wave 4/4)
+
+# v1.113.1 (2026-09-11)
+
+* **Documentation**: Updated S3 Object Lock Default Retention documentation.
+
# v1.113.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CopyObject.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CopyObject.go
index 690c41ab3..473bb5e3c 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CopyObject.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CopyObject.go
@@ -600,12 +600,14 @@ type CopyObjectInput struct {
// This functionality is not supported for directory buckets.
ObjectLockEventHold types.ObjectLockEventHold
- // The event hold duration in days to apply to the object copy.
+ // The event hold duration in days to apply to the object copy. You cannot specify
+ // a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationDays *int32
- // The event hold duration in years to apply to the object copy.
+ // The event hold duration in years to apply to the object copy. You cannot
+ // specify a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationYears *int32
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateBucket.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateBucket.go
index ed679df83..c05e347c9 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateBucket.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateBucket.go
@@ -348,6 +348,9 @@ func (c *Client) addOperationCreateBucketMiddlewares(stack *middleware.Stack, op
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateMultipartUpload.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateMultipartUpload.go
index f7fa1cc50..eed46ce57 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateMultipartUpload.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_CreateMultipartUpload.go
@@ -606,12 +606,14 @@ type CreateMultipartUploadInput struct {
// This functionality is not supported for directory buckets.
ObjectLockEventHold types.ObjectLockEventHold
- // Specifies the event hold duration in days to apply to the uploaded object.
+ // Specifies the event hold duration in days to apply to the uploaded object. You
+ // cannot specify a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationDays *int32
- // Specifies the event hold duration in years to apply to the uploaded object.
+ // Specifies the event hold duration in years to apply to the uploaded object. You
+ // cannot specify a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationYears *int32
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_DeleteObject.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_DeleteObject.go
index fa448fb12..df0993cce 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_DeleteObject.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_DeleteObject.go
@@ -334,6 +334,9 @@ func (c *Client) addOperationDeleteObjectMiddlewares(stack *middleware.Stack, op
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_HeadObject.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_HeadObject.go
index fa9fff53c..0e8341247 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_HeadObject.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_HeadObject.go
@@ -771,6 +771,9 @@ func (c *Client) addOperationHeadObjectMiddlewares(stack *middleware.Stack, opti
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjects.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjects.go
index fb86f2003..a6dbceb48 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjects.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjects.go
@@ -290,6 +290,9 @@ func (c *Client) addOperationListObjectsMiddlewares(stack *middleware.Stack, opt
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjectsV2.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjectsV2.go
index cbd5b86fe..27ab60824 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjectsV2.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_ListObjectsV2.go
@@ -385,6 +385,9 @@ func (c *Client) addOperationListObjectsV2Middlewares(stack *middleware.Stack, o
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutBucketAnalyticsConfiguration.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutBucketAnalyticsConfiguration.go
index cce27c704..cfe95fc4e 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutBucketAnalyticsConfiguration.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutBucketAnalyticsConfiguration.go
@@ -175,6 +175,9 @@ func (c *Client) addOperationPutBucketAnalyticsConfigurationMiddlewares(stack *m
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObject.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObject.go
index 94516da79..500309c31 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObject.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObject.go
@@ -521,12 +521,14 @@ type PutObjectInput struct {
// This functionality is not supported for directory buckets.
ObjectLockEventHold types.ObjectLockEventHold
- // Specifies the event hold duration in days to apply to this object.
+ // Specifies the event hold duration in days to apply to this object. You cannot
+ // specify a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationDays *int32
- // Specifies the event hold duration in years to apply to this object.
+ // Specifies the event hold duration in years to apply to this object. You cannot
+ // specify a duration in both days and years.
//
// This functionality is not supported for directory buckets.
ObjectLockEventHoldDurationYears *int32
@@ -1001,6 +1003,9 @@ func (c *Client) addOperationPutObjectMiddlewares(stack *middleware.Stack, optio
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObjectAcl.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObjectAcl.go
index cf84ae25b..033ba15ea 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObjectAcl.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_PutObjectAcl.go
@@ -380,6 +380,9 @@ func (c *Client) addOperationPutObjectAclMiddlewares(stack *middleware.Stack, op
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_UploadPart.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_UploadPart.go
index 5fb79ffab..ec293b2fe 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_UploadPart.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/api_op_UploadPart.go
@@ -587,6 +587,9 @@ func (c *Client) addOperationUploadPartMiddlewares(stack *middleware.Stack, opti
if err = disableAcceptEncodingGzip(stack); err != nil {
return err
}
+ if err = s3cust.HandleResponseErrorWith200Status(stack); err != nil {
+ return err
+ }
if err = addRequestResponseLogging(stack, options); err != nil {
return err
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/go_module_metadata.go
index 71072cc60..98b6b6404 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/go_module_metadata.go
@@ -3,4 +3,4 @@
package s3
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.113.0"
+const goModuleVersion = "1.114.0"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/enums.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/enums.go
index 91c710617..05f5681c5 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/enums.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/enums.go
@@ -786,24 +786,25 @@ type InventoryOptionalField string
// Enum values for InventoryOptionalField
const (
- InventoryOptionalFieldSize InventoryOptionalField = "Size"
- InventoryOptionalFieldLastModifiedDate InventoryOptionalField = "LastModifiedDate"
- InventoryOptionalFieldStorageClass InventoryOptionalField = "StorageClass"
- InventoryOptionalFieldETag InventoryOptionalField = "ETag"
- InventoryOptionalFieldIsMultipartUploaded InventoryOptionalField = "IsMultipartUploaded"
- InventoryOptionalFieldReplicationStatus InventoryOptionalField = "ReplicationStatus"
- InventoryOptionalFieldEncryptionStatus InventoryOptionalField = "EncryptionStatus"
- InventoryOptionalFieldObjectLockRetainUntilDate InventoryOptionalField = "ObjectLockRetainUntilDate"
- InventoryOptionalFieldObjectLockMode InventoryOptionalField = "ObjectLockMode"
- InventoryOptionalFieldObjectLockLegalHoldStatus InventoryOptionalField = "ObjectLockLegalHoldStatus"
- InventoryOptionalFieldObjectLockEventHoldStatus InventoryOptionalField = "ObjectLockEventHoldStatus"
- InventoryOptionalFieldObjectLockEventHoldDuration InventoryOptionalField = "ObjectLockEventHoldDuration"
- InventoryOptionalFieldIntelligentTieringAccessTier InventoryOptionalField = "IntelligentTieringAccessTier"
- InventoryOptionalFieldBucketKeyStatus InventoryOptionalField = "BucketKeyStatus"
- InventoryOptionalFieldChecksumAlgorithm InventoryOptionalField = "ChecksumAlgorithm"
- InventoryOptionalFieldObjectAccessControlList InventoryOptionalField = "ObjectAccessControlList"
- InventoryOptionalFieldObjectOwner InventoryOptionalField = "ObjectOwner"
- InventoryOptionalFieldLifecycleExpirationDate InventoryOptionalField = "LifecycleExpirationDate"
+ InventoryOptionalFieldSize InventoryOptionalField = "Size"
+ InventoryOptionalFieldLastModifiedDate InventoryOptionalField = "LastModifiedDate"
+ InventoryOptionalFieldStorageClass InventoryOptionalField = "StorageClass"
+ InventoryOptionalFieldETag InventoryOptionalField = "ETag"
+ InventoryOptionalFieldIsMultipartUploaded InventoryOptionalField = "IsMultipartUploaded"
+ InventoryOptionalFieldReplicationStatus InventoryOptionalField = "ReplicationStatus"
+ InventoryOptionalFieldEncryptionStatus InventoryOptionalField = "EncryptionStatus"
+ InventoryOptionalFieldObjectLockRetainUntilDate InventoryOptionalField = "ObjectLockRetainUntilDate"
+ InventoryOptionalFieldObjectLockMode InventoryOptionalField = "ObjectLockMode"
+ InventoryOptionalFieldObjectLockLegalHoldStatus InventoryOptionalField = "ObjectLockLegalHoldStatus"
+ InventoryOptionalFieldObjectLockEventHoldStatus InventoryOptionalField = "ObjectLockEventHoldStatus"
+ InventoryOptionalFieldObjectLockEventHoldDuration InventoryOptionalField = "ObjectLockEventHoldDuration"
+ InventoryOptionalFieldIntelligentTieringAccessTier InventoryOptionalField = "IntelligentTieringAccessTier"
+ InventoryOptionalFieldBucketKeyStatus InventoryOptionalField = "BucketKeyStatus"
+ InventoryOptionalFieldChecksumAlgorithm InventoryOptionalField = "ChecksumAlgorithm"
+ InventoryOptionalFieldObjectAccessControlList InventoryOptionalField = "ObjectAccessControlList"
+ InventoryOptionalFieldObjectOwner InventoryOptionalField = "ObjectOwner"
+ InventoryOptionalFieldLifecycleExpirationDate InventoryOptionalField = "LifecycleExpirationDate"
+ InventoryOptionalFieldIntelligentTieringReferenceDate InventoryOptionalField = "IntelligentTieringReferenceDate"
)
// Values returns all known values for InventoryOptionalField. Note that this can
@@ -830,6 +831,7 @@ func (InventoryOptionalField) Values() []InventoryOptionalField {
"ObjectAccessControlList",
"ObjectOwner",
"LifecycleExpirationDate",
+ "IntelligentTieringReferenceDate",
}
}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/types.go b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/types.go
index c712301cb..61d8b4ca7 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/types.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/s3/types/types.go
@@ -3702,10 +3702,15 @@ type ObjectLockRetention struct {
// The container element for an Object Lock rule.
type ObjectLockRule struct {
- // The default Object Lock retention mode and period that you want to apply to new
- // objects placed in the specified bucket. Bucket settings require both a mode and
- // a period. The period can be either Days or Years but you must select one. You
- // cannot specify Days and Years at the same time.
+ // The default Object Lock retention settings for new objects in this bucket. You
+ // can specify:
+ //
+ // - A default retention period, by using Days or Years .
+ //
+ // - A default event hold duration, by using DefaultEventHold . This setting also
+ // uses days or years.
+ //
+ // You can set one or both. You cannot use days and years in the same setting.
DefaultRetention *DefaultRetention
noSmithyDocumentSerde
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/signin/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/signin/CHANGELOG.md
index 508afc370..5b2e9bf15 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/signin/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/signin/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.10.1 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.10.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/signin/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/signin/go_module_metadata.go
index 4f75436db..0a71eb409 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/signin/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/signin/go_module_metadata.go
@@ -3,4 +3,4 @@
package signin
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.10.0"
+const goModuleVersion = "1.10.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sso/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/sso/CHANGELOG.md
index 7d6f31796..3343b37cd 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sso/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sso/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.38.1 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.38.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sso/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sso/go_module_metadata.go
index b2848584d..653969f93 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sso/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sso/go_module_metadata.go
@@ -3,4 +3,4 @@
package sso
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.38.0"
+const goModuleVersion = "1.38.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/CHANGELOG.md
index 4b8fb09b3..b99345083 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/CHANGELOG.md
@@ -1,3 +1,7 @@
+# v1.43.1 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
# v1.43.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/go_module_metadata.go
index 27c757f31..ae3957055 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/ssooidc/go_module_metadata.go
@@ -3,4 +3,4 @@
package ssooidc
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.43.0"
+const goModuleVersion = "1.43.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/CHANGELOG.md b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/CHANGELOG.md
index f30d0308e..410a4aea7 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/CHANGELOG.md
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/CHANGELOG.md
@@ -1,3 +1,11 @@
+# v1.51.1 (2026-09-24)
+
+* **Dependency Update**: Updated to the latest SDK module versions
+
+# v1.51.0 (2026-09-14)
+
+* **Feature**: Increases the maximum session token size to 4,096 bytes and removes the packed policy size limit. Adds SessionTokenSize and SessionTokenUtilization fields and a new MinimumSessionTokenSize parameter. PackedPolicySize is deprecated.
+
# v1.50.0 (2026-09-09)
* **Feature**: Stop registering the `retry.MetricsHeader` middleware in generated clients. The `Amz-Sdk-Request` header is now set by the retry middleware itself.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRole.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRole.go
index b1cd67560..958bfaa89 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRole.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRole.go
@@ -198,6 +198,12 @@ type AssumeRoleInput struct {
// [How to Use an External ID When Granting Access to Your Amazon Web Services Resources to a Third Party]: https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html
ExternalId *string
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
// An IAM policy in JSON format that you want to use as an inline session policy.
//
// This parameter is optional. Passing policies to this operation returns new
@@ -385,8 +391,18 @@ type AssumeRoleOutput struct {
// session tags combined passed in the request. The request fails if the packed
// size is greater than 100 percent, which means the policies and tags exceeded the
// allowed space.
+ //
+ // Deprecated: Deprecated. Replaced by SessionTokenUtilization.
PackedPolicySize *int32
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// The source identity specified by the principal that is calling the AssumeRole
// operation.
//
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithSAML.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithSAML.go
index 10f16e165..e4050fce8 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithSAML.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithSAML.go
@@ -202,6 +202,12 @@ type AssumeRoleWithSAMLInput struct {
// [Creating a URL that Enables Federated Users to Access the Amazon Web Services Management Console]: https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_providers_enable-console-custom-url.html
DurationSeconds *int32
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
// An IAM policy in JSON format that you want to use as an inline session policy.
//
// This parameter is optional. Passing policies to this operation returns new
@@ -305,8 +311,18 @@ type AssumeRoleWithSAMLOutput struct {
// session tags combined passed in the request. The request fails if the packed
// size is greater than 100 percent, which means the policies and tags exceeded the
// allowed space.
+ //
+ // Deprecated: Deprecated. Replaced by SessionTokenUtilization.
PackedPolicySize *int32
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// The value in the SourceIdentity attribute in the SAML assertion. The source
// identity value persists across [chained role]sessions.
//
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithWebIdentity.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithWebIdentity.go
index 97f51b8be..662b45a82 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithWebIdentity.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoleWithWebIdentity.go
@@ -222,6 +222,12 @@ type AssumeRoleWithWebIdentityInput struct {
// [Creating a URL that Enables Federated Users to Access the Amazon Web Services Management Console]: https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_providers_enable-console-custom-url.html
DurationSeconds *int32
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
// An IAM policy in JSON format that you want to use as an inline session policy.
//
// This parameter is optional. Passing policies to this operation returns new
@@ -320,6 +326,8 @@ type AssumeRoleWithWebIdentityOutput struct {
// session tags combined passed in the request. The request fails if the packed
// size is greater than 100 percent, which means the policies and tags exceeded the
// allowed space.
+ //
+ // Deprecated: Deprecated. Replaced by SessionTokenUtilization.
PackedPolicySize *int32
// The issuing authority of the web identity token presented. For OpenID Connect
@@ -328,6 +336,14 @@ type AssumeRoleWithWebIdentityOutput struct {
// the AssumeRoleWithWebIdentity request.
Provider *string
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// The value of the source identity that is returned in the JSON web token (JWT)
// from the identity provider.
//
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoot.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoot.go
index 8946a9bb9..c3437ca43 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoot.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_AssumeRoot.go
@@ -88,6 +88,12 @@ type AssumeRootInput struct {
// By default, the value is set to 900 seconds.
DurationSeconds *int32
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
noSmithyDocumentSerde
}
@@ -100,6 +106,14 @@ type AssumeRootOutput struct {
// strongly recommend that you make no assumptions about the maximum size.
Credentials *types.Credentials
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// The source identity specified by the principal that is calling the AssumeRoot
// operation.
//
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetDelegatedAccessToken.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetDelegatedAccessToken.go
index 33370240f..d3c8543f5 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetDelegatedAccessToken.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetDelegatedAccessToken.go
@@ -52,6 +52,8 @@ type GetDelegatedAccessTokenOutput struct {
// The policy size is calculated as the sum of all the session policies and
// permission boundaries attached to the session. If the packed size exceeds 100%,
// the request fails.
+ //
+ // Deprecated: Deprecated. This field is not populated for GetDelegatedAccessToken.
PackedPolicySize *int32
// Metadata pertaining to the operation's result.
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetFederationToken.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetFederationToken.go
index 09e7ab30b..ce0aef697 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetFederationToken.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetFederationToken.go
@@ -142,6 +142,12 @@ type GetFederationTokenInput struct {
// by using root user credentials defaults to one hour.
DurationSeconds *int32
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
// An IAM policy in JSON format that you want to use as an inline session policy.
//
// You must pass an inline or managed [session policy] to this operation. You can pass a single
@@ -276,8 +282,18 @@ type GetFederationTokenOutput struct {
// session tags combined passed in the request. The request fails if the packed
// size is greater than 100 percent, which means the policies and tags exceeded the
// allowed space.
+ //
+ // Deprecated: Deprecated. Replaced by SessionTokenUtilization.
PackedPolicySize *int32
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// Metadata pertaining to the operation's result.
ResultMetadata middleware.Metadata
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetSessionToken.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetSessionToken.go
index ce0b89566..159aa08ba 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetSessionToken.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetSessionToken.go
@@ -89,6 +89,12 @@ type GetSessionTokenInput struct {
// Services account owners defaults to one hour.
DurationSeconds *int32
+ // The minimum size, in bytes, of the session token that STS issues for the
+ // request. STS increases the session token to at least this size, regardless of
+ // its actual content. The value must not exceed 4,096 bytes. When set to 0 or not
+ // specified, the session token size is unchanged.
+ MinimumSessionTokenSize *int32
+
// The identification number of the MFA device that is associated with the IAM
// user who is making the GetSessionToken call. Specify this value if the IAM user
// has a policy that requires MFA authentication. The value is either the serial
@@ -127,6 +133,14 @@ type GetSessionTokenOutput struct {
// strongly recommend that you make no assumptions about the maximum size.
Credentials *types.Credentials
+ // The size, in bytes, of the session token returned in the Credentials for this
+ // response.
+ SessionTokenSize *int32
+
+ // The percentage (0-100) of the maximum allowed session token size that the
+ // returned session token consumes.
+ SessionTokenUtilization *int32
+
// Metadata pertaining to the operation's result.
ResultMetadata middleware.Metadata
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetWebIdentityToken.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetWebIdentityToken.go
index b36723d47..255f77e52 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetWebIdentityToken.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/api_op_GetWebIdentityToken.go
@@ -14,6 +14,8 @@ import (
// services that support OIDC discovery. The token is signed by Amazon Web Services
// STS and can be publicly verified using the verification keys published at the
// issuer's JWKS endpoint.
+//
+// The GetWebIdentityToken API is not available on the STS Global endpoint.
func (c *Client) GetWebIdentityToken(ctx context.Context, params *GetWebIdentityTokenInput, optFns ...func(*Options)) (*GetWebIdentityTokenOutput, error) {
if params == nil {
params = &GetWebIdentityTokenInput{}
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/deserializers.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/deserializers.go
index 45e073ffd..2c8267d38 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/deserializers.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/deserializers.go
@@ -2728,6 +2728,40 @@ func awsAwsquery_deserializeOpDocumentAssumeRoleOutput(v **AssumeRoleOutput, dec
sv.PackedPolicySize = ptr.Int32(int32(i64))
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
case strings.EqualFold("SourceIdentity", t.Name.Local):
val, err := decoder.Value()
if err != nil {
@@ -2845,6 +2879,40 @@ func awsAwsquery_deserializeOpDocumentAssumeRoleWithSAMLOutput(v **AssumeRoleWit
sv.PackedPolicySize = ptr.Int32(int32(i64))
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
case strings.EqualFold("SourceIdentity", t.Name.Local):
val, err := decoder.Value()
if err != nil {
@@ -2975,6 +3043,40 @@ func awsAwsquery_deserializeOpDocumentAssumeRoleWithWebIdentityOutput(v **Assume
sv.Provider = ptr.String(xtv)
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
case strings.EqualFold("SourceIdentity", t.Name.Local):
val, err := decoder.Value()
if err != nil {
@@ -3043,6 +3145,40 @@ func awsAwsquery_deserializeOpDocumentAssumeRootOutput(v **AssumeRootOutput, dec
return err
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
case strings.EqualFold("SourceIdentity", t.Name.Local):
val, err := decoder.Value()
if err != nil {
@@ -3366,6 +3502,40 @@ func awsAwsquery_deserializeOpDocumentGetFederationTokenOutput(v **GetFederation
sv.PackedPolicySize = ptr.Int32(int32(i64))
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
default:
// Do nothing and ignore the unexpected tag element
err = decoder.Decoder.Skip()
@@ -3408,6 +3578,40 @@ func awsAwsquery_deserializeOpDocumentGetSessionTokenOutput(v **GetSessionTokenO
return err
}
+ case strings.EqualFold("SessionTokenSize", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenSize = ptr.Int32(int32(i64))
+ }
+
+ case strings.EqualFold("SessionTokenUtilization", t.Name.Local):
+ val, err := decoder.Value()
+ if err != nil {
+ return err
+ }
+ if val == nil {
+ break
+ }
+ {
+ xtv := string(val)
+ i64, err := strconv.ParseInt(xtv, 10, 64)
+ if err != nil {
+ return err
+ }
+ sv.SessionTokenUtilization = ptr.Int32(int32(i64))
+ }
+
default:
// Do nothing and ignore the unexpected tag element
err = decoder.Decoder.Skip()
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/doc.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/doc.go
index cbb19c7f6..97efe4f93 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/doc.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/doc.go
@@ -5,9 +5,30 @@
//
// # Security Token Service
//
-// Security Token Service (STS) enables you to request temporary,
-// limited-privilege credentials for users. This guide provides descriptions of the
-// STS API. For more information about using this service, see [Temporary Security Credentials].
+// Amazon Web Services provides Security Token Service (STS) as a web service that
+// enables you to request temporary, limited-privilege credentials for users. This
+// guide describes the STS API. For more information, see [Temporary Security Credentials]in the IAM User Guide.
+//
+// As an alternative to using the API, you can use one of the Amazon Web Services
+// SDKs, which consist of libraries and sample code for various programming
+// languages and platforms such as Java, Ruby, .NET, iOS, Android, and others. The
+// SDKs provide a convenient way to create programmatic access to STS. For example,
+// the SDKs can cryptographically sign requests, manage errors, and retry requests
+// automatically. For information about the Amazon Web Services SDKs, see [Tools to Build on Amazon Web Services].
+//
+// For information about setting up signatures and authorization through the API,
+// see [Signing Amazon Web Services API Requests]in the Amazon Web Services General Reference. For general information about
+// the Query API, see [Making Query Requests]in the IAM User Guide. For information about using security
+// tokens with other Amazon Web Services products, see [Amazon Web Services Services That Work with IAM]in the IAM User Guide.
+//
+// For information about STS endpoints, see [STS Regions and endpoints] in the IAM User Guide. For
+// information about logging STS API calls, see [Logging IAM and STS API calls with CloudTrail]in the IAM User Guide.
//
// [Temporary Security Credentials]: https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_temp.html
+// [Making Query Requests]: https://docs.aws.amazon.com/IAM/latest/UserGuide/IAM_UsingQueryAPI.html
+// [Tools to Build on Amazon Web Services]: http://aws.amazon.com/tools/
+// [Amazon Web Services Services That Work with IAM]: https://docs.aws.amazon.com/IAM/latest/UserGuide/reference_aws-services-that-work-with-iam.html
+// [STS Regions and endpoints]: https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_temp_region-endpoints.html
+// [Logging IAM and STS API calls with CloudTrail]: https://docs.aws.amazon.com/IAM/latest/UserGuide/cloudtrail-integration.html
+// [Signing Amazon Web Services API Requests]: https://docs.aws.amazon.com/general/latest/gr/signing_aws_api_requests.html
package sts
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/go_module_metadata.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/go_module_metadata.go
index 8ca9182fe..d9d89fd0c 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/go_module_metadata.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/go_module_metadata.go
@@ -3,4 +3,4 @@
package sts
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.50.0"
+const goModuleVersion = "1.51.1"
diff --git a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/serializers.go b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/serializers.go
index 5e2273878..e361a3661 100644
--- a/vendor/github.com/aws/aws-sdk-go-v2/service/sts/serializers.go
+++ b/vendor/github.com/aws/aws-sdk-go-v2/service/sts/serializers.go
@@ -897,6 +897,11 @@ func awsAwsquery_serializeOpDocumentAssumeRoleInput(v *AssumeRoleInput, value qu
objectKey.String(*v.ExternalId)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.Policy != nil {
objectKey := object.Key("Policy")
objectKey.String(*v.Policy)
@@ -967,6 +972,11 @@ func awsAwsquery_serializeOpDocumentAssumeRoleWithSAMLInput(v *AssumeRoleWithSAM
objectKey.Integer(*v.DurationSeconds)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.Policy != nil {
objectKey := object.Key("Policy")
objectKey.String(*v.Policy)
@@ -1006,6 +1016,11 @@ func awsAwsquery_serializeOpDocumentAssumeRoleWithWebIdentityInput(v *AssumeRole
objectKey.Integer(*v.DurationSeconds)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.Policy != nil {
objectKey := object.Key("Policy")
objectKey.String(*v.Policy)
@@ -1050,6 +1065,11 @@ func awsAwsquery_serializeOpDocumentAssumeRootInput(v *AssumeRootInput, value qu
objectKey.Integer(*v.DurationSeconds)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.TargetPrincipal != nil {
objectKey := object.Key("TargetPrincipal")
objectKey.String(*v.TargetPrincipal)
@@ -1117,6 +1137,11 @@ func awsAwsquery_serializeOpDocumentGetFederationTokenInput(v *GetFederationToke
objectKey.Integer(*v.DurationSeconds)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.Name != nil {
objectKey := object.Key("Name")
objectKey.String(*v.Name)
@@ -1153,6 +1178,11 @@ func awsAwsquery_serializeOpDocumentGetSessionTokenInput(v *GetSessionTokenInput
objectKey.Integer(*v.DurationSeconds)
}
+ if v.MinimumSessionTokenSize != nil {
+ objectKey := object.Key("MinimumSessionTokenSize")
+ objectKey.Integer(*v.MinimumSessionTokenSize)
+ }
+
if v.SerialNumber != nil {
objectKey := object.Key("SerialNumber")
objectKey.String(*v.SerialNumber)
diff --git a/vendor/github.com/aws/smithy-go/CHANGELOG.md b/vendor/github.com/aws/smithy-go/CHANGELOG.md
index 0d26e973c..1bd86cb97 100644
--- a/vendor/github.com/aws/smithy-go/CHANGELOG.md
+++ b/vendor/github.com/aws/smithy-go/CHANGELOG.md
@@ -1,3 +1,15 @@
+# Release (2026-09-18)
+
+## General Highlights
+* **Dependency Update**: Updated to the latest SDK module versions
+
+## Module Highlights
+* `github.com/aws/smithy-go`: v1.28.2
+ * **Bug Fix**: Avoid allocating a slice in ValidateEndpointHost by indexing into the hostname instead of using strings.Split.
+ * **Bug Fix**: Fix event stream decode panic on unknown header value type.
+ * **Bug Fix**: Fix schema-serde CBOR decode panic on malformed string/blob length.
+ * **Bug Fix**: JoinPath keeps a trailing slash when the added path is a slash.
+
# Release (2026-08-26)
## General Highlights
diff --git a/vendor/github.com/aws/smithy-go/Makefile b/vendor/github.com/aws/smithy-go/Makefile
index a12b124d5..fb0670f0e 100644
--- a/vendor/github.com/aws/smithy-go/Makefile
+++ b/vendor/github.com/aws/smithy-go/Makefile
@@ -26,7 +26,7 @@ smithy-publish-local:
cd codegen && ./gradlew publishToMavenLocal
smithy-build:
- cd codegen && ./gradlew build
+ cd codegen && ./gradlew build --stacktrace
smithy-clean:
cd codegen && ./gradlew clean
diff --git a/vendor/github.com/aws/smithy-go/README.md b/vendor/github.com/aws/smithy-go/README.md
index ac5a0a613..28f3d1d5b 100644
--- a/vendor/github.com/aws/smithy-go/README.md
+++ b/vendor/github.com/aws/smithy-go/README.md
@@ -1,73 +1,52 @@
# Smithy Go
-[](https://github.com/aws/smithy-go/actions/workflows/go.yml)[](https://github.com/aws/smithy-go/actions/workflows/codegen.yml)
+[](https://github.com/aws/smithy-go/actions/workflows/go.yml)
+[](https://github.com/aws/smithy-go/actions/workflows/codegen.yml)
+[](LICENSE)
-[Smithy](https://smithy.io/) code generators for Go and the accompanying smithy-go runtime.
+[Smithy](https://smithy.io/) code generators for [Go](https://go.dev/), and
+the runtime package the generated code depends on.
-The smithy-go runtime requires a minimum version of Go 1.24.
+> [!WARNING]
+> All interfaces in this repository are subject to change. The client code
+> generator in particular powers
+> [aws-sdk-go-v2](https://github.com/aws/aws-sdk-go-v2), but arbitrary client
+> generation is in an early stage of development:
+> * Generated clients are missing certain features that were originally
+> implemented SDK-side (e.g. retries)
+> * There may be bugs
+> * The public APIs of generated clients may be unstable
+>
+> If you are interested in using the client code generators, we encourage you
+> to experiment and share any feedback with us in an issue.
-**WARNING: All interfaces are subject to change.**
+---
-## :warning: Client codegen is unstable
+This repository contains two major components:
-The client code generator in this repository powers the aws-sdk-go-v2.
-Arbitrary client generation, while possible, is in an early stage of
-development:
+1. **Codegen** ([`codegen/`](codegen)): A Java/Gradle-based Smithy build
+ plugin that generates Go client, server, and shape code from Smithy
+ models.
+2. **Runtime** (this module, `github.com/aws/smithy-go`): The Go packages
+ that code generated by the plugins above depends on.
-* Generated clients are missing certain features that were originally
- implemented SDK-side (e.g. retries)
-* There may be bugs
-* The public APIs of generated clients may be unstable
+> [!NOTE]
+> This repository does not contain any generated clients, such as for S3 or
+> other AWS services. Rather, these are the tools that facilitate generating
+> those clients (and non-AWS Smithy clients) from a Smithy model.
-If you are interested in using the client code generators, we encourage you to
-experiment and share any feedback with us in an issue.
+## Getting started
-## Plugins
+If this is your first time using Smithy, follow the
+[Smithy Quickstart guide](https://smithy.io/2.0/quickstart.html) to learn the
+basics and create a simple Smithy model.
-This repository implements the following Smithy build plugins:
-
-| ID | GAV prefix | Description |
-|----|------------|-------------|
-| `go-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Implements Go client code generation for Smithy models. |
-| `go-server-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Implements Go server code generation for Smithy models. |
-| `go-shape-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Implements Go shape code generation (types only) for Smithy models. |
-
-## `go-codegen`
-
-### Configuration
-
-[`GoSettings`](codegen/smithy-go-codegen/src/main/java/software/amazon/smithy/go/codegen/GoSettings.java)
-contains all of the settings enabled from `smithy-build.json` and helper
-methods and types. The up-to-date list of top-level properties enabled for
-`go-client-codegen` can be found in `GoSettings::from()`.
-
-| Setting | Type | Required | Description |
-|-----------------|---------|----------|-----------------------------------------------------------------------------------------------------------------------------|
-| `service` | string | yes | The Shape ID of the service for which to generate the client. |
-| `module` | string | yes | Name of the module in `generated.json` (and `go.mod` if `generateGoMod` is enabled) and `doc.go`. |
-| `generateGoMod` | boolean | | Whether to generate a default `go.mod` file. The default value is `false`. |
-| `goDirective` | string | | [Go directive](https://go.dev/ref/mod#go-mod-file-go) of the module. The default value is the minimum supported Go version. |
+The smithy-go runtime requires a minimum version of **Go 1.24**.
-### Supported protocols
+### Codegen
-The protocol a client uses is configured by the `Protocol` field on a client's
-`Options`. The SDK will configure a default based on the protocol traits
-applied to the modeled service.
-
-| Protocol | Notes |
-|----------|-------|
-| [`smithy.protocols#rpcv2Cbor`](https://smithy.io/2.0/additional-specs/protocols/smithy-rpc-v2.html) | |
-| [`aws.protocols#restJson1`](https://smithy.io/2.0/aws/protocols/aws-restjson1-protocol.html) | |
-| [`aws.protocols#restXml`](https://smithy.io/2.0/aws/protocols/aws-restxml-protocol.html) | |
-| [`aws.protocols#awsJson1_0`](https://smithy.io/2.0/aws/protocols/aws-json-1_0-protocol.html) | |
-| [`aws.protocols#awsJson1_1`](https://smithy.io/2.0/aws/protocols/aws-json-1_1-protocol.html) | |
-| [`aws.protocols#awsQuery`](https://smithy.io/2.0/aws/protocols/aws-query-protocol.html) | |
-| [`aws.protocols#ec2Query`](https://smithy.io/2.0/aws/protocols/aws-ec2-query-protocol.html) | |
-
-### Example
-
-This example applies the `go-codegen` build plugin to the Smithy quickstart
-example created from `smithy init`:
+To generate a Go client from a Smithy model, apply the `go-codegen` plugin in
+your `smithy-build.json`:
```json
{
@@ -91,15 +70,136 @@ example created from `smithy init`:
}
```
-## `go-server-codegen`
+This repository implements the following Smithy build plugins:
+
+| ID | GAV prefix | Description |
+|----|------------|-------------|
+| `go-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Go client code generation for Smithy models. |
+| `go-server-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Go server code generation for Smithy models (work-in-progress, undocumented). |
+| `go-shape-codegen` | `software.amazon.smithy.go:smithy-go-codegen` | Go shape code generation (types only) for Smithy models (work-in-progress, undocumented). |
-This plugin is a work-in-progress and is currently undocumented.
+#### `go-codegen` settings
-## `go-shape-codegen`
+[`GoSettings`](codegen/smithy-go-codegen/src/main/java/software/amazon/smithy/go/codegen/GoSettings.java)
+contains all of the settings enabled from `smithy-build.json`. The up-to-date
+list of top-level properties enabled for `go-codegen` can be found in
+`GoSettings::from()`.
-This plugin is a work-in-progress and is currently undocumented.
+| Setting | Type | Required | Description |
+|-----------------|---------|----------|-------------------------------------------------------------------------------------------------------------------------------|
+| `service` | string | yes | The Shape ID of the service for which to generate the client. |
+| `module` | string | yes | Name of the module in `generated.json` (and `go.mod` if `generateGoMod` is enabled) and `doc.go`. |
+| `generateGoMod` | boolean | | Whether to generate a default `go.mod` file. The default value is `false`. |
+| `goDirective` | string | | [Go directive](https://go.dev/ref/mod#go-mod-file-go) of the module. The default value is the minimum supported Go version. |
+
+#### Supported protocols
+
+The protocol a generated client uses is configured by the `Protocol` field on
+the client's `Options`. The SDK configures a default based on the protocol
+traits applied to the modeled service.
+
+Each protocol is implemented as its own package under
+[`transport/http/protocol`](transport/http/protocol). Serialization for these
+protocols is handled by internal codecs under `protocol/internal` (e.g.
+`protocol/internal/json`, `protocol/internal/cbor`,
+`protocol/internal/xml`); these largely supersede the top-level
+[`encoding/`](encoding) packages of the same name; see
+[Encoding](#encoding) below.
+
+| Protocol | Package | Notes |
+|----------|---------|-------|
+| [`smithy.protocols#rpcv2Cbor`](https://smithy.io/2.0/additional-specs/protocols/smithy-rpc-v2.html) | [`protocol/rpcv2`](transport/http/protocol/rpcv2) | |
+| [`aws.protocols#restJson1`](https://smithy.io/2.0/aws/protocols/aws-restjson1-protocol.html) | [`protocol/restjson1`](transport/http/protocol/restjson1) | |
+| [`aws.protocols#restXml`](https://smithy.io/2.0/aws/protocols/aws-restxml-protocol.html) | [`protocol/restxml`](transport/http/protocol/restxml) | |
+| [`aws.protocols#awsJson1_0`](https://smithy.io/2.0/aws/protocols/aws-json-1_0-protocol.html) | [`protocol/awsjson`](transport/http/protocol/awsjson) | `awsjson.New10` |
+| [`aws.protocols#awsJson1_1`](https://smithy.io/2.0/aws/protocols/aws-json-1_1-protocol.html) | [`protocol/awsjson`](transport/http/protocol/awsjson) | `awsjson.New11` |
+| [`aws.protocols#awsQuery`](https://smithy.io/2.0/aws/protocols/aws-query-protocol.html) | [`protocol/awsquery`](transport/http/protocol/awsquery) | |
+| [`aws.protocols#ec2Query`](https://smithy.io/2.0/aws/protocols/aws-ec2-query-protocol.html) | [`protocol/ec2query`](transport/http/protocol/ec2query) | |
+
+These packages are client-only; smithy-go does not currently implement
+server-side protocol support.
+
+Building and testing the codegen plugins is done via Gradle from the
+`codegen/` directory:
+
+```bash
+# Build and test codegen
+cd codegen && ./gradlew build
+
+# Publish to local Maven for downstream use
+cd codegen && ./gradlew publishToMavenLocal
+```
+
+See [`codegen/README.md`](codegen/README.md) for local setup instructions.
+
+## Runtime packages
+
+All generated clients depend on this module (`github.com/aws/smithy-go`) at
+runtime. It also includes a few standalone submodules published separately.
+
+### Core
+
+- [`middleware`](middleware): The middleware stack that drives the operation
+ pipeline.
+- [`transport/http`](transport/http): HTTP request/response types and
+ middleware.
+- [`auth`](auth): Auth identity and scheme interfaces.
+ - [`auth/bearer`](auth/bearer): Bearer token auth.
+- [`endpoints`](endpoints): Endpoint resolution types.
+- [`context`](context): Context helpers.
+- [`logging`](logging): Logging interfaces.
+- [`tracing`](tracing): Tracing interfaces.
+- [`metrics`](metrics): Metrics interfaces.
+
+### Encoding
+
+Wire format encoders/decoders under [`encoding/`](encoding).
+
+> [!NOTE]
+> Most of these packages are effectively legacy. The protocol
+> implementations under [`transport/http/protocol`](transport/http/protocol)
+> (used by current client codegen) have their own internal codecs under
+> `protocol/internal/*` and generally do not build on these packages.
+> The `encoding/json`, `encoding/xml`, and `encoding/cbor` packages otherwise
+> remain in use by [`document/json`](document/json)/[`document/cbor`](document/cbor)
+> and [`eventstream`](eventstream), and by existing generated SDK code that
+> predates the newer protocol implementations.
+
+- [`encoding/json`](encoding/json): JSON encoding/decoding.
+- [`encoding/xml`](encoding/xml): XML encoding/decoding.
+- [`encoding/cbor`](encoding/cbor): CBOR encoding/decoding (used by
+ `rpcv2Cbor`).
+- [`encoding/httpbinding`](encoding/httpbinding): HTTP binding serde helpers.
+
+### Document
+
+- [`document`](document): Smithy document type abstraction.
+ - [`document/json`](document/json): JSON document codec.
+
+### Utilities
+
+- [`container`](container): Generic container types.
+- [`io`](io): I/O helpers.
+- [`ptr`](ptr): Pointer-to/from-value helpers.
+- [`time`](time): Smithy timestamp format helpers.
+- [`rand`](rand): UUID/randomness helpers.
+- [`testing`](testing): Test assertion helpers for generated protocol tests.
+
+### Standalone modules
+
+These are published as separate Go modules, each with its own `go.mod`.
+
+- [`aws-http-auth`](aws-http-auth): AWS SigV4/SigV4A HTTP signing.
+- [`tracing/smithyoteltracing`](tracing/smithyoteltracing): OpenTelemetry
+ tracing adapter.
+- [`metrics/smithyotelmetrics`](metrics/smithyotelmetrics): OpenTelemetry
+ metrics adapter.
+
+## Development
+
+See [CONTRIBUTING](CONTRIBUTING.md) for more information on contributing to
+this project, including the changelog process for runtime changes.
## License
This project is licensed under the Apache-2.0 License.
-
diff --git a/vendor/github.com/aws/smithy-go/eventstream/debug.go b/vendor/github.com/aws/smithy-go/eventstream/debug.go
index 6049402b1..ca4394f8b 100644
--- a/vendor/github.com/aws/smithy-go/eventstream/debug.go
+++ b/vendor/github.com/aws/smithy-go/eventstream/debug.go
@@ -139,6 +139,6 @@ func valueFromType(typ valueType, val any) (Value, error) {
copy(tv[:], v)
return tv, err
default:
- panic(fmt.Sprintf("unknown type, %s, %T", typ.String(), val))
+ return nil, fmt.Errorf("unable to decode unknown type, %s, %T", typ.String(), val)
}
}
diff --git a/vendor/github.com/aws/smithy-go/eventstream/header.go b/vendor/github.com/aws/smithy-go/eventstream/header.go
index f580bda4c..b5aacca00 100644
--- a/vendor/github.com/aws/smithy-go/eventstream/header.go
+++ b/vendor/github.com/aws/smithy-go/eventstream/header.go
@@ -151,7 +151,7 @@ func decodeHeaderValue(r io.Reader) (Value, error) {
err = tv.decode(r)
v = tv
default:
- panic(fmt.Sprintf("unknown value type %d", raw.Type))
+ return nil, fmt.Errorf("unable to decode header of unknown value type %d", raw.Type)
}
// Error could be EOF, let caller deal with it
diff --git a/vendor/github.com/aws/smithy-go/go_module_metadata.go b/vendor/github.com/aws/smithy-go/go_module_metadata.go
index c945a45db..e5f64bbdd 100644
--- a/vendor/github.com/aws/smithy-go/go_module_metadata.go
+++ b/vendor/github.com/aws/smithy-go/go_module_metadata.go
@@ -3,4 +3,4 @@
package smithy
// goModuleVersion is the tagged release for this module
-const goModuleVersion = "1.28.1"
+const goModuleVersion = "1.28.2"
diff --git a/vendor/github.com/aws/smithy-go/transport/http/host.go b/vendor/github.com/aws/smithy-go/transport/http/host.go
index b504a455d..b1227bf9e 100644
--- a/vendor/github.com/aws/smithy-go/transport/http/host.go
+++ b/vendor/github.com/aws/smithy-go/transport/http/host.go
@@ -29,17 +29,23 @@ func ValidateEndpointHost(host string) error {
hostname = host
}
- labels := strings.Split(hostname, ".")
- for i, label := range labels {
- if i == len(labels)-1 && len(label) == 0 {
- // Allow trailing dot for FQDN hosts.
- continue
+ for start := 0; ; {
+ idx := strings.IndexByte(hostname[start:], '.')
+ if idx < 0 {
+ // Last label. Allow it to be empty to permit a trailing dot for
+ // FQDN hosts.
+ if label := hostname[start:]; len(label) != 0 && !ValidHostLabel(label) {
+ errors.WriteString("\nendpoint host domain labels must match \"[a-zA-Z0-9-]{1,63}\", but found: ")
+ errors.WriteString(label)
+ }
+ break
}
- if !ValidHostLabel(label) {
+ if label := hostname[start : start+idx]; !ValidHostLabel(label) {
errors.WriteString("\nendpoint host domain labels must match \"[a-zA-Z0-9-]{1,63}\", but found: ")
errors.WriteString(label)
}
+ start += idx + 1
}
if len(hostname) == 0 && len(port) != 0 {
diff --git a/vendor/github.com/aws/smithy-go/transport/http/url.go b/vendor/github.com/aws/smithy-go/transport/http/url.go
index 60a5fc100..99f9737af 100644
--- a/vendor/github.com/aws/smithy-go/transport/http/url.go
+++ b/vendor/github.com/aws/smithy-go/transport/http/url.go
@@ -12,6 +12,9 @@ func JoinPath(a, b string) string {
a = "/" + a
}
+ // Record b's trailing slash before the strip below can erase it (a bare
+ // "/" becomes "").
+ keepTrailing := len(b) > 0 && b[len(b)-1] == '/'
if len(b) != 0 && b[0] == '/' {
b = b[1:]
}
@@ -20,6 +23,10 @@ func JoinPath(a, b string) string {
a = a + "/"
}
+ if keepTrailing && len(b) == 0 && a[len(a)-1] != '/' {
+ a = a + "/"
+ }
+
return a + b
}
diff --git a/vendor/github.com/goccy/go-json/.gitignore b/vendor/github.com/goccy/go-json/.gitignore
index 378283829..b3623e1be 100644
--- a/vendor/github.com/goccy/go-json/.gitignore
+++ b/vendor/github.com/goccy/go-json/.gitignore
@@ -1,2 +1,4 @@
cover.html
cover.out
+bin/
+benchmarks/site/
diff --git a/vendor/github.com/goccy/go-json/.golangci.yml b/vendor/github.com/goccy/go-json/.golangci.yml
index 977accaa9..d4644a10d 100644
--- a/vendor/github.com/goccy/go-json/.golangci.yml
+++ b/vendor/github.com/goccy/go-json/.golangci.yml
@@ -1,84 +1,100 @@
-run:
- skip-files:
- - encode_optype.go
- - ".*_test\\.go$"
+version: "2"
-linters-settings:
- govet:
- enable-all: true
- disable:
- - shadow
+run:
+ tests: false
linters:
- enable-all: true
+ default: all
disable:
+ - containedctx
+ - cyclop
+ - depguard
- dogsled
- dupl
- - exhaustive
- - exhaustivestruct
+ - embeddedstructfieldcheck
+ - err113
- errorlint
+ - exhaustive
+ - exhaustruct
+ - exhaustruct_v5
- forbidigo
+ - forcetypeassert
+ - funcorder
- funlen
- - gci
- gochecknoglobals
- gochecknoinits
- gocognit
+ - goconst
- gocritic
- gocyclo
+ - godoclint
- godot
- godox
- - goerr113
- - gofumpt
- - gomnd
+ - gomodguard
- gosec
- - ifshort
+ - govet
+ - inamedparam
+ - intrange
+ - ireturn
- lll
- makezero
+ - mnd
+ - modernize
- nakedret
- nestif
+ - nilnil
- nlreturn
+ - noinlineerr
- paralleltest
+ - perfsprint
+ - revive
- testpackage
- thelper
+ - varnamelen
- wrapcheck
- - interfacer
- - lll
- - nakedret
- - nestif
- - nlreturn
- - testpackage
- wsl
- - varnamelen
- - nilnil
- - ireturn
- - govet
- - forcetypeassert
- - cyclop
- - containedctx
- - revive
- - nosnakecase
- - exhaustruct
- - depguard
+ - wsl_v5
+ settings:
+ govet:
+ enable-all: true
+ disable:
+ - shadow
+ staticcheck:
+ checks:
+ - all
+ # quickfix suggestions are not defects
+ - -QF*
+ exclusions:
+ generated: lax
+ presets:
+ - comments
+ - common-false-positives
+ - legacy
+ - std-error-handling
+ rules:
+ # not needed
+ - linters:
+ - staticcheck
+ text: "ST1003: should not use underscores in package names"
+ - linters:
+ - staticcheck
+ path: rtype.go
+ - linters:
+ - staticcheck
+ path: error.go
+ paths:
+ - encode_optype.go
-issues:
- exclude-rules:
- # not needed
- - path: /*.go
- text: "ST1003: should not use underscores in package names"
- linters:
- - stylecheck
- - path: /*.go
- text: "don't use an underscore in package name"
- linters:
- - golint
- - path: rtype.go
- linters:
- - golint
- - stylecheck
- - path: error.go
- linters:
- - staticcheck
+formatters:
+ enable:
+ - gofmt
+ - goimports
+ exclusions:
+ generated: lax
+ paths:
+ - encode_optype.go
+issues:
# Maximum issues count per one linter. Set to 0 to disable. Default is 50.
max-issues-per-linter: 0
diff --git a/vendor/github.com/goccy/go-json/Makefile b/vendor/github.com/goccy/go-json/Makefile
index c030577dc..507b009fc 100644
--- a/vendor/github.com/goccy/go-json/Makefile
+++ b/vendor/github.com/goccy/go-json/Makefile
@@ -30,10 +30,86 @@ golangci-lint: | $(BIN_DIR)
GOLANGCI_LINT_TMP_DIR=$$(mktemp -d); \
cd $$GOLANGCI_LINT_TMP_DIR; \
go mod init tmp; \
- GOBIN=$(BIN_DIR) go install github.com/golangci/golangci-lint/cmd/golangci-lint@v1.54.2; \
+ GOBIN=$(BIN_DIR) go install github.com/golangci/golangci-lint/v2/cmd/golangci-lint@v2.13.2; \
rm -rf $$GOLANGCI_LINT_TMP_DIR; \
}
.PHONY: generate
generate:
go generate ./internal/...
+
+# Fails if the benchmarks of go-json under ./benchmarks are degraded compared with the master branch:
+# their mean is slower beyond -tolerance, or one of them is slower beyond -single-tolerance.
+# The benchmarks of the other libraries are never measured.
+# Options of internal/cmd/benchcheck can be passed by BENCH_CHECK_FLAGS.
+# e.g.) make bench-check BENCH_CHECK_FLAGS="-bench GoJson -no-cache"
+.PHONY: bench-check
+bench-check:
+ go run ./internal/cmd/benchcheck $(BENCH_CHECK_FLAGS)
+
+# bench-calibrate measures the benchmarks of HEAD against themselves, linked with other function layouts,
+# and prints how much the results of identical code differ: the noise which bench-check has to see beyond.
+# e.g.) make bench-calibrate BENCH_CHECK_FLAGS="-group decode"
+.PHONY: bench-calibrate
+bench-calibrate:
+ go run ./internal/cmd/benchcheck -calibrate -attempts 1 $(BENCH_CHECK_FLAGS)
+
+# bench-compare-encode prints the encode benchmarks of go-json and of bytedance/sonic side by side.
+# SonicStd is sonic configured to do what encoding/json, and go-json, do ( escape HTML, sort the keys of a map ),
+# and GoJsonLikeSonic is go-json configured to do what sonic does by default.
+# SonicFastest is sonic.ConfigFastest. SONIC_MAX_INLINE_DEPTH sets how deep sonic inlines the nested structs.
+# The Twitter benchmarks are the ones of sonic itself, with go-json beside it ( benchmarks/sonic_bench_test.go, under the license of sonic ).
+.PHONY: bench-compare-encode
+bench-compare-encode:
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_(Encode|Marshal|EncodeBigData|MarshalBigData).*_(GoJson|GoJsonLikeSonic|Sonic|SonicFastest|SonicStd)$$' -benchtime 300ms -count 3 .
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Twitter' -benchtime 300ms -count 3 .
+
+# bench-compare-decode prints the decode benchmarks of go-json and of bytedance/sonic side by side.
+# Sonic is sonic.ConfigDefault and SonicStd is sonic.ConfigStd, which validates the strings as encoding/json does.
+# SonicFastest is sonic at its fastest, and GoJsonUnmarshalOfNoCopyString go-json at its ( benchmarks/sonic_decode_test.go ).
+# SonicFastestValidating is SonicFastest with the checks which go-json does: the values which are skipped and the
+# strings are validated.
+# The Twitter benchmarks decode the payload of sonic's own benchmarks ( benchmarks/sonic_bench_test.go ), and the
+# Keys ones structs whose keys differ only, in length or in script ( benchmarks/decode_key_length_test.go ), and the
+# GitHub ones the responses of the REST and the GraphQL APIs of GitHub ( benchmarks/decode_github_test.go ), and
+# the OpenAI and Anthropic ones the responses and the streams of the APIs of LLMs ( benchmarks/llm_api_test.go ).
+# BENCH_LIVE_HEAP_MB gives the benchmarks a live heap of that size, as a real program has, which sets the goal of the
+# GC for every library alike ( benchmarks/live_heap_test.go ).
+.PHONY: bench-compare-decode
+bench-compare-decode:
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Decode_(Small|Medium|Large)Struct_Unmarshal_(GoJson|GoJsonUnmarshalOfNoCopyString|Sonic|SonicStd|SonicFastest|SonicFastestValidating)$$' -benchtime 300ms -count 3 .
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Decode_Twitter' -benchtime 300ms -count 3 .
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Decode_(Short|Medium|Long|NonASCII|UnknownNonASCII)Keys_Unmarshal_' -benchtime 300ms -count 3 .
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Decode_GitHub(REST|GraphQL)_Unmarshal_' -benchtime 300ms -count 3 .
+ cd benchmarks && go test -run '^$$' -bench '^Benchmark_Decode_(OpenAIChatCompletion|OpenAIResponse|AnthropicMessage)(Stream)?_Unmarshal_' -benchtime 300ms -count 3 .
+
+# bench-report measures the JSON libraries doing the same work, as the benchmark report does on the CI, and
+# renders the page and the summary into benchmarks/site ( see benchmarks/report_test.go ).
+.PHONY: bench-report
+bench-report:
+ mkdir -p benchmarks/site
+ cd benchmarks && BENCH_REPORT_OUT=$(CURDIR)/benchmarks/site/results-$$(go env GOARCH).json go test -run '^TestReport$$' -count=1 -timeout 60m -test.benchtime=100ms .
+ cd benchmarks && go run ./cmd/benchreport -out site site/results-$$(go env GOARCH).json
+
+# bench-profile-decode prints where the CPU time of the decode benchmarks of go-json goes.
+.PHONY: bench-profile-decode
+bench-profile-decode:
+ cd benchmarks && for b in Decode_SmallStruct_Unmarshal_GoJson Decode_MediumStruct_Unmarshal_GoJson Decode_LargeStruct_Unmarshal_GoJson Decode_TwitterBinding_Unmarshal_GoJson Decode_TwitterGeneric_Unmarshal_GoJson Decode_LargeStruct_Stream_GoJson; do \
+ go test -run '^$$' -bench "^Benchmark_$$b$$" -benchtime 3s -cpuprofile /tmp/$$b.prof -o /tmp/bench.test . > /dev/null && \
+ echo "=== $$b" && go tool pprof -top -nodecount=22 /tmp/bench.test /tmp/$$b.prof 2>/dev/null | tail -n +5 && \
+ echo "--- by line" && go tool pprof -top -lines -nodecount=30 /tmp/bench.test /tmp/$$b.prof 2>/dev/null | tail -n +6; \
+ done
+
+# bench-profile-encode prints where the CPU time of the encode benchmarks of go-json goes.
+.PHONY: bench-profile-encode
+bench-profile-encode:
+ cd benchmarks && for b in Encode_SmallStructCached_GoJson Encode_MediumStructCached_GoJson Encode_LargeStructCached_GoJson Encode_MapInterface_GoJson TwitterGeneric_GoJson TwitterGeneric_GoJsonLikeSonicFast TwitterParallelBinding_GoJson; do \
+ go test -run '^$$' -bench "^Benchmark_$${b}$$" -benchtime 3s -cpuprofile /tmp/$$b.prof -o /tmp/bench.test . > /dev/null && \
+ echo "=== $$b" && go tool pprof -top -nodecount=22 /tmp/bench.test /tmp/$$b.prof 2>/dev/null | tail -n +5 && \
+ echo "--- by line" && go tool pprof -top -lines -nodecount=30 /tmp/bench.test /tmp/$$b.prof 2>/dev/null | tail -n +6; \
+ done
+
+# bench-variants measures the candidates of the optimizations against what is used now.
+.PHONY: bench-variants
+bench-variants:
+ go test -run '^$$' -bench 'BenchmarkVariant|BenchmarkAppendString|BenchmarkScanString' -benchtime 300ms -count 2 ./internal/encoder/
diff --git a/vendor/github.com/goccy/go-json/README.md b/vendor/github.com/goccy/go-json/README.md
index 7bacc54f9..0d9ae35d4 100644
--- a/vendor/github.com/goccy/go-json/README.md
+++ b/vendor/github.com/goccy/go-json/README.md
@@ -8,26 +8,11 @@ Fast JSON encoder/decoder compatible with encoding/json for Go
 -# Roadmap
-
-```
-* version ( expected release date )
-
-* v0.9.0
- |
- | while maintaining compatibility with encoding/json, we will add convenient APIs
- |
- v
-* v1.0.0
-```
-
-We are accepting requests for features that will be implemented between v0.9.0 and v.1.0.0.
-If you have the API you need, please submit your issue [here](https://github.com/goccy/go-json/issues).
-
# Features
-- Drop-in replacement of `encoding/json`
+- Drop-in replacement of `encoding/json`: values are decoded and encoded, and errors are reported, as `encoding/json` of the Go version in use does, including Go 1.27, whose `encoding/json` is built on `encoding/json/v2`
- Fast ( See [Benchmark section](https://github.com/goccy/go-json#benchmarks) )
+- `MarshalOf` and `UnmarshalOf`, which take the value by its type and save the allocations `Marshal` and `Unmarshal` need for an `interface{}` argument
- Flexible customization with options
- Coloring the encoded string
- Can propagate context.Context to `MarshalJSON` or `UnmarshalJSON`
@@ -59,10 +44,12 @@ Replace import statement from `encoding/json` to `github.com/goccy/go-json`
| [segmentio/encoding/json](https://github.com/segmentio/encoding/tree/master/json) | yes | yes | partial |
| [jettison](https://github.com/wI2L/jettison) | yes | no | no |
| [simdjson-go](https://github.com/minio/simdjson-go) | no | yes | no |
+| [bytedance/sonic](https://github.com/bytedance/sonic) | yes | yes | partial |
| goccy/go-json | yes | yes | yes |
- `json-iterator/go` isn't compatible with `encoding/json` in many ways (e.g. https://github.com/json-iterator/go/issues/229 ), but it hasn't been supported for a long time.
- `segmentio/encoding/json` is well supported for encoders, but some are not supported for decoder APIs such as `Token` ( streaming decode )
+- `bytedance/sonic` is compatible with `encoding/json` in its `ConfigStd` configuration; by default it doesn't escape HTML, sort the keys of maps or validate strings. It decodes and encodes by native code: SIMD code and, on amd64, code generated at run time. The benchmarks of this repository compare go-json with sonic in both configurations ( see below ).
## Other libraries
@@ -79,22 +66,26 @@ Also, development seems to have already stopped
# Benchmarks
-```
-$ cd benchmarks
-$ go test -bench .
-```
+[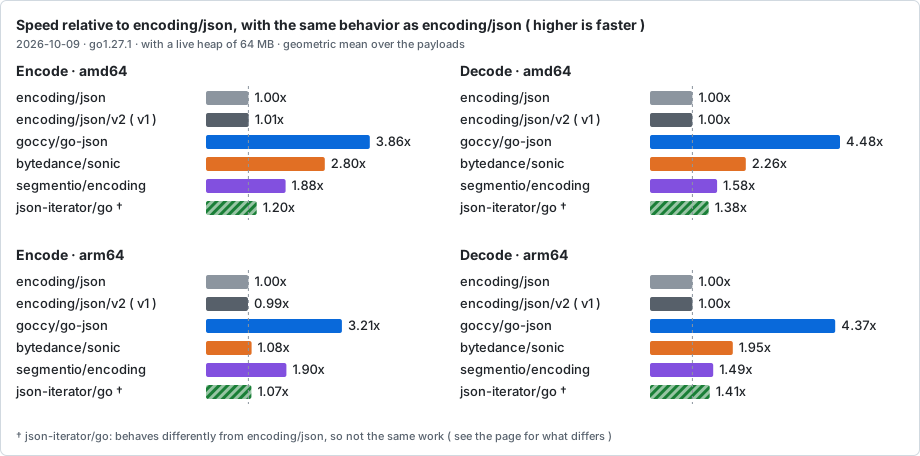](https://goccy.github.io/go-json/)
-## Encode
+The JSON libraries of Go are measured doing the same work on GitHub Actions, on amd64 and arm64, and the results are published at **https://goccy.github.io/go-json/**, measured again whenever go-json, the version of a library or the report changes. The page has every payload, the encode and decode of each library, the allocations, and the results without a live heap.
-
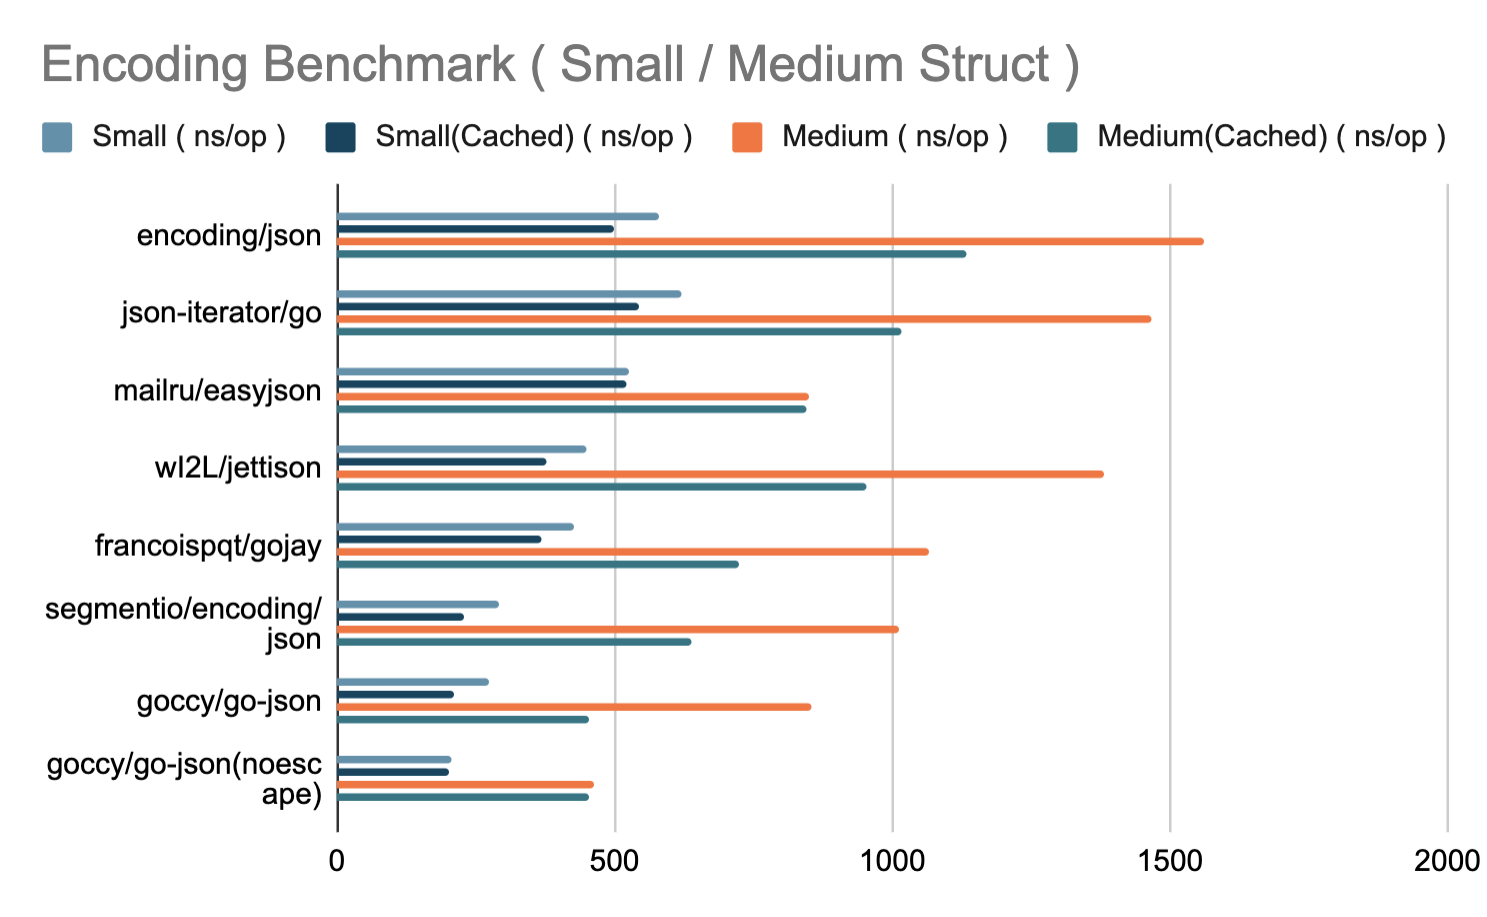 -
 +A comparison is fair only between libraries doing the same work, so the results are shown by category of behavior: the behavior of `encoding/json`, the behavior of `encoding/json/v2`, the behavior of `encoding/json` without HTML escaping, key sorting and string copying, and every library at its fastest. In each category, every library is configured by its options to behave as the category requires, as far as its options allow, and as fast as they allow. Every run checks the behavior of each library on small probes before it measures it, and a library which behaves differently is still shown, marked, with what differs. The result files are attested by GitHub Artifact Attestations: `gh attestation verify` tells that they were produced by the workflow of this repository.
-## Decode
+To run the report locally:
-
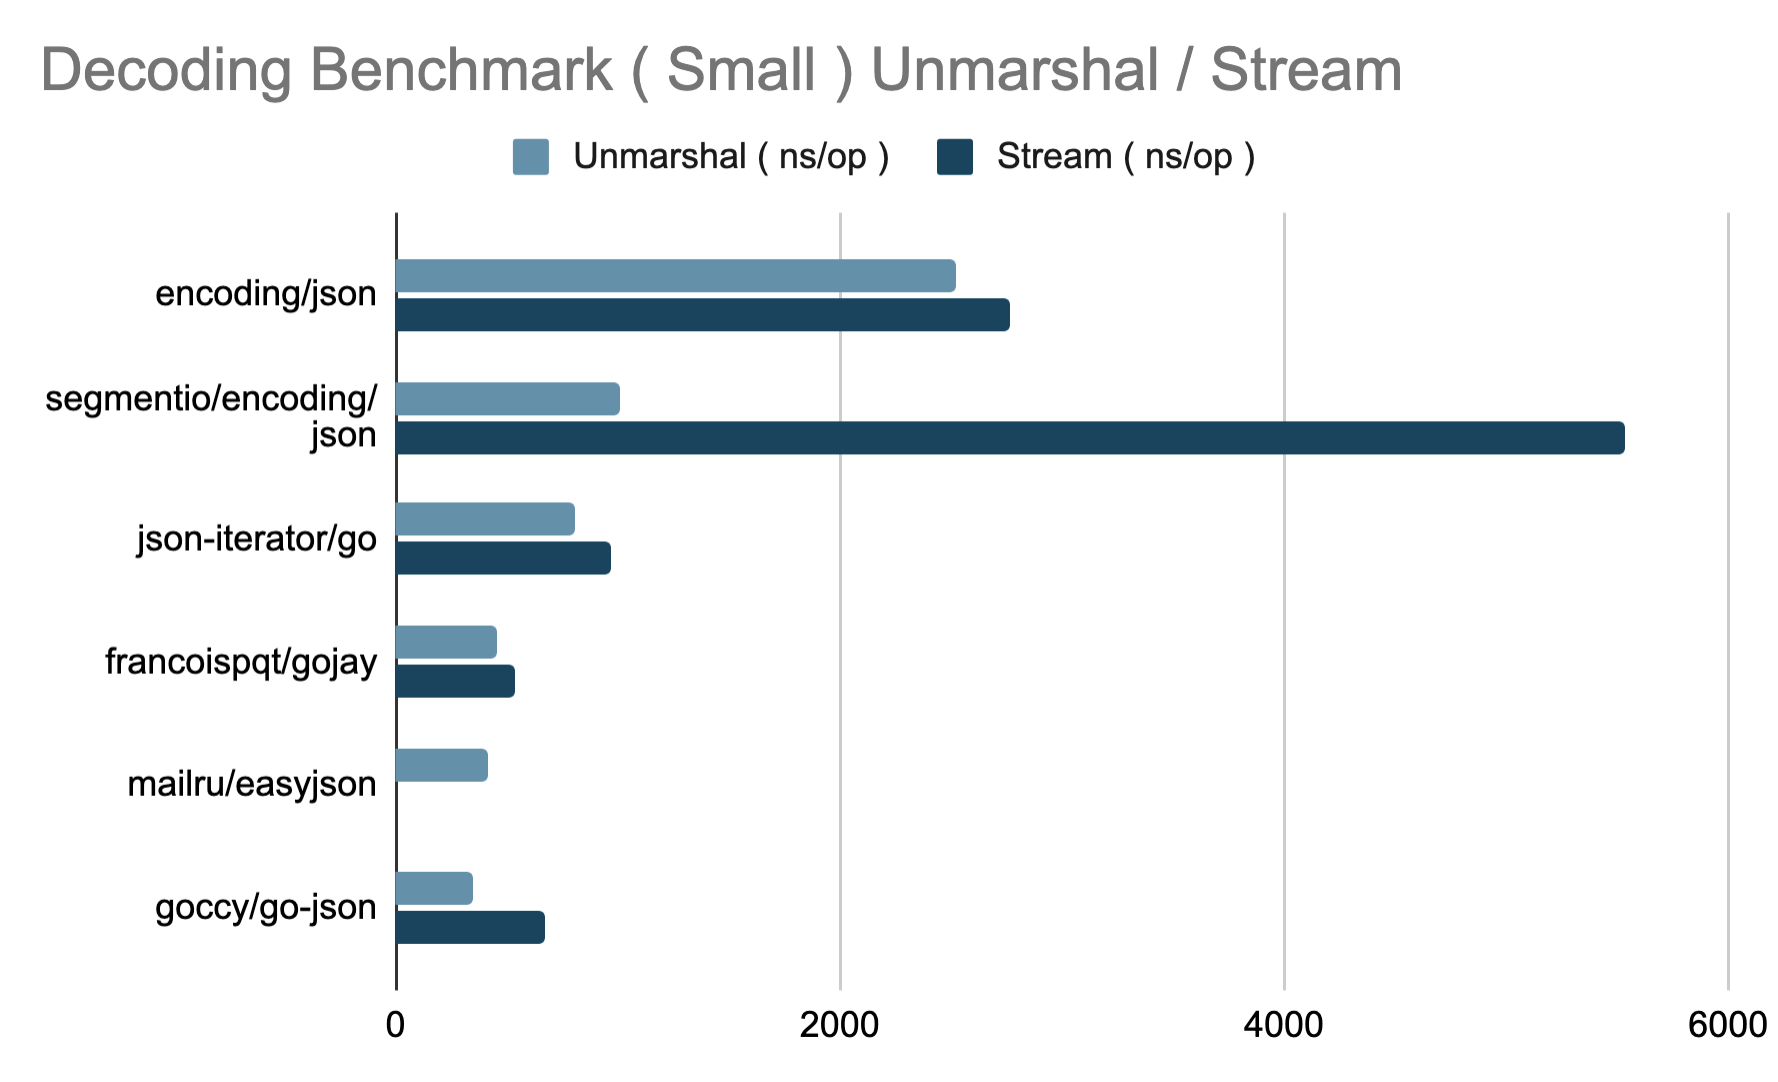 -
 -
 +```
+$ make bench-report
+```
+
+To compare go-json with `bytedance/sonic` side by side, benchmark by benchmark:
+
+```
+$ make bench-compare-encode
+$ make bench-compare-decode
+```
+`BENCH_LIVE_HEAP_MB=64 make bench-compare-decode` runs the decode benchmarks with 64 MB of live heap, as a real program has: the GC then runs less often, as it does in such a program.
# Fuzzing
@@ -128,7 +119,7 @@ type buffer struct {
}
var bufPool = sync.Pool{
- New: func() interface{} {
+ New: func() any {
return &buffer{data: make([]byte, 0, 1024)}
},
}
@@ -163,7 +154,7 @@ type emptyInterface struct {
var typeToEncoder = map[uintptr]func(unsafe.Pointer)([]byte, error){}
-func Marshal(v interface{}) ([]byte, error) {
+func Marshal(v any) ([]byte, error) {
iface := (*emptyInterface)(unsafe.Pointer(&v)
typeptr := uintptr(iface.typ)
if enc, exists := typeToEncoder[typeptr]; exists {
@@ -179,29 +170,38 @@ func Marshal(v interface{}) ([]byte, error) {
## Encoder
-### Do not escape arguments of `Marshal`
+### Encode a value without copying it to the heap by `MarshalOf`
-`json.Marshal` and `json.Unmarshal` receive `interface{}` value and they perform type determination dynamically to process.
-In normal case, you need to use the `reflect` library to determine the type dynamically, but since `reflect.Type` is defined as `interface`, when you call the method of `reflect.Type`, The reflect's argument is escaped.
+`json.Marshal` receives an `interface{}` value. A value which is not a pointer is copied to the heap when it is converted to an `interface{}` value, so `json.Marshal(v)` allocates the copy of `v` for every call, in addition to the result.
-Therefore, the arguments for `Marshal` and `Unmarshal` are always escaped to the heap.
-However, `go-json` can use the feature of `reflect.Type` while avoiding escaping.
+`json.MarshalOf[T]` receives the value by its type. It copies the value to a value in the heap which is reused, so the result is the only allocation.
-`reflect.Type` is defined as `interface`, but in reality `reflect.Type` is implemented only by the structure `rtype` defined in the `reflect` package.
-For this reason, to date `reflect.Type` is the same as `*reflect.rtype`.
+```go
+b, err := json.MarshalOf(v)
+```
-Therefore, by directly handling `*reflect.rtype`, which is an implementation of `reflect.Type`, it is possible to avoid escaping because it changes from `interface` to using `struct`.
+Which one to use depends on what is passed:
-The technique for working with `*reflect.rtype` directly from `go-json` is implemented at [rtype.go](https://github.com/goccy/go-json/blob/master/internal/runtime/rtype.go)
+| What is passed | Recommended | Why |
+|---|---|---|
+| A value which is not a pointer ( a struct, an `int`, a `string`, ... ) | `json.MarshalOf(v)` | It saves the allocation of the copy: about 15% faster for a small struct. `v` can also stay on the stack of the caller, which `json.Marshal(&v)` doesn't allow. |
+| A pointer or a map | either | Such a value is stored in an `interface{}` value without an allocation, so they are the same. |
+| A large value which is already referred to by a pointer `p` | `json.Marshal(p)` | `json.MarshalOf(*p)` copies the whole value, which costs more as the value gets larger. |
-Also, the same technique is cut out as a library ( https://github.com/goccy/go-reflect )
+`MarshalNoEscape`, which left the value on the stack, is deprecated: the encoder refers to the value by its address, and the address gets invalid when the stack of the goroutine is moved. It is now the same as `Marshal`.
-Initially this feature was the default behavior of `go-json`.
-But after careful testing, I found that I passed a large value to `json.Marshal()` and if the argument could not be assigned to the stack, it could not be properly escaped to the heap (a bug in the Go compiler).
+### Let the encoder order the fields of a struct by `OptimizeFieldOrder`
-Therefore, this feature will be provided as an **optional** until this issue is resolved.
+`encoding/json` writes the fields of a struct in the order of the struct, and so does `go-json` by default. A JSON object doesn't define the order of its keys, so when the order doesn't matter to the reader of the JSON, the option `json.OptimizeFieldOrder()` lets the encoder order the fields as it encodes them fastest:
-To use it, add `NoEscape` like `MarshalNoEscape()`
+```go
+b, err := json.MarshalWithOption(v, json.OptimizeFieldOrder())
+```
+
+- The fields of the same kind ( `int`, `uint`, `float64`, `string`, `bool` ) are put together, in the order of the first field of each kind, and are encoded without a dispatch of the VM between them ( see below ).
+- A field of the struct's own type ( the next node of a list ), if there is one, is put last, so that a list of values is encoded in one frame of the VM instead of one frame for each value.
+
+The keys are the same, only their order differs. The opcodes of a type are compiled for the option apart from the ones in the order of the struct, so the two can be used together.
### Encoding using opcode sequence
@@ -333,33 +333,38 @@ The technique of implementing recursive processing with the `JMP` operation whil
For more details, please refer to [the article](https://engineering.mercari.com/blog/entry/1599563768-081104c850) ( but Japanese only ).
-### Dispatch by typeptr from map to slice
+### Dispatch by typeptr without a lock
When retrieving the data cached from the type information by `typeptr`, we usually use map.
Map requires exclusive control, so use `sync.Map` for a naive implementation.
-However, this is slow, so it's a good idea to use the `atomic` package for exclusive control as implemented by `segmentio/encoding/json` ( https://github.com/segmentio/encoding/blob/master/json/codec.go#L41-L55 ).
+However, this is slow: as a result of profiling, `runtime.mapaccess2` accounted for a significant percentage of the execution time.
-This implementation slows down the set instead of speeding up the get, but it works well because of the nature of the library, it encodes much more for the same type.
+`go-json` looks up the cache in two steps, neither of which takes a lock:
-However, as a result of profiling, I noticed that `runtime.mapaccess2` accounts for a significant percentage of the execution time. So I thought if I could change the lookup from map to slice.
+1. The runtime context, which is taken from a pool for every call, remembers the opcodes of the types it encoded last. Most of the programs encode the same types again and again, so this is a load and a comparison in most cases.
+2. Otherwise a hash table with open addressing is looked up by the address of the type. An entry is written once ( the value, and then the key, by the `atomic` package ), and the table is replaced by a larger one when it gets half full, so a reader never waits for a writer. A value is stored only when a type is compiled for the first time.
-There is an API named `typelinks` defined in the `runtime` package that the `reflect` package uses internally.
-This allows you to get all the type information defined in the binary at runtime.
+An earlier version used a slice which had an element for every address a type of the program can be at, found by `typelinks` of the `runtime` package through `go:linkname`. It was replaced because it depended on the internals of the runtime, used memory in proportion to the size of the program, had to fall back to a map for a large program, and made the GC scan the whole slice in every cycle.
-The fact that all type information can be acquired means that by constructing slices in advance with the acquired total number of type information, it is possible to look up with the value of `typeptr` without worrying about out-of-range access.
+If you want to know more, please refer to the implementation [here](https://github.com/goccy/go-json/blob/master/internal/runtime/type_cache.go)
-However, if there is too much type information, it will use a lot of memory, so by default we will only use this optimization if the slice size fits within **2Mib** .
+## Decoder
-If this approach is not available, it will fall back to the `atomic` based process described above.
+### Dispatch by typeptr without a lock
-If you want to know more, please refer to the implementation [here](https://github.com/goccy/go-json/blob/master/internal/runtime/type.go#L36-L100)
+Like the encoder, the decoder uses `typeptr` to call the decoder built for the type. The runtime context of a call remembers the decoders of the types it decoded last, and otherwise a hash table which is read without a lock is looked up, as the encoder does.
-## Decoder
+### Decode a value without an allocation for the argument by `UnmarshalOf`
+
+`json.Unmarshal` receives an `interface{}` value, which makes the value escape to the heap. `json.UnmarshalOf[T]` receives the pointer by its type: it decodes into a value in the heap which is reused and copies the result to `*v`, so `v` may point to a variable on the stack of the caller, and a value without a pointer, slice or map to fill is decoded without an allocation.
-### Dispatch by typeptr from map to slice
+```go
+var v T
+err := json.UnmarshalOf(data, &v)
+```
-Like the encoder, the decoder also uses typeptr to call the dedicated process.
+The value is copied twice, so `json.Unmarshal` is faster for a large value which is in the heap anyway.
### Faster termination character inspection using NUL character
@@ -391,6 +396,8 @@ for {
}
```
+`Unmarshal` copies the input once, into a buffer followed by the `NUL` character which the runtime context keeps from a call to the next, so the copy allocates nothing in most calls. The stream decoder ( `Decoder` ) reads until its buffer holds a whole value, puts the `NUL` character after it, and decodes it by the same decoders.
+
### Use Boundary Check Elimination
Due to the `NUL` character optimization, the Go compiler does a boundary check every time, even though `buf[cursor]` does not cause out-of-range access.
@@ -413,101 +420,39 @@ for {
}
```
-### Checking the existence of fields of struct using Bitmaps
+### Scanning strings eight bytes at a time, and by SIMD
-I found by the profiling result, in the struct decode, lookup process for field was taking a long time.
+A string is scanned a word ( eight bytes ) at a time: a few bit operations on the word tell whether one of its bytes is a quote, a backslash or a control character, and whether one is not ASCII, so a byte is looked at alone only where the string ends or has an escape. After its first 64 bytes, the rest of a long string is scanned by AVX2 on amd64.
-For example, consider decoding a string like `{"a":1,"b":2,"c":3}` into the following structure:
+A string with an escape is decoded in the same pass as it is scanned from its first escape on: the runs of plain bytes between the escapes are moved at once, and the escapes are validated and decoded as they are met.
-```go
-type T struct {
- A int `json:"a"`
- B int `json:"b"`
- C int `json:"c"`
-}
-```
-
-At this time, it was found that it takes a lot of time to acquire the decoding process corresponding to the field from the field name as shown below during the decoding process.
+### Strings copied into an arena, or referring to the input
-```go
-fieldName := decodeKey(buf, cursor) // "a" or "b" or "c"
-decoder, exists := fieldToDecoderMap[fieldName] // so slow
-if exists {
- decoder(buf, cursor)
-} else {
- skipValue(buf, cursor)
-}
-```
+A decoded string is a copy, as with `encoding/json`, so the input may be modified after the call. The short strings are copied into chunks of up to 16 KB shared by the strings of a runtime context, instead of an allocation for each. With the option `json.DecodeNoCopyString()`, a string without an escape refers to the input without a copy.
-To improve this process, `json-iterator/go` is optimized so that it can be branched by switch-case when the number of fields in the structure is 10 or less (switch-case is faster than map). However, there is a risk of hash collision because the value hashed by the FNV algorithm is used for conditional branching. Also, `gojay` processes this part at high speed by letting the library user yourself write `switch-case`.
+### Finding the field of a key by its words
+The fields of a struct are in a hash table keyed by their keys folded to lower case, and a key of the input is looked up by two words: its first eight bytes and its last eight bytes, which overlap for a key shorter than 16 bytes. A key of up to 16 bytes is compared by its length and these two words only, and a key of ASCII is folded eight bytes at a time, so a field is found by a few word operations whatever the number of fields and the length of the keys. A key matches the field with the same key, or else the first field with the same key by case folding, as with `encoding/json`.
-`go-json` considers and implements a new approach that is different from these. I call this **bitmap field optimization**.
+An earlier version found the field by bitmaps of the characters of the keys, `[maxKeyLength][256]int8` or `int16`. It was replaced because it worked only for structs of up to 16 fields and keys shorter than 64 bytes, and fell back to a map for the others.
-The range of values per character can be represented by `[256]byte`. Also, if the number of fields in the structure is 8 or less, `int8` type can represent the state of each field.
-In other words, it has the following structure.
+### Parsing numbers in one pass
-- Base ( 8bit ): `00000000`
-- Key "a": `00000001` ( assign key "a" to the first bit )
-- Key "b": `00000010` ( assign key "b" to the second bit )
-- Key "c": `00000100` ( assign key "c" to the third bit )
+The digits of a number are accumulated as they are read and validated by the grammar of JSON. A float with a mantissa of up to 19 digits is computed from the mantissa and a power of ten: directly when both are held exactly by a float64, and else by a table of the powers of ten as 128-bit significands. The result is the one of `strconv.ParseFloat`, which is called only for the rare numbers the table doesn't decide.
-Bitmap structure is the following
+### Skipping values while validating them
-```
- | key index(0) |
-------------------------
- 0 | 00000000 |
- 1 | 00000000 |
-~~ | |
-97 (a) | 00000001 |
-98 (b) | 00000010 |
-99 (c) | 00000100 |
-~~ | |
-255 | 00000000 |
-```
-
-You can think of this as a Bitmap with a height of `256` and a width of the maximum string length in the field name.
-In other words, it can be represented by the following type .
-
-```go
-[maxFieldKeyLength][256]int8
-```
-
-When decoding a field character, check whether the corresponding character exists by referring to the pre-built bitmap like the following.
-
-```go
-var curBit int8 = math.MaxInt8 // 11111111
-
-c := char(buf, cursor)
-bit := bitmap[keyIdx][c]
-curBit &= bit
-if curBit == 0 {
- // not found field
-}
-```
-
-If `curBit` is not `0` until the end of the field string, then the string is
-You may have hit one of the fields.
-But the possibility is that if the decoded string is shorter than the field string, you will get a false hit.
-
-- input: `{"a":1}`
-```go
-type T struct {
- X int `json:"abc"`
-}
-```
-※ Since `a` is shorter than `abc`, it can decode to the end of the field character without `curBit` being 0.
+The value of a key which matches no field is not decoded, but it is still checked by the grammar of JSON, as `encoding/json` checks the whole input: an invalid value is a syntax error wherever it is. The skip is a state machine which calls no function in its loop, so that its state stays in the registers, and the rare cases it doesn't handle itself ( an escape, a number which is not an integer, a deep nesting ) are handled by its caller, which resumes it.
-Rest assured. In this case, it doesn't matter because you can tell if you hit by comparing the string length of `a` with the string length of `abc`.
+To find the end of an object or an array without decoding it, as the stream decoder does, the bytes are scanned 64 at a time: masks of the quotes, backslashes and brackets of a block are made by AVX2 on amd64, by NEON on arm64 and by words elsewhere, and a prefix XOR of the quotes tells which bytes are inside a string.
-Finally, calculate the position of the bit where `1` is set and get the corresponding value, and you're done.
+### Decoding `interface{}` values without reflection
-Using this technique, field lookups are possible with only bitwise operations and access to slices.
+The values of an array or an object decoded into `interface{}` are pushed to a stack of the runtime context, and a `[]interface{}` or a `map[string]interface{}` is made of their number at the end: a map filled entry by entry grows and moves its entries several times on the way. The numbers and the strings are stored into `interface{}` values from slabs, instead of an allocation for each, and the empty arrays share one empty slice.
-`go-json` uses a similar technique for fields with 9 or more and 16 or less fields. At this time, Bitmap is constructed as `[maxKeyLen][256]int16` type.
+### Sizing slices and maps by the last value
-Currently, this optimization is not performed when the maximum length of the field name is long (specifically, 64 bytes or more) in addition to the limitation of the number of fields from the viewpoint of saving memory usage.
+The elements of an array are decoded directly into the slice, which is allocated for the length of the array the decoder decoded last, and a map is made for the number of the entries of the last object: the values of a type often have the same size. The zero values the entries of a map are decoded into are reused from a pool.
### Others
diff --git a/vendor/github.com/goccy/go-json/decode.go b/vendor/github.com/goccy/go-json/decode.go
index 74c6ac3bc..c455b79a8 100644
--- a/vendor/github.com/goccy/go-json/decode.go
+++ b/vendor/github.com/goccy/go-json/decode.go
@@ -2,9 +2,7 @@ package json
import (
"context"
- "fmt"
"io"
- "reflect"
"unsafe"
"github.com/goccy/go-json/internal/decoder"
@@ -16,58 +14,53 @@ type Decoder struct {
s *decoder.Stream
}
-const (
- nul = '\000'
-)
-
type emptyInterface struct {
- typ *runtime.Type
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
-func unmarshal(data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
- src := make([]byte, len(data)+1) // append nul byte to the end
- copy(src, data)
-
+func unmarshal(data []byte, v any, optFuncs ...DecodeOptionFunc) error {
header := (*emptyInterface)(unsafe.Pointer(&v))
if err := validateType(header.typ, uintptr(header.ptr)); err != nil {
return err
}
- dec, err := decoder.CompileToGetDecoder(header.typ)
+ ctx := decoder.TakeRuntimeContext()
+ dec, err := ctx.DecoderOf(header.typ)
if err != nil {
+ decoder.ReleaseRuntimeContext(ctx)
return err
}
- ctx := decoder.TakeRuntimeContext()
- ctx.Buf = src
+ src := ctx.SetInput(data)
ctx.Option.Flags = 0
for _, optFunc := range optFuncs {
optFunc(ctx.Option)
}
cursor, err := dec.Decode(ctx, 0, 0, header.ptr)
- if err != nil {
- decoder.ReleaseRuntimeContext(ctx)
- return err
+ if err == nil {
+ // src is the buffer of the context: it is validated before the context is released
+ err = validateEndBuf(src, cursor)
+ }
+ if err != nil || ctx.HasTypeError() {
+ return endWithError(ctx, header.typ, err)
}
decoder.ReleaseRuntimeContext(ctx)
- return validateEndBuf(src, cursor)
+ return nil
}
-func unmarshalContext(ctx context.Context, data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
- src := make([]byte, len(data)+1) // append nul byte to the end
- copy(src, data)
-
+func unmarshalContext(ctx context.Context, data []byte, v any, optFuncs ...DecodeOptionFunc) error {
header := (*emptyInterface)(unsafe.Pointer(&v))
if err := validateType(header.typ, uintptr(header.ptr)); err != nil {
return err
}
- dec, err := decoder.CompileToGetDecoder(header.typ)
+ rctx := decoder.TakeRuntimeContext()
+ dec, err := rctx.DecoderOf(header.typ)
if err != nil {
+ decoder.ReleaseRuntimeContext(rctx)
return err
}
- rctx := decoder.TakeRuntimeContext()
- rctx.Buf = src
+ src := rctx.SetInput(data)
rctx.Option.Flags = 0
rctx.Option.Flags |= decoder.ContextOption
rctx.Option.Context = ctx
@@ -75,12 +68,15 @@ func unmarshalContext(ctx context.Context, data []byte, v interface{}, optFuncs
optFunc(rctx.Option)
}
cursor, err := dec.Decode(rctx, 0, 0, header.ptr)
- if err != nil {
- decoder.ReleaseRuntimeContext(rctx)
- return err
+ if err == nil {
+ // src is the buffer of the context: it is validated before the context is released
+ err = validateEndBuf(src, cursor)
+ }
+ if err != nil || rctx.HasTypeError() {
+ return endWithError(rctx, header.typ, err)
}
decoder.ReleaseRuntimeContext(rctx)
- return validateEndBuf(src, cursor)
+ return nil
}
var (
@@ -91,8 +87,7 @@ func extractFromPath(path *Path, data []byte, optFuncs ...DecodeOptionFunc) ([][
if path.path.RootSelectorOnly {
return [][]byte{data}, nil
}
- src := make([]byte, len(data)+1) // append nul byte to the end
- copy(src, data)
+ src := decoder.NewInput(data)
ctx := decoder.TakeRuntimeContext()
ctx.Buf = src
@@ -114,61 +109,51 @@ func extractFromPath(path *Path, data []byte, optFuncs ...DecodeOptionFunc) ([][
return paths, nil
}
-func unmarshalNoEscape(data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
- src := make([]byte, len(data)+1) // append nul byte to the end
- copy(src, data)
-
- header := (*emptyInterface)(unsafe.Pointer(&v))
-
- if err := validateType(header.typ, uintptr(header.ptr)); err != nil {
- return err
- }
- dec, err := decoder.CompileToGetDecoder(header.typ)
- if err != nil {
- return err
- }
-
- ctx := decoder.TakeRuntimeContext()
- ctx.Buf = src
- ctx.Option.Flags = 0
- for _, optFunc := range optFuncs {
- optFunc(ctx.Option)
- }
- cursor, err := dec.Decode(ctx, 0, 0, noescape(header.ptr))
- if err != nil {
- decoder.ReleaseRuntimeContext(ctx)
- return err
+// endWithError releases the context of a decoding into a value of the pointer type typ, which failed with err or
+// else has a type error, and returns the error: the type error is returned only when the whole input is valid, as
+// encoding/json does. It takes the decoder of typ again, so that the functions which decode keep nothing more
+// across their call of it: an error is rare.
+//
+//go:noinline
+func endWithError(ctx *decoder.RuntimeContext, typ unsafe.Pointer, err error) error {
+ err = inputSyntaxError(ctx, err)
+ if err == nil {
+ var dec decoder.Decoder
+ if dec, err = ctx.DecoderOf(typ); err == nil {
+ err = ctx.TypeError(dec, runtime.TypeOfPtr(typ), 0, 0)
+ }
}
+ ctx.DiscardTypeError()
decoder.ReleaseRuntimeContext(ctx)
- return validateEndBuf(src, cursor)
+ return err
}
-func validateEndBuf(src []byte, cursor int64) error {
- for {
- switch src[cursor] {
- case ' ', '\t', '\n', '\r':
- cursor++
- continue
- case nul:
- return nil
+// inputSyntaxError returns err, the error of the decoding of the input of ctx, or, for a syntax error, the first
+// syntax error of the input as encoding/json reports it: it checks the whole input before it decodes it.
+func inputSyntaxError(ctx *decoder.RuntimeContext, err error) error {
+ if _, ok := err.(*errors.SyntaxError); ok {
+ if serr := ctx.InputSyntaxError(); serr != nil {
+ return serr
}
- return errors.ErrSyntax(
- fmt.Sprintf("invalid character '%c' after top-level value", src[cursor]),
- cursor+1,
- )
}
+ return err
}
-//nolint:staticcheck
-//go:nosplit
-func noescape(p unsafe.Pointer) unsafe.Pointer {
- x := uintptr(p)
- return unsafe.Pointer(x ^ 0)
+// validateEndBuf returns the syntax error of what follows the value, which ends at cursor, in src, the input
+// followed by the nul byte: only white spaces may follow it. The value is most often at the end of the input, which
+// is checked without a call.
+func validateEndBuf(src []byte, cursor int64) error {
+ if cursor == int64(len(src))-1 {
+ return nil
+ }
+ return decoder.ValidateEnd(src, cursor)
}
-func validateType(typ *runtime.Type, p uintptr) error {
- if typ == nil || typ.Kind() != reflect.Ptr || p == 0 {
- return &InvalidUnmarshalError{Type: runtime.RType2Type(typ)}
+// validateType validates that the value is not nil.
+// Whether the type is a pointer is validated when its decoder is compiled, once per type.
+func validateType(typ unsafe.Pointer, p uintptr) error {
+ if typ == nil || p == 0 {
+ return &InvalidUnmarshalError{Type: runtime.TypeOfPtr(typ)}
}
return nil
}
@@ -195,46 +180,33 @@ func (d *Decoder) Buffered() io.Reader {
//
// See the documentation for Unmarshal for details about
// the conversion of JSON into a Go value.
-func (d *Decoder) Decode(v interface{}) error {
+func (d *Decoder) Decode(v any) error {
return d.DecodeWithOption(v)
}
// DecodeContext reads the next JSON-encoded value from its
// input and stores it in the value pointed to by v with context.Context.
-func (d *Decoder) DecodeContext(ctx context.Context, v interface{}) error {
+func (d *Decoder) DecodeContext(ctx context.Context, v any) error {
d.s.Option.Flags |= decoder.ContextOption
d.s.Option.Context = ctx
return d.DecodeWithOption(v)
}
-func (d *Decoder) DecodeWithOption(v interface{}, optFuncs ...DecodeOptionFunc) error {
+func (d *Decoder) DecodeWithOption(v any, optFuncs ...DecodeOptionFunc) error {
header := (*emptyInterface)(unsafe.Pointer(&v))
- typ := header.typ
- ptr := uintptr(header.ptr)
- typeptr := uintptr(unsafe.Pointer(typ))
- // noescape trick for header.typ ( reflect.*rtype )
- copiedType := *(**runtime.Type)(unsafe.Pointer(&typeptr))
-
- if err := validateType(copiedType, ptr); err != nil {
+ if err := validateType(header.typ, uintptr(header.ptr)); err != nil {
return err
}
- dec, err := decoder.CompileToGetDecoder(typ)
+ dec, err := d.s.DecoderOf(header.typ)
if err != nil {
return err
}
- if err := d.s.PrepareForDecode(); err != nil {
- return err
- }
s := d.s
for _, optFunc := range optFuncs {
optFunc(s.Option)
}
- if err := dec.DecodeStream(s, 0, header.ptr); err != nil {
- return err
- }
- s.Reset()
- return nil
+ return s.Decode(dec, header.typ, header.ptr)
}
func (d *Decoder) More() bool {
@@ -249,15 +221,15 @@ func (d *Decoder) Token() (Token, error) {
// is a struct and the input contains object keys which do not match any
// non-ignored, exported fields in the destination.
func (d *Decoder) DisallowUnknownFields() {
- d.s.DisallowUnknownFields = true
+ d.s.Option.Flags |= decoder.DisallowUnknownFieldsOption
}
func (d *Decoder) InputOffset() int64 {
- return d.s.TotalOffset()
+ return d.s.InputOffset()
}
// UseNumber causes the Decoder to unmarshal a number into an interface{} as a
// Number instead of as a float64.
func (d *Decoder) UseNumber() {
- d.s.UseNumber = true
+ d.s.Option.Flags |= decoder.UseNumberOption
}
diff --git a/vendor/github.com/goccy/go-json/decode_of.go b/vendor/github.com/goccy/go-json/decode_of.go
new file mode 100644
index 000000000..438c30525
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/decode_of.go
@@ -0,0 +1,78 @@
+package json
+
+import (
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/decoder"
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// UnmarshalOf parses the JSON-encoded data and stores the result in the value pointed to by v, as Unmarshal does.
+//
+// Unmarshal takes its argument as an interface value, and the decoder refers to the value by its address,
+// so the value always escapes to the heap. UnmarshalOf takes the pointer by its type and never gives it to
+// the decoder: it copies *v to a value in the heap which is reused, decodes into that value, and copies the
+// result back to *v. So v may point to a variable on the stack of the caller, and a value which needs no
+// allocation of its own ( no pointer, slice or map to fill ) is decoded without an allocation: the strings
+// are copied into a buffer shared by the calls, or refer to data with DecodeNoCopyString.
+//
+// A value is copied twice, so a large value is faster with Unmarshal when it is in the heap anyway. As the
+// result is a copy, an UnmarshalJSON or UnmarshalText method of a type in the value must not keep the address
+// of its receiver, which is the address of the copy.
+func UnmarshalOf[T any](data []byte, v *T, optFuncs ...DecodeOptionFunc) error {
+ ptrType := reflect.TypeOf((*T)(nil))
+ if v == nil {
+ return &InvalidUnmarshalError{Type: ptrType}
+ }
+ ctx := decoder.TakeRuntimeContext()
+ dec, err := ctx.DecoderOf(runtime.TypePtr(ptrType))
+ if err != nil {
+ decoder.ReleaseRuntimeContext(ctx)
+ return err
+ }
+ var p unsafe.Pointer
+ if unsafe.Sizeof(*v) > maxReusedValueSize {
+ // every context of the pool would keep such a value: it is left to the GC.
+ p = reflect.New(ptrType.Elem()).UnsafePointer()
+ } else {
+ p = ctx.TakeValue(ptrType.Elem(), runtime.TypePtr(ptrType.Elem()))
+ }
+ *(*T)(p) = *v
+
+ src := ctx.SetInput(data)
+ ctx.Option.Flags = 0
+ for _, optFunc := range optFuncs {
+ optFunc(ctx.Option)
+ }
+ cursor, err := dec.Decode(ctx, 0, 0, p)
+ if err == nil {
+ // a type error is returned only when the whole input is valid, as encoding/json does
+ if err = validateEndBuf(src, cursor); err == nil && ctx.HasTypeError() {
+ err = typeErrorOf(ctx, runtime.TypePtr(reflect.TypeOf((*T)(nil))))
+ }
+ }
+ if err != nil {
+ err = inputSyntaxError(ctx, err)
+ }
+ ctx.DiscardTypeError()
+ // What was decoded before an error is stored too, as Unmarshal does.
+ *v = *(*T)(p)
+ // the pool must not keep what the value refers to alive.
+ var zero T
+ *(*T)(p) = zero
+ decoder.ReleaseRuntimeContext(ctx)
+ return err
+}
+
+// typeErrorOf returns the type error of the decoding into a value of the pointer type typ. It takes the decoder of
+// typ again, so that UnmarshalOf keeps nothing more across its call of the decoder: a type error is rare.
+//
+//go:noinline
+func typeErrorOf(ctx *decoder.RuntimeContext, typ unsafe.Pointer) error {
+ dec, err := ctx.DecoderOf(typ)
+ if err != nil {
+ return err
+ }
+ return ctx.TypeError(dec, runtime.TypeOfPtr(typ), 0, 0)
+}
diff --git a/vendor/github.com/goccy/go-json/docker-compose.yml b/vendor/github.com/goccy/go-json/docker-compose.yml
index db40c79ad..880a37a40 100644
--- a/vendor/github.com/goccy/go-json/docker-compose.yml
+++ b/vendor/github.com/goccy/go-json/docker-compose.yml
@@ -1,7 +1,6 @@
-version: '2'
services:
go-json:
- image: golang:1.18
+ image: golang:1.25
volumes:
- '.:/go/src/go-json'
deploy:
diff --git a/vendor/github.com/goccy/go-json/encode.go b/vendor/github.com/goccy/go-json/encode.go
index c5173825a..65eedbaf3 100644
--- a/vendor/github.com/goccy/go-json/encode.go
+++ b/vendor/github.com/goccy/go-json/encode.go
@@ -4,6 +4,7 @@ import (
"context"
"io"
"os"
+ "runtime"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
@@ -30,12 +31,12 @@ func NewEncoder(w io.Writer) *Encoder {
// Encode writes the JSON encoding of v to the stream, followed by a newline character.
//
// See the documentation for Marshal for details about the conversion of Go values to JSON.
-func (e *Encoder) Encode(v interface{}) error {
+func (e *Encoder) Encode(v any) error {
return e.EncodeWithOption(v)
}
// EncodeWithOption call Encode with EncodeOption.
-func (e *Encoder) EncodeWithOption(v interface{}, optFuncs ...EncodeOptionFunc) error {
+func (e *Encoder) EncodeWithOption(v any, optFuncs ...EncodeOptionFunc) error {
ctx := encoder.TakeRuntimeContext()
ctx.Option.Flag = 0
@@ -46,19 +47,19 @@ func (e *Encoder) EncodeWithOption(v interface{}, optFuncs ...EncodeOptionFunc)
}
// EncodeContext call Encode with context.Context and EncodeOption.
-func (e *Encoder) EncodeContext(ctx context.Context, v interface{}, optFuncs ...EncodeOptionFunc) error {
+func (e *Encoder) EncodeContext(ctx context.Context, v any, optFuncs ...EncodeOptionFunc) error {
rctx := encoder.TakeRuntimeContext()
rctx.Option.Flag = 0
rctx.Option.Flag |= encoder.ContextOption
rctx.Option.Context = ctx
- err := e.encodeWithOption(rctx, v, optFuncs...) //nolint: contextcheck
+ err := e.encodeWithOption(rctx, v, optFuncs...)
encoder.ReleaseRuntimeContext(rctx)
return err
}
-func (e *Encoder) encodeWithOption(ctx *encoder.RuntimeContext, v interface{}, optFuncs ...EncodeOptionFunc) error {
+func (e *Encoder) encodeWithOption(ctx *encoder.RuntimeContext, v any, optFuncs ...EncodeOptionFunc) error {
if e.enabledHTMLEscape {
ctx.Option.Flag |= encoder.HTMLEscapeOption
}
@@ -111,7 +112,7 @@ func (e *Encoder) SetIndent(prefix, indent string) {
e.enabledIndent = true
}
-func marshalContext(ctx context.Context, v interface{}, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func marshalContext(ctx context.Context, v any, optFuncs ...EncodeOptionFunc) ([]byte, error) {
rctx := encoder.TakeRuntimeContext()
rctx.Option.Flag = 0
rctx.Option.Flag = encoder.HTMLEscapeOption | encoder.NormalizeUTF8Option | encoder.ContextOption
@@ -120,7 +121,7 @@ func marshalContext(ctx context.Context, v interface{}, optFuncs ...EncodeOption
optFunc(rctx.Option)
}
- buf, err := encode(rctx, v) //nolint: contextcheck
+ buf, err := encode(rctx, v)
if err != nil {
encoder.ReleaseRuntimeContext(rctx)
return nil, err
@@ -138,7 +139,7 @@ func marshalContext(ctx context.Context, v interface{}, optFuncs ...EncodeOption
return copied, nil
}
-func marshal(v interface{}, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func marshal(v any, optFuncs ...EncodeOptionFunc) ([]byte, error) {
ctx := encoder.TakeRuntimeContext()
ctx.Option.Flag = 0
@@ -165,31 +166,7 @@ func marshal(v interface{}, optFuncs ...EncodeOptionFunc) ([]byte, error) {
return copied, nil
}
-func marshalNoEscape(v interface{}) ([]byte, error) {
- ctx := encoder.TakeRuntimeContext()
-
- ctx.Option.Flag = 0
- ctx.Option.Flag |= (encoder.HTMLEscapeOption | encoder.NormalizeUTF8Option)
-
- buf, err := encodeNoEscape(ctx, v)
- if err != nil {
- encoder.ReleaseRuntimeContext(ctx)
- return nil, err
- }
-
- // this line exists to escape call of `runtime.makeslicecopy` .
- // if use `make([]byte, len(buf)-1)` and `copy(copied, buf)`,
- // dst buffer size and src buffer size are differrent.
- // in this case, compiler uses `runtime.makeslicecopy`, but it is slow.
- buf = buf[:len(buf)-1]
- copied := make([]byte, len(buf))
- copy(copied, buf)
-
- encoder.ReleaseRuntimeContext(ctx)
- return copied, nil
-}
-
-func marshalIndent(v interface{}, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func marshalIndent(v any, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error) {
ctx := encoder.TakeRuntimeContext()
ctx.Option.Flag = 0
@@ -212,7 +189,7 @@ func marshalIndent(v interface{}, prefix, indent string, optFuncs ...EncodeOptio
return copied, nil
}
-func encode(ctx *encoder.RuntimeContext, v interface{}) ([]byte, error) {
+func encode(ctx *encoder.RuntimeContext, v any) ([]byte, error) {
b := ctx.Buf[:0]
if v == nil {
b = encoder.AppendNull(ctx, b)
@@ -222,52 +199,32 @@ func encode(ctx *encoder.RuntimeContext, v interface{}) ([]byte, error) {
header := (*emptyInterface)(unsafe.Pointer(&v))
typ := header.typ
- typeptr := uintptr(unsafe.Pointer(typ))
+ typeptr := uintptr(typ)
codeSet, err := encoder.CompileToGetCodeSet(ctx, typeptr)
if err != nil {
return nil, err
}
- p := uintptr(header.ptr)
- ctx.Init(p, codeSet.CodeLength)
- ctx.KeepRefs = append(ctx.KeepRefs, header.ptr)
-
- buf, err := encodeRunCode(ctx, b, codeSet)
- if err != nil {
- return nil, err
- }
- ctx.Buf = buf
- return buf, nil
-}
-
-func encodeNoEscape(ctx *encoder.RuntimeContext, v interface{}) ([]byte, error) {
- b := ctx.Buf[:0]
- if v == nil {
+ p := ctx.ValueAddr(codeSet, header.ptr)
+ if p == nil {
+ // only a nil pointer has no address of the value.
b = encoder.AppendNull(ctx, b)
b = encoder.AppendComma(ctx, b)
return b, nil
}
- header := (*emptyInterface)(unsafe.Pointer(&v))
- typ := header.typ
-
- typeptr := uintptr(unsafe.Pointer(typ))
- codeSet, err := encoder.CompileToGetCodeSet(ctx, typeptr)
- if err != nil {
- return nil, err
- }
-
- p := uintptr(header.ptr)
ctx.Init(p, codeSet.CodeLength)
+
buf, err := encodeRunCode(ctx, b, codeSet)
+ // the VM refers to the value by uintptr.
+ runtime.KeepAlive(v)
if err != nil {
return nil, err
}
-
ctx.Buf = buf
return buf, nil
}
-func encodeIndent(ctx *encoder.RuntimeContext, v interface{}, prefix, indent string) ([]byte, error) {
+func encodeIndent(ctx *encoder.RuntimeContext, v any, prefix, indent string) ([]byte, error) {
b := ctx.Buf[:0]
if v == nil {
b = encoder.AppendNull(ctx, b)
@@ -277,17 +234,23 @@ func encodeIndent(ctx *encoder.RuntimeContext, v interface{}, prefix, indent str
header := (*emptyInterface)(unsafe.Pointer(&v))
typ := header.typ
- typeptr := uintptr(unsafe.Pointer(typ))
+ typeptr := uintptr(typ)
codeSet, err := encoder.CompileToGetCodeSet(ctx, typeptr)
if err != nil {
return nil, err
}
- p := uintptr(header.ptr)
+ p := ctx.ValueAddr(codeSet, header.ptr)
+ if p == nil {
+ // only a nil pointer has no address of the value.
+ b = encoder.AppendNull(ctx, b)
+ b = encoder.AppendCommaIndent(ctx, b)
+ return b, nil
+ }
ctx.Init(p, codeSet.CodeLength)
buf, err := encodeRunIndentCode(ctx, b, codeSet, prefix, indent)
-
- ctx.KeepRefs = append(ctx.KeepRefs, header.ptr)
+ // the VM refers to the value by uintptr.
+ runtime.KeepAlive(v)
if err != nil {
return nil, err
diff --git a/vendor/github.com/goccy/go-json/encode_of.go b/vendor/github.com/goccy/go-json/encode_of.go
new file mode 100644
index 000000000..995e5080e
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/encode_of.go
@@ -0,0 +1,86 @@
+package json
+
+import (
+ "reflect"
+
+ "github.com/goccy/go-json/internal/encoder"
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// MarshalOf returns the JSON encoding of v, as Marshal does.
+//
+// Marshal takes its argument as an interface value, so a value which is not a pointer is copied to the heap
+// for every call. MarshalOf takes the value by its type, and it copies the value to a value in the heap which is
+// reused, so it encodes a value without an allocation other than the one of the result.
+//
+// Which one to use depends on what is passed:
+// - A value which is not a pointer ( a struct, an int, a string, ... ): MarshalOf(v) is faster than Marshal(v),
+// because it saves the allocation. It also lets v stay on the stack of the caller, which Marshal(&v) doesn't.
+// - A pointer or a map: they are the same, because such a value is stored in an interface value without
+// an allocation.
+// - A large value which is already referred to by a pointer p: Marshal(p) is the fastest. MarshalOf(*p) copies
+// the whole value, which costs more as the value gets larger.
+func MarshalOf[T any](v T, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+ ctx := encoder.TakeRuntimeContext()
+
+ ctx.Option.Flag = 0
+ ctx.Option.Flag |= (encoder.HTMLEscapeOption | encoder.NormalizeUTF8Option)
+ for _, optFunc := range optFuncs {
+ optFunc(ctx.Option)
+ }
+
+ buf, err := encodeOf(ctx, &v)
+ if err != nil {
+ encoder.ReleaseRuntimeContext(ctx)
+ return nil, err
+ }
+
+ // see marshal for the reason why the result is copied this way.
+ buf = buf[:len(buf)-1]
+ copied := make([]byte, len(buf))
+ copy(copied, buf)
+
+ encoder.ReleaseRuntimeContext(ctx)
+ return copied, nil
+}
+
+// maxReusedValueSize is the size of the largest value which MarshalOf copies to a value it reuses.
+// Every runtime context in the pool keeps such a value, so a large one is left to the GC.
+const maxReusedValueSize = 4096
+
+func encodeOf[T any](ctx *encoder.RuntimeContext, v *T) ([]byte, error) {
+ typ := reflect.TypeOf(v).Elem()
+ switch typ.Kind() {
+ case reflect.Interface:
+ // the type to encode is the one of the value which the interface value holds.
+ return encode(ctx, *v)
+ case reflect.Ptr, reflect.Map:
+ // the value is stored directly in an interface value, which needs no allocation.
+ // The other types stored directly are found by their code set below.
+ return encode(ctx, *v)
+ }
+ codeSet, err := encoder.CompileToGetCodeSet(ctx, uintptr(runtime.TypePtr(typ)))
+ if err != nil {
+ return nil, err
+ }
+ if !codeSet.IfaceIndir {
+ // the value is stored directly in an interface value, which needs no allocation.
+ return encode(ctx, *v)
+ }
+ if typ.Size() > maxReusedValueSize {
+ return encode(ctx, *v)
+ }
+
+ p := codeSet.TakeValue(ctx)
+ *(*T)(p) = *v
+ ctx.Init(p, codeSet.CodeLength)
+ buf, err := encodeRunCode(ctx, ctx.Buf[:0], codeSet)
+ // the pool must not keep what the value refers to alive.
+ var zero T
+ *(*T)(p) = zero
+ if err != nil {
+ return nil, err
+ }
+ ctx.Buf = buf
+ return buf, nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/anonymous_field.go b/vendor/github.com/goccy/go-json/internal/decoder/anonymous_field.go
index b6876cf0d..4cb792c0a 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/anonymous_field.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/anonymous_field.go
@@ -1,18 +1,17 @@
package decoder
import (
+ "reflect"
"unsafe"
-
- "github.com/goccy/go-json/internal/runtime"
)
type anonymousFieldDecoder struct {
- structType *runtime.Type
+ structType reflect.Type
offset uintptr
dec Decoder
}
-func newAnonymousFieldDecoder(structType *runtime.Type, offset uintptr, dec Decoder) *anonymousFieldDecoder {
+func newAnonymousFieldDecoder(structType reflect.Type, offset uintptr, dec Decoder) *anonymousFieldDecoder {
return &anonymousFieldDecoder{
structType: structType,
offset: offset,
@@ -20,20 +19,12 @@ func newAnonymousFieldDecoder(structType *runtime.Type, offset uintptr, dec Deco
}
}
-func (d *anonymousFieldDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- if *(*unsafe.Pointer)(p) == nil {
- *(*unsafe.Pointer)(p) = unsafe_New(d.structType)
- }
- p = *(*unsafe.Pointer)(p)
- return d.dec.DecodeStream(s, depth, unsafe.Pointer(uintptr(p)+d.offset))
-}
-
func (d *anonymousFieldDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
if *(*unsafe.Pointer)(p) == nil {
- *(*unsafe.Pointer)(p) = unsafe_New(d.structType)
+ *(*unsafe.Pointer)(p) = newValue(d.structType)
}
p = *(*unsafe.Pointer)(p)
- return d.dec.Decode(ctx, cursor, depth, unsafe.Pointer(uintptr(p)+d.offset))
+ return d.dec.Decode(ctx, cursor, depth, unsafe.Add(p, d.offset))
}
func (d *anonymousFieldDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/array.go b/vendor/github.com/goccy/go-json/internal/decoder/array.go
index 4b23ed43f..76a307328 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/array.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/array.go
@@ -2,106 +2,45 @@ package decoder
import (
"fmt"
+ "reflect"
"unsafe"
"github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type arrayDecoder struct {
- elemType *runtime.Type
+ elemType reflect.Type
+ // arrayPtrType is the type descriptor of the pointer to the array.
+ arrayPtrType unsafe.Pointer
size uintptr
valueDecoder Decoder
alen int
structName string
fieldName string
- zeroValue unsafe.Pointer
+ // typ is the type of the array, which the type errors report.
+ typ reflect.Type
}
-func newArrayDecoder(dec Decoder, elemType *runtime.Type, alen int, structName, fieldName string) *arrayDecoder {
- // workaround to avoid checkptr errors. cannot use `*(*unsafe.Pointer)(unsafe_New(elemType))` directly.
- zeroValuePtr := unsafe_New(elemType)
- zeroValue := **(**unsafe.Pointer)(unsafe.Pointer(&zeroValuePtr))
+func newArrayDecoder(dec Decoder, arrayType reflect.Type, structName, fieldName string) *arrayDecoder {
+ elemType := arrayType.Elem()
return &arrayDecoder{
+ typ: arrayType,
valueDecoder: dec,
elemType: elemType,
+ arrayPtrType: ptrTypeOf(arrayType),
size: elemType.Size(),
- alen: alen,
+ alen: arrayType.Len(),
structName: structName,
fieldName: fieldName,
- zeroValue: zeroValue,
}
}
-func (d *arrayDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
+// zeroFrom sets the elements of the array at p from idx to the end to their zero value,
+// as encoding/json does for the elements the JSON array has not.
+func (d *arrayDecoder) zeroFrom(p unsafe.Pointer, idx int) {
+ if idx < d.alen {
+ valueAt(d.arrayPtrType, p).Slice(idx, d.alen).Clear()
}
-
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- return nil
- case '[':
- idx := 0
- s.cursor++
- if s.skipWhiteSpace() == ']' {
- for idx < d.alen {
- *(*unsafe.Pointer)(unsafe.Pointer(uintptr(p) + uintptr(idx)*d.size)) = d.zeroValue
- idx++
- }
- s.cursor++
- return nil
- }
- for {
- if idx < d.alen {
- if err := d.valueDecoder.DecodeStream(s, depth, unsafe.Pointer(uintptr(p)+uintptr(idx)*d.size)); err != nil {
- return err
- }
- } else {
- if err := s.skipValue(depth); err != nil {
- return err
- }
- }
- idx++
- switch s.skipWhiteSpace() {
- case ']':
- for idx < d.alen {
- *(*unsafe.Pointer)(unsafe.Pointer(uintptr(p) + uintptr(idx)*d.size)) = d.zeroValue
- idx++
- }
- s.cursor++
- return nil
- case ',':
- s.cursor++
- continue
- case nul:
- if s.read() {
- s.cursor++
- continue
- }
- goto ERROR
- default:
- goto ERROR
- }
- }
- case nul:
- if s.read() {
- continue
- }
- goto ERROR
- default:
- goto ERROR
- }
- s.cursor++
- }
-ERROR:
- return errors.ErrUnexpectedEndOfJSON("array", s.totalOffset())
}
func (d *arrayDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
@@ -127,16 +66,13 @@ func (d *arrayDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe
cursor++
cursor = skipWhiteSpace(buf, cursor)
if buf[cursor] == ']' {
- for idx < d.alen {
- *(*unsafe.Pointer)(unsafe.Pointer(uintptr(p) + uintptr(idx)*d.size)) = d.zeroValue
- idx++
- }
+ d.zeroFrom(p, idx)
cursor++
return cursor, nil
}
for {
if idx < d.alen {
- c, err := d.valueDecoder.Decode(ctx, cursor, depth, unsafe.Pointer(uintptr(p)+uintptr(idx)*d.size))
+ c, err := d.valueDecoder.Decode(ctx, cursor, depth, unsafe.Add(p, uintptr(idx)*d.size))
if err != nil {
return 0, err
}
@@ -152,10 +88,7 @@ func (d *arrayDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe
cursor = skipWhiteSpace(buf, cursor)
switch buf[cursor] {
case ']':
- for idx < d.alen {
- *(*unsafe.Pointer)(unsafe.Pointer(uintptr(p) + uintptr(idx)*d.size)) = d.zeroValue
- idx++
- }
+ d.zeroFrom(p, idx)
cursor++
return cursor, nil
case ',':
@@ -166,11 +99,22 @@ func (d *arrayDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe
}
}
default:
- return 0, errors.ErrUnexpectedEndOfJSON("array", cursor)
+ return d.decodeOther(ctx, cursor, depth-1)
}
}
}
+// decodeOther skips the value at cursor, which is not an array: a value of another kind is a type error, and
+// anything else a syntax error. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *arrayDecoder) decodeOther(ctx *RuntimeContext, cursor, depth int64) (int64, error) {
+ if isOtherValue(ctx.Buf[cursor], arrayValue) {
+ return ctx.skipTypeError(cursor, depth, d.typ)
+ }
+ return 0, errors.ErrUnexpectedEndOfJSON("array", cursor)
+}
+
func (d *arrayDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
return nil, 0, fmt.Errorf("json: array decoder does not support decode path")
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/bool.go b/vendor/github.com/goccy/go-json/internal/decoder/bool.go
index ba6cf5bc4..08f6cf3e7 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/bool.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/bool.go
@@ -2,6 +2,7 @@ package decoder
import (
"fmt"
+ "reflect"
"unsafe"
"github.com/goccy/go-json/internal/errors"
@@ -10,44 +11,12 @@ import (
type boolDecoder struct {
structName string
fieldName string
+ // typ is the type of the value, which the type errors report.
+ typ reflect.Type
}
func newBoolDecoder(structName, fieldName string) *boolDecoder {
- return &boolDecoder{structName: structName, fieldName: fieldName}
-}
-
-func (d *boolDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- c := s.skipWhiteSpace()
- for {
- switch c {
- case 't':
- if err := trueBytes(s); err != nil {
- return err
- }
- **(**bool)(unsafe.Pointer(&p)) = true
- return nil
- case 'f':
- if err := falseBytes(s); err != nil {
- return err
- }
- **(**bool)(unsafe.Pointer(&p)) = false
- return nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- return nil
- case nul:
- if s.read() {
- c = s.char()
- continue
- }
- goto ERROR
- }
- break
- }
-ERROR:
- return errors.ErrUnexpectedEndOfJSON("bool", s.totalOffset())
+ return &boolDecoder{structName: structName, fieldName: fieldName, typ: reflect.TypeOf(false)}
}
func (d *boolDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
@@ -75,6 +44,17 @@ func (d *boolDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.
cursor += 4
return cursor, nil
}
+ return d.decodeOther(ctx, cursor, depth)
+}
+
+// decodeOther skips the value at cursor, which is not a bool: a value of another kind is a type error, and
+// anything else a syntax error. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *boolDecoder) decodeOther(ctx *RuntimeContext, cursor, depth int64) (int64, error) {
+ if isOtherValue(ctx.Buf[cursor], boolValue) {
+ return ctx.skipTypeError(cursor, depth, d.typ)
+ }
return 0, errors.ErrUnexpectedEndOfJSON("bool", cursor)
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/bytes.go b/vendor/github.com/goccy/go-json/internal/decoder/bytes.go
index 939bf4327..5fff2b3ab 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/bytes.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/bytes.go
@@ -3,36 +3,39 @@ package decoder
import (
"encoding/base64"
"fmt"
+ "reflect"
"unsafe"
"github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type bytesDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
sliceDecoder Decoder
stringDecoder *stringDecoder
structName string
fieldName string
+ // sliceType is the type of the slice, which the type errors report.
+ sliceType reflect.Type
}
-func byteUnmarshalerSliceDecoder(typ *runtime.Type, structName string, fieldName string) Decoder {
+func byteUnmarshalerSliceDecoder(typ reflect.Type, structName string, fieldName string) Decoder {
var unmarshalDecoder Decoder
switch {
- case runtime.PtrTo(typ).Implements(unmarshalJSONType):
- unmarshalDecoder = newUnmarshalJSONDecoder(runtime.PtrTo(typ), structName, fieldName)
- case runtime.PtrTo(typ).Implements(unmarshalTextType):
- unmarshalDecoder = newUnmarshalTextDecoder(runtime.PtrTo(typ), structName, fieldName)
+ case reflect.PointerTo(typ).Implements(unmarshalJSONType):
+ unmarshalDecoder = newUnmarshalJSONDecoder(reflect.PointerTo(typ), structName, fieldName)
+ case reflect.PointerTo(typ).Implements(unmarshalTextType):
+ unmarshalDecoder = newUnmarshalTextDecoder(reflect.PointerTo(typ), structName, fieldName)
default:
unmarshalDecoder, _ = compileUint8(typ, structName, fieldName)
}
return newSliceDecoder(unmarshalDecoder, typ, 1, structName, fieldName)
}
-func newBytesDecoder(typ *runtime.Type, structName string, fieldName string) *bytesDecoder {
+func newBytesDecoder(typ reflect.Type, structName string, fieldName string) *bytesDecoder {
return &bytesDecoder{
typ: typ,
+ sliceType: reflect.SliceOf(typ),
sliceDecoder: byteUnmarshalerSliceDecoder(typ, structName, fieldName),
stringDecoder: newStringDecoder(structName, fieldName),
structName: structName,
@@ -40,29 +43,14 @@ func newBytesDecoder(typ *runtime.Type, structName string, fieldName string) *by
}
}
-func (d *bytesDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamBinary(s, depth, p)
- if err != nil {
- return err
- }
- if bytes == nil {
- s.reset()
- return nil
- }
- decodedLen := base64.StdEncoding.DecodedLen(len(bytes))
- buf := make([]byte, decodedLen)
- n, err := base64.StdEncoding.Decode(buf, bytes)
- if err != nil {
- return err
- }
- *(*[]byte)(p) = buf[:n]
- s.reset()
- return nil
-}
-
func (d *bytesDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ cursor = skipWhiteSpace(ctx.Buf, cursor)
+ start := cursor
bytes, c, err := d.decodeBinary(ctx, cursor, depth, p)
if err != nil {
+ if c := ctx.Buf[cursor]; c != '[' && isOtherValue(c, stringValue) {
+ return ctx.skipTypeError(cursor, depth, d.sliceType)
+ }
return 0, err
}
if bytes == nil {
@@ -73,7 +61,8 @@ func (d *bytesDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe
b := make([]byte, decodedLen)
n, err := base64.StdEncoding.Decode(b, bytes)
if err != nil {
- return 0, err
+ ctx.base64Error(start, cursor, d.sliceType, err)
+ return cursor, nil
}
*(*[]byte)(p) = b[:n]
return cursor, nil
@@ -83,28 +72,13 @@ func (d *bytesDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][
return nil, 0, fmt.Errorf("json: []byte decoder does not support decode path")
}
-func (d *bytesDecoder) decodeStreamBinary(s *Stream, depth int64, p unsafe.Pointer) ([]byte, error) {
- c := s.skipWhiteSpace()
- if c == '[' {
- if d.sliceDecoder == nil {
- return nil, &errors.UnmarshalTypeError{
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- }
- err := d.sliceDecoder.DecodeStream(s, depth, p)
- return nil, err
- }
- return d.stringDecoder.decodeStreamByte(s)
-}
-
func (d *bytesDecoder) decodeBinary(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) ([]byte, int64, error) {
buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
if buf[cursor] == '[' {
if d.sliceDecoder == nil {
return nil, 0, &errors.UnmarshalTypeError{
- Type: runtime.RType2Type(d.typ),
+ Type: d.typ,
Offset: cursor,
}
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/compile.go b/vendor/github.com/goccy/go-json/internal/decoder/compile.go
index 8ad50936c..5f32c339c 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/compile.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/compile.go
@@ -4,81 +4,54 @@ import (
"encoding/json"
"fmt"
"reflect"
- "strings"
- "sync"
- "sync/atomic"
"unicode"
"unsafe"
+ "github.com/goccy/go-json/internal/errors"
"github.com/goccy/go-json/internal/runtime"
)
-var (
- jsonNumberType = reflect.TypeOf(json.Number(""))
- typeAddr *runtime.TypeAddr
- cachedDecoderMap unsafe.Pointer // map[uintptr]decoder
- cachedDecoder []Decoder
- initOnce sync.Once
-)
-
-func initDecoder() {
- initOnce.Do(func() {
- typeAddr = runtime.AnalyzeTypeAddr()
- if typeAddr == nil {
- typeAddr = &runtime.TypeAddr{}
- }
- cachedDecoder = make([]Decoder, typeAddr.AddrRange>>typeAddr.AddrShift+1)
- })
-}
-
-func loadDecoderMap() map[uintptr]Decoder {
- initDecoder()
- p := atomic.LoadPointer(&cachedDecoderMap)
- return *(*map[uintptr]Decoder)(unsafe.Pointer(&p))
-}
-
-func storeDecoder(typ uintptr, dec Decoder, m map[uintptr]Decoder) {
- initDecoder()
- newDecoderMap := make(map[uintptr]Decoder, len(m)+1)
- newDecoderMap[typ] = dec
-
- for k, v := range m {
- newDecoderMap[k] = v
- }
-
- atomic.StorePointer(&cachedDecoderMap, *(*unsafe.Pointer)(unsafe.Pointer(&newDecoderMap)))
-}
-
-func compileToGetDecoderSlowPath(typeptr uintptr, typ *runtime.Type) (Decoder, error) {
- decoderMap := loadDecoderMap()
- if dec, exists := decoderMap[typeptr]; exists {
- return dec, nil
+// CompileToGetDecoder returns the decoder of the type.
+// The type is given by the pointer to its type descriptor, which the caller reads from an interface value,
+// because reflect.Type is required only when the decoder is not cached yet.
+func CompileToGetDecoder(typ unsafe.Pointer) (Decoder, error) {
+ typeptr := uintptr(typ)
+ if dec := cachedDecoder.Load(typeptr); dec != nil {
+ return *dec, nil
}
-
- dec, err := compileHead(typ, map[uintptr]Decoder{})
+ dec, err := compileHead(runtime.TypeOfPtr(typ), map[uintptr]Decoder{})
if err != nil {
return nil, err
}
- storeDecoder(typeptr, dec, decoderMap)
- return dec, nil
+ return *cachedDecoder.Store(typeptr, &dec), nil
}
-func compileHead(typ *runtime.Type, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+var (
+ jsonNumberType = reflect.TypeOf(json.Number(""))
+ cachedDecoder runtime.TypeCache[Decoder]
+)
+
+func compileHead(typ reflect.Type, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+ // The kind is validated here, once per type, instead of for every call of the decoding functions:
+ // the decoder of a non-pointer type is never created, so it is never cached either.
+ if typ.Kind() != reflect.Ptr {
+ return nil, &errors.InvalidUnmarshalError{Type: typ}
+ }
switch {
- case implementsUnmarshalJSONType(runtime.PtrTo(typ)):
- return newUnmarshalJSONDecoder(runtime.PtrTo(typ), "", ""), nil
- case runtime.PtrTo(typ).Implements(unmarshalTextType):
- return newUnmarshalTextDecoder(runtime.PtrTo(typ), "", ""), nil
+ case implementsUnmarshalJSONType(reflect.PointerTo(typ)):
+ return newUnmarshalJSONDecoder(reflect.PointerTo(typ), "", ""), nil
+ case reflect.PointerTo(typ).Implements(unmarshalTextType):
+ return newUnmarshalTextDecoder(reflect.PointerTo(typ), "", ""), nil
}
return compile(typ.Elem(), "", "", structTypeToDecoder)
}
-func compile(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func compile(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
switch {
- case implementsUnmarshalJSONType(runtime.PtrTo(typ)):
- return newUnmarshalJSONDecoder(runtime.PtrTo(typ), structName, fieldName), nil
- case runtime.PtrTo(typ).Implements(unmarshalTextType):
- return newUnmarshalTextDecoder(runtime.PtrTo(typ), structName, fieldName), nil
+ case implementsUnmarshalJSONType(reflect.PointerTo(typ)):
+ return newUnmarshalJSONDecoder(reflect.PointerTo(typ), structName, fieldName), nil
+ case reflect.PointerTo(typ).Implements(unmarshalTextType):
+ return newUnmarshalTextDecoder(reflect.PointerTo(typ), structName, fieldName), nil
}
switch typ.Kind() {
@@ -89,7 +62,7 @@ func compile(typ *runtime.Type, structName, fieldName string, structTypeToDecode
case reflect.Slice:
elem := typ.Elem()
if elem.Kind() == reflect.Uint8 {
- return compileBytes(elem, structName, fieldName)
+ return compileBytes(typ, structName, fieldName)
}
return compileSlice(typ, structName, fieldName, structTypeToDecoder)
case reflect.Array:
@@ -123,22 +96,22 @@ func compile(typ *runtime.Type, structName, fieldName string, structTypeToDecode
case reflect.String:
return compileString(typ, structName, fieldName)
case reflect.Bool:
- return compileBool(structName, fieldName)
+ return compileBool(typ, structName, fieldName)
case reflect.Float32:
- return compileFloat32(structName, fieldName)
+ return compileFloat32(typ, structName, fieldName)
case reflect.Float64:
- return compileFloat64(structName, fieldName)
+ return compileFloat64(typ, structName, fieldName)
case reflect.Func:
return compileFunc(typ, structName, fieldName)
}
return newInvalidDecoder(typ, structName, fieldName), nil
}
-func isStringTagSupportedType(typ *runtime.Type) bool {
+func isStringTagSupportedType(typ reflect.Type) bool {
switch {
- case implementsUnmarshalJSONType(runtime.PtrTo(typ)):
+ case implementsUnmarshalJSONType(reflect.PointerTo(typ)):
return false
- case runtime.PtrTo(typ).Implements(unmarshalTextType):
+ case reflect.PointerTo(typ).Implements(unmarshalTextType):
return false
}
switch typ.Kind() {
@@ -156,12 +129,14 @@ func isStringTagSupportedType(typ *runtime.Type) bool {
return true
}
-func compileMapKey(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
- if runtime.PtrTo(typ).Implements(unmarshalTextType) {
- return newUnmarshalTextDecoder(runtime.PtrTo(typ), structName, fieldName), nil
+func compileMapKey(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+ if reflect.PointerTo(typ).Implements(unmarshalTextType) {
+ return newUnmarshalTextDecoder(reflect.PointerTo(typ), structName, fieldName), nil
}
if typ.Kind() == reflect.String {
- return newStringDecoder(structName, fieldName), nil
+ d := newStringDecoder(structName, fieldName)
+ d.typ = typ
+ return d, nil
}
dec, err := compile(typ, structName, fieldName, structTypeToDecoder)
if err != nil {
@@ -171,17 +146,21 @@ func compileMapKey(typ *runtime.Type, structName, fieldName string, structTypeTo
switch t := dec.(type) {
case *stringDecoder, *interfaceDecoder:
return dec, nil
- case *boolDecoder, *intDecoder, *uintDecoder, *numberDecoder:
- return newWrappedStringDecoder(typ, dec, structName, fieldName), nil
+ case *boolDecoder, *intDecoder, *uintDecoder, *floatDecoder, *float32Decoder, *numberDecoder:
+ d := newWrappedStringDecoder(typ, dec, structName, fieldName)
+ d.isMapKey = true
+ return d, nil
case *ptrDecoder:
dec = t.dec
+ case *basicPtrDecoder:
+ dec = t.dec
default:
return newInvalidDecoder(typ, structName, fieldName), nil
}
}
}
-func compilePtr(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func compilePtr(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
dec, err := compile(typ.Elem(), structName, fieldName, structTypeToDecoder)
if err != nil {
return nil, err
@@ -189,114 +168,126 @@ func compilePtr(typ *runtime.Type, structName, fieldName string, structTypeToDec
return newPtrDecoder(dec, typ.Elem(), structName, fieldName), nil
}
-func compileInt(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInt(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newIntDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v int64) {
*(*int)(p) = int(v)
}), nil
}
-func compileInt8(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInt8(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newIntDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v int64) {
*(*int8)(p) = int8(v)
}), nil
}
-func compileInt16(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInt16(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newIntDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v int64) {
*(*int16)(p) = int16(v)
}), nil
}
-func compileInt32(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInt32(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newIntDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v int64) {
*(*int32)(p) = int32(v)
}), nil
}
-func compileInt64(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInt64(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newIntDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v int64) {
*(*int64)(p) = v
}), nil
}
-func compileUint(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileUint(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newUintDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v uint64) {
*(*uint)(p) = uint(v)
}), nil
}
-func compileUint8(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileUint8(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newUintDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v uint64) {
*(*uint8)(p) = uint8(v)
}), nil
}
-func compileUint16(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileUint16(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newUintDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v uint64) {
*(*uint16)(p) = uint16(v)
}), nil
}
-func compileUint32(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileUint32(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newUintDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v uint64) {
*(*uint32)(p) = uint32(v)
}), nil
}
-func compileUint64(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileUint64(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newUintDecoder(typ, structName, fieldName, func(p unsafe.Pointer, v uint64) {
*(*uint64)(p) = v
}), nil
}
-func compileFloat32(structName, fieldName string) (Decoder, error) {
- return newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
+func compileFloat32(typ reflect.Type, structName, fieldName string) (Decoder, error) {
+ d := newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
*(*float32)(p) = float32(v)
- }), nil
+ })
+ d.typ, d.is32 = typ, true
+ return &float32Decoder{floatDecoder: *d}, nil
}
-func compileFloat64(structName, fieldName string) (Decoder, error) {
- return newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
+func compileFloat64(typ reflect.Type, structName, fieldName string) (Decoder, error) {
+ d := newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
*(*float64)(p) = v
- }), nil
+ })
+ d.typ = typ
+ return d, nil
}
-func compileString(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
- if typ == runtime.Type2RType(jsonNumberType) {
+func compileString(typ reflect.Type, structName, fieldName string) (Decoder, error) {
+ if typ == jsonNumberType {
return newNumberDecoder(structName, fieldName, func(p unsafe.Pointer, v json.Number) {
*(*json.Number)(p) = v
}), nil
}
- return newStringDecoder(structName, fieldName), nil
+ d := newStringDecoder(structName, fieldName)
+ d.typ = typ
+ return d, nil
}
-func compileBool(structName, fieldName string) (Decoder, error) {
- return newBoolDecoder(structName, fieldName), nil
+func compileBool(typ reflect.Type, structName, fieldName string) (Decoder, error) {
+ d := newBoolDecoder(structName, fieldName)
+ d.typ = typ
+ return d, nil
}
-func compileBytes(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
- return newBytesDecoder(typ, structName, fieldName), nil
+func compileBytes(typ reflect.Type, structName, fieldName string) (Decoder, error) {
+ d := newBytesDecoder(typ.Elem(), structName, fieldName)
+ d.sliceType = typ
+ return d, nil
}
-func compileSlice(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func compileSlice(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
elem := typ.Elem()
decoder, err := compile(elem, structName, fieldName, structTypeToDecoder)
if err != nil {
return nil, err
}
- return newSliceDecoder(decoder, elem, elem.Size(), structName, fieldName), nil
+ d := newSliceDecoder(decoder, elem, elem.Size(), structName, fieldName)
+ d.typ = typ
+ return d, nil
}
-func compileArray(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func compileArray(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
elem := typ.Elem()
decoder, err := compile(elem, structName, fieldName, structTypeToDecoder)
if err != nil {
return nil, err
}
- return newArrayDecoder(decoder, elem, typ.Len(), structName, fieldName), nil
+ return newArrayDecoder(decoder, typ, structName, fieldName), nil
}
-func compileMap(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func compileMap(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
keyDec, err := compileMapKey(typ.Key(), structName, fieldName, structTypeToDecoder)
if err != nil {
return nil, err
@@ -308,15 +299,18 @@ func compileMap(typ *runtime.Type, structName, fieldName string, structTypeToDec
return newMapDecoder(typ, typ.Key(), keyDec, typ.Elem(), valueDec, structName, fieldName), nil
}
-func compileInterface(typ *runtime.Type, structName, fieldName string) (Decoder, error) {
+func compileInterface(typ reflect.Type, structName, fieldName string) (Decoder, error) {
return newInterfaceDecoder(typ, structName, fieldName), nil
}
-func compileFunc(typ *runtime.Type, strutName, fieldName string) (Decoder, error) {
+func compileFunc(typ reflect.Type, strutName, fieldName string) (Decoder, error) {
return newFuncDecoder(typ, strutName, fieldName), nil
}
-func typeToStructTags(typ *runtime.Type) runtime.StructTags {
+// typeToStructTags returns the tags of the fields of typ which have a key, which hides a field of the same key
+// promoted from an embedded struct. An embedded struct without a key in its tag has no key of its own: its fields
+// are promoted, and one of them may have the name of the embedded struct.
+func typeToStructTags(typ reflect.Type) runtime.StructTags {
tags := runtime.StructTags{}
fieldNum := typ.NumField()
for i := 0; i < fieldNum; i++ {
@@ -324,19 +318,30 @@ func typeToStructTags(typ *runtime.Type) runtime.StructTags {
if runtime.IsIgnoredStructField(field) {
continue
}
- tags = append(tags, runtime.StructTagFromField(field))
+ tag := runtime.StructTagFromField(field)
+ if field.Anonymous && !tag.IsTaggedKey && isStructOrPointerToStruct(field.Type) {
+ continue
+ }
+ tags = append(tags, tag)
}
return tags
}
-func compileStruct(typ *runtime.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
+func isStructOrPointerToStruct(typ reflect.Type) bool {
+ if typ.Kind() == reflect.Pointer {
+ typ = typ.Elem()
+ }
+ return typ.Kind() == reflect.Struct
+}
+
+func compileStruct(typ reflect.Type, structName, fieldName string, structTypeToDecoder map[uintptr]Decoder) (Decoder, error) {
fieldNum := typ.NumField()
- fieldMap := map[string]*structFieldSet{}
- typeptr := uintptr(unsafe.Pointer(typ))
+ typeptr := uintptr(runtime.TypePtr(typ))
if dec, exists := structTypeToDecoder[typeptr]; exists {
return dec, nil
}
- structDec := newStructDecoder(structName, fieldName, fieldMap)
+ structDec := newStructDecoder(structName, fieldName)
+ structDec.typ, structDec.typeName = typ, typ.Name()
structTypeToDecoder[typeptr] = structDec
structName = typ.Name()
tags := typeToStructTags(typ)
@@ -348,27 +353,28 @@ func compileStruct(typ *runtime.Type, structName, fieldName string, structTypeTo
}
isUnexportedField := unicode.IsLower([]rune(field.Name)[0])
tag := runtime.StructTagFromField(field)
- dec, err := compile(runtime.Type2RType(field.Type), structName, field.Name, structTypeToDecoder)
+ dec, err := compile(field.Type, structName, field.Name, structTypeToDecoder)
if err != nil {
return nil, err
}
if field.Anonymous && !tag.IsTaggedKey {
if stDec, ok := dec.(*structDecoder); ok {
- if runtime.Type2RType(field.Type) == typ {
+ if field.Type == typ {
// recursive definition
continue
}
- for k, v := range stDec.fieldMap {
- if tags.ExistsKey(k) {
+ for _, v := range stDec.fields {
+ if tags.ExistsKey(v.key) {
continue
}
fieldSet := &structFieldSet{
dec: v.dec,
offset: field.Offset + v.offset,
isTaggedKey: v.isTaggedKey,
- key: k,
- keyLen: int64(len(k)),
+ key: v.key,
+ keyLen: int64(len(v.key)),
}
+ structDec.setEmbedded(fieldSet, append([]string{field.Name}, stDec.embedded[v]...))
allFields = append(allFields, fieldSet)
}
} else if pdec, ok := dec.(*ptrDecoder); ok {
@@ -385,18 +391,19 @@ func compileStruct(typ *runtime.Type, structName, fieldName string, structTypeTo
)
}
if dec, ok := contentDec.(*structDecoder); ok {
- for k, v := range dec.fieldMap {
- if tags.ExistsKey(k) {
+ for _, v := range dec.fields {
+ if tags.ExistsKey(v.key) {
continue
}
fieldSet := &structFieldSet{
dec: newAnonymousFieldDecoder(pdec.typ, v.offset, v.dec),
offset: field.Offset,
isTaggedKey: v.isTaggedKey,
- key: k,
- keyLen: int64(len(k)),
+ key: v.key,
+ keyLen: int64(len(v.key)),
err: fieldSetErr,
}
+ structDec.setEmbedded(fieldSet, append([]string{field.Name}, dec.embedded[v]...))
allFields = append(allFields, fieldSet)
}
} else {
@@ -420,8 +427,8 @@ func compileStruct(typ *runtime.Type, structName, fieldName string, structTypeTo
allFields = append(allFields, fieldSet)
}
} else {
- if tag.IsString && isStringTagSupportedType(runtime.Type2RType(field.Type)) {
- dec = newWrappedStringDecoder(runtime.Type2RType(field.Type), dec, structName, field.Name)
+ if tag.IsString && isStringTagSupportedType(field.Type) {
+ dec = newWrappedStringDecoder(field.Type, dec, structName, field.Name)
}
var key string
if tag.Key != "" {
@@ -439,16 +446,20 @@ func compileStruct(typ *runtime.Type, structName, fieldName string, structTypeTo
allFields = append(allFields, fieldSet)
}
}
+ // A key which remains more than once is the one of the last field, as it was when the fields were kept
+ // in a map, at the place of the first.
+ fields := []*structFieldSet{}
+ indexByKey := map[string]int{}
for _, set := range filterDuplicatedFields(allFields) {
- fieldMap[set.key] = set
- lower := strings.ToLower(set.key)
- if _, exists := fieldMap[lower]; !exists {
- // first win
- fieldMap[lower] = set
+ if i, exists := indexByKey[set.key]; exists {
+ fields[i] = set
+ continue
}
+ indexByKey[set.key] = len(fields)
+ fields = append(fields, set)
}
+ structDec.setFields(fields)
delete(structTypeToDecoder, typeptr)
- structDec.tryOptimize()
return structDec, nil
}
@@ -488,6 +499,6 @@ func filterFieldSets(sets []*structFieldSet) []*structFieldSet {
return filtered
}
-func implementsUnmarshalJSONType(typ *runtime.Type) bool {
+func implementsUnmarshalJSONType(typ reflect.Type) bool {
return typ.Implements(unmarshalJSONType) || typ.Implements(unmarshalJSONContextType)
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/compile_norace.go b/vendor/github.com/goccy/go-json/internal/decoder/compile_norace.go
deleted file mode 100644
index 025ca85b5..000000000
--- a/vendor/github.com/goccy/go-json/internal/decoder/compile_norace.go
+++ /dev/null
@@ -1,30 +0,0 @@
-//go:build !race
-// +build !race
-
-package decoder
-
-import (
- "unsafe"
-
- "github.com/goccy/go-json/internal/runtime"
-)
-
-func CompileToGetDecoder(typ *runtime.Type) (Decoder, error) {
- initDecoder()
- typeptr := uintptr(unsafe.Pointer(typ))
- if typeptr > typeAddr.MaxTypeAddr {
- return compileToGetDecoderSlowPath(typeptr, typ)
- }
-
- index := (typeptr - typeAddr.BaseTypeAddr) >> typeAddr.AddrShift
- if dec := cachedDecoder[index]; dec != nil {
- return dec, nil
- }
-
- dec, err := compileHead(typ, map[uintptr]Decoder{})
- if err != nil {
- return nil, err
- }
- cachedDecoder[index] = dec
- return dec, nil
-}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/compile_race.go b/vendor/github.com/goccy/go-json/internal/decoder/compile_race.go
deleted file mode 100644
index 023b817c3..000000000
--- a/vendor/github.com/goccy/go-json/internal/decoder/compile_race.go
+++ /dev/null
@@ -1,38 +0,0 @@
-//go:build race
-// +build race
-
-package decoder
-
-import (
- "sync"
- "unsafe"
-
- "github.com/goccy/go-json/internal/runtime"
-)
-
-var decMu sync.RWMutex
-
-func CompileToGetDecoder(typ *runtime.Type) (Decoder, error) {
- initDecoder()
- typeptr := uintptr(unsafe.Pointer(typ))
- if typeptr > typeAddr.MaxTypeAddr {
- return compileToGetDecoderSlowPath(typeptr, typ)
- }
-
- index := (typeptr - typeAddr.BaseTypeAddr) >> typeAddr.AddrShift
- decMu.RLock()
- if dec := cachedDecoder[index]; dec != nil {
- decMu.RUnlock()
- return dec, nil
- }
- decMu.RUnlock()
-
- dec, err := compileHead(typ, map[uintptr]Decoder{})
- if err != nil {
- return nil, err
- }
- decMu.Lock()
- cachedDecoder[index] = dec
- decMu.Unlock()
- return dec, nil
-}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/context.go b/vendor/github.com/goccy/go-json/internal/decoder/context.go
index cb2ffdafd..7c0dfa88a 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/context.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/context.go
@@ -1,23 +1,265 @@
package decoder
import (
+ "math/bits"
+ "reflect"
"sync"
"unsafe"
"github.com/goccy/go-json/internal/errors"
+ "github.com/goccy/go-json/internal/runtime"
)
type RuntimeContext struct {
Buf []byte
Option *Option
+ // slot is where a value of interface{} is decoded before it is put into a map or a slice.
+ // The decoders of the values nested in it use it too: each of them takes the value out of it
+ // before the next value is decoded, and puts its own value into it only at its end.
+ slot any
+ // anyStack holds the elements of the arrays being decoded into []interface{}: an array pushes
+ // its elements above the ones of the arrays it is nested in, and pops them at its end. The objects
+ // being decoded into new maps of map[string]interface{} push their entries to entryStack, a key and its
+ // value at once, so that a map is made of the size of its object ( see decodeNewStringAnyMap ).
+ anyStack []any
+ entryStack []anyEntry
+ // floats and strings are the slabs in which the numbers and the strings decoded into interface{}
+ // are kept, so that an interface value refers to them without an allocation of its own.
+ // A slot of a slab is never written again once an interface value refers to it.
+ floats []float64
+ strings []string
+ // input is the buffer which the input of Unmarshal is copied to, followed by a nul byte. It is reused by
+ // the calls: nothing decoded refers to it, because the decoded strings are copied out of it ( makeString ).
+ input []byte
+ // origin is the input of the call when Buf is the reused copy of it, at the same offsets: the decoded strings
+ // are copied, or refer to origin under NoCopyStringOption. It is nil when Buf is never written again after the
+ // value is decoded, as the buffer of a stream: the strings refer to Buf then.
+ origin []byte
+ // arena is where the bytes of the decoded strings are copied to. A string refers to a part of it which is
+ // never written again, so the arena is kept from a call to the next, as the slab of floats.
+ arena []byte
+ // unescaped is where an escaped string too long for the arena is decoded to before it is copied, which is kept
+ // from a call to the next up to maxUnescapeScratchSize ( see unescapeLong ).
+ unescaped []byte
+ // value is a zero value of the type valueType in the heap, which UnmarshalOf decodes into
+ // before it copies the result to the value of the caller.
+ valueType unsafe.Pointer
+ value unsafe.Pointer
+ // recentDecoders are the decoders of the types decoded last, in the sets indexed by the address of the type.
+ // Only the contexts of the pool have them: a Decoder has a context of its own, which it would allocate
+ // with them for every stream.
+ recentDecoders *[recentDecoderSets]recentDecoderSet
+ // typeError is the first type error of the decoding, which is returned at its end ( see TypeError ). It is nil
+ // in a context of the pool: TypeError clears it, and DiscardTypeError when the decoding fails.
+ typeError *pendingTypeError
+}
+
+const (
+ // recentDecoderSets is the number of the sets of the recent decoders, of recentDecoderWays entries each,
+ // as the recent opcodes of the encoder: the set of a type is the top bits of the product of its address
+ // with an odd constant, and a set holds the two types hashed to it which were decoded last, so that the
+ // type passed to Unmarshal and a type held by its values of interface{} never evict each other.
+ recentDecoderSets = 16
+ recentDecoderHashShift = 64 - 4
+ recentDecoderWays = 2
+)
+
+type recentDecoder struct {
+ typeptr uintptr
+ dec Decoder
+}
+
+// recentDecoderSet is the entries of a set, the one decoded last first.
+type recentDecoderSet [recentDecoderWays]recentDecoder
+
+// DecoderOf returns the decoder of the type, compiling it if the type is new.
+//
+// A runtime context remembers the decoders of the types it decoded last: the same types are decoded again
+// and again in most of the programs, and this is cheaper than a lookup of the table shared by every goroutine.
+// The first entry of the set is looked at here, which is inlined into the callers; the rest in lookupDecoder.
+func (ctx *RuntimeContext) DecoderOf(typ unsafe.Pointer) (Decoder, error) {
+ if ctx.recentDecoders == nil {
+ return CompileToGetDecoder(typ)
+ }
+ set := &ctx.recentDecoders[(uint64(uintptr(typ))*runtime.TypeHashMultiplier)>>recentDecoderHashShift]
+ if set[0].typeptr == uintptr(typ) {
+ return set[0].dec, nil
+ }
+ return lookupDecoder(set, typ)
+}
+
+// lookupDecoder returns the decoder of the type from the second entry of its set, or from the shared table,
+// compiling it if the type is new. A decoder found in the shared table takes the first entry of the set,
+// and the one decoded before it is kept in the second.
+func lookupDecoder(set *recentDecoderSet, typ unsafe.Pointer) (Decoder, error) {
+ if set[1].typeptr == uintptr(typ) {
+ return set[1].dec, nil
+ }
+ dec, err := CompileToGetDecoder(typ)
+ if err != nil {
+ return nil, err
+ }
+ set[1] = set[0]
+ set[0] = recentDecoder{typeptr: uintptr(typ), dec: dec}
+ return dec, nil
+}
+
+const (
+ // minArenaChunkSize and arenaChunkSize are the sizes of the first and of the largest chunks of the arena
+ // of the strings: a chunk is twice as large as the previous one, so that a context which decodes a few
+ // short strings, as the one of a Decoder made for a small value, allocates little.
+ minArenaChunkSize = 64
+ arenaChunkSize = 16384
+ // maxArenaStringSize is the length of the longest string which is copied to the arena:
+ // a longer one gets an allocation of its own, which it alone keeps alive.
+ maxArenaStringSize = 512
+ // maxUnescapeScratchSize is the length of the longest escaped string which is decoded into the scratch bytes of
+ // a context: a longer one is decoded into bytes of its own, which the context doesn't keep.
+ maxUnescapeScratchSize = 64 << 10
+)
+
+// inputPadding is the number of the bytes the buffer of the input has after its nul byte, which the decoders
+// may read: the words of an object key are read from any byte of the buffer ( see structDecoder.Decode ).
+const inputPadding = 16
+
+// SetInput copies data to the buffer of the context, followed by a nul byte which ends every scan,
+// and makes it the buffer to decode.
+func (ctx *RuntimeContext) SetInput(data []byte) []byte {
+ n := len(data) + 1
+ if cap(ctx.input) < n+inputPadding {
+ // at least a cache line, which the buffer of another context doesn't share: it is written for every call.
+ ctx.input = make([]byte, n, max(n+inputPadding, cacheLineSize))
+ }
+ buf := ctx.input[:n]
+ copy(buf, data)
+ buf[len(data)] = nul
+ ctx.Buf = buf
+ ctx.origin = data
+ return buf
+}
+
+// makeString returns the string of lit, which the string decoder returned from Buf: lit is either a part of Buf,
+// which is reused by the next call and has the bytes of the input ( Buf is never written ), or a new slice of its
+// own ( an escape was decoded, or an invalid UTF-8 sequence was replaced ).
+//
+// Only the buffer of Unmarshal is reused ( origin is its input ): the strings are copied out of it, or refer to
+// the input under NoCopyStringOption. The other buffers, as the one of a stream, are never written again after
+// a value is decoded, so the strings refer to them.
+func (ctx *RuntimeContext) makeString(lit []byte) string {
+ if len(lit) == 0 {
+ return ""
+ }
+ if ctx.origin == nil {
+ return unsafe.String(unsafe.SliceData(lit), len(lit))
+ }
+ if (ctx.Option.Flags & NoCopyStringOption) != 0 {
+ return ctx.referString(lit)
+ }
+ return ctx.copyString(lit)
+}
+
+// isPartOf reports whether b is a part of buf.
+func isPartOf(b, buf []byte) bool {
+ base := uintptr(unsafe.Pointer(unsafe.SliceData(buf)))
+ p := uintptr(unsafe.Pointer(unsafe.SliceData(b)))
+ return base <= p && p < base+uintptr(len(buf))
+}
+
+// referString returns a string which refers to the input, where lit is a part of Buf, without a copy.
+func (ctx *RuntimeContext) referString(lit []byte) string {
+ if !isPartOf(lit, ctx.Buf) {
+ // a slice of its own
+ return unsafe.String(unsafe.SliceData(lit), len(lit))
+ }
+ off := uintptr(unsafe.Pointer(unsafe.SliceData(lit))) - uintptr(unsafe.Pointer(unsafe.SliceData(ctx.Buf)))
+ return unsafe.String(&ctx.origin[off], len(lit))
+}
+
+// reserveArena returns n bytes of the arena after its end, which a string may be written to:
+// the caller extends the arena by the length of the string it wrote.
+func (ctx *RuntimeContext) reserveArena(n int) []byte {
+ if cap(ctx.arena)-len(ctx.arena) < n {
+ size := min(max(2*cap(ctx.arena), minArenaChunkSize), arenaChunkSize)
+ ctx.arena = make([]byte, 0, max(size, n))
+ }
+ return ctx.arena[len(ctx.arena) : len(ctx.arena)+n]
+}
+
+// copyString returns a copy of lit, in the arena unless it is long.
+func (ctx *RuntimeContext) copyString(lit []byte) string {
+ if len(lit) > maxArenaStringSize {
+ return string(lit)
+ }
+ dst := ctx.reserveArena(len(lit))
+ copy(dst, lit)
+ ctx.arena = ctx.arena[:len(ctx.arena)+len(lit)]
+ return unsafe.String(unsafe.SliceData(dst), len(lit))
+}
+
+// boxSlabSize is the number of the values a slab of floats or strings holds.
+const boxSlabSize = 32
+
+var (
+ float64TypePtr = runtime.TypePtr(reflect.TypeOf(float64(0)))
+ stringTypePtr = runtime.TypePtr(reflect.TypeOf(""))
+)
+
+// boxFloat returns f as an interface value, which refers to a slot of the slab of floats.
+func (ctx *RuntimeContext) boxFloat(f float64) any {
+ if len(ctx.floats) == cap(ctx.floats) {
+ ctx.floats = make([]float64, 0, boxSlabSize)
+ }
+ ctx.floats = append(ctx.floats, f)
+ return *(*any)(unsafe.Pointer(&emptyInterface{typ: float64TypePtr, ptr: unsafe.Pointer(&ctx.floats[len(ctx.floats)-1])}))
+}
+
+// boxString returns s as an interface value, which refers to a slot of the slab of strings.
+func (ctx *RuntimeContext) boxString(s string) any {
+ if len(ctx.strings) == cap(ctx.strings) {
+ ctx.strings = make([]string, 0, boxSlabSize)
+ }
+ ctx.strings = append(ctx.strings, s)
+ return *(*any)(unsafe.Pointer(&emptyInterface{typ: stringTypePtr, ptr: unsafe.Pointer(&ctx.strings[len(ctx.strings)-1])}))
+}
+
+// popAny removes the elements of anyStack from base, clearing them so that the stack keeps nothing alive.
+func (ctx *RuntimeContext) popAny(base int) {
+ clear(ctx.anyStack[base:])
+ ctx.anyStack = ctx.anyStack[:base]
+}
+
+// anyEntry is an entry of an object being decoded into a map[string]interface{}.
+type anyEntry struct {
+ key string
+ value any
+}
+
+// popEntries removes the entries of entryStack from base, clearing them so that the stack keeps nothing alive.
+func (ctx *RuntimeContext) popEntries(base int) {
+ clear(ctx.entryStack[base:])
+ ctx.entryStack = ctx.entryStack[:base]
+}
+
+// cacheLineSize is the size of the cache lines the contexts are kept apart by: 128 bytes, which is the line of
+// the Apple M processors and two lines of amd64, whose adjacent lines are fetched together.
+const cacheLineSize = 128
+
+// pooledContext is a context of the pool with its option, in one allocation which fills its cache lines: the
+// contexts of the goroutines which decode at the same time are written for every call, so a context which
+// shared a cache line with another made each goroutine wait for the other.
+type pooledContext struct {
+ ctx RuntimeContext
+ opt Option
+ _ [cacheLineSize - (unsafe.Sizeof(RuntimeContext{})+unsafe.Sizeof(Option{}))%cacheLineSize]byte
}
var (
runtimeContextPool = sync.Pool{
- New: func() interface{} {
- return &RuntimeContext{
- Option: &Option{},
- }
+ New: func() any {
+ c := &pooledContext{}
+ c.ctx.Option = &c.opt
+ c.ctx.recentDecoders = &[recentDecoderSets]recentDecoderSet{}
+ return &c.ctx
},
}
)
@@ -27,6 +269,15 @@ func TakeRuntimeContext() *RuntimeContext {
}
func ReleaseRuntimeContext(ctx *RuntimeContext) {
+ // Nothing of the call is kept: the input of the caller may be referred to by the decoded strings.
+ ctx.Buf = nil
+ ctx.origin = nil
+ ctx.slot = nil
+ ctx.popAny(0)
+ ctx.popEntries(0)
+ // The strings refer to the input: the slab is not kept, so that a context in the pool doesn't keep
+ // the input of a previous call alive. The slab of floats refers to nothing and is kept.
+ ctx.strings = nil
runtimeContextPool.Put(ctx)
}
@@ -42,7 +293,7 @@ func init() {
}
func char(ptr unsafe.Pointer, offset int64) byte {
- return *(*byte)(unsafe.Pointer(uintptr(ptr) + uintptr(offset)))
+ return *(*byte)(unsafe.Add(ptr, offset))
}
func skipWhiteSpace(buf []byte, cursor int64) int64 {
@@ -52,96 +303,52 @@ func skipWhiteSpace(buf []byte, cursor int64) int64 {
return cursor
}
-func skipObject(buf []byte, cursor, depth int64) (int64, error) {
- braceCount := 1
- for {
- switch buf[cursor] {
- case '{':
- braceCount++
- depth++
- if depth > maxDecodeNestingDepth {
- return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
- }
- case '}':
- depth--
- braceCount--
- if braceCount == 0 {
- return cursor + 1, nil
- }
- case '[':
- depth++
- if depth > maxDecodeNestingDepth {
- return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
- }
- case ']':
- depth--
- case '"':
- for {
- cursor++
- switch buf[cursor] {
- case '\\':
- cursor++
- if buf[cursor] == nul {
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- case '"':
- goto SWITCH_OUT
- case nul:
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
+// skipStringDecoder scans the strings which skipValue skips.
+var skipStringDecoder = newStringDecoder("", "")
+
+// skipString returns the position after the string at cursor. A string without an escape is skipped word by
+// word up to its quote, where the buffer has room for the words ( the nul byte at its end stops them ), and, where the CPU has a SIMD scan, for its
+// first 64 bytes, after which the rest of a long string is scanned by SIMD ( see scanStringRest ). Any other
+// string is scanned as a string is decoded, and validated so. It is a function of its own, so that the code of
+// skipValue for the other values is the same whatever a string takes.
+func skipString(buf []byte, cursor int64) (int64, error) {
+ start := cursor + 1
+ wordsEnd := int64(len(buf))
+ if hasStringSIMD {
+ wordsEnd = min(wordsEnd, start+64)
+ }
+ c := start
+ for ; c+8 <= wordsEnd; c += 8 {
+ if special := keyEndBytes(load64(buf, c)); special != 0 {
+ c += int64(bits.TrailingZeros64(special) / 8)
+ if buf[c] == '"' {
+ return c + 1, nil
}
- case nul:
- return 0, errors.ErrUnexpectedEndOfJSON("object of object", cursor)
+ // an escape or a byte which is not valid in a string
+ return skipStringByScan(buf, cursor)
}
- SWITCH_OUT:
- cursor++
}
+ if c+8 > int64(len(buf)) {
+ // the end of the buffer, whose last bytes are scanned as a string
+ return skipStringByScan(buf, cursor)
+ }
+ _, next, _, err := skipStringDecoder.scanStringRest(buf, buf[start:c], c, stringInfo{firstEscape: -1})
+ if err != nil {
+ return 0, err
+ }
+ return next, nil
}
-func skipArray(buf []byte, cursor, depth int64) (int64, error) {
- bracketCount := 1
- for {
- switch buf[cursor] {
- case '[':
- bracketCount++
- depth++
- if depth > maxDecodeNestingDepth {
- return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
- }
- case ']':
- bracketCount--
- depth--
- if bracketCount == 0 {
- return cursor + 1, nil
- }
- case '{':
- depth++
- if depth > maxDecodeNestingDepth {
- return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
- }
- case '}':
- depth--
- case '"':
- for {
- cursor++
- switch buf[cursor] {
- case '\\':
- cursor++
- if buf[cursor] == nul {
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- case '"':
- goto SWITCH_OUT
- case nul:
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- }
- case nul:
- return 0, errors.ErrUnexpectedEndOfJSON("array of object", cursor)
- }
- SWITCH_OUT:
- cursor++
+// skipStringByScan is skipString for any string, which it scans as a string is decoded.
+func skipStringByScan(buf []byte, cursor int64) (int64, error) {
+ literal, next, info, err := skipStringDecoder.scanString(buf, cursor)
+ if next < 0 {
+ _, next, _, err = skipStringDecoder.scanStringRest(buf, literal, -next-1, info)
}
+ if err != nil {
+ return 0, err
+ }
+ return next, nil
}
func skipValue(buf []byte, cursor, depth int64) (int64, error) {
@@ -150,54 +357,49 @@ func skipValue(buf []byte, cursor, depth int64) (int64, error) {
case ' ', '\t', '\n', '\r':
cursor++
continue
- case '{':
- return skipObject(buf, cursor+1, depth+1)
- case '[':
- return skipArray(buf, cursor+1, depth+1)
+ case '{', '[':
+ // the grammar of the object or the array, by skipFast without the call of skipGrammarFast
+ end, level, objects, resume, ev := skipFast(buf, cursor, 0, 0, resumeValue, skipMaxLevel(depth))
+ if ev == skipDone {
+ return end, nil
+ }
+ return skipGrammarEvent(buf, end, depth, level, objects, resume, ev)
case '"':
- for {
- cursor++
- switch buf[cursor] {
- case '\\':
- cursor++
- if buf[cursor] == nul {
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- case '"':
- return cursor + 1, nil
- case nul:
- return 0, errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
+ end, err := skipString(buf, cursor)
+ if err != nil {
+ return 0, stringError(buf, cursor, err)
}
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- for {
+ return end, nil
+ case '1', '2', '3', '4', '5', '6', '7', '8', '9':
+ // an integer, which most numbers are, without a call
+ start := cursor
+ cursor++
+ for buf[cursor]-'0' <= 9 {
cursor++
- if floatTable[buf[cursor]] {
- continue
- }
- break
+ }
+ if c := buf[cursor]; c == '.' || c == 'e' || c == 'E' {
+ return skipNumberRest(buf, start, cursor)
}
return cursor, nil
+ case '-', '0':
+ return skipNumber(buf, cursor)
case 't':
- if err := validateTrue(buf, cursor); err != nil {
- return 0, err
+ if buf[cursor+1] != 'r' || buf[cursor+2] != 'u' || buf[cursor+3] != 'e' {
+ return 0, literalSyntaxError(buf, cursor, "true")
}
- cursor += 4
- return cursor, nil
+ return cursor + 4, nil
case 'f':
- if err := validateFalse(buf, cursor); err != nil {
- return 0, err
+ if buf[cursor+1] != 'a' || buf[cursor+2] != 'l' || buf[cursor+3] != 's' || buf[cursor+4] != 'e' {
+ return 0, literalSyntaxError(buf, cursor, "false")
}
- cursor += 5
- return cursor, nil
+ return cursor + 5, nil
case 'n':
- if err := validateNull(buf, cursor); err != nil {
- return 0, err
+ if buf[cursor+1] != 'u' || buf[cursor+2] != 'l' || buf[cursor+3] != 'l' {
+ return 0, literalSyntaxError(buf, cursor, "null")
}
- cursor += 4
- return cursor, nil
+ return cursor + 4, nil
default:
- return cursor, errors.ErrUnexpectedEndOfJSON("null", cursor)
+ return 0, syntaxErrorAt(buf, cursor, whereValue)
}
}
}
@@ -207,13 +409,13 @@ func validateTrue(buf []byte, cursor int64) error {
return errors.ErrUnexpectedEndOfJSON("true", cursor)
}
if buf[cursor+1] != 'r' {
- return errors.ErrInvalidCharacter(buf[cursor+1], "true", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+1], "true", cursor+1)
}
if buf[cursor+2] != 'u' {
- return errors.ErrInvalidCharacter(buf[cursor+2], "true", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+2], "true", cursor+2)
}
if buf[cursor+3] != 'e' {
- return errors.ErrInvalidCharacter(buf[cursor+3], "true", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+3], "true", cursor+3)
}
return nil
}
@@ -223,16 +425,16 @@ func validateFalse(buf []byte, cursor int64) error {
return errors.ErrUnexpectedEndOfJSON("false", cursor)
}
if buf[cursor+1] != 'a' {
- return errors.ErrInvalidCharacter(buf[cursor+1], "false", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+1], "false", cursor+1)
}
if buf[cursor+2] != 'l' {
- return errors.ErrInvalidCharacter(buf[cursor+2], "false", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+2], "false", cursor+2)
}
if buf[cursor+3] != 's' {
- return errors.ErrInvalidCharacter(buf[cursor+3], "false", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+3], "false", cursor+3)
}
if buf[cursor+4] != 'e' {
- return errors.ErrInvalidCharacter(buf[cursor+4], "false", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+4], "false", cursor+4)
}
return nil
}
@@ -242,13 +444,41 @@ func validateNull(buf []byte, cursor int64) error {
return errors.ErrUnexpectedEndOfJSON("null", cursor)
}
if buf[cursor+1] != 'u' {
- return errors.ErrInvalidCharacter(buf[cursor+1], "null", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+1], "null", cursor+1)
}
if buf[cursor+2] != 'l' {
- return errors.ErrInvalidCharacter(buf[cursor+2], "null", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+2], "null", cursor+2)
}
if buf[cursor+3] != 'l' {
- return errors.ErrInvalidCharacter(buf[cursor+3], "null", cursor)
+ return errors.ErrInvalidCharacter(buf[cursor+3], "null", cursor+3)
}
return nil
}
+
+// valuePools are the zero values of every type which UnmarshalOf decoded, besides the one a context keeps.
+var valuePools runtime.TypeCache[sync.Pool]
+
+// TakeValue returns the address of a zero value of typ in the heap, which the context keeps for the next call
+// with the same type. typ is given as its type descriptor too, which is how it is looked up.
+func (ctx *RuntimeContext) TakeValue(typ reflect.Type, typeptr unsafe.Pointer) unsafe.Pointer {
+ if ctx.valueType == typeptr {
+ return ctx.value
+ }
+ if ctx.valueType != nil {
+ valuePool(ctx.valueType).Put(ctx.value)
+ }
+ ctx.valueType = typeptr
+ if v := valuePool(typeptr).Get(); v != nil {
+ ctx.value = v.(unsafe.Pointer)
+ } else {
+ ctx.value = newValue(typ)
+ }
+ return ctx.value
+}
+
+func valuePool(typeptr unsafe.Pointer) *sync.Pool {
+ if pool := valuePools.Load(uintptr(typeptr)); pool != nil {
+ return pool
+ }
+ return valuePools.Store(uintptr(typeptr), &sync.Pool{})
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/float.go b/vendor/github.com/goccy/go-json/internal/decoder/float.go
index 9b2eb8b35..aebde0d96 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/float.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/float.go
@@ -1,6 +1,8 @@
package decoder
import (
+ "math"
+ "reflect"
"strconv"
"unsafe"
@@ -11,10 +13,22 @@ type floatDecoder struct {
op func(unsafe.Pointer, float64)
structName string
fieldName string
+ // is32 is set for a float32, whose range is checked: a number out of it is a type error.
+ is32 bool
+ // typ is the type of the value, which the type errors report.
+ typ reflect.Type
}
func newFloatDecoder(structName, fieldName string, op func(unsafe.Pointer, float64)) *floatDecoder {
- return &floatDecoder{op: op, structName: structName, fieldName: fieldName}
+ return &floatDecoder{op: op, structName: structName, fieldName: fieldName, typ: reflect.TypeOf(float64(0))}
+}
+
+// overflowsFloat32 reports whether f is out of the range of a float32, as reflect.Value.OverflowFloat does.
+func overflowsFloat32(f float64) bool {
+ if f < 0 {
+ f = -f
+ }
+ return math.MaxFloat32 < f && f <= math.MaxFloat64
}
var (
@@ -49,49 +63,6 @@ var (
}
)
-func floatBytes(s *Stream) []byte {
- start := s.cursor
- for {
- s.cursor++
- if floatTable[s.char()] {
- continue
- } else if s.char() == nul {
- if s.read() {
- s.cursor-- // for retry current character
- continue
- }
- }
- break
- }
- return s.buf[start:s.cursor]
-}
-
-func (d *floatDecoder) decodeStreamByte(s *Stream) ([]byte, error) {
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return floatBytes(s), nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case nul:
- if s.read() {
- continue
- }
- goto ERROR
- default:
- goto ERROR
- }
- }
-ERROR:
- return nil, errors.ErrUnexpectedEndOfJSON("float", s.totalOffset())
-}
-
func (d *floatDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
for {
switch buf[cursor] {
@@ -118,43 +89,67 @@ func (d *floatDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, erro
}
}
-func (d *floatDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamByte(s)
- if err != nil {
- return err
- }
- if bytes == nil {
- return nil
- }
- str := *(*string)(unsafe.Pointer(&bytes))
- f64, err := strconv.ParseFloat(str, 64)
- if err != nil {
- return errors.ErrSyntax(err.Error(), s.totalOffset())
+func (d *floatDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ if f, next, ok := parseFloatFast(buf, cursor); ok && validEndNumberChar[buf[next]] {
+ d.op(p, f)
+ return next, nil
}
- d.op(p, f64)
- return nil
+ return d.decodeSlow(ctx, cursor, depth, p)
}
-func (d *floatDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+// float32Decoder is the decoder of a float32, whose range is checked: a number out of it is a type error. It is a
+// type of its own, so that the decoder of a float64 checks nothing more.
+type float32Decoder struct {
+ floatDecoder
+}
+
+func (d *float32Decoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
- bytes, c, err := d.decodeByte(buf, cursor)
- if err != nil {
- return 0, err
+ cursor = skipWhiteSpace(buf, cursor)
+ if f, next, ok := parseFloatFast(buf, cursor); ok && validEndNumberChar[buf[next]] && !overflowsFloat32(f) {
+ d.op(p, f)
+ return next, nil
}
- if bytes == nil {
- return c, nil
- }
- cursor = c
- if !validEndNumberChar[buf[cursor]] {
- return 0, errors.ErrUnexpectedEndOfJSON("float", cursor)
- }
- s := *(*string)(unsafe.Pointer(&bytes))
- f64, err := strconv.ParseFloat(s, 64)
- if err != nil {
- return 0, errors.ErrSyntax(err.Error(), cursor)
+ return d.decodeSlow(ctx, cursor, depth, p)
+}
+
+// decodeSlow decodes the value at cursor which the fast parse doesn't: null, a number which it can't parse, a
+// number out of the range of the type, which is a type error, or a value of another kind, which is a type error
+// too. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *floatDecoder) decodeSlow(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ switch c := buf[cursor]; {
+ case c == 'n':
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
+ }
+ return cursor + 4, nil
+ case c == '-' || c-'0' <= 9:
+ end, err := numberEnd(buf, cursor)
+ if err != nil {
+ return 0, err
+ }
+ b := buf[cursor:end]
+ f, parseErr := strconv.ParseFloat(*(*string)(unsafe.Pointer(&b)), 64)
+ // a number of the grammar which ParseFloat fails is out of the range of float64
+ if inRange := parseErr == nil && !(d.is32 && overflowsFloat32(f)); !inRange {
+ ctx.numberTypeError(cursor, end, d.typ)
+ if storesFloatsOutOfRange {
+ // ±Inf, which ParseFloat returns, or which the conversion to a float32 makes
+ d.op(p, f)
+ }
+ return end, nil
+ }
+ d.op(p, f)
+ return end, nil
+ case isOtherValue(c, numberValue):
+ return ctx.skipTypeError(cursor, depth, d.typ)
}
- d.op(p, f64)
- return cursor, nil
+ return 0, errors.ErrUnexpectedEndOfJSON("float", cursor)
}
func (d *floatDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/func.go b/vendor/github.com/goccy/go-json/internal/decoder/func.go
index 4cc12ca81..0b7753b4d 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/func.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/func.go
@@ -1,144 +1,34 @@
package decoder
import (
- "bytes"
"fmt"
+ "reflect"
"unsafe"
-
- "github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type funcDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
structName string
fieldName string
}
-func newFuncDecoder(typ *runtime.Type, structName, fieldName string) *funcDecoder {
+func newFuncDecoder(typ reflect.Type, structName, fieldName string) *funcDecoder {
fnDecoder := &funcDecoder{typ, structName, fieldName}
return fnDecoder
}
-func (d *funcDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- s.skipWhiteSpace()
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- if len(src) > 0 {
- switch src[0] {
- case '"':
- return &errors.UnmarshalTypeError{
- Value: "string",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case '[':
- return &errors.UnmarshalTypeError{
- Value: "array",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case '{':
- return &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return &errors.UnmarshalTypeError{
- Value: "number",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- *(*unsafe.Pointer)(p) = nil
- return nil
- case 't':
- if err := trueBytes(s); err == nil {
- return &errors.UnmarshalTypeError{
- Value: "boolean",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- }
- case 'f':
- if err := falseBytes(s); err == nil {
- return &errors.UnmarshalTypeError{
- Value: "boolean",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- }
- }
- }
- return errors.ErrInvalidBeginningOfValue(s.buf[s.cursor], s.totalOffset())
-}
-
func (d *funcDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
- start := cursor
- end, err := skipValue(buf, cursor, depth)
- if err != nil {
- return 0, err
- }
- src := buf[start:end]
- if len(src) > 0 {
- switch src[0] {
- case '"':
- return 0, &errors.UnmarshalTypeError{
- Value: "string",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case '[':
- return 0, &errors.UnmarshalTypeError{
- Value: "array",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case '{':
- return 0, &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return 0, &errors.UnmarshalTypeError{
- Value: "number",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case 'n':
- if bytes.Equal(src, nullbytes) {
- *(*unsafe.Pointer)(p) = nil
- return end, nil
- }
- case 't':
- if err := validateTrue(buf, start); err == nil {
- return 0, &errors.UnmarshalTypeError{
- Value: "boolean",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- }
- case 'f':
- if err := validateFalse(buf, start); err == nil {
- return 0, &errors.UnmarshalTypeError{
- Value: "boolean",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- }
+ if buf[cursor] == 'n' {
+ if buf[cursor+1] != 'u' || buf[cursor+2] != 'l' || buf[cursor+3] != 'l' {
+ return 0, literalSyntaxError(buf, cursor, "null")
}
+ *(*unsafe.Pointer)(p) = nil
+ return cursor + 4, nil
}
- return cursor, errors.ErrInvalidBeginningOfValue(buf[cursor], cursor)
+ // a func can't be decoded from any other value: it is a type error, after which the decoding goes on
+ return ctx.skipTypeError(cursor, depth, d.typ)
}
func (d *funcDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/int.go b/vendor/github.com/goccy/go-json/internal/decoder/int.go
index 1a7f08199..caba2f993 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/int.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/int.go
@@ -6,18 +6,17 @@ import (
"unsafe"
"github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type intDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
kind reflect.Kind
op func(unsafe.Pointer, int64)
structName string
fieldName string
}
-func newIntDecoder(typ *runtime.Type, structName, fieldName string, op func(unsafe.Pointer, int64)) *intDecoder {
+func newIntDecoder(typ reflect.Type, structName, fieldName string, op func(unsafe.Pointer, int64)) *intDecoder {
return &intDecoder{
typ: typ,
kind: typ.Kind(),
@@ -27,218 +26,115 @@ func newIntDecoder(typ *runtime.Type, structName, fieldName string, op func(unsa
}
}
-func (d *intDecoder) typeError(buf []byte, offset int64) *errors.UnmarshalTypeError {
- return &errors.UnmarshalTypeError{
- Value: fmt.Sprintf("number %s", string(buf)),
- Type: runtime.RType2Type(d.typ),
- Struct: d.structName,
- Field: d.fieldName,
- Offset: offset,
- }
-}
-
-var (
- pow10i64 = [...]int64{
- 1e00, 1e01, 1e02, 1e03, 1e04, 1e05, 1e06, 1e07, 1e08, 1e09,
- 1e10, 1e11, 1e12, 1e13, 1e14, 1e15, 1e16, 1e17, 1e18,
- }
- pow10i64Len = len(pow10i64)
-)
-
-func (d *intDecoder) parseInt(b []byte) (int64, error) {
- isNegative := false
- if b[0] == '-' {
- b = b[1:]
- isNegative = true
- }
- maxDigit := len(b)
- if maxDigit > pow10i64Len {
- return 0, fmt.Errorf("invalid length of number")
- }
- sum := int64(0)
- for i := 0; i < maxDigit; i++ {
- c := int64(b[i]) - 48
- digitValue := pow10i64[maxDigit-i-1]
- sum += c * digitValue
- }
- if isNegative {
- return -1 * sum, nil
- }
- return sum, nil
-}
-
-var (
- numTable = [256]bool{
- '0': true,
- '1': true,
- '2': true,
- '3': true,
- '4': true,
- '5': true,
- '6': true,
- '7': true,
- '8': true,
- '9': true,
- }
-)
-
-var (
- numZeroBuf = []byte{'0'}
-)
-
-func (d *intDecoder) decodeStreamByte(s *Stream) ([]byte, error) {
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case '-':
- start := s.cursor
- for {
- s.cursor++
- if numTable[s.char()] {
- continue
- } else if s.char() == nul {
- if s.read() {
- s.cursor-- // for retry current character
- continue
- }
- }
- break
- }
- num := s.buf[start:s.cursor]
- if len(num) < 2 {
- goto ERROR
- }
- return num, nil
- case '0':
- s.cursor++
- return numZeroBuf, nil
- case '1', '2', '3', '4', '5', '6', '7', '8', '9':
- start := s.cursor
- for {
- s.cursor++
- if numTable[s.char()] {
- continue
- } else if s.char() == nul {
- if s.read() {
- s.cursor-- // for retry current character
- continue
- }
- }
- break
- }
- num := s.buf[start:s.cursor]
- return num, nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case nul:
- if s.read() {
- continue
- }
- goto ERROR
- default:
- return nil, d.typeError([]byte{s.char()}, s.totalOffset())
+func (d *intDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ start := cursor
+ switch buf[cursor] {
+ case 'n':
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
}
+ return cursor + 4, nil
+ case '-':
+ cursor++
}
-ERROR:
- return nil, errors.ErrUnexpectedEndOfJSON("number(integer)", s.totalOffset())
-}
-
-func (d *intDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
- b := (*sliceHeader)(unsafe.Pointer(&buf)).data
- for {
- switch char(b, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- continue
- case '0':
- cursor++
- return numZeroBuf, cursor, nil
- case '-', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- start := cursor
- cursor++
- for numTable[char(b, cursor)] {
- cursor++
- }
- num := buf[start:cursor]
- return num, cursor, nil
- case 'n':
- if err := validateNull(buf, cursor); err != nil {
- return nil, 0, err
- }
- cursor += 4
- return nil, cursor, nil
- default:
- return nil, 0, d.typeError([]byte{char(b, cursor)}, cursor)
- }
+ if buf[cursor]-'0' > 9 {
+ return d.decodeSlow(ctx, start, depth, p)
}
-}
-
-func (d *intDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamByte(s)
- if err != nil {
- return err
+ u, next, digits := parseDigits(buf, cursor)
+ if isFloatContinuation(buf[next]) || digits > maxUint64Digits {
+ return d.decodeSlow(ctx, start, depth, p)
}
- if bytes == nil {
- return nil
+ neg := cursor > start
+ if (neg && u > 1<<63) || (!neg && u > 1<<63-1) {
+ return d.decodeSlow(ctx, start, depth, p)
}
- i64, err := d.parseInt(bytes)
- if err != nil {
- return d.typeError(bytes, s.totalOffset())
+ i64 := int64(u)
+ if neg {
+ i64 = -i64
}
switch d.kind {
case reflect.Int8:
if i64 < -1*(1<<7) || (1<<7) <= i64 {
- return d.typeError(bytes, s.totalOffset())
+ return d.decodeSlow(ctx, start, depth, p)
}
case reflect.Int16:
if i64 < -1*(1<<15) || (1<<15) <= i64 {
- return d.typeError(bytes, s.totalOffset())
+ return d.decodeSlow(ctx, start, depth, p)
}
case reflect.Int32:
if i64 < -1*(1<<31) || (1<<31) <= i64 {
- return d.typeError(bytes, s.totalOffset())
+ return d.decodeSlow(ctx, start, depth, p)
}
}
d.op(p, i64)
- s.reset()
- return nil
+ return next, nil
}
-func (d *intDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- bytes, c, err := d.decodeByte(ctx.Buf, cursor)
- if err != nil {
- return 0, err
+// decodeSlow decodes the value at cursor, which Decode doesn't: a value of another kind, or a number which is not
+// an integer of the type, which are type errors, or a syntax error. It is a function of its own, so that Decode
+// keeps the size it had.
+//
+//go:noinline
+func (d *intDecoder) decodeSlow(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ start := cursor
+ switch buf[cursor] {
+ case 'n':
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
+ }
+ return cursor + 4, nil
+ case '-':
+ cursor++
}
- if bytes == nil {
- return c, nil
+ if buf[cursor]-'0' > 9 {
+ if cursor > start {
+ return 0, errors.ErrSyntax(fmt.Sprintf("invalid character %s in numeric literal", quoteChar(buf[cursor])), cursor+1)
+ }
+ // a value of another kind
+ return ctx.skipTypeError(cursor, depth, d.typ)
+ }
+ u, next, digits := parseDigits(buf, cursor)
+ if isFloatContinuation(buf[next]) || digits > maxUint64Digits {
+ // a number which is not an integer, or too large for any integer
+ end, err := numberEnd(buf, start)
+ if err != nil {
+ return 0, err
+ }
+ ctx.numberTypeError(start, end, d.typ)
+ return end, nil
}
- cursor = c
-
- i64, err := d.parseInt(bytes)
- if err != nil {
- return 0, d.typeError(bytes, cursor)
+ neg := cursor > start
+ if (neg && u > 1<<63) || (!neg && u > 1<<63-1) {
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
+ }
+ i64 := int64(u)
+ if neg {
+ i64 = -i64
}
switch d.kind {
case reflect.Int8:
if i64 < -1*(1<<7) || (1<<7) <= i64 {
- return 0, d.typeError(bytes, cursor)
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
case reflect.Int16:
if i64 < -1*(1<<15) || (1<<15) <= i64 {
- return 0, d.typeError(bytes, cursor)
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
case reflect.Int32:
if i64 < -1*(1<<31) || (1<<31) <= i64 {
- return 0, d.typeError(bytes, cursor)
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
}
d.op(p, i64)
- return cursor, nil
+ return next, nil
}
func (d *intDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/interface.go b/vendor/github.com/goccy/go-json/internal/decoder/interface.go
index 45c69ab8c..679e0cce0 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/interface.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/interface.go
@@ -1,10 +1,9 @@
package decoder
import (
- "bytes"
- "encoding"
"encoding/json"
"reflect"
+ "strconv"
"unsafe"
"github.com/goccy/go-json/internal/errors"
@@ -12,7 +11,13 @@ import (
)
type interfaceDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
+ // hasMethods is set for an interface type which has methods, whose value is not replaced by the decoded value
+ // ( see decodeWithMethods ): the value of an interface{} is read without reflect ( see Decode ).
+ hasMethods bool
+ // values are how the values of the types which the interface value holds are decoded, by the type of an
+ // interface{}, or by the itab of an interface type with methods ( see valueDecoderOf ).
+ values runtime.TypeCache[ifaceValueDecoder]
structName string
fieldName string
sliceDecoder *sliceDecoder
@@ -28,10 +33,10 @@ func newEmptyInterfaceDecoder(structName, fieldName string) *interfaceDecoder {
structName: structName,
fieldName: fieldName,
floatDecoder: newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
numberDecoder: newNumberDecoder(structName, fieldName, func(p unsafe.Pointer, v json.Number) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
stringDecoder: newStringDecoder(structName, fieldName),
}
@@ -53,11 +58,12 @@ func newEmptyInterfaceDecoder(structName, fieldName string) *interfaceDecoder {
return ifaceDecoder
}
-func newInterfaceDecoder(typ *runtime.Type, structName, fieldName string) *interfaceDecoder {
+func newInterfaceDecoder(typ reflect.Type, structName, fieldName string) *interfaceDecoder {
emptyIfaceDecoder := newEmptyInterfaceDecoder(structName, fieldName)
stringDecoder := newStringDecoder(structName, fieldName)
return &interfaceDecoder{
typ: typ,
+ hasMethods: typ.NumMethod() > 0,
structName: structName,
fieldName: fieldName,
sliceDecoder: newSliceDecoder(
@@ -76,328 +82,181 @@ func newInterfaceDecoder(typ *runtime.Type, structName, fieldName string) *inter
fieldName,
),
floatDecoder: newFloatDecoder(structName, fieldName, func(p unsafe.Pointer, v float64) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
numberDecoder: newNumberDecoder(structName, fieldName, func(p unsafe.Pointer, v json.Number) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
stringDecoder: stringDecoder,
}
}
-func (d *interfaceDecoder) numDecoder(s *Stream) Decoder {
- if s.UseNumber {
- return d.numberDecoder
- }
- return d.floatDecoder
-}
-
var (
- emptyInterfaceType = runtime.Type2RType(reflect.TypeOf((*interface{})(nil)).Elem())
+ emptyInterfaceType = reflect.TypeOf((*any)(nil)).Elem()
EmptyInterfaceType = emptyInterfaceType
- interfaceMapType = runtime.Type2RType(
- reflect.TypeOf((*map[string]interface{})(nil)).Elem(),
- )
- stringType = runtime.Type2RType(
- reflect.TypeOf(""),
- )
+ interfaceMapType = reflect.TypeOf((*map[string]any)(nil)).Elem()
+ stringType = reflect.TypeOf("")
)
-func decodeStreamUnmarshaler(s *Stream, depth int64, unmarshaler json.Unmarshaler) error {
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- dst := make([]byte, len(src))
- copy(dst, src)
-
- if err := unmarshaler.UnmarshalJSON(dst); err != nil {
- return err
- }
- return nil
-}
-
-func decodeStreamUnmarshalerContext(s *Stream, depth int64, unmarshaler unmarshalerContext) error {
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- dst := make([]byte, len(src))
- copy(dst, src)
-
- if err := unmarshaler.UnmarshalJSON(s.Option.Context, dst); err != nil {
- return err
- }
- return nil
+type emptyInterface struct {
+ typ unsafe.Pointer
+ ptr unsafe.Pointer
}
-func decodeUnmarshaler(buf []byte, cursor, depth int64, unmarshaler json.Unmarshaler) (int64, error) {
- cursor = skipWhiteSpace(buf, cursor)
- start := cursor
- end, err := skipValue(buf, cursor, depth)
- if err != nil {
- return 0, err
- }
- src := buf[start:end]
- dst := make([]byte, len(src))
- copy(dst, src)
-
- if err := unmarshaler.UnmarshalJSON(dst); err != nil {
- return 0, err
+func (d *interfaceDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ if d.hasMethods {
+ return d.decodeWithMethods(ctx, cursor, depth, p)
}
- return end, nil
-}
-
-func decodeUnmarshalerContext(ctx *RuntimeContext, buf []byte, cursor, depth int64, unmarshaler unmarshalerContext) (int64, error) {
- cursor = skipWhiteSpace(buf, cursor)
- start := cursor
- end, err := skipValue(buf, cursor, depth)
- if err != nil {
- return 0, err
+ // p is an interface{}: a nil one, the most common, is decoded as it is, and the value of another one may be
+ // decoded into what it points to
+ h := (*emptyInterface)(p)
+ if h.ptr == nil {
+ return d.decodeEmptyInterface(ctx, cursor, depth, p)
}
- src := buf[start:end]
- dst := make([]byte, len(src))
- copy(dst, src)
-
- if err := unmarshaler.UnmarshalJSON(ctx.Option.Context, dst); err != nil {
- return 0, err
+ v := d.values.Load(uintptr(h.typ))
+ if v == nil {
+ var err error
+ if v, err = d.valueDecoderOf(ctx, h.typ, *(*any)(p)); err != nil {
+ return 0, err
+ }
}
- return end, nil
+ return d.decodeValue(ctx, cursor, depth, p, v, h.ptr)
}
-func decodeStreamTextUnmarshaler(s *Stream, depth int64, unmarshaler encoding.TextUnmarshaler, p unsafe.Pointer) error {
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- if bytes.Equal(src, nullbytes) {
- *(*unsafe.Pointer)(p) = nil
- return nil
- }
-
- dst := make([]byte, len(src))
- copy(dst, src)
+// ifaceValueKind is how the value which an interface value holds is decoded, as encoding/json does.
+type ifaceValueKind uint8
- if err := unmarshaler.UnmarshalText(dst); err != nil {
- return err
- }
- return nil
-}
-
-func decodeTextUnmarshaler(buf []byte, cursor, depth int64, unmarshaler encoding.TextUnmarshaler, p unsafe.Pointer) (int64, error) {
- cursor = skipWhiteSpace(buf, cursor)
- start := cursor
- end, err := skipValue(buf, cursor, depth)
- if err != nil {
- return 0, err
- }
- src := buf[start:end]
- if bytes.Equal(src, nullbytes) {
- *(*unsafe.Pointer)(p) = nil
- return end, nil
- }
- if s, ok := unquoteBytes(src); ok {
- src = s
- }
- if err := unmarshaler.UnmarshalText(src); err != nil {
- return 0, err
- }
- return end, nil
-}
-
-func (d *interfaceDecoder) decodeStreamEmptyInterface(s *Stream, depth int64, p unsafe.Pointer) error {
- c := s.skipWhiteSpace()
- for {
- switch c {
- case '{':
- var v map[string]interface{}
- ptr := unsafe.Pointer(&v)
- if err := d.mapDecoder.DecodeStream(s, depth, ptr); err != nil {
- return err
- }
- *(*interface{})(p) = v
- return nil
- case '[':
- var v []interface{}
- ptr := unsafe.Pointer(&v)
- if err := d.sliceDecoder.DecodeStream(s, depth, ptr); err != nil {
- return err
- }
- *(*interface{})(p) = v
- return nil
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return d.numDecoder(s).DecodeStream(s, depth, p)
- case '"':
- s.cursor++
- start := s.cursor
- for {
- switch s.char() {
- case '\\':
- if _, err := decodeEscapeString(s, nil); err != nil {
- return err
- }
- case '"':
- literal := s.buf[start:s.cursor]
- s.cursor++
- *(*interface{})(p) = string(literal)
- return nil
- case nul:
- if s.read() {
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- }
- s.cursor++
- }
- case 't':
- if err := trueBytes(s); err != nil {
- return err
- }
- **(**interface{})(unsafe.Pointer(&p)) = true
- return nil
- case 'f':
- if err := falseBytes(s); err != nil {
- return err
- }
- **(**interface{})(unsafe.Pointer(&p)) = false
- return nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- *(*interface{})(p) = nil
- return nil
- case nul:
- if s.read() {
- c = s.char()
- continue
- }
- }
- break
- }
- return errors.ErrInvalidBeginningOfValue(c, s.totalOffset())
-}
+const (
+ // ifaceValueReplaced is a value of an interface{} which is replaced by the value decoded as the one of an
+ // interface{}.
+ ifaceValueReplaced ifaceValueKind = iota
+ // ifaceValuePointee is a pointer to a value which is not an interface value: the value is decoded into what it
+ // points to, as a value of the pointer type, whose unmarshalers are used.
+ ifaceValuePointee
+ // ifaceValueKept is a value of an interface type with methods which is not a pointer: it is kept, and can be
+ // decoded from null only, which sets the interface value to nil.
+ ifaceValueKept
+)
-type emptyInterface struct {
- typ *runtime.Type
- ptr unsafe.Pointer
+// ifaceValueDecoder is how a value of a type which an interface value holds is decoded, which depends on the type
+// only: it is found once for a type.
+type ifaceValueDecoder struct {
+ kind ifaceValueKind
+ // dec is the decoder of a pointer of ifaceValuePointee.
+ dec Decoder
+ // textType is the pointer type of ifaceValuePointee which implements encoding.TextUnmarshaler: a value which
+ // is not a string is a type error of the interface value ( see ifaceTextUnmarshalerKindError ).
+ textType reflect.Type
}
-func (d *interfaceDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- runtimeInterfaceValue := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
- ptr: p,
- }))
- rv := reflect.ValueOf(runtimeInterfaceValue)
- if rv.NumMethod() > 0 && rv.CanInterface() {
- if u, ok := rv.Interface().(unmarshalerContext); ok {
- return decodeStreamUnmarshalerContext(s, depth, u)
- }
- if u, ok := rv.Interface().(json.Unmarshaler); ok {
- return decodeStreamUnmarshaler(s, depth, u)
- }
- if u, ok := rv.Interface().(encoding.TextUnmarshaler); ok {
- return decodeStreamTextUnmarshaler(s, depth, u, p)
- }
- if s.skipWhiteSpace() == 'n' {
- if err := nullBytes(s); err != nil {
- return err
- }
- *(*interface{})(p) = nil
- return nil
+// valueDecoderOf finds how the value iface, of the type typ, which the interface value holds is decoded, and
+// keeps it for the type by key: the type of an interface{}, or the itab of an interface type with methods.
+func (d *interfaceDecoder) valueDecoderOf(ctx *RuntimeContext, key unsafe.Pointer, iface any) (*ifaceValueDecoder, error) {
+ v := &ifaceValueDecoder{kind: ifaceValueReplaced}
+ if d.hasMethods {
+ v.kind = ifaceValueKept
+ }
+ if typ := reflect.TypeOf(iface); typ.Kind() == reflect.Ptr && typ.Elem() != d.typ {
+ dec, err := ctx.DecoderOf((*emptyInterface)(unsafe.Pointer(&iface)).typ)
+ if err != nil {
+ return nil, err
}
- return d.errUnmarshalType(rv.Type(), s.totalOffset())
- }
- iface := rv.Interface()
- ifaceHeader := (*emptyInterface)(unsafe.Pointer(&iface))
- typ := ifaceHeader.typ
- if ifaceHeader.ptr == nil || d.typ == typ || typ == nil {
- // concrete type is empty interface
- return d.decodeStreamEmptyInterface(s, depth, p)
- }
- if typ.Kind() == reflect.Ptr && typ.Elem() == d.typ || typ.Kind() != reflect.Ptr {
- return d.decodeStreamEmptyInterface(s, depth, p)
- }
- if s.skipWhiteSpace() == 'n' {
- if err := nullBytes(s); err != nil {
- return err
+ v.kind, v.dec = ifaceValuePointee, dec
+ if text, ok := dec.(*unmarshalTextDecoder); ok {
+ v.textType = text.typ
}
- *(*interface{})(p) = nil
- return nil
- }
- decoder, err := CompileToGetDecoder(typ)
- if err != nil {
- return err
}
- return decoder.DecodeStream(s, depth, ifaceHeader.ptr)
+ return d.values.Store(uintptr(key), v), nil
}
-func (d *interfaceDecoder) errUnmarshalType(typ reflect.Type, offset int64) *errors.UnmarshalTypeError {
- return &errors.UnmarshalTypeError{
- Value: typ.String(),
- Type: typ,
- Offset: offset,
- Struct: d.structName,
- Field: d.fieldName,
- }
-}
-
-func (d *interfaceDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- buf := ctx.Buf
- runtimeInterfaceValue := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
- ptr: p,
- }))
- rv := reflect.ValueOf(runtimeInterfaceValue)
- if rv.NumMethod() > 0 && rv.CanInterface() {
- if u, ok := rv.Interface().(unmarshalerContext); ok {
- return decodeUnmarshalerContext(ctx, buf, cursor, depth, u)
- }
- if u, ok := rv.Interface().(json.Unmarshaler); ok {
- return decodeUnmarshaler(buf, cursor, depth, u)
- }
- if u, ok := rv.Interface().(encoding.TextUnmarshaler); ok {
- return decodeTextUnmarshaler(buf, cursor, depth, u, p)
- }
+// decodeValue decodes the value at cursor into the interface value at p, which holds a value decoded as v says,
+// whose data word is ptr.
+func (d *interfaceDecoder) decodeValue(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer, v *ifaceValueDecoder, ptr unsafe.Pointer) (int64, error) {
+ switch v.kind {
+ case ifaceValueReplaced:
+ return d.decodeEmptyInterface(ctx, cursor, depth, p)
+ case ifaceValuePointee:
+ buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
if buf[cursor] == 'n' {
+ // null sets the interface value to nil, not what it points to
if err := validateNull(buf, cursor); err != nil {
return 0, err
}
- cursor += 4
- **(**interface{})(unsafe.Pointer(&p)) = nil
- return cursor, nil
+ *(*[2]unsafe.Pointer)(p) = [2]unsafe.Pointer{}
+ return cursor + 4, nil
+ }
+ if v.textType != nil && isOtherValue(buf[cursor], stringValue) {
+ return ctx.ifaceTextUnmarshalerKindError(cursor, depth, d.typ, v.textType)
}
- return 0, d.errUnmarshalType(rv.Type(), cursor)
+ return v.dec.Decode(ctx, cursor, depth, ptr)
}
+ return d.decodeKept(ctx, cursor, depth, p)
+}
- iface := rv.Interface()
- ifaceHeader := (*emptyInterface)(unsafe.Pointer(&iface))
- typ := ifaceHeader.typ
- if ifaceHeader.ptr == nil || d.typ == typ || typ == nil {
- // concrete type is empty interface
- return d.decodeEmptyInterface(ctx, cursor, depth, p)
- }
- if typ.Kind() == reflect.Ptr && typ.Elem() == d.typ || typ.Kind() != reflect.Ptr {
- return d.decodeEmptyInterface(ctx, cursor, depth, p)
- }
+// decodeKept decodes the value at cursor into the interface value at p of an interface type with methods, whose
+// value is not decoded into: null sets it to nil, and any other value is a type error, which keeps it, as
+// encoding/json does.
+func (d *interfaceDecoder) decodeKept(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
if buf[cursor] == 'n' {
if err := validateNull(buf, cursor); err != nil {
return 0, err
}
- cursor += 4
- **(**interface{})(unsafe.Pointer(&p)) = nil
- return cursor, nil
+ *(*[2]unsafe.Pointer)(p) = [2]unsafe.Pointer{}
+ return cursor + 4, nil
+ }
+ return ctx.keptInterfaceTypeError(cursor, depth, d.typ, p)
+}
+
+// nonEmptyInterface is the layout of a value of an interface type with methods: the itab of the type it holds,
+// which is nil for a nil value, and the data word.
+type nonEmptyInterface struct {
+ itab unsafe.Pointer
+ ptr unsafe.Pointer
+}
+
+// decodeWithMethods decodes the value of an interface type which has methods: a value which is a pointer is
+// decoded into what it points to, as encoding/json does. How a value is decoded is kept by its itab, which is of
+// one type for the interface type of the decoder.
+func (d *interfaceDecoder) decodeWithMethods(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ h := (*nonEmptyInterface)(p)
+ if h.itab == nil || h.ptr == nil {
+ // a nil value, or a nil pointer
+ return d.decodeKept(ctx, cursor, depth, p)
+ }
+ v := d.values.Load(uintptr(h.itab))
+ if v == nil {
+ var err error
+ if v, err = d.valueDecoderOf(ctx, h.itab, reflect.NewAt(d.typ, p).Elem().Interface()); err != nil {
+ return 0, err
+ }
}
- decoder, err := CompileToGetDecoder(typ)
+ return d.decodeValue(ctx, cursor, depth, p, v, h.ptr)
+}
+
+// decodeFloatSlow decodes the number at cursor into the interface{} at p, which the fast parse doesn't: a number
+// which is not valid by the grammar is a syntax error, and a number out of the range of a float64 is a type error,
+// after which the decoding goes on ( see floatRangeErrorOfInterface ). It is not inlined, so that the decoding of
+// the values of interface{} keeps the size it had.
+//
+//go:noinline
+func decodeFloatSlow(ctx *RuntimeContext, cursor int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ end, err := numberEnd(buf, cursor)
if err != nil {
return 0, err
}
- return decoder.Decode(ctx, cursor, depth, ifaceHeader.ptr)
+ b := buf[cursor:end]
+ f, parseErr := strconv.ParseFloat(*(*string)(unsafe.Pointer(&b)), 64)
+ // a number of the grammar which ParseFloat fails is out of the range of float64
+ if inRange := parseErr == nil; !inRange {
+ ctx.floatRangeErrorOfInterface(cursor, end, f, p)
+ return end, nil
+ }
+ **(**any)(unsafe.Pointer(&p)) = ctx.boxFloat(f)
+ return end, nil
}
func (d *interfaceDecoder) decodeEmptyInterface(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
@@ -405,69 +264,222 @@ func (d *interfaceDecoder) decodeEmptyInterface(ctx *RuntimeContext, cursor, dep
cursor = skipWhiteSpace(buf, cursor)
switch buf[cursor] {
case '{':
- var v map[string]interface{}
- ptr := unsafe.Pointer(&v)
- cursor, err := d.mapDecoder.Decode(ctx, cursor, depth, ptr)
- if err != nil {
- return 0, err
+ depth++
+ if depth > maxDecodeNestingDepth {
+ return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
}
- **(**interface{})(unsafe.Pointer(&p)) = v
- return cursor, nil
- case '[':
- var v []interface{}
- ptr := unsafe.Pointer(&v)
- cursor, err := d.sliceDecoder.Decode(ctx, cursor, depth, ptr)
+ m, cursor, err := decodeNewStringAnyMap(ctx, d, cursor, depth)
if err != nil {
return 0, err
}
- **(**interface{})(unsafe.Pointer(&p)) = v
+ **(**any)(unsafe.Pointer(&p)) = m
return cursor, nil
+ case '[':
+ return d.decodeAnySlice(ctx, cursor, depth, p)
case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return d.floatDecoder.Decode(ctx, cursor, depth, p)
+ if (ctx.Option.Flags & UseNumberOption) != 0 {
+ return d.numberDecoder.Decode(ctx, cursor, depth, p)
+ }
+ if f, next, ok := parseFloatFast(buf, cursor); ok && validEndNumberChar[buf[next]] {
+ **(**any)(unsafe.Pointer(&p)) = ctx.boxFloat(f)
+ return next, nil
+ }
+ return decodeFloatSlow(ctx, cursor, p)
case '"':
- var v string
- ptr := unsafe.Pointer(&v)
- cursor, err := d.stringDecoder.Decode(ctx, cursor, depth, ptr)
+ if end := plainStringEnd(buf, cursor+1); end >= 0 {
+ **(**any)(unsafe.Pointer(&p)) = ctx.boxString(ctx.makeString(buf[cursor+1 : end]))
+ return end + 1, nil
+ }
+ s, c, _, err := d.stringDecoder.decodeString(ctx, cursor)
if err != nil {
return 0, err
}
- **(**interface{})(unsafe.Pointer(&p)) = v
- return cursor, nil
+ **(**any)(unsafe.Pointer(&p)) = ctx.boxString(s)
+ return c, nil
case 't':
if err := validateTrue(buf, cursor); err != nil {
return 0, err
}
cursor += 4
- **(**interface{})(unsafe.Pointer(&p)) = true
+ **(**any)(unsafe.Pointer(&p)) = true
return cursor, nil
case 'f':
if err := validateFalse(buf, cursor); err != nil {
return 0, err
}
cursor += 5
- **(**interface{})(unsafe.Pointer(&p)) = false
+ **(**any)(unsafe.Pointer(&p)) = false
return cursor, nil
case 'n':
if err := validateNull(buf, cursor); err != nil {
return 0, err
}
cursor += 4
- **(**interface{})(unsafe.Pointer(&p)) = nil
+ **(**any)(unsafe.Pointer(&p)) = nil
return cursor, nil
}
return cursor, errors.ErrInvalidBeginningOfValue(buf[cursor], cursor)
}
+// decodeStringAnyMap decodes the object at cursor into m, a map[string]interface{}, by the assignment of Go:
+// the values are decoded as interface{} by d. depth counts the object already.
+func decodeStringAnyMap(ctx *RuntimeContext, d *interfaceDecoder, m map[string]any, cursor, depth int64) (int64, error) {
+ buf := ctx.Buf
+ cursor++ // '{'
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == '}' {
+ return cursor + 1, nil
+ }
+ for {
+ key, c, ok, err := d.stringDecoder.decodeString(ctx, cursor)
+ if err != nil {
+ return 0, err
+ }
+ if !ok {
+ // null is not a key
+ return 0, errors.ErrSyntax("invalid character 'n' looking for beginning of object key string", skipWhiteSpace(buf, cursor)+1)
+ }
+ cursor = skipWhiteSpace(buf, c)
+ if buf[cursor] != ':' {
+ return 0, errors.ErrExpected("colon after object key", cursor)
+ }
+ cursor++
+ c, err = d.decodeEmptyInterface(ctx, cursor, depth, unsafe.Pointer(&ctx.slot))
+ if err != nil {
+ ctx.slot = nil
+ return 0, err
+ }
+ m[key] = ctx.slot
+ ctx.slot = nil
+ cursor = skipWhiteSpace(buf, c)
+ switch buf[cursor] {
+ case '}':
+ return cursor + 1, nil
+ case ',':
+ cursor++
+ default:
+ return 0, errors.ErrExpected("comma after object value", cursor)
+ }
+ }
+}
+
+// decodeNewStringAnyMap decodes the object at cursor into a new map[string]interface{}. The entries are pushed
+// to the stack of entries of the context, each key with its value, and put into a map of their number at the end
+// of the object: a map filled entry by entry grows and moves its entries several times on the way, which took
+// more time than the entries themselves. A key which is repeated is put later, so that the last one wins as in a
+// map filled in order.
+func decodeNewStringAnyMap(ctx *RuntimeContext, d *interfaceDecoder, cursor, depth int64) (map[string]any, int64, error) {
+ buf := ctx.Buf
+ cursor++ // '{'
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == '}' {
+ return map[string]any{}, cursor + 1, nil
+ }
+ base := len(ctx.entryStack)
+ fail := func(err error) (map[string]any, int64, error) {
+ ctx.slot = nil
+ ctx.popEntries(base)
+ return nil, 0, err
+ }
+ for {
+ if cursor = skipWhiteSpace(buf, cursor); buf[cursor] != '"' {
+ return fail(syntaxErrorAt(buf, cursor, whereKey))
+ }
+ var key string
+ var c int64
+ if end := plainStringEnd(buf, cursor+1); end >= 0 {
+ key, c = ctx.makeString(buf[cursor+1:end]), end+1
+ } else {
+ var err error
+ if key, c, _, err = d.stringDecoder.decodeString(ctx, cursor); err != nil {
+ return fail(err)
+ }
+ }
+ cursor = skipWhiteSpace(buf, c)
+ if buf[cursor] != ':' {
+ return fail(syntaxErrorAt(buf, cursor, whereAfterKey))
+ }
+ cursor++
+ c, err := d.decodeEmptyInterface(ctx, cursor, depth, unsafe.Pointer(&ctx.slot))
+ if err != nil {
+ return fail(err)
+ }
+ // the key and the value are pushed together, after the value, whose own entries are popped already.
+ ctx.entryStack = append(ctx.entryStack, anyEntry{key: key, value: ctx.slot})
+ ctx.slot = nil
+ cursor = skipWhiteSpace(buf, c)
+ switch buf[cursor] {
+ case '}':
+ entries := ctx.entryStack[base:]
+ m := make(map[string]any, len(entries))
+ for i := range entries {
+ m[entries[i].key] = entries[i].value
+ }
+ ctx.popEntries(base)
+ return m, cursor + 1, nil
+ case ',':
+ cursor++
+ default:
+ return fail(errors.ErrExpected("comma after object value", cursor))
+ }
+ }
+}
+
+// emptyAnySlice is the value of an empty array as interface{}: an empty []interface{}, which all of them share,
+// so that it is not allocated for each. It has no room for an element, so that nothing is written through it.
+var emptyAnySlice any = []any{}
+
+// decodeAnySlice decodes the array at cursor as a []interface{}: the elements are pushed to the stack
+// of the context, and copied into a slice of their number at the end of the array.
+func (d *interfaceDecoder) decodeAnySlice(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ depth++
+ if depth > maxDecodeNestingDepth {
+ return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
+ }
+ cursor++ // '['
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == ']' {
+ **(**any)(unsafe.Pointer(&p)) = emptyAnySlice
+ return cursor + 1, nil
+ }
+ base := len(ctx.anyStack)
+ for {
+ c, err := d.decodeEmptyInterface(ctx, cursor, depth, unsafe.Pointer(&ctx.slot))
+ if err != nil {
+ ctx.slot = nil
+ ctx.popAny(base)
+ return 0, err
+ }
+ ctx.anyStack = append(ctx.anyStack, ctx.slot)
+ ctx.slot = nil
+ cursor = skipWhiteSpace(buf, c)
+ switch buf[cursor] {
+ case ']':
+ elems := make([]any, len(ctx.anyStack)-base)
+ copy(elems, ctx.anyStack[base:])
+ ctx.popAny(base)
+ **(**any)(unsafe.Pointer(&p)) = elems
+ return cursor + 1, nil
+ case ',':
+ cursor++
+ default:
+ ctx.popAny(base)
+ return 0, errors.ErrInvalidCharacter(buf[cursor], "slice", cursor)
+ }
+ }
+}
+
func NewPathDecoder() Decoder {
ifaceDecoder := &interfaceDecoder{
typ: emptyInterfaceType,
structName: "",
fieldName: "",
floatDecoder: newFloatDecoder("", "", func(p unsafe.Pointer, v float64) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
numberDecoder: newNumberDecoder("", "", func(p unsafe.Pointer, v json.Number) {
- *(*interface{})(p) = v
+ *(*any)(p) = v
}),
stringDecoder: newStringDecoder("", ""),
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/invalid.go b/vendor/github.com/goccy/go-json/internal/decoder/invalid.go
index 4c9721b09..4fdc4fbc5 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/invalid.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/invalid.go
@@ -5,17 +5,16 @@ import (
"unsafe"
"github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type invalidDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
kind reflect.Kind
structName string
fieldName string
}
-func newInvalidDecoder(typ *runtime.Type, structName, fieldName string) *invalidDecoder {
+func newInvalidDecoder(typ reflect.Type, structName, fieldName string) *invalidDecoder {
return &invalidDecoder{
typ: typ,
kind: typ.Kind(),
@@ -24,30 +23,24 @@ func newInvalidDecoder(typ *runtime.Type, structName, fieldName string) *invalid
}
}
-func (d *invalidDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- return &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- Struct: d.structName,
- Field: d.fieldName,
- }
-}
-
+// Decode skips the value, which no value of the type can be decoded from: it is a type error, as encoding/json
+// reports it, but null, which is ignored.
func (d *invalidDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- return 0, &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: cursor,
- Struct: d.structName,
- Field: d.fieldName,
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == 'n' {
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
+ }
+ return cursor + 4, nil
}
+ return ctx.skipTypeError(cursor, depth, d.typ)
}
func (d *invalidDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
return nil, 0, &errors.UnmarshalTypeError{
Value: "object",
- Type: runtime.RType2Type(d.typ),
+ Type: d.typ,
Offset: cursor,
Struct: d.structName,
Field: d.fieldName,
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/map.go b/vendor/github.com/goccy/go-json/internal/decoder/map.go
index 07a9caea6..0a0465970 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/map.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/map.go
@@ -2,6 +2,8 @@ package decoder
import (
"reflect"
+ "sync"
+ "sync/atomic"
"unsafe"
"github.com/goccy/go-json/internal/errors"
@@ -9,118 +11,129 @@ import (
)
type mapDecoder struct {
- mapType *runtime.Type
- keyType *runtime.Type
- valueType *runtime.Type
- canUseAssignFaststrType bool
- keyDecoder Decoder
- valueDecoder Decoder
- structName string
- fieldName string
+ mapType reflect.Type
+ keyType reflect.Type
+ valueType reflect.Type
+ // mapTypePtr, keyPtrType and valuePtrType are the type descriptors of the map, of *K and of *V.
+ mapTypePtr unsafe.Pointer
+ keyPtrType unsafe.Pointer
+ valuePtrType unsafe.Pointer
+ // isStringAnyMap is whether the map is a map[string]interface{}, which is decoded without reflect.
+ isStringAnyMap bool
+ keyDecoder Decoder
+ valueDecoder Decoder
+ // keyUnsupported is set for a map whose keys encoding/json of the Go version doesn't decode ( see
+ // mapKeySupported ): an object is a type error.
+ keyUnsupported bool
+ structName string
+ fieldName string
+ // temps holds the zero values which the key and the value of an entry are decoded into ( see mapTemps ).
+ temps sync.Pool
+ // lastLen is the number of the entries of the object which the decoder decoded last, up to maxMapSizeHint,
+ // which a new map is made for: the objects of a kind often have a number of entries. It is only a hint, for
+ // any goroutine.
+ lastLen atomic.Int32
}
-func newMapDecoder(mapType *runtime.Type, keyType *runtime.Type, keyDec Decoder, valueType *runtime.Type, valueDec Decoder, structName, fieldName string) *mapDecoder {
- return &mapDecoder{
- mapType: mapType,
- keyDecoder: keyDec,
- keyType: keyType,
- canUseAssignFaststrType: canUseAssignFaststrType(keyType, valueType),
- valueType: valueType,
- valueDecoder: valueDec,
- structName: structName,
- fieldName: fieldName,
- }
-}
-
-const (
- mapMaxElemSize = 128
-)
+// maxMapSizeHint is the largest number of the entries which a new map is made for ( see lastLen ).
+const maxMapSizeHint = 64
-// See detail: https://github.com/goccy/go-json/pull/283
-func canUseAssignFaststrType(key *runtime.Type, value *runtime.Type) bool {
- indirectElem := value.Size() > mapMaxElemSize
- if indirectElem {
- return false
- }
- return key.Kind() == reflect.String
+// mapTemps are the zero values of the key and of the value of a map, into which the key and the value of every
+// entry are decoded, which reflect.Value.SetMapIndex copies into the map, and which are zeroed after it: a
+// decoder keeps them in a pool, so that a map is decoded without allocating them.
+type mapTemps struct {
+ k, v unsafe.Pointer
+ kv, vv reflect.Value
}
-//go:linkname makemap reflect.makemap
-func makemap(*runtime.Type, int) unsafe.Pointer
-
-//nolint:golint
-//go:linkname mapassign_faststr runtime.mapassign_faststr
-//go:noescape
-func mapassign_faststr(t *runtime.Type, m unsafe.Pointer, s string) unsafe.Pointer
-
-//go:linkname mapassign reflect.mapassign
-//go:noescape
-func mapassign(t *runtime.Type, m unsafe.Pointer, k, v unsafe.Pointer)
-
-func (d *mapDecoder) mapassign(t *runtime.Type, m, k, v unsafe.Pointer) {
- if d.canUseAssignFaststrType {
- mapV := mapassign_faststr(t, m, *(*string)(k))
- typedmemmove(d.valueType, mapV, v)
- } else {
- mapassign(t, m, k, v)
+func newMapDecoder(mapType reflect.Type, keyType reflect.Type, keyDec Decoder, valueType reflect.Type, valueDec Decoder, structName, fieldName string) *mapDecoder {
+ _, isIfaceValue := valueDec.(*interfaceDecoder)
+ d := &mapDecoder{
+ mapType: mapType,
+ keyDecoder: keyDec,
+ keyType: keyType,
+ valueType: valueType,
+ mapTypePtr: runtime.TypePtr(mapType),
+ keyPtrType: ptrTypeOf(keyType),
+ valuePtrType: ptrTypeOf(valueType),
+ isStringAnyMap: mapType == interfaceMapType && isIfaceValue,
+ valueDecoder: valueDec,
+ keyUnsupported: !mapKeySupported(keyType, keyDec),
+ structName: structName,
+ fieldName: fieldName,
+ }
+ d.temps.New = func() any {
+ t := &mapTemps{k: newValue(keyType), v: newValue(valueType)}
+ t.kv, t.vv = valueAt(d.keyPtrType, t.k), valueAt(d.valuePtrType, t.v)
+ return t
}
+ return d
}
-func (d *mapDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
- }
+// mapValue returns the reflect.Value of the map m.
+func (d *mapDecoder) mapValue(m unsafe.Pointer) reflect.Value {
+ // A map is a pointer in an interface value.
+ return reflect.ValueOf(*(*any)(unsafe.Pointer(&emptyInterface{typ: d.mapTypePtr, ptr: m})))
+}
- switch s.skipWhiteSpace() {
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- **(**unsafe.Pointer)(unsafe.Pointer(&p)) = nil
- return nil
- case '{':
- default:
- return errors.ErrExpected("{ character for map value", s.totalOffset())
- }
- mapValue := *(*unsafe.Pointer)(p)
- if mapValue == nil {
- mapValue = makemap(d.mapType, 0)
- }
- s.cursor++
- if s.skipWhiteSpace() == '}' {
- *(*unsafe.Pointer)(p) = mapValue
- s.cursor++
- return nil
- }
+// decodeEntries decodes the entries of the object from cursor into the map, whose keys and values are decoded into
+// k and v, as Decode does, but the entries whose keys are of another type ( see errMapKeyType ), which are dropped.
+// If afterKey is set, cursor is after the key of such an entry, whose value is decoded first. It is a function of
+// its own, so that Decode keeps the size it had: such a key is rare.
+//
+//go:noinline
+func (d *mapDecoder) decodeEntries(ctx *RuntimeContext, cursor, depth int64, p, mapValue, k, v unsafe.Pointer, afterKey bool) (int64, error) {
+ buf := ctx.Buf
+ mv := d.mapValue(mapValue)
+ kv := valueAt(d.keyPtrType, k)
+ vv := valueAt(d.valuePtrType, v)
for {
- k := unsafe_New(d.keyType)
- if err := d.keyDecoder.DecodeStream(s, depth, k); err != nil {
- return err
+ drop := afterKey
+ if !afterKey {
+ keyCursor, err := d.keyDecoder.Decode(ctx, cursor, depth, k)
+ if err != nil && err != errMapKeyType {
+ return 0, err
+ }
+ drop = err != nil
+ cursor = keyCursor
+ }
+ afterKey = false
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] != ':' {
+ return 0, errors.ErrExpected("colon after object key", cursor)
}
- s.skipWhiteSpace()
- if !s.equalChar(':') {
- return errors.ErrExpected("colon after object key", s.totalOffset())
+ valueCursor, err := d.valueDecoder.Decode(ctx, cursor+1, depth, v)
+ if err != nil {
+ return 0, err
}
- s.cursor++
- v := unsafe_New(d.valueType)
- if err := d.valueDecoder.DecodeStream(s, depth, v); err != nil {
- return err
+ if !drop {
+ mv.SetMapIndex(kv, vv)
}
- d.mapassign(d.mapType, mapValue, k, v)
- s.skipWhiteSpace()
- if s.equalChar('}') {
+ kv.SetZero()
+ vv.SetZero()
+ cursor = skipWhiteSpace(buf, valueCursor)
+ if buf[cursor] == '}' {
**(**unsafe.Pointer)(unsafe.Pointer(&p)) = mapValue
- s.cursor++
- return nil
+ return cursor + 1, nil
}
- if !s.equalChar(',') {
- return errors.ErrExpected("comma after object value", s.totalOffset())
+ if buf[cursor] != ',' {
+ return 0, errors.ErrExpected("comma after object value", cursor)
}
- s.cursor++
+ cursor++
}
}
+// decodeOther skips the value at cursor, which is not an object: a value of another kind is a type error, and
+// anything else a syntax error. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *mapDecoder) decodeOther(ctx *RuntimeContext, cursor, depth int64) (int64, error) {
+ if isOtherValue(ctx.Buf[cursor], objectValue) {
+ return ctx.skipTypeError(cursor, depth, d.mapType)
+ }
+ return 0, errors.ErrExpected("{ character for map value", cursor)
+}
+
func (d *mapDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
depth++
@@ -143,23 +156,52 @@ func (d *mapDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.P
return cursor, nil
case '{':
default:
- return 0, errors.ErrExpected("{ character for map value", cursor)
+ return d.decodeOther(ctx, cursor, depth-1)
+ }
+ if d.keyUnsupported {
+ return ctx.unsupportedMapKeys(d, cursor, depth-1, p)
+ }
+ if d.isStringAnyMap {
+ m := *(*map[string]any)(p)
+ if m == nil {
+ m, c, err := decodeNewStringAnyMap(ctx, d.valueDecoder.(*interfaceDecoder), cursor, depth)
+ if err != nil {
+ return 0, err
+ }
+ *(*map[string]any)(p) = m
+ return c, nil
+ }
+ c, err := decodeStringAnyMap(ctx, d.valueDecoder.(*interfaceDecoder), m, cursor, depth)
+ if err != nil {
+ return 0, err
+ }
+ return c, nil
}
cursor++
cursor = skipWhiteSpace(buf, cursor)
mapValue := *(*unsafe.Pointer)(p)
if mapValue == nil {
- mapValue = makemap(d.mapType, 0)
+ // made for the number of the entries of the last object, which an object of the kind is likely to have
+ mapValue = reflect.MakeMapWithSize(d.mapType, int(d.lastLen.Load())).UnsafePointer()
}
if buf[cursor] == '}' {
**(**unsafe.Pointer)(unsafe.Pointer(&p)) = mapValue
cursor++
return cursor, nil
}
+ // The key and the value of every entry are decoded into the same zero values ( see mapTemps ), which go back
+ // to the pool when the object ends: after an error, they may have values, and are left to the collector.
+ t := d.temps.Get().(*mapTemps)
+ k, v, kv, vv := t.k, t.v, t.kv, t.vv
+ mv := d.mapValue(mapValue)
+ n := int32(0)
for {
- k := unsafe_New(d.keyType)
keyCursor, err := d.keyDecoder.Decode(ctx, cursor, depth, k)
if err != nil {
+ if err == errMapKeyType {
+ // a key of another type: the rest of the object is decoded by decodeEntries
+ return d.decodeEntries(ctx, keyCursor, depth, p, mapValue, k, v, true)
+ }
return 0, err
}
cursor = skipWhiteSpace(buf, keyCursor)
@@ -167,15 +209,19 @@ func (d *mapDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.P
return 0, errors.ErrExpected("colon after object key", cursor)
}
cursor++
- v := unsafe_New(d.valueType)
valueCursor, err := d.valueDecoder.Decode(ctx, cursor, depth, v)
if err != nil {
return 0, err
}
- d.mapassign(d.mapType, mapValue, k, v)
+ mv.SetMapIndex(kv, vv)
+ kv.SetZero()
+ vv.SetZero()
+ n++
cursor = skipWhiteSpace(buf, valueCursor)
if buf[cursor] == '}' {
**(**unsafe.Pointer)(unsafe.Pointer(&p)) = mapValue
+ d.temps.Put(t)
+ d.lastLen.Store(min(n, maxMapSizeHint))
cursor++
return cursor, nil
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/number.go b/vendor/github.com/goccy/go-json/internal/decoder/number.go
index 10e5435e6..d15b3eb2d 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/number.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/number.go
@@ -2,7 +2,6 @@ package decoder
import (
"encoding/json"
- "strconv"
"unsafe"
"github.com/goccy/go-json/internal/errors"
@@ -24,31 +23,74 @@ func newNumberDecoder(structName, fieldName string, op func(unsafe.Pointer, json
}
}
-func (d *numberDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamByte(s)
+func (d *numberDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ start := cursor
+ switch c := buf[cursor]; {
+ case c == '-' || c-'0' <= 9:
+ end, err := numberEnd(buf, cursor)
+ if err != nil {
+ return 0, err
+ }
+ d.op(p, json.Number(ctx.makeString(buf[cursor:end])))
+ return end, nil
+ case c == '"', c == 'n':
+ case isOtherValue(c, numberValue):
+ return ctx.numberKindError(cursor, depth, jsonNumberType)
+ }
+ bytes, c, err := d.decodeByte(buf, cursor)
if err != nil {
- return err
+ return 0, err
}
- if _, err := strconv.ParseFloat(*(*string)(unsafe.Pointer(&bytes)), 64); err != nil {
- return errors.ErrSyntax(err.Error(), s.totalOffset())
+ if bytes == nil {
+ // null, which is ignored
+ return c, nil
}
- d.op(p, json.Number(string(bytes)))
- s.reset()
- return nil
+ if !isValidNumber(bytes) {
+ return ctx.numberStringError(start, c, jsonNumberType)
+ }
+ // a number in a string: its bytes end before the quote
+ d.op(p, json.Number(ctx.makeString(bytes)))
+ return c, nil
}
-func (d *numberDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- bytes, c, err := d.decodeByte(ctx.Buf, cursor)
- if err != nil {
- return 0, err
+// isValidNumber reports whether b is a number by the grammar of the JSON numbers.
+func isValidNumber(b []byte) bool {
+ i := 0
+ if i < len(b) && b[i] == '-' {
+ i++
+ }
+ digits := func() int {
+ n := 0
+ for i < len(b) && b[i]-'0' <= 9 {
+ i++
+ n++
+ }
+ return n
}
- if _, err := strconv.ParseFloat(*(*string)(unsafe.Pointer(&bytes)), 64); err != nil {
- return 0, errors.ErrSyntax(err.Error(), c)
+ switch {
+ case i < len(b) && b[i] == '0':
+ i++
+ case digits() == 0:
+ return false
+ }
+ if i < len(b) && b[i] == '.' {
+ i++
+ if digits() == 0 {
+ return false
+ }
}
- cursor = c
- s := *(*string)(unsafe.Pointer(&bytes))
- d.op(p, json.Number(s))
- return cursor, nil
+ if i < len(b) && (b[i] == 'e' || b[i] == 'E') {
+ i++
+ if i < len(b) && (b[i] == '+' || b[i] == '-') {
+ i++
+ }
+ if digits() == 0 {
+ return false
+ }
+ }
+ return i == len(b)
}
func (d *numberDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
@@ -62,38 +104,6 @@ func (d *numberDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([]
return [][]byte{bytes}, c, nil
}
-func (d *numberDecoder) decodeStreamByte(s *Stream) ([]byte, error) {
- start := s.cursor
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return floatBytes(s), nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case '"':
- return d.stringDecoder.decodeStreamByte(s)
- case nul:
- if s.read() {
- continue
- }
- goto ERROR
- default:
- goto ERROR
- }
- }
-ERROR:
- if s.cursor == start {
- return nil, errors.ErrInvalidBeginningOfValue(s.char(), s.totalOffset())
- }
- return nil, errors.ErrUnexpectedEndOfJSON("json.Number", s.totalOffset())
-}
-
func (d *numberDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
for {
switch buf[cursor] {
@@ -116,8 +126,10 @@ func (d *numberDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, err
return nil, cursor, nil
case '"':
return d.stringDecoder.decodeByte(buf, cursor)
- default:
+ case nul:
return nil, 0, errors.ErrUnexpectedEndOfJSON("json.Number", cursor)
+ default:
+ return nil, 0, errors.ErrInvalidBeginningOfValue(buf[cursor], cursor+1)
}
}
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/number_parse.go b/vendor/github.com/goccy/go-json/internal/decoder/number_parse.go
new file mode 100644
index 000000000..0921e1d14
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/number_parse.go
@@ -0,0 +1,181 @@
+package decoder
+
+import (
+ "fmt"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// The numbers of the input are parsed in one pass: the digits are accumulated as they are read.
+
+// maxUint64Digits is the number of the digits which a uint64 holds whatever they are: 19 nines are less than 1<<64.
+const maxUint64Digits = 19
+
+// parseDigits reads the digits at cursor, which starts a number after its sign, and returns their value, the
+// position after them and their number. A number which starts with 0 has no other digit: the digit after it,
+// if any, is not read. The value is exact for up to maxUint64Digits digits.
+func parseDigits(buf []byte, cursor int64) (uint64, int64, int) {
+ if buf[cursor] == '0' {
+ return 0, cursor + 1, 1
+ }
+ start := cursor
+ var u uint64
+ for {
+ d := buf[cursor] - '0'
+ if d > 9 {
+ break
+ }
+ u = u*10 + uint64(d)
+ cursor++
+ }
+ return u, cursor, int(cursor - start)
+}
+
+// isFloatContinuation reports whether c continues an integer as a number which is not an integer.
+func isFloatContinuation(c byte) bool {
+ return c == '.' || c == 'e' || c == 'E'
+}
+
+// float64pow10 are the powers of ten which a float64 holds exactly.
+var float64pow10 = [...]float64{
+ 1e0, 1e1, 1e2, 1e3, 1e4, 1e5, 1e6, 1e7, 1e8, 1e9, 1e10, 1e11,
+ 1e12, 1e13, 1e14, 1e15, 1e16, 1e17, 1e18, 1e19, 1e20, 1e21, 1e22,
+}
+
+// parseFloatFast parses the number at cursor, as the JSON grammar has it, when its mantissa has at most 19
+// digits: the float64 of a mantissa of at most 53 bits times or divided by a power of ten which a float64 holds
+// exactly is correctly rounded as it is ( Clinger's fast path ), and any other is multiplied by the power of ten
+// from a table ( mulPow10 ). The result is the one of strconv.ParseFloat. It returns false for a number which
+// is not decided so, or anything which is not a number by the grammar, which the caller parses as it did before.
+func parseFloatFast(buf []byte, cursor int64) (float64, int64, bool) {
+ neg := buf[cursor] == '-'
+ if neg {
+ cursor++
+ }
+ if buf[cursor]-'0' > 9 {
+ return 0, 0, false
+ }
+ mantissa, cursor, digits := parseDigits(buf, cursor)
+ exp := 0
+ if buf[cursor] == '.' {
+ cursor++
+ start := cursor
+ if mantissa == 0 {
+ // the zeros before the first digit which is not zero are not digits of the mantissa
+ digits = 0
+ }
+ for {
+ d := buf[cursor] - '0'
+ if d > 9 {
+ break
+ }
+ mantissa = mantissa*10 + uint64(d)
+ if mantissa != 0 {
+ digits++
+ }
+ cursor++
+ }
+ fraction := int(cursor - start)
+ if fraction == 0 {
+ return 0, 0, false
+ }
+ exp = -fraction
+ }
+ if c := buf[cursor]; c == 'e' || c == 'E' {
+ cursor++
+ expNeg := false
+ switch buf[cursor] {
+ case '-':
+ expNeg = true
+ cursor++
+ case '+':
+ cursor++
+ }
+ start := cursor
+ e := 0
+ for {
+ d := buf[cursor] - '0'
+ if d > 9 {
+ break
+ }
+ if e < 10000 {
+ e = e*10 + int(d)
+ }
+ cursor++
+ }
+ if cursor == start {
+ return 0, 0, false
+ }
+ if expNeg {
+ e = -e
+ }
+ exp += e
+ }
+ if digits > maxUint64Digits {
+ return 0, 0, false
+ }
+ var f float64
+ if mantissa <= 1<<53 && exp >= -22 && exp <= 22 {
+ f = float64(mantissa)
+ if exp < 0 {
+ f /= float64pow10[-exp]
+ } else {
+ f *= float64pow10[exp]
+ }
+ } else {
+ var ok bool
+ if f, ok = mulPow10(mantissa, exp); !ok {
+ return 0, 0, false
+ }
+ }
+ if neg {
+ f = -f
+ }
+ return f, cursor, true
+}
+
+// numberEnd returns the position after the number which starts at start, validated by the grammar of the JSON
+// numbers, which is followed by a byte which may end a value.
+func numberEnd(buf []byte, start int64) (int64, error) {
+ c := start
+ if buf[c] == '-' {
+ c++
+ }
+ switch {
+ case buf[c] == '0':
+ c++
+ case '1' <= buf[c] && buf[c] <= '9':
+ c = skipDigits(buf, c+1)
+ default:
+ return 0, errors.ErrSyntax(fmt.Sprintf("invalid character %s in numeric literal", quoteChar(buf[c])), c+1)
+ }
+ if buf[c] == '.' {
+ c++
+ if buf[c]-'0' > 9 {
+ return 0, errors.ErrSyntax(fmt.Sprintf("invalid character %s after decimal point in numeric literal", quoteChar(buf[c])), c+1)
+ }
+ c = skipDigits(buf, c)
+ }
+ if buf[c] == 'e' || buf[c] == 'E' {
+ c++
+ if buf[c] == '+' || buf[c] == '-' {
+ c++
+ }
+ if buf[c]-'0' > 9 {
+ return 0, errors.ErrSyntax(fmt.Sprintf("invalid character %s in exponent of numeric literal", quoteChar(buf[c])), c+1)
+ }
+ c = skipDigits(buf, c)
+ }
+ if !validEndNumberChar[buf[c]] {
+ return 0, errors.ErrSyntax(fmt.Sprintf("invalid character %s after top-level value", quoteChar(buf[c])), c+1)
+ }
+ return c, nil
+}
+
+// skipDigits returns the position of the first byte from c which is not a digit.
+func skipDigits(buf []byte, c int64) int64 {
+ for buf[c]-'0' <= 9 {
+ c++
+ }
+ return c
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/option.go b/vendor/github.com/goccy/go-json/internal/decoder/option.go
index 502f772eb..9ac6cd6f6 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/option.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/option.go
@@ -8,6 +8,12 @@ const (
FirstWinOption OptionFlags = 1 << iota
ContextOption
PathOption
+ // UseNumberOption decodes a number into interface{} as json.Number instead of float64.
+ UseNumberOption
+ // DisallowUnknownFieldsOption makes an object key which matches no field of the struct an error.
+ DisallowUnknownFieldsOption
+ // NoCopyStringOption makes the decoded strings refer to the input instead of a copy of their bytes.
+ NoCopyStringOption
)
type Option struct {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/path.go b/vendor/github.com/goccy/go-json/internal/decoder/path.go
index a15ff69e3..35f85f63f 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/path.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/path.go
@@ -512,9 +512,9 @@ func (n *PathIndexAllNode) Field(fieldName string) (PathNode, bool, error) {
func (n *PathIndexAllNode) Get(src, dst reflect.Value) error {
switch src.Type().Kind() {
case reflect.Array, reflect.Slice:
- var arr []interface{}
+ var arr []any
for i := 0; i < src.Len(); i++ {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
if n.child != nil {
if err := n.child.Get(src.Index(i), rv); err != nil {
@@ -573,23 +573,23 @@ func (n *PathRecursiveNode) Index(_ int) (PathNode, bool, error) {
return n, true, nil
}
-func valueToSliceValue(v interface{}) []interface{} {
+func valueToSliceValue(v any) []any {
rv := reflect.ValueOf(v)
- ret := []interface{}{}
+ ret := []any{}
if rv.Type().Kind() == reflect.Slice || rv.Type().Kind() == reflect.Array {
for i := 0; i < rv.Len(); i++ {
ret = append(ret, rv.Index(i).Interface())
}
return ret
}
- return []interface{}{v}
+ return []any{v}
}
func (n *PathRecursiveNode) Get(src, dst reflect.Value) error {
if n.child == nil {
return fmt.Errorf("failed to get by recursive path ..%s", n.selector)
}
- var arr []interface{}
+ var arr []any
switch src.Type().Kind() {
case reflect.Map:
iter := src.MapRange()
@@ -603,12 +603,12 @@ func (n *PathRecursiveNode) Get(src, dst reflect.Value) error {
return err
}
if found {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
_ = child.Get(iter.Value(), rv)
arr = append(arr, valueToSliceValue(v)...)
} else {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
_ = n.Get(iter.Value(), rv)
if v != nil {
@@ -627,12 +627,12 @@ func (n *PathRecursiveNode) Get(src, dst reflect.Value) error {
return err
}
if found {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
_ = child.Get(src.Field(i), rv)
arr = append(arr, valueToSliceValue(v)...)
} else {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
_ = n.Get(src.Field(i), rv)
if v != nil {
@@ -644,7 +644,7 @@ func (n *PathRecursiveNode) Get(src, dst reflect.Value) error {
return nil
case reflect.Array, reflect.Slice:
for i := 0; i < src.Len(); i++ {
- var v interface{}
+ var v any
rv := reflect.ValueOf(&v)
_ = n.Get(src.Index(i), rv)
if v != nil {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/pow10.go b/vendor/github.com/goccy/go-json/internal/decoder/pow10.go
new file mode 100644
index 000000000..80a1142b0
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/pow10.go
@@ -0,0 +1,83 @@
+package decoder
+
+import (
+ "math"
+ "math/bits"
+)
+
+//go:generate go run ../cmd/pow10table pow10_table.go
+
+// pow10Entry is 10^q as a truncated 128-bit significand: ( hi*2^64 + lo ) * 2^exp2 <= 10^q, less than the
+// next significand times 2^exp2.
+type pow10Entry struct {
+ hi, lo uint64
+ exp2 int
+}
+
+// mulPow10 returns the float64 nearest to w * 10^q, rounded to even, and true; or false when that is not decided
+// by the table, which the caller then leaves to strconv.
+//
+// The significand T of 10^q is truncated, so the exact product w * 10^q is in [w*T, w*T + w) times 2^exp2. Both
+// ends are rounded to 53 bits: when they give the same float64, it is the one of every value between them, so it
+// is the float64 of w * 10^q. Only a product very near a half-way point between two float64 values gives two,
+// which is rare.
+func mulPow10(w uint64, q int) (float64, bool) {
+ if w == 0 {
+ return 0, true
+ }
+ if q < minPow10Exp10 || q > maxPow10Exp10 {
+ return 0, false
+ }
+ p := &pow10Table[q-minPow10Exp10]
+ // the lower end: w * T, a number of 192 bits in p2, p1, p0.
+ hi1, lo1 := bits.Mul64(w, p.lo)
+ hi2, lo2 := bits.Mul64(w, p.hi)
+ p0 := lo1
+ p1, carry := bits.Add64(lo2, hi1, 0)
+ p2 := hi2 + carry
+ // the upper end: w * T + w.
+ u0, c0 := bits.Add64(p0, w, 0)
+ u1, c1 := bits.Add64(p1, 0, c0)
+ u2 := p2 + c1
+ m, e, ok := round192(p2, p1, p0)
+ if !ok {
+ return 0, false
+ }
+ mu, eu, ok := round192(u2, u1, u0)
+ if !ok || mu != m || eu != e {
+ return 0, false
+ }
+ // the value is m * 2^( e + exp2 ), and m has 53 bits.
+ exp := e + p.exp2
+ // a normal float64 is m * 2^exp with 53-bit m and exp from -1074 to 971.
+ if exp < -1074 || exp > 971 {
+ return 0, false
+ }
+ return math.Ldexp(float64(m), exp), true
+}
+
+// round192 rounds the 192-bit number x2*2^128 + x1*2^64 + x0, whose top word is not zero, to 53 bits, to even:
+// it returns m and e such that the rounded number is m * 2^e with 2^52 <= m < 2^53.
+func round192(x2, x1, x0 uint64) (uint64, int, bool) {
+ if x2 == 0 {
+ return 0, 0, false
+ }
+ lz := bits.LeadingZeros64(x2)
+ // the top 64 bits of the number, and whether a bit below them is set.
+ top := x2<>uint(64-lz)
+ if lz == 0 {
+ top = x2
+ }
+ rest := x1<> 11
+ half := top>>10&1 != 0
+ if half && (sticky || m&1 != 0) {
+ m++
+ if m == 1<<53 {
+ m >>= 1
+ return m, 11 + 128 - lz + 1, true
+ }
+ }
+ return m, 11 + 128 - lz, true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/pow10_table.go b/vendor/github.com/goccy/go-json/internal/decoder/pow10_table.go
new file mode 100644
index 000000000..c5fb58f70
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/pow10_table.go
@@ -0,0 +1,708 @@
+// Code generated by internal/cmd/pow10table. DO NOT EDIT.
+
+package decoder
+
+const (
+ minPow10Exp10 = -348
+ maxPow10Exp10 = 347
+)
+
+// pow10Table has 10^q as hi*2^64 + lo times 2^exp2, truncated, for q from minPow10Exp10.
+var pow10Table = [...]pow10Entry{
+ {hi: 0xfa8fd5a0081c0288, lo: 0x1732c869cd60e453, exp2: -1284}, // 1e-348
+ {hi: 0x9c99e58405118195, lo: 0x0e7fbd42205c8eb4, exp2: -1280}, // 1e-347
+ {hi: 0xc3c05ee50655e1fa, lo: 0x521fac92a873b261, exp2: -1277}, // 1e-346
+ {hi: 0xf4b0769e47eb5a78, lo: 0xe6a797b752909ef9, exp2: -1274}, // 1e-345
+ {hi: 0x98ee4a22ecf3188b, lo: 0x9028bed2939a635c, exp2: -1270}, // 1e-344
+ {hi: 0xbf29dcaba82fdeae, lo: 0x7432ee873880fc33, exp2: -1267}, // 1e-343
+ {hi: 0xeef453d6923bd65a, lo: 0x113faa2906a13b3f, exp2: -1264}, // 1e-342
+ {hi: 0x9558b4661b6565f8, lo: 0x4ac7ca59a424c507, exp2: -1260}, // 1e-341
+ {hi: 0xbaaee17fa23ebf76, lo: 0x5d79bcf00d2df649, exp2: -1257}, // 1e-340
+ {hi: 0xe95a99df8ace6f53, lo: 0xf4d82c2c107973dc, exp2: -1254}, // 1e-339
+ {hi: 0x91d8a02bb6c10594, lo: 0x79071b9b8a4be869, exp2: -1250}, // 1e-338
+ {hi: 0xb64ec836a47146f9, lo: 0x9748e2826cdee284, exp2: -1247}, // 1e-337
+ {hi: 0xe3e27a444d8d98b7, lo: 0xfd1b1b2308169b25, exp2: -1244}, // 1e-336
+ {hi: 0x8e6d8c6ab0787f72, lo: 0xfe30f0f5e50e20f7, exp2: -1240}, // 1e-335
+ {hi: 0xb208ef855c969f4f, lo: 0xbdbd2d335e51a935, exp2: -1237}, // 1e-334
+ {hi: 0xde8b2b66b3bc4723, lo: 0xad2c788035e61382, exp2: -1234}, // 1e-333
+ {hi: 0x8b16fb203055ac76, lo: 0x4c3bcb5021afcc31, exp2: -1230}, // 1e-332
+ {hi: 0xaddcb9e83c6b1793, lo: 0xdf4abe242a1bbf3d, exp2: -1227}, // 1e-331
+ {hi: 0xd953e8624b85dd78, lo: 0xd71d6dad34a2af0d, exp2: -1224}, // 1e-330
+ {hi: 0x87d4713d6f33aa6b, lo: 0x8672648c40e5ad68, exp2: -1220}, // 1e-329
+ {hi: 0xa9c98d8ccb009506, lo: 0x680efdaf511f18c2, exp2: -1217}, // 1e-328
+ {hi: 0xd43bf0effdc0ba48, lo: 0x0212bd1b2566def2, exp2: -1214}, // 1e-327
+ {hi: 0x84a57695fe98746d, lo: 0x014bb630f7604b57, exp2: -1210}, // 1e-326
+ {hi: 0xa5ced43b7e3e9188, lo: 0x419ea3bd35385e2d, exp2: -1207}, // 1e-325
+ {hi: 0xcf42894a5dce35ea, lo: 0x52064cac828675b9, exp2: -1204}, // 1e-324
+ {hi: 0x818995ce7aa0e1b2, lo: 0x7343efebd1940993, exp2: -1200}, // 1e-323
+ {hi: 0xa1ebfb4219491a1f, lo: 0x1014ebe6c5f90bf8, exp2: -1197}, // 1e-322
+ {hi: 0xca66fa129f9b60a6, lo: 0xd41a26e077774ef6, exp2: -1194}, // 1e-321
+ {hi: 0xfd00b897478238d0, lo: 0x8920b098955522b4, exp2: -1191}, // 1e-320
+ {hi: 0x9e20735e8cb16382, lo: 0x55b46e5f5d5535b0, exp2: -1187}, // 1e-319
+ {hi: 0xc5a890362fddbc62, lo: 0xeb2189f734aa831d, exp2: -1184}, // 1e-318
+ {hi: 0xf712b443bbd52b7b, lo: 0xa5e9ec7501d523e4, exp2: -1181}, // 1e-317
+ {hi: 0x9a6bb0aa55653b2d, lo: 0x47b233c92125366e, exp2: -1177}, // 1e-316
+ {hi: 0xc1069cd4eabe89f8, lo: 0x999ec0bb696e840a, exp2: -1174}, // 1e-315
+ {hi: 0xf148440a256e2c76, lo: 0xc00670ea43ca250d, exp2: -1171}, // 1e-314
+ {hi: 0x96cd2a865764dbca, lo: 0x380406926a5e5728, exp2: -1167}, // 1e-313
+ {hi: 0xbc807527ed3e12bc, lo: 0xc605083704f5ecf2, exp2: -1164}, // 1e-312
+ {hi: 0xeba09271e88d976b, lo: 0xf7864a44c633682e, exp2: -1161}, // 1e-311
+ {hi: 0x93445b8731587ea3, lo: 0x7ab3ee6afbe0211d, exp2: -1157}, // 1e-310
+ {hi: 0xb8157268fdae9e4c, lo: 0x5960ea05bad82964, exp2: -1154}, // 1e-309
+ {hi: 0xe61acf033d1a45df, lo: 0x6fb92487298e33bd, exp2: -1151}, // 1e-308
+ {hi: 0x8fd0c16206306bab, lo: 0xa5d3b6d479f8e056, exp2: -1147}, // 1e-307
+ {hi: 0xb3c4f1ba87bc8696, lo: 0x8f48a4899877186c, exp2: -1144}, // 1e-306
+ {hi: 0xe0b62e2929aba83c, lo: 0x331acdabfe94de87, exp2: -1141}, // 1e-305
+ {hi: 0x8c71dcd9ba0b4925, lo: 0x9ff0c08b7f1d0b14, exp2: -1137}, // 1e-304
+ {hi: 0xaf8e5410288e1b6f, lo: 0x07ecf0ae5ee44dd9, exp2: -1134}, // 1e-303
+ {hi: 0xdb71e91432b1a24a, lo: 0xc9e82cd9f69d6150, exp2: -1131}, // 1e-302
+ {hi: 0x892731ac9faf056e, lo: 0xbe311c083a225cd2, exp2: -1127}, // 1e-301
+ {hi: 0xab70fe17c79ac6ca, lo: 0x6dbd630a48aaf406, exp2: -1124}, // 1e-300
+ {hi: 0xd64d3d9db981787d, lo: 0x092cbbccdad5b108, exp2: -1121}, // 1e-299
+ {hi: 0x85f0468293f0eb4e, lo: 0x25bbf56008c58ea5, exp2: -1117}, // 1e-298
+ {hi: 0xa76c582338ed2621, lo: 0xaf2af2b80af6f24e, exp2: -1114}, // 1e-297
+ {hi: 0xd1476e2c07286faa, lo: 0x1af5af660db4aee1, exp2: -1111}, // 1e-296
+ {hi: 0x82cca4db847945ca, lo: 0x50d98d9fc890ed4d, exp2: -1107}, // 1e-295
+ {hi: 0xa37fce126597973c, lo: 0xe50ff107bab528a0, exp2: -1104}, // 1e-294
+ {hi: 0xcc5fc196fefd7d0c, lo: 0x1e53ed49a96272c8, exp2: -1101}, // 1e-293
+ {hi: 0xff77b1fcbebcdc4f, lo: 0x25e8e89c13bb0f7a, exp2: -1098}, // 1e-292
+ {hi: 0x9faacf3df73609b1, lo: 0x77b191618c54e9ac, exp2: -1094}, // 1e-291
+ {hi: 0xc795830d75038c1d, lo: 0xd59df5b9ef6a2417, exp2: -1091}, // 1e-290
+ {hi: 0xf97ae3d0d2446f25, lo: 0x4b0573286b44ad1d, exp2: -1088}, // 1e-289
+ {hi: 0x9becce62836ac577, lo: 0x4ee367f9430aec32, exp2: -1084}, // 1e-288
+ {hi: 0xc2e801fb244576d5, lo: 0x229c41f793cda73f, exp2: -1081}, // 1e-287
+ {hi: 0xf3a20279ed56d48a, lo: 0x6b43527578c1110f, exp2: -1078}, // 1e-286
+ {hi: 0x9845418c345644d6, lo: 0x830a13896b78aaa9, exp2: -1074}, // 1e-285
+ {hi: 0xbe5691ef416bd60c, lo: 0x23cc986bc656d553, exp2: -1071}, // 1e-284
+ {hi: 0xedec366b11c6cb8f, lo: 0x2cbfbe86b7ec8aa8, exp2: -1068}, // 1e-283
+ {hi: 0x94b3a202eb1c3f39, lo: 0x7bf7d71432f3d6a9, exp2: -1064}, // 1e-282
+ {hi: 0xb9e08a83a5e34f07, lo: 0xdaf5ccd93fb0cc53, exp2: -1061}, // 1e-281
+ {hi: 0xe858ad248f5c22c9, lo: 0xd1b3400f8f9cff68, exp2: -1058}, // 1e-280
+ {hi: 0x91376c36d99995be, lo: 0x23100809b9c21fa1, exp2: -1054}, // 1e-279
+ {hi: 0xb58547448ffffb2d, lo: 0xabd40a0c2832a78a, exp2: -1051}, // 1e-278
+ {hi: 0xe2e69915b3fff9f9, lo: 0x16c90c8f323f516c, exp2: -1048}, // 1e-277
+ {hi: 0x8dd01fad907ffc3b, lo: 0xae3da7d97f6792e3, exp2: -1044}, // 1e-276
+ {hi: 0xb1442798f49ffb4a, lo: 0x99cd11cfdf41779c, exp2: -1041}, // 1e-275
+ {hi: 0xdd95317f31c7fa1d, lo: 0x40405643d711d583, exp2: -1038}, // 1e-274
+ {hi: 0x8a7d3eef7f1cfc52, lo: 0x482835ea666b2572, exp2: -1034}, // 1e-273
+ {hi: 0xad1c8eab5ee43b66, lo: 0xda3243650005eecf, exp2: -1031}, // 1e-272
+ {hi: 0xd863b256369d4a40, lo: 0x90bed43e40076a82, exp2: -1028}, // 1e-271
+ {hi: 0x873e4f75e2224e68, lo: 0x5a7744a6e804a291, exp2: -1024}, // 1e-270
+ {hi: 0xa90de3535aaae202, lo: 0x711515d0a205cb36, exp2: -1021}, // 1e-269
+ {hi: 0xd3515c2831559a83, lo: 0x0d5a5b44ca873e03, exp2: -1018}, // 1e-268
+ {hi: 0x8412d9991ed58091, lo: 0xe858790afe9486c2, exp2: -1014}, // 1e-267
+ {hi: 0xa5178fff668ae0b6, lo: 0x626e974dbe39a872, exp2: -1011}, // 1e-266
+ {hi: 0xce5d73ff402d98e3, lo: 0xfb0a3d212dc8128f, exp2: -1008}, // 1e-265
+ {hi: 0x80fa687f881c7f8e, lo: 0x7ce66634bc9d0b99, exp2: -1004}, // 1e-264
+ {hi: 0xa139029f6a239f72, lo: 0x1c1fffc1ebc44e80, exp2: -1001}, // 1e-263
+ {hi: 0xc987434744ac874e, lo: 0xa327ffb266b56220, exp2: -998}, // 1e-262
+ {hi: 0xfbe9141915d7a922, lo: 0x4bf1ff9f0062baa8, exp2: -995}, // 1e-261
+ {hi: 0x9d71ac8fada6c9b5, lo: 0x6f773fc3603db4a9, exp2: -991}, // 1e-260
+ {hi: 0xc4ce17b399107c22, lo: 0xcb550fb4384d21d3, exp2: -988}, // 1e-259
+ {hi: 0xf6019da07f549b2b, lo: 0x7e2a53a146606a48, exp2: -985}, // 1e-258
+ {hi: 0x99c102844f94e0fb, lo: 0x2eda7444cbfc426d, exp2: -981}, // 1e-257
+ {hi: 0xc0314325637a1939, lo: 0xfa911155fefb5308, exp2: -978}, // 1e-256
+ {hi: 0xf03d93eebc589f88, lo: 0x793555ab7eba27ca, exp2: -975}, // 1e-255
+ {hi: 0x96267c7535b763b5, lo: 0x4bc1558b2f3458de, exp2: -971}, // 1e-254
+ {hi: 0xbbb01b9283253ca2, lo: 0x9eb1aaedfb016f16, exp2: -968}, // 1e-253
+ {hi: 0xea9c227723ee8bcb, lo: 0x465e15a979c1cadc, exp2: -965}, // 1e-252
+ {hi: 0x92a1958a7675175f, lo: 0x0bfacd89ec191ec9, exp2: -961}, // 1e-251
+ {hi: 0xb749faed14125d36, lo: 0xcef980ec671f667b, exp2: -958}, // 1e-250
+ {hi: 0xe51c79a85916f484, lo: 0x82b7e12780e7401a, exp2: -955}, // 1e-249
+ {hi: 0x8f31cc0937ae58d2, lo: 0xd1b2ecb8b0908810, exp2: -951}, // 1e-248
+ {hi: 0xb2fe3f0b8599ef07, lo: 0x861fa7e6dcb4aa15, exp2: -948}, // 1e-247
+ {hi: 0xdfbdcece67006ac9, lo: 0x67a791e093e1d49a, exp2: -945}, // 1e-246
+ {hi: 0x8bd6a141006042bd, lo: 0xe0c8bb2c5c6d24e0, exp2: -941}, // 1e-245
+ {hi: 0xaecc49914078536d, lo: 0x58fae9f773886e18, exp2: -938}, // 1e-244
+ {hi: 0xda7f5bf590966848, lo: 0xaf39a475506a899e, exp2: -935}, // 1e-243
+ {hi: 0x888f99797a5e012d, lo: 0x6d8406c952429603, exp2: -931}, // 1e-242
+ {hi: 0xaab37fd7d8f58178, lo: 0xc8e5087ba6d33b83, exp2: -928}, // 1e-241
+ {hi: 0xd5605fcdcf32e1d6, lo: 0xfb1e4a9a90880a64, exp2: -925}, // 1e-240
+ {hi: 0x855c3be0a17fcd26, lo: 0x5cf2eea09a55067f, exp2: -921}, // 1e-239
+ {hi: 0xa6b34ad8c9dfc06f, lo: 0xf42faa48c0ea481e, exp2: -918}, // 1e-238
+ {hi: 0xd0601d8efc57b08b, lo: 0xf13b94daf124da26, exp2: -915}, // 1e-237
+ {hi: 0x823c12795db6ce57, lo: 0x76c53d08d6b70858, exp2: -911}, // 1e-236
+ {hi: 0xa2cb1717b52481ed, lo: 0x54768c4b0c64ca6e, exp2: -908}, // 1e-235
+ {hi: 0xcb7ddcdda26da268, lo: 0xa9942f5dcf7dfd09, exp2: -905}, // 1e-234
+ {hi: 0xfe5d54150b090b02, lo: 0xd3f93b35435d7c4c, exp2: -902}, // 1e-233
+ {hi: 0x9efa548d26e5a6e1, lo: 0xc47bc5014a1a6daf, exp2: -898}, // 1e-232
+ {hi: 0xc6b8e9b0709f109a, lo: 0x359ab6419ca1091b, exp2: -895}, // 1e-231
+ {hi: 0xf867241c8cc6d4c0, lo: 0xc30163d203c94b62, exp2: -892}, // 1e-230
+ {hi: 0x9b407691d7fc44f8, lo: 0x79e0de63425dcf1d, exp2: -888}, // 1e-229
+ {hi: 0xc21094364dfb5636, lo: 0x985915fc12f542e4, exp2: -885}, // 1e-228
+ {hi: 0xf294b943e17a2bc4, lo: 0x3e6f5b7b17b2939d, exp2: -882}, // 1e-227
+ {hi: 0x979cf3ca6cec5b5a, lo: 0xa705992ceecf9c42, exp2: -878}, // 1e-226
+ {hi: 0xbd8430bd08277231, lo: 0x50c6ff782a838353, exp2: -875}, // 1e-225
+ {hi: 0xece53cec4a314ebd, lo: 0xa4f8bf5635246428, exp2: -872}, // 1e-224
+ {hi: 0x940f4613ae5ed136, lo: 0x871b7795e136be99, exp2: -868}, // 1e-223
+ {hi: 0xb913179899f68584, lo: 0x28e2557b59846e3f, exp2: -865}, // 1e-222
+ {hi: 0xe757dd7ec07426e5, lo: 0x331aeada2fe589cf, exp2: -862}, // 1e-221
+ {hi: 0x9096ea6f3848984f, lo: 0x3ff0d2c85def7621, exp2: -858}, // 1e-220
+ {hi: 0xb4bca50b065abe63, lo: 0x0fed077a756b53a9, exp2: -855}, // 1e-219
+ {hi: 0xe1ebce4dc7f16dfb, lo: 0xd3e8495912c62894, exp2: -852}, // 1e-218
+ {hi: 0x8d3360f09cf6e4bd, lo: 0x64712dd7abbbd95c, exp2: -848}, // 1e-217
+ {hi: 0xb080392cc4349dec, lo: 0xbd8d794d96aacfb3, exp2: -845}, // 1e-216
+ {hi: 0xdca04777f541c567, lo: 0xecf0d7a0fc5583a0, exp2: -842}, // 1e-215
+ {hi: 0x89e42caaf9491b60, lo: 0xf41686c49db57244, exp2: -838}, // 1e-214
+ {hi: 0xac5d37d5b79b6239, lo: 0x311c2875c522ced5, exp2: -835}, // 1e-213
+ {hi: 0xd77485cb25823ac7, lo: 0x7d633293366b828b, exp2: -832}, // 1e-212
+ {hi: 0x86a8d39ef77164bc, lo: 0xae5dff9c02033197, exp2: -828}, // 1e-211
+ {hi: 0xa8530886b54dbdeb, lo: 0xd9f57f830283fdfc, exp2: -825}, // 1e-210
+ {hi: 0xd267caa862a12d66, lo: 0xd072df63c324fd7b, exp2: -822}, // 1e-209
+ {hi: 0x8380dea93da4bc60, lo: 0x4247cb9e59f71e6d, exp2: -818}, // 1e-208
+ {hi: 0xa46116538d0deb78, lo: 0x52d9be85f074e608, exp2: -815}, // 1e-207
+ {hi: 0xcd795be870516656, lo: 0x67902e276c921f8b, exp2: -812}, // 1e-206
+ {hi: 0x806bd9714632dff6, lo: 0x00ba1cd8a3db53b6, exp2: -808}, // 1e-205
+ {hi: 0xa086cfcd97bf97f3, lo: 0x80e8a40eccd228a4, exp2: -805}, // 1e-204
+ {hi: 0xc8a883c0fdaf7df0, lo: 0x6122cd128006b2cd, exp2: -802}, // 1e-203
+ {hi: 0xfad2a4b13d1b5d6c, lo: 0x796b805720085f81, exp2: -799}, // 1e-202
+ {hi: 0x9cc3a6eec6311a63, lo: 0xcbe3303674053bb0, exp2: -795}, // 1e-201
+ {hi: 0xc3f490aa77bd60fc, lo: 0xbedbfc4411068a9c, exp2: -792}, // 1e-200
+ {hi: 0xf4f1b4d515acb93b, lo: 0xee92fb5515482d44, exp2: -789}, // 1e-199
+ {hi: 0x991711052d8bf3c5, lo: 0x751bdd152d4d1c4a, exp2: -785}, // 1e-198
+ {hi: 0xbf5cd54678eef0b6, lo: 0xd262d45a78a0635d, exp2: -782}, // 1e-197
+ {hi: 0xef340a98172aace4, lo: 0x86fb897116c87c34, exp2: -779}, // 1e-196
+ {hi: 0x9580869f0e7aac0e, lo: 0xd45d35e6ae3d4da0, exp2: -775}, // 1e-195
+ {hi: 0xbae0a846d2195712, lo: 0x8974836059cca109, exp2: -772}, // 1e-194
+ {hi: 0xe998d258869facd7, lo: 0x2bd1a438703fc94b, exp2: -769}, // 1e-193
+ {hi: 0x91ff83775423cc06, lo: 0x7b6306a34627ddcf, exp2: -765}, // 1e-192
+ {hi: 0xb67f6455292cbf08, lo: 0x1a3bc84c17b1d542, exp2: -762}, // 1e-191
+ {hi: 0xe41f3d6a7377eeca, lo: 0x20caba5f1d9e4a93, exp2: -759}, // 1e-190
+ {hi: 0x8e938662882af53e, lo: 0x547eb47b7282ee9c, exp2: -755}, // 1e-189
+ {hi: 0xb23867fb2a35b28d, lo: 0xe99e619a4f23aa43, exp2: -752}, // 1e-188
+ {hi: 0xdec681f9f4c31f31, lo: 0x6405fa00e2ec94d4, exp2: -749}, // 1e-187
+ {hi: 0x8b3c113c38f9f37e, lo: 0xde83bc408dd3dd04, exp2: -745}, // 1e-186
+ {hi: 0xae0b158b4738705e, lo: 0x9624ab50b148d445, exp2: -742}, // 1e-185
+ {hi: 0xd98ddaee19068c76, lo: 0x3badd624dd9b0957, exp2: -739}, // 1e-184
+ {hi: 0x87f8a8d4cfa417c9, lo: 0xe54ca5d70a80e5d6, exp2: -735}, // 1e-183
+ {hi: 0xa9f6d30a038d1dbc, lo: 0x5e9fcf4ccd211f4c, exp2: -732}, // 1e-182
+ {hi: 0xd47487cc8470652b, lo: 0x7647c3200069671f, exp2: -729}, // 1e-181
+ {hi: 0x84c8d4dfd2c63f3b, lo: 0x29ecd9f40041e073, exp2: -725}, // 1e-180
+ {hi: 0xa5fb0a17c777cf09, lo: 0xf468107100525890, exp2: -722}, // 1e-179
+ {hi: 0xcf79cc9db955c2cc, lo: 0x7182148d4066eeb4, exp2: -719}, // 1e-178
+ {hi: 0x81ac1fe293d599bf, lo: 0xc6f14cd848405530, exp2: -715}, // 1e-177
+ {hi: 0xa21727db38cb002f, lo: 0xb8ada00e5a506a7c, exp2: -712}, // 1e-176
+ {hi: 0xca9cf1d206fdc03b, lo: 0xa6d90811f0e4851c, exp2: -709}, // 1e-175
+ {hi: 0xfd442e4688bd304a, lo: 0x908f4a166d1da663, exp2: -706}, // 1e-174
+ {hi: 0x9e4a9cec15763e2e, lo: 0x9a598e4e043287fe, exp2: -702}, // 1e-173
+ {hi: 0xc5dd44271ad3cdba, lo: 0x40eff1e1853f29fd, exp2: -699}, // 1e-172
+ {hi: 0xf7549530e188c128, lo: 0xd12bee59e68ef47c, exp2: -696}, // 1e-171
+ {hi: 0x9a94dd3e8cf578b9, lo: 0x82bb74f8301958ce, exp2: -692}, // 1e-170
+ {hi: 0xc13a148e3032d6e7, lo: 0xe36a52363c1faf01, exp2: -689}, // 1e-169
+ {hi: 0xf18899b1bc3f8ca1, lo: 0xdc44e6c3cb279ac1, exp2: -686}, // 1e-168
+ {hi: 0x96f5600f15a7b7e5, lo: 0x29ab103a5ef8c0b9, exp2: -682}, // 1e-167
+ {hi: 0xbcb2b812db11a5de, lo: 0x7415d448f6b6f0e7, exp2: -679}, // 1e-166
+ {hi: 0xebdf661791d60f56, lo: 0x111b495b3464ad21, exp2: -676}, // 1e-165
+ {hi: 0x936b9fcebb25c995, lo: 0xcab10dd900beec34, exp2: -672}, // 1e-164
+ {hi: 0xb84687c269ef3bfb, lo: 0x3d5d514f40eea742, exp2: -669}, // 1e-163
+ {hi: 0xe65829b3046b0afa, lo: 0x0cb4a5a3112a5112, exp2: -666}, // 1e-162
+ {hi: 0x8ff71a0fe2c2e6dc, lo: 0x47f0e785eaba72ab, exp2: -662}, // 1e-161
+ {hi: 0xb3f4e093db73a093, lo: 0x59ed216765690f56, exp2: -659}, // 1e-160
+ {hi: 0xe0f218b8d25088b8, lo: 0x306869c13ec3532c, exp2: -656}, // 1e-159
+ {hi: 0x8c974f7383725573, lo: 0x1e414218c73a13fb, exp2: -652}, // 1e-158
+ {hi: 0xafbd2350644eeacf, lo: 0xe5d1929ef90898fa, exp2: -649}, // 1e-157
+ {hi: 0xdbac6c247d62a583, lo: 0xdf45f746b74abf39, exp2: -646}, // 1e-156
+ {hi: 0x894bc396ce5da772, lo: 0x6b8bba8c328eb783, exp2: -642}, // 1e-155
+ {hi: 0xab9eb47c81f5114f, lo: 0x066ea92f3f326564, exp2: -639}, // 1e-154
+ {hi: 0xd686619ba27255a2, lo: 0xc80a537b0efefebd, exp2: -636}, // 1e-153
+ {hi: 0x8613fd0145877585, lo: 0xbd06742ce95f5f36, exp2: -632}, // 1e-152
+ {hi: 0xa798fc4196e952e7, lo: 0x2c48113823b73704, exp2: -629}, // 1e-151
+ {hi: 0xd17f3b51fca3a7a0, lo: 0xf75a15862ca504c5, exp2: -626}, // 1e-150
+ {hi: 0x82ef85133de648c4, lo: 0x9a984d73dbe722fb, exp2: -622}, // 1e-149
+ {hi: 0xa3ab66580d5fdaf5, lo: 0xc13e60d0d2e0ebba, exp2: -619}, // 1e-148
+ {hi: 0xcc963fee10b7d1b3, lo: 0x318df905079926a8, exp2: -616}, // 1e-147
+ {hi: 0xffbbcfe994e5c61f, lo: 0xfdf17746497f7052, exp2: -613}, // 1e-146
+ {hi: 0x9fd561f1fd0f9bd3, lo: 0xfeb6ea8bedefa633, exp2: -609}, // 1e-145
+ {hi: 0xc7caba6e7c5382c8, lo: 0xfe64a52ee96b8fc0, exp2: -606}, // 1e-144
+ {hi: 0xf9bd690a1b68637b, lo: 0x3dfdce7aa3c673b0, exp2: -603}, // 1e-143
+ {hi: 0x9c1661a651213e2d, lo: 0x06bea10ca65c084e, exp2: -599}, // 1e-142
+ {hi: 0xc31bfa0fe5698db8, lo: 0x486e494fcff30a62, exp2: -596}, // 1e-141
+ {hi: 0xf3e2f893dec3f126, lo: 0x5a89dba3c3efccfa, exp2: -593}, // 1e-140
+ {hi: 0x986ddb5c6b3a76b7, lo: 0xf89629465a75e01c, exp2: -589}, // 1e-139
+ {hi: 0xbe89523386091465, lo: 0xf6bbb397f1135823, exp2: -586}, // 1e-138
+ {hi: 0xee2ba6c0678b597f, lo: 0x746aa07ded582e2c, exp2: -583}, // 1e-137
+ {hi: 0x94db483840b717ef, lo: 0xa8c2a44eb4571cdc, exp2: -579}, // 1e-136
+ {hi: 0xba121a4650e4ddeb, lo: 0x92f34d62616ce413, exp2: -576}, // 1e-135
+ {hi: 0xe896a0d7e51e1566, lo: 0x77b020baf9c81d17, exp2: -573}, // 1e-134
+ {hi: 0x915e2486ef32cd60, lo: 0x0ace1474dc1d122e, exp2: -569}, // 1e-133
+ {hi: 0xb5b5ada8aaff80b8, lo: 0x0d819992132456ba, exp2: -566}, // 1e-132
+ {hi: 0xe3231912d5bf60e6, lo: 0x10e1fff697ed6c69, exp2: -563}, // 1e-131
+ {hi: 0x8df5efabc5979c8f, lo: 0xca8d3ffa1ef463c1, exp2: -559}, // 1e-130
+ {hi: 0xb1736b96b6fd83b3, lo: 0xbd308ff8a6b17cb2, exp2: -556}, // 1e-129
+ {hi: 0xddd0467c64bce4a0, lo: 0xac7cb3f6d05ddbde, exp2: -553}, // 1e-128
+ {hi: 0x8aa22c0dbef60ee4, lo: 0x6bcdf07a423aa96b, exp2: -549}, // 1e-127
+ {hi: 0xad4ab7112eb3929d, lo: 0x86c16c98d2c953c6, exp2: -546}, // 1e-126
+ {hi: 0xd89d64d57a607744, lo: 0xe871c7bf077ba8b7, exp2: -543}, // 1e-125
+ {hi: 0x87625f056c7c4a8b, lo: 0x11471cd764ad4972, exp2: -539}, // 1e-124
+ {hi: 0xa93af6c6c79b5d2d, lo: 0xd598e40d3dd89bcf, exp2: -536}, // 1e-123
+ {hi: 0xd389b47879823479, lo: 0x4aff1d108d4ec2c3, exp2: -533}, // 1e-122
+ {hi: 0x843610cb4bf160cb, lo: 0xcedf722a585139ba, exp2: -529}, // 1e-121
+ {hi: 0xa54394fe1eedb8fe, lo: 0xc2974eb4ee658828, exp2: -526}, // 1e-120
+ {hi: 0xce947a3da6a9273e, lo: 0x733d226229feea32, exp2: -523}, // 1e-119
+ {hi: 0x811ccc668829b887, lo: 0x0806357d5a3f525f, exp2: -519}, // 1e-118
+ {hi: 0xa163ff802a3426a8, lo: 0xca07c2dcb0cf26f7, exp2: -516}, // 1e-117
+ {hi: 0xc9bcff6034c13052, lo: 0xfc89b393dd02f0b5, exp2: -513}, // 1e-116
+ {hi: 0xfc2c3f3841f17c67, lo: 0xbbac2078d443ace2, exp2: -510}, // 1e-115
+ {hi: 0x9d9ba7832936edc0, lo: 0xd54b944b84aa4c0d, exp2: -506}, // 1e-114
+ {hi: 0xc5029163f384a931, lo: 0x0a9e795e65d4df11, exp2: -503}, // 1e-113
+ {hi: 0xf64335bcf065d37d, lo: 0x4d4617b5ff4a16d5, exp2: -500}, // 1e-112
+ {hi: 0x99ea0196163fa42e, lo: 0x504bced1bf8e4e45, exp2: -496}, // 1e-111
+ {hi: 0xc06481fb9bcf8d39, lo: 0xe45ec2862f71e1d6, exp2: -493}, // 1e-110
+ {hi: 0xf07da27a82c37088, lo: 0x5d767327bb4e5a4c, exp2: -490}, // 1e-109
+ {hi: 0x964e858c91ba2655, lo: 0x3a6a07f8d510f86f, exp2: -486}, // 1e-108
+ {hi: 0xbbe226efb628afea, lo: 0x890489f70a55368b, exp2: -483}, // 1e-107
+ {hi: 0xeadab0aba3b2dbe5, lo: 0x2b45ac74ccea842e, exp2: -480}, // 1e-106
+ {hi: 0x92c8ae6b464fc96f, lo: 0x3b0b8bc90012929d, exp2: -476}, // 1e-105
+ {hi: 0xb77ada0617e3bbcb, lo: 0x09ce6ebb40173744, exp2: -473}, // 1e-104
+ {hi: 0xe55990879ddcaabd, lo: 0xcc420a6a101d0515, exp2: -470}, // 1e-103
+ {hi: 0x8f57fa54c2a9eab6, lo: 0x9fa946824a12232d, exp2: -466}, // 1e-102
+ {hi: 0xb32df8e9f3546564, lo: 0x47939822dc96abf9, exp2: -463}, // 1e-101
+ {hi: 0xdff9772470297ebd, lo: 0x59787e2b93bc56f7, exp2: -460}, // 1e-100
+ {hi: 0x8bfbea76c619ef36, lo: 0x57eb4edb3c55b65a, exp2: -456}, // 1e-99
+ {hi: 0xaefae51477a06b03, lo: 0xede622920b6b23f1, exp2: -453}, // 1e-98
+ {hi: 0xdab99e59958885c4, lo: 0xe95fab368e45eced, exp2: -450}, // 1e-97
+ {hi: 0x88b402f7fd75539b, lo: 0x11dbcb0218ebb414, exp2: -446}, // 1e-96
+ {hi: 0xaae103b5fcd2a881, lo: 0xd652bdc29f26a119, exp2: -443}, // 1e-95
+ {hi: 0xd59944a37c0752a2, lo: 0x4be76d3346f0495f, exp2: -440}, // 1e-94
+ {hi: 0x857fcae62d8493a5, lo: 0x6f70a4400c562ddb, exp2: -436}, // 1e-93
+ {hi: 0xa6dfbd9fb8e5b88e, lo: 0xcb4ccd500f6bb952, exp2: -433}, // 1e-92
+ {hi: 0xd097ad07a71f26b2, lo: 0x7e2000a41346a7a7, exp2: -430}, // 1e-91
+ {hi: 0x825ecc24c873782f, lo: 0x8ed400668c0c28c8, exp2: -426}, // 1e-90
+ {hi: 0xa2f67f2dfa90563b, lo: 0x728900802f0f32fa, exp2: -423}, // 1e-89
+ {hi: 0xcbb41ef979346bca, lo: 0x4f2b40a03ad2ffb9, exp2: -420}, // 1e-88
+ {hi: 0xfea126b7d78186bc, lo: 0xe2f610c84987bfa8, exp2: -417}, // 1e-87
+ {hi: 0x9f24b832e6b0f436, lo: 0x0dd9ca7d2df4d7c9, exp2: -413}, // 1e-86
+ {hi: 0xc6ede63fa05d3143, lo: 0x91503d1c79720dbb, exp2: -410}, // 1e-85
+ {hi: 0xf8a95fcf88747d94, lo: 0x75a44c6397ce912a, exp2: -407}, // 1e-84
+ {hi: 0x9b69dbe1b548ce7c, lo: 0xc986afbe3ee11aba, exp2: -403}, // 1e-83
+ {hi: 0xc24452da229b021b, lo: 0xfbe85badce996168, exp2: -400}, // 1e-82
+ {hi: 0xf2d56790ab41c2a2, lo: 0xfae27299423fb9c3, exp2: -397}, // 1e-81
+ {hi: 0x97c560ba6b0919a5, lo: 0xdccd879fc967d41a, exp2: -393}, // 1e-80
+ {hi: 0xbdb6b8e905cb600f, lo: 0x5400e987bbc1c920, exp2: -390}, // 1e-79
+ {hi: 0xed246723473e3813, lo: 0x290123e9aab23b68, exp2: -387}, // 1e-78
+ {hi: 0x9436c0760c86e30b, lo: 0xf9a0b6720aaf6521, exp2: -383}, // 1e-77
+ {hi: 0xb94470938fa89bce, lo: 0xf808e40e8d5b3e69, exp2: -380}, // 1e-76
+ {hi: 0xe7958cb87392c2c2, lo: 0xb60b1d1230b20e04, exp2: -377}, // 1e-75
+ {hi: 0x90bd77f3483bb9b9, lo: 0xb1c6f22b5e6f48c2, exp2: -373}, // 1e-74
+ {hi: 0xb4ecd5f01a4aa828, lo: 0x1e38aeb6360b1af3, exp2: -370}, // 1e-73
+ {hi: 0xe2280b6c20dd5232, lo: 0x25c6da63c38de1b0, exp2: -367}, // 1e-72
+ {hi: 0x8d590723948a535f, lo: 0x579c487e5a38ad0e, exp2: -363}, // 1e-71
+ {hi: 0xb0af48ec79ace837, lo: 0x2d835a9df0c6d851, exp2: -360}, // 1e-70
+ {hi: 0xdcdb1b2798182244, lo: 0xf8e431456cf88e65, exp2: -357}, // 1e-69
+ {hi: 0x8a08f0f8bf0f156b, lo: 0x1b8e9ecb641b58ff, exp2: -353}, // 1e-68
+ {hi: 0xac8b2d36eed2dac5, lo: 0xe272467e3d222f3f, exp2: -350}, // 1e-67
+ {hi: 0xd7adf884aa879177, lo: 0x5b0ed81dcc6abb0f, exp2: -347}, // 1e-66
+ {hi: 0x86ccbb52ea94baea, lo: 0x98e947129fc2b4e9, exp2: -343}, // 1e-65
+ {hi: 0xa87fea27a539e9a5, lo: 0x3f2398d747b36224, exp2: -340}, // 1e-64
+ {hi: 0xd29fe4b18e88640e, lo: 0x8eec7f0d19a03aad, exp2: -337}, // 1e-63
+ {hi: 0x83a3eeeef9153e89, lo: 0x1953cf68300424ac, exp2: -333}, // 1e-62
+ {hi: 0xa48ceaaab75a8e2b, lo: 0x5fa8c3423c052dd7, exp2: -330}, // 1e-61
+ {hi: 0xcdb02555653131b6, lo: 0x3792f412cb06794d, exp2: -327}, // 1e-60
+ {hi: 0x808e17555f3ebf11, lo: 0xe2bbd88bbee40bd0, exp2: -323}, // 1e-59
+ {hi: 0xa0b19d2ab70e6ed6, lo: 0x5b6aceaeae9d0ec4, exp2: -320}, // 1e-58
+ {hi: 0xc8de047564d20a8b, lo: 0xf245825a5a445275, exp2: -317}, // 1e-57
+ {hi: 0xfb158592be068d2e, lo: 0xeed6e2f0f0d56712, exp2: -314}, // 1e-56
+ {hi: 0x9ced737bb6c4183d, lo: 0x55464dd69685606b, exp2: -310}, // 1e-55
+ {hi: 0xc428d05aa4751e4c, lo: 0xaa97e14c3c26b886, exp2: -307}, // 1e-54
+ {hi: 0xf53304714d9265df, lo: 0xd53dd99f4b3066a8, exp2: -304}, // 1e-53
+ {hi: 0x993fe2c6d07b7fab, lo: 0xe546a8038efe4029, exp2: -300}, // 1e-52
+ {hi: 0xbf8fdb78849a5f96, lo: 0xde98520472bdd033, exp2: -297}, // 1e-51
+ {hi: 0xef73d256a5c0f77c, lo: 0x963e66858f6d4440, exp2: -294}, // 1e-50
+ {hi: 0x95a8637627989aad, lo: 0xdde7001379a44aa8, exp2: -290}, // 1e-49
+ {hi: 0xbb127c53b17ec159, lo: 0x5560c018580d5d52, exp2: -287}, // 1e-48
+ {hi: 0xe9d71b689dde71af, lo: 0xaab8f01e6e10b4a6, exp2: -284}, // 1e-47
+ {hi: 0x9226712162ab070d, lo: 0xcab3961304ca70e8, exp2: -280}, // 1e-46
+ {hi: 0xb6b00d69bb55c8d1, lo: 0x3d607b97c5fd0d22, exp2: -277}, // 1e-45
+ {hi: 0xe45c10c42a2b3b05, lo: 0x8cb89a7db77c506a, exp2: -274}, // 1e-44
+ {hi: 0x8eb98a7a9a5b04e3, lo: 0x77f3608e92adb242, exp2: -270}, // 1e-43
+ {hi: 0xb267ed1940f1c61c, lo: 0x55f038b237591ed3, exp2: -267}, // 1e-42
+ {hi: 0xdf01e85f912e37a3, lo: 0x6b6c46dec52f6688, exp2: -264}, // 1e-41
+ {hi: 0x8b61313bbabce2c6, lo: 0x2323ac4b3b3da015, exp2: -260}, // 1e-40
+ {hi: 0xae397d8aa96c1b77, lo: 0xabec975e0a0d081a, exp2: -257}, // 1e-39
+ {hi: 0xd9c7dced53c72255, lo: 0x96e7bd358c904a21, exp2: -254}, // 1e-38
+ {hi: 0x881cea14545c7575, lo: 0x7e50d64177da2e54, exp2: -250}, // 1e-37
+ {hi: 0xaa242499697392d2, lo: 0xdde50bd1d5d0b9e9, exp2: -247}, // 1e-36
+ {hi: 0xd4ad2dbfc3d07787, lo: 0x955e4ec64b44e864, exp2: -244}, // 1e-35
+ {hi: 0x84ec3c97da624ab4, lo: 0xbd5af13bef0b113e, exp2: -240}, // 1e-34
+ {hi: 0xa6274bbdd0fadd61, lo: 0xecb1ad8aeacdd58e, exp2: -237}, // 1e-33
+ {hi: 0xcfb11ead453994ba, lo: 0x67de18eda5814af2, exp2: -234}, // 1e-32
+ {hi: 0x81ceb32c4b43fcf4, lo: 0x80eacf948770ced7, exp2: -230}, // 1e-31
+ {hi: 0xa2425ff75e14fc31, lo: 0xa1258379a94d028d, exp2: -227}, // 1e-30
+ {hi: 0xcad2f7f5359a3b3e, lo: 0x096ee45813a04330, exp2: -224}, // 1e-29
+ {hi: 0xfd87b5f28300ca0d, lo: 0x8bca9d6e188853fc, exp2: -221}, // 1e-28
+ {hi: 0x9e74d1b791e07e48, lo: 0x775ea264cf55347d, exp2: -217}, // 1e-27
+ {hi: 0xc612062576589dda, lo: 0x95364afe032a819d, exp2: -214}, // 1e-26
+ {hi: 0xf79687aed3eec551, lo: 0x3a83ddbd83f52204, exp2: -211}, // 1e-25
+ {hi: 0x9abe14cd44753b52, lo: 0xc4926a9672793542, exp2: -207}, // 1e-24
+ {hi: 0xc16d9a0095928a27, lo: 0x75b7053c0f178293, exp2: -204}, // 1e-23
+ {hi: 0xf1c90080baf72cb1, lo: 0x5324c68b12dd6338, exp2: -201}, // 1e-22
+ {hi: 0x971da05074da7bee, lo: 0xd3f6fc16ebca5e03, exp2: -197}, // 1e-21
+ {hi: 0xbce5086492111aea, lo: 0x88f4bb1ca6bcf584, exp2: -194}, // 1e-20
+ {hi: 0xec1e4a7db69561a5, lo: 0x2b31e9e3d06c32e5, exp2: -191}, // 1e-19
+ {hi: 0x9392ee8e921d5d07, lo: 0x3aff322e62439fcf, exp2: -187}, // 1e-18
+ {hi: 0xb877aa3236a4b449, lo: 0x09befeb9fad487c2, exp2: -184}, // 1e-17
+ {hi: 0xe69594bec44de15b, lo: 0x4c2ebe687989a9b3, exp2: -181}, // 1e-16
+ {hi: 0x901d7cf73ab0acd9, lo: 0x0f9d37014bf60a10, exp2: -177}, // 1e-15
+ {hi: 0xb424dc35095cd80f, lo: 0x538484c19ef38c94, exp2: -174}, // 1e-14
+ {hi: 0xe12e13424bb40e13, lo: 0x2865a5f206b06fb9, exp2: -171}, // 1e-13
+ {hi: 0x8cbccc096f5088cb, lo: 0xf93f87b7442e45d3, exp2: -167}, // 1e-12
+ {hi: 0xafebff0bcb24aafe, lo: 0xf78f69a51539d748, exp2: -164}, // 1e-11
+ {hi: 0xdbe6fecebdedd5be, lo: 0xb573440e5a884d1b, exp2: -161}, // 1e-10
+ {hi: 0x89705f4136b4a597, lo: 0x31680a88f8953030, exp2: -157}, // 1e-9
+ {hi: 0xabcc77118461cefc, lo: 0xfdc20d2b36ba7c3d, exp2: -154}, // 1e-8
+ {hi: 0xd6bf94d5e57a42bc, lo: 0x3d32907604691b4c, exp2: -151}, // 1e-7
+ {hi: 0x8637bd05af6c69b5, lo: 0xa63f9a49c2c1b10f, exp2: -147}, // 1e-6
+ {hi: 0xa7c5ac471b478423, lo: 0x0fcf80dc33721d53, exp2: -144}, // 1e-5
+ {hi: 0xd1b71758e219652b, lo: 0xd3c36113404ea4a8, exp2: -141}, // 1e-4
+ {hi: 0x83126e978d4fdf3b, lo: 0x645a1cac083126e9, exp2: -137}, // 1e-3
+ {hi: 0xa3d70a3d70a3d70a, lo: 0x3d70a3d70a3d70a3, exp2: -134}, // 1e-2
+ {hi: 0xcccccccccccccccc, lo: 0xcccccccccccccccc, exp2: -131}, // 1e-1
+ {hi: 0x8000000000000000, lo: 0x0000000000000000, exp2: -127}, // 1e0
+ {hi: 0xa000000000000000, lo: 0x0000000000000000, exp2: -124}, // 1e1
+ {hi: 0xc800000000000000, lo: 0x0000000000000000, exp2: -121}, // 1e2
+ {hi: 0xfa00000000000000, lo: 0x0000000000000000, exp2: -118}, // 1e3
+ {hi: 0x9c40000000000000, lo: 0x0000000000000000, exp2: -114}, // 1e4
+ {hi: 0xc350000000000000, lo: 0x0000000000000000, exp2: -111}, // 1e5
+ {hi: 0xf424000000000000, lo: 0x0000000000000000, exp2: -108}, // 1e6
+ {hi: 0x9896800000000000, lo: 0x0000000000000000, exp2: -104}, // 1e7
+ {hi: 0xbebc200000000000, lo: 0x0000000000000000, exp2: -101}, // 1e8
+ {hi: 0xee6b280000000000, lo: 0x0000000000000000, exp2: -98}, // 1e9
+ {hi: 0x9502f90000000000, lo: 0x0000000000000000, exp2: -94}, // 1e10
+ {hi: 0xba43b74000000000, lo: 0x0000000000000000, exp2: -91}, // 1e11
+ {hi: 0xe8d4a51000000000, lo: 0x0000000000000000, exp2: -88}, // 1e12
+ {hi: 0x9184e72a00000000, lo: 0x0000000000000000, exp2: -84}, // 1e13
+ {hi: 0xb5e620f480000000, lo: 0x0000000000000000, exp2: -81}, // 1e14
+ {hi: 0xe35fa931a0000000, lo: 0x0000000000000000, exp2: -78}, // 1e15
+ {hi: 0x8e1bc9bf04000000, lo: 0x0000000000000000, exp2: -74}, // 1e16
+ {hi: 0xb1a2bc2ec5000000, lo: 0x0000000000000000, exp2: -71}, // 1e17
+ {hi: 0xde0b6b3a76400000, lo: 0x0000000000000000, exp2: -68}, // 1e18
+ {hi: 0x8ac7230489e80000, lo: 0x0000000000000000, exp2: -64}, // 1e19
+ {hi: 0xad78ebc5ac620000, lo: 0x0000000000000000, exp2: -61}, // 1e20
+ {hi: 0xd8d726b7177a8000, lo: 0x0000000000000000, exp2: -58}, // 1e21
+ {hi: 0x878678326eac9000, lo: 0x0000000000000000, exp2: -54}, // 1e22
+ {hi: 0xa968163f0a57b400, lo: 0x0000000000000000, exp2: -51}, // 1e23
+ {hi: 0xd3c21bcecceda100, lo: 0x0000000000000000, exp2: -48}, // 1e24
+ {hi: 0x84595161401484a0, lo: 0x0000000000000000, exp2: -44}, // 1e25
+ {hi: 0xa56fa5b99019a5c8, lo: 0x0000000000000000, exp2: -41}, // 1e26
+ {hi: 0xcecb8f27f4200f3a, lo: 0x0000000000000000, exp2: -38}, // 1e27
+ {hi: 0x813f3978f8940984, lo: 0x4000000000000000, exp2: -34}, // 1e28
+ {hi: 0xa18f07d736b90be5, lo: 0x5000000000000000, exp2: -31}, // 1e29
+ {hi: 0xc9f2c9cd04674ede, lo: 0xa400000000000000, exp2: -28}, // 1e30
+ {hi: 0xfc6f7c4045812296, lo: 0x4d00000000000000, exp2: -25}, // 1e31
+ {hi: 0x9dc5ada82b70b59d, lo: 0xf020000000000000, exp2: -21}, // 1e32
+ {hi: 0xc5371912364ce305, lo: 0x6c28000000000000, exp2: -18}, // 1e33
+ {hi: 0xf684df56c3e01bc6, lo: 0xc732000000000000, exp2: -15}, // 1e34
+ {hi: 0x9a130b963a6c115c, lo: 0x3c7f400000000000, exp2: -11}, // 1e35
+ {hi: 0xc097ce7bc90715b3, lo: 0x4b9f100000000000, exp2: -8}, // 1e36
+ {hi: 0xf0bdc21abb48db20, lo: 0x1e86d40000000000, exp2: -5}, // 1e37
+ {hi: 0x96769950b50d88f4, lo: 0x1314448000000000, exp2: -1}, // 1e38
+ {hi: 0xbc143fa4e250eb31, lo: 0x17d955a000000000, exp2: 2}, // 1e39
+ {hi: 0xeb194f8e1ae525fd, lo: 0x5dcfab0800000000, exp2: 5}, // 1e40
+ {hi: 0x92efd1b8d0cf37be, lo: 0x5aa1cae500000000, exp2: 9}, // 1e41
+ {hi: 0xb7abc627050305ad, lo: 0xf14a3d9e40000000, exp2: 12}, // 1e42
+ {hi: 0xe596b7b0c643c719, lo: 0x6d9ccd05d0000000, exp2: 15}, // 1e43
+ {hi: 0x8f7e32ce7bea5c6f, lo: 0xe4820023a2000000, exp2: 19}, // 1e44
+ {hi: 0xb35dbf821ae4f38b, lo: 0xdda2802c8a800000, exp2: 22}, // 1e45
+ {hi: 0xe0352f62a19e306e, lo: 0xd50b2037ad200000, exp2: 25}, // 1e46
+ {hi: 0x8c213d9da502de45, lo: 0x4526f422cc340000, exp2: 29}, // 1e47
+ {hi: 0xaf298d050e4395d6, lo: 0x9670b12b7f410000, exp2: 32}, // 1e48
+ {hi: 0xdaf3f04651d47b4c, lo: 0x3c0cdd765f114000, exp2: 35}, // 1e49
+ {hi: 0x88d8762bf324cd0f, lo: 0xa5880a69fb6ac800, exp2: 39}, // 1e50
+ {hi: 0xab0e93b6efee0053, lo: 0x8eea0d047a457a00, exp2: 42}, // 1e51
+ {hi: 0xd5d238a4abe98068, lo: 0x72a4904598d6d880, exp2: 45}, // 1e52
+ {hi: 0x85a36366eb71f041, lo: 0x47a6da2b7f864750, exp2: 49}, // 1e53
+ {hi: 0xa70c3c40a64e6c51, lo: 0x999090b65f67d924, exp2: 52}, // 1e54
+ {hi: 0xd0cf4b50cfe20765, lo: 0xfff4b4e3f741cf6d, exp2: 55}, // 1e55
+ {hi: 0x82818f1281ed449f, lo: 0xbff8f10e7a8921a4, exp2: 59}, // 1e56
+ {hi: 0xa321f2d7226895c7, lo: 0xaff72d52192b6a0d, exp2: 62}, // 1e57
+ {hi: 0xcbea6f8ceb02bb39, lo: 0x9bf4f8a69f764490, exp2: 65}, // 1e58
+ {hi: 0xfee50b7025c36a08, lo: 0x02f236d04753d5b4, exp2: 68}, // 1e59
+ {hi: 0x9f4f2726179a2245, lo: 0x01d762422c946590, exp2: 72}, // 1e60
+ {hi: 0xc722f0ef9d80aad6, lo: 0x424d3ad2b7b97ef5, exp2: 75}, // 1e61
+ {hi: 0xf8ebad2b84e0d58b, lo: 0xd2e0898765a7deb2, exp2: 78}, // 1e62
+ {hi: 0x9b934c3b330c8577, lo: 0x63cc55f49f88eb2f, exp2: 82}, // 1e63
+ {hi: 0xc2781f49ffcfa6d5, lo: 0x3cbf6b71c76b25fb, exp2: 85}, // 1e64
+ {hi: 0xf316271c7fc3908a, lo: 0x8bef464e3945ef7a, exp2: 88}, // 1e65
+ {hi: 0x97edd871cfda3a56, lo: 0x97758bf0e3cbb5ac, exp2: 92}, // 1e66
+ {hi: 0xbde94e8e43d0c8ec, lo: 0x3d52eeed1cbea317, exp2: 95}, // 1e67
+ {hi: 0xed63a231d4c4fb27, lo: 0x4ca7aaa863ee4bdd, exp2: 98}, // 1e68
+ {hi: 0x945e455f24fb1cf8, lo: 0x8fe8caa93e74ef6a, exp2: 102}, // 1e69
+ {hi: 0xb975d6b6ee39e436, lo: 0xb3e2fd538e122b44, exp2: 105}, // 1e70
+ {hi: 0xe7d34c64a9c85d44, lo: 0x60dbbca87196b616, exp2: 108}, // 1e71
+ {hi: 0x90e40fbeea1d3a4a, lo: 0xbc8955e946fe31cd, exp2: 112}, // 1e72
+ {hi: 0xb51d13aea4a488dd, lo: 0x6babab6398bdbe41, exp2: 115}, // 1e73
+ {hi: 0xe264589a4dcdab14, lo: 0xc696963c7eed2dd1, exp2: 118}, // 1e74
+ {hi: 0x8d7eb76070a08aec, lo: 0xfc1e1de5cf543ca2, exp2: 122}, // 1e75
+ {hi: 0xb0de65388cc8ada8, lo: 0x3b25a55f43294bcb, exp2: 125}, // 1e76
+ {hi: 0xdd15fe86affad912, lo: 0x49ef0eb713f39ebe, exp2: 128}, // 1e77
+ {hi: 0x8a2dbf142dfcc7ab, lo: 0x6e3569326c784337, exp2: 132}, // 1e78
+ {hi: 0xacb92ed9397bf996, lo: 0x49c2c37f07965404, exp2: 135}, // 1e79
+ {hi: 0xd7e77a8f87daf7fb, lo: 0xdc33745ec97be906, exp2: 138}, // 1e80
+ {hi: 0x86f0ac99b4e8dafd, lo: 0x69a028bb3ded71a3, exp2: 142}, // 1e81
+ {hi: 0xa8acd7c0222311bc, lo: 0xc40832ea0d68ce0c, exp2: 145}, // 1e82
+ {hi: 0xd2d80db02aabd62b, lo: 0xf50a3fa490c30190, exp2: 148}, // 1e83
+ {hi: 0x83c7088e1aab65db, lo: 0x792667c6da79e0fa, exp2: 152}, // 1e84
+ {hi: 0xa4b8cab1a1563f52, lo: 0x577001b891185938, exp2: 155}, // 1e85
+ {hi: 0xcde6fd5e09abcf26, lo: 0xed4c0226b55e6f86, exp2: 158}, // 1e86
+ {hi: 0x80b05e5ac60b6178, lo: 0x544f8158315b05b4, exp2: 162}, // 1e87
+ {hi: 0xa0dc75f1778e39d6, lo: 0x696361ae3db1c721, exp2: 165}, // 1e88
+ {hi: 0xc913936dd571c84c, lo: 0x03bc3a19cd1e38e9, exp2: 168}, // 1e89
+ {hi: 0xfb5878494ace3a5f, lo: 0x04ab48a04065c723, exp2: 171}, // 1e90
+ {hi: 0x9d174b2dcec0e47b, lo: 0x62eb0d64283f9c76, exp2: 175}, // 1e91
+ {hi: 0xc45d1df942711d9a, lo: 0x3ba5d0bd324f8394, exp2: 178}, // 1e92
+ {hi: 0xf5746577930d6500, lo: 0xca8f44ec7ee36479, exp2: 181}, // 1e93
+ {hi: 0x9968bf6abbe85f20, lo: 0x7e998b13cf4e1ecb, exp2: 185}, // 1e94
+ {hi: 0xbfc2ef456ae276e8, lo: 0x9e3fedd8c321a67e, exp2: 188}, // 1e95
+ {hi: 0xefb3ab16c59b14a2, lo: 0xc5cfe94ef3ea101e, exp2: 191}, // 1e96
+ {hi: 0x95d04aee3b80ece5, lo: 0xbba1f1d158724a12, exp2: 195}, // 1e97
+ {hi: 0xbb445da9ca61281f, lo: 0x2a8a6e45ae8edc97, exp2: 198}, // 1e98
+ {hi: 0xea1575143cf97226, lo: 0xf52d09d71a3293bd, exp2: 201}, // 1e99
+ {hi: 0x924d692ca61be758, lo: 0x593c2626705f9c56, exp2: 205}, // 1e100
+ {hi: 0xb6e0c377cfa2e12e, lo: 0x6f8b2fb00c77836c, exp2: 208}, // 1e101
+ {hi: 0xe498f455c38b997a, lo: 0x0b6dfb9c0f956447, exp2: 211}, // 1e102
+ {hi: 0x8edf98b59a373fec, lo: 0x4724bd4189bd5eac, exp2: 215}, // 1e103
+ {hi: 0xb2977ee300c50fe7, lo: 0x58edec91ec2cb657, exp2: 218}, // 1e104
+ {hi: 0xdf3d5e9bc0f653e1, lo: 0x2f2967b66737e3ed, exp2: 221}, // 1e105
+ {hi: 0x8b865b215899f46c, lo: 0xbd79e0d20082ee74, exp2: 225}, // 1e106
+ {hi: 0xae67f1e9aec07187, lo: 0xecd8590680a3aa11, exp2: 228}, // 1e107
+ {hi: 0xda01ee641a708de9, lo: 0xe80e6f4820cc9495, exp2: 231}, // 1e108
+ {hi: 0x884134fe908658b2, lo: 0x3109058d147fdcdd, exp2: 235}, // 1e109
+ {hi: 0xaa51823e34a7eede, lo: 0xbd4b46f0599fd415, exp2: 238}, // 1e110
+ {hi: 0xd4e5e2cdc1d1ea96, lo: 0x6c9e18ac7007c91a, exp2: 241}, // 1e111
+ {hi: 0x850fadc09923329e, lo: 0x03e2cf6bc604ddb0, exp2: 245}, // 1e112
+ {hi: 0xa6539930bf6bff45, lo: 0x84db8346b786151c, exp2: 248}, // 1e113
+ {hi: 0xcfe87f7cef46ff16, lo: 0xe612641865679a63, exp2: 251}, // 1e114
+ {hi: 0x81f14fae158c5f6e, lo: 0x4fcb7e8f3f60c07e, exp2: 255}, // 1e115
+ {hi: 0xa26da3999aef7749, lo: 0xe3be5e330f38f09d, exp2: 258}, // 1e116
+ {hi: 0xcb090c8001ab551c, lo: 0x5cadf5bfd3072cc5, exp2: 261}, // 1e117
+ {hi: 0xfdcb4fa002162a63, lo: 0x73d9732fc7c8f7f6, exp2: 264}, // 1e118
+ {hi: 0x9e9f11c4014dda7e, lo: 0x2867e7fddcdd9afa, exp2: 268}, // 1e119
+ {hi: 0xc646d63501a1511d, lo: 0xb281e1fd541501b8, exp2: 271}, // 1e120
+ {hi: 0xf7d88bc24209a565, lo: 0x1f225a7ca91a4226, exp2: 274}, // 1e121
+ {hi: 0x9ae757596946075f, lo: 0x3375788de9b06958, exp2: 278}, // 1e122
+ {hi: 0xc1a12d2fc3978937, lo: 0x0052d6b1641c83ae, exp2: 281}, // 1e123
+ {hi: 0xf209787bb47d6b84, lo: 0xc0678c5dbd23a49a, exp2: 284}, // 1e124
+ {hi: 0x9745eb4d50ce6332, lo: 0xf840b7ba963646e0, exp2: 288}, // 1e125
+ {hi: 0xbd176620a501fbff, lo: 0xb650e5a93bc3d898, exp2: 291}, // 1e126
+ {hi: 0xec5d3fa8ce427aff, lo: 0xa3e51f138ab4cebe, exp2: 294}, // 1e127
+ {hi: 0x93ba47c980e98cdf, lo: 0xc66f336c36b10137, exp2: 298}, // 1e128
+ {hi: 0xb8a8d9bbe123f017, lo: 0xb80b0047445d4184, exp2: 301}, // 1e129
+ {hi: 0xe6d3102ad96cec1d, lo: 0xa60dc059157491e5, exp2: 304}, // 1e130
+ {hi: 0x9043ea1ac7e41392, lo: 0x87c89837ad68db2f, exp2: 308}, // 1e131
+ {hi: 0xb454e4a179dd1877, lo: 0x29babe4598c311fb, exp2: 311}, // 1e132
+ {hi: 0xe16a1dc9d8545e94, lo: 0xf4296dd6fef3d67a, exp2: 314}, // 1e133
+ {hi: 0x8ce2529e2734bb1d, lo: 0x1899e4a65f58660c, exp2: 318}, // 1e134
+ {hi: 0xb01ae745b101e9e4, lo: 0x5ec05dcff72e7f8f, exp2: 321}, // 1e135
+ {hi: 0xdc21a1171d42645d, lo: 0x76707543f4fa1f73, exp2: 324}, // 1e136
+ {hi: 0x899504ae72497eba, lo: 0x6a06494a791c53a8, exp2: 328}, // 1e137
+ {hi: 0xabfa45da0edbde69, lo: 0x0487db9d17636892, exp2: 331}, // 1e138
+ {hi: 0xd6f8d7509292d603, lo: 0x45a9d2845d3c42b6, exp2: 334}, // 1e139
+ {hi: 0x865b86925b9bc5c2, lo: 0x0b8a2392ba45a9b2, exp2: 338}, // 1e140
+ {hi: 0xa7f26836f282b732, lo: 0x8e6cac7768d7141e, exp2: 341}, // 1e141
+ {hi: 0xd1ef0244af2364ff, lo: 0x3207d795430cd926, exp2: 344}, // 1e142
+ {hi: 0x8335616aed761f1f, lo: 0x7f44e6bd49e807b8, exp2: 348}, // 1e143
+ {hi: 0xa402b9c5a8d3a6e7, lo: 0x5f16206c9c6209a6, exp2: 351}, // 1e144
+ {hi: 0xcd036837130890a1, lo: 0x36dba887c37a8c0f, exp2: 354}, // 1e145
+ {hi: 0x802221226be55a64, lo: 0xc2494954da2c9789, exp2: 358}, // 1e146
+ {hi: 0xa02aa96b06deb0fd, lo: 0xf2db9baa10b7bd6c, exp2: 361}, // 1e147
+ {hi: 0xc83553c5c8965d3d, lo: 0x6f92829494e5acc7, exp2: 364}, // 1e148
+ {hi: 0xfa42a8b73abbf48c, lo: 0xcb772339ba1f17f9, exp2: 367}, // 1e149
+ {hi: 0x9c69a97284b578d7, lo: 0xff2a760414536efb, exp2: 371}, // 1e150
+ {hi: 0xc38413cf25e2d70d, lo: 0xfef5138519684aba, exp2: 374}, // 1e151
+ {hi: 0xf46518c2ef5b8cd1, lo: 0x7eb258665fc25d69, exp2: 377}, // 1e152
+ {hi: 0x98bf2f79d5993802, lo: 0xef2f773ffbd97a61, exp2: 381}, // 1e153
+ {hi: 0xbeeefb584aff8603, lo: 0xaafb550ffacfd8fa, exp2: 384}, // 1e154
+ {hi: 0xeeaaba2e5dbf6784, lo: 0x95ba2a53f983cf38, exp2: 387}, // 1e155
+ {hi: 0x952ab45cfa97a0b2, lo: 0xdd945a747bf26183, exp2: 391}, // 1e156
+ {hi: 0xba756174393d88df, lo: 0x94f971119aeef9e4, exp2: 394}, // 1e157
+ {hi: 0xe912b9d1478ceb17, lo: 0x7a37cd5601aab85d, exp2: 397}, // 1e158
+ {hi: 0x91abb422ccb812ee, lo: 0xac62e055c10ab33a, exp2: 401}, // 1e159
+ {hi: 0xb616a12b7fe617aa, lo: 0x577b986b314d6009, exp2: 404}, // 1e160
+ {hi: 0xe39c49765fdf9d94, lo: 0xed5a7e85fda0b80b, exp2: 407}, // 1e161
+ {hi: 0x8e41ade9fbebc27d, lo: 0x14588f13be847307, exp2: 411}, // 1e162
+ {hi: 0xb1d219647ae6b31c, lo: 0x596eb2d8ae258fc8, exp2: 414}, // 1e163
+ {hi: 0xde469fbd99a05fe3, lo: 0x6fca5f8ed9aef3bb, exp2: 417}, // 1e164
+ {hi: 0x8aec23d680043bee, lo: 0x25de7bb9480d5854, exp2: 421}, // 1e165
+ {hi: 0xada72ccc20054ae9, lo: 0xaf561aa79a10ae6a, exp2: 424}, // 1e166
+ {hi: 0xd910f7ff28069da4, lo: 0x1b2ba1518094da04, exp2: 427}, // 1e167
+ {hi: 0x87aa9aff79042286, lo: 0x90fb44d2f05d0842, exp2: 431}, // 1e168
+ {hi: 0xa99541bf57452b28, lo: 0x353a1607ac744a53, exp2: 434}, // 1e169
+ {hi: 0xd3fa922f2d1675f2, lo: 0x42889b8997915ce8, exp2: 437}, // 1e170
+ {hi: 0x847c9b5d7c2e09b7, lo: 0x69956135febada11, exp2: 441}, // 1e171
+ {hi: 0xa59bc234db398c25, lo: 0x43fab9837e699095, exp2: 444}, // 1e172
+ {hi: 0xcf02b2c21207ef2e, lo: 0x94f967e45e03f4bb, exp2: 447}, // 1e173
+ {hi: 0x8161afb94b44f57d, lo: 0x1d1be0eebac278f5, exp2: 451}, // 1e174
+ {hi: 0xa1ba1ba79e1632dc, lo: 0x6462d92a69731732, exp2: 454}, // 1e175
+ {hi: 0xca28a291859bbf93, lo: 0x7d7b8f7503cfdcfe, exp2: 457}, // 1e176
+ {hi: 0xfcb2cb35e702af78, lo: 0x5cda735244c3d43e, exp2: 460}, // 1e177
+ {hi: 0x9defbf01b061adab, lo: 0x3a0888136afa64a7, exp2: 464}, // 1e178
+ {hi: 0xc56baec21c7a1916, lo: 0x088aaa1845b8fdd0, exp2: 467}, // 1e179
+ {hi: 0xf6c69a72a3989f5b, lo: 0x8aad549e57273d45, exp2: 470}, // 1e180
+ {hi: 0x9a3c2087a63f6399, lo: 0x36ac54e2f678864b, exp2: 474}, // 1e181
+ {hi: 0xc0cb28a98fcf3c7f, lo: 0x84576a1bb416a7dd, exp2: 477}, // 1e182
+ {hi: 0xf0fdf2d3f3c30b9f, lo: 0x656d44a2a11c51d5, exp2: 480}, // 1e183
+ {hi: 0x969eb7c47859e743, lo: 0x9f644ae5a4b1b325, exp2: 484}, // 1e184
+ {hi: 0xbc4665b596706114, lo: 0x873d5d9f0dde1fee, exp2: 487}, // 1e185
+ {hi: 0xeb57ff22fc0c7959, lo: 0xa90cb506d155a7ea, exp2: 490}, // 1e186
+ {hi: 0x9316ff75dd87cbd8, lo: 0x09a7f12442d588f2, exp2: 494}, // 1e187
+ {hi: 0xb7dcbf5354e9bece, lo: 0x0c11ed6d538aeb2f, exp2: 497}, // 1e188
+ {hi: 0xe5d3ef282a242e81, lo: 0x8f1668c8a86da5fa, exp2: 500}, // 1e189
+ {hi: 0x8fa475791a569d10, lo: 0xf96e017d694487bc, exp2: 504}, // 1e190
+ {hi: 0xb38d92d760ec4455, lo: 0x37c981dcc395a9ac, exp2: 507}, // 1e191
+ {hi: 0xe070f78d3927556a, lo: 0x85bbe253f47b1417, exp2: 510}, // 1e192
+ {hi: 0x8c469ab843b89562, lo: 0x93956d7478ccec8e, exp2: 514}, // 1e193
+ {hi: 0xaf58416654a6babb, lo: 0x387ac8d1970027b2, exp2: 517}, // 1e194
+ {hi: 0xdb2e51bfe9d0696a, lo: 0x06997b05fcc0319e, exp2: 520}, // 1e195
+ {hi: 0x88fcf317f22241e2, lo: 0x441fece3bdf81f03, exp2: 524}, // 1e196
+ {hi: 0xab3c2fddeeaad25a, lo: 0xd527e81cad7626c3, exp2: 527}, // 1e197
+ {hi: 0xd60b3bd56a5586f1, lo: 0x8a71e223d8d3b074, exp2: 530}, // 1e198
+ {hi: 0x85c7056562757456, lo: 0xf6872d5667844e49, exp2: 534}, // 1e199
+ {hi: 0xa738c6bebb12d16c, lo: 0xb428f8ac016561db, exp2: 537}, // 1e200
+ {hi: 0xd106f86e69d785c7, lo: 0xe13336d701beba52, exp2: 540}, // 1e201
+ {hi: 0x82a45b450226b39c, lo: 0xecc0024661173473, exp2: 544}, // 1e202
+ {hi: 0xa34d721642b06084, lo: 0x27f002d7f95d0190, exp2: 547}, // 1e203
+ {hi: 0xcc20ce9bd35c78a5, lo: 0x31ec038df7b441f4, exp2: 550}, // 1e204
+ {hi: 0xff290242c83396ce, lo: 0x7e67047175a15271, exp2: 553}, // 1e205
+ {hi: 0x9f79a169bd203e41, lo: 0x0f0062c6e984d386, exp2: 557}, // 1e206
+ {hi: 0xc75809c42c684dd1, lo: 0x52c07b78a3e60868, exp2: 560}, // 1e207
+ {hi: 0xf92e0c3537826145, lo: 0xa7709a56ccdf8a82, exp2: 563}, // 1e208
+ {hi: 0x9bbcc7a142b17ccb, lo: 0x88a66076400bb691, exp2: 567}, // 1e209
+ {hi: 0xc2abf989935ddbfe, lo: 0x6acff893d00ea435, exp2: 570}, // 1e210
+ {hi: 0xf356f7ebf83552fe, lo: 0x0583f6b8c4124d43, exp2: 573}, // 1e211
+ {hi: 0x98165af37b2153de, lo: 0xc3727a337a8b704a, exp2: 577}, // 1e212
+ {hi: 0xbe1bf1b059e9a8d6, lo: 0x744f18c0592e4c5c, exp2: 580}, // 1e213
+ {hi: 0xeda2ee1c7064130c, lo: 0x1162def06f79df73, exp2: 583}, // 1e214
+ {hi: 0x9485d4d1c63e8be7, lo: 0x8addcb5645ac2ba8, exp2: 587}, // 1e215
+ {hi: 0xb9a74a0637ce2ee1, lo: 0x6d953e2bd7173692, exp2: 590}, // 1e216
+ {hi: 0xe8111c87c5c1ba99, lo: 0xc8fa8db6ccdd0437, exp2: 593}, // 1e217
+ {hi: 0x910ab1d4db9914a0, lo: 0x1d9c9892400a22a2, exp2: 597}, // 1e218
+ {hi: 0xb54d5e4a127f59c8, lo: 0x2503beb6d00cab4b, exp2: 600}, // 1e219
+ {hi: 0xe2a0b5dc971f303a, lo: 0x2e44ae64840fd61d, exp2: 603}, // 1e220
+ {hi: 0x8da471a9de737e24, lo: 0x5ceaecfed289e5d2, exp2: 607}, // 1e221
+ {hi: 0xb10d8e1456105dad, lo: 0x7425a83e872c5f47, exp2: 610}, // 1e222
+ {hi: 0xdd50f1996b947518, lo: 0xd12f124e28f77719, exp2: 613}, // 1e223
+ {hi: 0x8a5296ffe33cc92f, lo: 0x82bd6b70d99aaa6f, exp2: 617}, // 1e224
+ {hi: 0xace73cbfdc0bfb7b, lo: 0x636cc64d1001550b, exp2: 620}, // 1e225
+ {hi: 0xd8210befd30efa5a, lo: 0x3c47f7e05401aa4e, exp2: 623}, // 1e226
+ {hi: 0x8714a775e3e95c78, lo: 0x65acfaec34810a71, exp2: 627}, // 1e227
+ {hi: 0xa8d9d1535ce3b396, lo: 0x7f1839a741a14d0d, exp2: 630}, // 1e228
+ {hi: 0xd31045a8341ca07c, lo: 0x1ede48111209a050, exp2: 633}, // 1e229
+ {hi: 0x83ea2b892091e44d, lo: 0x934aed0aab460432, exp2: 637}, // 1e230
+ {hi: 0xa4e4b66b68b65d60, lo: 0xf81da84d5617853f, exp2: 640}, // 1e231
+ {hi: 0xce1de40642e3f4b9, lo: 0x36251260ab9d668e, exp2: 643}, // 1e232
+ {hi: 0x80d2ae83e9ce78f3, lo: 0xc1d72b7c6b426019, exp2: 647}, // 1e233
+ {hi: 0xa1075a24e4421730, lo: 0xb24cf65b8612f81f, exp2: 650}, // 1e234
+ {hi: 0xc94930ae1d529cfc, lo: 0xdee033f26797b627, exp2: 653}, // 1e235
+ {hi: 0xfb9b7cd9a4a7443c, lo: 0x169840ef017da3b1, exp2: 656}, // 1e236
+ {hi: 0x9d412e0806e88aa5, lo: 0x8e1f289560ee864e, exp2: 660}, // 1e237
+ {hi: 0xc491798a08a2ad4e, lo: 0xf1a6f2bab92a27e2, exp2: 663}, // 1e238
+ {hi: 0xf5b5d7ec8acb58a2, lo: 0xae10af696774b1db, exp2: 666}, // 1e239
+ {hi: 0x9991a6f3d6bf1765, lo: 0xacca6da1e0a8ef29, exp2: 670}, // 1e240
+ {hi: 0xbff610b0cc6edd3f, lo: 0x17fd090a58d32af3, exp2: 673}, // 1e241
+ {hi: 0xeff394dcff8a948e, lo: 0xddfc4b4cef07f5b0, exp2: 676}, // 1e242
+ {hi: 0x95f83d0a1fb69cd9, lo: 0x4abdaf101564f98e, exp2: 680}, // 1e243
+ {hi: 0xbb764c4ca7a4440f, lo: 0x9d6d1ad41abe37f1, exp2: 683}, // 1e244
+ {hi: 0xea53df5fd18d5513, lo: 0x84c86189216dc5ed, exp2: 686}, // 1e245
+ {hi: 0x92746b9be2f8552c, lo: 0x32fd3cf5b4e49bb4, exp2: 690}, // 1e246
+ {hi: 0xb7118682dbb66a77, lo: 0x3fbc8c33221dc2a1, exp2: 693}, // 1e247
+ {hi: 0xe4d5e82392a40515, lo: 0x0fabaf3feaa5334a, exp2: 696}, // 1e248
+ {hi: 0x8f05b1163ba6832d, lo: 0x29cb4d87f2a7400e, exp2: 700}, // 1e249
+ {hi: 0xb2c71d5bca9023f8, lo: 0x743e20e9ef511012, exp2: 703}, // 1e250
+ {hi: 0xdf78e4b2bd342cf6, lo: 0x914da9246b255416, exp2: 706}, // 1e251
+ {hi: 0x8bab8eefb6409c1a, lo: 0x1ad089b6c2f7548e, exp2: 710}, // 1e252
+ {hi: 0xae9672aba3d0c320, lo: 0xa184ac2473b529b1, exp2: 713}, // 1e253
+ {hi: 0xda3c0f568cc4f3e8, lo: 0xc9e5d72d90a2741e, exp2: 716}, // 1e254
+ {hi: 0x8865899617fb1871, lo: 0x7e2fa67c7a658892, exp2: 720}, // 1e255
+ {hi: 0xaa7eebfb9df9de8d, lo: 0xddbb901b98feeab7, exp2: 723}, // 1e256
+ {hi: 0xd51ea6fa85785631, lo: 0x552a74227f3ea565, exp2: 726}, // 1e257
+ {hi: 0x8533285c936b35de, lo: 0xd53a88958f87275f, exp2: 730}, // 1e258
+ {hi: 0xa67ff273b8460356, lo: 0x8a892abaf368f137, exp2: 733}, // 1e259
+ {hi: 0xd01fef10a657842c, lo: 0x2d2b7569b0432d85, exp2: 736}, // 1e260
+ {hi: 0x8213f56a67f6b29b, lo: 0x9c3b29620e29fc73, exp2: 740}, // 1e261
+ {hi: 0xa298f2c501f45f42, lo: 0x8349f3ba91b47b8f, exp2: 743}, // 1e262
+ {hi: 0xcb3f2f7642717713, lo: 0x241c70a936219a73, exp2: 746}, // 1e263
+ {hi: 0xfe0efb53d30dd4d7, lo: 0xed238cd383aa0110, exp2: 749}, // 1e264
+ {hi: 0x9ec95d1463e8a506, lo: 0xf4363804324a40aa, exp2: 753}, // 1e265
+ {hi: 0xc67bb4597ce2ce48, lo: 0xb143c6053edcd0d5, exp2: 756}, // 1e266
+ {hi: 0xf81aa16fdc1b81da, lo: 0xdd94b7868e94050a, exp2: 759}, // 1e267
+ {hi: 0x9b10a4e5e9913128, lo: 0xca7cf2b4191c8326, exp2: 763}, // 1e268
+ {hi: 0xc1d4ce1f63f57d72, lo: 0xfd1c2f611f63a3f0, exp2: 766}, // 1e269
+ {hi: 0xf24a01a73cf2dccf, lo: 0xbc633b39673c8cec, exp2: 769}, // 1e270
+ {hi: 0x976e41088617ca01, lo: 0xd5be0503e085d813, exp2: 773}, // 1e271
+ {hi: 0xbd49d14aa79dbc82, lo: 0x4b2d8644d8a74e18, exp2: 776}, // 1e272
+ {hi: 0xec9c459d51852ba2, lo: 0xddf8e7d60ed1219e, exp2: 779}, // 1e273
+ {hi: 0x93e1ab8252f33b45, lo: 0xcabb90e5c942b503, exp2: 783}, // 1e274
+ {hi: 0xb8da1662e7b00a17, lo: 0x3d6a751f3b936243, exp2: 786}, // 1e275
+ {hi: 0xe7109bfba19c0c9d, lo: 0x0cc512670a783ad4, exp2: 789}, // 1e276
+ {hi: 0x906a617d450187e2, lo: 0x27fb2b80668b24c5, exp2: 793}, // 1e277
+ {hi: 0xb484f9dc9641e9da, lo: 0xb1f9f660802dedf6, exp2: 796}, // 1e278
+ {hi: 0xe1a63853bbd26451, lo: 0x5e7873f8a0396973, exp2: 799}, // 1e279
+ {hi: 0x8d07e33455637eb2, lo: 0xdb0b487b6423e1e8, exp2: 803}, // 1e280
+ {hi: 0xb049dc016abc5e5f, lo: 0x91ce1a9a3d2cda62, exp2: 806}, // 1e281
+ {hi: 0xdc5c5301c56b75f7, lo: 0x7641a140cc7810fb, exp2: 809}, // 1e282
+ {hi: 0x89b9b3e11b6329ba, lo: 0xa9e904c87fcb0a9d, exp2: 813}, // 1e283
+ {hi: 0xac2820d9623bf429, lo: 0x546345fa9fbdcd44, exp2: 816}, // 1e284
+ {hi: 0xd732290fbacaf133, lo: 0xa97c177947ad4095, exp2: 819}, // 1e285
+ {hi: 0x867f59a9d4bed6c0, lo: 0x49ed8eabcccc485d, exp2: 823}, // 1e286
+ {hi: 0xa81f301449ee8c70, lo: 0x5c68f256bfff5a74, exp2: 826}, // 1e287
+ {hi: 0xd226fc195c6a2f8c, lo: 0x73832eec6fff3111, exp2: 829}, // 1e288
+ {hi: 0x83585d8fd9c25db7, lo: 0xc831fd53c5ff7eab, exp2: 833}, // 1e289
+ {hi: 0xa42e74f3d032f525, lo: 0xba3e7ca8b77f5e55, exp2: 836}, // 1e290
+ {hi: 0xcd3a1230c43fb26f, lo: 0x28ce1bd2e55f35eb, exp2: 839}, // 1e291
+ {hi: 0x80444b5e7aa7cf85, lo: 0x7980d163cf5b81b3, exp2: 843}, // 1e292
+ {hi: 0xa0555e361951c366, lo: 0xd7e105bcc332621f, exp2: 846}, // 1e293
+ {hi: 0xc86ab5c39fa63440, lo: 0x8dd9472bf3fefaa7, exp2: 849}, // 1e294
+ {hi: 0xfa856334878fc150, lo: 0xb14f98f6f0feb951, exp2: 852}, // 1e295
+ {hi: 0x9c935e00d4b9d8d2, lo: 0x6ed1bf9a569f33d3, exp2: 856}, // 1e296
+ {hi: 0xc3b8358109e84f07, lo: 0x0a862f80ec4700c8, exp2: 859}, // 1e297
+ {hi: 0xf4a642e14c6262c8, lo: 0xcd27bb612758c0fa, exp2: 862}, // 1e298
+ {hi: 0x98e7e9cccfbd7dbd, lo: 0x8038d51cb897789c, exp2: 866}, // 1e299
+ {hi: 0xbf21e44003acdd2c, lo: 0xe0470a63e6bd56c3, exp2: 869}, // 1e300
+ {hi: 0xeeea5d5004981478, lo: 0x1858ccfce06cac74, exp2: 872}, // 1e301
+ {hi: 0x95527a5202df0ccb, lo: 0x0f37801e0c43ebc8, exp2: 876}, // 1e302
+ {hi: 0xbaa718e68396cffd, lo: 0xd30560258f54e6ba, exp2: 879}, // 1e303
+ {hi: 0xe950df20247c83fd, lo: 0x47c6b82ef32a2069, exp2: 882}, // 1e304
+ {hi: 0x91d28b7416cdd27e, lo: 0x4cdc331d57fa5441, exp2: 886}, // 1e305
+ {hi: 0xb6472e511c81471d, lo: 0xe0133fe4adf8e952, exp2: 889}, // 1e306
+ {hi: 0xe3d8f9e563a198e5, lo: 0x58180fddd97723a6, exp2: 892}, // 1e307
+ {hi: 0x8e679c2f5e44ff8f, lo: 0x570f09eaa7ea7648, exp2: 896}, // 1e308
+ {hi: 0xb201833b35d63f73, lo: 0x2cd2cc6551e513da, exp2: 899}, // 1e309
+ {hi: 0xde81e40a034bcf4f, lo: 0xf8077f7ea65e58d1, exp2: 902}, // 1e310
+ {hi: 0x8b112e86420f6191, lo: 0xfb04afaf27faf782, exp2: 906}, // 1e311
+ {hi: 0xadd57a27d29339f6, lo: 0x79c5db9af1f9b563, exp2: 909}, // 1e312
+ {hi: 0xd94ad8b1c7380874, lo: 0x18375281ae7822bc, exp2: 912}, // 1e313
+ {hi: 0x87cec76f1c830548, lo: 0x8f2293910d0b15b5, exp2: 916}, // 1e314
+ {hi: 0xa9c2794ae3a3c69a, lo: 0xb2eb3875504ddb22, exp2: 919}, // 1e315
+ {hi: 0xd433179d9c8cb841, lo: 0x5fa60692a46151eb, exp2: 922}, // 1e316
+ {hi: 0x849feec281d7f328, lo: 0xdbc7c41ba6bcd333, exp2: 926}, // 1e317
+ {hi: 0xa5c7ea73224deff3, lo: 0x12b9b522906c0800, exp2: 929}, // 1e318
+ {hi: 0xcf39e50feae16bef, lo: 0xd768226b34870a00, exp2: 932}, // 1e319
+ {hi: 0x81842f29f2cce375, lo: 0xe6a1158300d46640, exp2: 936}, // 1e320
+ {hi: 0xa1e53af46f801c53, lo: 0x60495ae3c1097fd0, exp2: 939}, // 1e321
+ {hi: 0xca5e89b18b602368, lo: 0x385bb19cb14bdfc4, exp2: 942}, // 1e322
+ {hi: 0xfcf62c1dee382c42, lo: 0x46729e03dd9ed7b5, exp2: 945}, // 1e323
+ {hi: 0x9e19db92b4e31ba9, lo: 0x6c07a2c26a8346d1, exp2: 949}, // 1e324
+ {hi: 0xc5a05277621be293, lo: 0xc7098b7305241885, exp2: 952}, // 1e325
+ {hi: 0xf70867153aa2db38, lo: 0xb8cbee4fc66d1ea7, exp2: 955}, // 1e326
+ {hi: 0x9a65406d44a5c903, lo: 0x737f74f1dc043328, exp2: 959}, // 1e327
+ {hi: 0xc0fe908895cf3b44, lo: 0x505f522e53053ff2, exp2: 962}, // 1e328
+ {hi: 0xf13e34aabb430a15, lo: 0x647726b9e7c68fef, exp2: 965}, // 1e329
+ {hi: 0x96c6e0eab509e64d, lo: 0x5eca783430dc19f5, exp2: 969}, // 1e330
+ {hi: 0xbc789925624c5fe0, lo: 0xb67d16413d132072, exp2: 972}, // 1e331
+ {hi: 0xeb96bf6ebadf77d8, lo: 0xe41c5bd18c57e88f, exp2: 975}, // 1e332
+ {hi: 0x933e37a534cbaae7, lo: 0x8e91b962f7b6f159, exp2: 979}, // 1e333
+ {hi: 0xb80dc58e81fe95a1, lo: 0x723627bbb5a4adb0, exp2: 982}, // 1e334
+ {hi: 0xe61136f2227e3b09, lo: 0xcec3b1aaa30dd91c, exp2: 985}, // 1e335
+ {hi: 0x8fcac257558ee4e6, lo: 0x213a4f0aa5e8a7b1, exp2: 989}, // 1e336
+ {hi: 0xb3bd72ed2af29e1f, lo: 0xa988e2cd4f62d19d, exp2: 992}, // 1e337
+ {hi: 0xe0accfa875af45a7, lo: 0x93eb1b80a33b8605, exp2: 995}, // 1e338
+ {hi: 0x8c6c01c9498d8b88, lo: 0xbc72f130660533c3, exp2: 999}, // 1e339
+ {hi: 0xaf87023b9bf0ee6a, lo: 0xeb8fad7c7f8680b4, exp2: 1002}, // 1e340
+ {hi: 0xdb68c2ca82ed2a05, lo: 0xa67398db9f6820e1, exp2: 1005}, // 1e341
+ {hi: 0x892179be91d43a43, lo: 0x88083f8943a1148c, exp2: 1009}, // 1e342
+ {hi: 0xab69d82e364948d4, lo: 0x6a0a4f6b948959b0, exp2: 1012}, // 1e343
+ {hi: 0xd6444e39c3db9b09, lo: 0x848ce34679abb01c, exp2: 1015}, // 1e344
+ {hi: 0x85eab0e41a6940e5, lo: 0xf2d80e0c0c0b4e11, exp2: 1019}, // 1e345
+ {hi: 0xa7655d1d2103911f, lo: 0x6f8e118f0f0e2195, exp2: 1022}, // 1e346
+ {hi: 0xd13eb46469447567, lo: 0x4b7195f2d2d1a9fb, exp2: 1025}, // 1e347
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/ptr.go b/vendor/github.com/goccy/go-json/internal/decoder/ptr.go
index ae2299466..701640e14 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/ptr.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/ptr.go
@@ -2,68 +2,80 @@ package decoder
import (
"fmt"
+ "reflect"
"unsafe"
-
- "github.com/goccy/go-json/internal/runtime"
)
type ptrDecoder struct {
dec Decoder
- typ *runtime.Type
+ typ reflect.Type
structName string
fieldName string
}
-func newPtrDecoder(dec Decoder, typ *runtime.Type, structName, fieldName string) *ptrDecoder {
- return &ptrDecoder{
+// newPtrDecoder returns the decoder of a pointer to typ: a basicPtrDecoder if typ has an allocator of its own
+// ( see allocatorOf ), and else a ptrDecoder.
+func newPtrDecoder(dec Decoder, typ reflect.Type, structName, fieldName string) Decoder {
+ d := ptrDecoder{
dec: dec,
typ: typ,
structName: structName,
fieldName: fieldName,
}
+ if alloc := allocatorOf(typ); alloc != nil {
+ return &basicPtrDecoder{ptrDecoder: d, alloc: alloc}
+ }
+ return &d
}
func (d *ptrDecoder) contentDecoder() Decoder {
- dec, ok := d.dec.(*ptrDecoder)
- if !ok {
- return d.dec
+ switch dec := d.dec.(type) {
+ case *ptrDecoder:
+ return dec.contentDecoder()
+ case *basicPtrDecoder:
+ return dec.contentDecoder()
}
- return dec.contentDecoder()
-}
-
-//nolint:golint
-//go:linkname unsafe_New reflect.unsafe_New
-func unsafe_New(*runtime.Type) unsafe.Pointer
-
-func UnsafeNew(t *runtime.Type) unsafe.Pointer {
- return unsafe_New(t)
+ return d.dec
}
-func (d *ptrDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- if s.skipWhiteSpace() == nul {
- s.read()
- }
- if s.char() == 'n' {
- if err := nullBytes(s); err != nil {
- return err
+func (d *ptrDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == 'n' {
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
}
- *(*unsafe.Pointer)(p) = nil
- return nil
+ if p != nil {
+ *(*unsafe.Pointer)(p) = nil
+ }
+ cursor += 4
+ return cursor, nil
}
var newptr unsafe.Pointer
if *(*unsafe.Pointer)(p) == nil {
- newptr = unsafe_New(d.typ)
+ newptr = newValue(d.typ)
*(*unsafe.Pointer)(p) = newptr
} else {
newptr = *(*unsafe.Pointer)(p)
}
- if err := d.dec.DecodeStream(s, depth, newptr); err != nil {
- return err
+ c, err := d.dec.Decode(ctx, cursor, depth, newptr)
+ if err != nil {
+ *(*unsafe.Pointer)(p) = nil
+ return 0, err
}
- return nil
+ cursor = c
+ return cursor, nil
}
-func (d *ptrDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+// basicPtrDecoder is the decoder of a pointer to a type which has an allocator of its own ( see allocatorOf ),
+// which allocates the value a nil pointer is set to. It is a type of its own, so that the decoder of a pointer
+// to any other type is the one it was.
+type basicPtrDecoder struct {
+ ptrDecoder
+ alloc func() unsafe.Pointer
+}
+
+func (d *basicPtrDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
if buf[cursor] == 'n' {
@@ -73,23 +85,19 @@ func (d *ptrDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.P
if p != nil {
*(*unsafe.Pointer)(p) = nil
}
- cursor += 4
- return cursor, nil
+ return cursor + 4, nil
}
- var newptr unsafe.Pointer
- if *(*unsafe.Pointer)(p) == nil {
- newptr = unsafe_New(d.typ)
+ newptr := *(*unsafe.Pointer)(p)
+ if newptr == nil {
+ newptr = d.alloc()
*(*unsafe.Pointer)(p) = newptr
- } else {
- newptr = *(*unsafe.Pointer)(p)
}
c, err := d.dec.Decode(ctx, cursor, depth, newptr)
if err != nil {
*(*unsafe.Pointer)(p) = nil
return 0, err
}
- cursor = c
- return cursor, nil
+ return c, nil
}
func (d *ptrDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/reflect.go b/vendor/github.com/goccy/go-json/internal/decoder/reflect.go
new file mode 100644
index 000000000..9ea78d185
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/reflect.go
@@ -0,0 +1,81 @@
+package decoder
+
+import (
+ "reflect"
+ "time"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// The decoders allocate and assign values through the reflect package, never through the internal
+// functions of the runtime: the pointers to the type descriptors they need are computed once, when
+// a decoder is compiled.
+
+// valueAt returns the addressable reflect.Value of the value at p, whose pointer type is ptrType
+// ( the type descriptor of *T for a value of T ). It is reflect.NewAt(T, p).Elem() without the lookup
+// of the pointer type which reflect.NewAt does for every call.
+func valueAt(ptrType, p unsafe.Pointer) reflect.Value {
+ return reflect.ValueOf(*(*any)(unsafe.Pointer(&emptyInterface{typ: ptrType, ptr: p}))).Elem()
+}
+
+// ptrTypeOf returns the type descriptor of *typ.
+func ptrTypeOf(typ reflect.Type) unsafe.Pointer {
+ return runtime.TypePtr(reflect.PointerTo(typ))
+}
+
+// newValue allocates a zero value of typ.
+func newValue(typ reflect.Type) unsafe.Pointer {
+ return reflect.New(typ).UnsafePointer()
+}
+
+// allocatorOf returns the function which allocates a zero value of typ, for a decoder which allocates one for
+// every value it decodes, as the one of a pointer does. For the kinds of the basic types it is new of the basic
+// type of the kind, whose layout, pointers included, is the one of typ whatever its name; for time.Time, it is
+// new of it. They cost less than reflect.New, which looks up the pointer type of typ at every call. It is nil
+// for any other type, whose pointer is decoded by ptrDecoder, which allocates by newValue ( see basicPtrDecoder ).
+func allocatorOf(typ reflect.Type) func() unsafe.Pointer {
+ if typ == reflect.TypeOf(time.Time{}) {
+ return func() unsafe.Pointer { return unsafe.Pointer(new(time.Time)) }
+ }
+ switch typ.Kind() {
+ case reflect.Bool:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(bool)) }
+ case reflect.Int:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(int)) }
+ case reflect.Int8:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(int8)) }
+ case reflect.Int16:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(int16)) }
+ case reflect.Int32:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(int32)) }
+ case reflect.Int64:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(int64)) }
+ case reflect.Uint:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uint)) }
+ case reflect.Uint8:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uint8)) }
+ case reflect.Uint16:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uint16)) }
+ case reflect.Uint32:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uint32)) }
+ case reflect.Uint64:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uint64)) }
+ case reflect.Uintptr:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(uintptr)) }
+ case reflect.Float32:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(float32)) }
+ case reflect.Float64:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(float64)) }
+ case reflect.Complex64:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(complex64)) }
+ case reflect.Complex128:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(complex128)) }
+ case reflect.String:
+ return func() unsafe.Pointer { return unsafe.Pointer(new(string)) }
+ }
+ return nil
+}
+
+// zeroBase is the address of the data of an empty slice which is not nil.
+var zeroBase [0]byte
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan.go b/vendor/github.com/goccy/go-json/internal/decoder/scan.go
new file mode 100644
index 000000000..23cfd403d
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan.go
@@ -0,0 +1,238 @@
+package decoder
+
+import (
+ "encoding/binary"
+ "math/bits"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+const (
+ lsb = 0x0101010101010101
+ msb = 0x8080808080808080
+ // bit5 is the bit which distinguishes '{' from '[' and '}' from ']'.
+ bit5 = 0x2020202020202020
+
+ // scanBlockSize is the number of the bytes the masks of a scan cover.
+ scanBlockSize = 64
+ // shortScanLength is the number of the bytes a scan looks at one by one before it works by blocks.
+ shortScanLength = 16
+)
+
+// NewInput returns the buffer which the decoders decode: a copy of the input followed by a nul byte,
+// which ends every scan.
+func NewInput(data []byte) []byte {
+ buf := make([]byte, len(data)+1)
+ copy(buf, data)
+ return buf
+}
+
+// load64 returns the eight bytes at pos as a little-endian word, whatever the byte order of the machine:
+// the masks made from a word give the position of a byte by the count of the trailing zeros.
+// It compiles to a single load on a little-endian machine.
+func load64(buf []byte, pos int64) uint64 {
+ return binary.LittleEndian.Uint64((*[8]byte)(unsafe.Add((*sliceHeader)(unsafe.Pointer(&buf)).data, pos))[:])
+}
+
+// byteMask returns the word whose byte is 0x80 where the byte of w is c, and 0 elsewhere.
+func byteMask(w, c uint64) uint64 {
+ x := w ^ (c * lsb)
+ return ^(((x & ^uint64(msb)) + ^uint64(msb)) | x) & msb
+}
+
+// scanMasks are the masks of a block of scanBlockSize bytes: bit i of a mask is set if the byte i
+// of the block is the character. The brackets are folded: open is '{' or '[' and closing is '}' or ']'.
+type scanMasks struct {
+ quote uint64
+ backslash uint64
+ open uint64
+ closing uint64
+}
+
+// scanBlockWords computes the masks of the block at p by words, eight bytes at a time.
+// It is what the architectures without a SIMD scan use.
+func scanBlockWords(p unsafe.Pointer, m *scanMasks) {
+ var quote, backslash, open, closing uint64
+ for i := 0; i < scanBlockSize/8; i++ {
+ w := binary.LittleEndian.Uint64((*[8]byte)(unsafe.Add(p, i*8))[:])
+ folded := w &^ bit5
+ shift := uint(i * 8)
+ quote |= gatherMask(byteMask(w, '"')) << shift
+ backslash |= gatherMask(byteMask(w, '\\')) << shift
+ open |= gatherMask(byteMask(folded, '[')) << shift
+ closing |= gatherMask(byteMask(folded, ']')) << shift
+ }
+ m.quote, m.backslash, m.open, m.closing = quote, backslash, open, closing
+}
+
+// gatherMask turns a mask of 0x80 bytes into the byte whose bit i is the byte i of the mask.
+func gatherMask(m uint64) uint64 {
+ return ((m >> 7) * 0x0102040810204080) >> 56
+}
+
+// compoundScanner finds the end of an object or an array without decoding it: the position after
+// the bracket which closes it. It keeps its state between the calls of scan, so that a stream may
+// scan what it has read so far and go on after reading more.
+//
+// The bytes are scanned a block at a time, by their masks ( scanMasks ): the quotes which are not
+// escaped toggle whether the bytes are inside a string, which a prefix xor of the quote mask tells
+// for every byte at once, and the brackets outside strings count the depth. The bytes are looked at
+// one by one only in a block where the value may end or the nesting may get too deep.
+type compoundScanner struct {
+ // depth is the number of the brackets opened but not closed.
+ depth int64
+ // maxDepth is the depth beyond which the nesting is too deep.
+ maxDepth int64
+ inString bool
+ // escaped is whether the next byte is escaped by the backslash before it.
+ escaped bool
+}
+
+// scan scans buf[pos:lim] and returns the position after the bracket which closes the value, or,
+// when the value doesn't end before lim, the position it stopped at and false.
+// A whole block is read at once where the capacity of the buffer has room for it.
+func (sc *compoundScanner) scan(buf []byte, pos, lim int64) (int64, bool, error) {
+ const evenBits = 0x5555555555555555
+ // A short value ends within a few bytes, which are looked at one by one: that costs less
+ // than the masks of a whole block.
+ pos, found, err := sc.scanBytes(buf, pos, min(pos+shortScanLength, lim))
+ if found || err != nil {
+ return pos, found, err
+ }
+ depth := sc.depth
+ var inString, prevEscaped uint64
+ if sc.inString {
+ inString = ^uint64(0)
+ }
+ if sc.escaped {
+ prevEscaped = 1
+ }
+ base := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ readable := int64(cap(buf))
+ for pos < lim {
+ if pos+scanBlockSize > readable {
+ // The buffer has no room for a block: its last bytes are looked at one by one.
+ sc.depth, sc.inString, sc.escaped = depth, inString != 0, prevEscaped != 0
+ return sc.scanBytes(buf, pos, lim)
+ }
+ var m scanMasks
+ scanBlock(unsafe.Add(base, pos), &m)
+ n := lim - pos
+ if n < scanBlockSize {
+ valid := uint64(1)<> uint(n)) & 1
+ } else {
+ prevEscaped = carry
+ }
+ // inside has the bytes which are inside a string after the byte itself is read:
+ // the parity of the quotes up to the byte, flipped if the block begins inside a string.
+ quote := m.quote &^ escaped
+ inside := quote
+ inside ^= inside << 1
+ inside ^= inside << 2
+ inside ^= inside << 4
+ inside ^= inside << 8
+ inside ^= inside << 16
+ inside ^= inside << 32
+ inside ^= inString
+ inString = uint64(int64(inside) >> 63) // the state after the last byte, in every bit
+ // An escaped byte is neither a quote nor a bracket, wherever it is.
+ outside := ^(inside | escaped)
+ open := m.open & outside
+ closing := m.closing & outside
+ opens := int64(bits.OnesCount64(open))
+ closes := int64(bits.OnesCount64(closing))
+ if closes < depth && depth+opens <= sc.maxDepth {
+ // the value can't end in this block, nor go too deep
+ depth += opens - closes
+ pos += scanBlockSize
+ continue
+ }
+ for brackets := open | closing; brackets != 0; brackets &= brackets - 1 {
+ i := bits.TrailingZeros64(brackets)
+ if open&(1< sc.maxDepth {
+ return 0, false, errors.ErrExceededMaxDepth(buf[pos+int64(i)], pos+int64(i))
+ }
+ } else {
+ depth--
+ if depth == 0 {
+ return pos + int64(i) + 1, true, nil
+ }
+ }
+ }
+ pos += scanBlockSize
+ }
+ sc.depth, sc.inString, sc.escaped = depth, inString != 0, prevEscaped != 0
+ return lim, false, nil
+}
+
+// scanBytes scans buf[pos:end] one byte at a time, as scan does by blocks.
+// A byte after a backslash is neither a quote nor a bracket, wherever it is.
+func (sc *compoundScanner) scanBytes(buf []byte, pos, end int64) (int64, bool, error) {
+ if pos >= end {
+ return pos, false, nil
+ }
+ depth, inString := sc.depth, sc.inString
+ if sc.escaped {
+ sc.escaped = false
+ pos++
+ }
+ for pos < end {
+ if inString {
+ for pos < end {
+ c := buf[pos]
+ pos++
+ if c == '"' {
+ inString = false
+ break
+ }
+ if c == '\\' {
+ pos++
+ }
+ }
+ continue
+ }
+ c := buf[pos]
+ pos++
+ switch c {
+ case '"':
+ inString = true
+ case '\\':
+ pos++
+ case '{', '[':
+ depth++
+ if depth > sc.maxDepth {
+ return 0, false, errors.ErrExceededMaxDepth(c, pos-1)
+ }
+ case '}', ']':
+ depth--
+ if depth == 0 {
+ return pos, true, nil
+ }
+ }
+ }
+ // A backslash as the last byte escapes the byte after end.
+ escaped := pos > end
+ if escaped {
+ pos = end
+ }
+ sc.depth, sc.inString, sc.escaped = depth, inString, escaped
+ return pos, false, nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.go b/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.go
new file mode 100644
index 000000000..ba0757739
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.go
@@ -0,0 +1,19 @@
+package decoder
+
+import (
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+//go:noescape
+func scanBlockAVX2(p unsafe.Pointer, m *scanMasks)
+
+// scanBlock computes the masks of the block at p: by AVX2 when the CPU has it, else by words.
+func scanBlock(p unsafe.Pointer, m *scanMasks) {
+ if runtime.HasAVX2 {
+ scanBlockAVX2(p, m)
+ return
+ }
+ scanBlockWords(p, m)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.s b/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.s
new file mode 100644
index 000000000..e2294ac50
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan_amd64.s
@@ -0,0 +1,54 @@
+#include "textflag.h"
+
+// MASK64 computes into R the 64-bit mask of the bytes of the block in Y0 ( the first 32 bytes ) and
+// Y1 ( the last 32 bytes ) which are equal to the byte broadcast in Yc, using Yt as a temporary and
+// Rt as a temporary register.
+//
+// Only VEX instructions are used: a legacy SSE instruction mixed with them costs a transition.
+#define MASK64(Yc, Yt, R, Rt) \
+ VPCMPEQB Yc, Y0, Yt \
+ VPMOVMSKB Yt, R \
+ VPCMPEQB Yc, Y1, Yt \
+ VPMOVMSKB Yt, Rt \
+ SHLQ $32, Rt \
+ ORQ Rt, R
+
+// func scanBlockAVX2(p unsafe.Pointer, m *scanMasks)
+//
+// It computes the masks of the 64 bytes at p: bit i of a mask is set if the byte i is the character.
+// The brackets are folded by clearing the bit 5, which makes '{' a '[' and '}' a ']'.
+TEXT ·scanBlockAVX2(SB), NOSPLIT, $0-16
+ MOVQ p+0(FP), SI
+ MOVQ m+8(FP), DI
+
+ VMOVDQU (SI), Y0
+ VMOVDQU 32(SI), Y1
+ VPBROADCASTB cQuote<>(SB), Y8
+ VPBROADCASTB cBackslash<>(SB), Y9
+ VPBROADCASTB cOpen<>(SB), Y10
+ VPBROADCASTB cClose<>(SB), Y11
+ VPBROADCASTB cFold<>(SB), Y12
+
+ MASK64(Y8, Y4, AX, BX)
+ MOVQ AX, 0(DI)
+ MASK64(Y9, Y4, AX, BX)
+ MOVQ AX, 8(DI)
+ VPAND Y12, Y0, Y0
+ VPAND Y12, Y1, Y1
+ MASK64(Y10, Y4, AX, BX)
+ MOVQ AX, 16(DI)
+ MASK64(Y11, Y4, AX, BX)
+ MOVQ AX, 24(DI)
+ VZEROUPPER
+ RET
+
+DATA cQuote<>+0(SB)/1, $0x22
+GLOBL cQuote<>(SB), RODATA|NOPTR, $1
+DATA cBackslash<>+0(SB)/1, $0x5c
+GLOBL cBackslash<>(SB), RODATA|NOPTR, $1
+DATA cOpen<>+0(SB)/1, $0x5b
+GLOBL cOpen<>(SB), RODATA|NOPTR, $1
+DATA cClose<>+0(SB)/1, $0x5d
+GLOBL cClose<>(SB), RODATA|NOPTR, $1
+DATA cFold<>+0(SB)/1, $0xdf
+GLOBL cFold<>(SB), RODATA|NOPTR, $1
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.go b/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.go
new file mode 100644
index 000000000..3d1fa4ad0
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.go
@@ -0,0 +1,11 @@
+package decoder
+
+import "unsafe"
+
+//go:noescape
+func scanBlockNEON(p unsafe.Pointer, m *scanMasks)
+
+// scanBlock computes the masks of the block at p, by NEON.
+func scanBlock(p unsafe.Pointer, m *scanMasks) {
+ scanBlockNEON(p, m)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.s b/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.s
new file mode 100644
index 000000000..194860ff5
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan_arm64.s
@@ -0,0 +1,60 @@
+#include "textflag.h"
+
+// MASK64 computes into R the 64-bit mask of the bytes of the block in V0..V3 which are equal to the byte
+// broadcast in Vc. Every lane of a compare is 0xff or 0: it is masked to the weight of the lane in its
+// byte of the mask ( V20: 1, 2, 4 ... 128, repeated ), and three pairwise additions sum the weights of
+// the eight lanes of every byte of the mask, in the order of the block.
+#define MASK64(Vc, R) \
+ VCMEQ Vc.B16, V0.B16, V4.B16 \
+ VCMEQ Vc.B16, V1.B16, V5.B16 \
+ VCMEQ Vc.B16, V2.B16, V6.B16 \
+ VCMEQ Vc.B16, V3.B16, V7.B16 \
+ VAND V20.B16, V4.B16, V4.B16 \
+ VAND V20.B16, V5.B16, V5.B16 \
+ VAND V20.B16, V6.B16, V6.B16 \
+ VAND V20.B16, V7.B16, V7.B16 \
+ VADDP V5.B16, V4.B16, V4.B16 \
+ VADDP V7.B16, V6.B16, V6.B16 \
+ VADDP V6.B16, V4.B16, V4.B16 \
+ VADDP V4.B16, V4.B16, V4.B16 \
+ VMOV V4.D[0], R
+
+// func scanBlockNEON(p unsafe.Pointer, m *scanMasks)
+//
+// It computes the masks of the 64 bytes at p: bit i of a mask is set if the byte i is the character.
+// The brackets are folded by clearing the bit 5, which makes '{' a '[' and '}' a ']'.
+TEXT ·scanBlockNEON(SB), NOSPLIT, $0-16
+ MOVD p+0(FP), R0
+ MOVD m+8(FP), R1
+
+ VLD1 (R0), [V0.B16, V1.B16, V2.B16, V3.B16]
+ MOVD $weights<>(SB), R2
+ VLD1 (R2), [V20.B16]
+ MOVD $0x22, R3
+ VMOV R3, V16.B16
+ MOVD $0x5c, R3
+ VMOV R3, V17.B16
+ MOVD $0x5b, R3
+ VMOV R3, V18.B16
+ MOVD $0x5d, R3
+ VMOV R3, V19.B16
+ MOVD $0xdf, R3
+ VMOV R3, V21.B16
+
+ MASK64(V16, R4)
+ MOVD R4, 0(R1)
+ MASK64(V17, R4)
+ MOVD R4, 8(R1)
+ VAND V21.B16, V0.B16, V0.B16
+ VAND V21.B16, V1.B16, V1.B16
+ VAND V21.B16, V2.B16, V2.B16
+ VAND V21.B16, V3.B16, V3.B16
+ MASK64(V18, R4)
+ MOVD R4, 16(R1)
+ MASK64(V19, R4)
+ MOVD R4, 24(R1)
+ RET
+
+DATA weights<>+0(SB)/8, $0x8040201008040201
+DATA weights<>+8(SB)/8, $0x8040201008040201
+GLOBL weights<>(SB), RODATA|NOPTR, $16
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/scan_other.go b/vendor/github.com/goccy/go-json/internal/decoder/scan_other.go
new file mode 100644
index 000000000..2ea3cd71d
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/scan_other.go
@@ -0,0 +1,10 @@
+//go:build !amd64 && !arm64
+
+package decoder
+
+import "unsafe"
+
+// scanBlock computes the masks of the block at p, by words: this architecture has no SIMD scan.
+func scanBlock(p unsafe.Pointer, m *scanMasks) {
+ scanBlockWords(p, m)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/skip.go b/vendor/github.com/goccy/go-json/internal/decoder/skip.go
new file mode 100644
index 000000000..19f0e2e70
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/skip.go
@@ -0,0 +1,598 @@
+package decoder
+
+import (
+ "math/bits"
+ "unsafe"
+)
+
+// The values which are not decoded, as the ones of the keys which match no field, are skipped by the grammar of
+// JSON, as encoding/json checks the whole input: a value which is not valid is a syntax error wherever it is.
+
+// skipState is where a skip of an object or an array is: what it looks for next.
+type skipState uint8
+
+const (
+ // skipValueStart looks for a value.
+ skipValueStart skipState = iota
+ // skipAfterValue looks for what follows a value: a comma or the end of the object or the array it is in.
+ skipAfterValue
+)
+
+// skipRestOfObject returns the position after the end of the object whose value ends at cursor, which it checks by
+// the grammar of JSON: nesting is how deep the object is nested in the input.
+func skipRestOfObject(buf []byte, cursor, nesting int64) (int64, error) {
+ return skipGrammarFast(buf, cursor, nesting-1, 1, 1, resumeAfterValue)
+}
+
+// skipResume is where skipFast resumes: at a value, after a value, or after the key of an object.
+type skipResume uint8
+
+const (
+ resumeValue skipResume = iota
+ resumeAfterValue
+ resumeAfterKey
+ // resumeKey is where a key is waited for, which skipFast doesn't resume at: it tells the error of the byte.
+ resumeKey
+)
+
+// skipEvent is why skipFast returns: the end of the value, or what it doesn't do itself, which its caller does
+// before it resumes it.
+type skipEvent uint8
+
+const (
+ skipDone skipEvent = iota
+ // skipAString is a string which has an escape or a control character, or is at the end of the buffer.
+ skipAString
+ // skipANumber is a number which starts with a minus sign or is not an integer.
+ skipANumber
+ // skipDeep is an object or an array deeper than the levels which the bits of a word hold.
+ skipDeep
+ // skipInvalid is a byte which the grammar doesn't have where it is, for which the caller makes the error.
+ skipInvalid
+)
+
+// skipGrammarFast skips the objects and the arrays which are open, level of them whose kinds are the bits of
+// objects, from cursor, where it resumes, by skipFast, which returns for what it doesn't do: a string with an
+// escape, a number which is not an integer, a byte which is not valid, which is done here, or an object or an array
+// deeper than 64 levels, which the rest of the value is skipped by skipGrammar for.
+func skipGrammarFast(buf []byte, cursor, nesting, level int64, objects uint64, resume skipResume) (int64, error) {
+ var ev skipEvent
+ cursor, level, objects, resume, ev = skipFast(buf, cursor, level, objects, resume, skipMaxLevel(nesting))
+ if ev == skipDone {
+ return cursor, nil
+ }
+ return skipGrammarEvent(buf, cursor, nesting, level, objects, resume, ev)
+}
+
+// skipMaxLevel returns the number of the levels of objects and arrays which skipFast opens at most, for a value
+// nested nesting levels deep.
+func skipMaxLevel(nesting int64) int64 {
+ return min(maxDecodeNestingDepth-nesting, 64)
+}
+
+// skipGrammarEvent does what skipFast stopped for at cursor, ev, and resumes it, up to the end of the value.
+func skipGrammarEvent(buf []byte, cursor, nesting, level int64, objects uint64, resume skipResume, ev skipEvent) (int64, error) {
+ maxLevel := skipMaxLevel(nesting)
+ for {
+ switch ev {
+ case skipDone:
+ return cursor, nil
+ case skipAString:
+ end, err := skipString(buf, cursor)
+ if err != nil {
+ return 0, stringError(buf, cursor, err)
+ }
+ cursor = end
+ case skipANumber:
+ end, err := skipNumber(buf, cursor)
+ if err != nil {
+ return 0, err
+ }
+ cursor = end
+ case skipDeep:
+ // the value at cursor opens the level 64, or the limit of the nesting
+ return skipGrammar(buf, cursor, nesting, level, objects, skipValueStart)
+ default:
+ return 0, skipFastError(buf, cursor, level, objects, resume)
+ }
+ cursor, level, objects, resume, ev = skipFast(buf, cursor, level, objects, resume, maxLevel)
+ }
+}
+
+// skipFastError returns the syntax error of the byte at cursor, which skipFast stopped at, where it resumes.
+func skipFastError(buf []byte, cursor, level int64, objects uint64, resume skipResume) error {
+ switch resume {
+ case resumeKey:
+ return syntaxErrorAt(buf, cursor, whereKey)
+ case resumeAfterKey:
+ return syntaxErrorAt(buf, cursor, whereAfterKey)
+ case resumeAfterValue:
+ if objects&(1< maxLevel {
+ return cursor, level, objects, resumeValue, skipDeep
+ }
+ if c == '{' {
+ objects |= 1 << uint(level)
+ } else {
+ objects &^= 1 << uint(level)
+ }
+ level++
+ cursor++
+ open := c
+ if c = char(b, cursor); c <= ' ' {
+ for isWhiteSpace[c] {
+ cursor++
+ c = char(b, cursor)
+ }
+ }
+ if open == '{' {
+ if c == '}' {
+ cursor++
+ goto closed
+ }
+ goto key
+ }
+ if c == ']' {
+ cursor++
+ goto closed
+ }
+ goto value
+ case '1', '2', '3', '4', '5', '6', '7', '8', '9':
+ start := cursor
+ cursor++
+ for char(b, cursor)-'0' <= 9 {
+ cursor++
+ }
+ if c := char(b, cursor); c == '.' || c == 'e' || c == 'E' {
+ // a number which is not an integer, which skipNumber checks from its start
+ return start, level, objects, resumeAfterValue, skipANumber
+ }
+ case '0':
+ if c := char(b, cursor+1); c == '.' || c == 'e' || c == 'E' {
+ return cursor, level, objects, resumeAfterValue, skipANumber
+ }
+ cursor++
+ case '-':
+ return cursor, level, objects, resumeAfterValue, skipANumber
+ case 't':
+ if char(b, cursor+1) != 'r' || char(b, cursor+2) != 'u' || char(b, cursor+3) != 'e' {
+ return cursor, level, objects, resumeValue, skipInvalid
+ }
+ cursor += 4
+ case 'f':
+ if char(b, cursor+1) != 'a' || char(b, cursor+2) != 'l' || char(b, cursor+3) != 's' || char(b, cursor+4) != 'e' {
+ return cursor, level, objects, resumeValue, skipInvalid
+ }
+ cursor += 5
+ case 'n':
+ if char(b, cursor+1) != 'u' || char(b, cursor+2) != 'l' || char(b, cursor+3) != 'l' {
+ return cursor, level, objects, resumeValue, skipInvalid
+ }
+ cursor += 4
+ default:
+ return cursor, level, objects, resumeValue, skipInvalid
+ }
+afterValue:
+ // a value here is in an object or an array: the value which skipFast starts at is one of them, and the end of
+ // the outermost is returned at closed
+ if c = char(b, cursor); c <= ' ' {
+ for isWhiteSpace[c] {
+ cursor++
+ c = char(b, cursor)
+ }
+ }
+ if objects&(1< maxLevel {
+ return 0, depthSyntaxError(buf, cursor)
+ }
+ if level < 64 {
+ if c == '{' {
+ objects |= 1 << uint(level)
+ } else {
+ objects &^= 1 << uint(level)
+ }
+ } else {
+ deeper = pushDeeper(deeper, level, c == '{')
+ }
+ level++
+ cursor++
+ for isWhiteSpace[char(b, cursor)] {
+ cursor++
+ }
+ if c == '{' {
+ if char(b, cursor) == '}' {
+ cursor++
+ level--
+ goto afterValue
+ }
+ goto key
+ }
+ if char(b, cursor) == ']' {
+ cursor++
+ level--
+ goto afterValue
+ }
+ goto value
+ case '"':
+ // a string of plain bytes up to its quote without a call, eight bytes at a time, and any other by
+ // skipString, which checks its escapes
+ for c := cursor + 1; c+8 <= length; c += 8 {
+ if special := keyEndBytes(load64(buf, c)); special != 0 {
+ if c += int64(bits.TrailingZeros64(special) / 8); char(b, c) == '"' {
+ cursor = c + 1
+ goto afterValue
+ }
+ break
+ }
+ }
+ end, err := skipString(buf, cursor)
+ if err != nil {
+ return 0, stringError(buf, cursor, err)
+ }
+ cursor = end
+ case '1', '2', '3', '4', '5', '6', '7', '8', '9':
+ // an integer, which most numbers are, without a call
+ start := cursor
+ cursor++
+ for char(b, cursor)-'0' <= 9 {
+ cursor++
+ }
+ if c := char(b, cursor); c == '.' || c == 'e' || c == 'E' {
+ end, err := skipNumberRest(buf, start, cursor)
+ if err != nil {
+ return 0, err
+ }
+ cursor = end
+ }
+ case '0':
+ start := cursor
+ cursor++
+ if c := char(b, cursor); c == '.' || c == 'e' || c == 'E' {
+ end, err := skipNumberRest(buf, start, cursor)
+ if err != nil {
+ return 0, err
+ }
+ cursor = end
+ }
+ case '-':
+ end, err := skipNumber(buf, cursor)
+ if err != nil {
+ return 0, err
+ }
+ cursor = end
+ case 't':
+ if char(b, cursor+1) != 'r' || char(b, cursor+2) != 'u' || char(b, cursor+3) != 'e' {
+ return 0, literalSyntaxError(buf, cursor, "true")
+ }
+ cursor += 4
+ case 'f':
+ if char(b, cursor+1) != 'a' || char(b, cursor+2) != 'l' || char(b, cursor+3) != 's' || char(b, cursor+4) != 'e' {
+ return 0, literalSyntaxError(buf, cursor, "false")
+ }
+ cursor += 5
+ case 'n':
+ if char(b, cursor+1) != 'u' || char(b, cursor+2) != 'l' || char(b, cursor+3) != 'l' {
+ return 0, literalSyntaxError(buf, cursor, "null")
+ }
+ cursor += 4
+ default:
+ return 0, syntaxErrorAt(buf, cursor, whereValue)
+ }
+afterValue:
+ if level == 0 {
+ return cursor, nil
+ }
+ for isWhiteSpace[char(b, cursor)] {
+ cursor++
+ }
+ if inObject(objects, deeper, level-1) {
+ switch char(b, cursor) {
+ case ',':
+ cursor++
+ for isWhiteSpace[char(b, cursor)] {
+ cursor++
+ }
+ goto key
+ case '}':
+ cursor++
+ level--
+ goto afterValue
+ }
+ return 0, syntaxErrorAt(buf, cursor, whereAfterPair)
+ }
+ switch char(b, cursor) {
+ case ',':
+ cursor++
+ goto value
+ case ']':
+ cursor++
+ level--
+ goto afterValue
+ }
+ return 0, syntaxErrorAt(buf, cursor, whereAfterElement)
+key:
+ if char(b, cursor) != '"' {
+ return 0, syntaxErrorAt(buf, cursor, whereKey)
+ }
+ // a key of plain bytes without a call, as the strings of the values
+ for c := cursor + 1; c+8 <= length; c += 8 {
+ if special := keyEndBytes(load64(buf, c)); special != 0 {
+ if c += int64(bits.TrailingZeros64(special) / 8); char(b, c) == '"' {
+ cursor = c + 1
+ goto afterKey
+ }
+ break
+ }
+ }
+ {
+ end, err := skipString(buf, cursor)
+ if err != nil {
+ return 0, stringError(buf, cursor, err)
+ }
+ cursor = end
+ }
+afterKey:
+ for isWhiteSpace[char(b, cursor)] {
+ cursor++
+ }
+ if char(b, cursor) != ':' {
+ return 0, syntaxErrorAt(buf, cursor, whereAfterKey)
+ }
+ cursor++
+ goto value
+}
+
+// inObject reports whether the value open at level is an object.
+func inObject(objects uint64, deeper []uint64, level int64) bool {
+ if level < 64 {
+ return objects&(1< 9 {
+ return 0, numberSyntaxError(buf, c, start, whereFraction)
+ }
+ c = skipDigits(buf, c)
+ }
+ if buf[c] == 'e' || buf[c] == 'E' {
+ c++
+ if buf[c] == '+' || buf[c] == '-' {
+ c++
+ }
+ if buf[c]-'0' > 9 {
+ return 0, numberSyntaxError(buf, c, start, whereExponent)
+ }
+ c = skipDigits(buf, c)
+ }
+ return c, nil
+}
+
+// stringError returns the syntax error of the string at cursor, which skipString failed with err, as encoding/json
+// has it.
+func stringError(buf []byte, cursor int64, err error) error {
+ if serr := stringSyntaxError(buf, cursor); serr != nil {
+ return serr
+ }
+ return err
+}
+
+// InputSyntaxError returns the first syntax error of the input of the decoding, as encoding/json reports it, or
+// nil if the input is valid: the decoders report a syntax error as they meet it, which this reports again as
+// encoding/json does, which checks the whole input first. The input is copied again, since the decoding writes
+// its buffer, as the escapes of the keys are decoded in it.
+func (ctx *RuntimeContext) InputSyntaxError() error {
+ return inputSyntaxError(NewInput(ctx.origin))
+}
+
+// inputSyntaxError returns the first syntax error of buf, the input followed by the nul byte, or nil.
+func inputSyntaxError(buf []byte) error {
+ end, err := skipValue(buf, skipWhiteSpace(buf, 0), 0)
+ if err != nil {
+ return err
+ }
+ return ValidateEnd(buf, end)
+}
+
+// Valid reports whether buf, the input followed by the nul byte, is a JSON value, by the grammar which the values
+// which are not decoded are skipped by.
+func Valid(buf []byte) bool {
+ end, err := skipValue(buf, skipWhiteSpace(buf, 0), 0)
+ return err == nil && skipWhiteSpace(buf, end) == int64(len(buf))-1
+}
+
+// ValidateEnd returns the syntax error of what follows the value which ends at cursor in buf, the input followed by
+// the nul byte: white spaces only may follow it, up to the end of the input. A nul byte in the input is a byte which
+// the grammar doesn't have there, as encoding/json has it.
+func ValidateEnd(buf []byte, cursor int64) error {
+ cursor = skipWhiteSpace(buf, cursor)
+ if cursor == int64(len(buf))-1 {
+ return nil
+ }
+ return syntaxErrorAt(buf, cursor, whereAfterTop)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/slice.go b/vendor/github.com/goccy/go-json/internal/decoder/slice.go
index 30a23e4b5..ff7a38653 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/slice.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/slice.go
@@ -3,27 +3,29 @@ package decoder
import (
"reflect"
"sync"
+ "sync/atomic"
"unsafe"
"github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
-)
-
-var (
- sliceType = runtime.Type2RType(
- reflect.TypeOf((*sliceHeader)(nil)).Elem(),
- )
- nilSlice = unsafe.Pointer(&sliceHeader{})
)
type sliceDecoder struct {
- elemType *runtime.Type
- isElemPointerType bool
- valueDecoder Decoder
- size uintptr
- arrayPool sync.Pool
- structName string
- fieldName string
+ elemType reflect.Type
+ // slicePtrType is the type descriptor of the pointer to the slice.
+ slicePtrType unsafe.Pointer
+ valueDecoder Decoder
+ size uintptr
+ // bufPool holds the buffers into which the elements of a long array are decoded before its length is known
+ // ( see decodeLong ). A buffer in the pool has only zero values, so that an element is decoded into a zero
+ // value.
+ bufPool sync.Pool
+ // lastLen is the length of the array which the decoder decoded last, which an empty slice is allocated for,
+ // up to inPlaceSliceLength: the arrays of a kind are often of a length. It is only a hint, for any goroutine.
+ lastLen atomic.Int32
+ structName string
+ fieldName string
+ // typ is the type of the slice, which the type errors report.
+ typ reflect.Type
}
// If use reflect.SliceHeader, data type is uintptr.
@@ -35,23 +37,31 @@ type sliceHeader struct {
cap int
}
+// sliceBuf is a buffer of the elements of a slice, allocated and grown by reflect.Value.Grow,
+// so that its memory has the type of the elements.
+type sliceBuf struct {
+ hdr sliceHeader
+}
+
const (
- defaultSliceCapacity = 2
+ // inPlaceSliceLength is the number of the elements of an array which are decoded into the slice itself, if it
+ // has no more capacity: most arrays are no longer, and the elements of a longer one are decoded into a buffer
+ // from there, so that its slice is allocated once, of its length.
+ inPlaceSliceLength = 64
+ // defaultSliceCapacity is the capacity of a new buffer of the elements.
+ defaultSliceCapacity = 4
)
-func newSliceDecoder(dec Decoder, elemType *runtime.Type, size uintptr, structName, fieldName string) *sliceDecoder {
+func newSliceDecoder(dec Decoder, elemType reflect.Type, size uintptr, structName, fieldName string) *sliceDecoder {
return &sliceDecoder{
- valueDecoder: dec,
- elemType: elemType,
- isElemPointerType: elemType.Kind() == reflect.Ptr || elemType.Kind() == reflect.Map,
- size: size,
- arrayPool: sync.Pool{
- New: func() interface{} {
- return &sliceHeader{
- data: newArray(elemType, defaultSliceCapacity),
- len: 0,
- cap: defaultSliceCapacity,
- }
+ typ: reflect.SliceOf(elemType),
+ valueDecoder: dec,
+ elemType: elemType,
+ slicePtrType: ptrTypeOf(reflect.SliceOf(elemType)),
+ size: size,
+ bufPool: sync.Pool{
+ New: func() any {
+ return &sliceBuf{}
},
},
structName: structName,
@@ -59,151 +69,91 @@ func newSliceDecoder(dec Decoder, elemType *runtime.Type, size uintptr, structNa
}
}
-func (d *sliceDecoder) newSlice(src *sliceHeader) *sliceHeader {
- slice := d.arrayPool.Get().(*sliceHeader)
- if src.len > 0 {
- // copy original elem
- if slice.cap < src.cap {
- data := newArray(d.elemType, src.cap)
- slice = &sliceHeader{data: data, len: src.len, cap: src.cap}
- } else {
- slice.len = src.len
- }
- copySlice(d.elemType, *slice, *src)
- } else {
- slice.len = 0
- }
- return slice
-}
-
-func (d *sliceDecoder) releaseSlice(p *sliceHeader) {
- d.arrayPool.Put(p)
+// sliceValue returns the reflect.Value of the slice whose header is at p.
+func (d *sliceDecoder) sliceValue(p *sliceHeader) reflect.Value {
+ return valueAt(d.slicePtrType, unsafe.Pointer(p))
}
-//go:linkname copySlice reflect.typedslicecopy
-func copySlice(elemType *runtime.Type, dst, src sliceHeader) int
-
-//go:linkname newArray reflect.unsafe_NewArray
-func newArray(*runtime.Type, int) unsafe.Pointer
-
-//go:linkname typedmemmove reflect.typedmemmove
-func typedmemmove(t *runtime.Type, dst, src unsafe.Pointer)
-
-func (d *sliceDecoder) errNumber(offset int64) *errors.UnmarshalTypeError {
- return &errors.UnmarshalTypeError{
- Value: "number",
- Type: reflect.SliceOf(runtime.RType2Type(d.elemType)),
- Struct: d.structName,
- Field: d.fieldName,
- Offset: offset,
+// grow makes the capacity of the slice at dst n or more, keeping its first length elements, as append does.
+func (d *sliceDecoder) grow(dst *sliceHeader, length, n int) {
+ if n <= dst.cap {
+ return
}
+ dst.len = length
+ if n < defaultSliceCapacity {
+ n = defaultSliceCapacity
+ }
+ d.sliceValue(dst).Grow(n - length)
}
-func (d *sliceDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
+// decodeLong decodes the elements of the array from cursor, the one at index n, which follows the n elements
+// decoded into the slice at dst, into a buffer whose length is not known yet, and stores them all into the slice,
+// allocated once, of their length. It is not inlined, so that Decode keeps the size it had: most arrays are shorter.
+//
+//go:noinline
+func (d *sliceDecoder) decodeLong(ctx *RuntimeContext, cursor, depth int64, dst *sliceHeader, n int) (int64, error) {
+ buf := ctx.Buf
+ elems := d.bufPool.Get().(*sliceBuf)
+ d.growBuf(elems, 0, 2*n)
+ elems.hdr.len = n
+ head := *dst
+ head.len = n
+ reflect.Copy(d.sliceValue(&elems.hdr), d.sliceValue(&head))
+ idx := n
+ for {
+ d.growBuf(elems, idx, idx+1)
+ ep := unsafe.Add(elems.hdr.data, uintptr(idx)*d.size)
+ c, err := d.valueDecoder.Decode(ctx, cursor, depth, ep)
+ if err != nil {
+ d.store(dst, elems, idx+1)
+ d.releaseBuf(elems, idx+1)
+ return 0, err
+ }
+ cursor = skipWhiteSpace(buf, c)
+ switch buf[cursor] {
+ case ']':
+ d.store(dst, elems, idx+1)
+ d.releaseBuf(elems, idx+1)
+ d.lastLen.Store(int32(min(idx+1, inPlaceSliceLength)))
+ return cursor + 1, nil
+ case ',':
+ idx++
+ default:
+ d.store(dst, elems, idx+1)
+ d.releaseBuf(elems, idx+1)
+ return 0, errors.ErrInvalidCharacter(buf[cursor], "slice", cursor)
+ }
+ cursor++
}
+}
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case 'n':
- if err := nullBytes(s); err != nil {
- return err
- }
- typedmemmove(sliceType, p, nilSlice)
- return nil
- case '[':
- s.cursor++
- if s.skipWhiteSpace() == ']' {
- dst := (*sliceHeader)(p)
- if dst.data == nil {
- dst.data = newArray(d.elemType, 0)
- } else {
- dst.len = 0
- }
- s.cursor++
- return nil
- }
- idx := 0
- slice := d.newSlice((*sliceHeader)(p))
- srcLen := slice.len
- capacity := slice.cap
- data := slice.data
- for {
- if capacity <= idx {
- src := sliceHeader{data: data, len: idx, cap: capacity}
- capacity *= 2
- data = newArray(d.elemType, capacity)
- dst := sliceHeader{data: data, len: idx, cap: capacity}
- copySlice(d.elemType, dst, src)
- }
- ep := unsafe.Pointer(uintptr(data) + uintptr(idx)*d.size)
+// growBuf makes the capacity of the buffer n or more, keeping its first length elements.
+// The elements after them are zero values.
+func (d *sliceDecoder) growBuf(buf *sliceBuf, length, n int) {
+ d.grow(&buf.hdr, length, n)
+}
- // if srcLen is greater than idx, keep the original reference
- if srcLen <= idx {
- if d.isElemPointerType {
- **(**unsafe.Pointer)(unsafe.Pointer(&ep)) = nil // initialize elem pointer
- } else {
- // assign new element to the slice
- typedmemmove(d.elemType, ep, unsafe_New(d.elemType))
- }
- }
+// releaseBuf clears the first n elements of the buffer, which are all it may have used,
+// and puts it back to the pool: it keeps nothing the decoded value refers to.
+func (d *sliceDecoder) releaseBuf(buf *sliceBuf, n int) {
+ if n > 0 {
+ buf.hdr.len = n
+ d.sliceValue(&buf.hdr).Clear()
+ }
+ buf.hdr.len = 0
+ d.bufPool.Put(buf)
+}
- if err := d.valueDecoder.DecodeStream(s, depth, ep); err != nil {
- return err
- }
- s.skipWhiteSpace()
- RETRY:
- switch s.char() {
- case ']':
- slice.cap = capacity
- slice.len = idx + 1
- slice.data = data
- dst := (*sliceHeader)(p)
- dst.len = idx + 1
- if dst.len > dst.cap {
- dst.data = newArray(d.elemType, dst.len)
- dst.cap = dst.len
- }
- copySlice(d.elemType, *dst, *slice)
- d.releaseSlice(slice)
- s.cursor++
- return nil
- case ',':
- idx++
- case nul:
- if s.read() {
- goto RETRY
- }
- slice.cap = capacity
- slice.data = data
- d.releaseSlice(slice)
- goto ERROR
- default:
- slice.cap = capacity
- slice.data = data
- d.releaseSlice(slice)
- goto ERROR
- }
- s.cursor++
- }
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return d.errNumber(s.totalOffset())
- case nul:
- if s.read() {
- continue
- }
- goto ERROR
- default:
- goto ERROR
- }
+// store copies the n elements of the buffer to the slice at dst: into its array when it has room
+// for them, or else into a new array of their length.
+func (d *sliceDecoder) store(dst *sliceHeader, buf *sliceBuf, n int) {
+ if dst.cap < n {
+ *dst = sliceHeader{}
+ d.sliceValue(dst).Grow(n)
}
-ERROR:
- return errors.ErrUnexpectedEndOfJSON("slice", s.totalOffset())
+ dst.len = n
+ buf.hdr.len = n
+ reflect.Copy(d.sliceValue(dst), d.sliceValue(&buf.hdr))
}
func (d *sliceDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
@@ -223,83 +173,75 @@ func (d *sliceDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe
return 0, err
}
cursor += 4
- typedmemmove(sliceType, p, nilSlice)
+ *(*sliceHeader)(p) = sliceHeader{}
return cursor, nil
case '[':
cursor++
cursor = skipWhiteSpace(buf, cursor)
+ dst := (*sliceHeader)(p)
if buf[cursor] == ']' {
- dst := (*sliceHeader)(p)
if dst.data == nil {
- dst.data = newArray(d.elemType, 0)
+ dst.data = unsafe.Pointer(&zeroBase)
} else {
dst.len = 0
}
cursor++
return cursor, nil
}
+ // The elements are decoded into the slice, which grows as append grows it: the elements of its array are
+ // decoded into, the ones after its length too, as encoding/json does. The elements beyond its capacity
+ // and inPlaceSliceLength are decoded into a buffer ( see decodeLong ).
+ limit := max(dst.cap, inPlaceSliceLength)
+ if dst.cap == 0 {
+ // the length of the last array, which an array of the kind is likely to have
+ if n := int(d.lastLen.Load()); n > 0 {
+ d.grow(dst, 0, min(n, inPlaceSliceLength))
+ }
+ }
idx := 0
- slice := d.newSlice((*sliceHeader)(p))
- srcLen := slice.len
- capacity := slice.cap
- data := slice.data
for {
- if capacity <= idx {
- src := sliceHeader{data: data, len: idx, cap: capacity}
- capacity *= 2
- data = newArray(d.elemType, capacity)
- dst := sliceHeader{data: data, len: idx, cap: capacity}
- copySlice(d.elemType, dst, src)
- }
- ep := unsafe.Pointer(uintptr(data) + uintptr(idx)*d.size)
- // if srcLen is greater than idx, keep the original reference
- if srcLen <= idx {
- if d.isElemPointerType {
- **(**unsafe.Pointer)(unsafe.Pointer(&ep)) = nil // initialize elem pointer
- } else {
- // assign new element to the slice
- typedmemmove(d.elemType, ep, unsafe_New(d.elemType))
- }
+ if idx == limit {
+ return d.decodeLong(ctx, cursor, depth, dst, idx)
}
+ d.grow(dst, idx, idx+1)
+ ep := unsafe.Add(dst.data, uintptr(idx)*d.size)
c, err := d.valueDecoder.Decode(ctx, cursor, depth, ep)
if err != nil {
+ dst.len = idx + 1
return 0, err
}
- cursor = c
- cursor = skipWhiteSpace(buf, cursor)
+ cursor = skipWhiteSpace(buf, c)
switch buf[cursor] {
case ']':
- slice.cap = capacity
- slice.len = idx + 1
- slice.data = data
- dst := (*sliceHeader)(p)
dst.len = idx + 1
- if dst.len > dst.cap {
- dst.data = newArray(d.elemType, dst.len)
- dst.cap = dst.len
- }
- copySlice(d.elemType, *dst, *slice)
- d.releaseSlice(slice)
+ d.lastLen.Store(int32(idx + 1))
cursor++
return cursor, nil
case ',':
idx++
default:
- slice.cap = capacity
- slice.data = data
- d.releaseSlice(slice)
+ dst.len = idx + 1
return 0, errors.ErrInvalidCharacter(buf[cursor], "slice", cursor)
}
cursor++
}
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return 0, d.errNumber(cursor)
default:
- return 0, errors.ErrUnexpectedEndOfJSON("slice", cursor)
+ return d.decodeOther(ctx, cursor, depth-1)
}
}
}
+// decodeOther skips the value at cursor, which is not an array: a value of another kind is a type error, and
+// anything else a syntax error. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *sliceDecoder) decodeOther(ctx *RuntimeContext, cursor, depth int64) (int64, error) {
+ if isOtherValue(ctx.Buf[cursor], arrayValue) {
+ return ctx.skipTypeError(cursor, depth, d.typ)
+ }
+ return 0, errors.ErrUnexpectedEndOfJSON("slice", cursor)
+}
+
func (d *sliceDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
buf := ctx.Buf
depth++
@@ -372,7 +314,7 @@ func (d *sliceDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][
cursor++
}
case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return nil, 0, d.errNumber(cursor)
+ return nil, 0, &errors.UnmarshalTypeError{Value: "number", Type: d.typ, Offset: cursor}
default:
return nil, 0, errors.ErrUnexpectedEndOfJSON("slice", cursor)
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/stream.go b/vendor/github.com/goccy/go-json/internal/decoder/stream.go
index a383f7259..97b5a98ea 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/stream.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/stream.go
@@ -2,555 +2,588 @@ package decoder
import (
"bytes"
- "encoding/json"
"io"
- "strconv"
+ "math/bits"
"unsafe"
"github.com/goccy/go-json/internal/errors"
+ "github.com/goccy/go-json/internal/runtime"
)
const (
+ // initBufSize is the size of the buffer of a new stream.
initBufSize = 512
+ // bufPadding is the number of the bytes kept free after the data in the buffer of a stream:
+ // one for the nul byte which ends the value being decoded, the rest so that a scan reads
+ // a whole block from any byte of the value.
+ bufPadding = scanBlockSize
)
+// Stream reads the values of a JSON text from an io.Reader one by one.
+//
+// A value is decoded by the same decoders as a byte slice is: the stream reads until its buffer
+// holds the whole value ( scanValue ), puts a nul byte after the value and lets the decoder work
+// on the buffer. The decoded strings refer to the buffer, so a byte which has been read is never
+// overwritten: when the buffer is full, the bytes which are not consumed yet are copied to a new one.
type Stream struct {
- buf []byte
- bufSize int64
- length int64
- r io.Reader
- offset int64
- cursor int64
- filledBuffer bool
- allRead bool
- UseNumber bool
- DisallowUnknownFields bool
- Option *Option
+ // buf[:length] is what has been read, buf[length] is nul, and bufPadding bytes are free at the end.
+ buf []byte
+ length int64
+ // cursor is the first byte which is not consumed yet.
+ cursor int64
+ // offset is the number of the bytes discarded before buf[0]: the total offset is offset + cursor.
+ offset int64
+ r io.Reader
+ // readErr is the error the reader returned. Once set, the reader is never read again:
+ // the data read before the error is consumed first, then the error is reported.
+ readErr error
+ ctx *RuntimeContext
+ Option *Option
+ // prevEnd is the total offset of the end of the previous value, which the offset of a type error may be
+ // relative to ( see StreamOffsetBase ).
+ prevEnd int64
+ // tokenState is where the stream is between the tokens, and tokenStack the states of the objects and the
+ // arrays which Token opened, the innermost last ( see Token ).
+ tokenState tokenState
+ tokenStack []tokenState
+ // err is the error which a read failed with, which every read returns after it, as encoding/json does, and
+ // errOffset the total offset which InputOffset reports after it: the end of the previous value.
+ err error
+ errOffset int64
+ // readStart is the total offset where the read of the value of Decode, or of the value of Token, started, and
+ // scanned the number of the bytes which these reads read before it, by which encoding/json before Go 1.27
+ // reports the offset of a syntax error of the value ( see scannedOffset ).
+ readStart int64
+ scanned int64
+ // more is what More peeked at, which InputOffset reports ( see streamPeek ).
+ more streamPeek
+ // keeps is set while the bytes from the total offset keepFrom are kept in the buffer, before the cursor too:
+ // a read of a token which fails leaves the stream where it was ( see Token ).
+ keeps bool
+ keepFrom int64
}
func NewStream(r io.Reader) *Stream {
+ opt := &Option{}
return &Stream{
- r: r,
- bufSize: initBufSize,
- buf: make([]byte, initBufSize),
- Option: &Option{},
+ r: r,
+ buf: make([]byte, initBufSize+bufPadding),
+ ctx: &RuntimeContext{Option: opt},
+ Option: opt,
}
}
-func (s *Stream) TotalOffset() int64 {
- return s.totalOffset()
-}
-
-func (s *Stream) Buffered() io.Reader {
- buflen := int64(len(s.buf))
- for i := s.cursor; i < buflen; i++ {
- if s.buf[i] == nul {
- return bytes.NewReader(s.buf[s.cursor:i])
- }
- }
- return bytes.NewReader(s.buf[s.cursor:])
+// markPrevEnd keeps the end of the previous value of the stream: the offsets of the type errors of the next value
+// may be relative to it ( see StreamOffsetBase ), and InputOffset reports it after a read which fails.
+func (s *Stream) markPrevEnd() {
+ s.prevEnd = s.offset + s.cursor
}
-func (s *Stream) PrepareForDecode() error {
- for {
- switch s.char() {
- case ' ', '\t', '\r', '\n':
- s.cursor++
- continue
- case ',', ':':
- s.cursor++
- return nil
- case nul:
- if s.read() {
- continue
- }
- return io.EOF
- }
- break
- }
- return nil
+// fail keeps err, the error which a read failed with, which every read returns after it, as encoding/json does.
+//
+//go:noinline
+func (s *Stream) fail(err error) error {
+ s.err, s.errOffset, s.tokenState = err, s.prevEnd, tokenFailed
+ return err
}
-func (s *Stream) totalOffset() int64 {
+// TotalOffset returns the number of the bytes consumed from the reader.
+func (s *Stream) TotalOffset() int64 {
return s.offset + s.cursor
}
-func (s *Stream) char() byte {
- return s.buf[s.cursor]
+// Buffered returns a reader of the data read from the reader but not consumed yet.
+func (s *Stream) Buffered() io.Reader {
+ return bytes.NewReader(s.buf[s.cursor:s.length])
}
-func (s *Stream) equalChar(c byte) bool {
- cur := s.buf[s.cursor]
- if cur == nul {
- s.read()
- cur = s.buf[s.cursor]
+// read reads more bytes from the reader into the buffer.
+// It returns false when nothing more can be read: the reader ended or failed ( readErr ).
+func (s *Stream) read() bool {
+ if s.readErr != nil {
+ return false
+ }
+ if int64(len(s.buf))-s.length <= bufPadding {
+ s.grow()
+ }
+ n, err := s.r.Read(s.buf[s.length : int64(len(s.buf))-bufPadding])
+ s.length += int64(n)
+ s.buf[s.length] = nul
+ if err != nil {
+ s.readErr = err
}
- return cur == c
+ return n > 0 || err == nil
}
-func (s *Stream) stat() ([]byte, int64, unsafe.Pointer) {
- return s.buf, s.cursor, (*sliceHeader)(unsafe.Pointer(&s.buf)).data
+// grow moves the bytes which are not consumed yet to a new buffer, so that the reader
+// has room to read into. The old buffer is left to the strings which refer to it.
+func (s *Stream) grow() {
+ // the bytes from the cursor are moved, or from the one which is kept before it
+ from := s.cursor
+ if keep := s.keepFrom - s.offset; s.keeps && keep >= 0 && keep < from {
+ from = keep
+ }
+ remain := s.length - from
+ size := int64(len(s.buf)) - bufPadding
+ if remain*2 > size {
+ // The data which is not consumed yet fills more than half of the buffer: it is a value
+ // larger than the buffer, which is grown faster so that it is copied fewer times.
+ size *= 4
+ }
+ if r, ok := s.r.(interface{ Len() int }); ok {
+ // The reader knows how much is left ( bytes.Reader, strings.Reader, bytes.Buffer ):
+ // the buffer holds all of it at once, so that nothing is copied again.
+ size = remain + int64(r.Len())
+ }
+ buf := make([]byte, size+bufPadding)
+ copy(buf, s.buf[from:s.length])
+ s.offset += from
+ s.buf = buf
+ s.length = remain
+ s.cursor -= from
}
-func (s *Stream) bufptr() unsafe.Pointer {
- return (*sliceHeader)(unsafe.Pointer(&s.buf)).data
+// fill makes sure that the buffer holds the byte at the cursor.
+func (s *Stream) fill() bool {
+ for s.cursor >= s.length {
+ if !s.read() {
+ return false
+ }
+ }
+ return true
}
-func (s *Stream) statForRetry() ([]byte, int64, unsafe.Pointer) {
- s.cursor-- // for retry ( because caller progress cursor position in each loop )
- return s.buf, s.cursor, (*sliceHeader)(unsafe.Pointer(&s.buf)).data
+// endError is the error reported when the reader has nothing more: io.EOF or what the reader returned.
+func (s *Stream) endError() error {
+ if s.readErr != nil {
+ return s.readErr
+ }
+ return io.EOF
}
-func (s *Stream) Reset() {
- s.reset()
- s.bufSize = int64(len(s.buf))
+// truncatedValueError is the error reported when the reader ends in the middle of the value at the cursor: the first
+// syntax error of what has been read, as encoding/json reads a value byte by byte, or the unexpected end.
+//
+//go:noinline
+func (s *Stream) truncatedValueError() error {
+ if err := s.valueSyntaxError(); err != nil {
+ return err
+ }
+ return s.unexpectedEndError()
}
-func (s *Stream) More() bool {
- for {
- switch s.char() {
- case ' ', '\n', '\r', '\t':
- s.cursor++
- continue
- case '}', ']':
- return false
- case nul:
- if s.read() {
- continue
- }
- return false
- }
- break
+// unexpectedEndError is the error reported when the reader ends in the middle of a value.
+func (s *Stream) unexpectedEndError() error {
+ if s.readErr != nil && s.readErr != io.EOF {
+ return s.readErr
}
- return true
+ return io.ErrUnexpectedEOF
}
-func (s *Stream) Token() (interface{}, error) {
+// skipWhiteSpace moves the cursor to the next byte which is not white space.
+// It returns false when the reader has nothing more.
+func (s *Stream) skipWhiteSpace() bool {
for {
- c := s.char()
- switch c {
- case ' ', '\n', '\r', '\t':
- s.cursor++
- case '{', '[', ']', '}':
- s.cursor++
- return json.Delim(c), nil
- case ',', ':':
+ if !s.fill() {
+ return false
+ }
+ switch s.buf[s.cursor] {
+ case ' ', '\n', '\t', '\r':
s.cursor++
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- bytes := floatBytes(s)
- str := *(*string)(unsafe.Pointer(&bytes))
- if s.UseNumber {
- return json.Number(str), nil
- }
- f64, err := strconv.ParseFloat(str, 64)
- if err != nil {
- return nil, err
- }
- return f64, nil
- case '"':
- bytes, err := stringBytes(s)
- if err != nil {
- return nil, err
- }
- return string(bytes), nil
- case 't':
- if err := trueBytes(s); err != nil {
- return nil, err
- }
- return true, nil
- case 'f':
- if err := falseBytes(s); err != nil {
- return nil, err
- }
- return false, nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case nul:
- if s.read() {
- continue
- }
- goto END
default:
- return nil, errors.ErrInvalidCharacter(s.char(), "token", s.totalOffset())
+ return true
}
}
-END:
- return nil, io.EOF
-}
-
-func (s *Stream) reset() {
- s.offset += s.cursor
- s.buf = s.buf[s.cursor:]
- s.length -= s.cursor
- s.cursor = 0
}
-func (s *Stream) readBuf() []byte {
- if s.filledBuffer {
- s.bufSize *= 2
- remainBuf := s.buf
- s.buf = make([]byte, s.bufSize)
- copy(s.buf, remainBuf)
- }
- remainLen := s.length - s.cursor
- remainNotNulCharNum := int64(0)
- for i := int64(0); i < remainLen; i++ {
- if s.buf[s.cursor+i] == nul {
- break
+// peek moves the cursor to the next byte which is not a white space, as skipWhiteSpace does, but leaves it where it
+// is when the input ends with white spaces only: the offset of the input doesn't count them, as encoding/json
+// doesn't count what it peeks at. It returns false when the reader has nothing more.
+func (s *Stream) peek() bool {
+ var rel int64
+ for {
+ // the position is kept relative to the cursor, because a read may move the data ( grow )
+ for pos := s.cursor + rel; pos < s.length; pos++ {
+ if !isWhiteSpace[s.buf[pos]] {
+ s.cursor = pos
+ return true
+ }
+ }
+ rel = s.length - s.cursor
+ if !s.read() {
+ return false
}
- remainNotNulCharNum++
}
- s.length = s.cursor + remainNotNulCharNum
- return s.buf[s.cursor+remainNotNulCharNum:]
}
-func (s *Stream) read() bool {
- if s.allRead {
- return false
- }
- buf := s.readBuf()
- last := len(buf) - 1
- buf[last] = nul
- n, err := s.r.Read(buf[:last])
- s.length += int64(n)
- if n == last {
- s.filledBuffer = true
- } else {
- s.filledBuffer = false
+// prepare moves the cursor to the beginning of the next value: the white space is skipped, and, between the
+// tokens of an object or an array, the comma or the colon which the grammar has before the value.
+func (s *Stream) prepare() error {
+ if s.tokenState != tokenTopValue {
+ return s.prepareInTokens()
}
- if err == io.EOF {
- s.allRead = true
- } else if err != nil {
- return false
+ s.readStart = s.offset + s.cursor
+ if !s.skipWhiteSpace() {
+ return s.fail(s.endError())
}
- return true
+ return nil
}
-func (s *Stream) skipWhiteSpace() byte {
- p := s.bufptr()
-LOOP:
- c := char(p, s.cursor)
- switch c {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- goto LOOP
- case nul:
- if s.read() {
- p = s.bufptr()
- goto LOOP
- }
+// isLiteralChar is true for the bytes of a number, true, false and null.
+var isLiteralChar = [256]bool{
+ '0': true, '1': true, '2': true, '3': true, '4': true, '5': true, '6': true, '7': true, '8': true, '9': true,
+ '-': true, '+': true, '.': true, 'e': true, 'E': true,
+ 't': true, 'r': true, 'u': true, 'f': true, 'a': true, 'l': true, 's': true, 'n': true,
+}
+
+// scanValue finds the end of the value which begins at the cursor, reading from the reader as needed,
+// and returns the position after the value. The value is not validated: the decoder does it.
+// The cursor is not moved: the value is in buf[cursor:end], but the buffer may have been replaced.
+func (s *Stream) scanValue() (int64, error) {
+ if !s.fill() {
+ return 0, s.endError()
+ }
+ switch c := s.buf[s.cursor]; {
+ case c == '{' || c == '[':
+ return s.scanCompound()
+ case c == '"':
+ return s.scanString()
+ case isLiteralChar[c]:
+ return s.scanLiteral()
}
- return c
+ // The decoder reports the invalid character.
+ return s.cursor + 1, nil
}
-func (s *Stream) skipObject(depth int64) error {
- braceCount := 1
- _, cursor, p := s.stat()
+// scanCompound finds the end of the object or the array at the cursor: the position after the bracket
+// which closes it.
+func (s *Stream) scanCompound() (int64, error) {
+ // The position is kept relative to the cursor, because a read may move the data ( grow ).
+ var rel int64
+ sc := compoundScanner{maxDepth: maxDecodeNestingDepth}
for {
- switch char(p, cursor) {
- case '{':
- braceCount++
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
- }
- case '}':
- braceCount--
- depth--
- if braceCount == 0 {
- s.cursor = cursor + 1
- return nil
- }
- case '[':
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
- }
- case ']':
- depth--
- case '"':
- for {
- cursor++
- switch char(p, cursor) {
- case '\\':
- cursor++
- if char(p, cursor) == nul {
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- case '"':
- goto SWITCH_OUT
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.statForRetry()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- }
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("object of object", cursor)
+ pos, found, err := sc.scan(s.buf, s.cursor+rel, s.length)
+ if err != nil {
+ return 0, s.totalOffsetError(err)
+ }
+ if found {
+ return pos, nil
+ }
+ rel = pos - s.cursor
+ if !s.read() {
+ return 0, s.truncatedValueError()
}
- SWITCH_OUT:
- cursor++
}
}
-func (s *Stream) skipArray(depth int64) error {
- bracketCount := 1
- _, cursor, p := s.stat()
+// scanString finds the end of the string at the cursor: the position after the quote which closes it.
+func (s *Stream) scanString() (int64, error) {
+ var (
+ rel int64 = 1 // after the opening quote
+ escaped bool
+ )
for {
- switch char(p, cursor) {
- case '[':
- bracketCount++
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
- }
- case ']':
- bracketCount--
- depth--
- if bracketCount == 0 {
- s.cursor = cursor + 1
- return nil
+ buf := s.buf
+ pos := s.cursor + rel
+ end := s.length
+ for pos+8 <= end {
+ w := load64(buf, pos)
+ if byteMask(w, '\\') != 0 || escaped {
+ break
}
- case '{':
- depth++
- if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
+ if quote := byteMask(w, '"'); quote != 0 {
+ return pos + int64(bits.TrailingZeros64(quote)/8) + 1, nil
}
- case '}':
- depth--
- case '"':
- for {
- cursor++
- switch char(p, cursor) {
- case '\\':
- cursor++
- if char(p, cursor) == nul {
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- case '"':
- goto SWITCH_OUT
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.statForRetry()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("string of object", cursor)
- }
- }
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
+ pos += 8
+ }
+ lim := min(pos+8, end)
+ for pos < lim {
+ c := buf[pos]
+ pos++
+ switch {
+ case escaped:
+ escaped = false
+ case c == '\\':
+ escaped = true
+ case c == '"':
+ return pos, nil
}
- return errors.ErrUnexpectedEndOfJSON("array of object", cursor)
}
- SWITCH_OUT:
- cursor++
+ rel = pos - s.cursor
+ if pos < end {
+ continue
+ }
+ if !s.read() {
+ return 0, s.truncatedValueError()
+ }
}
}
-func (s *Stream) skipValue(depth int64) error {
- _, cursor, p := s.stat()
+// scanLiteral finds the end of the number, true, false or null at the cursor: the position of
+// the first byte which can't belong to it, or the end of the input. The bytes may be more than one value, as 01 is
+// 0 and 1, which the decoder rejects: Decode then decodes the first alone ( see decodeError ).
+func (s *Stream) scanLiteral() (int64, error) {
+ var rel int64
for {
- switch char(p, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- continue
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("value of object", s.totalOffset())
- case '{':
- s.cursor = cursor + 1
- return s.skipObject(depth + 1)
- case '[':
- s.cursor = cursor + 1
- return s.skipArray(depth + 1)
- case '"':
- for {
- cursor++
- switch char(p, cursor) {
- case '\\':
- cursor++
- if char(p, cursor) == nul {
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("value of string", s.totalOffset())
- }
- case '"':
- s.cursor = cursor + 1
- return nil
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.statForRetry()
- continue
- }
- return errors.ErrUnexpectedEndOfJSON("value of string", s.totalOffset())
- }
+ buf := s.buf
+ pos := s.cursor + rel
+ end := s.length
+ for pos < end {
+ if !isLiteralChar[buf[pos]] {
+ return pos, nil
}
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- for {
- cursor++
- c := char(p, cursor)
- if floatTable[c] {
- continue
- } else if c == nul {
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- }
- s.cursor = cursor
- return nil
- }
- case 't':
- s.cursor = cursor
- if err := trueBytes(s); err != nil {
- return err
- }
- return nil
- case 'f':
- s.cursor = cursor
- if err := falseBytes(s); err != nil {
- return err
- }
- return nil
- case 'n':
- s.cursor = cursor
- if err := nullBytes(s); err != nil {
- return err
+ pos++
+ }
+ rel = pos - s.cursor
+ if !s.read() {
+ if s.readErr != io.EOF {
+ return 0, s.readErr
}
- return nil
+ return s.cursor + rel, nil
}
- cursor++
}
}
-func nullBytes(s *Stream) error {
- // current cursor's character is 'n'
- s.cursor++
- if s.char() != 'u' {
- if err := retryReadNull(s); err != nil {
- return err
+// streamNumberEnd returns the end of the number at start in buf[:lim] by the grammar of the numbers, which may be
+// cut there: what follows is not read yet, or is the next value.
+func streamNumberEnd(buf []byte, start, lim int64) int64 {
+ isDigit := func(i int64) bool { return i < lim && buf[i]-'0' <= 9 }
+ i := start
+ if buf[i] == '-' {
+ i++
+ }
+ if i < lim && buf[i] == '0' {
+ i++
+ } else {
+ for isDigit(i) {
+ i++
}
}
- s.cursor++
- if s.char() != 'l' {
- if err := retryReadNull(s); err != nil {
- return err
+ if i < lim && buf[i] == '.' {
+ for i++; isDigit(i); i++ {
}
}
- s.cursor++
- if s.char() != 'l' {
- if err := retryReadNull(s); err != nil {
- return err
+ if i < lim && (buf[i] == 'e' || buf[i] == 'E') {
+ i++
+ if i < lim && (buf[i] == '+' || buf[i] == '-') {
+ i++
+ }
+ for isDigit(i) {
+ i++
}
}
- s.cursor++
- return nil
+ return i
}
-func retryReadNull(s *Stream) error {
- if s.char() == nul && s.read() {
- return nil
+// DecoderOf returns the decoder of the type, from the recent decoders of the context of the stream.
+func (s *Stream) DecoderOf(typ unsafe.Pointer) (Decoder, error) {
+ return s.ctx.DecoderOf(typ)
+}
+
+// Decode decodes the next value of the stream into p, of the pointer type typ, by dec. If the value has a type
+// error, the stream goes on after the value, as the one of encoding/json does.
+func (s *Stream) Decode(dec Decoder, typ unsafe.Pointer, p unsafe.Pointer) error {
+ s.markPrevEnd()
+ if err := s.prepare(); err != nil {
+ return err
+ }
+ end, err := s.scanValue()
+ if err != nil {
+ return s.fail(err)
}
- return errors.ErrInvalidCharacter(s.char(), "null", s.totalOffset())
+ ctx := s.ctx
+ ctx.Option = s.Option
+ var cursor int64
+ if c := s.buf[s.cursor]; c != 't' && c != 'f' && c != 'n' {
+ // The end of the value is known exactly: a nul byte is put there while the value is decoded,
+ // so that the decoder never reads the next value, whatever it makes of a malformed one.
+ // A number needs it too, because the decoder validates the byte which ends it.
+ saved := s.buf[end]
+ s.buf[end] = nul
+ ctx.Buf = s.buf[:end+1]
+ cursor, err = dec.Decode(ctx, s.cursor, 0, p)
+ s.buf[end] = saved
+ } else {
+ // true, false and null end at the first byte which can't belong to them, and the decoder
+ // reports that byte when it is wrong: it sees the whole buffer, ended by the nul byte.
+ ctx.Buf = s.buf[:s.length+1]
+ cursor, err = dec.Decode(ctx, s.cursor, 0, p)
+ }
+ ctx.Buf = nil
+ if err != nil {
+ return s.decodeError(err, dec, typ, p, end)
+ }
+ if ctx.HasTypeError() {
+ return s.typeError(typ, cursor)
+ }
+ s.cursor = cursor
+ if countsScanned {
+ s.scanned += s.offset + cursor - s.readStart
+ }
+ s.more.reset()
+ if s.tokenState != tokenTopValue {
+ s.tokenValueEnd()
+ }
+ return nil
}
-func trueBytes(s *Stream) error {
- // current cursor's character is 't'
- s.cursor++
- if s.char() != 'r' {
- if err := retryReadTrue(s); err != nil {
- return err
+// decodeError returns the error of the decoder, whose offset is made the one in the whole input, of the value at
+// the cursor, which scanValue ended at end. A type error before it is not kept for the next value.
+//
+// A syntax error is the first one of the value by the grammar, as encoding/json reports it: it checks the value
+// before it decodes it. The decoder never writes the buffer, which keeps the input.
+//
+//go:noinline
+func (s *Stream) decodeError(err error, dec Decoder, typ, p unsafe.Pointer, end int64) error {
+ if c := s.buf[s.cursor]; c == '-' || c-'0' <= 9 {
+ if first := streamNumberEnd(s.buf, s.cursor, end); first < end {
+ // the bytes of the numbers which scanLiteral read are more than one value, as 01 is 0 and 1: the first
+ // is decoded alone, and the next one after it
+ s.ctx.DiscardTypeError()
+ return s.decodeFirstNumber(dec, typ, p, first)
}
}
- s.cursor++
- if s.char() != 'u' {
- if err := retryReadTrue(s); err != nil {
- return err
+ s.ctx.DiscardTypeError()
+ if _, ok := err.(*errors.SyntaxError); ok {
+ if serr := s.valueSyntaxError(); serr != nil {
+ return s.fail(serr)
}
}
- s.cursor++
- if s.char() != 'e' {
- if err := retryReadTrue(s); err != nil {
- return err
+ return s.fail(s.totalOffsetError(err))
+}
+
+// decodeFirstNumber decodes the number at the cursor, which ends at end by the grammar, as Decode does.
+func (s *Stream) decodeFirstNumber(dec Decoder, typ, p unsafe.Pointer, end int64) error {
+ ctx := s.ctx
+ saved := s.buf[end]
+ s.buf[end] = nul
+ ctx.Buf = s.buf[:end+1]
+ cursor, err := dec.Decode(ctx, s.cursor, 0, p)
+ s.buf[end] = saved
+ ctx.Buf = nil
+ if err != nil {
+ s.ctx.DiscardTypeError()
+ if serr := s.valueSyntaxError(); serr != nil {
+ return s.fail(serr)
}
+ return s.fail(s.totalOffsetError(err))
+ }
+ if ctx.HasTypeError() {
+ return s.typeError(typ, cursor)
+ }
+ s.cursor = cursor
+ if countsScanned {
+ s.scanned += s.offset + cursor - s.readStart
+ }
+ s.more.reset()
+ if s.tokenState != tokenTopValue {
+ s.tokenValueEnd()
}
- s.cursor++
return nil
}
-func retryReadTrue(s *Stream) error {
- if s.char() == nul && s.read() {
+// valueSyntaxError returns the first syntax error of the value at the cursor by the grammar, in what has been read:
+// the error of a byte, with its offset in the whole input, or the unexpected end of the input, where encoding/json
+// reads more. A number, true, false or null is followed by the byte after it, or by the end of the input: the scan
+// of the value has read either. It is nil if what has been read has none.
+//
+//go:noinline
+func (s *Stream) valueSyntaxError() error {
+ _, err := skipValue(s.buf[:s.length+1], s.cursor, 0)
+ if err == nil {
return nil
}
- return errors.ErrInvalidCharacter(s.char(), "bool(true)", s.totalOffset())
+ if errors.IsAtEnd(err) {
+ return s.unexpectedEndError()
+ }
+ if at, ok := errors.ValueStartAt(err); ok {
+ if merr := s.valueStartMismatch(at); merr != nil {
+ return merr
+ }
+ }
+ return s.scannedOffset(s.totalOffsetError(err))
}
-func falseBytes(s *Stream) error {
- // current cursor's character is 'f'
- s.cursor++
- if s.char() != 'a' {
- if err := retryReadFalse(s); err != nil {
- return err
- }
+// scannedOffset makes the offset of the syntax error of the value read from readStart the one which encoding/json
+// of the Go version reports ( see countsScanned ).
+func (s *Stream) scannedOffset(err error) error {
+ if e, ok := err.(*errors.SyntaxError); ok && countsScanned {
+ e.Offset += s.scanned - s.readStart
}
- s.cursor++
- if s.char() != 'l' {
- if err := retryReadFalse(s); err != nil {
- return err
- }
+ return err
+}
+
+// typeError returns the type error of the value of the pointer type typ which Decode decoded from the cursor up
+// to end, and moves the cursor after the value: the stream goes on after it, as the one of encoding/json does.
+// Its offset is relative to the value, as encoding/json of the Go version reports it ( see StreamOffsetBase ).
+// It takes the decoder of the type again, so that Decode keeps nothing more across its call of the decoder.
+//
+//go:noinline
+func (s *Stream) typeError(typ unsafe.Pointer, end int64) error {
+ start := s.cursor
+ s.cursor = end
+ if countsScanned {
+ s.scanned += s.offset + end - s.readStart
}
- s.cursor++
- if s.char() != 's' {
- if err := retryReadFalse(s); err != nil {
- return err
- }
+ s.more.reset()
+ if s.tokenState != tokenTopValue {
+ s.tokenValueEnd()
}
- s.cursor++
- if s.char() != 'e' {
- if err := retryReadFalse(s); err != nil {
- return err
- }
+ ctx := s.ctx
+ dec, err := s.DecoderOf(typ)
+ if err != nil {
+ ctx.DiscardTypeError()
+ return err
}
- s.cursor++
- return nil
+ // the path of the error is walked in the value ended by the nul byte, as it was decoded
+ saved := s.buf[end]
+ s.buf[end] = nul
+ ctx.Buf = s.buf[:end+1]
+ base := StreamOffsetBase(s.prevEnd, s.offset+start) - s.offset
+ err = ctx.TypeError(dec, runtime.TypeOfPtr(typ), start, base)
+ ctx.Buf = nil
+ s.buf[end] = saved
+ return err
}
-func retryReadFalse(s *Stream) error {
- if s.char() == nul && s.read() {
- return nil
+// totalOffsetError makes the offset of an error of the decoder, which is relative to the buffer,
+// the offset in the whole input.
+func (s *Stream) totalOffsetError(err error) error {
+ switch e := err.(type) {
+ case *errors.SyntaxError:
+ e.Offset += s.offset
+ case *errors.UnmarshalTypeError:
+ e.Offset += s.offset
}
- return errors.ErrInvalidCharacter(s.char(), "bool(false)", s.totalOffset())
+ return err
}
+
+// tokenString decodes the string at the cursor by the string decoder, as Decode does.
+func (s *Stream) tokenString() (any, error) {
+ s.readStart = s.offset + s.cursor
+ end, err := s.scanValue()
+ if err != nil {
+ return nil, err
+ }
+ saved := s.buf[end]
+ s.buf[end] = nul
+ literal, _, err := tokenStringDecoder.decodeByte(s.buf[:end+1], s.cursor)
+ s.buf[end] = saved
+ if err != nil {
+ if serr := s.valueSyntaxError(); serr != nil {
+ return nil, serr
+ }
+ return nil, s.totalOffsetError(err)
+ }
+ s.cursor = end
+ if countsScanned {
+ s.scanned += s.offset + end - s.readStart
+ }
+ if len(literal) != 0 && !isPartOf(literal, s.buf) {
+ // the bytes of the escaped string, which decodeLiteral made: they are the string's own
+ return unsafe.String(unsafe.SliceData(literal), len(literal)), nil
+ }
+ return string(literal), nil
+}
+
+var tokenStringDecoder = newStringDecoder("", "")
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/stream_token.go b/vendor/github.com/goccy/go-json/internal/decoder/stream_token.go
new file mode 100644
index 000000000..b81ddd305
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/stream_token.go
@@ -0,0 +1,36 @@
+package decoder
+
+// The tokens of a stream are read as encoding/json reads them: the stream keeps where it is in the objects and
+// the arrays which Token opened, so that a delimiter is checked by the grammar, and a value which Decode reads
+// between the tokens follows the comma or the colon before it.
+
+// tokenState is where the stream is between the tokens of the objects and the arrays which Token opened.
+type tokenState uint8
+
+const (
+ // tokenTopValue is out of any: the values of the stream follow each other.
+ tokenTopValue tokenState = iota
+ tokenArrayStart
+ tokenArrayValue
+ tokenArrayComma
+ tokenObjectStart
+ tokenObjectKey
+ tokenObjectColon
+ tokenObjectValue
+ tokenObjectComma
+ // tokenFailed is after a read which failed: every read returns its error.
+ tokenFailed
+)
+
+// tokenValueEnd moves the state after a value, which is the key of an object where one is waited for, as
+// encoding/json of Go 1.27 reads it.
+func (s *Stream) tokenValueEnd() {
+ switch s.tokenState {
+ case tokenArrayStart, tokenArrayValue:
+ s.tokenState = tokenArrayComma
+ case tokenObjectValue:
+ s.tokenState = tokenObjectComma
+ case tokenObjectStart, tokenObjectKey:
+ s.tokenState = tokenObjectColon
+ }
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/stream_token_legacy.go b/vendor/github.com/goccy/go-json/internal/decoder/stream_token_legacy.go
new file mode 100644
index 000000000..c4998d00c
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/stream_token_legacy.go
@@ -0,0 +1,210 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package decoder
+
+import (
+ "encoding/json"
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// The tokens of a stream as encoding/json before Go 1.27 reads them: a comma or a colon which the grammar doesn't
+// have is an error of Token, which is not kept, and Decode reads a value where Token would.
+
+// streamPeek is what More peeked at, which encoding/json before Go 1.27 doesn't keep: More and Token move the
+// offset over the white spaces.
+type streamPeek struct{}
+
+// reset does nothing.
+func (streamPeek) reset() {}
+
+// valueStartMismatch returns nil: encoding/json before Go 1.27 tells the bracket where a value is waited for as
+// the grammar does.
+func (*Stream) valueStartMismatch(int64) error {
+ return nil
+}
+
+// countsScanned is whether the offset of a syntax error of a value of Decode is counted from the bytes which the
+// reads of the values read, as encoding/json before Go 1.27 counts it: the white spaces and the delimiters which
+// Token or More read, and the comma or the colon before a value of Decode, are not counted.
+const countsScanned = true
+
+// prepareInTokens moves the cursor to the value which Decode reads between the tokens: after the comma or the
+// colon which the state waits for. It is not inlined, so that Decode keeps the size it had.
+//
+//go:noinline
+func (s *Stream) prepareInTokens() error {
+ switch s.tokenState {
+ case tokenFailed:
+ return s.err
+ case tokenArrayComma:
+ // the comma and the colon are looked for without an error kept, as encoding/json does
+ if !s.peek() {
+ return s.endError()
+ }
+ if s.buf[s.cursor] != ',' {
+ return errors.ErrSyntax("expected comma after array element", s.TotalOffset())
+ }
+ s.cursor++
+ s.tokenState = tokenArrayValue
+ // the value is read after the comma
+ s.markPrevEnd()
+ s.readStart = s.offset + s.cursor
+ case tokenObjectColon:
+ if !s.peek() {
+ return s.endError()
+ }
+ if s.buf[s.cursor] != ':' {
+ return errors.ErrSyntax("expected colon after object key", s.TotalOffset())
+ }
+ s.cursor++
+ s.tokenState = tokenObjectValue
+ // the value is read after the colon
+ s.markPrevEnd()
+ s.readStart = s.offset + s.cursor
+ default:
+ // the value is read from the cursor, white spaces before it too
+ s.readStart = s.offset + s.cursor
+ }
+ if !s.tokenValueAllowed() {
+ return errors.ErrSyntax("not at beginning of value", s.TotalOffset())
+ }
+ if !s.skipWhiteSpace() {
+ return s.fail(s.endError())
+ }
+ return nil
+}
+
+// Token returns the next token of the stream: a delimiter, a string, a number, a bool or nil. The commas and the
+// colons are consumed where the grammar has them.
+func (s *Stream) Token() (any, error) {
+ if s.tokenState == tokenFailed {
+ return nil, s.err
+ }
+ for {
+ if !s.peek() {
+ return nil, s.endError()
+ }
+ c := s.buf[s.cursor]
+ switch c {
+ case '[', '{':
+ if !s.tokenValueAllowed() {
+ return nil, s.tokenError(c)
+ }
+ s.cursor++
+ s.tokenStack = append(s.tokenStack, s.tokenState)
+ if c == '[' {
+ s.tokenState = tokenArrayStart
+ } else {
+ s.tokenState = tokenObjectStart
+ }
+ return json.Delim(c), nil
+ case ']', '}':
+ if c == ']' && s.tokenState != tokenArrayStart && s.tokenState != tokenArrayComma ||
+ c == '}' && s.tokenState != tokenObjectStart && s.tokenState != tokenObjectComma {
+ return nil, s.tokenError(c)
+ }
+ s.cursor++
+ s.tokenState = s.tokenStack[len(s.tokenStack)-1]
+ s.tokenStack = s.tokenStack[:len(s.tokenStack)-1]
+ s.tokenValueEnd()
+ return json.Delim(c), nil
+ case ':':
+ if s.tokenState != tokenObjectColon {
+ return nil, s.tokenError(c)
+ }
+ s.cursor++
+ s.tokenState = tokenObjectValue
+ continue
+ case ',':
+ switch s.tokenState {
+ case tokenArrayComma:
+ s.tokenState = tokenArrayValue
+ case tokenObjectComma:
+ s.tokenState = tokenObjectKey
+ default:
+ return nil, s.tokenError(c)
+ }
+ s.cursor++
+ continue
+ case '"':
+ if s.tokenState == tokenObjectStart || s.tokenState == tokenObjectKey {
+ key, err := s.tokenString()
+ if err != nil {
+ return nil, err
+ }
+ s.tokenState = tokenObjectColon
+ return key, nil
+ }
+ }
+ if !s.tokenValueAllowed() {
+ return nil, s.tokenError(c)
+ }
+ // a value is read as Decode reads it into an interface{}, as encoding/json before Go 1.27 reads it: its
+ // errors, and the bytes which the reads of the values read ( see countsScanned ), are the ones of Decode
+ dec, err := s.DecoderOf(anyPtrType)
+ if err != nil {
+ return nil, err
+ }
+ var v any
+ if err := s.Decode(dec, anyPtrType, unsafe.Pointer(&v)); err != nil {
+ return nil, err
+ }
+ return v, nil
+ }
+}
+
+// anyPtrType is the type of *interface{}, which Token decodes a value into.
+var anyPtrType = runtime.TypePtr(reflect.TypeOf((*any)(nil)))
+
+// tokenError returns the syntax error of the byte c at the cursor, which the grammar doesn't have in the state, as
+// encoding/json has it.
+func (s *Stream) tokenError(c byte) error {
+ var context string
+ switch s.tokenState {
+ case tokenTopValue, tokenArrayStart, tokenArrayValue, tokenObjectValue:
+ context = " looking for beginning of value"
+ case tokenArrayComma:
+ context = " after array element"
+ case tokenObjectKey:
+ context = " looking for beginning of object key string"
+ case tokenObjectColon:
+ context = " after object key"
+ case tokenObjectComma:
+ context = " after object key:value pair"
+ }
+ return errors.ErrSyntax("invalid character "+quoteChar(c)+context, s.TotalOffset())
+}
+
+// InputOffset returns the offset of the stream which Decoder.InputOffset reports: the number of the bytes
+// consumed from the reader, or, after a read failed, the end of the value before it.
+func (s *Stream) InputOffset() int64 {
+ if s.tokenState == tokenFailed {
+ return s.errOffset
+ }
+ return s.TotalOffset()
+}
+
+// More reports whether the current array or object has another element.
+func (s *Stream) More() bool {
+ if !s.peek() {
+ return false
+ }
+ switch s.buf[s.cursor] {
+ case ']', '}':
+ return false
+ }
+ return true
+}
+
+// tokenValueAllowed reports whether a value may be read in the state.
+func (s *Stream) tokenValueAllowed() bool {
+ switch s.tokenState {
+ case tokenTopValue, tokenArrayStart, tokenArrayValue, tokenObjectValue:
+ return true
+ }
+ return false
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/stream_token_v2.go b/vendor/github.com/goccy/go-json/internal/decoder/stream_token_v2.go
new file mode 100644
index 000000000..c8a9291b7
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/stream_token_v2.go
@@ -0,0 +1,490 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package decoder
+
+import (
+ "bytes"
+ "encoding/json"
+ "io"
+ "strconv"
+ "unicode/utf8"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// The tokens of a stream as encoding/json of Go 1.27 reads them, by encoding/json/jsontext: a token or a value is
+// read after the comma or the colon which the grammar has before it, which is checked against the kind of the
+// token, and a read which fails leaves the stream where it was. A value may be read where a key is waited for,
+// as the key.
+
+// streamPeek is what More peeked at: encoding/json of Go 1.27 reports by InputOffset the start of the next token
+// after More, until a value or a token is read.
+type streamPeek struct {
+ // peeked is whether More was called after the last value or token which was read.
+ peeked bool
+ // offset is the total offset of the next token which More peeked at, or of the end of the value or the token
+ // before it if the input has none.
+ offset int64
+}
+
+// reset forgets what More peeked at, after a value or a token is read.
+func (p *streamPeek) reset() {
+ p.peeked = false
+}
+
+// countsScanned is whether the offset of a syntax error of a value of Decode is counted from the bytes which the
+// reads of the values read: encoding/json of Go 1.27 reports the offset in the whole input.
+const countsScanned = false
+
+// invalidCharacter returns the syntax error of the character at the total offset, which the grammar doesn't
+// have where it is: encoding/json of Go 1.27 reports the rune there. The bytes of the rune are read if the buffer
+// ends in it, and the ones from at are kept for it.
+func (s *Stream) invalidCharacter(at int64, where string) error {
+ cursor := s.TotalOffset()
+ s.cursor = min(cursor, at) - s.offset
+ for s.length-(at-s.offset) < utf8.UTFMax && !utf8.FullRune(s.buf[at-s.offset:s.length]) && s.read() {
+ }
+ s.cursor = cursor - s.offset
+ err := invalidCharacterError(s.buf[:s.length+1], at-s.offset, where)
+ return s.totalOffsetError(err)
+}
+
+// tokenEnded is after Token read the end of the input: every read returns io.EOF.
+const tokenEnded = tokenFailed + 1
+
+// needDelim returns the comma or the colon which the grammar has before a token of the kind which starts with c,
+// or 0 for none.
+func (s *Stream) needDelim(c byte) byte {
+ switch s.tokenState {
+ case tokenObjectColon:
+ return ':'
+ case tokenArrayComma, tokenObjectComma:
+ if c != '}' && c != ']' {
+ return ','
+ }
+ }
+ return 0
+}
+
+// readDelim reads, from start, the white spaces and the comma or the colon before the next token, which it checks
+// against the token, and moves the state after it. It returns the byte which starts the token.
+func (s *Stream) readDelim(start int64) (byte, error) {
+ if !s.peek() {
+ return 0, s.tokenEnd(start)
+ }
+ var delim byte
+ at := s.TotalOffset()
+ if c := s.buf[s.cursor]; c == ',' || c == ':' {
+ delim = c
+ s.cursor++
+ if !s.skipWhiteSpace() {
+ // the next token is not known: a string, which follows any comma or colon, is taken for it
+ if s.needDelim('"') != delim {
+ return 0, s.delimError('"', at)
+ }
+ return 0, s.tokenEnd(start)
+ }
+ }
+ c := s.buf[s.cursor]
+ if s.needDelim(c) != delim {
+ // the byte after the white spaces: the comma or the colon, or else the token
+ return 0, s.delimError(c, at)
+ }
+ switch {
+ case delim == ',' && s.tokenState == tokenArrayComma:
+ s.tokenState = tokenArrayValue
+ case delim == ',':
+ s.tokenState = tokenObjectKey
+ case delim == ':':
+ s.tokenState = tokenObjectValue
+ }
+ return c, nil
+}
+
+// delimError returns the error of the byte c at the total offset at, which is not the comma or the colon which the
+// grammar has before a token which starts with next.
+func (s *Stream) delimError(next byte, at int64) error {
+ where := "looking for beginning of value"
+ switch s.needDelim(next) {
+ case ':':
+ where = "after object key"
+ case ',':
+ if s.tokenState == tokenObjectComma {
+ where = "after object key:value pair"
+ } else {
+ where = "after array element"
+ }
+ }
+ return s.invalidCharacter(at, where)
+}
+
+// tokenEnd returns the error of the end of the input before a token: io.EOF if what is left is white spaces,
+// commas and colons, which a value may follow, as encoding/json reports it.
+func (s *Stream) tokenEnd(start int64) error {
+ if err := s.endError(); err != io.EOF {
+ return err
+ }
+ for i := start - s.offset; i < s.length; i++ {
+ switch s.buf[i] {
+ case ' ', '\t', '\n', '\r', ',', ':':
+ default:
+ return io.ErrUnexpectedEOF
+ }
+ }
+ return io.EOF
+}
+
+// restore moves the stream back to the total offset start, where a read which failed started, which InputOffset
+// reports, and returns err.
+func (s *Stream) restore(start int64, err error) error {
+ s.moveBack(start)
+ return err
+}
+
+// moveBack moves the stream back to the total offset start, where a read which failed started, which InputOffset
+// reports.
+func (s *Stream) moveBack(start int64) {
+ if start >= s.offset {
+ s.cursor = start - s.offset
+ }
+ s.errOffset = start
+}
+
+// prepareInTokens moves the cursor to the value which Decode reads between the tokens: after the comma or the
+// colon which the grammar has before it. A read which fails is kept, as encoding/json keeps it. It is not
+// inlined, so that Decode keeps the size it had.
+//
+//go:noinline
+func (s *Stream) prepareInTokens() error {
+ if s.tokenState == tokenFailed || s.tokenState == tokenEnded {
+ return s.err
+ }
+ start := s.TotalOffset()
+ c, err := s.readDelim(start)
+ if err == nil {
+ err = s.valueStartError(c)
+ }
+ if err != nil {
+ if err == io.EOF {
+ // the end of the input in an object or an array
+ err = io.ErrUnexpectedEOF
+ }
+ s.moveBack(start)
+ s.err, s.tokenState = err, tokenFailed
+ return err
+ }
+ return nil
+}
+
+// valueStartError returns the error of a value which starts with c where it can't be read: the end of an object or
+// an array, or a value which is not a string where a key is waited for.
+func (s *Stream) valueStartError(c byte) error {
+ at := s.TotalOffset()
+ switch {
+ case c == '}' || c == ']':
+ // a bracket where the value starts
+ if err := s.valueStartMismatch(at - s.offset); err != nil {
+ return err
+ }
+ return s.invalidCharacter(at, "looking for beginning of value")
+ case kindOf(c) == noValue:
+ // a byte which starts no token
+ return s.invalidCharacter(at, "looking for beginning of value")
+ case c != '"' && (s.tokenState == tokenObjectStart || s.tokenState == tokenObjectKey):
+ return s.memberNameError(at)
+ }
+ return nil
+}
+
+// valueStartMismatch returns the error of the bracket at the position at in the buffer, where a value is waited for
+// in the value which is read or where it starts, if it is the end of the other kind of the object or the array
+// which Token opened last, which has a member or an element already: jsontext reports it as a mismatch of that
+// one, whatever the value is in. It returns nil for any other one, which is not the start of a value.
+func (s *Stream) valueStartMismatch(at int64) error {
+ switch c := s.buf[at]; {
+ case c == ']' && (s.tokenState == tokenObjectKey || s.tokenState == tokenObjectColon ||
+ s.tokenState == tokenObjectValue || s.tokenState == tokenObjectComma):
+ return s.invalidCharacter(s.offset+at, "after object key:value pair")
+ case c == '}' && (s.tokenState == tokenArrayValue || s.tokenState == tokenArrayComma):
+ return s.invalidCharacter(s.offset+at, "after array element")
+ }
+ return nil
+}
+
+// memberNameError returns the error of the value at the cursor, at the total offset at, where the name of a member
+// of an object is waited for: the value is read first, as jsontext reads a value or a token, and its syntax error,
+// or the end of the input in it, is the error; else the name is not a string.
+func (s *Stream) memberNameError(at int64) error {
+ if _, err := s.scanValue(); err != nil {
+ return err
+ }
+ if err := s.valueSyntaxError(); err != nil {
+ return err
+ }
+ return errors.ErrSyntax("object member name must be a string", at+1)
+}
+
+// mismatchError returns the error of the end of an object or an array c at the total offset at, which doesn't end
+// the one which is open.
+func (s *Stream) mismatchError(at int64) error {
+ where := "looking for beginning of value"
+ switch s.tokenState {
+ case tokenArrayComma:
+ where = "after array element"
+ case tokenObjectComma, tokenObjectValue:
+ // a bracket where a value of an object is waited for too, as jsontext reports it
+ where = "after object key:value pair"
+ }
+ return s.invalidCharacter(at, where)
+}
+
+// Token returns the next token of the stream: a delimiter, a string, a number, a bool or nil. The commas and the
+// colons are consumed where the grammar has them.
+func (s *Stream) Token() (any, error) {
+ // a read which fails leaves the stream where it was, in its state, with the bytes from where it was
+ state := s.tokenState
+ s.keeps, s.keepFrom = true, s.TotalOffset()
+ v, err := s.token()
+ s.keeps = false
+ if _, ok := err.(*errors.UnmarshalTypeError); err == nil || ok {
+ // a token is read: InputOffset reports its end again
+ s.more.reset()
+ } else if s.tokenState != tokenFailed && s.tokenState != tokenEnded {
+ s.tokenState = state
+ }
+ return v, err
+}
+
+// token reads the next token for Token.
+func (s *Stream) token() (any, error) {
+ if s.tokenState == tokenFailed || s.tokenState == tokenEnded {
+ return nil, s.err
+ }
+ start := s.TotalOffset()
+ c, err := s.readDelim(start)
+ if err != nil {
+ if err == io.EOF {
+ // InputOffset reports a comma or a colon before the end, with the white spaces before it, and not the
+ // white spaces at the end
+ s.moveBack(start)
+ if rest := trimLeftSpaces(s.buf[s.cursor:s.length]); len(rest) > 0 && (rest[0] == ',' || rest[0] == ':') {
+ s.errOffset = s.TotalOffset() + int64(len(s.buf[s.cursor:s.length])-len(rest)) + 1
+ }
+ s.tokenState, s.err = tokenEnded, err
+ return nil, err
+ }
+ return nil, s.restore(start, err)
+ }
+ at := s.TotalOffset()
+ switch c {
+ case '[', '{':
+ if s.tokenState == tokenObjectStart || s.tokenState == tokenObjectKey {
+ return nil, s.restore(start, errors.ErrSyntax("object member name must be a string", at+1))
+ }
+ s.cursor++
+ s.tokenStack = append(s.tokenStack, s.tokenState)
+ if c == '[' {
+ s.tokenState = tokenArrayStart
+ } else {
+ s.tokenState = tokenObjectStart
+ }
+ return json.Delim(c), nil
+ case ']', '}':
+ open := tokenArrayStart
+ if c == '}' {
+ open = tokenObjectStart
+ }
+ if len(s.tokenStack) == 0 || !s.inOpen(open) {
+ return nil, s.restore(start, s.mismatchError(at))
+ }
+ if s.tokenState == tokenObjectValue {
+ return nil, s.restore(start, errors.ErrSyntax("missing value after object key", at+1))
+ }
+ s.cursor++
+ s.tokenState = s.tokenStack[len(s.tokenStack)-1]
+ s.tokenStack = s.tokenStack[:len(s.tokenStack)-1]
+ s.tokenValueEnd()
+ return json.Delim(c), nil
+ case '"':
+ if s.tokenState == tokenObjectStart || s.tokenState == tokenObjectKey {
+ key, err := s.tokenString()
+ if err != nil {
+ return nil, s.restore(start, err)
+ }
+ s.tokenState = tokenObjectColon
+ return key, nil
+ }
+ default:
+ if kindOf(c) != noValue && (s.tokenState == tokenObjectStart || s.tokenState == tokenObjectKey) {
+ return nil, s.restore(start, s.memberNameError(at))
+ }
+ }
+ v, err := s.tokenValue(c)
+ if err != nil {
+ if _, ok := err.(*errors.UnmarshalTypeError); ok {
+ // the value is read: the stream goes on after it
+ s.tokenValueEnd()
+ return nil, err
+ }
+ return nil, s.restore(start, err)
+ }
+ s.tokenValueEnd()
+ return v, nil
+}
+
+// inOpen reports whether the innermost object or array which is open is of the kind of the state open.
+func (s *Stream) inOpen(open tokenState) bool {
+ switch s.tokenState {
+ case tokenArrayStart, tokenArrayValue, tokenArrayComma:
+ return open == tokenArrayStart
+ }
+ return open == tokenObjectStart
+}
+
+// tokenError returns the syntax error of the byte c at the cursor, which the grammar doesn't have in the state.
+func (s *Stream) tokenError(c byte) error {
+ return s.invalidCharacter(s.TotalOffset(), "looking for beginning of value")
+}
+
+// InputOffset returns the offset of the stream which Decoder.InputOffset reports: the end of the last token or
+// value read, or where a read which failed started.
+func (s *Stream) InputOffset() int64 {
+ offset := s.TotalOffset()
+ if s.tokenState == tokenFailed || s.tokenState == tokenEnded {
+ offset = s.errOffset
+ }
+ if s.more.peeked {
+ // after More, the start of the next token which it peeked at, after the white spaces before it
+ return s.more.offset
+ }
+ return offset
+}
+
+// More reports whether the current array or object has another element: at the end of the input in one, it
+// reports true, and the error of the end is returned by the next read, as encoding/json of Go 1.27 does.
+func (s *Stream) More() bool {
+ if s.tokenState == tokenFailed || s.tokenState == tokenEnded {
+ return s.err != io.EOF
+ }
+ // the next token is peeked at, with the comma or the colon before it, as Token reads it: the cursor is kept,
+ // so that the bytes from it stay in the buffer while more input is read
+ start := s.TotalOffset()
+ s.more.peeked, s.more.offset = true, start
+ pos, ok := s.peekFrom(s.cursor)
+ if !ok {
+ return s.moreAtEnd(start)
+ }
+ s.more.offset = s.offset + pos
+ at, c := s.offset+pos, s.buf[pos]
+ var delim byte
+ if c == ',' || c == ':' {
+ delim = c
+ if pos, ok = s.peekFrom(pos + 1); !ok {
+ // the next token is not known: a string, which follows any comma or colon, is taken for it
+ if s.needDelim('"') != delim {
+ return s.moreError(s.delimError('"', at))
+ }
+ return s.moreAtEnd(start)
+ }
+ c = s.buf[pos]
+ }
+ if s.needDelim(c) != delim {
+ return s.moreError(s.delimError(c, at))
+ }
+ return c != ']' && c != '}'
+}
+
+// peekFrom returns the position of the first byte from pos which is not a white space, reading more input as
+// needed without moving the cursor, or false at the end of the input.
+func (s *Stream) peekFrom(pos int64) (int64, bool) {
+ // the position is kept relative to the cursor, because a read may move the data ( grow )
+ rel := pos - s.cursor
+ for {
+ for pos = s.cursor + rel; pos < s.length; pos++ {
+ if !isWhiteSpace[s.buf[pos]] {
+ return pos, true
+ }
+ }
+ rel = s.length - s.cursor
+ if !s.read() {
+ return 0, false
+ }
+ }
+}
+
+// moreAtEnd returns what More reports at the end of the input, which it peeked at from the total offset start: the
+// end of a stream of values, or the unexpected end of an object or an array, which is kept as the error.
+func (s *Stream) moreAtEnd(start int64) bool {
+ if len(s.tokenStack) == 0 {
+ return false
+ }
+ // the error is at the end of the input, after the white spaces, which InputOffset doesn't report
+ s.err, s.errOffset, s.tokenState = errors.ErrSyntax("unexpected end of JSON input", s.offset+s.length), start, tokenFailed
+ return true
+}
+
+// moreError keeps err, the error of the token which More peeked at, which encoding/json of Go 1.27 reads, and
+// returns true.
+func (s *Stream) moreError(err error) bool {
+ s.err, s.errOffset, s.tokenState = err, s.TotalOffset(), tokenFailed
+ return true
+}
+
+func trimLeftSpaces(b []byte) []byte {
+ for len(b) > 0 && (b[0] == ' ' || b[0] == '\t' || b[0] == '\n' || b[0] == '\r') {
+ b = b[1:]
+ }
+ return b
+}
+
+// tokenValue returns the value at the cursor, which starts with c, as the token of a string, a number, a bool or
+// null.
+func (s *Stream) tokenValue(c byte) (any, error) {
+ switch c {
+ case '"':
+ return s.tokenString()
+ case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
+ end, err := s.scanValue()
+ if err != nil {
+ return nil, err
+ }
+ // the number ends where the grammar ends it, as 01 is 0 and 1, and is a number by the grammar
+ end = streamNumberEnd(s.buf, s.cursor, end)
+ literal := s.buf[s.cursor:end]
+ if !isValidNumber(literal) {
+ return nil, s.valueSyntaxError()
+ }
+ s.cursor = end
+ if (s.Option.Flags & UseNumberOption) != 0 {
+ return json.Number(literal), nil
+ }
+ f64, err := strconv.ParseFloat(*(*string)(unsafe.Pointer(&literal)), 64)
+ if err != nil {
+ // a number out of the range of float64, which is read: a type error of the value, which Token
+ // returns after it
+ return nil, &errors.UnmarshalTypeError{Value: "number " + string(literal), Type: float64Type, Offset: s.TotalOffset()}
+ }
+ return f64, nil
+ case 't', 'f', 'n':
+ end, err := s.scanValue()
+ if err != nil {
+ return nil, err
+ }
+ var v any
+ lit := "null"
+ switch c {
+ case 't':
+ v, lit = true, "true"
+ case 'f':
+ v, lit = false, "false"
+ }
+ // the literal ends after its bytes: what follows is the next token
+ if !bytes.HasPrefix(s.buf[s.cursor:end], []byte(lit)) {
+ return nil, s.valueSyntaxError()
+ }
+ s.cursor += int64(len(lit))
+ return v, nil
+ }
+ return nil, s.tokenError(c)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/string.go b/vendor/github.com/goccy/go-json/internal/decoder/string.go
index 32602c908..dc3d277ca 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/string.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/string.go
@@ -2,10 +2,11 @@ package decoder
import (
"bytes"
+ "encoding/binary"
"fmt"
+ "math/bits"
"reflect"
- "unicode"
- "unicode/utf16"
+ "strconv"
"unicode/utf8"
"unsafe"
@@ -15,12 +16,15 @@ import (
type stringDecoder struct {
structName string
fieldName string
+ // typ is the type of the string, which the type errors report.
+ typ reflect.Type
}
func newStringDecoder(structName, fieldName string) *stringDecoder {
return &stringDecoder{
structName: structName,
fieldName: fieldName,
+ typ: reflect.TypeOf(""),
}
}
@@ -34,30 +38,26 @@ func (d *stringDecoder) errUnmarshalType(typeName string, offset int64) *errors.
}
}
-func (d *stringDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamByte(s)
- if err != nil {
- return err
- }
- if bytes == nil {
- return nil
- }
- **(**string)(unsafe.Pointer(&p)) = *(*string)(unsafe.Pointer(&bytes))
- s.reset()
- return nil
-}
-
func (d *stringDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- bytes, c, err := d.decodeByte(ctx.Buf, cursor)
+ var (
+ s string
+ c int64
+ ok bool
+ err error
+ )
+ buf := ctx.Buf
+ if start := skipWhiteSpace(buf, cursor); buf[start] == '"' {
+ s, c, ok, err = d.decodeStringField(ctx, start+1)
+ } else {
+ s, c, ok, err = d.decodeStringValue(ctx, cursor)
+ }
if err != nil {
return 0, err
}
- if bytes == nil {
- return c, nil
+ if ok {
+ **(**string)(unsafe.Pointer(&p)) = s
}
- cursor = c
- **(**string)(unsafe.Pointer(&p)) = *(*string)(unsafe.Pointer(&bytes))
- return cursor, nil
+ return c, nil
}
func (d *stringDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
@@ -98,281 +98,453 @@ var (
}
)
-func unicodeToRune(code []byte) rune {
- var r rune
- for i := 0; i < len(code); i++ {
- r = r*16 + rune(hexToInt[code[i]])
- }
- return r
+var runeErrBytes = []byte(string(utf8.RuneError))
+
+// stringInfo is what scanString found in a string.
+type stringInfo struct {
+ // firstEscape is the offset of the first backslash in the bytes of the string, or -1 if it has no escape:
+ // its bytes are the ones of the value then.
+ firstEscape int
+ // nonASCII is whether a byte of the string is not ASCII: the string may be invalid UTF-8.
+ nonASCII bool
}
-func readAtLeast(s *Stream, n int64, p *unsafe.Pointer) bool {
- for s.cursor+n >= s.length {
- if !s.read() {
- return false
- }
- *p = s.bufptr()
+// decodeByte returns the bytes of the string at cursor, or nil for null: a part of buf, or a slice of their own if
+// the string has an escape or invalid UTF-8 ( see decodeLiteral ).
+func (d *stringDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
+ literal, next, info, err := d.scanString(buf, cursor)
+ if next < 0 {
+ literal, next, info, err = d.scanStringRest(buf, literal, -next-1, info)
}
- return true
+ if err != nil || literal == nil {
+ return literal, next, err
+ }
+ return decodeLiteral(literal, info), next, nil
}
-func decodeUnicodeRune(s *Stream, p unsafe.Pointer) (rune, int64, unsafe.Pointer, error) {
- const defaultOffset = 5
- const surrogateOffset = 11
-
- if !readAtLeast(s, defaultOffset, &p) {
- return rune(0), 0, nil, errors.ErrInvalidCharacter(s.char(), "escaped string", s.totalOffset())
+// unescapeLong returns the string of the literal, which has an escape and is too long for the arena: it is decoded
+// into the scratch bytes of the context, and copied, so that the bytes of the string are not zeroed before they are
+// written, and the buffer is not written.
+func (ctx *RuntimeContext) unescapeLong(literal []byte, info stringInfo) string {
+ if len(literal) > maxUnescapeScratchSize {
+ decoded := decodeLiteral(literal, info)
+ return unsafe.String(unsafe.SliceData(decoded), len(decoded))
}
-
- r := unicodeToRune(s.buf[s.cursor+1 : s.cursor+defaultOffset])
- if utf16.IsSurrogate(r) {
- if !readAtLeast(s, surrogateOffset, &p) {
- return unicode.ReplacementChar, defaultOffset, p, nil
- }
- if s.buf[s.cursor+defaultOffset] != '\\' || s.buf[s.cursor+defaultOffset+1] != 'u' {
- return unicode.ReplacementChar, defaultOffset, p, nil
- }
- r2 := unicodeToRune(s.buf[s.cursor+defaultOffset+2 : s.cursor+surrogateOffset])
- if r := utf16.DecodeRune(r, r2); r != unicode.ReplacementChar {
- return r, surrogateOffset, p, nil
- }
+ if cap(ctx.unescaped) < len(literal) {
+ ctx.unescaped = make([]byte, len(literal))
+ }
+ n := unescapeTo(unsafe.Pointer(unsafe.SliceData(ctx.unescaped)), literal, info.firstEscape)
+ decoded := ctx.unescaped[:n]
+ if info.nonASCII && !utf8.Valid(decoded) {
+ return string(coerceUTF8(decoded))
}
- return r, defaultOffset, p, nil
+ return string(decoded)
}
-func decodeUnicode(s *Stream, p unsafe.Pointer) (unsafe.Pointer, error) {
- const backSlashAndULen = 2 // length of \u
+// decodeLiteral decodes the escapes of the literal and replaces its invalid UTF-8, into a slice of its own if it
+// has any: the buffer is never written, so that it keeps the input, which is checked again for a syntax error
+// ( see Stream.decodeError ).
+func decodeLiteral(literal []byte, info stringInfo) []byte {
+ if info.firstEscape >= 0 {
+ out := make([]byte, len(literal))
+ literal = out[:unescapeTo(unsafe.Pointer(unsafe.SliceData(out)), literal, info.firstEscape)]
+ }
+ if info.nonASCII && !utf8.Valid(literal) {
+ literal = coerceUTF8(literal)
+ }
+ return literal
+}
- r, offset, pp, err := decodeUnicodeRune(s, p)
- if err != nil {
- return nil, err
- }
- unicode := []byte(string(r))
- unicodeLen := int64(len(unicode))
- s.buf = append(append(s.buf[:s.cursor-1], unicode...), s.buf[s.cursor+offset:]...)
- unicodeOrgLen := offset - 1
- s.length = s.length - (backSlashAndULen + (unicodeOrgLen - unicodeLen))
- s.cursor = s.cursor - backSlashAndULen + unicodeLen
- return pp, nil
+// validLiteral returns the literal of a string without an escape, whose bytes are not all ASCII, with its invalid
+// UTF-8 replaced ( see decodeLiteral ).
+func validLiteral(literal []byte) []byte {
+ if !utf8.Valid(literal) {
+ return coerceUTF8(literal)
+ }
+ return literal
}
-func decodeEscapeString(s *Stream, p unsafe.Pointer) (unsafe.Pointer, error) {
- s.cursor++
-RETRY:
- switch s.buf[s.cursor] {
- case '"':
- s.buf[s.cursor] = '"'
- case '\\':
- s.buf[s.cursor] = '\\'
- case '/':
- s.buf[s.cursor] = '/'
- case 'b':
- s.buf[s.cursor] = '\b'
- case 'f':
- s.buf[s.cursor] = '\f'
- case 'n':
- s.buf[s.cursor] = '\n'
- case 'r':
- s.buf[s.cursor] = '\r'
- case 't':
- s.buf[s.cursor] = '\t'
- case 'u':
- return decodeUnicode(s, p)
- case nul:
- if !s.read() {
- return nil, errors.ErrInvalidCharacter(s.char(), "escaped string", s.totalOffset())
+// decodeStringValue is decodeString for the value of a string: a value of another kind is a type error, which is
+// recorded, and skipped ( see skipOtherValue ). It is a function of its own, so that the decoding of the other
+// strings, as the keys, is the one it was, and that Decode keeps nothing across its call.
+func (d *stringDecoder) decodeStringValue(ctx *RuntimeContext, cursor int64) (string, int64, bool, error) {
+ literal, next, info, err := d.scanString(ctx.Buf, cursor)
+ if next < 0 {
+ return d.decodeStringRest(ctx, literal, -next-1, info)
+ }
+ if err != nil {
+ return d.skipOtherValue(ctx, err)
+ }
+ if literal == nil {
+ return "", next, false, nil
+ }
+ if info.firstEscape >= 0 && len(literal) <= maxArenaStringSize {
+ // an escaped string is decoded into the arena, out of the buffer, which is never written
+ dst := ctx.reserveArena(len(literal))
+ n := unescapeTo(unsafe.Pointer(unsafe.SliceData(dst)), literal, info.firstEscape)
+ decoded := dst[:n]
+ if info.nonASCII && !utf8.Valid(decoded) {
+ return string(coerceUTF8(decoded)), next, true, nil
}
- p = s.bufptr()
- goto RETRY
- default:
- return nil, errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
+ ctx.arena = ctx.arena[:len(ctx.arena)+n]
+ return unsafe.String(unsafe.SliceData(decoded), n), next, true, nil
}
- s.buf = append(s.buf[:s.cursor-1], s.buf[s.cursor:]...)
- s.length--
- s.cursor--
- p = s.bufptr()
- return p, nil
+ if info.firstEscape >= 0 {
+ return ctx.unescapeLong(literal, info), next, true, nil
+ }
+ if info.nonASCII {
+ literal = validLiteral(literal)
+ }
+ return ctx.makeString(literal), next, true, nil
}
-var (
- runeErrBytes = []byte(string(utf8.RuneError))
- runeErrBytesLen = int64(len(runeErrBytes))
-)
-
-func stringBytes(s *Stream) ([]byte, error) {
- _, cursor, p := s.stat()
- cursor++ // skip double quote char
- start := cursor
+// decodeStringField is decodeStringValue for the string whose bytes start at start, after its quote, which the decoder
+// of a string field decodes. Its words are looked at for their end, an escape and a control byte, and, until the
+// first one is met, a byte which is not ASCII: the words of a plain ASCII string are looked at for nothing more, and
+// its bytes are the string. An escape is validated where it is met, and a byte which is not ASCII makes the words
+// look past such bytes, so that any string is scanned once. The string is then decoded as decodeStringValue decodes
+// it: a short escaped string into the arena, a long one from where the words stop ( see decodeStringRest ). Where
+// the CPU has a SIMD scan, the words are looked at in the first 64 bytes only, after which a long string is scanned
+// by SIMD. An error in the string is a syntax error of the string.
+func (d *stringDecoder) decodeStringField(ctx *RuntimeContext, start int64) (string, int64, bool, error) {
+ buf := ctx.Buf
+ b := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ buflen := int64(len(buf))
+ cursor := start
+ wordsEnd := buflen
+ if hasStringSIMD {
+ wordsEnd = min(buflen, start+64)
+ }
+ // The words of a plain ASCII string, which most are, are looked at by this loop, which keeps nothing else: the
+ // loop below goes on from the byte it stops at, which is not read again.
+ for cursor+8 <= wordsEnd {
+ w := load64(buf, cursor)
+ if stop := keyEndBytes(w) | w&msb; stop != 0 {
+ cursor += int64(bits.TrailingZeros64(stop) / 8)
+ if char(b, cursor) == '"' {
+ return ctx.makeString(buf[start:cursor]), cursor + 1, true, nil
+ }
+ break
+ }
+ cursor += 8
+ }
+ firstEscape := int64(-1)
+ nonASCII := false
+ // ascii are the top bits which stop the words at a byte which is not ASCII, until the first one is met.
+ ascii := uint64(msb)
for {
- switch char(p, cursor) {
- case '\\':
- s.cursor = cursor
- pp, err := decodeEscapeString(s, p)
- if err != nil {
- return nil, err
+ c := char(b, cursor)
+ switch {
+ case c == '"':
+ literal, next := buf[start:cursor], cursor+1
+ if firstEscape < 0 {
+ if nonASCII {
+ literal = validLiteral(literal)
+ }
+ return ctx.makeString(literal), next, true, nil
}
- p = pp
- cursor = s.cursor
- case '"':
- literal := s.buf[start:cursor]
- cursor++
- s.cursor = cursor
- return literal, nil
- case
- // 0x00 is nul, 0x5c is '\\', 0x22 is '"' .
- 0x01, 0x02, 0x03, 0x04, 0x05, 0x06, 0x07, 0x08, 0x09, 0x0A, 0x0B, 0x0C, 0x0D, 0x0E, 0x0F, // 0x00-0x0F
- 0x10, 0x11, 0x12, 0x13, 0x14, 0x15, 0x16, 0x17, 0x18, 0x19, 0x1A, 0x1B, 0x1C, 0x1D, 0x1E, 0x1F, // 0x10-0x1F
- 0x20, 0x21 /*0x22,*/, 0x23, 0x24, 0x25, 0x26, 0x27, 0x28, 0x29, 0x2A, 0x2B, 0x2C, 0x2D, 0x2E, 0x2F, // 0x20-0x2F
- 0x30, 0x31, 0x32, 0x33, 0x34, 0x35, 0x36, 0x37, 0x38, 0x39, 0x3A, 0x3B, 0x3C, 0x3D, 0x3E, 0x3F, // 0x30-0x3F
- 0x40, 0x41, 0x42, 0x43, 0x44, 0x45, 0x46, 0x47, 0x48, 0x49, 0x4A, 0x4B, 0x4C, 0x4D, 0x4E, 0x4F, // 0x40-0x4F
- 0x50, 0x51, 0x52, 0x53, 0x54, 0x55, 0x56, 0x57, 0x58, 0x59, 0x5A, 0x5B /*0x5C,*/, 0x5D, 0x5E, 0x5F, // 0x50-0x5F
- 0x60, 0x61, 0x62, 0x63, 0x64, 0x65, 0x66, 0x67, 0x68, 0x69, 0x6A, 0x6B, 0x6C, 0x6D, 0x6E, 0x6F, // 0x60-0x6F
- 0x70, 0x71, 0x72, 0x73, 0x74, 0x75, 0x76, 0x77, 0x78, 0x79, 0x7A, 0x7B, 0x7C, 0x7D, 0x7E, 0x7F: // 0x70-0x7F
- // character is ASCII. skip to next char
- case
- 0x80, 0x81, 0x82, 0x83, 0x84, 0x85, 0x86, 0x87, 0x88, 0x89, 0x8A, 0x8B, 0x8C, 0x8D, 0x8E, 0x8F, // 0x80-0x8F
- 0x90, 0x91, 0x92, 0x93, 0x94, 0x95, 0x96, 0x97, 0x98, 0x99, 0x9A, 0x9B, 0x9C, 0x9D, 0x9E, 0x9F, // 0x90-0x9F
- 0xA0, 0xA1, 0xA2, 0xA3, 0xA4, 0xA5, 0xA6, 0xA7, 0xA8, 0xA9, 0xAA, 0xAB, 0xAC, 0xAD, 0xAE, 0xAF, // 0xA0-0xAF
- 0xB0, 0xB1, 0xB2, 0xB3, 0xB4, 0xB5, 0xB6, 0xB7, 0xB8, 0xB9, 0xBA, 0xBB, 0xBC, 0xBD, 0xBE, 0xBF, // 0xB0-0xBF
- 0xC0, 0xC1, // 0xC0-0xC1
- 0xF5, 0xF6, 0xF7, 0xF8, 0xF9, 0xFA, 0xFB, 0xFC, 0xFD, 0xFE, 0xFF: // 0xF5-0xFE
- // character is invalid
- s.buf = append(append(append([]byte{}, s.buf[:cursor]...), runeErrBytes...), s.buf[cursor+1:]...)
- _, _, p = s.stat()
- cursor += runeErrBytesLen
- s.length += runeErrBytesLen
- continue
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
+ if len(literal) <= maxArenaStringSize {
+ // an escaped string is decoded into the arena, out of the buffer, which is never written
+ dst := ctx.reserveArena(len(literal))
+ n := unescapeTo(unsafe.Pointer(unsafe.SliceData(dst)), literal, int(firstEscape))
+ decoded := dst[:n]
+ if nonASCII && !utf8.Valid(decoded) {
+ return string(coerceUTF8(decoded)), next, true, nil
+ }
+ ctx.arena = ctx.arena[:len(ctx.arena)+n]
+ return unsafe.String(unsafe.SliceData(decoded), n), next, true, nil
}
- goto ERROR
- case 0xEF:
- // RuneError is {0xEF, 0xBF, 0xBD}
- if s.buf[cursor+1] == 0xBF && s.buf[cursor+2] == 0xBD {
- // found RuneError: skip
- cursor += 2
- break
+ return ctx.unescapeLong(literal, stringInfo{firstEscape: int(firstEscape), nonASCII: nonASCII}), next, true, nil
+ case c == '\\':
+ if firstEscape < 0 {
+ firstEscape = cursor - start
}
- fallthrough
- default:
- // multi bytes character
- if !utf8.FullRune(s.buf[cursor : len(s.buf)-1]) {
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
+ cursor++
+ switch char(b, cursor) {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ cursor++
+ case 'u':
+ if cursor+5 >= buflen {
+ return "", 0, false, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
+ }
+ for i := int64(1); i <= 4; i++ {
+ c := char(b, cursor+i)
+ if !(('0' <= c && c <= '9') || ('a' <= c && c <= 'f') || ('A' <= c && c <= 'F')) {
+ return "", 0, false, errors.ErrSyntax(fmt.Sprintf("json: invalid character %c in \\u hexadecimal character escape", c), cursor+i)
+ }
}
- goto ERROR
+ cursor += 5
+ default:
+ return "", 0, false, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
}
- r, size := utf8.DecodeRune(s.buf[cursor:])
- if r == utf8.RuneError {
- s.buf = append(append(append([]byte{}, s.buf[:cursor]...), runeErrBytes...), s.buf[cursor+1:]...)
- cursor += runeErrBytesLen
- s.length += runeErrBytesLen
- _, _, p = s.stat()
- } else {
- cursor += int64(size)
+ case c >= 0x80:
+ nonASCII, ascii = true, 0
+ cursor++
+ case c == nul:
+ return "", 0, false, errors.ErrUnexpectedEndOfJSON("string", cursor)
+ case c < 0x20:
+ return "", 0, false, errors.ErrSyntax(fmt.Sprintf("invalid character %s in string literal", quoteChar(c)), cursor+1)
+ default:
+ // the words stopped where they may not be read, not at a byte to look at
+ if wordsEnd != buflen {
+ // the words stopped at wordsEnd, not at a byte to look at: the rest is scanned by SIMD
+ return d.decodeStringRest(ctx, buf[start:cursor], cursor, stringInfo{firstEscape: int(firstEscape), nonASCII: nonASCII})
}
- continue
+ cursor++
+ }
+ for cursor+8 <= wordsEnd {
+ w := load64(buf, cursor)
+ if stop := keyEndBytes(w) | w&ascii; stop != 0 {
+ cursor += int64(bits.TrailingZeros64(stop) / 8)
+ break
+ }
+ cursor += 8
}
- cursor++
}
-ERROR:
- return nil, errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
}
-func (d *stringDecoder) decodeStreamByte(s *Stream) ([]byte, error) {
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case '[':
- return nil, d.errUnmarshalType("array", s.totalOffset())
- case '{':
- return nil, d.errUnmarshalType("object", s.totalOffset())
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return nil, d.errUnmarshalType("number", s.totalOffset())
- case '"':
- return stringBytes(s)
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case nul:
- if s.read() {
- continue
+// skipOtherValue returns the error of scanString for a value which is not a string, or, for a value of another
+// kind, which scanString reports by an error at its position, records its type error and skips it. The skipped
+// value is not nested in the ones before it: its depth is counted from 0.
+//
+//go:noinline
+func (d *stringDecoder) skipOtherValue(ctx *RuntimeContext, err error) (string, int64, bool, error) {
+ var cursor int64
+ switch e := err.(type) {
+ case *errors.UnmarshalTypeError:
+ // a number, an array or an object
+ cursor = e.Offset
+ case *errors.SyntaxError:
+ // true and false start no string
+ if c := ctx.Buf[e.Offset]; c != 't' && c != 'f' {
+ return "", 0, false, err
+ }
+ cursor = e.Offset
+ default:
+ return "", 0, false, err
+ }
+ next, err := ctx.skipTypeError(cursor, 0, d.typ)
+ return "", next, false, err
+}
+
+// decodeString returns the string at cursor as a value to store, and false for null.
+// An escaped string is decoded out of the buffer directly.
+func (d *stringDecoder) decodeString(ctx *RuntimeContext, cursor int64) (string, int64, bool, error) {
+ literal, next, info, err := d.scanString(ctx.Buf, cursor)
+ if next < 0 {
+ literal, next, info, err = d.scanStringRest(ctx.Buf, literal, -next-1, info)
+ }
+ if err != nil || literal == nil {
+ return "", next, false, err
+ }
+ if info.firstEscape >= 0 && len(literal) <= maxArenaStringSize {
+ // an escaped string is decoded into the arena, out of the buffer, which is never written
+ dst := ctx.reserveArena(len(literal))
+ n := unescapeTo(unsafe.Pointer(unsafe.SliceData(dst)), literal, info.firstEscape)
+ decoded := dst[:n]
+ if info.nonASCII && !utf8.Valid(decoded) {
+ return string(coerceUTF8(decoded)), next, true, nil
+ }
+ ctx.arena = ctx.arena[:len(ctx.arena)+n]
+ return unsafe.String(unsafe.SliceData(decoded), n), next, true, nil
+ }
+ if info.firstEscape >= 0 {
+ return ctx.unescapeLong(literal, info), next, true, nil
+ }
+ if info.nonASCII {
+ literal = validLiteral(literal)
+ }
+ return ctx.makeString(literal), next, true, nil
+}
+
+// plainStringEnd returns the position of the quote which ends the string whose bytes start at start, if its bytes
+// are all ASCII and none of them is escaped, and -1 for any other string, which the caller decodes by decodeString.
+// Most of the keys and many of the values are such strings: this is their scan alone, eight bytes at a time, with
+// nothing to keep about the bytes it passes. A word is read only where the buffer has room for it, so that a string
+// at the end of the buffer is left to decodeString too.
+func plainStringEnd(buf []byte, start int64) int64 {
+ cursor := start
+ buflen := int64(len(buf))
+ for cursor+8 <= buflen {
+ w := load64(buf, cursor)
+ // keyEndBytes has no false bit before its first true one, and none at a byte which is not ASCII, which the top
+ // bits add: the first bit is the first byte which ends the plain bytes.
+ if stop := keyEndBytes(w) | w&msb; stop != 0 {
+ cursor += int64(bits.TrailingZeros64(stop) / 8)
+ if buf[cursor] == '"' {
+ return cursor
}
+ return -1
}
- break
+ cursor += 8
}
- return nil, errors.ErrInvalidBeginningOfValue(s.char(), s.totalOffset())
+ return -1
}
-func (d *stringDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
+// scanString finds the string at cursor, and returns its bytes as they are in buf, the position after it and
+// what it found in it, or nil for null.
+//
+// Most strings are short, and scanned by its loop, which calls nothing so that it keeps its values in the
+// registers. After 64 bytes of plain bytes, it stops and returns the bytes of the string so far, -1 minus the
+// position it stopped at, and what it found so far: the caller continues the scan by scanStringRest, which scans
+// the runs of plain bytes of a long string by SIMD where the CPU has it. The position is negative so that the
+// result has no field more, whose return every string would pay for.
+func (d *stringDecoder) scanString(buf []byte, cursor int64) ([]byte, int64, stringInfo, error) {
for {
switch buf[cursor] {
case ' ', '\n', '\t', '\r':
cursor++
case '[':
- return nil, 0, d.errUnmarshalType("array", cursor)
+ return nil, 0, stringInfo{}, d.errUnmarshalType("array", cursor)
case '{':
- return nil, 0, d.errUnmarshalType("object", cursor)
+ return nil, 0, stringInfo{}, d.errUnmarshalType("object", cursor)
case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return nil, 0, d.errUnmarshalType("number", cursor)
+ return nil, 0, stringInfo{}, d.errUnmarshalType("number", cursor)
case '"':
cursor++
start := cursor
b := (*sliceHeader)(unsafe.Pointer(&buf)).data
- escaped := 0
+ buflen := int64(len(buf))
+ firstEscape := int64(-1)
+ // high accumulates the bytes of the string: it is not zero if one of them is not ASCII.
+ var high uint64
+ // The words are read up to wordsEnd: the end of the buffer, or, where the CPU has a SIMD scan, 64
+ // bytes after the start, after which the rest of a long string is left to scanStringRest ( see
+ // scanString ). It is looked at once for a string, not for every word.
+ wordsEnd := buflen
+ if hasStringSIMD {
+ wordsEnd = min(buflen, start+64)
+ }
for {
- switch char(b, cursor) {
+ // The words with nothing to look at are skipped eight bytes at a time: a word is read only where
+ // the buffer has room for it, so that its end is scanned byte by byte.
+ for cursor+8 <= wordsEnd {
+ w := load64(buf, cursor)
+ if special := keyEndBytes(w); special != 0 {
+ i := int64(bits.TrailingZeros64(special) / 8)
+ high |= w & msb & (1<<(uint(i)*8&63) - 1)
+ cursor += i
+ break
+ }
+ high |= w & msb
+ cursor += 8
+ }
+ c := char(b, cursor)
+ switch c {
case '\\':
- escaped++
+ if firstEscape < 0 {
+ firstEscape = cursor - start
+ }
cursor++
switch char(b, cursor) {
case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
cursor++
case 'u':
- buflen := int64(len(buf))
if cursor+5 >= buflen {
- return nil, 0, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
}
for i := int64(1); i <= 4; i++ {
c := char(b, cursor+i)
if !(('0' <= c && c <= '9') || ('a' <= c && c <= 'f') || ('A' <= c && c <= 'F')) {
- return nil, 0, errors.ErrSyntax(fmt.Sprintf("json: invalid character %c in \\u hexadecimal character escape", c), cursor+i)
+ return nil, 0, stringInfo{}, errors.ErrSyntax(fmt.Sprintf("json: invalid character %c in \\u hexadecimal character escape", c), cursor+i)
}
}
cursor += 5
default:
- return nil, 0, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
}
- continue
case '"':
- literal := buf[start:cursor]
- if escaped > 0 {
- literal = literal[:unescapeString(literal)]
+ return buf[start:cursor], cursor + 1, stringInfo{firstEscape: int(firstEscape), nonASCII: high&msb != 0}, nil
+ case nul:
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("string", cursor)
+ default:
+ if c < 0x20 {
+ return nil, 0, stringInfo{}, errors.ErrSyntax(fmt.Sprintf("invalid character %s in string literal", quoteChar(c)), cursor+1)
+ }
+ if wordsEnd != buflen {
+ // the words stopped at wordsEnd, not at a byte to look at
+ return buf[start:cursor], -cursor - 1, stringInfo{firstEscape: int(firstEscape), nonASCII: high&msb != 0}, nil
}
+ high |= uint64(c)
cursor++
- return literal, cursor, nil
- case nul:
- return nil, 0, errors.ErrUnexpectedEndOfJSON("string", cursor)
}
- cursor++
}
case 'n':
if err := validateNull(buf, cursor); err != nil {
- return nil, 0, err
+ return nil, 0, stringInfo{}, err
}
cursor += 4
- return nil, cursor, nil
+ return nil, cursor, stringInfo{}, nil
+ default:
+ return nil, 0, stringInfo{}, errors.ErrInvalidBeginningOfValue(buf[cursor], cursor)
+ }
+ }
+}
+
+// scanStringRest continues the scan of a long string from where scanString stopped, which returned the bytes
+// of the string so far, the position it stopped at and what it found so far: the runs of plain bytes are scanned
+// by SIMD ( see indexStringSpecial ), and a run near the end of the buffer by words. The escapes are validated as
+// scanString does.
+func (d *stringDecoder) scanStringRest(buf, literal []byte, cursor int64, info stringInfo) ([]byte, int64, stringInfo, error) {
+ start := cursor - int64(len(literal))
+ firstEscape := int64(info.firstEscape)
+ var high uint64
+ if info.nonASCII {
+ high = msb
+ }
+ b := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ buflen := int64(len(buf))
+ for {
+ if i, h, ok := indexStringSpecial(unsafe.Add(b, cursor), int(buflen-cursor)); ok {
+ high |= h
+ cursor += int64(i)
+ } else {
+ for cursor+8 <= buflen {
+ w := load64(buf, cursor)
+ if special := keyEndBytes(w); special != 0 {
+ i := int64(bits.TrailingZeros64(special) / 8)
+ high |= w & msb & (1<<(uint(i)*8&63) - 1)
+ cursor += i
+ break
+ }
+ high |= w & msb
+ cursor += 8
+ }
+ }
+ c := char(b, cursor)
+ switch c {
+ case '\\':
+ if firstEscape < 0 {
+ firstEscape = cursor - start
+ }
+ cursor++
+ switch char(b, cursor) {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ cursor++
+ case 'u':
+ if cursor+5 >= buflen {
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
+ }
+ for i := int64(1); i <= 4; i++ {
+ c := char(b, cursor+i)
+ if !(('0' <= c && c <= '9') || ('a' <= c && c <= 'f') || ('A' <= c && c <= 'F')) {
+ return nil, 0, stringInfo{}, errors.ErrSyntax(fmt.Sprintf("json: invalid character %c in \\u hexadecimal character escape", c), cursor+i)
+ }
+ }
+ cursor += 5
+ default:
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
+ }
+ case '"':
+ return buf[start:cursor], cursor + 1, stringInfo{firstEscape: int(firstEscape), nonASCII: high&msb != 0}, nil
+ case nul:
+ return nil, 0, stringInfo{}, errors.ErrUnexpectedEndOfJSON("string", cursor)
default:
- return nil, 0, errors.ErrInvalidBeginningOfValue(buf[cursor], cursor)
+ if c < 0x20 {
+ return nil, 0, stringInfo{}, errors.ErrSyntax(fmt.Sprintf("invalid character %s in string literal", quoteChar(c)), cursor+1)
+ }
+ high |= uint64(c)
+ cursor++
}
}
}
@@ -389,15 +561,66 @@ var unescapeMap = [256]byte{
}
func unsafeAdd(ptr unsafe.Pointer, offset int) unsafe.Pointer {
- return unsafe.Pointer(uintptr(ptr) + uintptr(offset))
+ return unsafe.Add(ptr, offset)
+}
+
+// copyToBackslash copies the bytes from src up to the first backslash of the n bytes, or all of them, to dst, and
+// returns how many it copied: bytes.IndexByte and copy go by vectors. It is not inlined, so that unescapeTo keeps
+// its registers for the short runs, which most are.
+//
+//go:noinline
+func copyToBackslash(dst, src unsafe.Pointer, n int) int {
+ rest := unsafe.Slice((*byte)(src), n)
+ if i := bytes.IndexByte(rest, '\\'); i >= 0 {
+ n = i
+ }
+ copy(unsafe.Slice((*byte)(dst), n), rest[:n])
+ return n
}
-func unescapeString(buf []byte) int {
+// unescapeTo decodes the escapes of the bytes of an escaped string into out, which has room for as many bytes and
+// is not the bytes themselves, and returns the length of the result, which is at most the length of the bytes.
+//
+// first is the offset of the first backslash, which scanString found.
+func unescapeTo(out unsafe.Pointer, buf []byte, first int) int {
p := (*sliceHeader)(unsafe.Pointer(&buf)).data
end := unsafeAdd(p, len(buf))
- src := unsafeAdd(p, bytes.IndexByte(buf, '\\'))
- dst := src
+ // the bytes before the first escape, by words: a short string is not worth a call of memmove.
+ i := 0
+ for ; i+8 <= first; i += 8 {
+ *(*uint64)(unsafeAdd(out, i)) = *(*uint64)(unsafeAdd(p, i))
+ }
+ for ; i < first; i++ {
+ *(*byte)(unsafeAdd(out, i)) = *(*byte)(unsafeAdd(p, i))
+ }
+ src := unsafeAdd(p, first)
+ dst := unsafeAdd(out, first)
for src != end {
+ // The bytes up to the next backslash are copied eight at a time, from the words which are all in the
+ // string. A word is written whole, and the output goes on to its backslash: out has the length of buf, and
+ // is never ahead of the bytes read, so that a word written at dst ends before out does. A run longer than
+ // two words is looked through by bytes.IndexByte and moved by copy, which go by vectors.
+ for words := 0; *(*byte)(src) != '\\' && uintptr(src)+8 <= uintptr(end); words++ {
+ if words == 2 {
+ n := copyToBackslash(dst, src, int(uintptr(end)-uintptr(src)))
+ src = unsafeAdd(src, n)
+ dst = unsafeAdd(dst, n)
+ break
+ }
+ w := binary.LittleEndian.Uint64((*[8]byte)(src)[:])
+ binary.LittleEndian.PutUint64((*[8]byte)(dst)[:], w)
+ if backslash := firstByteMask(w, '\\'); backslash != 0 {
+ n := bits.TrailingZeros64(backslash) / 8
+ src = unsafeAdd(src, n)
+ dst = unsafeAdd(dst, n)
+ break
+ }
+ src = unsafeAdd(src, 8)
+ dst = unsafeAdd(dst, 8)
+ }
+ if src == end {
+ break
+ }
c := char(src, 0)
if c == '\\' {
escapeChar := char(src, 1)
@@ -448,5 +671,40 @@ func unescapeString(buf []byte) int {
dst = unsafeAdd(dst, 1)
}
}
- return int(uintptr(dst) - uintptr(p))
+ return int(uintptr(dst) - uintptr(out))
+}
+
+// firstByteMask returns the word which has the top bit of the first byte of w which is c, if it has one, and maybe
+// the top bits of bytes after it: a subtraction borrows from the next byte only at a byte which is c.
+func firstByteMask(w, c uint64) uint64 {
+ x := w ^ (c * lsb)
+ return (x - lsb) &^ x & msb
+}
+
+// coerceUTF8 returns a copy of the literal in which every byte of an invalid UTF-8 sequence
+// is replaced by utf8.RuneError, as encoding/json does.
+func coerceUTF8(literal []byte) []byte {
+ out := make([]byte, 0, len(literal)+2*utf8.UTFMax)
+ for i := 0; i < len(literal); {
+ r, size := utf8.DecodeRune(literal[i:])
+ if r == utf8.RuneError && size == 1 {
+ out = append(out, runeErrBytes...)
+ } else {
+ out = append(out, literal[i:i+size]...)
+ }
+ i += size
+ }
+ return out
+}
+
+// quoteChar formats c as a quoted character literal, as encoding/json does in its errors.
+func quoteChar(c byte) string {
+ if c == '\'' {
+ return `'\''`
+ }
+ if c == '"' {
+ return `'"'`
+ }
+ s := strconv.Quote(string(c))
+ return "'" + s[1:len(s)-1] + "'"
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.go b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.go
new file mode 100644
index 000000000..ec5246e50
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.go
@@ -0,0 +1,33 @@
+package decoder
+
+import (
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// hasStringSIMD is whether indexStringSpecial scans: whether the CPU has AVX2.
+var hasStringSIMD = runtime.HasAVX2
+
+//go:noescape
+func indexStringSpecialAVX2(p unsafe.Pointer, n int) (index int, high uint64)
+
+// minStringSIMDLength is the number of the bytes from which the rest of a string is scanned by SIMD, after its
+// first words: the call and the setup of the registers cost about as much as a few words of the scalar scan.
+const minStringSIMDLength = 32
+
+// indexStringSpecial returns the index of the first byte of the n bytes at p which is a quote, a backslash or a
+// control character, or n if there is none, and high, which is msb if a byte before it is not ASCII and else 0,
+// as the scan by words accumulates it. The last result is false if the CPU has no SIMD scan or n is less than
+// minStringSIMDLength: nothing is scanned.
+func indexStringSpecial(p unsafe.Pointer, n int) (int, uint64, bool) {
+ if !runtime.HasAVX2 || n < minStringSIMDLength {
+ return 0, 0, false
+ }
+ index, high := indexStringSpecialAVX2(p, n)
+ if high != 0 {
+ // the scan by AVX2 has a bit for every byte which is not ASCII: the callers look at the top bits of bytes.
+ high = msb
+ }
+ return index, high, true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.s b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.s
new file mode 100644
index 000000000..05d53fa56
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_amd64.s
@@ -0,0 +1,83 @@
+#include "textflag.h"
+
+// SPECIAL computes into Yd the lanes of the bytes of Yx which end a run of the plain bytes of a string: a quote, a
+// backslash or a control character ( 0x1f or less, which the unsigned minimum with 0x1f leaves unchanged ). Y8, Y9
+// and Y10 have the quote, the backslash and 0x1f in every lane; Yt is a temporary.
+//
+// Only VEX instructions are used: a legacy SSE instruction mixed with them costs a transition.
+#define SPECIAL(Yx, Yt, Yd) \
+ VPCMPEQB Y8, Yx, Yd \
+ VPCMPEQB Y9, Yx, Yt \
+ VPOR Yt, Yd, Yd \
+ VPMINUB Y10, Yx, Yt \
+ VPCMPEQB Yx, Yt, Yt \
+ VPOR Yt, Yd, Yd
+
+// func indexStringSpecialAVX2(p unsafe.Pointer, n int) (index int, high uint64)
+//
+// It returns the index of the first byte of the n bytes at p which is a quote, a backslash or a control
+// character, or n if there is none, and high, which is not zero if a byte before it is 0x80 or more. n is 32
+// or more. The blocks of 32 bytes are looked at in order, and the last block overlaps the previous one.
+TEXT ·indexStringSpecialAVX2(SB), NOSPLIT, $0-32
+ MOVQ p+0(FP), SI
+ MOVQ n+8(FP), CX
+
+ VPBROADCASTB cQuoteS<>(SB), Y8
+ VPBROADCASTB cBackslashS<>(SB), Y9
+ VPBROADCASTB c1f<>(SB), Y10
+
+ XORQ R8, R8 // the top bits of the bytes before the index
+ MOVQ SI, DI // the address of the block
+ LEAQ -32(SI)(CX*1), R11 // the address of the last block
+loop:
+ CMPQ DI, R11
+ JGT last
+ VMOVDQU (DI), Y0
+ SPECIAL(Y0, Y1, Y2)
+ VPMOVMSKB Y2, DX
+ VPMOVMSKB Y0, BX
+ TESTL DX, DX
+ JNE found
+ ORL BX, R8
+ ADDQ $32, DI
+ JMP loop
+last:
+ // the last block, which overlaps the previous one unless the blocks ended exactly at n.
+ LEAQ (SI)(CX*1), AX
+ CMPQ DI, AX
+ JEQ none
+ MOVQ R11, DI
+ VMOVDQU (DI), Y0
+ SPECIAL(Y0, Y1, Y2)
+ VPMOVMSKB Y2, DX
+ VPMOVMSKB Y0, BX
+ TESTL DX, DX
+ JNE found
+ ORL BX, R8
+none:
+ VZEROUPPER
+ MOVQ CX, index+16(FP)
+ MOVQ R8, high+24(FP)
+ RET
+found:
+ // the top bits of the bytes of the block before the special one: below the lowest bit of DX.
+ MOVL DX, AX
+ NEGL AX
+ ANDL DX, AX
+ DECL AX
+ ANDL AX, BX
+ ORL BX, R8
+ BSFL DX, DX
+ SUBQ SI, DI
+ ADDQ DX, DI
+ VZEROUPPER
+ MOVQ DI, index+16(FP)
+ MOVQ R8, high+24(FP)
+ RET
+
+DATA cQuoteS<>+0(SB)/1, $0x22
+GLOBL cQuoteS<>(SB), RODATA|NOPTR, $1
+DATA cBackslashS<>+0(SB)/1, $0x5c
+GLOBL cBackslashS<>(SB), RODATA|NOPTR, $1
+DATA c1f<>+0(SB)/1, $0x1f
+GLOBL c1f<>(SB), RODATA|NOPTR, $1
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/string_scan_other.go b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_other.go
new file mode 100644
index 000000000..f72610d2b
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/string_scan_other.go
@@ -0,0 +1,13 @@
+//go:build !amd64
+
+package decoder
+
+import "unsafe"
+
+// hasStringSIMD is false: this architecture has no SIMD scan of a string.
+const hasStringSIMD = false
+
+// indexStringSpecial scans nothing: this architecture has no SIMD scan of a string ( see string_scan_amd64.go ).
+func indexStringSpecial(p unsafe.Pointer, n int) (int, uint64, bool) {
+ return 0, 0, false
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/string_unescape.go b/vendor/github.com/goccy/go-json/internal/decoder/string_unescape.go
new file mode 100644
index 000000000..04f9a2ca9
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/string_unescape.go
@@ -0,0 +1,204 @@
+package decoder
+
+import (
+ "fmt"
+ "math/bits"
+ "unicode/utf8"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// decodeStringRest is decodeStringValue for a long string, which scanString stopped in: it scans the rest of the
+// string as scanStringRest does, and, at an escape, leaves the rest to unescapeRest, which decodes the string in
+// the same pass. The loop of a string without an escape keeps nothing more than the one of scanStringRest.
+//
+//go:noinline
+func (d *stringDecoder) decodeStringRest(ctx *RuntimeContext, literal []byte, cursor int64, info stringInfo) (string, int64, bool, error) {
+ if info.firstEscape >= 0 {
+ return d.unescapeRest(ctx, literal, cursor, info)
+ }
+ buf := ctx.Buf
+ start := cursor - int64(len(literal))
+ var high uint64
+ if info.nonASCII {
+ high = msb
+ }
+ b := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ buflen := int64(len(buf))
+ for {
+ if i, h, ok := indexStringSpecial(unsafe.Add(b, cursor), int(buflen-cursor)); ok {
+ high |= h
+ cursor += int64(i)
+ } else {
+ for cursor+8 <= buflen {
+ w := load64(buf, cursor)
+ if special := keyEndBytes(w); special != 0 {
+ i := int64(bits.TrailingZeros64(special) / 8)
+ high |= w & msb & (1<<(uint(i)*8&63) - 1)
+ cursor += i
+ break
+ }
+ high |= w & msb
+ cursor += 8
+ }
+ }
+ c := char(b, cursor)
+ switch c {
+ case '\\':
+ return d.unescapeRest(ctx, buf[start:cursor], cursor, stringInfo{firstEscape: -1, nonASCII: high&msb != 0})
+ case '"':
+ literal := buf[start:cursor]
+ if high&msb != 0 {
+ literal = validLiteral(literal)
+ }
+ return ctx.makeString(literal), cursor + 1, true, nil
+ case nul:
+ return d.skipOtherValue(ctx, errors.ErrUnexpectedEndOfJSON("string", cursor))
+ default:
+ if c < 0x20 {
+ return d.skipOtherValue(ctx, errors.ErrSyntax(fmt.Sprintf("invalid character %s in string literal", quoteChar(c)), cursor+1))
+ }
+ high |= uint64(c)
+ cursor++
+ }
+ }
+}
+
+// unescapeRest continues decodeStringRest from the bytes of the string so far, literal, and the position after
+// them, cursor, which is at an escape or after the first 64 bytes of a string with an escape: it scans the rest
+// of the string and decodes it in the same pass, into the scratch bytes of the context. A run of plain bytes is
+// scanned by SIMD, and moved at the byte which ends it.
+//
+//go:noinline
+func (d *stringDecoder) unescapeRest(ctx *RuntimeContext, literal []byte, cursor int64, info stringInfo) (string, int64, bool, error) {
+ buf := ctx.Buf
+ start := cursor - int64(len(literal))
+ var high uint64
+ if info.nonASCII {
+ high = msb
+ }
+ escaped := info.firstEscape >= 0
+ out := ctx.unescaped[:0]
+ if escaped {
+ out = growBytes(out, len(literal)+64)
+ out = out[:unescapeTo(unsafe.Pointer(unsafe.SliceData(out)), literal, info.firstEscape)]
+ }
+ // run is the position of the plain bytes which are not in out yet, once the string has an escape.
+ run := cursor
+ b := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ buflen := int64(len(buf))
+ for {
+ if i, h, ok := indexStringSpecial(unsafe.Add(b, cursor), int(buflen-cursor)); ok {
+ high |= h
+ cursor += int64(i)
+ } else {
+ for cursor+8 <= buflen {
+ w := load64(buf, cursor)
+ if special := keyEndBytes(w); special != 0 {
+ i := int64(bits.TrailingZeros64(special) / 8)
+ high |= w & msb & (1<<(uint(i)*8&63) - 1)
+ cursor += i
+ break
+ }
+ high |= w & msb
+ cursor += 8
+ }
+ }
+ c := char(b, cursor)
+ switch c {
+ case '\\':
+ if escaped {
+ out = append(out, buf[run:cursor]...)
+ } else {
+ escaped = true
+ out = append(growBytes(out, int(cursor-start)+64), buf[start:cursor]...)
+ }
+ cursor++
+ switch e := char(b, cursor); e {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ out = append(out, unescapeMap[e])
+ cursor++
+ case 'u':
+ code, ok := hex4(b, cursor+1, buflen)
+ if !ok {
+ return d.skipOtherValue(ctx, d.hexError(buf, cursor))
+ }
+ cursor += 5
+ if code >= 0xd800 && code < 0xdc00 && char(b, cursor) == '\\' && cursor+1 < buflen && char(b, cursor+1) == 'u' {
+ if lo, ok := hex4(b, cursor+2, buflen); ok && lo >= 0xdc00 && lo < 0xe000 {
+ code = (code-0xd800)<<10 | (lo - 0xdc00) + 0x10000
+ cursor += 6
+ }
+ }
+ out = utf8.AppendRune(out, code)
+ default:
+ return d.skipOtherValue(ctx, errors.ErrUnexpectedEndOfJSON("escaped string", cursor))
+ }
+ run = cursor
+ case '"':
+ next := cursor + 1
+ if !escaped {
+ literal := buf[start:cursor]
+ if high&msb != 0 {
+ literal = validLiteral(literal)
+ }
+ return ctx.makeString(literal), next, true, nil
+ }
+ out = append(out, buf[run:cursor]...)
+ if cap(out) <= maxUnescapeScratchSize {
+ ctx.unescaped = out[:0]
+ }
+ if high&msb != 0 && !utf8.Valid(out) {
+ return string(coerceUTF8(out)), next, true, nil
+ }
+ return ctx.copyString(out), next, true, nil
+ case nul:
+ return d.skipOtherValue(ctx, errors.ErrUnexpectedEndOfJSON("string", cursor))
+ default:
+ if c < 0x20 {
+ return d.skipOtherValue(ctx, errors.ErrSyntax(fmt.Sprintf("invalid character %s in string literal", quoteChar(c)), cursor+1))
+ }
+ high |= uint64(c)
+ cursor++
+ }
+ }
+}
+
+// growBytes returns b with room for n bytes more.
+func growBytes(b []byte, n int) []byte {
+ if cap(b)-len(b) < n {
+ b = append(b[:cap(b)], make([]byte, n)...)[:len(b)]
+ }
+ return b
+}
+
+// hex4 returns the code of the four hexadecimal digits at pos, and false if they are not four of them.
+func hex4(b unsafe.Pointer, pos, buflen int64) (rune, bool) {
+ if pos+4 >= buflen {
+ return 0, false
+ }
+ var code rune
+ for i := int64(0); i < 4; i++ {
+ c := char(b, pos+i)
+ if !(('0' <= c && c <= '9') || ('a' <= c && c <= 'f') || ('A' <= c && c <= 'F')) {
+ return 0, false
+ }
+ code = code<<4 | rune(hexToInt[c])
+ }
+ return code, true
+}
+
+// hexError returns the error of the \u escape at pos, whose digits are not four hexadecimal ones, as scanString does.
+func (d *stringDecoder) hexError(buf []byte, pos int64) error {
+ if pos+5 >= int64(len(buf)) {
+ return errors.ErrUnexpectedEndOfJSON("escaped string", pos)
+ }
+ for i := int64(1); i <= 4; i++ {
+ c := buf[pos+i]
+ if !(('0' <= c && c <= '9') || ('a' <= c && c <= 'f') || ('A' <= c && c <= 'F')) {
+ return errors.ErrSyntax(fmt.Sprintf("json: invalid character %c in \\u hexadecimal character escape", c), pos+i)
+ }
+ }
+ return errors.ErrUnexpectedEndOfJSON("escaped string", pos)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/struct.go b/vendor/github.com/goccy/go-json/internal/decoder/struct.go
index 313da153b..04c164019 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/struct.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/struct.go
@@ -2,12 +2,8 @@ package decoder
import (
"fmt"
- "math"
"math/bits"
- "sort"
- "strings"
- "unicode"
- "unicode/utf16"
+ "reflect"
"unsafe"
"github.com/goccy/go-json/internal/errors"
@@ -24,802 +20,203 @@ type structFieldSet struct {
}
type structDecoder struct {
- fieldMap map[string]*structFieldSet
+ // fields are the fields of the struct in their order, by their exact keys.
+ fields []*structFieldSet
+ keys *structKeys
+ // fieldUniqueNameNum is the number of the fields which differ by their folded keys: under FirstWinOption,
+ // the rest of an object is skipped when every one of them was decoded.
fieldUniqueNameNum int
stringDecoder *stringDecoder
structName string
fieldName string
- isTriedOptimize bool
- keyBitmapUint8 [][256]uint8
- keyBitmapUint16 [][256]uint16
- sortedFieldSets []*structFieldSet
- keyDecoder func(*structDecoder, []byte, int64) (int64, *structFieldSet, error)
- keyStreamDecoder func(*structDecoder, *Stream) (*structFieldSet, string, error)
+ // typ is the struct type, and typeName its name, which the type errors report.
+ typ reflect.Type
+ typeName string
+ // embedded are the names of the embedded fields which the fields are promoted through, from the struct, which
+ // only the type errors report ( see typeErrorPath ).
+ embedded map[*structFieldSet][]string
}
-var (
- largeToSmallTable [256]byte
-)
-
-func init() {
- for i := 0; i < 256; i++ {
- c := i
- if 'A' <= c && c <= 'Z' {
- c += 'a' - 'A'
- }
- largeToSmallTable[i] = byte(c)
- }
-}
-
-func toASCIILower(s string) string {
- b := []byte(s)
- for i := range b {
- b[i] = largeToSmallTable[b[i]]
- }
- return string(b)
-}
-
-func newStructDecoder(structName, fieldName string, fieldMap map[string]*structFieldSet) *structDecoder {
+func newStructDecoder(structName, fieldName string) *structDecoder {
return &structDecoder{
- fieldMap: fieldMap,
- stringDecoder: newStringDecoder(structName, fieldName),
- structName: structName,
- fieldName: fieldName,
- keyDecoder: decodeKey,
- keyStreamDecoder: decodeKeyStream,
+ keys: newStructKeys(nil),
+ stringDecoder: newStringDecoder(structName, fieldName),
+ structName: structName,
+ fieldName: fieldName,
}
}
-const (
- allowOptimizeMaxKeyLen = 64
- allowOptimizeMaxFieldLen = 16
-)
-
-func (d *structDecoder) tryOptimize() {
- fieldUniqueNameMap := map[string]int{}
- fieldIdx := -1
- for k, v := range d.fieldMap {
- lower := strings.ToLower(k)
- idx, exists := fieldUniqueNameMap[lower]
- if exists {
- v.fieldIdx = idx
- } else {
- fieldIdx++
- v.fieldIdx = fieldIdx
- }
- fieldUniqueNameMap[lower] = fieldIdx
- }
- d.fieldUniqueNameNum = len(fieldUniqueNameMap)
-
- if d.isTriedOptimize {
- return
- }
- fieldMap := map[string]*structFieldSet{}
- conflicted := map[string]struct{}{}
- for k, v := range d.fieldMap {
- key := strings.ToLower(k)
- if key != k {
- if key != toASCIILower(k) {
- d.isTriedOptimize = true
- return
- }
- // already exists same key (e.g. Hello and HELLO has same lower case key
- if _, exists := conflicted[key]; exists {
- d.isTriedOptimize = true
- return
- }
- conflicted[key] = struct{}{}
- }
- if field, exists := fieldMap[key]; exists {
- if field != v {
- d.isTriedOptimize = true
- return
- }
- }
- fieldMap[key] = v
- }
-
- if len(fieldMap) > allowOptimizeMaxFieldLen {
- d.isTriedOptimize = true
- return
- }
-
- var maxKeyLen int
- sortedKeys := []string{}
- for key := range fieldMap {
- keyLen := len(key)
- if keyLen > allowOptimizeMaxKeyLen {
- d.isTriedOptimize = true
- return
- }
- if maxKeyLen < keyLen {
- maxKeyLen = keyLen
- }
- sortedKeys = append(sortedKeys, key)
- }
- sort.Strings(sortedKeys)
-
- // By allocating one extra capacity than `maxKeyLen`,
- // it is possible to avoid the process of comparing the index of the key with the length of the bitmap each time.
- bitmapLen := maxKeyLen + 1
- if len(sortedKeys) <= 8 {
- keyBitmap := make([][256]uint8, bitmapLen)
- for i, key := range sortedKeys {
- for j := 0; j < len(key); j++ {
- c := key[j]
- keyBitmap[j][c] |= (1 << uint(i))
- }
- d.sortedFieldSets = append(d.sortedFieldSets, fieldMap[key])
- }
- d.keyBitmapUint8 = keyBitmap
- d.keyDecoder = decodeKeyByBitmapUint8
- d.keyStreamDecoder = decodeKeyByBitmapUint8Stream
- } else {
- keyBitmap := make([][256]uint16, bitmapLen)
- for i, key := range sortedKeys {
- for j := 0; j < len(key); j++ {
- c := key[j]
- keyBitmap[j][c] |= (1 << uint(i))
- }
- d.sortedFieldSets = append(d.sortedFieldSets, fieldMap[key])
- }
- d.keyBitmapUint16 = keyBitmap
- d.keyDecoder = decodeKeyByBitmapUint16
- d.keyStreamDecoder = decodeKeyByBitmapUint16Stream
- }
+// setFields sets the fields of the struct, which are in the order of the struct, and makes their tables.
+func (d *structDecoder) setFields(fields []*structFieldSet) {
+ d.fields = fields
+ d.keys = newStructKeys(fields)
+ indexByFolded := map[string]int{}
+ for _, field := range fields {
+ folded := string(appendFoldedKey(nil, []byte(field.key)))
+ idx, exists := indexByFolded[folded]
+ if !exists {
+ idx = len(indexByFolded)
+ indexByFolded[folded] = idx
+ }
+ field.fieldIdx = idx
+ }
+ d.fieldUniqueNameNum = len(indexByFolded)
}
-// decode from '\uXXXX'
-func decodeKeyCharByUnicodeRune(buf []byte, cursor int64) ([]byte, int64, error) {
- const defaultOffset = 4
- const surrogateOffset = 6
-
- if cursor+defaultOffset >= int64(len(buf)) {
- return nil, 0, errors.ErrUnexpectedEndOfJSON("escaped string", cursor)
- }
-
- r := unicodeToRune(buf[cursor : cursor+defaultOffset])
- if utf16.IsSurrogate(r) {
- cursor += defaultOffset
- if cursor+surrogateOffset >= int64(len(buf)) || buf[cursor] != '\\' || buf[cursor+1] != 'u' {
- return []byte(string(unicode.ReplacementChar)), cursor + defaultOffset - 1, nil
- }
- cursor += 2
- r2 := unicodeToRune(buf[cursor : cursor+defaultOffset])
- if r := utf16.DecodeRune(r, r2); r != unicode.ReplacementChar {
- return []byte(string(r)), cursor + defaultOffset - 1, nil
- }
- }
- return []byte(string(r)), cursor + defaultOffset - 1, nil
-}
-
-func decodeKeyCharByEscapedChar(buf []byte, cursor int64) ([]byte, int64, error) {
- c := buf[cursor]
- cursor++
- switch c {
- case '"':
- return []byte{'"'}, cursor, nil
- case '\\':
- return []byte{'\\'}, cursor, nil
- case '/':
- return []byte{'/'}, cursor, nil
- case 'b':
- return []byte{'\b'}, cursor, nil
- case 'f':
- return []byte{'\f'}, cursor, nil
- case 'n':
- return []byte{'\n'}, cursor, nil
- case 'r':
- return []byte{'\r'}, cursor, nil
- case 't':
- return []byte{'\t'}, cursor, nil
- case 'u':
- return decodeKeyCharByUnicodeRune(buf, cursor)
- }
- return nil, cursor, nil
-}
-
-func decodeKeyByBitmapUint8(d *structDecoder, buf []byte, cursor int64) (int64, *structFieldSet, error) {
- var (
- curBit uint8 = math.MaxUint8
- )
- b := (*sliceHeader)(unsafe.Pointer(&buf)).data
- for {
- switch char(b, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- case '"':
- cursor++
- c := char(b, cursor)
- switch c {
- case '"':
- cursor++
- return cursor, nil, nil
- case nul:
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- }
- keyIdx := 0
- bitmap := d.keyBitmapUint8
- start := cursor
- for {
- c := char(b, cursor)
- switch c {
- case '"':
- fieldSetIndex := bits.TrailingZeros8(curBit)
- field := d.sortedFieldSets[fieldSetIndex]
- keyLen := cursor - start
- cursor++
- if keyLen < field.keyLen {
- // early match
- return cursor, nil, nil
- }
- return cursor, field, nil
- case nul:
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- case '\\':
- cursor++
- chars, nextCursor, err := decodeKeyCharByEscapedChar(buf, cursor)
- if err != nil {
- return 0, nil, err
- }
- for _, c := range chars {
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- return decodeKeyNotFound(b, cursor)
- }
- keyIdx++
- }
- cursor = nextCursor
- default:
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- return decodeKeyNotFound(b, cursor)
- }
- keyIdx++
- }
- cursor++
- }
- default:
- return cursor, nil, errors.ErrInvalidBeginningOfValue(char(b, cursor), cursor)
- }
- }
-}
-
-func decodeKeyByBitmapUint16(d *structDecoder, buf []byte, cursor int64) (int64, *structFieldSet, error) {
- var (
- curBit uint16 = math.MaxUint16
- )
- b := (*sliceHeader)(unsafe.Pointer(&buf)).data
- for {
- switch char(b, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- case '"':
- cursor++
- c := char(b, cursor)
- switch c {
- case '"':
- cursor++
- return cursor, nil, nil
- case nul:
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- }
- keyIdx := 0
- bitmap := d.keyBitmapUint16
- start := cursor
- for {
- c := char(b, cursor)
- switch c {
- case '"':
- fieldSetIndex := bits.TrailingZeros16(curBit)
- field := d.sortedFieldSets[fieldSetIndex]
- keyLen := cursor - start
- cursor++
- if keyLen < field.keyLen {
- // early match
- return cursor, nil, nil
- }
- return cursor, field, nil
- case nul:
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- case '\\':
- cursor++
- chars, nextCursor, err := decodeKeyCharByEscapedChar(buf, cursor)
- if err != nil {
- return 0, nil, err
- }
- for _, c := range chars {
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- return decodeKeyNotFound(b, cursor)
- }
- keyIdx++
- }
- cursor = nextCursor
- default:
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- return decodeKeyNotFound(b, cursor)
- }
- keyIdx++
- }
- cursor++
- }
- default:
- return cursor, nil, errors.ErrInvalidBeginningOfValue(char(b, cursor), cursor)
- }
- }
-}
-
-func decodeKeyNotFound(b unsafe.Pointer, cursor int64) (int64, *structFieldSet, error) {
- for {
- cursor++
- switch char(b, cursor) {
- case '"':
- cursor++
- return cursor, nil, nil
- case '\\':
- cursor++
- if char(b, cursor) == nul {
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- }
- case nul:
- return 0, nil, errors.ErrUnexpectedEndOfJSON("string", cursor)
- }
- }
-}
-
-func decodeKey(d *structDecoder, buf []byte, cursor int64) (int64, *structFieldSet, error) {
- key, c, err := d.stringDecoder.decodeByte(buf, cursor)
- if err != nil {
- return 0, nil, err
- }
- cursor = c
- k := *(*string)(unsafe.Pointer(&key))
- field, exists := d.fieldMap[k]
- if !exists {
- return cursor, nil, nil
- }
- return cursor, field, nil
-}
-
-func decodeKeyByBitmapUint8Stream(d *structDecoder, s *Stream) (*structFieldSet, string, error) {
- var (
- curBit uint8 = math.MaxUint8
- )
- _, cursor, p := s.stat()
- for {
- switch char(p, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return nil, "", errors.ErrInvalidBeginningOfValue(char(p, cursor), s.totalOffset())
- case '"':
- cursor++
- FIRST_CHAR:
- start := cursor
- switch char(p, cursor) {
- case '"':
- cursor++
- s.cursor = cursor
- return nil, "", nil
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- goto FIRST_CHAR
- }
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- }
- keyIdx := 0
- bitmap := d.keyBitmapUint8
- for {
- c := char(p, cursor)
- switch c {
- case '"':
- fieldSetIndex := bits.TrailingZeros8(curBit)
- field := d.sortedFieldSets[fieldSetIndex]
- keyLen := cursor - start
- cursor++
- s.cursor = cursor
- if keyLen < field.keyLen {
- // early match
- return nil, field.key, nil
- }
- return field, field.key, nil
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- case '\\':
- s.cursor = cursor + 1 // skip '\' char
- chars, err := decodeKeyCharByEscapeCharStream(s)
- if err != nil {
- return nil, "", err
- }
- cursor = s.cursor
- for _, c := range chars {
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- s.cursor = cursor
- return decodeKeyNotFoundStream(s, start)
- }
- keyIdx++
- }
- default:
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- s.cursor = cursor
- return decodeKeyNotFoundStream(s, start)
- }
- keyIdx++
- }
- cursor++
- }
- default:
- return nil, "", errors.ErrInvalidBeginningOfValue(char(p, cursor), s.totalOffset())
- }
- }
-}
-
-func decodeKeyByBitmapUint16Stream(d *structDecoder, s *Stream) (*structFieldSet, string, error) {
- var (
- curBit uint16 = math.MaxUint16
- )
- _, cursor, p := s.stat()
- for {
- switch char(p, cursor) {
- case ' ', '\n', '\t', '\r':
- cursor++
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return nil, "", errors.ErrInvalidBeginningOfValue(char(p, cursor), s.totalOffset())
- case '"':
- cursor++
- FIRST_CHAR:
- start := cursor
- switch char(p, cursor) {
- case '"':
- cursor++
- s.cursor = cursor
- return nil, "", nil
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- goto FIRST_CHAR
- }
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- }
- keyIdx := 0
- bitmap := d.keyBitmapUint16
- for {
- c := char(p, cursor)
- switch c {
- case '"':
- fieldSetIndex := bits.TrailingZeros16(curBit)
- field := d.sortedFieldSets[fieldSetIndex]
- keyLen := cursor - start
- cursor++
- s.cursor = cursor
- if keyLen < field.keyLen {
- // early match
- return nil, field.key, nil
- }
- return field, field.key, nil
- case nul:
- s.cursor = cursor
- if s.read() {
- _, cursor, p = s.stat()
- continue
- }
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- case '\\':
- s.cursor = cursor + 1 // skip '\' char
- chars, err := decodeKeyCharByEscapeCharStream(s)
- if err != nil {
- return nil, "", err
- }
- cursor = s.cursor
- for _, c := range chars {
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- s.cursor = cursor
- return decodeKeyNotFoundStream(s, start)
- }
- keyIdx++
- }
- default:
- curBit &= bitmap[keyIdx][largeToSmallTable[c]]
- if curBit == 0 {
- s.cursor = cursor
- return decodeKeyNotFoundStream(s, start)
- }
- keyIdx++
- }
- cursor++
- }
- default:
- return nil, "", errors.ErrInvalidBeginningOfValue(char(p, cursor), s.totalOffset())
- }
- }
-}
-
-// decode from '\uXXXX'
-func decodeKeyCharByUnicodeRuneStream(s *Stream) ([]byte, error) {
- const defaultOffset = 4
- const surrogateOffset = 6
-
- if s.cursor+defaultOffset >= s.length {
- if !s.read() {
- return nil, errors.ErrInvalidCharacter(s.char(), "escaped unicode char", s.totalOffset())
- }
- }
-
- r := unicodeToRune(s.buf[s.cursor : s.cursor+defaultOffset])
- if utf16.IsSurrogate(r) {
- s.cursor += defaultOffset
- if s.cursor+surrogateOffset >= s.length {
- s.read()
- }
- if s.cursor+surrogateOffset >= s.length || s.buf[s.cursor] != '\\' || s.buf[s.cursor+1] != 'u' {
- s.cursor += defaultOffset - 1
- return []byte(string(unicode.ReplacementChar)), nil
- }
- r2 := unicodeToRune(s.buf[s.cursor+defaultOffset+2 : s.cursor+surrogateOffset])
- if r := utf16.DecodeRune(r, r2); r != unicode.ReplacementChar {
- s.cursor += defaultOffset - 1
- return []byte(string(r)), nil
- }
- }
- s.cursor += defaultOffset - 1
- return []byte(string(r)), nil
-}
-
-func decodeKeyCharByEscapeCharStream(s *Stream) ([]byte, error) {
- c := s.buf[s.cursor]
- s.cursor++
-RETRY:
- switch c {
- case '"':
- return []byte{'"'}, nil
- case '\\':
- return []byte{'\\'}, nil
- case '/':
- return []byte{'/'}, nil
- case 'b':
- return []byte{'\b'}, nil
- case 'f':
- return []byte{'\f'}, nil
- case 'n':
- return []byte{'\n'}, nil
- case 'r':
- return []byte{'\r'}, nil
- case 't':
- return []byte{'\t'}, nil
- case 'u':
- return decodeKeyCharByUnicodeRuneStream(s)
- case nul:
- if !s.read() {
- return nil, errors.ErrInvalidCharacter(s.char(), "escaped char", s.totalOffset())
- }
- goto RETRY
- default:
- return nil, errors.ErrUnexpectedEndOfJSON("struct field", s.totalOffset())
- }
-}
-
-func decodeKeyNotFoundStream(s *Stream, start int64) (*structFieldSet, string, error) {
- buf, cursor, p := s.stat()
- for {
- cursor++
- switch char(p, cursor) {
- case '"':
- b := buf[start:cursor]
- key := *(*string)(unsafe.Pointer(&b))
- cursor++
- s.cursor = cursor
- return nil, key, nil
- case '\\':
- cursor++
- if char(p, cursor) == nul {
- s.cursor = cursor
- if !s.read() {
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- }
- buf, cursor, p = s.statForRetry()
- }
- case nul:
- s.cursor = cursor
- if !s.read() {
- return nil, "", errors.ErrUnexpectedEndOfJSON("string", s.totalOffset())
- }
- buf, cursor, p = s.statForRetry()
- }
- }
-}
-
-func decodeKeyStream(d *structDecoder, s *Stream) (*structFieldSet, string, error) {
- key, err := d.stringDecoder.decodeStreamByte(s)
- if err != nil {
- return nil, "", err
- }
- k := *(*string)(unsafe.Pointer(&key))
- return d.fieldMap[k], k, nil
-}
-
-func (d *structDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
+func (d *structDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
depth++
if depth > maxDecodeNestingDepth {
- return errors.ErrExceededMaxDepth(s.char(), s.cursor)
+ return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
}
-
- c := s.skipWhiteSpace()
- switch c {
+ buflen := int64(len(buf))
+ cursor = skipWhiteSpace(buf, cursor)
+ b := (*sliceHeader)(unsafe.Pointer(&buf)).data
+ switch char(b, cursor) {
case 'n':
- if err := nullBytes(s); err != nil {
- return err
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
}
- return nil
+ cursor += 4
+ return cursor, nil
+ case '{':
default:
- if s.char() != '{' {
- return errors.ErrInvalidBeginningOfValue(s.char(), s.totalOffset())
- }
+ return d.decodeOther(ctx, cursor, depth-1)
}
- s.cursor++
- if s.skipWhiteSpace() == '}' {
- s.cursor++
- return nil
+ cursor++
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == '}' {
+ cursor++
+ return cursor, nil
}
- var (
- seenFields map[int]struct{}
- seenFieldNum int
- )
- firstWin := (s.Option.Flags & FirstWinOption) != 0
- if firstWin {
- seenFields = make(map[int]struct{}, d.fieldUniqueNameNum)
+ if (ctx.Option.Flags & FirstWinOption) != 0 {
+ return d.decodeObjectFirstWin(ctx, cursor, depth, p)
}
+ disallowUnknownFields := (ctx.Option.Flags & DisallowUnknownFieldsOption) != 0
for {
- s.reset()
- field, key, err := d.keyStreamDecoder(d, s)
+ field, c, err := d.decodeKey(buf, cursor, disallowUnknownFields)
if err != nil {
- return err
+ return 0, err
+ }
+ if char(b, c) == ':' {
+ cursor = c + 1
+ } else {
+ cursor = skipWhiteSpace(buf, c)
+ if char(b, cursor) != ':' {
+ return 0, errors.ErrExpected("colon after object key", cursor)
+ }
+ cursor++
}
- if s.skipWhiteSpace() != ':' {
- return errors.ErrExpected("colon after object key", s.totalOffset())
+ if cursor >= buflen {
+ return 0, errors.ErrExpected("object value after colon", cursor)
}
- s.cursor++
if field != nil {
if field.err != nil {
- return field.err
- }
- if firstWin {
- if _, exists := seenFields[field.fieldIdx]; exists {
- if err := s.skipValue(depth); err != nil {
- return err
- }
- } else {
- if err := field.dec.DecodeStream(s, depth, unsafe.Pointer(uintptr(p)+field.offset)); err != nil {
- return err
- }
- seenFieldNum++
- if d.fieldUniqueNameNum <= seenFieldNum {
- return s.skipObject(depth)
- }
- seenFields[field.fieldIdx] = struct{}{}
+ // a field which can't be set: the error is recorded as a type error, and the decoding goes on
+ c, err := d.unsettableField(ctx, cursor, depth, field.err)
+ if err != nil {
+ return 0, err
}
+ cursor = c
} else {
- if err := field.dec.DecodeStream(s, depth, unsafe.Pointer(uintptr(p)+field.offset)); err != nil {
- return err
+ c, err := field.dec.Decode(ctx, cursor, depth, unsafe.Add(p, field.offset))
+ if err != nil {
+ return 0, err
}
+ cursor = c
}
- } else if s.DisallowUnknownFields {
- return fmt.Errorf("json: unknown field %q", key)
} else {
- if err := s.skipValue(depth); err != nil {
- return err
+ c, err := skipValue(buf, cursor, depth)
+ if err != nil {
+ return 0, err
}
+ cursor = c
}
- c := s.skipWhiteSpace()
- if c == '}' {
- s.cursor++
- return nil
+ cursor = skipWhiteSpace(buf, cursor)
+ if char(b, cursor) == '}' {
+ cursor++
+ return cursor, nil
}
- if c != ',' {
- return errors.ErrExpected("comma after object element", s.totalOffset())
+ if char(b, cursor) != ',' {
+ return 0, errors.ErrExpected("comma after object element", cursor)
}
- s.cursor++
+ cursor++
}
}
-func (d *structDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+// decodeObjectFirstWin is the loop of Decode under FirstWinOption, from the first key of a non-empty object at
+// cursor: a field is decoded at its first key, the value of a later key of the field is skipped, and the rest of
+// the object is skipped once every field is decoded. It is a function of its own, so that the loop of Decode keeps
+// nothing of it in its registers.
+func (d *structDecoder) decodeObjectFirstWin(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
- depth++
- if depth > maxDecodeNestingDepth {
- return 0, errors.ErrExceededMaxDepth(buf[cursor], cursor)
- }
buflen := int64(len(buf))
- cursor = skipWhiteSpace(buf, cursor)
b := (*sliceHeader)(unsafe.Pointer(&buf)).data
- switch char(b, cursor) {
- case 'n':
- if err := validateNull(buf, cursor); err != nil {
- return 0, err
- }
- cursor += 4
- return cursor, nil
- case '{':
- default:
- return 0, errors.ErrInvalidBeginningOfValue(char(b, cursor), cursor)
- }
- cursor++
- cursor = skipWhiteSpace(buf, cursor)
- if buf[cursor] == '}' {
- cursor++
- return cursor, nil
- }
+ // seen and seenMore are the fields decoded in the object, by their indexes: the bits of seen are the first 64
+ // fields, and the ones of seenMore the others ( see decodedBefore ); seenFieldNum is their number.
var (
- seenFields map[int]struct{}
+ seen uint64
+ seenMore []uint64
seenFieldNum int
)
- firstWin := (ctx.Option.Flags & FirstWinOption) != 0
- if firstWin {
- seenFields = make(map[int]struct{}, d.fieldUniqueNameNum)
- }
+ disallowUnknownFields := (ctx.Option.Flags & DisallowUnknownFieldsOption) != 0
for {
- c, field, err := d.keyDecoder(d, buf, cursor)
+ field, c, err := d.decodeKey(buf, cursor, disallowUnknownFields)
if err != nil {
return 0, err
}
- cursor = skipWhiteSpace(buf, c)
- if char(b, cursor) != ':' {
- return 0, errors.ErrExpected("colon after object key", cursor)
+ if char(b, c) == ':' {
+ cursor = c + 1
+ } else {
+ cursor = skipWhiteSpace(buf, c)
+ if char(b, cursor) != ':' {
+ return 0, errors.ErrExpected("colon after object key", cursor)
+ }
+ cursor++
}
- cursor++
if cursor >= buflen {
return 0, errors.ErrExpected("object value after colon", cursor)
}
if field != nil {
+ // the first 64 fields are the bits of seen, in a register; the others are looked at by a call
+ var decoded bool
if field.err != nil {
- return 0, field.err
- }
- if firstWin {
- if _, exists := seenFields[field.fieldIdx]; exists {
- c, err := skipValue(buf, cursor, depth)
- if err != nil {
- return 0, err
- }
- cursor = c
- } else {
- c, err := field.dec.Decode(ctx, cursor, depth, unsafe.Pointer(uintptr(p)+field.offset))
- if err != nil {
- return 0, err
- }
- cursor = c
- seenFieldNum++
- if d.fieldUniqueNameNum <= seenFieldNum {
- return skipObject(buf, cursor, depth)
- }
- seenFields[field.fieldIdx] = struct{}{}
+ // a field which can't be set: the error is recorded as a type error, and the decoding goes on
+ c, err := d.unsettableField(ctx, cursor, depth, field.err)
+ if err != nil {
+ return 0, err
}
+ cursor = c
+ } else if idx := field.fieldIdx; idx < 64 {
+ bit := uint64(1) << uint(idx)
+ decoded = seen&bit != 0
+ seen |= bit
} else {
- c, err := field.dec.Decode(ctx, cursor, depth, unsafe.Pointer(uintptr(p)+field.offset))
+ decoded = d.decodedBefore(idx, &seenMore)
+ }
+ switch {
+ case field.err != nil:
+ case decoded:
+ c, err := skipValue(buf, cursor, depth)
+ if err != nil {
+ return 0, err
+ }
+ cursor = c
+ default:
+ c, err := field.dec.Decode(ctx, cursor, depth, unsafe.Add(p, field.offset))
if err != nil {
return 0, err
}
cursor = c
+ seenFieldNum++
+ if d.fieldUniqueNameNum <= seenFieldNum {
+ // every field is decoded: the rest of the object is skipped, which is nothing in most objects,
+ // whose last key is the last field
+ if cursor = skipWhiteSpace(buf, cursor); char(b, cursor) == '}' {
+ return cursor + 1, nil
+ }
+ return skipRestOfObject(buf, cursor, depth)
+ }
}
} else {
c, err := skipValue(buf, cursor, depth)
@@ -840,6 +237,221 @@ func (d *structDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsaf
}
}
+// decodedBefore reports whether the field of the index, which is 64 or more, was decoded before in the object, under
+// FirstWinOption, and marks it decoded: its bit is in more, which is made for a struct of more than 64 fields when
+// such a field is decoded. The first 64 fields are marked in decodeObjectFirstWin itself, without an allocation.
+//
+//go:noinline
+func (d *structDecoder) decodedBefore(idx int, more *[]uint64) bool {
+ if *more == nil {
+ *more = make([]uint64, (d.fieldUniqueNameNum-64+63)/64)
+ }
+ idx -= 64
+ w, bit := &(*more)[idx/64], uint64(1)<> 8
+ w0 &= m
+ fw := foldASCIIWord(w0)
+ e := &keys.entries[keys.index(w0|bit5&m, 0)]
+ var field *structFieldSet
+ if e.short == fw {
+ field = e.unique
+ } else if e.fields != nil && keys.hasLength(n) {
+ field = keys.findASCII(buf[start:start+int64(n)], w0, 0)
+ }
+ if field == nil && disallowUnknownFields {
+ return nil, 0, unknownFieldError(buf[start : start+int64(n)])
+ }
+ return field, start + int64(n) + 1, nil
+ }
+ // A key of 8 bytes or more, whose end is looked for word by word. It is looked up by its first and last
+ // words, as a short key is.
+ end := start + 8
+ special = specialKeyBytes(load64(buf, end))
+ for special == 0 {
+ end += 8
+ if end+8 > int64(cap(buf)) {
+ return d.decodeKeyByScan(buf, cursor, disallowUnknownFields)
+ }
+ special = specialKeyBytes(load64(buf, end))
+ }
+ end += int64(bits.TrailingZeros64(special) / 8)
+ if buf[end] != '"' {
+ return d.decodeKeyNotASCII(buf, cursor, disallowUnknownFields)
+ }
+ key := buf[start:end]
+ n := len(key)
+ var field *structFieldSet
+ // A key of a length which no field has, which is a key of no field in most objects of such a length,
+ // is not looked up.
+ if keys.hasLength(n) {
+ w1 := load64(buf, end-8)
+ fw0, fw1 := foldASCIIWord(w0), foldASCIIWord(w1)
+ e := &keys.entries[keys.index(w0|bit5, w1|bit5)]
+ if e.n == n && e.w0 == fw0 && e.w1 == fw1 && e.unique != nil && (n <= 16 || equalFoldedASCII(key, e.folded)) {
+ field = e.unique
+ } else if e.fields != nil {
+ field = keys.findASCII(key, w0, w1)
+ }
+ }
+ if field == nil && disallowUnknownFields {
+ return nil, 0, unknownFieldError(key)
+ }
+ return field, end + 1, nil
+ }
+ return d.decodeKeyByScan(buf, cursor, disallowUnknownFields)
+}
+
+// decodeKeyNotASCII is decodeKey for a key which has a byte which is not ASCII, or an escape. A key without an
+// escape is read word by word too, and looked up by its bytes as they are among the keys which are not ASCII
+// first: a key is usually the same as the key of its field, which it is found by whatever the fold of its runes,
+// because a key which is the same wins over the others. Any other key is folded rune by rune if its runes may
+// fold to the ones of a key, and else is of no field. A key with an escape is scanned as a string.
+func (d *structDecoder) decodeKeyNotASCII(buf []byte, cursor int64, disallowUnknownFields bool) (*structFieldSet, int64, error) {
+ start := cursor + 1
+ end := start
+ for {
+ if end+8 > int64(cap(buf)) {
+ return d.decodeKeyByScan(buf, cursor, disallowUnknownFields)
+ }
+ if special := keyEndBytes(load64(buf, end)); special != 0 {
+ end += int64(bits.TrailingZeros64(special) / 8)
+ break
+ }
+ end += 8
+ }
+ if buf[end] != '"' {
+ return d.decodeKeyByScan(buf, cursor, disallowUnknownFields)
+ }
+ key := buf[start:end]
+ n := len(key)
+ keys := d.keys
+ // the words of the key, as keyWords makes them, read from the buffer
+ w0 := load64(buf, start)
+ var w1 uint64
+ if n < 8 {
+ w0 &= 1<<(uint(n)*8&63) - 1
+ } else {
+ w1 = load64(buf, end-8)
+ }
+ var field *structFieldSet
+ if keys.hasExactLength(n) {
+ // the first entry of the key is looked at here: most keys are found in it.
+ h0, h1 := hashWords(w0, w1, n)
+ e := &keys.exact[indexOf(h0, h1, keys.exactShift)]
+ if e.n == n && e.w0 == w0 && e.w1 == w1 && e.unique != nil && (n <= 16 || equalMiddleWords(key, e.folded)) {
+ return e.unique, end + 1, nil
+ }
+ if e.unique != nil {
+ field = keys.findExact(key, w0, w1)
+ }
+ }
+ if field == nil {
+ // Most keys which are not the key of a field are told so by their first rune which is not ASCII, which
+ // folds to no rune of a key ( see mayFold ); the others are looked at rune by rune.
+ if keys.leadMayFold(w0) && keys.firstRuneMayFold(key, w0) && keys.mayFold(key) {
+ field, key = keys.lookup(key, stringInfo{firstEscape: -1, nonASCII: true})
+ } else if disallowUnknownFields {
+ key = decodeLiteral(key, stringInfo{firstEscape: -1, nonASCII: true})
+ }
+ }
+ if field == nil && disallowUnknownFields {
+ return nil, 0, unknownFieldError(key)
+ }
+ return field, end + 1, nil
+}
+
+// decodeKeyByScan is decodeKey for any key, which it scans as a string.
+func (d *structDecoder) decodeKeyByScan(buf []byte, cursor int64, disallowUnknownFields bool) (*structFieldSet, int64, error) {
+ rawKey, next, info, err := d.stringDecoder.scanString(buf, cursor)
+ if next < 0 {
+ rawKey, next, info, err = d.stringDecoder.scanStringRest(buf, rawKey, -next-1, info)
+ }
+ if err != nil {
+ return nil, 0, err
+ }
+ field, key := d.keys.lookup(rawKey, info)
+ if field == nil && disallowUnknownFields {
+ return nil, 0, unknownFieldError(key)
+ }
+ return field, next, nil
+}
+
+// decodeOther skips the value at cursor, which is not an object: a value of another kind is a type error, and
+// anything else a syntax error. It is a function of its own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *structDecoder) decodeOther(ctx *RuntimeContext, cursor, depth int64) (int64, error) {
+ if c := ctx.Buf[cursor]; isOtherValue(c, objectValue) {
+ return ctx.skipTypeError(cursor, depth, d.typ)
+ }
+ return 0, errors.ErrInvalidBeginningOfValue(ctx.Buf[cursor], cursor)
+}
+
+func unknownFieldError(key []byte) error {
+ return fmt.Errorf("json: unknown field %q", key)
+}
+
+// specialKeyBytes returns the word which has the top bit of the first byte of w which ends a simple key, and
+// maybe the top bits of bytes after it: a quote, a backslash, a control character or a byte which is not ASCII.
+func specialKeyBytes(w uint64) uint64 {
+ // Only the first such byte is looked for, so the masks may be wrong in the bytes after it, which saves
+ // instructions: a subtraction borrows from the next byte only at a byte which is found.
+ // A byte of a quote or a backslash is 0 in q or s, whose subtraction sets its top bit; the one of a control
+ // character sets the top bit of the subtraction of 0x20, and the one of a byte which is not ASCII is set.
+ q := w ^ ('"' * lsb)
+ s := w ^ ('\\' * lsb)
+ return (((q - lsb) &^ q) | ((s - lsb) &^ s) | (w - 0x20*lsb) | w) & msb
+}
+
+// keyEndBytes is specialKeyBytes for a key which may have bytes which are not ASCII: it has the top bit of the
+// first byte of w which is a quote, a backslash or a control character, and maybe of bytes after it.
+func keyEndBytes(w uint64) uint64 {
+ // a byte of 0x80 or more is none of them: its top bit is cleared from the subtractions, which don't borrow
+ // from the next byte at such a byte.
+ q := w ^ ('"' * lsb)
+ s := w ^ ('\\' * lsb)
+ return (((q - lsb) &^ q) | ((s - lsb) &^ s) | ((w - 0x20*lsb) &^ w)) & msb
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/struct_keys.go b/vendor/github.com/goccy/go-json/internal/decoder/struct_keys.go
new file mode 100644
index 000000000..012dac861
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/struct_keys.go
@@ -0,0 +1,461 @@
+package decoder
+
+import (
+ "bytes"
+ "encoding/binary"
+ "math/bits"
+ "unicode"
+ "unicode/utf8"
+)
+
+// structKeys finds the field of a struct which an object key is decoded into, as encoding/json does:
+// the field whose key is the same, or else the first field whose key is the same by case folding.
+//
+// The fields are in a table keyed by their folded keys: the fields of a folded key are in one entry, so that
+// a key is looked up once, whether it matches a field exactly or by folding. A key is looked up by two words:
+// its first eight bytes, and its last eight bytes, which overlap the first ones for a key shorter than 16 bytes.
+// These are all the bytes of a key of up to 16 bytes, so such a key is compared by its length and the two words
+// only; a longer one is compared by the words between them as well. The words of a key of ASCII are folded in
+// place, eight bytes at a time, and only a key which is not ASCII is folded rune by rune.
+type structKeys struct {
+ entries []keyEntry
+ shift uint
+ // lengths has the bit of the length of every folded key ( 63 for the longer keys ):
+ // a key of another length matches no field, which is known without a lookup.
+ lengths uint64
+ // exact is a table of the keys which are not ASCII, by their bytes as they are ( see findExact ), and
+ // exactLengths has the bit of the length of every such key, as lengths does for the folded keys.
+ exact []keyEntry
+ exactShift uint
+ exactLengths uint64
+ // foldRunes has a bit for every rune which is not ASCII and which folds to a rune of a folded key, by the
+ // low byte of the rune ( see mayFold ).
+ foldRunes [4]uint64
+ // foldLeads has a bit for the first byte of the encoding of every rune of foldRunes ( see leadMayFold ).
+ foldLeads [4]uint64
+ // hasRuneError is set if a key has utf8.RuneError, which a byte of an object key which is not valid UTF-8
+ // is replaced by.
+ hasRuneError bool
+}
+
+type keyEntry struct {
+ // short is the word of the folded key if it is of less than 8 bytes, none of which is nul, and its field
+ // is the only one: a short key of ASCII whose folded word is the same is of that field, whatever its case.
+ // It is noShortKey for any other entry, which no such word is.
+ short uint64
+ // w0 and w1 are the words of the folded key, and n its length.
+ w0, w1 uint64
+ n int
+ folded []byte
+ // unique is the field of the folded key if it is the only one, which a key matches whichever its case.
+ unique *structFieldSet
+ // fields are the fields of the folded key in the order of the struct: the first one is the field of
+ // a key which matches none of them exactly.
+ fields []*structFieldSet
+}
+
+// hasLength reports whether a key of n bytes may match a field.
+func (k *structKeys) hasLength(n int) bool {
+ return k.lengths&(1<<(uint(min(n, 63))&63)) != 0
+}
+
+// newStructKeys makes the table of the fields, which are in the order of the struct.
+func newStructKeys(fields []*structFieldSet) *structKeys {
+ // the table is at most half full, so that a lookup ends after a few entries.
+ size := 8
+ for size < 2*len(fields) {
+ size *= 2
+ }
+ k := &structKeys{
+ entries: make([]keyEntry, size),
+ shift: uint(64 - bits.TrailingZeros(uint(size))),
+ }
+ for _, field := range fields {
+ folded := appendFoldedKey(nil, []byte(field.key))
+ if e := k.find(folded); e != nil {
+ e.fields = append(e.fields, field)
+ e.unique = nil
+ continue
+ }
+ k.insert(folded, field)
+ }
+ k.makeExact(fields)
+ k.makeFoldRunes(fields)
+ for i := range k.entries {
+ e := &k.entries[i]
+ e.short = noShortKey
+ if e.unique != nil && e.n < 8 && !bytes.Contains(e.folded, []byte{0}) {
+ e.short = e.w0
+ }
+ }
+ return k
+}
+
+// makeExact makes the table of the keys which are not ASCII, by their bytes as they are. A key which is not
+// valid UTF-8 is not in it: an object key which is not valid UTF-8 is decoded with its bytes replaced first.
+func (k *structKeys) makeExact(fields []*structFieldSet) {
+ var keys []*structFieldSet
+ for _, field := range fields {
+ if !isASCII(field.key) && utf8.ValidString(field.key) {
+ keys = append(keys, field)
+ }
+ }
+ if len(keys) == 0 {
+ return
+ }
+ size := 8
+ for size < 2*len(keys) {
+ size *= 2
+ }
+ k.exact = make([]keyEntry, size)
+ k.exactShift = uint(64 - bits.TrailingZeros(uint(size)))
+ for _, field := range keys {
+ key := []byte(field.key)
+ w0, w1 := keyWords(key)
+ h0, h1 := hashWords(w0, w1, len(key))
+ mask := len(k.exact) - 1
+ for i := indexOf(h0, h1, k.exactShift); ; i = (i + 1) & mask {
+ if k.exact[i].unique == nil {
+ k.exact[i] = keyEntry{w0: w0, w1: w1, n: len(key), folded: key, unique: field}
+ k.exactLengths |= 1 << (uint(min(len(key), 63)) & 63)
+ break
+ }
+ }
+ }
+}
+
+// findExact returns the field whose key is the same as the key, which is not ASCII and is in a buffer which
+// has room for a word after it, or nil. w0 and w1 are the words of the key as keyWords makes them.
+func (k *structKeys) findExact(key []byte, w0, w1 uint64) *structFieldSet {
+ n := len(key)
+ mask := len(k.exact) - 1
+ h0, h1 := hashWords(w0, w1, n)
+ for i := indexOf(h0, h1, k.exactShift); ; i = (i + 1) & mask {
+ e := &k.exact[i]
+ if e.unique == nil {
+ return nil
+ }
+ if e.n == n && e.w0 == w0 && e.w1 == w1 && (n <= 16 || equalMiddleWords(key, e.folded)) {
+ return e.unique
+ }
+ }
+}
+
+// hasExactLength reports whether a key of n bytes which is not ASCII may be the same as the key of a field.
+func (k *structKeys) hasExactLength(n int) bool {
+ return k.exactLengths&(1<<(uint(min(n, 63))&63)) != 0
+}
+
+// equalMiddleWords reports whether two keys of the same length of more than 16 bytes, whose first and last eight
+// bytes are known to be the same, have the same words between them.
+func equalMiddleWords(a, b []byte) bool {
+ n := len(a)
+ if n != len(b) {
+ return false
+ }
+ for i := 8; i < n-8; i += 8 {
+ if binary.LittleEndian.Uint64(a[i:]) != binary.LittleEndian.Uint64(b[i:]) {
+ return false
+ }
+ }
+ return true
+}
+
+// makeFoldRunes sets the bits of the runes which are not ASCII and fold to a rune of a key: the runes of the
+// fold orbits of the runes of the keys, which include the Kelvin sign for K and the long s for S.
+func (k *structKeys) makeFoldRunes(fields []*structFieldSet) {
+ for _, field := range fields {
+ for _, r := range field.key {
+ if r == utf8.RuneError {
+ k.hasRuneError = true
+ }
+ for f := r; ; {
+ if f >= utf8.RuneSelf {
+ k.foldRunes[f&0xff>>6] |= 1 << (uint(f) & 63)
+ lead := utf8.AppendRune(nil, f)[0]
+ k.foldLeads[lead>>6] |= 1 << (lead & 63)
+ }
+ if f = unicode.SimpleFold(f); f == r {
+ break
+ }
+ }
+ }
+ }
+}
+
+// mayFold reports whether a key which is not ASCII may be of a field by case folding: every rune of it which
+// is not ASCII folds to a rune of a key, which is told by the low byte of the rune. The low byte is taken from
+// the last two bytes of the encoding of the rune, which is not decoded. A key which is not valid UTF-8 has its
+// invalid bytes replaced by utf8.RuneError, so it may be of a field only if a key has utf8.RuneError: then
+// the runes are decoded.
+func (k *structKeys) mayFold(key []byte) bool {
+ if k.hasRuneError {
+ return k.mayFoldDecoded(key)
+ }
+ n := len(key)
+ for i := 0; i < n; {
+ c := key[i]
+ if c < utf8.RuneSelf {
+ i++
+ continue
+ }
+ size := 2
+ switch {
+ case c < 0xc0:
+ return false // a continuation byte without a first byte: not valid UTF-8
+ case c >= 0xf0:
+ size = 4
+ case c >= 0xe0:
+ size = 3
+ }
+ if i+size > n {
+ return false
+ }
+ low := key[i+size-2]&3<<6 | key[i+size-1]&0x3f
+ if k.foldRunes[low>>6]&(1<<(low&63)) == 0 {
+ return false
+ }
+ i += size
+ }
+ return true
+}
+
+// leadMayFold reports whether the first byte of the key which is not ASCII, if it is in the first word of the
+// key, w0, may be the first byte of a rune which folds to a rune of a key, and else true. It is the cheapest
+// check, which needs no load: most keys which are of no field are told so by it.
+func (k *structKeys) leadMayFold(w0 uint64) bool {
+ high := w0 & msb
+ if high == 0 || k.hasRuneError {
+ return true
+ }
+ lead := byte(w0 >> (uint(bits.TrailingZeros64(high)) - 7))
+ return k.foldLeads[lead>>6]&(1<<(lead&63)) != 0
+}
+
+// firstRuneMayFold reports whether the first rune of the key which is not ASCII may fold to a rune of a key, if
+// that rune begins in the first word of the key, w0, and else true: it tells mayFold for most keys, without a
+// call. The low byte of the rune is taken from its bytes as mayFold does, and a key which may not be valid
+// UTF-8 is left to mayFold.
+func (k *structKeys) firstRuneMayFold(key []byte, w0 uint64) bool {
+ high := w0 & msb
+ if high == 0 || k.hasRuneError {
+ return true
+ }
+ i := bits.TrailingZeros64(high) / 8
+ c := key[i]
+ size := 2
+ switch {
+ case c < 0xc0:
+ return true
+ case c >= 0xf0:
+ size = 4
+ case c >= 0xe0:
+ size = 3
+ }
+ if i+size > len(key) {
+ return true
+ }
+ low := key[i+size-2]&3<<6 | key[i+size-1]&0x3f
+ return k.foldRunes[low>>6]&(1<<(low&63)) != 0
+}
+
+// mayFoldDecoded is mayFold by the decoded runes.
+func (k *structKeys) mayFoldDecoded(key []byte) bool {
+ for i := 0; i < len(key); {
+ if key[i] < utf8.RuneSelf {
+ i++
+ continue
+ }
+ r, size := utf8.DecodeRune(key[i:])
+ if k.foldRunes[r&0xff>>6]&(1<<(uint(r)&63)) == 0 {
+ return false
+ }
+ i += size
+ }
+ return true
+}
+
+func isASCII(s string) bool {
+ for i := 0; i < len(s); i++ {
+ if s[i] >= utf8.RuneSelf {
+ return false
+ }
+ }
+ return true
+}
+
+// noShortKey is the short word of an entry which a short key is not found by: a word of ASCII has no byte of
+// 0x80 or more.
+const noShortKey = ^uint64(0)
+
+// keyWords returns the words of a key: its first eight bytes and its last eight bytes, as little-endian
+// numbers, which are zero where the key is shorter. The capacity of the key is read past its length when it
+// has room, which is the rest of the buffer of the input.
+func keyWords(key []byte) (uint64, uint64) {
+ n := len(key)
+ switch {
+ case n >= 8:
+ return binary.LittleEndian.Uint64(key), binary.LittleEndian.Uint64(key[n-8:])
+ case cap(key) >= 8:
+ return binary.LittleEndian.Uint64(key[:8]) & (1<<(8*uint(n)) - 1), 0
+ }
+ var w uint64
+ for i := n - 1; i >= 0; i-- {
+ w = w<<8 | uint64(key[i])
+ }
+ return w, 0
+}
+
+// index returns the first entry to look at for a key whose words are w0 and w1, with the bit 5 of their bytes
+// set by hashWords: a letter of either case has the same index, so the index of a key is made from its bytes
+// before they are folded. The product spreads the keys, which differ in a few bits.
+func (k *structKeys) index(w0, w1 uint64) int {
+ return indexOf(w0, w1, k.shift)
+}
+
+func indexOf(w0, w1 uint64, shift uint) int {
+ h := (w0 ^ bits.RotateLeft64(w1, 29)) * 0x9E3779B97F4A7C15
+ return int(h >> shift)
+}
+
+// hashWords returns the words of a key of n bytes, or of its folded key, which index takes: the bit 5 of their
+// bytes set, which folding a letter doesn't change, and the bytes after the key zero.
+func hashWords(w0, w1 uint64, n int) (uint64, uint64) {
+ if n < 8 {
+ return (w0 | bit5) & (1<<(uint(n)*8&63) - 1), 0
+ }
+ return w0 | bit5, w1 | bit5
+}
+
+func (k *structKeys) insert(folded []byte, field *structFieldSet) {
+ w0, w1 := keyWords(folded)
+ mask := len(k.entries) - 1
+ for i := k.index(hashWords(w0, w1, len(folded))); ; i = (i + 1) & mask {
+ if k.entries[i].fields == nil {
+ k.entries[i] = keyEntry{w0: w0, w1: w1, n: len(folded), folded: folded, unique: field, fields: []*structFieldSet{field}}
+ k.lengths |= 1 << uint(min(len(folded), 63))
+ return
+ }
+ }
+}
+
+// find returns the entry of the folded key, or nil.
+func (k *structKeys) find(folded []byte) *keyEntry {
+ w0, w1 := keyWords(folded)
+ n := len(folded)
+ mask := len(k.entries) - 1
+ for i := k.index(hashWords(w0, w1, n)); ; i = (i + 1) & mask {
+ e := &k.entries[i]
+ if e.fields == nil {
+ return nil
+ }
+ if e.n == n && e.w0 == w0 && e.w1 == w1 && (n <= 16 || string(e.folded) == string(folded)) {
+ return e
+ }
+ }
+}
+
+// field returns the field of the key among the fields of its folded key: the one whose key is the same,
+// or the first one.
+func (e *keyEntry) field(key []byte) *structFieldSet {
+ if len(e.fields) == 1 {
+ return e.fields[0]
+ }
+ for _, field := range e.fields {
+ if field.key == string(key) {
+ return field
+ }
+ }
+ return e.fields[0]
+}
+
+// findASCII returns the field of a key of ASCII without an escape, whose words are w0 and w1, or nil.
+func (k *structKeys) findASCII(key []byte, w0, w1 uint64) *structFieldSet {
+ n := len(key)
+ start := k.index(hashWords(w0, w1, n))
+ w0, w1 = foldASCIIWord(w0), foldASCIIWord(w1)
+ mask := len(k.entries) - 1
+ for i := start; ; i = (i + 1) & mask {
+ e := &k.entries[i]
+ if e.fields == nil {
+ return nil
+ }
+ if e.n == n && e.w0 == w0 && e.w1 == w1 && (n <= 16 || equalFoldedASCII(key, e.folded)) {
+ if len(e.fields) == 1 {
+ return e.fields[0]
+ }
+ return e.field(key)
+ }
+ }
+}
+
+// foldASCIIWord folds the bytes of a word of ASCII as encoding/json does: a lower case letter to upper case.
+func foldASCIIWord(w uint64) uint64 {
+ // the bytes are less than 0x80: adding to one never carries to the next.
+ ge := w + (0x80-'a')*lsb // 0x80 in the bytes from 'a'
+ gt := w + (0x80-'z'-1)*lsb // 0x80 in the bytes after 'z'
+ lower := (ge &^ gt) & msb // 0x80 in the lower case letters
+ return w &^ (lower >> 2) // clear 0x20 of them
+}
+
+// equalFoldedASCII reports whether the key of ASCII, of more than 16 bytes, folds to folded, whose first and
+// last eight bytes are known to be the ones of the key folded: the words between them are compared.
+func equalFoldedASCII(key, folded []byte) bool {
+ n := len(key)
+ if n != len(folded) {
+ return false
+ }
+ for i := 8; i < n-8; i += 8 {
+ if foldASCIIWord(binary.LittleEndian.Uint64(key[i:])) != binary.LittleEndian.Uint64(folded[i:]) {
+ return false
+ }
+ }
+ return true
+}
+
+// lookup returns the field of the key, or nil, and the key, which is decoded in place if it is escaped.
+func (k *structKeys) lookup(key []byte, info stringInfo) (*structFieldSet, []byte) {
+ if info.firstEscape < 0 && !info.nonASCII {
+ if !k.hasLength(len(key)) {
+ return nil, key
+ }
+ w0, w1 := keyWords(key)
+ return k.findASCII(key, w0, w1), key
+ }
+ key = decodeLiteral(key, info)
+ var arr [64]byte
+ if e := k.find(appendFoldedKey(arr[:0], key)); e != nil {
+ return e.field(key), key
+ }
+ return nil, key
+}
+
+// appendFoldedKey appends the key folded as encoding/json folds a key to compare it case insensitively:
+// a lower case ASCII letter to upper case, and any other rune to the smallest rune which folds to it.
+func appendFoldedKey(out, key []byte) []byte {
+ for i := 0; i < len(key); {
+ if c := key[i]; c < utf8.RuneSelf {
+ if 'a' <= c && c <= 'z' {
+ c -= 'a' - 'A'
+ }
+ out = append(out, c)
+ i++
+ continue
+ }
+ r, n := utf8.DecodeRune(key[i:])
+ out = utf8.AppendRune(out, foldRune(r))
+ i += n
+ }
+ return out
+}
+
+// foldRune returns the smallest rune of the fold set of r.
+func foldRune(r rune) rune {
+ for {
+ r2 := unicode.SimpleFold(r)
+ if r2 <= r {
+ return r2
+ }
+ r = r2
+ }
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/syntax_error.go b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error.go
new file mode 100644
index 000000000..40cd048ec
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error.go
@@ -0,0 +1,108 @@
+package decoder
+
+import (
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// The syntax errors are the ones of encoding/json of the Go version, whose messages and offsets differ between Go
+// 1.27, which is made of encoding/json/v2, and the earlier versions ( see syntax_error_legacy.go and
+// syntax_error_v2.go ).
+
+// syntaxWhere is where in the grammar a byte is which the grammar doesn't have there.
+type syntaxWhere uint8
+
+const (
+ whereValue syntaxWhere = iota
+ whereKey
+ whereAfterKey
+ whereAfterPair
+ whereAfterElement
+ whereAfterTop
+ whereString
+ whereNumber
+ whereFraction
+ whereExponent
+)
+
+// isEnd reports whether cursor is the nul byte which ends buf, the input followed by it.
+func isEnd(buf []byte, cursor int64) bool {
+ return cursor == int64(len(buf))-1 && buf[cursor] == nul
+}
+
+// endError returns the error of the end of the input at the total offset at.
+func endError(at int64) error {
+ return errors.ErrSyntaxAtEnd("unexpected end of JSON input", at)
+}
+
+// syntaxErrorAt returns the syntax error of the byte at cursor, which the grammar doesn't have where it is: the end
+// of the input if it is the nul byte which ends the buffer. It is not inlined, so that its callers keep their size.
+//
+//go:noinline
+func syntaxErrorAt(buf []byte, cursor int64, where syntaxWhere) error {
+ if isEnd(buf, cursor) {
+ return endError(cursor)
+ }
+ err := invalidCharacterError(buf, cursor, where.text())
+ if where == whereValue {
+ // a stream of Go 1.27 tells a bracket there by the object or the array which Token opened
+ err = errors.WithValueStartAt(err, cursor)
+ }
+ return err
+}
+
+// numberSyntaxError returns the syntax error of the byte at cursor in the number which starts at start.
+//
+//go:noinline
+func numberSyntaxError(buf []byte, cursor, start int64, where syntaxWhere) error {
+ if isEnd(buf, cursor) {
+ return scalarEndError(buf, cursor, start, where.text())
+ }
+ return invalidCharacterError(buf, cursor, where.text())
+}
+
+// literalSyntaxError returns the syntax error of the literal at cursor, which is not lit: the first byte which
+// differs from lit.
+func literalSyntaxError(buf []byte, cursor int64, lit string) error {
+ for i := 1; i < len(lit); i++ {
+ at := cursor + int64(i)
+ if c := buf[at]; c != lit[i] {
+ what := "in literal " + lit + " (expecting " + quoteChar(lit[i]) + ")"
+ if isEnd(buf, at) {
+ return scalarEndError(buf, at, int64(len(buf))-1, what)
+ }
+ return invalidCharacterError(buf, at, what)
+ }
+ }
+ return nil
+}
+
+// stringSyntaxError returns the syntax error of the string at cursor: a control character, an escape which is not
+// one, or the end of the input.
+func stringSyntaxError(buf []byte, cursor int64) error {
+ for c := cursor + 1; ; c++ {
+ switch b := buf[c]; {
+ case b == '"':
+ return nil
+ case b < ' ':
+ return syntaxErrorAt(buf, c, whereString)
+ case b == '\\':
+ switch buf[c+1] {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ c++
+ case 'u':
+ for i := int64(2); i <= 5; i++ {
+ if !isHexDigit(buf[c+i]) {
+ return escapeSyntaxError(buf, c, c+i)
+ }
+ }
+ c += 5
+ default:
+ return escapeSyntaxError(buf, c, c+1)
+ }
+ }
+ }
+}
+
+func isHexDigit(c byte) bool {
+ return c-'0' <= 9 || (c|0x20)-'a' <= 5
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_legacy.go b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_legacy.go
new file mode 100644
index 000000000..042b5abce
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_legacy.go
@@ -0,0 +1,64 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package decoder
+
+import (
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// text returns the words of the message of a syntax error which tell where the byte is, as encoding/json before
+// Go 1.27 has them.
+func (w syntaxWhere) text() string {
+ switch w {
+ case whereKey:
+ return "looking for beginning of object key string"
+ case whereAfterKey:
+ return "after object key"
+ case whereAfterPair:
+ return "after object key:value pair"
+ case whereAfterElement:
+ return "after array element"
+ case whereAfterTop:
+ return "after top-level value"
+ case whereString:
+ return "in string literal"
+ case whereNumber:
+ return "in numeric literal"
+ case whereFraction:
+ return "after decimal point in numeric literal"
+ case whereExponent:
+ return "in exponent of numeric literal"
+ }
+ return "looking for beginning of value"
+}
+
+// invalidCharacterError returns the syntax error of the byte at cursor, which the offset is after.
+func invalidCharacterError(buf []byte, cursor int64, what string) *errors.SyntaxError {
+ return errors.ErrSyntax("invalid character "+quoteChar(buf[cursor])+" "+what, cursor+1)
+}
+
+// scalarEndError returns the syntax error of the end of the input at cursor in a number, a literal or an escape,
+// which starts at start: encoding/json before Go 1.27 reads a white space at the end of the input, which is the
+// byte of the error.
+func scalarEndError(_ []byte, cursor, _ int64, what string) error {
+ return errors.ErrSyntaxAtEnd("invalid character ' ' "+what, cursor)
+}
+
+// escapeSyntaxError returns the syntax error of the byte at cursor, in the escape which the backslash at backslash
+// starts.
+func escapeSyntaxError(buf []byte, backslash, cursor int64) error {
+ what := "in string escape code"
+ if cursor > backslash+1 {
+ what = `in \u hexadecimal character escape`
+ }
+ if isEnd(buf, cursor) {
+ return scalarEndError(buf, cursor, backslash, what)
+ }
+ return invalidCharacterError(buf, cursor, what)
+}
+
+// depthSyntaxError returns the syntax error of the object or the array at cursor, which is nested deeper than the
+// limit.
+func depthSyntaxError(buf []byte, cursor int64) error {
+ return invalidCharacterError(buf, cursor, "exceeded max depth")
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_v2.go b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_v2.go
new file mode 100644
index 000000000..4f65a1658
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/syntax_error_v2.go
@@ -0,0 +1,91 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package decoder
+
+import (
+ "strconv"
+ "strings"
+ "unicode"
+ "unicode/utf8"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// text returns the words of the message of a syntax error which tell where the byte is, as encoding/json of Go 1.27
+// has them: the ones of encoding/json/jsontext, which are made the ones of encoding/json.
+func (w syntaxWhere) text() string {
+ switch w {
+ case whereKey:
+ return "looking for beginning of object key string"
+ case whereAfterKey:
+ return "after object key"
+ case whereAfterPair:
+ return "after object key:value pair"
+ case whereAfterElement:
+ return "after array element"
+ case whereAfterTop:
+ return "after top-level value"
+ case whereString:
+ return "in string"
+ case whereNumber, whereFraction, whereExponent:
+ return "in numeric literal"
+ }
+ return "looking for beginning of value"
+}
+
+// invalidCharacterError returns the syntax error of the character at cursor, which the offset is after: the
+// character of the UTF-8 sequence at cursor, or its byte if it is not one.
+func invalidCharacterError(buf []byte, cursor int64, what string) *errors.SyntaxError {
+ r, n := utf8.DecodeRune(buf[cursor : len(buf)-1])
+ quoted := strconv.QuoteRune(r)
+ if r == utf8.RuneError && n == 1 {
+ quoted = `'\x` + strconv.FormatUint(uint64(buf[cursor]), 16) + `'`
+ }
+ return errors.ErrSyntax("invalid character "+quoted+" "+what, cursor+int64(n))
+}
+
+// scalarEndError returns the syntax error of the end of the input at cursor in a number, a literal or an escape,
+// which starts at start: encoding/json of Go 1.27 reports it at the start of the number or of the escape, and at
+// the end of the input for a literal.
+func scalarEndError(_ []byte, _, start int64, _ string) error {
+ return endError(start)
+}
+
+// escapeSyntaxError returns the syntax error of the byte at cursor, in the escape which the backslash at backslash
+// starts: encoding/json of Go 1.27 reports the escape, which is 6 bytes for \u.
+func escapeSyntaxError(buf []byte, backslash, cursor int64) error {
+ end := backslash + 2
+ if cursor > backslash+1 {
+ end = backslash + 6
+ }
+ input := buf[:len(buf)-1]
+ if end > int64(len(input)) {
+ // the escape is cut by the end of the input: the end of the input if what it has may start an escape,
+ // and else what it has
+ rest := input[backslash:]
+ prefix := len(rest) < 2 || rest[1] == 'u'
+ for i := 2; prefix && i < len(rest); i++ {
+ prefix = isHexDigit(rest[i])
+ }
+ if prefix {
+ return endError(backslash)
+ }
+ end = int64(len(input))
+ }
+ seq := string(input[backslash:end])
+ var quoted string
+ if strings.ContainsFunc(seq, func(r rune) bool {
+ return r == '`' || r == utf8.RuneError || unicode.IsSpace(r) || !unicode.IsPrint(r)
+ }) {
+ quoted = strconv.Quote(seq)
+ } else {
+ quoted = "`" + seq + "`"
+ }
+ return errors.ErrSyntax("invalid escape sequence "+quoted+" in string", end)
+}
+
+// depthSyntaxError returns the syntax error of the object or the array at cursor, which is nested deeper than the
+// limit.
+func depthSyntaxError(_ []byte, cursor int64) error {
+ return errors.ErrSyntax("exceeded max depth", cursor+1)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type.go b/vendor/github.com/goccy/go-json/internal/decoder/type.go
index beaf3ab86..adb51c0b6 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/type.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type.go
@@ -11,7 +11,6 @@ import (
type Decoder interface {
Decode(*RuntimeContext, int64, int64, unsafe.Pointer) (int64, error)
DecodePath(*RuntimeContext, int64, int64) ([][]byte, int64, error)
- DecodeStream(*Stream, int64, unsafe.Pointer) error
}
const (
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type_error.go b/vendor/github.com/goccy/go-json/internal/decoder/type_error.go
new file mode 100644
index 000000000..ed8dd8f8e
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type_error.go
@@ -0,0 +1,399 @@
+package decoder
+
+import (
+ "reflect"
+ "strconv"
+)
+
+// The type errors are the ones of encoding/json: a value which is not of the type of its destination is skipped,
+// the decoding goes on, and the first such error is returned at the end, unless the input has a syntax error,
+// which is returned instead. The error is recorded where it happens by its position only; the path to its value,
+// which encoding/json reports as the Struct and the Field of the error, is computed at the end by a walk of the
+// input from the root ( see typeErrorPath ), so that the decoding of a value which has no error keeps no path.
+
+// float64Type is the type which the type error of a number out of the range of a float64 decoded into an
+// interface{} reports.
+var float64Type = reflect.TypeOf(float64(0))
+
+// pendingTypeError is the first type error of a decoding, as it is recorded.
+type pendingTypeError struct {
+ typ reflect.Type
+ // start and end are the positions of the value in the buffer.
+ start, end int64
+ // value is the description of the value which the error reports, as "string" or "number 1.5".
+ value string
+ // kind is the kind of the value.
+ kind jsonKind
+ // atKey is set for the error of the key of a map entry, whose value starts at start too.
+ atKey bool
+ // literal is set for an error which reports the literal of the value in its value, as "number 1.5".
+ literal bool
+ // plain is an error which is not a type error, which encoding/json returns as it is: an invalid use of the string
+ // option before Go 1.27, or the error of an unmarshal method by Go 1.27.
+ plain error
+ // err is the cause of the error, which encoding/json of Go 1.27 reports.
+ err error
+ // noContext is set for an error which is reported with no path and no offset, as encoding/json of Go 1.27
+ // reports the ones of a json.Number.
+ noContext bool
+ // atStart is set for an error whose offset is the start of the value, as encoding/json of Go 1.27 reports the
+ // ones of an interface value which is kept.
+ atStart bool
+}
+
+// jsonKind is the kind of a JSON value, which a decoder decodes and a type error reports.
+type jsonKind uint8
+
+const (
+ noValue jsonKind = iota
+ stringValue
+ numberValue
+ boolValue
+ nullValue
+ arrayValue
+ objectValue
+)
+
+// kindOf returns the kind of the value which starts with c, or noValue if c starts no value.
+func kindOf(c byte) jsonKind {
+ switch c {
+ case '"':
+ return stringValue
+ case 't', 'f':
+ return boolValue
+ case 'n':
+ return nullValue
+ case '[':
+ return arrayValue
+ case '{':
+ return objectValue
+ case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
+ return numberValue
+ }
+ return noValue
+}
+
+// String returns the description of the kind which the type errors report.
+func (k jsonKind) String() string {
+ switch k {
+ case stringValue:
+ return "string"
+ case boolValue:
+ return "bool"
+ case nullValue:
+ return "null"
+ case arrayValue:
+ return "array"
+ case objectValue:
+ return "object"
+ case numberValue:
+ return "number"
+ }
+ return ""
+}
+
+// isOtherValue reports whether c starts a JSON value of another kind than kind, which is the kind of the values
+// of a decoder: such a value is of another type, and is a type error, as a byte which starts no value is a
+// syntax error.
+func isOtherValue(c byte, kind jsonKind) bool {
+ k := kindOf(c)
+ return k != noValue && k != kind
+}
+
+// skipTypeError records the type error of the value at cursor, which is not of typ, if it is the first one, and
+// returns the position after the value, which is skipped. A syntax error of the value is returned instead.
+func (ctx *RuntimeContext) skipTypeError(cursor, depth int64, typ reflect.Type) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ end, err := skipValue(buf, cursor, depth)
+ if err != nil {
+ return 0, err
+ }
+ if ctx.typeError == nil {
+ kind := kindOf(buf[cursor])
+ ctx.typeError = &pendingTypeError{typ: typ, start: cursor, end: end, value: kind.String(), kind: kind}
+ }
+ return end, nil
+}
+
+// setEmbedded sets the names of the embedded fields which the field is promoted through.
+func (d *structDecoder) setEmbedded(field *structFieldSet, names []string) {
+ if d.embedded == nil {
+ d.embedded = map[*structFieldSet][]string{}
+ }
+ d.embedded[field] = names
+}
+
+// numberTypeError records the type error of the number between start and end, which is not of typ because it
+// is out of its range or not an integer: the error reports the literal of the number. It is not inlined, so that
+// the decoders of the numbers keep the size they had.
+//
+//go:noinline
+func (ctx *RuntimeContext) numberTypeError(start, end int64, typ reflect.Type) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: typ, start: start, end: end, value: "number " + string(ctx.Buf[start:end]), kind: numberValue,
+ literal: true,
+ }
+ }
+}
+
+// keyTypeError records the type error of the key of a map entry between start and end, the quotes of which are
+// included, which is not a number of typ: the error reports the key.
+func (ctx *RuntimeContext) keyTypeError(start, end int64, key []byte, typ reflect.Type) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: typ, start: start, end: end, value: "number " + string(key), kind: stringValue, atKey: true,
+ literal: true,
+ }
+ }
+}
+
+// HasTypeError reports whether the decoding has a type error, which TypeError returns: the type of the value
+// is made for it only.
+func (ctx *RuntimeContext) HasTypeError() bool {
+ return ctx.typeError != nil
+}
+
+// DiscardTypeError drops the type error of a decoding which failed with another error.
+func (ctx *RuntimeContext) DiscardTypeError() {
+ ctx.typeError = nil
+}
+
+// TypeError returns the first type error of the decoding of the value which dec decoded from base into a value
+// of typ, as encoding/json of the Go version reports it, or nil if the decoding had none. Its offset is relative
+// to offsetBase.
+func (ctx *RuntimeContext) TypeError(dec Decoder, typ reflect.Type, base, offsetBase int64) error {
+ p := ctx.typeError
+ if p == nil {
+ return nil
+ }
+ ctx.typeError = nil
+ if p.plain != nil {
+ return p.plain
+ }
+ e := newTypeError(p, typeErrorPath(dec, ctx.Buf, base, p), typ)
+ if p.atStart {
+ e.Offset = p.start
+ }
+ if e.Offset != 0 {
+ e.Offset -= offsetBase
+ }
+ return e
+}
+
+// typeErrorStep is a step of the path from the root to the value of a type error: a field of a struct, an
+// element of an array or a slice, or an entry of a map.
+type typeErrorStep struct {
+ // structName is the name of the struct type of a field.
+ structName string
+ // embedded are the names of the embedded fields which a field is promoted through.
+ embedded []string
+ // name is the name of a field, which is its key, the key of a map entry as it is decoded, or the index of an
+ // element.
+ name string
+ // inputName is the key of a field as the input has it, decoded, which encoding/json of Go 1.27 reports.
+ inputName string
+ // isField is set for a field of a struct.
+ isField bool
+}
+
+// typeErrorPath returns the path from the value which dec decodes at cursor to the value of the error, by the
+// decoders of the values it goes through.
+func typeErrorPath(dec Decoder, buf []byte, cursor int64, p *pendingTypeError) []typeErrorStep {
+ var path []typeErrorStep
+ for {
+ cursor = skipWhiteSpace(buf, cursor)
+ if cursor >= p.start {
+ return path
+ }
+ switch d := dec.(type) {
+ case *ptrDecoder:
+ dec = d.dec
+ continue
+ case *basicPtrDecoder:
+ dec = d.dec
+ continue
+ case *anonymousFieldDecoder:
+ dec = d.dec
+ continue
+ case *structDecoder:
+ step, child, next, ok := d.typeErrorChild(buf, cursor, p)
+ if !ok {
+ return path
+ }
+ path = append(path, step)
+ if next < 0 {
+ return path
+ }
+ dec, cursor = child, next
+ case *sliceDecoder:
+ i, next, ok := typeErrorElement(buf, cursor, p)
+ if !ok {
+ return path
+ }
+ path = append(path, typeErrorStep{name: strconv.Itoa(i)})
+ dec, cursor = d.valueDecoder, next
+ case *arrayDecoder:
+ i, next, ok := typeErrorElement(buf, cursor, p)
+ if !ok {
+ return path
+ }
+ path = append(path, typeErrorStep{name: strconv.Itoa(i)})
+ dec, cursor = d.valueDecoder, next
+ case *interfaceDecoder:
+ // the objects and the arrays of an interface{}, whose values are decoded by the same decoder
+ var next int64
+ var ok bool
+ switch buf[cursor] {
+ case '{':
+ var key string
+ if key, next, ok = typeErrorEntry(buf, cursor, p); ok {
+ path = append(path, typeErrorStep{name: key})
+ }
+ case '[':
+ var i int
+ if i, next, ok = typeErrorElement(buf, cursor, p); ok {
+ path = append(path, typeErrorStep{name: strconv.Itoa(i)})
+ }
+ }
+ if !ok || next < 0 || d.hasMethods {
+ return path
+ }
+ cursor = next
+ case *mapDecoder:
+ key, next, ok := typeErrorEntry(buf, cursor, p)
+ if !ok {
+ return path
+ }
+ path = append(path, typeErrorStep{name: key})
+ if next < 0 {
+ return path
+ }
+ dec, cursor = d.valueDecoder, next
+ default:
+ return path
+ }
+ }
+}
+
+// typeErrorChild returns the step to the field of the object at cursor whose value has the error, the decoder of
+// the field and the position of its value, which is -1 if the error is of the key. ok is false if the error is in
+// no field of the object.
+func (d *structDecoder) typeErrorChild(buf []byte, cursor int64, p *pendingTypeError) (typeErrorStep, Decoder, int64, bool) {
+ if buf[cursor] != '{' {
+ return typeErrorStep{}, nil, 0, false
+ }
+ cursor++
+ for {
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] != '"' {
+ return typeErrorStep{}, nil, 0, false
+ }
+ key, info, next, ok := typeErrorKey(buf, cursor)
+ if !ok {
+ return typeErrorStep{}, nil, 0, false
+ }
+ field, _ := d.keys.lookup(key, info)
+ cursor = skipWhiteSpace(buf, next)
+ if buf[cursor] != ':' {
+ return typeErrorStep{}, nil, 0, false
+ }
+ cursor = skipWhiteSpace(buf, cursor+1)
+ end, err := skipValue(buf, cursor, 0)
+ if err != nil {
+ return typeErrorStep{}, nil, 0, false
+ }
+ if p.start >= cursor && p.start < end {
+ if field == nil {
+ return typeErrorStep{}, nil, 0, false
+ }
+ step := typeErrorStep{
+ structName: d.typeName, name: field.key, inputName: string(decodeLiteral(key, info)), isField: true,
+ }
+ if embeddedFieldNames {
+ step.embedded = d.embedded[field]
+ }
+ return step, field.dec, cursor, true
+ }
+ cursor = skipWhiteSpace(buf, end)
+ if buf[cursor] != ',' {
+ return typeErrorStep{}, nil, 0, false
+ }
+ cursor++
+ }
+}
+
+// typeErrorElement returns the index of the element of the array at cursor which has the error, and its position.
+func typeErrorElement(buf []byte, cursor int64, p *pendingTypeError) (int, int64, bool) {
+ if buf[cursor] != '[' {
+ return 0, 0, false
+ }
+ cursor++
+ for i := 0; ; i++ {
+ cursor = skipWhiteSpace(buf, cursor)
+ end, err := skipValue(buf, cursor, 0)
+ if err != nil {
+ return 0, 0, false
+ }
+ if p.start >= cursor && p.start < end {
+ return i, cursor, true
+ }
+ cursor = skipWhiteSpace(buf, end)
+ if buf[cursor] != ',' {
+ return 0, 0, false
+ }
+ cursor++
+ }
+}
+
+// typeErrorEntry returns the key of the entry of the object at cursor which has the error, and the position of
+// its value, which is -1 if the error is of the key.
+func typeErrorEntry(buf []byte, cursor int64, p *pendingTypeError) (string, int64, bool) {
+ if buf[cursor] != '{' {
+ return "", 0, false
+ }
+ cursor++
+ for {
+ cursor = skipWhiteSpace(buf, cursor)
+ keyStart := cursor
+ key, info, next, ok := typeErrorKey(buf, cursor)
+ if !ok {
+ return "", 0, false
+ }
+ key = decodeLiteral(key, info)
+ if p.atKey && keyStart == p.start {
+ return string(key), -1, true
+ }
+ cursor = skipWhiteSpace(buf, next)
+ if buf[cursor] != ':' {
+ return "", 0, false
+ }
+ cursor = skipWhiteSpace(buf, cursor+1)
+ end, err := skipValue(buf, cursor, 0)
+ if err != nil {
+ return "", 0, false
+ }
+ if p.start >= cursor && p.start < end {
+ return string(key), cursor, true
+ }
+ cursor = skipWhiteSpace(buf, end)
+ if buf[cursor] != ',' {
+ return "", 0, false
+ }
+ cursor++
+ }
+}
+
+// typeErrorKey returns a copy of the bytes of the key at cursor as they are in buf, what they have, and the position
+// after the key: the buffer is not written, as the decoding of a key does to its escapes.
+func typeErrorKey(buf []byte, cursor int64) ([]byte, stringInfo, int64, bool) {
+ raw, next, info, err := skipStringDecoder.scanString(buf, cursor)
+ if next < 0 {
+ raw, next, info, err = skipStringDecoder.scanStringRest(buf, raw, -next-1, info)
+ }
+ if err != nil || raw == nil {
+ return nil, stringInfo{}, 0, false
+ }
+ return append([]byte(nil), raw...), info, next, true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded.go b/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded.go
new file mode 100644
index 000000000..771a84d99
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded.go
@@ -0,0 +1,7 @@
+//go:build go1.24
+
+package decoder
+
+// embeddedFieldNames is whether the path of a type error has the names of the embedded fields which a field
+// is promoted through, which encoding/json of Go 1.24 to 1.26 reports ( see typeErrorPath ).
+const embeddedFieldNames = true
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded_legacy.go b/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded_legacy.go
new file mode 100644
index 000000000..0e5a7492e
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type_error_embedded_legacy.go
@@ -0,0 +1,7 @@
+//go:build !go1.24
+
+package decoder
+
+// embeddedFieldNames is whether the path of a type error has the names of the embedded fields which a field
+// is promoted through: encoding/json before Go 1.24 reports the name of the field only ( see typeErrorPath ).
+const embeddedFieldNames = false
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type_error_legacy.go b/vendor/github.com/goccy/go-json/internal/decoder/type_error_legacy.go
new file mode 100644
index 000000000..a026365b3
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type_error_legacy.go
@@ -0,0 +1,280 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package decoder
+
+import (
+ "encoding/json"
+ "fmt"
+ "reflect"
+ "strings"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// newTypeError returns the type error as encoding/json before Go 1.27, and with GOEXPERIMENT=nojsonv2, reports
+// it. Offset is after a literal and after the bracket of an array or an object, and at the first byte of a key.
+// Struct is the struct type of the last field of the path, and Field the names of its fields, through their
+// embedded fields since Go 1.24 ( see embeddedFieldNames ); the elements and the entries of the path have no name. An error in no field has neither.
+func newTypeError(p *pendingTypeError, path []typeErrorStep, _ reflect.Type) *errors.UnmarshalTypeError {
+ e := &errors.UnmarshalTypeError{Value: p.value, Type: p.typ, Offset: p.end, Err: p.err}
+ if p.noContext {
+ return e
+ }
+ switch {
+ case p.atKey:
+ e.Offset = p.start + 1
+ case !p.literal && (p.kind == arrayValue || p.kind == objectValue):
+ e.Offset = p.start + 1
+ }
+ var names []string
+ for _, step := range path {
+ if !step.isField {
+ continue
+ }
+ e.Struct = step.structName
+ names = append(append(names, step.embedded...), step.name)
+ }
+ e.Field = strings.Join(names, ".")
+ return e
+}
+
+// base64Error records the error of the decoding of the string between start and end into typ, which is not
+// base64: encoding/json before Go 1.27 returns the error of the decoding as it is.
+func (ctx *RuntimeContext) base64Error(_, _ int64, _ reflect.Type, err error) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{plain: err}
+ }
+}
+
+// numberKindError records the type error of the value at cursor, of another kind than a number or a string,
+// which is decoded into a json.Number, and skips it.
+func (ctx *RuntimeContext) numberKindError(cursor, depth int64, typ reflect.Type) (int64, error) {
+ return ctx.skipTypeError(cursor, depth, typ)
+}
+
+// numberStringError returns the error of the string between start and end, which is not a number, decoded into
+// a json.Number: encoding/json before Go 1.27 stops the decoding with it.
+func (ctx *RuntimeContext) numberStringError(start, end int64, _ reflect.Type) (int64, error) {
+ return 0, fmt.Errorf("json: invalid number literal, trying to unmarshal %q into Number", ctx.Buf[start:end])
+}
+
+// stringOptionUnquoted records the error of the value at cursor of a field of the string option, which is not in
+// a string, and skips it: encoding/json before Go 1.27 reports it as an invalid use of the option.
+func (ctx *RuntimeContext) stringOptionUnquoted(cursor, depth int64, typ reflect.Type) (int64, error) {
+ end, err := skipValue(ctx.Buf, skipWhiteSpace(ctx.Buf, cursor), depth)
+ if err != nil {
+ return 0, err
+ }
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ plain: fmt.Errorf("json: invalid use of ,string struct tag, trying to unmarshal unquoted value into %v", typ),
+ }
+ }
+ return end, nil
+}
+
+// stringOptionError records or returns the error of the string between start and end of a field of the string
+// option, whose bytes are not a value of typ, as encoding/json before Go 1.27 tells it from the first byte of the
+// value and the kind of typ: a number out of the range of typ is a type error, a value which starts as no value
+// of its kind stops the decoding, and any other one is an invalid use of the option.
+func (ctx *RuntimeContext) stringOptionError(start, end int64, value []byte, typ reflect.Type) (int64, error) {
+ invalidUse := func() error {
+ return fmt.Errorf("json: invalid use of ,string struct tag, trying to unmarshal %q into %v", value, typ)
+ }
+ save := func(err error) (int64, error) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{plain: err}
+ }
+ return end, nil
+ }
+ if len(value) == 0 {
+ return save(invalidUse())
+ }
+ elem := typ
+ for elem.Kind() == reflect.Pointer {
+ elem = elem.Elem()
+ }
+ invalidUse = func() error {
+ return fmt.Errorf("json: invalid use of ,string struct tag, trying to unmarshal %q into %v", value, elem)
+ }
+ switch c := value[0]; {
+ case c == 'n', c == 't', c == 'f':
+ return save(invalidUse())
+ case c == '"':
+ if elem == jsonNumberType {
+ // a JSON string, whose bytes must be a number
+ if s, ok := unquoteBytes(value); ok && !isValidNumber(s) {
+ return 0, fmt.Errorf("json: invalid number literal, trying to unmarshal %q into Number", value)
+ }
+ }
+ if elem.Kind() == reflect.String {
+ return 0, invalidUse()
+ }
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{typ: elem, start: start, end: end, value: "string", kind: stringValue, literal: true}
+ }
+ return end, nil
+ case c != '-' && c-'0' > 9:
+ return 0, invalidUse()
+ }
+ switch elem.Kind() {
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr,
+ reflect.Float32, reflect.Float64:
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: elem, start: start, end: end, value: "number " + string(value), kind: numberValue, literal: true,
+ }
+ }
+ return end, nil
+ }
+ return 0, invalidUse()
+}
+
+// annotateMethodError sets the field of a type error, or the offset of a syntax error, which an unmarshal method
+// of the value at cursor returned, as encoding/json before Go 1.27 does.
+func annotateMethodError(cursor int64, err error, structName, fieldName string) {
+ switch e := err.(type) {
+ case *errors.UnmarshalTypeError:
+ e.Struct = structName
+ e.Field = fieldName
+ case *json.UnmarshalTypeError:
+ // the type error of encoding/json, which it sets as its own
+ e.Struct = structName
+ e.Field = fieldName
+ case *errors.SyntaxError:
+ e.Offset = cursor
+ }
+}
+
+// methodError returns err, which an unmarshal method of the value between cursor and end returned: encoding/json
+// before Go 1.27 stops the decoding with it, with the field of a type error and the offset of a syntax error.
+func (ctx *RuntimeContext) methodError(cursor, _ int64, err error, structName, fieldName string) (int64, error) {
+ annotateMethodError(cursor, err, structName, fieldName)
+ return 0, err
+}
+
+// timeKindTypeErrors is whether a value of a time.Time which is not a string or null is a type error: encoding/json
+// before Go 1.27 gives it to the UnmarshalJSON of time.Time, whose error stops the decoding.
+const timeKindTypeErrors = false
+
+// stringOptionNumber reports whether the bytes of the string of a json.Number of the string option are stored as
+// they are: encoding/json before Go 1.27 stores any bytes which start as a number does, without the grammar of the
+// numbers, and decodes any other ones as a JSON value ( see stringOptionNumberDecoded ).
+func stringOptionNumber(value []byte) bool {
+ return len(value) != 0 && (value[0] == '-' || value[0]-'0' <= 9)
+}
+
+// stringOptionNumberDecoded is whether the bytes of the string of a json.Number of the string option, when
+// stringOptionNumber doesn't store them, are decoded as a JSON value, a string of a number or null, as encoding/json
+// before Go 1.27 decodes them.
+const stringOptionNumberDecoded = true
+
+// stringOptionUnquotedAllocates is whether a nil pointer of a field of the string option is set to a zero value
+// when the value of the field is not in a string: encoding/json before Go 1.27 leaves it.
+const stringOptionUnquotedAllocates = false
+
+// StreamOffsetBase returns the position which the offsets of the type errors of a value of a stream are relative to,
+// of the end of the previous value and of the start of the value: encoding/json before Go 1.27 reports them from
+// the end of the previous value.
+func StreamOffsetBase(prevEnd, _ int64) int64 {
+ return prevEnd
+}
+
+// stringOptionAllocates reports whether a nil pointer of a field of the string option is set to a zero value when
+// the value in the string of the field is not of its type: encoding/json before Go 1.27 leaves it for an empty
+// string.
+func stringOptionAllocates(value []byte) bool {
+ return len(value) > 0
+}
+
+// textUnmarshalerKindError records the type error of the value at cursor, which is not a string, of a type whose
+// pointer type typ implements encoding.TextUnmarshaler, and skips it: encoding/json before Go 1.27 reports the
+// pointer type.
+func (ctx *RuntimeContext) textUnmarshalerKindError(cursor, depth int64, typ reflect.Type) (int64, error) {
+ return ctx.skipTypeError(cursor, depth, typ)
+}
+
+// ifaceTextUnmarshalerKindError records the type error of the value at cursor, which is not a string, of an
+// interface value of ifaceType which holds a pointer of typ, which implements encoding.TextUnmarshaler, and skips
+// it: encoding/json before Go 1.27 reports the interface type.
+func (ctx *RuntimeContext) ifaceTextUnmarshalerKindError(cursor, depth int64, ifaceType, _ reflect.Type) (int64, error) {
+ return ctx.skipTypeError(cursor, depth, ifaceType)
+}
+
+// keptInterfaceTypeError records the type error of the value at cursor, which is not null, decoded into the
+// value at p of the interface type typ, which has methods and holds no pointer, and skips it: encoding/json before
+// Go 1.27 keeps the interface value, and reports the error as the other type errors.
+func (ctx *RuntimeContext) keptInterfaceTypeError(cursor, depth int64, typ reflect.Type, _ unsafe.Pointer) (int64, error) {
+ return ctx.skipTypeError(cursor, depth, typ)
+}
+
+// textUnmarshalerNullSetsZero reports whether null sets a value of the kind, whose pointer type implements
+// encoding.TextUnmarshaler, to its zero value: encoding/json before Go 1.27 does it for a slice, a map, a pointer
+// and an interface value, as it does for any value of these kinds.
+func textUnmarshalerNullSetsZero(kind reflect.Kind) bool {
+ switch kind {
+ case reflect.Slice, reflect.Map, reflect.Pointer, reflect.Interface:
+ return true
+ }
+ return false
+}
+
+// unsettableFieldError records err, the error of a field of the struct typ which can't be set, as an embedded
+// pointer to an unexported struct, for the value at cursor, and skips the value: encoding/json before Go 1.27
+// returns the error as it is.
+func (ctx *RuntimeContext) unsettableFieldError(cursor, depth int64, _ reflect.Type, err error) (int64, error) {
+ buf := ctx.Buf
+ end, skipErr := skipValue(buf, skipWhiteSpace(buf, cursor), depth)
+ if skipErr != nil {
+ return 0, skipErr
+ }
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{plain: err}
+ }
+ return end, nil
+}
+
+// storesFloatsOutOfRange reports whether a number out of the range of a float is stored as ±Inf with its type
+// error: encoding/json before Go 1.27 leaves the value as it is.
+const storesFloatsOutOfRange = false
+
+// floatRangeErrorOfInterface records the type error of the number between start and end, which is out of the
+// range of a float64, decoded into the interface{} at p, of value f: encoding/json before Go 1.27 leaves the
+// value as it is, and reports the error after the byte which follows the number.
+func (ctx *RuntimeContext) floatRangeErrorOfInterface(start, end int64, _ float64, _ unsafe.Pointer) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: float64Type, start: start, end: end + 1, value: "number " + string(ctx.Buf[start:end]),
+ kind: numberValue, literal: true,
+ }
+ }
+}
+
+// stringOptionNumberStart reports whether c starts a number of a string of the string option which encoding/json
+// before Go 1.27 reads: a minus sign or a digit. It reads the numbers of the keys of maps whatever they start with.
+func stringOptionNumberStart(c byte) bool {
+ return c == '-' || c-'0' <= 9
+}
+
+// mapKeySupported reports whether encoding/json before Go 1.27 decodes the keys of a map of keyType, which dec
+// decodes: strings, integers and the types which implement encoding.TextUnmarshaler.
+func mapKeySupported(keyType reflect.Type, dec Decoder) bool {
+ if _, ok := dec.(*unmarshalTextDecoder); ok {
+ return true
+ }
+ switch keyType.Kind() {
+ case reflect.String,
+ reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr:
+ return true
+ }
+ return false
+}
+
+// unsupportedMapKeys records the type error of the object at cursor of a map whose keys are not decoded ( see
+// mapKeySupported ), and skips it: encoding/json before Go 1.27 reports the map, which is left.
+func (ctx *RuntimeContext) unsupportedMapKeys(d *mapDecoder, cursor, depth int64, _ unsafe.Pointer) (int64, error) {
+ return ctx.skipTypeError(cursor, depth, d.mapType)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/type_error_v2.go b/vendor/github.com/goccy/go-json/internal/decoder/type_error_v2.go
new file mode 100644
index 000000000..e0215549b
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/decoder/type_error_v2.go
@@ -0,0 +1,353 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package decoder
+
+import (
+ stderrors "errors"
+ "fmt"
+ "reflect"
+ "strconv"
+ "strings"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+)
+
+// newTypeError returns the type error as encoding/json of Go 1.27, which is made of encoding/json/v2, reports it.
+// Offset is after the value, or after the key of a map entry. Struct is the name of the root type, and Field the
+// path from it to the value: the names of the fields, the indices of the elements and the keys of the entries.
+// An error at the root has neither.
+// jsonPointerEscaper escapes a token of a JSON pointer ( RFC 6901 ).
+var jsonPointerEscaper = strings.NewReplacer("~", "~0", "/", "~1")
+
+func newTypeError(p *pendingTypeError, path []typeErrorStep, root reflect.Type) *errors.UnmarshalTypeError {
+ e := &errors.UnmarshalTypeError{Value: p.value, Type: p.typ, Offset: p.end, Err: p.err}
+ if !p.literal && (p.kind == arrayValue || p.kind == objectValue) {
+ e.Offset = p.start + 1
+ }
+ if p.noContext {
+ e.Offset = 0
+ return e
+ }
+ if len(path) > 0 {
+ if root.Kind() == reflect.Pointer {
+ root = root.Elem()
+ }
+ e.Struct = root.Name()
+ names := make([]string, len(path))
+ for i, step := range path {
+ names[i] = step.name
+ if step.isField {
+ // the key of a field as the input has it
+ names[i] = step.inputName
+ }
+ // encoding/json of Go 1.27 makes the path of the tokens of the JSON pointer of the value, which are
+ // escaped as a JSON pointer escapes them
+ names[i] = jsonPointerEscaper.Replace(names[i])
+ }
+ e.Field = strings.Join(names, ".")
+ }
+ return e
+}
+
+// base64Error records the error of the decoding of the string between start and end into typ, which is not
+// base64: encoding/json of Go 1.27 reports it as a type error of the string, whose cause is the error.
+func (ctx *RuntimeContext) base64Error(start, end int64, typ reflect.Type, err error) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{typ: typ, start: start, end: end, value: "string", kind: stringValue, err: err}
+ }
+}
+
+// numberKindError records the type error of the value at cursor, of another kind than a number or a string,
+// which is decoded into a json.Number, and skips it: encoding/json of Go 1.27 reports it with no path and no
+// offset.
+func (ctx *RuntimeContext) numberKindError(cursor, depth int64, typ reflect.Type) (int64, error) {
+ first := ctx.typeError == nil
+ next, err := ctx.skipTypeError(cursor, depth, typ)
+ if err == nil && first {
+ ctx.typeError.noContext = true
+ }
+ return next, err
+}
+
+// numberStringError records the type error of the string between start and end, which is not a number, decoded
+// into a json.Number: encoding/json of Go 1.27 reports the string, with no path and no offset.
+func (ctx *RuntimeContext) numberStringError(start, end int64, typ reflect.Type) (int64, error) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: typ, start: start, end: end, value: "string " + string(ctx.Buf[start:end]), kind: stringValue,
+ literal: true, err: strconv.ErrSyntax, noContext: true,
+ }
+ }
+ return end, nil
+}
+
+// stringOptionUnquoted records the type error of the value at cursor of a field of the string option, which is not
+// in a string, and skips it: encoding/json of Go 1.27 reports the value as a value of the type of the field.
+func (ctx *RuntimeContext) stringOptionUnquoted(cursor, depth int64, typ reflect.Type) (int64, error) {
+ for typ.Kind() == reflect.Pointer {
+ typ = typ.Elem()
+ }
+ if typ == jsonNumberType {
+ return ctx.numberKindError(cursor, depth, typ)
+ }
+ return ctx.skipTypeError(cursor, depth, typ)
+}
+
+// methodError records err, which an unmarshal method of the value between cursor and end returned, if it is the
+// first error, and returns end: encoding/json of Go 1.27 goes on after it, as after a type error, and returns it as
+// it is.
+func (ctx *RuntimeContext) methodError(_, end int64, err error, _, _ string) (int64, error) {
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{plain: err}
+ }
+ return end, nil
+}
+
+// timeKindTypeErrors is whether a value of a time.Time which is not a string or null is a type error: encoding/json
+// of Go 1.27 reports it as a type error, after which the decoding goes on.
+const timeKindTypeErrors = true
+
+// stringOptionNumber reports whether the bytes of the string of a json.Number of the string option are stored as
+// they are: encoding/json of Go 1.27 stores a number by the grammar of the numbers, and nothing else.
+func stringOptionNumber(value []byte) bool {
+ return isValidNumber(value)
+}
+
+// stringOptionNumberDecoded is whether the bytes of the string of a json.Number of the string option, when they are
+// not a number, are decoded as a JSON value: encoding/json of Go 1.27 reports them as a type error.
+const stringOptionNumberDecoded = false
+
+// stringOptionError records the type error of the string between start and end of a field of the string option,
+// whose bytes are not a value of typ: encoding/json of Go 1.27 reports the bytes as a number for a number type,
+// and else the string, whose cause is a syntax error.
+func (ctx *RuntimeContext) stringOptionError(start, end int64, value []byte, typ reflect.Type) (int64, error) {
+ for typ.Kind() == reflect.Pointer {
+ typ = typ.Elem()
+ }
+ if typ == jsonNumberType {
+ return ctx.numberStringError(start, end, typ)
+ }
+ if ctx.typeError != nil {
+ return end, nil
+ }
+ p := &pendingTypeError{typ: typ, start: start, end: end, kind: stringValue, literal: true}
+ switch typ.Kind() {
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr,
+ reflect.Float32, reflect.Float64:
+ p.value = "number " + string(value)
+ case reflect.String:
+ // the bytes are decoded as a JSON string, whose syntax error is the cause
+ p.value = "string"
+ p.err = stringOptionStringError(value)
+ default:
+ p.value = "string " + string(ctx.Buf[start:end])
+ p.err = strconv.ErrSyntax
+ }
+ ctx.typeError = p
+ return end, nil
+}
+
+// stringOptionUnquotedAllocates is whether a nil pointer of a field of the string option is set to a zero value
+// when the value of the field is not in a string: encoding/json of Go 1.27 sets it.
+const stringOptionUnquotedAllocates = true
+
+// StreamOffsetBase returns the position which the offsets of the type errors of a value of a stream are relative to,
+// of the end of the previous value and of the start of the value: encoding/json of Go 1.27 reports them from the
+// start of the value.
+func StreamOffsetBase(_, valueStart int64) int64 {
+ return valueStart
+}
+
+// stringOptionAllocates reports whether a nil pointer of a field of the string option is set to a zero value when
+// the value in the string of the field is not of its type: encoding/json of Go 1.27 sets it.
+func stringOptionAllocates([]byte) bool {
+ return true
+}
+
+// errTextUnmarshalerKind is the cause of the type error of a value which is not a string, of a type which
+// implements encoding.TextUnmarshaler, as encoding/json of Go 1.27 reports it.
+var errTextUnmarshalerKind = stderrors.New("JSON value must be string type")
+
+// textUnmarshalerKindError records the type error of the value at cursor, which is not a string, of a type whose
+// pointer type typ implements encoding.TextUnmarshaler, and skips it: encoding/json of Go 1.27 reports the type
+// of the value, and the cause of the error.
+func (ctx *RuntimeContext) textUnmarshalerKindError(cursor, depth int64, typ reflect.Type) (int64, error) {
+ first := ctx.typeError == nil
+ next, err := ctx.skipTypeError(cursor, depth, typ.Elem())
+ if err == nil && first {
+ ctx.typeError.err = errTextUnmarshalerKind
+ }
+ return next, err
+}
+
+// ifaceTextUnmarshalerKindError records the type error of the value at cursor, which is not a string, of an
+// interface value of ifaceType which holds a pointer of typ, which implements encoding.TextUnmarshaler, and skips
+// it: encoding/json of Go 1.27 reports it as the one of the pointer ( see textUnmarshalerKindError ).
+func (ctx *RuntimeContext) ifaceTextUnmarshalerKindError(cursor, depth int64, _, typ reflect.Type) (int64, error) {
+ return ctx.textUnmarshalerKindError(cursor, depth, typ)
+}
+
+// keptInterfaceTypeError records the type error of the value at cursor, which is not null, decoded into the
+// value at p of the interface type typ, which has methods and holds no pointer, and skips it: encoding/json of Go
+// 1.27 sets the interface value to nil, and reports the error at the start of the value.
+func (ctx *RuntimeContext) keptInterfaceTypeError(cursor, depth int64, typ reflect.Type, p unsafe.Pointer) (int64, error) {
+ *(*[2]unsafe.Pointer)(p) = [2]unsafe.Pointer{}
+ first := ctx.typeError == nil
+ next, err := ctx.skipTypeError(cursor, depth, typ)
+ if err == nil && first {
+ ctx.typeError.atStart = true
+ }
+ return next, err
+}
+
+// textUnmarshalerNullSetsZero reports whether null sets a value of the kind, whose pointer type implements
+// encoding.TextUnmarshaler, to its zero value: encoding/json of Go 1.27 leaves every such value as it is.
+func textUnmarshalerNullSetsZero(reflect.Kind) bool {
+ return false
+}
+
+// errUnsettableEmbeddedPointer is the cause which encoding/json of Go 1.27 reports for a field promoted from an
+// embedded pointer to an unexported struct, which can't be set.
+var errUnsettableEmbeddedPointer = stderrors.New("cannot set embedded pointer to unexported struct type")
+
+// unsettableFieldError records the type error of the value at cursor of a field of the struct typ which can't be
+// set, as an embedded pointer to an unexported struct, and skips the value: encoding/json of Go 1.27 reports it as
+// a type error of the struct at the start of the value.
+func (ctx *RuntimeContext) unsettableFieldError(cursor, depth int64, typ reflect.Type, _ error) (int64, error) {
+ first := ctx.typeError == nil
+ next, err := ctx.skipTypeError(cursor, depth, typ)
+ if err == nil && first {
+ ctx.typeError.err = errUnsettableEmbeddedPointer
+ ctx.typeError.atStart = true
+ }
+ return next, err
+}
+
+// storesFloatsOutOfRange reports whether a number out of the range of a float is stored as ±Inf with its type
+// error, as encoding/json of Go 1.27 does.
+const storesFloatsOutOfRange = true
+
+// floatRangeErrorOfInterface records the type error of the number between start and end, which is out of the
+// range of a float64, decoded into the interface{} at p, and stores f, which is ±Inf, as encoding/json of Go 1.27
+// does.
+func (ctx *RuntimeContext) floatRangeErrorOfInterface(start, end int64, f float64, p unsafe.Pointer) {
+ **(**any)(unsafe.Pointer(&p)) = ctx.boxFloat(f)
+ ctx.numberTypeError(start, end, float64Type)
+}
+
+// stringOptionNumberStart reports whether c starts a number of a string of the string option which encoding/json
+// reads: encoding/json of Go 1.27 reads whatever strconv reads.
+func stringOptionNumberStart(byte) bool {
+ return true
+}
+
+// mapKeySupported reports whether encoding/json of Go 1.27 decodes the keys of a map of keyType, which dec
+// decodes: any key but a bool and a key of a type which no key is decoded into.
+func mapKeySupported(keyType reflect.Type, dec Decoder) bool {
+ if _, ok := dec.(*invalidDecoder); ok {
+ return false
+ }
+ return keyType.Kind() != reflect.Bool
+}
+
+// unsupportedMapKeys records the type error of the first key of the object at cursor of a map whose keys are not
+// decoded ( see mapKeySupported ), and skips the object: encoding/json of Go 1.27 reports the key as a string of
+// the type of the keys, and makes the map.
+func (ctx *RuntimeContext) unsupportedMapKeys(d *mapDecoder, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ if *(*unsafe.Pointer)(p) == nil {
+ *(*unsafe.Pointer)(p) = reflect.MakeMapWithSize(d.mapType, 0).UnsafePointer()
+ }
+ cursor = skipWhiteSpace(buf, cursor) + 1
+ for {
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == '}' {
+ return cursor + 1, nil
+ }
+ keyStart := cursor
+ keyEnd, err := skipValue(buf, cursor, depth)
+ if err != nil {
+ return 0, err
+ }
+ if ctx.typeError == nil {
+ ctx.typeError = &pendingTypeError{
+ typ: d.keyType, start: keyStart, end: keyEnd, value: "string", kind: stringValue, atKey: true,
+ literal: true,
+ }
+ }
+ cursor = skipWhiteSpace(buf, keyEnd)
+ if buf[cursor] != ':' {
+ return 0, errors.ErrExpected("colon after object key", cursor)
+ }
+ end, err := skipValue(buf, skipWhiteSpace(buf, cursor+1), depth)
+ if err != nil {
+ return 0, err
+ }
+ cursor = skipWhiteSpace(buf, end)
+ switch buf[cursor] {
+ case ',':
+ cursor++
+ case '}':
+ return cursor + 1, nil
+ default:
+ return 0, errors.ErrExpected("comma after object value", cursor)
+ }
+ }
+}
+
+// stringOptionStringError returns the syntax error of the bytes of a string of the string option of a string,
+// which are not a JSON string and nothing else, as encoding/json of Go 1.27 reports it.
+func stringOptionStringError(value []byte) error {
+ if len(value) == 0 {
+ return errors.ErrSyntax("unexpected end of JSON input", 0)
+ }
+ if value[0] != '"' {
+ return errors.ErrSyntax(fmt.Sprintf("invalid character %s looking for beginning of object key string", quoteChar(value[0])), 0)
+ }
+ i := 1
+ for {
+ if i >= len(value) {
+ return errors.ErrSyntax("unexpected end of JSON input", 0)
+ }
+ c := value[i]
+ if c == '"' {
+ i++
+ break
+ }
+ if c != '\\' {
+ i++
+ continue
+ }
+ if i+1 >= len(value) {
+ return errors.ErrSyntax("unexpected end of JSON input", 0)
+ }
+ switch value[i+1] {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ i += 2
+ continue
+ case 'u':
+ if i+6 <= len(value) && isHex(value[i+2:i+6]) {
+ i += 6
+ continue
+ }
+ return errors.ErrSyntax(fmt.Sprintf("invalid escape sequence `%s` in string", value[i:min(i+6, len(value))]), 0)
+ }
+ return errors.ErrSyntax(fmt.Sprintf("invalid escape sequence `%s` in string", value[i:i+2]), 0)
+ }
+ if i < len(value) {
+ return errors.ErrSyntax(fmt.Sprintf("invalid character %s after string value", quoteChar(value[i])), 0)
+ }
+ return nil
+}
+
+// isHex reports whether every byte of b is a hexadecimal digit.
+func isHex(b []byte) bool {
+ for _, c := range b {
+ if !('0' <= c && c <= '9' || 'a' <= c && c <= 'f' || 'A' <= c && c <= 'F') {
+ return false
+ }
+ }
+ return true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/uint.go b/vendor/github.com/goccy/go-json/internal/decoder/uint.go
index 4131731b8..42e2e37b6 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/uint.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/uint.go
@@ -4,20 +4,17 @@ import (
"fmt"
"reflect"
"unsafe"
-
- "github.com/goccy/go-json/internal/errors"
- "github.com/goccy/go-json/internal/runtime"
)
type uintDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
kind reflect.Kind
op func(unsafe.Pointer, uint64)
structName string
fieldName string
}
-func newUintDecoder(typ *runtime.Type, structName, fieldName string, op func(unsafe.Pointer, uint64)) *uintDecoder {
+func newUintDecoder(typ reflect.Type, structName, fieldName string, op func(unsafe.Pointer, uint64)) *uintDecoder {
return &uintDecoder{
typ: typ,
kind: typ.Kind(),
@@ -27,166 +24,122 @@ func newUintDecoder(typ *runtime.Type, structName, fieldName string, op func(uns
}
}
-func (d *uintDecoder) typeError(buf []byte, offset int64) *errors.UnmarshalTypeError {
- return &errors.UnmarshalTypeError{
- Value: fmt.Sprintf("number %s", string(buf)),
- Type: runtime.RType2Type(d.typ),
- Offset: offset,
- }
-}
-
-var (
- pow10u64 = [...]uint64{
- 1e00, 1e01, 1e02, 1e03, 1e04, 1e05, 1e06, 1e07, 1e08, 1e09,
- 1e10, 1e11, 1e12, 1e13, 1e14, 1e15, 1e16, 1e17, 1e18, 1e19,
+func (d *uintDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ if buf[cursor] == 'n' {
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
+ }
+ return cursor + 4, nil
}
- pow10u64Len = len(pow10u64)
-)
-
-func (d *uintDecoder) parseUint(b []byte) (uint64, error) {
- maxDigit := len(b)
- if maxDigit > pow10u64Len {
- return 0, fmt.Errorf("invalid length of number")
+ if buf[cursor]-'0' > 9 {
+ return d.decodeSlow(ctx, cursor, depth, p)
}
- sum := uint64(0)
- for i := 0; i < maxDigit; i++ {
- c := uint64(b[i]) - 48
- digitValue := pow10u64[maxDigit-i-1]
- sum += c * digitValue
+ start := cursor
+ u, next, digits := parseDigits(buf, cursor)
+ if isFloatContinuation(buf[next]) || digits > maxUint64Digits+1 {
+ return d.decodeSlow(ctx, start, depth, p)
}
- return sum, nil
-}
-
-func (d *uintDecoder) decodeStreamByte(s *Stream) ([]byte, error) {
- for {
- switch s.char() {
- case ' ', '\n', '\t', '\r':
- s.cursor++
- continue
- case '0':
- s.cursor++
- return numZeroBuf, nil
- case '1', '2', '3', '4', '5', '6', '7', '8', '9':
- start := s.cursor
- for {
- s.cursor++
- if numTable[s.char()] {
- continue
- } else if s.char() == nul {
- if s.read() {
- s.cursor-- // for retry current character
- continue
- }
- }
- break
- }
- num := s.buf[start:s.cursor]
- return num, nil
- case 'n':
- if err := nullBytes(s); err != nil {
- return nil, err
- }
- return nil, nil
- case nul:
- if s.read() {
- continue
- }
- default:
- return nil, d.typeError([]byte{s.char()}, s.totalOffset())
+ if digits == maxUint64Digits+1 {
+ // 20 digits: the value of the first 19 is exact, and the last one fits if the whole is less than 1<<64.
+ var hi uint64
+ for i := int64(0); i < maxUint64Digits; i++ {
+ hi = hi*10 + uint64(buf[start+i]-'0')
}
- break
- }
- return nil, errors.ErrUnexpectedEndOfJSON("number(unsigned integer)", s.totalOffset())
-}
-
-func (d *uintDecoder) decodeByte(buf []byte, cursor int64) ([]byte, int64, error) {
- for {
- switch buf[cursor] {
- case ' ', '\n', '\t', '\r':
- cursor++
- continue
- case '0':
- cursor++
- return numZeroBuf, cursor, nil
- case '1', '2', '3', '4', '5', '6', '7', '8', '9':
- start := cursor
- cursor++
- for numTable[buf[cursor]] {
- cursor++
- }
- num := buf[start:cursor]
- return num, cursor, nil
- case 'n':
- if err := validateNull(buf, cursor); err != nil {
- return nil, 0, err
- }
- cursor += 4
- return nil, cursor, nil
- default:
- return nil, 0, d.typeError([]byte{buf[cursor]}, cursor)
+ lo := uint64(buf[start+maxUint64Digits] - '0')
+ if hi > (1<<64-1)/10 || (hi == (1<<64-1)/10 && lo > (1<<64-1)%10) {
+ return d.decodeSlow(ctx, start, depth, p)
}
- }
-}
-
-func (d *uintDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.decodeStreamByte(s)
- if err != nil {
- return err
- }
- if bytes == nil {
- return nil
- }
- u64, err := d.parseUint(bytes)
- if err != nil {
- return d.typeError(bytes, s.totalOffset())
+ u = hi*10 + lo
}
switch d.kind {
case reflect.Uint8:
- if (1 << 8) <= u64 {
- return d.typeError(bytes, s.totalOffset())
+ if (1 << 8) <= u {
+ return d.decodeSlow(ctx, start, depth, p)
}
case reflect.Uint16:
- if (1 << 16) <= u64 {
- return d.typeError(bytes, s.totalOffset())
+ if (1 << 16) <= u {
+ return d.decodeSlow(ctx, start, depth, p)
}
case reflect.Uint32:
- if (1 << 32) <= u64 {
- return d.typeError(bytes, s.totalOffset())
+ if (1 << 32) <= u {
+ return d.decodeSlow(ctx, start, depth, p)
}
}
- d.op(p, u64)
- return nil
+ d.op(p, u)
+ return next, nil
}
-func (d *uintDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- bytes, c, err := d.decodeByte(ctx.Buf, cursor)
- if err != nil {
- return 0, err
+// decodeSlow decodes the value at cursor, which Decode doesn't: a value of another kind, a negative number or
+// a number which is not an integer of the type, which are type errors, or a syntax error. It is a function of its
+// own, so that Decode keeps the size it had.
+//
+//go:noinline
+func (d *uintDecoder) decodeSlow(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ switch c := buf[cursor]; {
+ case c == 'n':
+ if err := validateNull(buf, cursor); err != nil {
+ return 0, err
+ }
+ return cursor + 4, nil
+ case c == '-':
+ // a negative number, which the error reports
+ end, err := numberEnd(buf, cursor)
+ if err != nil {
+ return 0, err
+ }
+ ctx.numberTypeError(cursor, end, d.typ)
+ return end, nil
+ case c-'0' > 9:
+ // a value of another kind
+ return ctx.skipTypeError(cursor, depth, d.typ)
}
- if bytes == nil {
- return c, nil
+ start := cursor
+ u, next, digits := parseDigits(buf, cursor)
+ if isFloatContinuation(buf[next]) || digits > maxUint64Digits+1 {
+ // a number which is not an integer, or too large for any integer
+ end, err := numberEnd(buf, start)
+ if err != nil {
+ return 0, err
+ }
+ ctx.numberTypeError(start, end, d.typ)
+ return end, nil
}
- cursor = c
- u64, err := d.parseUint(bytes)
- if err != nil {
- return 0, d.typeError(bytes, cursor)
+ if digits == maxUint64Digits+1 {
+ // 20 digits: the value of the first 19 is exact, and the last one fits if the whole is less than 1<<64.
+ var hi uint64
+ for i := int64(0); i < maxUint64Digits; i++ {
+ hi = hi*10 + uint64(buf[start+i]-'0')
+ }
+ lo := uint64(buf[start+maxUint64Digits] - '0')
+ if hi > (1<<64-1)/10 || (hi == (1<<64-1)/10 && lo > (1<<64-1)%10) {
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
+ }
+ u = hi*10 + lo
}
switch d.kind {
case reflect.Uint8:
- if (1 << 8) <= u64 {
- return 0, d.typeError(bytes, cursor)
+ if (1 << 8) <= u {
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
case reflect.Uint16:
- if (1 << 16) <= u64 {
- return 0, d.typeError(bytes, cursor)
+ if (1 << 16) <= u {
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
case reflect.Uint32:
- if (1 << 32) <= u64 {
- return 0, d.typeError(bytes, cursor)
+ if (1 << 32) <= u {
+ ctx.numberTypeError(start, next, d.typ)
+ return next, nil
}
}
- d.op(p, u64)
- return cursor, nil
+ d.op(p, u)
+ return next, nil
}
func (d *uintDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_json.go b/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_json.go
index 4cd6dbd57..f45963874 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_json.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_json.go
@@ -4,96 +4,91 @@ import (
"context"
"encoding/json"
"fmt"
+ "reflect"
+ "time"
"unsafe"
- "github.com/goccy/go-json/internal/errors"
"github.com/goccy/go-json/internal/runtime"
)
type unmarshalJSONDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
structName string
fieldName string
+ // retainsNothing is set for a type whose UnmarshalJSON keeps nothing of the bytes it is given, which are then
+ // the ones of the buffer: a type of the standard library ( see runtime.IsStdMarshalerType ), a type which has
+ // the UnmarshalJSON of one only by embedding it, and json.RawMessage, which copies them. The bytes of any other type are copied: its UnmarshalJSON may keep them,
+ // and the buffer is written again by the next call.
+ retainsNothing bool
}
-func newUnmarshalJSONDecoder(typ *runtime.Type, structName, fieldName string) *unmarshalJSONDecoder {
- return &unmarshalJSONDecoder{
- typ: typ,
- structName: structName,
- fieldName: fieldName,
- }
-}
+// timePtrType is the type of *time.Time, which is decoded from a string only. The decoder is made for the pointer
+// type, whose method set has UnmarshalJSON.
+var timePtrType = reflect.TypeOf(&time.Time{})
-func (d *unmarshalJSONDecoder) annotateError(cursor int64, err error) {
- switch e := err.(type) {
- case *errors.UnmarshalTypeError:
- e.Struct = d.structName
- e.Field = d.fieldName
- case *errors.SyntaxError:
- e.Offset = cursor
- }
-}
+// rawMessagePtrType is the type of *json.RawMessage, whose UnmarshalJSON copies the bytes it is given: a copy of
+// them made here would be copied again.
+var rawMessagePtrType = reflect.TypeOf(&json.RawMessage{})
-func (d *unmarshalJSONDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- s.skipWhiteSpace()
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- dst := make([]byte, len(src))
- copy(dst, src)
+// timeType is the type of time.Time.
+var timeType = timePtrType.Elem()
- v := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
- ptr: p,
- }))
- switch v := v.(type) {
- case unmarshalerContext:
- var ctx context.Context
- if (s.Option.Flags & ContextOption) != 0 {
- ctx = s.Option.Context
- } else {
- ctx = context.Background()
- }
- if err := v.UnmarshalJSON(ctx, dst); err != nil {
- d.annotateError(s.cursor, err)
- return err
- }
- case json.Unmarshaler:
- if err := v.UnmarshalJSON(dst); err != nil {
- d.annotateError(s.cursor, err)
- return err
- }
+func newUnmarshalJSONDecoder(typ reflect.Type, structName, fieldName string) *unmarshalJSONDecoder {
+ return &unmarshalJSONDecoder{
+ typ: typ,
+ structName: structName,
+ fieldName: fieldName,
+ retainsNothing: typ == rawMessagePtrType || runtime.IsStdMarshalerType(typ) || promotesStdUnmarshalJSON(typ),
}
- return nil
+}
+
+// promotesStdUnmarshalJSON is whether the UnmarshalJSON of the type is the one of an embedded type of the standard
+// library, which the type doesn't declare itself ( see runtime.PromotedStdMethod ).
+func promotesStdUnmarshalJSON(typ reflect.Type) bool {
+ _, _, _, ok := runtime.PromotedStdMethod(typ, runtime.UnmarshalJSONMethod)
+ return ok
}
func (d *unmarshalJSONDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
+ if timeKindTypeErrors && d.typ == timePtrType {
+ if c := buf[cursor]; c != '"' && c != 'n' {
+ // a time.Time is decoded from a string only: any other value is a type error
+ return ctx.skipTypeError(cursor, depth, timeType)
+ }
+ }
start := cursor
end, err := skipValue(buf, cursor, depth)
if err != nil {
return 0, err
}
- src := buf[start:end]
- dst := make([]byte, len(src))
- copy(dst, src)
+ dst := buf[start:end:end]
+ if !d.retainsNothing {
+ // a copy of the exact length: append would round its capacity up, which costs more
+ copied := make([]byte, len(dst))
+ copy(copied, dst)
+ dst = copied
+ }
- v := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
+ v := *(*any)(unsafe.Pointer(&emptyInterface{
+ typ: runtime.TypePtr(d.typ),
ptr: p,
}))
- if (ctx.Option.Flags & ContextOption) != 0 {
- if err := v.(unmarshalerContext).UnmarshalJSON(ctx.Option.Context, dst); err != nil {
- d.annotateError(cursor, err)
- return 0, err
+ // The method is chosen by what the type implements, not by the entry point:
+ // json.Unmarshal may meet a type with the context method and UnmarshalContext one without it.
+ switch v := v.(type) {
+ case unmarshalerContext:
+ c := ctx.Option.Context
+ if (ctx.Option.Flags&ContextOption) == 0 || c == nil {
+ c = context.Background()
}
- } else {
- if err := v.(json.Unmarshaler).UnmarshalJSON(dst); err != nil {
- d.annotateError(cursor, err)
- return 0, err
+ if err := v.UnmarshalJSON(c, dst); err != nil {
+ return ctx.methodError(cursor, end, err, d.structName, d.fieldName)
+ }
+ case json.Unmarshaler:
+ if err := v.UnmarshalJSON(dst); err != nil {
+ return ctx.methodError(cursor, end, err, d.structName, d.fieldName)
}
}
return end, nil
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_text.go b/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_text.go
index d711d0f85..fd671cdc4 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_text.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/unmarshal_text.go
@@ -1,39 +1,32 @@
package decoder
import (
- "bytes"
"encoding"
"fmt"
+ "reflect"
"unicode"
"unicode/utf16"
"unicode/utf8"
"unsafe"
- "github.com/goccy/go-json/internal/errors"
"github.com/goccy/go-json/internal/runtime"
)
type unmarshalTextDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
structName string
fieldName string
+ // nullSetsZero is set for a value which null sets to its zero value ( see textUnmarshalerNullSetsZero ): null
+ // leaves any other value as it is, and is not given to UnmarshalText.
+ nullSetsZero bool
}
-func newUnmarshalTextDecoder(typ *runtime.Type, structName, fieldName string) *unmarshalTextDecoder {
+func newUnmarshalTextDecoder(typ reflect.Type, structName, fieldName string) *unmarshalTextDecoder {
return &unmarshalTextDecoder{
- typ: typ,
- structName: structName,
- fieldName: fieldName,
- }
-}
-
-func (d *unmarshalTextDecoder) annotateError(cursor int64, err error) {
- switch e := err.(type) {
- case *errors.UnmarshalTypeError:
- e.Struct = d.structName
- e.Field = d.fieldName
- case *errors.SyntaxError:
- e.Offset = cursor
+ typ: typ,
+ structName: structName,
+ fieldName: fieldName,
+ nullSetsZero: textUnmarshalerNullSetsZero(typ.Elem().Kind()),
}
}
@@ -41,57 +34,6 @@ var (
nullbytes = []byte(`null`)
)
-func (d *unmarshalTextDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- s.skipWhiteSpace()
- start := s.cursor
- if err := s.skipValue(depth); err != nil {
- return err
- }
- src := s.buf[start:s.cursor]
- if len(src) > 0 {
- switch src[0] {
- case '[':
- return &errors.UnmarshalTypeError{
- Value: "array",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case '{':
- return &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return &errors.UnmarshalTypeError{
- Value: "number",
- Type: runtime.RType2Type(d.typ),
- Offset: s.totalOffset(),
- }
- case 'n':
- if bytes.Equal(src, nullbytes) {
- *(*unsafe.Pointer)(p) = nil
- return nil
- }
- }
- }
- dst := make([]byte, len(src))
- copy(dst, src)
-
- if b, ok := unquoteBytes(dst); ok {
- dst = b
- }
- v := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
- ptr: p,
- }))
- if err := v.(encoding.TextUnmarshaler).UnmarshalText(dst); err != nil {
- d.annotateError(s.cursor, err)
- return err
- }
- return nil
-}
-
func (d *unmarshalTextDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
buf := ctx.Buf
cursor = skipWhiteSpace(buf, cursor)
@@ -101,44 +43,26 @@ func (d *unmarshalTextDecoder) Decode(ctx *RuntimeContext, cursor, depth int64,
return 0, err
}
src := buf[start:end]
- if len(src) > 0 {
- switch src[0] {
- case '[':
- return 0, &errors.UnmarshalTypeError{
- Value: "array",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case '{':
- return 0, &errors.UnmarshalTypeError{
- Value: "object",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case '-', '0', '1', '2', '3', '4', '5', '6', '7', '8', '9':
- return 0, &errors.UnmarshalTypeError{
- Value: "number",
- Type: runtime.RType2Type(d.typ),
- Offset: start,
- }
- case 'n':
- if bytes.Equal(src, nullbytes) {
- *(*unsafe.Pointer)(p) = nil
- return end, nil
- }
+ switch c := src[0]; {
+ case c == 'n':
+ if d.nullSetsZero {
+ reflect.NewAt(d.typ.Elem(), p).Elem().SetZero()
}
+ return end, nil
+ case c != '"':
+ // a value of another kind than a string, which is a type error
+ return ctx.textUnmarshalerKindError(start, depth, d.typ)
}
if s, ok := unquoteBytes(src); ok {
src = s
}
- v := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: d.typ,
+ v := *(*any)(unsafe.Pointer(&emptyInterface{
+ typ: runtime.TypePtr(d.typ),
ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
}))
if err := v.(encoding.TextUnmarshaler).UnmarshalText(src); err != nil {
- d.annotateError(cursor, err)
- return 0, err
+ return ctx.methodError(cursor, end, err, d.structName, d.fieldName)
}
return end, nil
}
diff --git a/vendor/github.com/goccy/go-json/internal/decoder/wrapped_string.go b/vendor/github.com/goccy/go-json/internal/decoder/wrapped_string.go
index 0c4e2e6ea..f46abda90 100644
--- a/vendor/github.com/goccy/go-json/internal/decoder/wrapped_string.go
+++ b/vendor/github.com/goccy/go-json/internal/decoder/wrapped_string.go
@@ -1,24 +1,43 @@
package decoder
import (
+ "encoding/json"
+ "errors"
"fmt"
"reflect"
+ "strconv"
"unsafe"
+)
- "github.com/goccy/go-json/internal/runtime"
+var (
+ // errStringOptionRest tells that the value of a string of the string option is followed by more bytes.
+ errStringOptionRest = errors.New("json: value followed by more bytes in a string of the string option")
+ // errMapKeyType is returned by the decoder of a key of a map which is not of the type of the keys, whose type
+ // error is recorded: the map decodes the value of the entry, and drops the entry, as encoding/json does.
+ errMapKeyType = errors.New("json: map key of another type")
)
type wrappedStringDecoder struct {
- typ *runtime.Type
+ typ reflect.Type
dec Decoder
stringDecoder *stringDecoder
structName string
fieldName string
isPtrType bool
+ // isMapKey is set for the decoder of the keys of a map, whose errors are the ones of the keys.
+ isMapKey bool
+ // numberKind is the kind of a number which the string has, read by strconv as encoding/json reads it ( see
+ // decodeNumber ), or reflect.Invalid for a value of any other type.
+ numberKind reflect.Kind
+ // numberType is the type of the number, which typ is or points to.
+ numberType reflect.Type
+ // isJSONNumber is set for a json.Number, or a pointer to one, whose bytes are checked as encoding/json of the Go
+ // version checks them ( see stringOptionNumber ).
+ isJSONNumber bool
}
-func newWrappedStringDecoder(typ *runtime.Type, dec Decoder, structName, fieldName string) *wrappedStringDecoder {
- return &wrappedStringDecoder{
+func newWrappedStringDecoder(typ reflect.Type, dec Decoder, structName, fieldName string) *wrappedStringDecoder {
+ d := &wrappedStringDecoder{
typ: typ,
dec: dec,
stringDecoder: newStringDecoder(structName, fieldName),
@@ -26,29 +45,38 @@ func newWrappedStringDecoder(typ *runtime.Type, dec Decoder, structName, fieldNa
fieldName: fieldName,
isPtrType: typ.Kind() == reflect.Ptr,
}
-}
-
-func (d *wrappedStringDecoder) DecodeStream(s *Stream, depth int64, p unsafe.Pointer) error {
- bytes, err := d.stringDecoder.decodeStreamByte(s)
- if err != nil {
- return err
+ numberType := typ
+ if numberType.Kind() == reflect.Pointer {
+ numberType = numberType.Elem()
}
- if bytes == nil {
- if d.isPtrType {
- *(*unsafe.Pointer)(p) = nil
+ d.isJSONNumber = numberType == jsonNumberType
+ switch numberType.Kind() {
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr,
+ reflect.Float32, reflect.Float64:
+ if numberType.Implements(unmarshalJSONType) || reflect.PointerTo(numberType).Implements(unmarshalJSONType) ||
+ reflect.PointerTo(numberType).Implements(unmarshalJSONContextType) ||
+ reflect.PointerTo(numberType).Implements(unmarshalTextType) {
+ // a number decoded by its own unmarshaler
+ break
}
- return nil
- }
- b := make([]byte, len(bytes)+1)
- copy(b, bytes)
- if _, err := d.dec.Decode(&RuntimeContext{Buf: b}, 0, depth, p); err != nil {
- return err
+ d.numberKind, d.numberType = numberType.Kind(), numberType
}
- return nil
+ return d
}
func (d *wrappedStringDecoder) Decode(ctx *RuntimeContext, cursor, depth int64, p unsafe.Pointer) (int64, error) {
- bytes, c, err := d.stringDecoder.decodeByte(ctx.Buf, cursor)
+ buf := ctx.Buf
+ cursor = skipWhiteSpace(buf, cursor)
+ start := cursor
+ if c := buf[cursor]; c != 'n' && isOtherValue(c, stringValue) {
+ // a value which is not in a string
+ if d.isPtrType && stringOptionUnquotedAllocates {
+ d.allocate(p)
+ }
+ return ctx.stringOptionUnquoted(cursor, depth, d.typ)
+ }
+ bytes, c, err := d.stringDecoder.decodeByte(buf, cursor)
if err != nil {
return 0, err
}
@@ -58,16 +86,135 @@ func (d *wrappedStringDecoder) Decode(ctx *RuntimeContext, cursor, depth int64,
}
return c, nil
}
- bytes = append(bytes, nul)
- oldBuf := ctx.Buf
- ctx.Buf = bytes
- if _, err := d.dec.Decode(ctx, 0, depth, p); err != nil {
- return 0, err
+ if d.isJSONNumber && !d.isMapKey {
+ if stringOptionNumber(bytes) {
+ *(*json.Number)(d.target(p)) = json.Number(ctx.makeString(bytes))
+ return c, nil
+ }
+ if !stringOptionNumberDecoded {
+ return d.stringError(ctx, start, c, bytes, p)
+ }
+ }
+ if d.numberKind != reflect.Invalid && len(bytes) > 0 {
+ if d.decodeNumber(bytes, p) {
+ return c, nil
+ }
+ return d.stringError(ctx, start, c, bytes, p)
+ }
+ if len(bytes) != 0 && (isWhiteSpace[bytes[0]] || isWhiteSpace[bytes[len(bytes)-1]]) {
+ // encoding/json reads the bytes of the string as a value with nothing around it
+ return d.stringError(ctx, start, c, bytes, p)
+ }
+ // The value is decoded from a copy of its bytes, which nothing else uses: its strings may refer to it. A type
+ // error of it is the one of the string, which is made after it ( see stringOptionError ).
+ saved := ctx.typeError
+ ctx.typeError = nil
+ oldBuf, oldOrigin := ctx.Buf, ctx.origin
+ ctx.Buf, ctx.origin = NewInput(bytes), nil
+ next, err := d.dec.Decode(ctx, 0, depth, p)
+ if err == nil && skipWhiteSpace(ctx.Buf, next) != int64(len(bytes)) {
+ // the value is followed by more bytes in the string
+ err = errStringOptionRest
+ }
+ ctx.Buf, ctx.origin = oldBuf, oldOrigin
+ failed := err != nil || ctx.typeError != nil
+ ctx.typeError = saved
+ if failed || len(bytes) == 0 {
+ return d.stringError(ctx, start, c, bytes, p)
}
- ctx.Buf = oldBuf
return c, nil
}
+// stringError records or returns the error of the string between start and end, whose bytes are not a value of
+// the type.
+func (d *wrappedStringDecoder) stringError(ctx *RuntimeContext, start, end int64, bytes []byte, p unsafe.Pointer) (int64, error) {
+ if d.isMapKey {
+ ctx.keyTypeError(start, end, bytes, d.elemType())
+ return end, errMapKeyType
+ }
+ if d.isPtrType && stringOptionAllocates(bytes) {
+ d.allocate(p)
+ }
+ return ctx.stringOptionError(start, end, bytes, d.typ)
+}
+
+// decodeNumber reads the number which the bytes of the string are, as encoding/json reads the number of a string of
+// the string option or of a key of a map, by strconv: a number which it fails, or which is out of the range of the
+// type, is not stored. It reports whether the number is stored.
+func (d *wrappedStringDecoder) decodeNumber(bytes []byte, p unsafe.Pointer) bool {
+ if !d.isMapKey && !stringOptionNumberStart(bytes[0]) {
+ return false
+ }
+ s := *(*string)(unsafe.Pointer(&bytes))
+ bits := int(d.numberType.Size() * 8)
+ switch d.numberKind {
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64:
+ n, err := strconv.ParseInt(s, 10, bits)
+ if err != nil {
+ return false
+ }
+ storeInt(d.target(p), bits, uint64(n))
+ case reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr:
+ n, err := strconv.ParseUint(s, 10, bits)
+ if err != nil {
+ return false
+ }
+ storeInt(d.target(p), bits, n)
+ default:
+ n, err := strconv.ParseFloat(s, bits)
+ if err != nil {
+ return false
+ }
+ if bits == 32 {
+ *(*float32)(d.target(p)) = float32(n)
+ } else {
+ *(*float64)(d.target(p)) = n
+ }
+ }
+ return true
+}
+
+// storeInt stores the lowest bits of n, an integer of the size of bits, at p.
+func storeInt(p unsafe.Pointer, bits int, n uint64) {
+ switch bits {
+ case 8:
+ *(*uint8)(p) = uint8(n)
+ case 16:
+ *(*uint16)(p) = uint16(n)
+ case 32:
+ *(*uint32)(p) = uint32(n)
+ default:
+ *(*uint64)(p) = n
+ }
+}
+
+// target returns where the number is stored: at p, or where the pointer at p points to, which is allocated if it
+// is nil.
+func (d *wrappedStringDecoder) target(p unsafe.Pointer) unsafe.Pointer {
+ if !d.isPtrType {
+ return p
+ }
+ d.allocate(p)
+ return *(*unsafe.Pointer)(p)
+}
+
+// elemType returns the type of the value, which the pointers of the type point to.
+func (d *wrappedStringDecoder) elemType() reflect.Type {
+ typ := d.typ
+ for typ.Kind() == reflect.Pointer {
+ typ = typ.Elem()
+ }
+ return typ
+}
+
+// allocate sets the pointer at p, if it is nil, to a zero value, as encoding/json does for a value it fails to
+// decode.
+func (d *wrappedStringDecoder) allocate(p unsafe.Pointer) {
+ if *(*unsafe.Pointer)(p) == nil {
+ *(*unsafe.Pointer)(p) = newValue(d.typ.Elem())
+ }
+}
+
func (d *wrappedStringDecoder) DecodePath(ctx *RuntimeContext, cursor, depth int64) ([][]byte, int64, error) {
return nil, 0, fmt.Errorf("json: wrapped string decoder does not support decode path")
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/code.go b/vendor/github.com/goccy/go-json/internal/encoder/code.go
index fec45a4b8..31bf39cab 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/code.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/code.go
@@ -59,7 +59,7 @@ const (
)
type IntCode struct {
- typ *runtime.Type
+ typ reflect.Type
bitSize uint8
isString bool
isPtr bool
@@ -89,7 +89,7 @@ func (c *IntCode) Filter(_ *FieldQuery) Code {
}
type UintCode struct {
- typ *runtime.Type
+ typ reflect.Type
bitSize uint8
isString bool
isPtr bool
@@ -119,7 +119,7 @@ func (c *UintCode) Filter(_ *FieldQuery) Code {
}
type FloatCode struct {
- typ *runtime.Type
+ typ reflect.Type
bitSize uint8
isPtr bool
}
@@ -155,7 +155,7 @@ func (c *FloatCode) Filter(_ *FieldQuery) Code {
}
type StringCode struct {
- typ *runtime.Type
+ typ reflect.Type
isPtr bool
}
@@ -164,7 +164,7 @@ func (c *StringCode) Kind() CodeKind {
}
func (c *StringCode) ToOpcode(ctx *compileContext) Opcodes {
- isJSONNumberType := c.typ == runtime.Type2RType(jsonNumberType)
+ isJSONNumberType := c.typ == jsonNumberType
var code *Opcode
if c.isPtr {
if isJSONNumberType {
@@ -188,7 +188,7 @@ func (c *StringCode) Filter(_ *FieldQuery) Code {
}
type BoolCode struct {
- typ *runtime.Type
+ typ reflect.Type
isPtr bool
}
@@ -213,7 +213,7 @@ func (c *BoolCode) Filter(_ *FieldQuery) Code {
}
type BytesCode struct {
- typ *runtime.Type
+ typ reflect.Type
isPtr bool
}
@@ -238,7 +238,7 @@ func (c *BytesCode) Filter(_ *FieldQuery) Code {
}
type SliceCode struct {
- typ *runtime.Type
+ typ reflect.Type
value Code
}
@@ -259,10 +259,11 @@ func (c *SliceCode) ToOpcode(ctx *compileContext) Opcodes {
ctx.decIndent()
codes.First().Flags |= IndirectFlags
+ // the opcodes after the elements refer to the slots of the header, and they don't take a slot.
elemCode := newSliceElemCode(ctx, c.typ.Elem(), header, size)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
end := newOpCode(ctx, c.typ, OpSliceEnd)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
header.End = end
header.Next = codes.First()
codes.Last().Next = elemCode
@@ -276,7 +277,7 @@ func (c *SliceCode) Filter(_ *FieldQuery) Code {
}
type ArrayCode struct {
- typ *runtime.Type
+ typ reflect.Type
value Code
}
@@ -301,11 +302,12 @@ func (c *ArrayCode) ToOpcode(ctx *compileContext) Opcodes {
codes.First().Flags |= IndirectFlags
+ // the opcodes after the elements refer to the slot of the header, and they don't take a slot.
elemCode := newArrayElemCode(ctx, elem, header, alen, size)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
end := newOpCode(ctx, c.typ, OpArrayEnd)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
header.End = end
header.Next = codes.First()
@@ -321,7 +323,7 @@ func (c *ArrayCode) Filter(_ *FieldQuery) Code {
}
type MapCode struct {
- typ *runtime.Type
+ typ reflect.Type
key Code
value Code
}
@@ -337,10 +339,45 @@ func (c *MapCode) ToOpcode(ctx *compileContext) Opcodes {
header := newMapHeaderCode(ctx, c.typ)
ctx.incIndex()
+ if c.isStringKey() {
+ // header => value => key => end: the key of an entry is written by the header for the first entry and
+ // by OpMapKey for the others, which give the value to its opcode.
+ // ^ |
+ // |_________|
+ header.Flags |= MapStringKeyFlags
+
+ ctx.incIndent()
+ valueCodes := c.value.ToOpcode(ctx)
+ ctx.decIndent()
+ valueCodes.First().Flags |= IndirectFlags
+ header.Map.ScalarValue = len(valueCodes) == 1 && isScalarOp(valueCodes.First().Op) &&
+ header.Map.ValueWords >= 0 && header.Map.ValueWords <= MapScalarValueWords
+
+ key := newMapKeyCode(ctx, c.typ.Key(), header)
+ key.Flags |= MapStringKeyFlags
+ ctx.incOpcodeIndex()
+
+ end := newMapEndCode(ctx, c.typ, header)
+ ctx.incOpcodeIndex()
+
+ header.Next = valueCodes.First()
+ valueCodes.Last().Next = key
+ key.Next = valueCodes.First()
+ header.End = end
+ key.End = end
+ return Opcodes{header}.Add(valueCodes...).Add(key).Add(end)
+ }
+
keyCodes := c.key.ToOpcode(ctx)
+ if first := keyCodes.First(); first.Op == OpMarshalText && first.Flags&IsNilableTypeFlags != 0 {
+ // the opcode of the key is given the address of the key, and the marshaler of a key of a pointer
+ // type is called with the pointer.
+ first.Flags |= IndirectFlags
+ }
+ // the opcodes other than the header refer to the slot of the header, and they don't take a slot.
value := newMapValueCode(ctx, c.typ.Elem(), header)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
ctx.incIndent()
valueCodes := c.value.ToOpcode(ctx)
@@ -349,10 +386,10 @@ func (c *MapCode) ToOpcode(ctx *compileContext) Opcodes {
valueCodes.First().Flags |= IndirectFlags
key := newMapKeyCode(ctx, c.typ.Key(), header)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
end := newMapEndCode(ctx, c.typ, header)
- ctx.incIndex()
+ ctx.incOpcodeIndex()
header.Next = keyCodes.First()
keyCodes.Last().Next = value
@@ -366,17 +403,29 @@ func (c *MapCode) ToOpcode(ctx *compileContext) Opcodes {
return Opcodes{header}.Add(keyCodes...).Add(value).Add(valueCodes...).Add(key).Add(end)
}
+// isStringKey is whether the key of the map is a plain string, which OpMapKey writes itself: not a pointer,
+// not json.Number, and not a type with a marshaler, whose code is not a StringCode.
+func (c *MapCode) isStringKey() bool {
+ key, ok := c.key.(*StringCode)
+ return ok && !key.isPtr && key.typ != jsonNumberType
+}
+
func (c *MapCode) Filter(_ *FieldQuery) Code {
return c
}
type StructCode struct {
- typ *runtime.Type
+ typ reflect.Type
fields []*StructFieldCode
isPtr bool
disableIndirectConversion bool
isIndirect bool
isRecursive bool
+ // isHiddenByItself is whether the struct is a recursive one embedded in itself, which has nothing to write.
+ isHiddenByItself bool
+ // fieldQuery is the query which the fields of a recursive struct are filtered by: the code which is jumped
+ // to is filtered by it when the recursive codes are linked.
+ fieldQuery *FieldQuery
}
func (c *StructCode) Kind() CodeKind {
@@ -400,11 +449,43 @@ func (c *StructCode) lastAnonymousFieldCode(firstField *Opcode) *Opcode {
for firstField.Op == OpStructHead || firstField.Op == OpStructField {
firstField = firstField.Next
}
- lastField := firstField
- for lastField.NextField != nil {
- lastField = lastField.NextField
+ return lastFieldOpcode(firstField)
+}
+
+// lastFieldOpcode returns the last field of the chain of the fields which starts from field.
+// If a field of the chain is an embedded struct, which is a head without a value followed by
+// the fields of the struct, the chain continues with those fields.
+func lastFieldOpcode(field *Opcode) *Opcode {
+ for field.NextField != nil {
+ field = field.NextField
+ for field.Flags&AnonymousHeadFlags != 0 && (field.Op == OpStructField || field.Op == OpStructHead) {
+ field = field.Next
+ }
}
- return lastField
+ return field
+}
+
+// fieldSlots makes the fields of a struct share the slots.
+//
+// The slot of the first field holds the address of the struct, which every field refers to. The slots after it
+// are for the value of a field, and they are used only while that field is encoded, so every field takes the
+// same ones: the length of a frame depends on how deep the values are nested, not on how many fields there are.
+type fieldSlots struct {
+ structIndex int
+ isFirst bool
+}
+
+func newFieldSlots(ctx *compileContext) *fieldSlots {
+ return &fieldSlots{structIndex: ctx.ptrIndex, isFirst: true}
+}
+
+// reuse is called before a field is compiled.
+func (s *fieldSlots) reuse(ctx *compileContext) {
+ if s.isFirst {
+ s.isFirst = false
+ return
+ }
+ ctx.ptrIndex = s.structIndex + 1
}
func (c *StructCode) ToOpcode(ctx *compileContext) Opcodes {
@@ -413,7 +494,8 @@ func (c *StructCode) ToOpcode(ctx *compileContext) Opcodes {
// |__________|
if c.isRecursive {
recursive := newRecursiveCode(ctx, c.typ, &CompiledCode{})
- recursive.Type = c.typ
+ recursive.Type = runtime.TypePtr(c.typ)
+ recursive.FieldQuery = c.fieldQuery
ctx.incIndex()
*ctx.recursiveCodes = append(*ctx.recursiveCodes, recursive)
return Opcodes{recursive}
@@ -421,9 +503,11 @@ func (c *StructCode) ToOpcode(ctx *compileContext) Opcodes {
codes := Opcodes{}
var prevField *Opcode
ctx.incIndent()
+ fieldSlots := newFieldSlots(ctx)
for idx, field := range c.fields {
isFirstField := idx == 0
isEndField := idx == len(c.fields)-1
+ fieldSlots.reuse(ctx)
fieldCodes := field.ToOpcode(ctx, isFirstField, isEndField)
for _, code := range fieldCodes {
if c.isIndirect {
@@ -455,7 +539,7 @@ func (c *StructCode) ToOpcode(ctx *compileContext) Opcodes {
head := &Opcode{
Op: OpStructHead,
Idx: opcodeOffset(ctx.ptrIndex),
- Type: c.typ,
+ Type: runtime.TypePtr(c.typ),
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
}
@@ -473,26 +557,63 @@ func (c *StructCode) ToOpcode(ctx *compileContext) Opcodes {
ctx.incIndex()
}
ctx.decIndent()
- ctx.structTypeToCodes[uintptr(unsafe.Pointer(c.typ))] = codes
+ markFieldRuns(codes)
+ ctx.structTypeToCodes[uintptr(runtime.TypePtr(c.typ))] = codes
return codes
}
+// fieldRunOps are, for the opcode of a field, the opcodes of a run of two and of three such fields in a row.
+var fieldRunOps = map[OpType][2]OpType{
+ OpStructFieldInt: {OpStructFieldInt2, OpStructFieldInt3},
+ OpStructFieldUint: {OpStructFieldUint2, OpStructFieldUint3},
+ OpStructFieldFloat64: {OpStructFieldFloat642, OpStructFieldFloat643},
+ OpStructFieldString: {OpStructFieldString2, OpStructFieldString3},
+ OpStructFieldBool: {OpStructFieldBool2, OpStructFieldBool3},
+}
+
+// maxFieldRun is the number of the fields of a run.
+const maxFieldRun = 3
+
+// markFieldRuns gives the first field of a run of fields of the same kind in a row the opcode of the run: the
+// VM encodes the fields after it without a dispatch. The fields keep their opcodes, which the VM falls
+// through; a run is never entered but at its first field, since only an omitted field is jumped over.
+func markFieldRuns(codes Opcodes) {
+ for i := 0; i < len(codes); {
+ runs, ok := fieldRunOps[codes[i].Op]
+ if !ok {
+ i++
+ continue
+ }
+ n := 1
+ for i+n < len(codes) && n < maxFieldRun && codes[i+n].Op == codes[i].Op && codes[i+n-1].Next == codes[i+n] {
+ n++
+ }
+ if n > 1 {
+ codes[i].Op = runs[n-2]
+ }
+ i += n
+ }
+}
+
func (c *StructCode) ToAnonymousOpcode(ctx *compileContext) Opcodes {
// header => code => structField => code => end
// ^ |
// |__________|
if c.isRecursive {
- recursive := newRecursiveCode(ctx, c.typ, &CompiledCode{})
- recursive.Type = c.typ
+ recursive := newRecursiveCode(ctx, c.typ, &CompiledCode{Embedded: true})
+ recursive.Type = runtime.TypePtr(c.typ)
+ recursive.FieldQuery = c.fieldQuery
ctx.incIndex()
*ctx.recursiveCodes = append(*ctx.recursiveCodes, recursive)
return Opcodes{recursive}
}
codes := Opcodes{}
var prevField *Opcode
+ fieldSlots := newFieldSlots(ctx)
for idx, field := range c.fields {
isFirstField := idx == 0
isEndField := idx == len(c.fields)-1
+ fieldSlots.reuse(ctx)
fieldCodes := field.ToAnonymousOpcode(ctx, isFirstField, isEndField)
for _, code := range fieldCodes {
if c.isIndirect {
@@ -515,10 +636,13 @@ func (c *StructCode) ToAnonymousOpcode(ctx *compileContext) Opcodes {
firstField.End = lastField
}
}
- prevField = firstField
+ // the next field is linked from the last field of this one:
+ // if this field is an embedded struct, it is the last field of that struct, as ToOpcode does.
+ prevField = c.lastFieldCode(field, firstField)
codes = codes.Add(fieldCodes...)
}
- ctx.structTypeToCodes[uintptr(unsafe.Pointer(c.typ))] = codes
+ // The opcodes of an embedded struct are only the fields: they have neither the braces nor the check
+ // of nil. So they are not registered to structTypeToCodes, which is where a recursive code jumps to.
return codes
}
@@ -559,6 +683,12 @@ func (c *StructCode) enableIndirect() {
}
func (c *StructCode) Filter(query *FieldQuery) Code {
+ if c.isRecursive {
+ // the code of a recursive struct is a jump: the code which is jumped to is filtered when it is linked.
+ filtered := *c
+ filtered.fieldQuery = query
+ return &filtered
+ }
fieldMap := map[string]*FieldQuery{}
for _, field := range query.Fields {
fieldMap[field.Name] = field
@@ -598,7 +728,7 @@ func (c *StructCode) Filter(query *FieldQuery) Code {
}
type StructFieldCode struct {
- typ *runtime.Type
+ typ reflect.Type
key string
tag *runtime.StructTag
value Code
@@ -612,6 +742,37 @@ type StructFieldCode struct {
isMarshalerContext bool
}
+// runKind returns the kind of the field if it is one which has the opcodes of a run ( fieldRunOps ): a field of
+// int, uint, float64, string or bool, not a pointer, without omitempty or the string option, and not embedded.
+func (c *StructFieldCode) runKind() (CodeKind, bool) {
+ if c.isAnonymous || c.tag.IsOmitEmpty || c.tag.IsOmitZero || c.tag.IsString {
+ return 0, false
+ }
+ switch value := c.value.(type) {
+ case *IntCode:
+ return CodeKindInt, !value.isPtr && !value.isString
+ case *UintCode:
+ return CodeKindUint, !value.isPtr && !value.isString
+ case *FloatCode:
+ return CodeKindFloat, !value.isPtr && value.bitSize == 64
+ case *StringCode:
+ return CodeKindString, !value.isPtr && value.typ != jsonNumberType
+ case *BoolCode:
+ return CodeKindBool, !value.isPtr
+ }
+ return 0, false
+}
+
+// isRecursiveValueOf is whether the field is a value of typ, the struct it is a field of, or a pointer to one:
+// what markTailRecursion encodes without a frame when the field is the last.
+func (c *StructFieldCode) isRecursiveValueOf(typ reflect.Type) bool {
+ if c.isAnonymous {
+ return false
+ }
+ structCode := c.getStruct()
+ return structCode != nil && structCode.isRecursive && structCode.typ == typ
+}
+
func (c *StructFieldCode) getStruct() *StructCode {
value := c.value
ptr, ok := value.(*PtrCode)
@@ -632,14 +793,6 @@ func (c *StructFieldCode) getAnonymousStruct() *StructCode {
return c.getStruct()
}
-func optimizeStructHeader(code *Opcode, tag *runtime.StructTag) OpType {
- headType := code.ToHeaderType(tag.IsString)
- if tag.IsOmitEmpty {
- headType = headType.HeadToOmitEmptyHead()
- }
- return headType
-}
-
func optimizeStructField(code *Opcode, tag *runtime.StructTag) OpType {
fieldType := code.ToFieldType(tag.IsString)
if tag.IsOmitEmpty {
@@ -648,36 +801,87 @@ func optimizeStructField(code *Opcode, tag *runtime.StructTag) OpType {
return fieldType
}
-func (c *StructFieldCode) headerOpcodes(ctx *compileContext, field *Opcode, valueCodes Opcodes) Opcodes {
- value := valueCodes.First()
- op := optimizeStructHeader(value, c.tag)
- field.Op = op
- if value.Flags&MarshalerContextFlags != 0 {
- field.Flags |= MarshalerContextFlags
- }
- field.NumBitSize = value.NumBitSize
- field.PtrNum = value.PtrNum
- field.FieldQuery = value.FieldQuery
- fieldCodes := Opcodes{field}
- if op.IsMultipleOpHead() {
- field.Next = value
- fieldCodes = fieldCodes.Add(valueCodes...)
- } else {
- ctx.decIndex()
+// headOpcode returns the opcode of the head of the struct, which precedes the opcode of the first field.
+// It is made before the first field, so that it has the index before the ones of the field.
+//
+// The head is not fused with the first field: that made an opcode per type of a field for the head, which was
+// more than half of the VM, for a dispatch saved per struct. The head writes the brace, and the first field
+// is encoded by the same opcode as the other fields.
+func (c *StructFieldCode) headOpcode(ctx *compileContext, flags OpFlags) *Opcode {
+ head := &Opcode{
+ Op: OpStructHead,
+ Idx: opcodeOffset(ctx.ptrIndex),
+ Flags: flags & AnonymousHeadFlags,
+ Type: runtime.TypePtr(c.typ),
+ DisplayIdx: ctx.opcodeIndex,
+ Indent: ctx.indent,
}
- return fieldCodes
+ ctx.incOpcodeIndex()
+ return head
+}
+
+// withHead links the head to the opcodes of the first field.
+func withHead(head *Opcode, codes Opcodes) Opcodes {
+ head.Next = codes.First()
+ head.NextField = codes.First()
+ return append(Opcodes{head}, codes...)
+}
+
+// isLongKey is whether the key of the field is longer than a chunk: then the field is not encoded by one opcode
+// with its value, but by the generic field opcode, which writes a key of any length, and the opcode of the value.
+func (c *StructFieldCode) isLongKey(field *Opcode) bool {
+ return len(field.Key) > KeyChunkSize
+}
+
+// isGenericField is whether the field is encoded by the generic field opcode and the opcode of the value: a
+// field of a long key, or of omitzero, whose check the generic opcode makes for a value of any type.
+func (c *StructFieldCode) isGenericField(field *Opcode) bool {
+ return c.isLongKey(field) || c.tag.IsOmitZero
}
func (c *StructFieldCode) fieldOpcodes(ctx *compileContext, field *Opcode, valueCodes Opcodes) Opcodes {
value := valueCodes.First()
- op := optimizeStructField(value, c.tag)
+ var op OpType
+ if c.isGenericField(field) {
+ op = OpStructField
+ if c.tag.IsOmitEmpty || c.tag.IsOmitZero {
+ op = OpStructFieldOmitEmpty
+ }
+ if c.tag.IsString {
+ value.Op = value.Op.ToStringOp()
+ }
+ // the generic field opcode gives the opcode of the value the address of the field, while the opcode of
+ // a map takes the map: the map is followed from the address, as the value of a map or of a list is.
+ switch value.Op {
+ case OpMap:
+ value.Op = OpMapPtr
+ value.PtrNum = 1
+ case OpMapPtr:
+ value.PtrNum++
+ }
+ } else {
+ op = optimizeStructField(value, c.tag)
+ }
field.Op = op
+ if op == OpStructFieldOmitEmpty {
+ if c.tag.IsOmitEmpty {
+ field.EmptyKind = emptyKindOf(c.typ)
+ }
+ if c.tag.IsOmitZero {
+ field.ZeroKind = zeroKindOf(c.typ)
+ }
+ }
if value.Flags&MarshalerContextFlags != 0 {
field.Flags |= MarshalerContextFlags
}
+ // the field of interface{} enters the value as the opcode of the value does: it needs to know the interface.
+ if value.Flags&NonEmptyInterfaceFlags != 0 {
+ field.Flags |= NonEmptyInterfaceFlags
+ }
field.NumBitSize = value.NumBitSize
field.PtrNum = value.PtrNum
field.FieldQuery = value.FieldQuery
+ field.Marshaler = value.Marshaler
fieldCodes := Opcodes{field}
if op.IsMultipleOpField() {
@@ -701,22 +905,110 @@ func (c *StructFieldCode) addStructEndCode(ctx *compileContext, codes Opcodes) O
for code.Op == OpStructField || code.Op == OpStructHead {
code = code.Next
}
- for code.NextField != nil {
- code = code.NextField
- }
- code.NextField = end
+ lastFieldOpcode(code).NextField = end
codes = codes.Add(end)
ctx.incOpcodeIndex()
return codes
}
+// KeyChunkSize is the size of the chunk which the VM copies a key by: a key up to it is written by the
+// opcode of its field, as a chunk. A longer key is written by the generic field opcode, and its value by the
+// opcode of the value.
+const KeyChunkSize = 32
+
+// PaddedKey returns the key whose memory has the bytes after it up to a chunk,
+// so that a chunk is copied from the key without reading the memory of others.
+func PaddedKey(key string) string {
+ buf := make([]byte, len(key)+KeyChunkSize)
+ copy(buf, key)
+ return unsafe.String(unsafe.SliceData(buf), len(key))
+}
+
+// keyChunk returns the chunk at the start of a padded key.
+func keyChunk(paddedKey string) *[KeyChunkSize]byte {
+ return (*[KeyChunkSize]byte)(unsafe.Pointer(unsafe.StringData(paddedKey)))
+}
+
+// EmptyKind is what makes the value of a field empty for omitempty, as encoding/json decides it by the kind
+// of the type of the field: false, 0, a nil pointer or interface value, or an empty array, slice, map or string.
+type EmptyKind uint8
+
+const (
+ EmptyNever EmptyKind = iota
+ EmptyNil // a nil pointer or interface value: the first word is zero
+ EmptyBool
+ EmptyInt // an integer of NumBitSize bits which is 0
+ EmptyFloat32
+ EmptyFloat64
+ EmptyLen // a string or a slice whose length is zero
+ EmptyMapLen // a map whose length is zero
+ EmptyAlways // an array of no element
+)
+
+// emptyKindOf returns what makes a value of the type empty.
+func emptyKindOf(typ reflect.Type) EmptyKind {
+ switch typ.Kind() {
+ case reflect.Ptr, reflect.Interface:
+ return EmptyNil
+ case reflect.Bool:
+ return EmptyBool
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr:
+ return EmptyInt
+ case reflect.Float32:
+ return EmptyFloat32
+ case reflect.Float64:
+ return EmptyFloat64
+ case reflect.String, reflect.Slice:
+ return EmptyLen
+ case reflect.Map:
+ return EmptyMapLen
+ case reflect.Array:
+ if typ.Len() == 0 {
+ return EmptyAlways
+ }
+ }
+ return EmptyNever
+}
+
+// IsEmptyField is whether the value at p, of a field whose kind of emptiness is kind, is empty for omitempty.
+func IsEmptyField(kind EmptyKind, bitSize uint8, p unsafe.Pointer) bool {
+ switch kind {
+ case EmptyNil:
+ return *(*unsafe.Pointer)(p) == nil
+ case EmptyBool:
+ return !*(*bool)(p)
+ case EmptyInt:
+ switch bitSize {
+ case 8:
+ return *(*uint8)(p) == 0
+ case 16:
+ return *(*uint16)(p) == 0
+ case 32:
+ return *(*uint32)(p) == 0
+ }
+ return *(*uint64)(p) == 0
+ case EmptyFloat32:
+ return *(*float32)(p) == 0
+ case EmptyFloat64:
+ return *(*float64)(p) == 0
+ case EmptyLen:
+ return (*runtime.SliceHeader)(p).Len == 0
+ case EmptyMapLen:
+ return MapLen(*(*unsafe.Pointer)(p)) == 0
+ case EmptyAlways:
+ return true
+ }
+ return false
+}
+
func (c *StructFieldCode) structKey(ctx *compileContext) string {
if ctx.escapeKey {
rctx := &RuntimeContext{Option: &Option{Flag: HTMLEscapeOption}}
- return fmt.Sprintf(`%s:`, string(AppendString(rctx, []byte{}, c.key)))
+ return PaddedKey(fmt.Sprintf(`%s:`, string(AppendString(rctx, []byte{}, c.key))))
}
- return fmt.Sprintf(`"%s":`, c.key)
+ return PaddedKey(fmt.Sprintf(`"%s":`, c.key))
}
func (c *StructFieldCode) flags() OpFlags {
@@ -756,53 +1048,60 @@ func (c *StructFieldCode) toValueOpcodes(ctx *compileContext) Opcodes {
}
func (c *StructFieldCode) ToOpcode(ctx *compileContext, isFirstField, isEndField bool) Opcodes {
+ var head *Opcode
+ if isFirstField {
+ head = c.headOpcode(ctx, c.flags())
+ }
+ key := c.structKey(ctx)
field := &Opcode{
Idx: opcodeOffset(ctx.ptrIndex),
Flags: c.flags(),
- Key: c.structKey(ctx),
+ Key: key,
+ KeyChunk: keyChunk(key),
Offset: uint32(c.offset),
- Type: c.typ,
+ Type: runtime.TypePtr(c.typ),
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
- DisplayKey: c.key,
}
ctx.incIndex()
valueCodes := c.toValueOpcodes(ctx)
- if isFirstField {
- codes := c.headerOpcodes(ctx, field, valueCodes)
- if isEndField {
- codes = c.addStructEndCode(ctx, codes)
- }
- return codes
- }
codes := c.fieldOpcodes(ctx, field, valueCodes)
if isEndField {
- if isEnableStructEndOptimization(c.value) {
+ if isEnableStructEndOptimization(c.value) && !c.isGenericField(field) {
field.Op = field.Op.FieldToEnd()
} else {
codes = c.addStructEndCode(ctx, codes)
}
}
+ if head != nil {
+ codes = withHead(head, codes)
+ }
return codes
}
func (c *StructFieldCode) ToAnonymousOpcode(ctx *compileContext, isFirstField, isEndField bool) Opcodes {
+ var head *Opcode
+ if isFirstField {
+ head = c.headOpcode(ctx, c.flags()|AnonymousHeadFlags)
+ }
+ key := c.structKey(ctx)
field := &Opcode{
Idx: opcodeOffset(ctx.ptrIndex),
Flags: c.flags() | AnonymousHeadFlags,
- Key: c.structKey(ctx),
+ Key: key,
+ KeyChunk: keyChunk(key),
Offset: uint32(c.offset),
- Type: c.typ,
+ Type: runtime.TypePtr(c.typ),
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
- DisplayKey: c.key,
}
ctx.incIndex()
valueCodes := c.toValueOpcodes(ctx)
- if isFirstField {
- return c.headerOpcodes(ctx, field, valueCodes)
+ codes := c.fieldOpcodes(ctx, field, valueCodes)
+ if head != nil {
+ codes = withHead(head, codes)
}
- return c.fieldOpcodes(ctx, field, valueCodes)
+ return codes
}
func isEnableStructEndOptimization(value Code) bool {
@@ -822,7 +1121,7 @@ func isEnableStructEndOptimization(value Code) bool {
}
type InterfaceCode struct {
- typ *runtime.Type
+ typ reflect.Type
fieldQuery *FieldQuery
isPtr bool
}
@@ -856,7 +1155,7 @@ func (c *InterfaceCode) Filter(query *FieldQuery) Code {
}
type MarshalJSONCode struct {
- typ *runtime.Type
+ typ reflect.Type
fieldQuery *FieldQuery
isAddrForMarshaler bool
isNilableType bool
@@ -870,6 +1169,7 @@ func (c *MarshalJSONCode) Kind() CodeKind {
func (c *MarshalJSONCode) ToOpcode(ctx *compileContext) Opcodes {
code := newOpCode(ctx, c.typ, OpMarshalJSON)
code.FieldQuery = c.fieldQuery
+ code.Marshaler = c.marshalerCall()
if c.isAddrForMarshaler {
code.Flags |= AddrForMarshalerFlags
}
@@ -885,6 +1185,23 @@ func (c *MarshalJSONCode) ToOpcode(ctx *compileContext) Opcodes {
return Opcodes{code}
}
+// marshalerCall returns the direct call of the method, or nil if the method is called through the interface:
+// a value of the size of a pointer whose method is on the pointer is copied first, see addrForMarshaler.
+func (c *MarshalJSONCode) marshalerCall() *MarshalerCall {
+ recv := c.typ
+ if c.isAddrForMarshaler {
+ if c.typ.Size() == unsafe.Sizeof(unsafe.Pointer(nil)) {
+ return nil
+ }
+ recv = reflect.PointerTo(c.typ)
+ }
+ iface := marshalJSONInterface
+ if c.isMarshalerContext {
+ iface = marshalJSONContextInterface
+ }
+ return newMarshalerCall(recv, iface)
+}
+
func (c *MarshalJSONCode) Filter(query *FieldQuery) Code {
return &MarshalJSONCode{
typ: c.typ,
@@ -896,10 +1213,15 @@ func (c *MarshalJSONCode) Filter(query *FieldQuery) Code {
}
type MarshalTextCode struct {
- typ *runtime.Type
+ typ reflect.Type
fieldQuery *FieldQuery
isAddrForMarshaler bool
isNilableType bool
+ // isInterfaceMapKey is whether the code is the one of the key of a map of an interface type, whose name is
+ // of the dynamic value of the key ( see appendInterfaceMapKey ).
+ isInterfaceMapKey bool
+ // isMapKey is whether the code is the one of the key of a map, whose name is "" for a nil pointer.
+ isMapKey bool
}
func (c *MarshalTextCode) Kind() CodeKind {
@@ -909,9 +1231,20 @@ func (c *MarshalTextCode) Kind() CodeKind {
func (c *MarshalTextCode) ToOpcode(ctx *compileContext) Opcodes {
code := newOpCode(ctx, c.typ, OpMarshalText)
code.FieldQuery = c.fieldQuery
+ if c.isInterfaceMapKey {
+ // the opcode is given the address of the key, whose name AppendMarshalText makes without a marshaler.
+ code.Flags |= InterfaceMapKeyFlags
+ code.Flags &= ^IsNilableTypeFlags
+ ctx.incIndex()
+ return Opcodes{code}
+ }
+ code.Marshaler = c.marshalerCall()
if c.isAddrForMarshaler {
code.Flags |= AddrForMarshalerFlags
}
+ if c.isMapKey {
+ code.Flags |= MapKeyFlags
+ }
if c.isNilableType {
code.Flags |= IsNilableTypeFlags
} else {
@@ -921,17 +1254,32 @@ func (c *MarshalTextCode) ToOpcode(ctx *compileContext) Opcodes {
return Opcodes{code}
}
+// marshalerCall returns the direct call of the method, or nil if the method is called through the interface:
+// see MarshalJSONCode.marshalerCall.
+func (c *MarshalTextCode) marshalerCall() *MarshalerCall {
+ recv := c.typ
+ if c.isAddrForMarshaler {
+ if c.typ.Size() == unsafe.Sizeof(unsafe.Pointer(nil)) {
+ return nil
+ }
+ recv = reflect.PointerTo(c.typ)
+ }
+ return newMarshalerCall(recv, marshalTextInterface)
+}
+
func (c *MarshalTextCode) Filter(query *FieldQuery) Code {
return &MarshalTextCode{
typ: c.typ,
fieldQuery: query,
isAddrForMarshaler: c.isAddrForMarshaler,
isNilableType: c.isNilableType,
+ isInterfaceMapKey: c.isInterfaceMapKey,
+ isMapKey: c.isMapKey,
}
}
type PtrCode struct {
- typ *runtime.Type
+ typ reflect.Type
value Code
ptrNum uint8
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/compact.go b/vendor/github.com/goccy/go-json/internal/encoder/compact.go
index e287a6c03..4c42ea291 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/compact.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/compact.go
@@ -2,6 +2,7 @@ package encoder
import (
"bytes"
+ stderrors "errors"
"fmt"
"strconv"
"unsafe"
@@ -242,7 +243,9 @@ func compactNumber(dst, src []byte, cursor int64) ([]byte, int64, error) {
break
}
num := src[start:cursor]
- if _, err := strconv.ParseFloat(*(*string)(unsafe.Pointer(&num)), 64); err != nil {
+ // ParseFloat is used only to validate the syntax. A number out of the range of float64 is valid JSON,
+ // and it is written as it is, as encoding/json does.
+ if _, err := strconv.ParseFloat(*(*string)(unsafe.Pointer(&num)), 64); err != nil && !stderrors.Is(err, strconv.ErrRange) {
return nil, 0, err
}
dst = append(dst, num...)
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/compact_fast.go b/vendor/github.com/goccy/go-json/internal/encoder/compact_fast.go
new file mode 100644
index 000000000..3be7d7aa9
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/compact_fast.go
@@ -0,0 +1,415 @@
+package encoder
+
+import (
+ "bytes"
+ "encoding/binary"
+ "math/bits"
+ "unsafe"
+)
+
+// The output of a marshaler is compacted and validated, as encoding/json does. Most of the outputs are compact
+// already, so they are copied as they are after being checked: a scan by SIMD finds the bytes which would have
+// to be rewritten or looked at, and a walk of the structure without a write validates the rest, the escapes of
+// the strings included. The characters which compact escapes for HTML are escaped as the output is copied.
+// Anything else is left to compact, which rewrites and reports the errors.
+
+// byteClass is a set of bytes, as a table of the bytes and as the tables of the scan by SIMD.
+type byteClass struct {
+ table [256]bool
+ tables nibbleTables
+}
+
+func newByteClass(bytes ...byte) *byteClass {
+ c := &byteClass{}
+ for _, b := range bytes {
+ c.table[b] = true
+ }
+ for b := 0; b < 0x20; b++ {
+ c.table[b] = true
+ }
+ c.tables = newNibbleTables(&c.table)
+ return c
+}
+
+// has is whether a byte of src is in the class.
+func (c *byteClass) has(src []byte) bool {
+ n := len(src)
+ if n == 0 {
+ return false
+ }
+ p := unsafe.Pointer(unsafe.SliceData(src))
+ if found, ok := scanBytesSIMD(p, n, &c.tables); ok {
+ return found
+ }
+ for _, b := range src {
+ if c.table[b] {
+ return true
+ }
+ }
+ return false
+}
+
+// controlChars are the control characters, which compact removes as white space or reports as errors: an output
+// with one is left to compact. lookedAtByCompact are those and the bytes which the check must look at: an
+// escape, whose sequence is validated, and, if HTML is escaped, the characters which compact escapes then:
+// '<', '>', '&' and the first byte of U+2028 and U+2029, which starts other characters as well. Most of the
+// outputs have none of them: their strings are walked to the next quote at once and they are copied as they are.
+var (
+ controlChars = newByteClass()
+ lookedAtByCompact = [2]*byteClass{
+ newByteClass('\\'),
+ newByteClass('\\', '<', '>', '&', 0xe2),
+ }
+)
+
+// The walks of the strings of an output, as the type argument of isCompactJSON: each walk is compiled into a
+// function of its own, so that the walk of the plain strings, which most of the outputs have, has neither a
+// branch nor a call for the escapes in its loop. The types differ by their sizes, which the compiler knows for
+// each of them: the branch on the size is resolved when the function of a walk is compiled.
+type (
+ // plainStrings have no escape: a string ends at the next quote.
+ plainStrings struct{}
+ // escapedStrings may have escapes, which are validated.
+ escapedStrings struct{ _ byte }
+)
+
+// maxDepthOfCompactCheck is the nesting up to which the output is checked here: a deeper one is compacted.
+const maxDepthOfCompactCheck = 64
+
+// appendCompactOutput appends src, the output of a marshaler, to dst as compact appends it, if src is compact
+// and valid JSON, and returns false without appending if it may not be: then src is to be compacted. The output
+// of a trusted marshaler, valid and compact, is appended as it is if compact leaves it so.
+func appendCompactOutput(dst, src []byte, escape, trusted bool) ([]byte, bool) {
+ if len(src) == 0 {
+ return dst, false
+ }
+ option := 0
+ if escape {
+ option = 1
+ }
+ if !lookedAtByCompact[option].has(src) {
+ if !trusted && !isCompactJSON[plainStrings](src) {
+ return dst, false
+ }
+ return append(dst, src...), true
+ }
+ if controlChars.has(src) || !isCompactJSON[escapedStrings](src) {
+ return dst, false
+ }
+ if escape {
+ return appendHTMLEscaped(dst, src), true
+ }
+ return append(dst, src...), true
+}
+
+// htmlOfCompact are the bytes which compact escapes for HTML in valid JSON, '<', '>' and '&', and the first byte
+// of U+2028 and U+2029, as a table and as the tables of the loop of the escapes by SIMD, which stops at that byte
+// since it has no sequence ( see escapeSequences ).
+var (
+ htmlOfCompact = [256]bool{'<': true, '>': true, '&': true, 0xe2: true}
+ htmlOfCompactTables = newNibbleTables(&htmlOfCompact)
+)
+
+// appendHTMLEscaped appends src, valid JSON, to dst with the characters which compact escapes for HTML escaped as
+// it escapes them.
+func appendHTMLEscaped(dst, src []byte) []byte {
+ s := unsafe.String(unsafe.SliceData(src), len(src))
+ n := len(s)
+ i, j := 0, 0
+ // limit is where the loop of the bytes gives the rest back to the loop by SIMD, which stops at the first byte
+ // of U+2028 and U+2029, as appendNormalizedString does.
+ limit := n
+ if n >= 32 && hasEscapeLoop {
+ dst, j = appendEscapedSIMD(dst, s, &htmlOfCompactTables, false)
+ i = j
+ limit = min(n, j+32)
+ }
+ for {
+ for j < limit {
+ c := s[j]
+ if !htmlOfCompact[c] {
+ j++
+ continue
+ }
+ if c == 0xe2 {
+ // U+2028 and U+2029 are E2 80 A8 and E2 80 A9.
+ if j+2 < n && s[j+1] == 0x80 && s[j+2]&^1 == 0xa8 {
+ dst = append(dst, s[i:j]...)
+ dst = append(dst, `\u202`...)
+ dst = append(dst, hex[s[j+2]&0xf])
+ j += 3
+ i = j
+ continue
+ }
+ j++
+ continue
+ }
+ dst = append(dst, s[i:j]...)
+ seq := escapeSequences[c]
+ l := len(dst)
+ dst = binary.LittleEndian.AppendUint64(dst, seq)[:l+int(seq>>56)]
+ j++
+ i = j
+ }
+ if j >= n {
+ break
+ }
+ dst = append(dst, s[i:j]...)
+ var consumed int
+ dst, consumed = appendEscapedSIMD(dst, s[j:], &htmlOfCompactTables, false)
+ j += consumed
+ i = j
+ limit = min(n, j+32)
+ }
+ return append(dst, s[i:]...)
+}
+
+// isCompactJSON is whether src, which has no control character, is valid JSON without a byte to remove, whose
+// strings are walked as S tells.
+func isCompactJSON[S plainStrings | escapedStrings](src []byte) bool {
+ var walk S
+ plain := unsafe.Sizeof(walk) == unsafe.Sizeof(plainStrings{})
+ var stack [maxDepthOfCompactCheck]byte // the closing brackets of the values being read
+ depth := 0
+ n := len(src)
+ i := 0
+ for {
+ // a value.
+ if i >= n {
+ return false
+ }
+ switch c := src[i]; {
+ case c == '"':
+ if plain {
+ i = quoteEnd(src, i+1)
+ } else {
+ i = escapedQuoteEnd(src, i+1)
+ }
+ if i < 0 {
+ return false
+ }
+ case c == '{':
+ if depth == maxDepthOfCompactCheck {
+ return false
+ }
+ stack[depth] = '}'
+ depth++
+ i++
+ if i < n && src[i] == '}' {
+ i++
+ depth--
+ break
+ }
+ // a key.
+ if i >= n || src[i] != '"' {
+ return false
+ }
+ if plain {
+ i = quoteEnd(src, i+1)
+ } else {
+ i = escapedQuoteEnd(src, i+1)
+ }
+ if i < 0 {
+ return false
+ }
+ if i >= n || src[i] != ':' {
+ return false
+ }
+ i++
+ continue
+ case c == '[':
+ if depth == maxDepthOfCompactCheck {
+ return false
+ }
+ stack[depth] = ']'
+ depth++
+ i++
+ if i < n && src[i] == ']' {
+ i++
+ depth--
+ break
+ }
+ continue
+ case c == 't':
+ if !bytes.HasPrefix(src[i:], []byte("true")) {
+ return false
+ }
+ i += 4
+ case c == 'f':
+ if !bytes.HasPrefix(src[i:], []byte("false")) {
+ return false
+ }
+ i += 5
+ case c == 'n':
+ if !bytes.HasPrefix(src[i:], []byte("null")) {
+ return false
+ }
+ i += 4
+ case c == '-' || ('0' <= c && c <= '9'):
+ j := numberEnd(src, i)
+ if j < 0 {
+ return false
+ }
+ i = j
+ default:
+ return false
+ }
+ // after a value.
+ for {
+ if depth == 0 {
+ return i == n
+ }
+ if i >= n {
+ return false
+ }
+ switch src[i] {
+ case ',':
+ i++
+ if stack[depth-1] == '}' {
+ // a key.
+ if i >= n || src[i] != '"' {
+ return false
+ }
+ if plain {
+ i = quoteEnd(src, i+1)
+ } else {
+ i = escapedQuoteEnd(src, i+1)
+ }
+ if i < 0 {
+ return false
+ }
+ if i >= n || src[i] != ':' {
+ return false
+ }
+ i++
+ }
+ case stack[depth-1]:
+ depth--
+ i++
+ continue
+ default:
+ return false
+ }
+ break
+ }
+ }
+}
+
+// quoteEnd returns the index after the quote which ends the string whose content starts at i, or -1.
+// The string has no escape, so the quote is the next one. Most of the strings are short, so the quote is
+// looked for by words here, not by a call. The words are read as little-endian ones, so that the lowest byte
+// found by bits.TrailingZeros64 is the first one in memory on a big-endian machine too; on a little-endian one
+// the read is a load as it is.
+func quoteEnd(src []byte, i int) int {
+ n := len(src)
+ p := unsafe.Pointer(unsafe.SliceData(src))
+ for ; i+8 <= n; i += 8 {
+ w := binary.LittleEndian.Uint64((*[8]byte)(unsafe.Add(p, i))[:]) ^ (lsb * '"')
+ if mask := (w - lsb) &^ w & msb; mask != 0 {
+ return i + bits.TrailingZeros64(mask)/8 + 1
+ }
+ }
+ for ; i < n; i++ {
+ if src[i] == '"' {
+ return i + 1
+ }
+ }
+ return -1
+}
+
+// escapedQuoteEnd is quoteEnd for a string which may have escapes, which are validated.
+func escapedQuoteEnd(src []byte, i int) int {
+ n := len(src)
+ p := unsafe.Pointer(unsafe.SliceData(src))
+ for {
+ for ; i+8 <= n; i += 8 {
+ w := binary.LittleEndian.Uint64((*[8]byte)(unsafe.Add(p, i))[:])
+ q := w ^ (lsb * '"')
+ b := w ^ (lsb * '\\')
+ // the lowest bit of the mask of each byte is exact, so the lowest one of both is.
+ if mask := ((q-lsb)&^q | (b-lsb)&^b) & msb; mask != 0 {
+ i += bits.TrailingZeros64(mask) / 8
+ break
+ }
+ }
+ for ; i < n && src[i] != '"' && src[i] != '\\'; i++ {
+ }
+ if i >= n {
+ return -1
+ }
+ if src[i] == '"' {
+ return i + 1
+ }
+ i = escapeEnd(src, i+1)
+ if i < 0 {
+ return -1
+ }
+ }
+}
+
+// escapeEnd returns the index after the escape of a string whose backslash is before i, or -1 if it is not an
+// escape of JSON.
+func escapeEnd(src []byte, i int) int {
+ if i >= len(src) {
+ return -1
+ }
+ switch src[i] {
+ case '"', '\\', '/', 'b', 'f', 'n', 'r', 't':
+ return i + 1
+ case 'u':
+ if i+5 > len(src) {
+ return -1
+ }
+ for _, c := range src[i+1 : i+5] {
+ if !('0' <= c && c <= '9' || 'a' <= c && c <= 'f' || 'A' <= c && c <= 'F') {
+ return -1
+ }
+ }
+ return i + 5
+ }
+ return -1
+}
+
+// numberEnd returns the index after the number which starts at i, or -1 if it is not a number of JSON.
+func numberEnd(src []byte, i int) int {
+ n := len(src)
+ if src[i] == '-' {
+ i++
+ if i >= n {
+ return -1
+ }
+ }
+ switch {
+ case src[i] == '0':
+ i++
+ case '1' <= src[i] && src[i] <= '9':
+ i++
+ for i < n && '0' <= src[i] && src[i] <= '9' {
+ i++
+ }
+ default:
+ return -1
+ }
+ if i < n && src[i] == '.' {
+ i++
+ if i >= n || src[i] < '0' || src[i] > '9' {
+ return -1
+ }
+ for i < n && '0' <= src[i] && src[i] <= '9' {
+ i++
+ }
+ }
+ if i < n && (src[i] == 'e' || src[i] == 'E') {
+ i++
+ if i < n && (src[i] == '+' || src[i] == '-') {
+ i++
+ }
+ if i >= n || src[i] < '0' || src[i] > '9' {
+ return -1
+ }
+ for i < n && '0' <= src[i] && src[i] <= '9' {
+ i++
+ }
+ }
+ return i
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/compiler.go b/vendor/github.com/goccy/go-json/internal/encoder/compiler.go
index b10763689..0205e4e24 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/compiler.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/compiler.go
@@ -5,68 +5,97 @@ import (
"encoding"
"encoding/json"
"reflect"
- "sync"
- "sync/atomic"
+ "slices"
+ "sort"
"unsafe"
"github.com/goccy/go-json/internal/errors"
"github.com/goccy/go-json/internal/runtime"
)
-type marshalerContext interface {
- MarshalJSON(context.Context) ([]byte, error)
-}
-
-var (
- marshalJSONType = reflect.TypeOf((*json.Marshaler)(nil)).Elem()
- marshalJSONContextType = reflect.TypeOf((*marshalerContext)(nil)).Elem()
- marshalTextType = reflect.TypeOf((*encoding.TextMarshaler)(nil)).Elem()
- jsonNumberType = reflect.TypeOf(json.Number(""))
- cachedOpcodeSets []*OpcodeSet
- cachedOpcodeMap unsafe.Pointer // map[uintptr]*OpcodeSet
- typeAddr *runtime.TypeAddr
- initEncoderOnce sync.Once
-)
-
-func initEncoder() {
- initEncoderOnce.Do(func() {
- typeAddr = runtime.AnalyzeTypeAddr()
- if typeAddr == nil {
- typeAddr = &runtime.TypeAddr{}
+// CompileToGetCodeSet returns the opcodes of the type, compiling them if the type is new.
+func CompileToGetCodeSet(ctx *RuntimeContext, typeptr uintptr) (*OpcodeSet, error) {
+ if codeSet := ctx.RecentCodeSet(typeptr); codeSet != nil {
+ return codeSet, nil
+ }
+ key := ctx.codeSetKey(typeptr)
+ set := &ctx.recentCodeSets[recentCodeSetIndex(key)]
+ for i := range set {
+ if set[i].typeptr == key {
+ return getFilteredCodeSetIfNeeded(ctx, set[i].codeSet)
+ }
+ }
+ codeSet, err := compileToGetUnfilteredCodeSet(typeptr, ctx.Option.Flag&OptimizeFieldOrderOption != 0)
+ if err != nil {
+ return nil, err
+ }
+ // the type takes the first entry of its set, and the one encoded before it is kept in the second.
+ copy(set[1:], set[:])
+ set[0] = recentCodeSet{typeptr: key, codeSet: codeSet}
+ return getFilteredCodeSetIfNeeded(ctx, codeSet)
+}
+
+// codeSetKey is what the opcodes of a type are looked up by in a context: the address of the type, whose
+// lowest bit is free by the alignment of a type and is set when the fields are ordered by the encoder.
+func (c *RuntimeContext) codeSetKey(typeptr uintptr) uintptr {
+ return typeptr | uintptr(c.Option.Flag&OptimizeFieldOrderOption)/uintptr(OptimizeFieldOrderOption)
+}
+
+// RecentCodeSet returns the opcodes of the type if the context encoded it recently and has no context which
+// may filter the fields, or nil: then CompileToGetCodeSet is to be called.
+//
+// A runtime context remembers the opcodes of the types it encoded last: the same types are encoded again
+// and again in most of the programs, and this is cheaper than a lookup of the table shared by every goroutine.
+// This is inlined into the callers: the values of interface{} come through it one by one.
+func (c *RuntimeContext) RecentCodeSet(typeptr uintptr) *OpcodeSet {
+ key := c.codeSetKey(typeptr)
+ set := &c.recentCodeSets[recentCodeSetIndex(key)]
+ if c.Option.Flag&ContextOption == 0 {
+ if set[0].typeptr == key {
+ return set[0].codeSet
}
- cachedOpcodeSets = make([]*OpcodeSet, typeAddr.AddrRange>>typeAddr.AddrShift+1)
- })
+ if set[1].typeptr == key {
+ return set[1].codeSet
+ }
+ }
+ return nil
}
-func loadOpcodeMap() map[uintptr]*OpcodeSet {
- p := atomic.LoadPointer(&cachedOpcodeMap)
- return *(*map[uintptr]*OpcodeSet)(unsafe.Pointer(&p))
+func recentCodeSetIndex(typeptr uintptr) uint64 {
+ return (uint64(typeptr) * runtime.TypeHashMultiplier) >> recentCodeSetHashShift
}
-func storeOpcodeSet(typ uintptr, set *OpcodeSet, m map[uintptr]*OpcodeSet) {
- newOpcodeMap := make(map[uintptr]*OpcodeSet, len(m)+1)
- newOpcodeMap[typ] = set
-
- for k, v := range m {
- newOpcodeMap[k] = v
+// compileToGetUnfilteredCodeSet is CompileToGetCodeSet without the filter by the field query of the context.
+// The opcodes with the fields ordered by the encoder are cached apart from the ones in the order of the struct.
+func compileToGetUnfilteredCodeSet(typeptr uintptr, optimizeFieldOrder bool) (*OpcodeSet, error) {
+ cache := &cachedOpcodeSets
+ if optimizeFieldOrder {
+ cache = &cachedOptimizedOpcodeSets
}
-
- atomic.StorePointer(&cachedOpcodeMap, *(*unsafe.Pointer)(unsafe.Pointer(&newOpcodeMap)))
-}
-
-func compileToGetCodeSetSlowPath(typeptr uintptr) (*OpcodeSet, error) {
- opcodeMap := loadOpcodeMap()
- if codeSet, exists := opcodeMap[typeptr]; exists {
+ if codeSet := cache.Load(typeptr); codeSet != nil {
return codeSet, nil
}
- codeSet, err := newCompiler().compile(typeptr)
+ codeSet, err := newCompiler(optimizeFieldOrder).compile(typeptr)
if err != nil {
return nil, err
}
- storeOpcodeSet(typeptr, codeSet, opcodeMap)
- return codeSet, nil
+ return cache.Store(typeptr, codeSet), nil
+}
+
+type marshalerContext interface {
+ MarshalJSON(context.Context) ([]byte, error)
}
+var (
+ marshalJSONType = reflect.TypeOf((*json.Marshaler)(nil)).Elem()
+ marshalJSONContextType = reflect.TypeOf((*marshalerContext)(nil)).Elem()
+ marshalTextType = reflect.TypeOf((*encoding.TextMarshaler)(nil)).Elem()
+ jsonNumberType = reflect.TypeOf(json.Number(""))
+ cachedOpcodeSets runtime.TypeCache[OpcodeSet]
+ // cachedOptimizedOpcodeSets are the opcodes with the fields ordered by the encoder.
+ cachedOptimizedOpcodeSets runtime.TypeCache[OpcodeSet]
+)
+
func getFilteredCodeSetIfNeeded(ctx *RuntimeContext, codeSet *OpcodeSet) (*OpcodeSet, error) {
if (ctx.Option.Flag & ContextOption) == 0 {
return codeSet, nil
@@ -80,7 +109,11 @@ func getFilteredCodeSetIfNeeded(ctx *RuntimeContext, codeSet *OpcodeSet) (*Opcod
if cacheCodeSet != nil {
return cacheCodeSet, nil
}
- queryCodeSet, err := newCompiler().codeToOpcodeSet(codeSet.Type, codeSet.Code.Filter(query))
+ // the fields of the code are already in their order: the compiler orders only the fields of the recursive
+ // structs it compiles when it links them, as the code was compiled.
+ compiler := newCompiler(ctx.Option.Flag&OptimizeFieldOrderOption != 0)
+ compiler.isFiltered = true
+ queryCodeSet, err := compiler.codeToOpcodeSet(codeSet.Type, codeSet.Code.Filter(query))
if err != nil {
return nil, err
}
@@ -90,37 +123,106 @@ func getFilteredCodeSetIfNeeded(ctx *RuntimeContext, codeSet *OpcodeSet) (*Opcod
type Compiler struct {
structTypeToCode map[uintptr]*StructCode
-}
-
-func newCompiler() *Compiler {
+ // optimizeFieldOrder is whether the fields of a struct are ordered as they are encoded fastest.
+ optimizeFieldOrder bool
+ // embeddingChain is the types of the structs whose fields are written to the JSON object being compiled:
+ // the struct of the object and the structs embedded in it, down to the one being compiled.
+ embeddingChain []uintptr
+ // structFieldCounts is, for a struct which has been compiled as a value of its own ( not embedded ), how
+ // many fields its code has, with the fields of the structs in it: see sharedStructFieldCount.
+ structFieldCounts map[uintptr]int
+ // fieldCount is how many fields have been compiled.
+ fieldCount int
+ // nextIsEmbedded is whether the struct compiled next is an embedded struct, whose fields are written to
+ // the JSON object of the struct which embeds it.
+ nextIsEmbedded bool
+ // isFiltered is whether the code being compiled to opcodes is filtered by a field query: then the opcodes
+ // which a struct has in one place are not the ones of the struct in another.
+ isFiltered bool
+}
+
+// sharedStructFieldCount is how many fields the code of a struct has, with the fields of the structs in it,
+// above which the struct is encoded, where it is again a value in the same type, by a jump to one code of it
+// as a recursive struct is, instead of by a copy of its code. A type whose structs refer to each other in
+// many places would otherwise have a code of a size exponential to their depth, which takes the memory and
+// the time of compiling it ( the structs of an API with many resources expanded into each other ). A smaller
+// struct is copied, which saves the jump for each value.
+const sharedStructFieldCount = 128
+
+func newCompiler(optimizeFieldOrder bool) *Compiler {
return &Compiler{
- structTypeToCode: map[uintptr]*StructCode{},
+ structTypeToCode: map[uintptr]*StructCode{},
+ optimizeFieldOrder: optimizeFieldOrder,
+ structFieldCounts: map[uintptr]int{},
}
}
func (c *Compiler) compile(typeptr uintptr) (*OpcodeSet, error) {
// noescape trick for header.typ ( reflect.*rtype )
- typ := *(**runtime.Type)(unsafe.Pointer(&typeptr))
- code, err := c.typeToCode(typ)
+ typ := runtime.TypeOfPtr(*(*unsafe.Pointer)(unsafe.Pointer(&typeptr)))
+ if typ.Kind() == reflect.Ptr {
+ // a pointer is the address of a value, so the opcodes are the ones of the value it points to.
+ code, err := c.pointeeCode(typ.Elem())
+ if err != nil {
+ return nil, err
+ }
+ return c.codeToOpcodeSet(typ, code)
+ }
+ code, err := c.valueCode(typ)
if err != nil {
return nil, err
}
return c.codeToOpcodeSet(typ, code)
}
-func (c *Compiler) codeToOpcodeSet(typ *runtime.Type, code Code) (*OpcodeSet, error) {
- noescapeKeyCode := c.codeToOpcode(&compileContext{
+// pointeeCode returns the code for the value which a pointer points to.
+// It is addressable, as an element of a slice is.
+func (c *Compiler) pointeeCode(typ reflect.Type) (Code, error) {
+ code, err := c.listElemCode(typ)
+ if err != nil {
+ return nil, err
+ }
+ if code.Kind() == CodeKindStruct {
+ structCode := code.(*StructCode)
+ structCode.enableIndirect()
+ }
+ return code, nil
+}
+
+// valueCode returns the code for a value which is not addressable and whose address is given to the opcode:
+// the value passed to Marshal and the value held by an interface value.
+// It is the same as the value of a map, which is not addressable either.
+func (c *Compiler) valueCode(typ reflect.Type) (Code, error) {
+ code, err := c.mapValueCode(typ)
+ if err != nil {
+ return nil, err
+ }
+ if code.Kind() == CodeKindStruct {
+ structCode := code.(*StructCode)
+ structCode.enableIndirect()
+ }
+ return code, nil
+}
+
+func (c *Compiler) codeToOpcodeSet(typ reflect.Type, code Code) (*OpcodeSet, error) {
+ noescapeKeyCode, err := c.codeToOpcode(&compileContext{
structTypeToCodes: map[uintptr]Opcodes{},
recursiveCodes: &Opcodes{},
}, typ, code)
+ if err != nil {
+ return nil, err
+ }
if err := noescapeKeyCode.Validate(); err != nil {
return nil, err
}
- escapeKeyCode := c.codeToOpcode(&compileContext{
+ escapeKeyCode, err := c.codeToOpcode(&compileContext{
structTypeToCodes: map[uintptr]Opcodes{},
recursiveCodes: &Opcodes{},
escapeKey: true,
}, typ, code)
+ if err != nil {
+ return nil, err
+ }
noescapeKeyCode = copyOpcode(noescapeKeyCode)
escapeKeyCode = copyOpcode(escapeKeyCode)
setTotalLengthToInterfaceOp(noescapeKeyCode)
@@ -130,93 +232,39 @@ func (c *Compiler) codeToOpcodeSet(typ *runtime.Type, code Code) (*OpcodeSet, er
codeLength := noescapeKeyCode.TotalLength()
return &OpcodeSet{
Type: typ,
+ IfaceIndir: runtime.IfaceIndir(typ),
+ DataWordIsAddr: runtime.IfaceIndir(typ) || typ.Kind() == reflect.Ptr,
NoescapeKeyCode: noescapeKeyCode,
EscapeKeyCode: escapeKeyCode,
InterfaceNoescapeKeyCode: interfaceNoescapeKeyCode,
InterfaceEscapeKeyCode: interfaceEscapeKeyCode,
CodeLength: codeLength,
EndCode: ToEndCode(interfaceNoescapeKeyCode),
+ Scalar: scalarOpcode(noescapeKeyCode),
Code: code,
QueryCache: map[string]*OpcodeSet{},
}, nil
}
-func (c *Compiler) typeToCode(typ *runtime.Type) (Code, error) {
- switch {
- case c.implementsMarshalJSON(typ):
- return c.marshalJSONCode(typ)
- case c.implementsMarshalText(typ):
- return c.marshalTextCode(typ)
+// scalarOpcode returns the opcode if the code is a single opcode of a scalar followed by the end, or nil.
+func scalarOpcode(code *Opcode) *Opcode {
+ if isScalarOp(code.Op) && code.Next != nil && code.Next.Op == OpEnd {
+ return code
}
+ return nil
+}
- isPtr := false
- orgType := typ
- if typ.Kind() == reflect.Ptr {
- typ = typ.Elem()
- isPtr = true
- }
- switch {
- case c.implementsMarshalJSON(typ):
- return c.marshalJSONCode(orgType)
- case c.implementsMarshalText(typ):
- return c.marshalTextCode(orgType)
- }
- switch typ.Kind() {
- case reflect.Slice:
- elem := typ.Elem()
- if elem.Kind() == reflect.Uint8 {
- p := runtime.PtrTo(elem)
- if !c.implementsMarshalJSONType(p) && !p.Implements(marshalTextType) {
- return c.bytesCode(typ, isPtr)
- }
- }
- return c.sliceCode(typ)
- case reflect.Map:
- if isPtr {
- return c.ptrCode(runtime.PtrTo(typ))
- }
- return c.mapCode(typ)
- case reflect.Struct:
- return c.structCode(typ, isPtr)
- case reflect.Int:
- return c.intCode(typ, isPtr)
- case reflect.Int8:
- return c.int8Code(typ, isPtr)
- case reflect.Int16:
- return c.int16Code(typ, isPtr)
- case reflect.Int32:
- return c.int32Code(typ, isPtr)
- case reflect.Int64:
- return c.int64Code(typ, isPtr)
- case reflect.Uint, reflect.Uintptr:
- return c.uintCode(typ, isPtr)
- case reflect.Uint8:
- return c.uint8Code(typ, isPtr)
- case reflect.Uint16:
- return c.uint16Code(typ, isPtr)
- case reflect.Uint32:
- return c.uint32Code(typ, isPtr)
- case reflect.Uint64:
- return c.uint64Code(typ, isPtr)
- case reflect.Float32:
- return c.float32Code(typ, isPtr)
- case reflect.Float64:
- return c.float64Code(typ, isPtr)
- case reflect.String:
- return c.stringCode(typ, isPtr)
- case reflect.Bool:
- return c.boolCode(typ, isPtr)
- case reflect.Interface:
- return c.interfaceCode(typ, isPtr)
- default:
- if isPtr && typ.Implements(marshalTextType) {
- typ = orgType
- }
- return c.typeToCodeWithPtr(typ, isPtr)
+// isScalarOp is whether the opcode writes a scalar from the address of its value, which appendScalar of the VMs
+// does for such an opcode wherever the value is.
+func isScalarOp(op OpType) bool {
+ switch op {
+ case OpInt, OpUint, OpFloat32, OpFloat64, OpString, OpBool, OpBytes, OpNumber:
+ return true
}
+ return false
}
-func (c *Compiler) typeToCodeWithPtr(typ *runtime.Type, isPtr bool) (Code, error) {
+func (c *Compiler) typeToCodeWithPtr(typ reflect.Type, isPtr bool) (Code, error) {
switch {
case c.implementsMarshalJSON(typ):
return c.marshalJSONCode(typ)
@@ -229,7 +277,7 @@ func (c *Compiler) typeToCodeWithPtr(typ *runtime.Type, isPtr bool) (Code, error
case reflect.Slice:
elem := typ.Elem()
if elem.Kind() == reflect.Uint8 {
- p := runtime.PtrTo(elem)
+ p := reflect.PointerTo(elem)
if !c.implementsMarshalJSONType(p) && !p.Implements(marshalTextType) {
return c.bytesCode(typ, false)
}
@@ -274,153 +322,153 @@ func (c *Compiler) typeToCodeWithPtr(typ *runtime.Type, isPtr bool) (Code, error
case reflect.Bool:
return c.boolCode(typ, false)
}
- return nil, &errors.UnsupportedTypeError{Type: runtime.RType2Type(typ)}
+ return nil, &errors.UnsupportedTypeError{Type: typ}
}
const intSize = 32 << (^uint(0) >> 63)
//nolint:unparam
-func (c *Compiler) intCode(typ *runtime.Type, isPtr bool) (*IntCode, error) {
+func (c *Compiler) intCode(typ reflect.Type, isPtr bool) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: intSize, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) int8Code(typ *runtime.Type, isPtr bool) (*IntCode, error) {
+func (c *Compiler) int8Code(typ reflect.Type, isPtr bool) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 8, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) int16Code(typ *runtime.Type, isPtr bool) (*IntCode, error) {
+func (c *Compiler) int16Code(typ reflect.Type, isPtr bool) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 16, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) int32Code(typ *runtime.Type, isPtr bool) (*IntCode, error) {
+func (c *Compiler) int32Code(typ reflect.Type, isPtr bool) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 32, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) int64Code(typ *runtime.Type, isPtr bool) (*IntCode, error) {
+func (c *Compiler) int64Code(typ reflect.Type, isPtr bool) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 64, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) uintCode(typ *runtime.Type, isPtr bool) (*UintCode, error) {
+func (c *Compiler) uintCode(typ reflect.Type, isPtr bool) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: intSize, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) uint8Code(typ *runtime.Type, isPtr bool) (*UintCode, error) {
+func (c *Compiler) uint8Code(typ reflect.Type, isPtr bool) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 8, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) uint16Code(typ *runtime.Type, isPtr bool) (*UintCode, error) {
+func (c *Compiler) uint16Code(typ reflect.Type, isPtr bool) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 16, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) uint32Code(typ *runtime.Type, isPtr bool) (*UintCode, error) {
+func (c *Compiler) uint32Code(typ reflect.Type, isPtr bool) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 32, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) uint64Code(typ *runtime.Type, isPtr bool) (*UintCode, error) {
+func (c *Compiler) uint64Code(typ reflect.Type, isPtr bool) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 64, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) float32Code(typ *runtime.Type, isPtr bool) (*FloatCode, error) {
+func (c *Compiler) float32Code(typ reflect.Type, isPtr bool) (*FloatCode, error) {
return &FloatCode{typ: typ, bitSize: 32, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) float64Code(typ *runtime.Type, isPtr bool) (*FloatCode, error) {
+func (c *Compiler) float64Code(typ reflect.Type, isPtr bool) (*FloatCode, error) {
return &FloatCode{typ: typ, bitSize: 64, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) stringCode(typ *runtime.Type, isPtr bool) (*StringCode, error) {
+func (c *Compiler) stringCode(typ reflect.Type, isPtr bool) (*StringCode, error) {
return &StringCode{typ: typ, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) boolCode(typ *runtime.Type, isPtr bool) (*BoolCode, error) {
+func (c *Compiler) boolCode(typ reflect.Type, isPtr bool) (*BoolCode, error) {
return &BoolCode{typ: typ, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) intStringCode(typ *runtime.Type) (*IntCode, error) {
+func (c *Compiler) intStringCode(typ reflect.Type) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: intSize, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) int8StringCode(typ *runtime.Type) (*IntCode, error) {
+func (c *Compiler) int8StringCode(typ reflect.Type) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 8, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) int16StringCode(typ *runtime.Type) (*IntCode, error) {
+func (c *Compiler) int16StringCode(typ reflect.Type) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 16, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) int32StringCode(typ *runtime.Type) (*IntCode, error) {
+func (c *Compiler) int32StringCode(typ reflect.Type) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 32, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) int64StringCode(typ *runtime.Type) (*IntCode, error) {
+func (c *Compiler) int64StringCode(typ reflect.Type) (*IntCode, error) {
return &IntCode{typ: typ, bitSize: 64, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) uintStringCode(typ *runtime.Type) (*UintCode, error) {
+func (c *Compiler) uintStringCode(typ reflect.Type) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: intSize, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) uint8StringCode(typ *runtime.Type) (*UintCode, error) {
+func (c *Compiler) uint8StringCode(typ reflect.Type) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 8, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) uint16StringCode(typ *runtime.Type) (*UintCode, error) {
+func (c *Compiler) uint16StringCode(typ reflect.Type) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 16, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) uint32StringCode(typ *runtime.Type) (*UintCode, error) {
+func (c *Compiler) uint32StringCode(typ reflect.Type) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 32, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) uint64StringCode(typ *runtime.Type) (*UintCode, error) {
+func (c *Compiler) uint64StringCode(typ reflect.Type) (*UintCode, error) {
return &UintCode{typ: typ, bitSize: 64, isString: true}, nil
}
//nolint:unparam
-func (c *Compiler) bytesCode(typ *runtime.Type, isPtr bool) (*BytesCode, error) {
+func (c *Compiler) bytesCode(typ reflect.Type, isPtr bool) (*BytesCode, error) {
return &BytesCode{typ: typ, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) interfaceCode(typ *runtime.Type, isPtr bool) (*InterfaceCode, error) {
+func (c *Compiler) interfaceCode(typ reflect.Type, isPtr bool) (*InterfaceCode, error) {
return &InterfaceCode{typ: typ, isPtr: isPtr}, nil
}
//nolint:unparam
-func (c *Compiler) marshalJSONCode(typ *runtime.Type) (*MarshalJSONCode, error) {
+func (c *Compiler) marshalJSONCode(typ reflect.Type) (*MarshalJSONCode, error) {
return &MarshalJSONCode{
typ: typ,
isAddrForMarshaler: c.isPtrMarshalJSONType(typ),
isNilableType: c.isNilableType(typ),
- isMarshalerContext: typ.Implements(marshalJSONContextType) || runtime.PtrTo(typ).Implements(marshalJSONContextType),
+ isMarshalerContext: typ.Implements(marshalJSONContextType) || reflect.PointerTo(typ).Implements(marshalJSONContextType),
}, nil
}
//nolint:unparam
-func (c *Compiler) marshalTextCode(typ *runtime.Type) (*MarshalTextCode, error) {
+func (c *Compiler) marshalTextCode(typ reflect.Type) (*MarshalTextCode, error) {
return &MarshalTextCode{
typ: typ,
isAddrForMarshaler: c.isPtrMarshalTextType(typ),
@@ -428,7 +476,7 @@ func (c *Compiler) marshalTextCode(typ *runtime.Type) (*MarshalTextCode, error)
}, nil
}
-func (c *Compiler) ptrCode(typ *runtime.Type) (*PtrCode, error) {
+func (c *Compiler) ptrCode(typ reflect.Type) (*PtrCode, error) {
code, err := c.typeToCodeWithPtr(typ.Elem(), true)
if err != nil {
return nil, err
@@ -440,7 +488,7 @@ func (c *Compiler) ptrCode(typ *runtime.Type) (*PtrCode, error) {
return &PtrCode{typ: typ, value: code, ptrNum: 1}, nil
}
-func (c *Compiler) sliceCode(typ *runtime.Type) (*SliceCode, error) {
+func (c *Compiler) sliceCode(typ reflect.Type) (*SliceCode, error) {
elem := typ.Elem()
code, err := c.listElemCode(elem)
if err != nil {
@@ -453,7 +501,7 @@ func (c *Compiler) sliceCode(typ *runtime.Type) (*SliceCode, error) {
return &SliceCode{typ: typ, value: code}, nil
}
-func (c *Compiler) arrayCode(typ *runtime.Type) (*ArrayCode, error) {
+func (c *Compiler) arrayCode(typ reflect.Type) (*ArrayCode, error) {
elem := typ.Elem()
code, err := c.listElemCode(elem)
if err != nil {
@@ -466,7 +514,7 @@ func (c *Compiler) arrayCode(typ *runtime.Type) (*ArrayCode, error) {
return &ArrayCode{typ: typ, value: code}, nil
}
-func (c *Compiler) mapCode(typ *runtime.Type) (*MapCode, error) {
+func (c *Compiler) mapCode(typ reflect.Type) (*MapCode, error) {
keyCode, err := c.mapKeyCode(typ.Key())
if err != nil {
return nil, err
@@ -482,14 +530,22 @@ func (c *Compiler) mapCode(typ *runtime.Type) (*MapCode, error) {
return &MapCode{typ: typ, key: keyCode, value: valueCode}, nil
}
-func (c *Compiler) listElemCode(typ *runtime.Type) (Code, error) {
+func (c *Compiler) listElemCode(typ reflect.Type) (Code, error) {
switch {
- case c.implementsMarshalJSONType(typ) || c.implementsMarshalJSONType(runtime.PtrTo(typ)):
+ case c.isPtrMarshalJSONType(typ):
+ // The opcode takes the address of the element, which is the very pointer the marshaler is called with.
+ // So the opcode is the one of the pointer type, and neither a copy of the element nor reflect is needed.
+ ptrType := reflect.PointerTo(typ)
+ return &MarshalJSONCode{
+ typ: ptrType,
+ isMarshalerContext: ptrType.Implements(marshalJSONContextType),
+ }, nil
+ case c.implementsMarshalJSONType(typ):
return c.marshalJSONCode(typ)
- case !typ.Implements(marshalTextType) && runtime.PtrTo(typ).Implements(marshalTextType):
- return c.marshalTextCode(typ)
+ case !typ.Implements(marshalTextType) && reflect.PointerTo(typ).Implements(marshalTextType):
+ return &MarshalTextCode{typ: reflect.PointerTo(typ)}, nil
case typ.Kind() == reflect.Map:
- return c.ptrCode(runtime.PtrTo(typ))
+ return c.ptrCode(reflect.PointerTo(typ))
default:
// isPtr was originally used to indicate whether the type of top level is pointer.
// However, since the slice/array element is a specification that can get the pointer address, explicitly set isPtr to true.
@@ -508,14 +564,32 @@ func (c *Compiler) listElemCode(typ *runtime.Type) (Code, error) {
}
}
-func (c *Compiler) mapKeyCode(typ *runtime.Type) (Code, error) {
+func (c *Compiler) mapKeyCode(typ reflect.Type) (Code, error) {
switch {
+ case typ.Kind() == reflect.Interface && (interfaceMapKeys || c.implementsMarshalText(typ)):
+ // the name of a key is of its dynamic value, as encoding/json of the Go it is built with makes it: every
+ // key of an interface type where it is built on encoding/json/v2, and else a key of an interface type
+ // which has MarshalText ( see appendInterfaceMapKey ).
+ return &MarshalTextCode{typ: typ, isInterfaceMapKey: true}, nil
case c.implementsMarshalText(typ):
- return c.marshalTextCode(typ)
+ code, err := c.marshalTextCode(typ)
+ if err != nil {
+ return nil, err
+ }
+ code.isMapKey = true
+ return code, nil
}
switch typ.Kind() {
case reflect.Ptr:
- return c.ptrCode(typ)
+ code, err := c.ptrCode(typ)
+ if err != nil {
+ return nil, err
+ }
+ if text, ok := code.value.(*MarshalTextCode); ok {
+ // a pointer to a value whose MarshalText has a value receiver
+ text.isMapKey = true
+ }
+ return code, nil
case reflect.String:
return c.stringCode(typ, false)
case reflect.Int:
@@ -541,13 +615,14 @@ func (c *Compiler) mapKeyCode(typ *runtime.Type) (Code, error) {
case reflect.Uintptr:
return c.uintStringCode(typ)
}
- return nil, &errors.UnsupportedTypeError{Type: runtime.RType2Type(typ)}
+ return nil, &errors.UnsupportedTypeError{Type: typ}
}
-func (c *Compiler) mapValueCode(typ *runtime.Type) (Code, error) {
- switch typ.Kind() {
- case reflect.Map:
- return c.ptrCode(runtime.PtrTo(typ))
+func (c *Compiler) mapValueCode(typ reflect.Type) (Code, error) {
+ switch {
+ case typ.Kind() == reflect.Map && !c.implementsMarshalJSON(typ) && !c.implementsMarshalText(typ):
+ // a map which has a marshaler is encoded by the marshaler, not as a map.
+ return c.ptrCode(reflect.PointerTo(typ))
default:
code, err := c.typeToCodeWithPtr(typ, false)
if err != nil {
@@ -563,21 +638,50 @@ func (c *Compiler) mapValueCode(typ *runtime.Type) (Code, error) {
}
}
-func (c *Compiler) structCode(typ *runtime.Type, isPtr bool) (*StructCode, error) {
- typeptr := uintptr(unsafe.Pointer(typ))
+func (c *Compiler) structCode(typ reflect.Type, isPtr bool) (*StructCode, error) {
+ embedded := c.nextIsEmbedded
+ c.nextIsEmbedded = false
+ return c.compileStruct(typ, isPtr, embedded, !embedded)
+}
+
+// compileStruct returns the code of the struct. embedded is whether it is an embedded struct. mayShare is
+// whether the struct may be encoded by a jump to one code of it, if it is large and has been compiled before
+// ( see sharedStructFieldCount ): an embedded struct is not, because its fields are the ones of the struct
+// which embeds it, which may hide some of them.
+func (c *Compiler) compileStruct(typ reflect.Type, isPtr, embedded, mayShare bool) (*StructCode, error) {
+ typeptr := uintptr(runtime.TypePtr(typ))
+ if count, compiled := c.structFieldCounts[typeptr]; mayShare && compiled && count > sharedStructFieldCount {
+ if _, onPath := c.structTypeToCode[typeptr]; !onPath {
+ // the code which is jumped to is compiled when the recursive codes are linked.
+ return &StructCode{typ: typ, isPtr: isPtr, isIndirect: runtime.IfaceIndir(typ), isRecursive: true}, nil
+ }
+ }
if code, exists := c.structTypeToCode[typeptr]; exists {
derefCode := *code
derefCode.isRecursive = true
+ if slices.Contains(c.embeddingChain, typeptr) {
+ // The struct is embedded in itself, directly or through the other embedded structs. All of its
+ // fields are hidden by the same fields of itself at the shallower depth of the same JSON
+ // object, as in encoding/json, so it has nothing to write.
+ derefCode.isHiddenByItself = true
+ }
return &derefCode, nil
}
+ c.embeddingChain = append(c.embeddingChain, typeptr)
+ defer func() { c.embeddingChain = c.embeddingChain[:len(c.embeddingChain)-1] }()
indirect := runtime.IfaceIndir(typ)
code := &StructCode{typ: typ, isPtr: isPtr, isIndirect: indirect}
c.structTypeToCode[typeptr] = code
+ firstField := c.fieldCount
fieldNum := typ.NumField()
tags := c.typeToStructTags(typ)
fields := []*StructFieldCode{}
for i, tag := range tags {
+ if (tag.IsOmitEmpty || tag.IsOmitZero) && tag.Field.Type.Kind() == reflect.Array && tag.Field.Type.Len() == 0 {
+ // an array of no elements is always empty and zero, as in encoding/json.
+ continue
+ }
isOnlyOneFirstField := i == 0 && fieldNum == 1
field, err := c.structFieldCode(code, tag, isPtr, isOnlyOneFirstField)
if err != nil {
@@ -585,8 +689,11 @@ func (c *Compiler) structCode(typ *runtime.Type, isPtr bool) (*StructCode, error
}
if field.isAnonymous {
structCode := field.getAnonymousStruct()
+ if structCode != nil && structCode.isHiddenByItself {
+ continue
+ }
if structCode != nil {
- structCode.removeFieldsByTags(tags)
+ structCode.removeFieldsByTags(c.keyTags(tags))
if c.isAssignableIndirect(field, isPtr) {
if indirect {
structCode.isIndirect = true
@@ -614,14 +721,66 @@ func (c *Compiler) structCode(typ *runtime.Type, isPtr bool) (*StructCode, error
fieldMap := c.getFieldMap(fields)
duplicatedFieldMap := c.getDuplicatedFieldMap(fieldMap)
code.fields = c.filteredDuplicatedFields(fields, duplicatedFieldMap)
+ if c.optimizeFieldOrder {
+ code.fields = orderFieldsForSpeed(code.fields, typ)
+ }
if !code.disableIndirectConversion && !indirect && isPtr {
code.enableIndirect()
}
delete(c.structTypeToCode, typeptr)
+ c.fieldCount += len(code.fields)
+ if !embedded {
+ c.structFieldCounts[typeptr] = c.fieldCount - firstField
+ }
return code, nil
}
-func toElemType(t *runtime.Type) *runtime.Type {
+// orderFieldsForSpeed returns the fields in the order they are encoded fastest ( OptimizeFieldOrderOption ):
+// the fields of a kind which has the opcodes of a run ( fieldRunOps ) are put together, where the first field
+// of the kind is, so that a run is as long as it can be; and a field which is a value of the struct's own type,
+// if there is one, is put last, so that a list of values is encoded in one frame ( markTailRecursion ).
+// The other fields stay in their order.
+func orderFieldsForSpeed(fields []*StructFieldCode, typ reflect.Type) []*StructFieldCode {
+ recursive := -1
+ for i, field := range fields {
+ if field.isRecursiveValueOf(typ) {
+ if recursive >= 0 {
+ recursive = -1 // more than one: none of them is the last
+ break
+ }
+ recursive = i
+ }
+ }
+ // the order key of a field: where the first field of its kind is, or its own place.
+ keys := make([]int, len(fields))
+ firstOfKind := map[CodeKind]int{}
+ for i, field := range fields {
+ keys[i] = i
+ if i == recursive {
+ keys[i] = len(fields)
+ continue
+ }
+ if kind, ok := field.runKind(); ok {
+ if first, seen := firstOfKind[kind]; seen {
+ keys[i] = first
+ } else {
+ firstOfKind[kind] = i
+ }
+ }
+ }
+ order := make([]int, len(fields))
+ for i := range order {
+ order[i] = i
+ }
+ sort.SliceStable(order, func(i, j int) bool { return keys[order[i]] < keys[order[j]] })
+ ordered := make([]*StructFieldCode, len(fields))
+ for i, j := range order {
+ ordered[i] = fields[j]
+ }
+ return ordered
+}
+
+func toElemType(t reflect.Type) reflect.Type {
for t.Kind() == reflect.Ptr {
t = t.Elem()
}
@@ -630,17 +789,35 @@ func toElemType(t *runtime.Type) *runtime.Type {
func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTag, isPtr, isOnlyOneFirstField bool) (*StructFieldCode, error) {
field := tag.Field
- fieldType := runtime.Type2RType(field.Type)
+ fieldType := field.Type
isIndirectSpecialCase := isPtr && isOnlyOneFirstField
fieldCode := &StructFieldCode{
typ: fieldType,
key: tag.Key,
tag: tag,
offset: field.Offset,
- isAnonymous: field.Anonymous && !tag.IsTaggedKey && toElemType(fieldType).Kind() == reflect.Struct,
+ isAnonymous: c.isEmbeddedStruct(tag),
isTaggedKey: tag.IsTaggedKey,
isNilableType: c.isNilableType(fieldType),
- isNilCheck: true,
+ // The check writes null instead of calling the marshaler, which encoding/json does only for a nil
+ // pointer: the marshaler of a nil map is called. With omitempty the check is what decides that
+ // the field is empty, for every kind.
+ isNilCheck: tag.IsOmitEmpty || fieldType.Kind() == reflect.Ptr,
+ }
+ if !fieldCode.isAnonymous {
+ // the value of the field is not a part of the JSON object being compiled.
+ embeddingChain := c.embeddingChain
+ c.embeddingChain = nil
+ defer func() { c.embeddingChain = embeddingChain }()
+ }
+ if fieldCode.isAnonymous && (tag.IsOmitEmpty || tag.IsOmitZero) {
+ // The fields of an embedded struct are written as the fields of the struct which embeds it, so there is
+ // nothing for omitempty or omitzero of the embedded struct itself to omit, as in encoding/json. The
+ // opcode for them would write the key of the embedded struct.
+ inlined := *tag
+ inlined.IsOmitEmpty = false
+ inlined.IsOmitZero = false
+ fieldCode.tag = &inlined
}
switch {
case c.isMovePointerPositionFromHeadToFirstMarshalJSONFieldCase(fieldType, isIndirectSpecialCase):
@@ -650,7 +827,7 @@ func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTa
}
fieldCode.value = code
fieldCode.isAddrForMarshaler = true
- fieldCode.isNilCheck = false
+ fieldCode.isNilCheck = c.isNilCheckForAddrMarshaler(tag)
structCode.isIndirect = false
structCode.disableIndirectConversion = true
case c.isMovePointerPositionFromHeadToFirstMarshalTextFieldCase(fieldType, isIndirectSpecialCase):
@@ -660,7 +837,7 @@ func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTa
}
fieldCode.value = code
fieldCode.isAddrForMarshaler = true
- fieldCode.isNilCheck = false
+ fieldCode.isNilCheck = c.isNilCheckForAddrMarshaler(tag)
structCode.isIndirect = false
structCode.disableIndirectConversion = true
case isPtr && c.isPtrMarshalJSONType(fieldType):
@@ -672,7 +849,7 @@ func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTa
}
fieldCode.value = code
fieldCode.isAddrForMarshaler = true
- fieldCode.isNilCheck = false
+ fieldCode.isNilCheck = c.isNilCheckForAddrMarshaler(tag)
case isPtr && c.isPtrMarshalTextType(fieldType):
// *struct{ field T }
// func (*T) MarshalText() ([]byte, error)
@@ -682,9 +859,11 @@ func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTa
}
fieldCode.value = code
fieldCode.isAddrForMarshaler = true
- fieldCode.isNilCheck = false
+ fieldCode.isNilCheck = c.isNilCheckForAddrMarshaler(tag)
default:
+ c.nextIsEmbedded = fieldCode.isAnonymous
code, err := c.typeToCodeWithPtr(fieldType, isPtr)
+ c.nextIsEmbedded = false
if err != nil {
return nil, err
}
@@ -697,6 +876,34 @@ func (c *Compiler) structFieldCode(structCode *StructCode, tag *runtime.StructTa
return fieldCode, nil
}
+// isNilCheckForAddrMarshaler returns whether a field whose marshaler is called with its address is checked.
+//
+// The check is what decides that the field is empty for omitempty, by the kind of the value as encoding/json
+// does, so it is required for omitempty. Without omitempty it would write null instead of calling the
+// marshaler, which a pointer to the field never needs.
+func (c *Compiler) isNilCheckForAddrMarshaler(tag *runtime.StructTag) bool {
+ return tag.IsOmitEmpty
+}
+
+// isEmbeddedStruct reports whether the field is an embedded struct whose fields are written as the fields of
+// the struct which embeds it.
+func (c *Compiler) isEmbeddedStruct(tag *runtime.StructTag) bool {
+ return tag.Field.Anonymous && !tag.IsTaggedKey && toElemType(tag.Field.Type).Kind() == reflect.Struct
+}
+
+// keyTags returns the tags of the fields which are written with their own keys.
+// An embedded struct is not: its name is not a key, so it doesn't hide a field of the same name.
+func (c *Compiler) keyTags(tags runtime.StructTags) runtime.StructTags {
+ keyTags := make(runtime.StructTags, 0, len(tags))
+ for _, tag := range tags {
+ if c.isEmbeddedStruct(tag) {
+ continue
+ }
+ keyTags = append(keyTags, tag)
+ }
+ return keyTags
+}
+
func (c *Compiler) isAssignableIndirect(fieldCode *StructFieldCode, isPtr bool) bool {
if isPtr {
return false
@@ -809,7 +1016,7 @@ func (c *Compiler) isTaggedKeyOnly(fields []*StructFieldCode) bool {
return taggedKeyFieldCount == 1
}
-func (c *Compiler) typeToStructTags(typ *runtime.Type) runtime.StructTags {
+func (c *Compiler) typeToStructTags(typ reflect.Type) runtime.StructTags {
tags := runtime.StructTags{}
fieldNum := typ.NumField()
for i := 0; i < fieldNum; i++ {
@@ -824,17 +1031,17 @@ func (c *Compiler) typeToStructTags(typ *runtime.Type) runtime.StructTags {
// *struct{ field T } => struct { field *T }
// func (*T) MarshalJSON() ([]byte, error)
-func (c *Compiler) isMovePointerPositionFromHeadToFirstMarshalJSONFieldCase(typ *runtime.Type, isIndirectSpecialCase bool) bool {
+func (c *Compiler) isMovePointerPositionFromHeadToFirstMarshalJSONFieldCase(typ reflect.Type, isIndirectSpecialCase bool) bool {
return isIndirectSpecialCase && !c.isNilableType(typ) && c.isPtrMarshalJSONType(typ)
}
// *struct{ field T } => struct { field *T }
// func (*T) MarshalText() ([]byte, error)
-func (c *Compiler) isMovePointerPositionFromHeadToFirstMarshalTextFieldCase(typ *runtime.Type, isIndirectSpecialCase bool) bool {
+func (c *Compiler) isMovePointerPositionFromHeadToFirstMarshalTextFieldCase(typ reflect.Type, isIndirectSpecialCase bool) bool {
return isIndirectSpecialCase && !c.isNilableType(typ) && c.isPtrMarshalTextType(typ)
}
-func (c *Compiler) implementsMarshalJSON(typ *runtime.Type) bool {
+func (c *Compiler) implementsMarshalJSON(typ reflect.Type) bool {
if !c.implementsMarshalJSONType(typ) {
return false
}
@@ -845,11 +1052,17 @@ func (c *Compiler) implementsMarshalJSON(typ *runtime.Type) bool {
if !c.implementsMarshalJSONType(typ.Elem()) {
return true
}
+ if !runtime.IfaceIndir(typ.Elem()) {
+ // the value is stored directly in an interface value ( a map, a func, a struct of one pointer, ... ): the
+ // method of the pointer takes the pointer, where the one of the value would take the value itself, which the
+ // opcodes of a dereferenced pointer don't load.
+ return true
+ }
// needs to dereference
return false
}
-func (c *Compiler) implementsMarshalText(typ *runtime.Type) bool {
+func (c *Compiler) implementsMarshalText(typ reflect.Type) bool {
if !typ.Implements(marshalTextType) {
return false
}
@@ -860,11 +1073,17 @@ func (c *Compiler) implementsMarshalText(typ *runtime.Type) bool {
if !typ.Elem().Implements(marshalTextType) {
return true
}
+ if !runtime.IfaceIndir(typ.Elem()) {
+ // the value is stored directly in an interface value ( a map, a func, a struct of one pointer, ... ): the
+ // method of the pointer takes the pointer, where the one of the value would take the value itself, which the
+ // opcodes of a dereferenced pointer don't load.
+ return true
+ }
// needs to dereference
return false
}
-func (c *Compiler) isNilableType(typ *runtime.Type) bool {
+func (c *Compiler) isNilableType(typ reflect.Type) bool {
if !runtime.IfaceIndir(typ) {
return true
}
@@ -880,60 +1099,144 @@ func (c *Compiler) isNilableType(typ *runtime.Type) bool {
}
}
-func (c *Compiler) implementsMarshalJSONType(typ *runtime.Type) bool {
+func (c *Compiler) implementsMarshalJSONType(typ reflect.Type) bool {
return typ.Implements(marshalJSONType) || typ.Implements(marshalJSONContextType)
}
-func (c *Compiler) isPtrMarshalJSONType(typ *runtime.Type) bool {
- return !c.implementsMarshalJSONType(typ) && c.implementsMarshalJSONType(runtime.PtrTo(typ))
+func (c *Compiler) isPtrMarshalJSONType(typ reflect.Type) bool {
+ return !c.implementsMarshalJSONType(typ) && c.implementsMarshalJSONType(reflect.PointerTo(typ))
}
-func (c *Compiler) isPtrMarshalTextType(typ *runtime.Type) bool {
- return !typ.Implements(marshalTextType) && runtime.PtrTo(typ).Implements(marshalTextType)
+func (c *Compiler) isPtrMarshalTextType(typ reflect.Type) bool {
+ return !typ.Implements(marshalTextType) && reflect.PointerTo(typ).Implements(marshalTextType)
}
-func (c *Compiler) codeToOpcode(ctx *compileContext, typ *runtime.Type, code Code) *Opcode {
+func (c *Compiler) codeToOpcode(ctx *compileContext, typ reflect.Type, code Code) (*Opcode, error) {
codes := code.ToOpcode(ctx)
+ // the first opcode takes the address of the value, as the one of the value of a map does.
+ codes.First().Flags |= IndirectFlags
codes.Last().Next = newEndOp(ctx, typ)
- c.linkRecursiveCode(ctx)
- return codes.First()
+ if err := c.linkRecursiveCode(ctx); err != nil {
+ return nil, err
+ }
+ return codes.First(), nil
+}
+
+// markTailRecursion marks the opcodes of code, the code of a recursive struct, which encode a value of the same
+// type as its last field: such a value is encoded in the frame of the struct, without a frame of its own
+// ( RuntimeContext.EnterTailRecursive ), and the end of the struct closes the braces of the values one by one
+// when the last of them ends ( LeaveTailRecursive ), which is why the end opcode leads back to it.
+//
+// The opcodes of the struct which the code is copied from, the ones which are jumped to it from, are not
+// marked: the first value of the type in a frame enters a frame, so that the last value returns from it.
+func markTailRecursion(code, end *Opcode, compiled *CompiledCode) {
+ // the end of the struct is an opcode of its own only when the last field is not encoded by one opcode:
+ // then it is the end which closes the braces, and which a value in the last field is followed by.
+ if code.End.Op != OpStructEnd {
+ return
+ }
+ for c := code; !c.IsEnd(); c = c.IterNext() {
+ if (c.Op == OpRecursive || c.Op == OpRecursivePtr) && c.Jmp == compiled && c.Next == code.End {
+ c.Flags |= TailRecursiveFlags
+ // what the indent is deeper by for a value: LeaveTailRecursive takes it back.
+ end.Indent = c.Indent - (code.Indent - 1)
+ }
+ }
+ end.Next = code.End
}
-func (c *Compiler) linkRecursiveCode(ctx *compileContext) {
- recursiveCodes := map[uintptr]*CompiledCode{}
- for _, recursive := range *ctx.recursiveCodes {
- typeptr := uintptr(unsafe.Pointer(recursive.Type))
- codes := ctx.structTypeToCodes[typeptr]
- if recursiveCode, ok := recursiveCodes[typeptr]; ok {
+func (c *Compiler) linkRecursiveCode(ctx *compileContext) error {
+ type recursiveTarget struct {
+ typeptr uintptr
+ embedded bool
+ query *FieldQuery
+ }
+ recursiveCodes := map[recursiveTarget]*CompiledCode{}
+ // maxFrameLength is the length of the longest frame which a recursive code is jumped from.
+ var maxFrameLength uintptr
+ // the recursive codes may increase while they are linked, so the length is evaluated every time.
+ for i := 0; i < len(*ctx.recursiveCodes); i++ {
+ recursive := (*ctx.recursiveCodes)[i]
+ target := recursiveTarget{typeptr: uintptr(recursive.Type), embedded: recursive.Jmp.Embedded, query: recursive.FieldQuery}
+ typeptr := target.typeptr
+ if recursiveCode, ok := recursiveCodes[target]; ok {
*recursive.Jmp = *recursiveCode
continue
}
+ codes, exists := ctx.structTypeToCodes[typeptr]
+ if target.embedded || !exists || c.isFiltered {
+ // structTypeToCodes has the opcodes of the struct itself, with the braces and the check of nil.
+ // - A recursive struct which is embedded jumps to the opcodes only of the fields.
+ // - A struct which has been compiled only as an embedded struct is not in structTypeToCodes.
+ // - The opcodes of a struct filtered by a field query are filtered by the query of their place,
+ // and the struct is filtered by the query of the code which jumps to it.
+ // In these cases the opcodes to jump to are compiled here.
+ structCode, err := c.compileStruct(runtime.TypeOfPtr(recursive.Type), false, target.embedded, false)
+ if err != nil {
+ return err
+ }
+ if target.query != nil {
+ structCode = structCode.Filter(target.query).(*StructCode)
+ }
+ structCode.enableIndirect()
+ if target.embedded {
+ codes = structCode.ToAnonymousOpcode(ctx)
+ } else {
+ codes = structCode.ToOpcode(ctx)
+ }
+ // the opcodes are copied up to the end, as the ones in the code which jumps to them are.
+ codes.Last().Next = newEndOp(ctx, runtime.TypeOfPtr(recursive.Type))
+ }
code := copyOpcode(codes.First())
code.Op = code.Op.PtrHeadToHead()
- lastCode := newEndOp(&compileContext{}, recursive.Type)
+ lastCode := newEndOp(&compileContext{}, runtime.TypeOfPtr(recursive.Type))
lastCode.Op = OpRecursiveEnd
// OpRecursiveEnd must set before call TotalLength
code.End.Next = lastCode
+ markTailRecursion(code, lastCode, recursive.Jmp)
totalLength := code.TotalLength()
// Idx, ElemIdx, Length must set after call TotalLength
- lastCode.Idx = uint32((totalLength + 1) * uintptrSize)
- lastCode.ElemIdx = lastCode.Idx + uintptrSize
- lastCode.Length = lastCode.Idx + 2*uintptrSize
-
+ lastCode.Idx = opcodeOffset(totalLength + 1)
+ lastCode.setEndSlots()
+
+ // An interface in the recursive code allocates its frame after the frame it is in, which is
+ // the one of the recursive code, not of the code which jumps to it. The length must include
+ // the slots of OpRecursiveEnd, so it is set after they are decided.
+ setTotalLengthToInterfaceOp(code)
+
+ // The frame of the recursive code has the slots up to the ones of OpRecursiveEnd
+ // ( the offset to return to, the opcode to return to and the indent to restore ),
+ // so its length is the last index + 1.
+ nextTotalLength := uintptr(code.TotalLength()) + 1
+ if maxFrameLength < nextTotalLength {
+ maxFrameLength = nextTotalLength
+ }
// extend length to alloc slot for elemIdx + length
- curTotalLength := uintptr(recursive.TotalLength()) + 3
- nextTotalLength := uintptr(totalLength) + 3
+ if curTotalLength := uintptr(recursive.TotalLength()) + 3; maxFrameLength < curTotalLength {
+ maxFrameLength = curTotalLength
+ }
compiled := recursive.Jmp
compiled.Code = code
- compiled.CurLen = curTotalLength
compiled.NextLen = nextTotalLength
compiled.Linked = true
- recursiveCodes[typeptr] = compiled
+ recursiveCodes[target] = compiled
+ }
+ // The new frame is allocated after the frame which the recursive code is jumped from, and CurLen is the
+ // length of that frame. The same CompiledCode is jumped to from the code of the top level and from every
+ // recursive code, including itself, so CurLen must not be less than any of those frames: otherwise the
+ // new frame overlaps the slots of OpRecursiveEnd of the frame it is jumped from, and the indent to
+ // restore is broken by a pointer.
+ for _, compiled := range recursiveCodes {
+ compiled.CurLen = maxFrameLength
+ }
+ for _, recursive := range *ctx.recursiveCodes {
+ recursive.Jmp.CurLen = maxFrameLength
}
+ return nil
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/compiler_norace.go b/vendor/github.com/goccy/go-json/internal/encoder/compiler_norace.go
deleted file mode 100644
index b6f45a49b..000000000
--- a/vendor/github.com/goccy/go-json/internal/encoder/compiler_norace.go
+++ /dev/null
@@ -1,33 +0,0 @@
-//go:build !race
-// +build !race
-
-package encoder
-
-func CompileToGetCodeSet(ctx *RuntimeContext, typeptr uintptr) (*OpcodeSet, error) {
- initEncoder()
- if typeptr > typeAddr.MaxTypeAddr || typeptr < typeAddr.BaseTypeAddr {
- codeSet, err := compileToGetCodeSetSlowPath(typeptr)
- if err != nil {
- return nil, err
- }
- return getFilteredCodeSetIfNeeded(ctx, codeSet)
- }
- index := (typeptr - typeAddr.BaseTypeAddr) >> typeAddr.AddrShift
- if codeSet := cachedOpcodeSets[index]; codeSet != nil {
- filtered, err := getFilteredCodeSetIfNeeded(ctx, codeSet)
- if err != nil {
- return nil, err
- }
- return filtered, nil
- }
- codeSet, err := newCompiler().compile(typeptr)
- if err != nil {
- return nil, err
- }
- filtered, err := getFilteredCodeSetIfNeeded(ctx, codeSet)
- if err != nil {
- return nil, err
- }
- cachedOpcodeSets[index] = codeSet
- return filtered, nil
-}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/compiler_race.go b/vendor/github.com/goccy/go-json/internal/encoder/compiler_race.go
deleted file mode 100644
index 47b482f7f..000000000
--- a/vendor/github.com/goccy/go-json/internal/encoder/compiler_race.go
+++ /dev/null
@@ -1,46 +0,0 @@
-//go:build race
-// +build race
-
-package encoder
-
-import (
- "sync"
-)
-
-var setsMu sync.RWMutex
-
-func CompileToGetCodeSet(ctx *RuntimeContext, typeptr uintptr) (*OpcodeSet, error) {
- initEncoder()
- if typeptr > typeAddr.MaxTypeAddr || typeptr < typeAddr.BaseTypeAddr {
- codeSet, err := compileToGetCodeSetSlowPath(typeptr)
- if err != nil {
- return nil, err
- }
- return getFilteredCodeSetIfNeeded(ctx, codeSet)
- }
- index := (typeptr - typeAddr.BaseTypeAddr) >> typeAddr.AddrShift
- setsMu.RLock()
- if codeSet := cachedOpcodeSets[index]; codeSet != nil {
- filtered, err := getFilteredCodeSetIfNeeded(ctx, codeSet)
- if err != nil {
- setsMu.RUnlock()
- return nil, err
- }
- setsMu.RUnlock()
- return filtered, nil
- }
- setsMu.RUnlock()
-
- codeSet, err := newCompiler().compile(typeptr)
- if err != nil {
- return nil, err
- }
- filtered, err := getFilteredCodeSetIfNeeded(ctx, codeSet)
- if err != nil {
- return nil, err
- }
- setsMu.Lock()
- cachedOpcodeSets[index] = codeSet
- setsMu.Unlock()
- return filtered, nil
-}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/context.go b/vendor/github.com/goccy/go-json/internal/encoder/context.go
index 3833d0c86..ddd88181a 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/context.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/context.go
@@ -57,43 +57,154 @@ const (
var (
runtimeContextPool = sync.Pool{
- New: func() interface{} {
+ New: func() any {
return &RuntimeContext{
- Buf: make([]byte, 0, bufSize),
- Ptrs: make([]uintptr, 128),
- KeepRefs: make([]unsafe.Pointer, 0, 8),
- Option: &Option{},
+ Buf: make([]byte, 0, bufSize),
+ Slots: make([]uintptr, 128*slotWords),
+ Option: &Option{},
}
},
}
)
+// Slot is the layout of a slot of the VM. The opcodes refer to a half of a slot by its offset from the head of
+// the frame: Ptr is for a pointer ( the address of a value, the context of a map, the opcode to return to ) and
+// Int is for the other values ( an index, a length, the offset of a frame, an indent ).
+//
+// The slots are in the heap, and both halves are stored as uintptr there: a store of a pointer to the heap goes
+// through the write barrier while the GC is marking, which made the encoding of a struct about 50% slower during
+// that time. So the GC doesn't see the slots, and what they refer to is kept alive by others:
+// - the value passed to Marshal is kept alive by its caller, and so is everything reachable from it
+// - the value copied from an interface value is referred to by RuntimeContext
+// - the context of a map is referred to by RuntimeContext
+//
+// The opcodes are never freed.
+type Slot struct {
+ Ptr unsafe.Pointer
+ Int uintptr
+}
+
+// slotWords is the number of the words of a slot.
+const slotWords = 2
+
+const (
+ // recentCodeSetSets is the number of the sets of the recent opcodes, of recentCodeSetWays entries each.
+ // The set of a type is the top bits of the product of its address with an odd constant, which spreads
+ // the addresses of the types, which are close to each other, over the sets.
+ //
+ // The shape of the table is by BenchmarkVariant_RecentCodeSets and by the encoding of values whose types
+ // are of the same set, on arm64 and on the amd64 machines of the CI:
+ // - a lookup which hits costs the same whatever the number of the sets ( 16 to 128 ), and a miss
+ // costs the lookup of the shared table on top: 4 ns on arm64, 8 ns on amd64;
+ // - two entries per set cost the same as one when the first entry hits, and a third and a fourth
+ // entry cost a nanosecond for every value of interface{} on arm64, whether they hit or not;
+ // - more sets only make it rarer for three types encoded by turns to be of one set: it is the case
+ // for some three of six types, which a document of map[string]interface{} has, in 8% of the
+ // binaries with 16 sets and in 2% with 32. That is not worth the memory of every context: 64 sets,
+ // 1 KB, measured +1% on the whole on amd64, and 32 sets measured nothing.
+ // So the table is 256 B: 16 sets of two entries.
+ recentCodeSetSets = 16
+ recentCodeSetHashShift = 64 - 4
+ // recentCodeSetWays is the number of the types a set holds: the ones hashed to it which were encoded
+ // last. Two types encoded by turns, such as the type passed to Marshal and the type held by its values
+ // of interface{}, never evict each other then, whatever their addresses are. With one entry per set,
+ // they did whenever their addresses hashed to the same entry, which depends on where the binary has the
+ // types, and every Marshal of them cost two lookups of the table shared by every goroutine: 20% of the
+ // encoding of a small value, present or absent by the build. Three types of a set encoded by turns still
+ // evict each other, which costs those lookups, not the result.
+ recentCodeSetWays = 2
+)
+
+type recentCodeSet struct {
+ typeptr uintptr
+ codeSet *OpcodeSet
+}
+
+// recentCodeSetSet is the entries of a set, the one encoded last first.
+type recentCodeSetSet [recentCodeSetWays]recentCodeSet
+
type RuntimeContext struct {
Context context.Context
Buf []byte
MarshalBuf []byte
- Ptrs []uintptr
- KeepRefs []unsafe.Pointer
- SeenPtr []uintptr
+ Slots []uintptr
+ SeenPtr []unsafe.Pointer
BaseIndent uint32
+ // RecursiveLevel and SlotOffset are the state of the VM which only the opcodes of an interface value and of
+ // a recursive type use. They are here, not in the variables of the VM: the VM keeps its variables in the
+ // registers across the opcodes, and it has to restore every one of them after each call in an opcode.
+ RecursiveLevel int
+ SlotOffset uintptr
+ // TailLevels is the number of the values of a recursive type which are being encoded in the current frame,
+ // one after the other as the last field of the previous, without a frame of their own: see
+ // EnterTailRecursive. Their braces are closed one by one when the last of them ends.
+ TailLevels uint32
Prefix []byte
IndentStr []byte
Option *Option
+ // mapContexts are the contexts of the maps nested in each other, one for each level, and mapDepth is the
+ // number of the maps being encoded.
+ mapContexts []*MapContext
+ mapDepth int
+ // nested is whether a frame was added by ReserveSlots: only such a frame uses SeenPtr.
+ nested bool
+ // topValue holds the value passed to Marshal when it is stored directly in its interface value: the
+ // interface value is an argument, whose address may change with the stack, so the value is copied here.
+ topValue unsafe.Pointer
+ // recentCodeSets are the opcodes of the types encoded last, in the sets indexed by the address of the type.
+ recentCodeSets [recentCodeSetSets]recentCodeSetSet
+ // value is a zero value of the type of valueCodeSet in the heap, which MarshalOf copies its argument to.
+ // It is zeroed again after the encoding.
+ valueCodeSet *OpcodeSet
+ value unsafe.Pointer
+}
+
+// ValueAddr returns the address of the value passed to Marshal, which the data word of its interface value
+// represents.
+//
+// The opcodes always take the address of a value. The data word of an interface value is the address
+// for most of the types, but it is the value itself if the type is stored directly ( a pointer, a map,
+// a struct of a single pointer, ... ). Such a value is copied to the context, and the address of the copy
+// is returned.
+func (c *RuntimeContext) ValueAddr(codeSet *OpcodeSet, dataWord unsafe.Pointer) unsafe.Pointer {
+ if codeSet.DataWordIsAddr {
+ return dataWord
+ }
+ c.topValue = dataWord
+ return unsafe.Pointer(&c.topValue)
}
-func (c *RuntimeContext) Init(p uintptr, codelen int) {
- if len(c.Ptrs) < codelen {
- c.Ptrs = make([]uintptr, codelen)
+func (c *RuntimeContext) Init(p unsafe.Pointer, codelen int) {
+ if len(c.Slots) < codelen*slotWords {
+ c.Slots = make([]uintptr, codelen*slotWords)
}
- c.Ptrs[0] = p
- c.KeepRefs = c.KeepRefs[:0]
+ c.Slots[0] = uintptr(p)
c.SeenPtr = c.SeenPtr[:0]
c.BaseIndent = 0
+ c.RecursiveLevel = 0
+ c.SlotOffset = 0
+ c.TailLevels = 0
}
-func (c *RuntimeContext) Ptr() uintptr {
- header := (*runtime.SliceHeader)(unsafe.Pointer(&c.Ptrs))
- return uintptr(header.Data)
+// ReserveSlots makes the context have the slots of the frames up to the length.
+func (c *RuntimeContext) ReserveSlots(length uintptr) {
+ c.nested = true
+ if uintptr(len(c.Slots)) < length*slotWords {
+ c.growSlots(length)
+ }
+}
+
+//go:noinline
+func (c *RuntimeContext) growSlots(length uintptr) {
+ c.Slots = append(c.Slots, make([]uintptr, int(length)*slotWords-len(c.Slots))...)
+}
+
+// Ptr returns the pointer to the slots.
+// It is unsafe.Pointer, not uintptr, so that the address of a slot is calculated by unsafe.Add,
+// which the compiler folds into the addressing mode of the load / store of the slot.
+func (c *RuntimeContext) Ptr() unsafe.Pointer {
+ header := (*runtime.SliceHeader)(unsafe.Pointer(&c.Slots))
+ return header.Data
}
func TakeRuntimeContext() *RuntimeContext {
@@ -101,5 +212,29 @@ func TakeRuntimeContext() *RuntimeContext {
}
func ReleaseRuntimeContext(ctx *RuntimeContext) {
+ // The context of a call must neither be kept by the pool nor be seen by the next call,
+ // which may not be given a context at all.
+ ctx.Option.Context = nil
+ ctx.releaseValues()
runtimeContextPool.Put(ctx)
}
+
+// releaseValues clears every pointer to the values which were encoded, so that the pool doesn't keep them alive.
+func (c *RuntimeContext) releaseValues() {
+ c.topValue = nil
+ c.mapDepth = 0
+ if c.nested {
+ // what only the frames of an interface value and of a recursive type use.
+ clear(c.SeenPtr[:cap(c.SeenPtr)])
+ c.nested = false
+ }
+}
+
+// marshalerContext returns the context to call MarshalJSON(context.Context) with.
+// It is never nil, also for a call which is not given a context.
+func (c *RuntimeContext) marshalerContext() context.Context {
+ if c.Option.Context == nil {
+ return context.Background()
+ }
+ return c.Option.Context
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/encoder.go b/vendor/github.com/goccy/go-json/internal/encoder/encoder.go
index b436f5b21..9a124735e 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/encoder.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/encoder.go
@@ -8,53 +8,17 @@ import (
"fmt"
"math"
"reflect"
+ "slices"
"strconv"
"strings"
"sync"
+ "unicode/utf8"
"unsafe"
"github.com/goccy/go-json/internal/errors"
"github.com/goccy/go-json/internal/runtime"
)
-func (t OpType) IsMultipleOpHead() bool {
- switch t {
- case OpStructHead:
- return true
- case OpStructHeadSlice:
- return true
- case OpStructHeadArray:
- return true
- case OpStructHeadMap:
- return true
- case OpStructHeadStruct:
- return true
- case OpStructHeadOmitEmpty:
- return true
- case OpStructHeadOmitEmptySlice:
- return true
- case OpStructHeadOmitEmptyArray:
- return true
- case OpStructHeadOmitEmptyMap:
- return true
- case OpStructHeadOmitEmptyStruct:
- return true
- case OpStructHeadSlicePtr:
- return true
- case OpStructHeadOmitEmptySlicePtr:
- return true
- case OpStructHeadArrayPtr:
- return true
- case OpStructHeadOmitEmptyArrayPtr:
- return true
- case OpStructHeadMapPtr:
- return true
- case OpStructHeadOmitEmptyMapPtr:
- return true
- }
- return false
-}
-
func (t OpType) IsMultipleOpField() bool {
switch t {
case OpStructField:
@@ -94,16 +58,101 @@ func (t OpType) IsMultipleOpField() bool {
}
type OpcodeSet struct {
- Type *runtime.Type
+ Type reflect.Type
+ // IfaceIndir is whether a value of Type is stored indirectly in an interface value.
+ // It is decided when the type is compiled, because deciding it is not cheap.
+ IfaceIndir bool
+ // DataWordIsAddr is whether the data word of an interface value of Type is the address of the value
+ // which the opcodes take: the type is stored indirectly, or it is a pointer, which is the address of
+ // the value it points to.
+ DataWordIsAddr bool
NoescapeKeyCode *Opcode
EscapeKeyCode *Opcode
InterfaceNoescapeKeyCode *Opcode
InterfaceEscapeKeyCode *Opcode
CodeLength int
EndCode *Opcode
- Code Code
- QueryCache map[string]*OpcodeSet
- cacheMu sync.RWMutex
+ // Scalar is the opcode of the value if the type is encoded by a single opcode of a scalar ( a number,
+ // a string, a bool, ... ), or nil. Such a value held by an interface value is encoded without a frame.
+ Scalar *Opcode
+ Code Code
+ QueryCache map[string]*OpcodeSet
+ // values is the pool of the values of Type in the heap, which MarshalOf copies its argument to.
+ values sync.Pool
+ cacheMu sync.RWMutex
+}
+
+// ValueShape classifies a type by what a nil data word of an interface value of the type means.
+type ValueShape uint
+
+const (
+ // ValueShapePointer is the type whose nil data word is encoded as null: a pointer, a map, ...
+ ValueShapePointer ValueShape = iota
+ // ValueShapeAggregate is the type whose nil data word is a value to encode, if the type is stored directly
+ // in an interface value:
+ // - a struct or an array which consists of a single pointer. The pointer is nil, not the value.
+ // - a map which has a marshaler. encoding/json writes null instead of calling the marshaler
+ // only for a nil pointer, so the marshaler of a nil map is called.
+ ValueShapeAggregate
+)
+
+// ShapeOf returns the shape of the type given by the pointer to its type descriptor.
+//
+// ShapeOf and IfaceIndir are functions of their own, not a part of the VM, and the VM calls them in the
+// same form as it did before, because any change of the code of the VM changes the register allocation
+// of the whole VM.
+//
+//go:noinline
+func ShapeOf(typ unsafe.Pointer) ValueShape {
+ switch runtime.TypeOfPtr(typ).Kind() {
+ case reflect.Struct, reflect.Array:
+ return ValueShapeAggregate
+ case reflect.Map:
+ // whether the type has a marshaler was decided when the type was compiled.
+ codeSet, err := compileToGetUnfilteredCodeSet(uintptr(typ), false)
+ if err != nil {
+ // the VM compiles the type right after this, and it reports the error.
+ return ValueShapeAggregate
+ }
+ switch codeSet.Code.Kind() {
+ case CodeKindMarshalJSON, CodeKindMarshalText:
+ return ValueShapeAggregate
+ }
+ }
+ return ValueShapePointer
+}
+
+// IfaceIndir reports whether a value of the type is stored indirectly in an interface value.
+// It is decided only once per type, when the type is compiled.
+//
+//go:noinline
+func IfaceIndir(typ unsafe.Pointer) bool {
+ codeSet, err := compileToGetUnfilteredCodeSet(uintptr(typ), false)
+ if err != nil {
+ // the VM compiles the type right after this, and it reports the error.
+ return false
+ }
+ return codeSet.IfaceIndir
+}
+
+// TakeValue returns the address of a zero value of Type in the heap.
+//
+// The runtime context keeps the value of the type it encoded last, because taking one from a sync.Pool costs
+// as much as a small allocation, and a runtime context is already taken from a pool.
+func (s *OpcodeSet) TakeValue(ctx *RuntimeContext) unsafe.Pointer {
+ if ctx.valueCodeSet == s {
+ return ctx.value
+ }
+ if ctx.valueCodeSet != nil {
+ ctx.valueCodeSet.values.Put(ctx.value)
+ }
+ ctx.valueCodeSet = s
+ if p := s.values.Get(); p != nil {
+ ctx.value = p.(unsafe.Pointer)
+ } else {
+ ctx.value = reflect.New(s.Type).UnsafePointer()
+ }
+ return ctx.value
}
func (s *OpcodeSet) getQueryCache(hash string) *OpcodeSet {
@@ -124,77 +173,21 @@ type CompiledCode struct {
Linked bool // whether recursive code already have linked
CurLen uintptr
NextLen uintptr
+ // Embedded is whether the recursive struct is embedded in the struct which jumps to it.
+ // The code to jump to is only the fields of the struct then: it has neither the braces nor the check of nil.
+ Embedded bool
}
const StartDetectingCyclesAfter = 1000
-func Load(base uintptr, idx uintptr) uintptr {
- addr := base + idx
- return **(**uintptr)(unsafe.Pointer(&addr))
-}
-
-func Store(base uintptr, idx uintptr, p uintptr) {
- addr := base + idx
- **(**uintptr)(unsafe.Pointer(&addr)) = p
-}
-
-func LoadNPtr(base uintptr, idx uintptr, ptrNum int) uintptr {
- addr := base + idx
- p := **(**uintptr)(unsafe.Pointer(&addr))
- if p == 0 {
- return 0
- }
- return PtrToPtr(p)
- /*
- for i := 0; i < ptrNum; i++ {
- if p == 0 {
- return p
- }
- p = PtrToPtr(p)
- }
- return p
- */
-}
-
-func PtrToUint64(p uintptr) uint64 { return **(**uint64)(unsafe.Pointer(&p)) }
-func PtrToFloat32(p uintptr) float32 { return **(**float32)(unsafe.Pointer(&p)) }
-func PtrToFloat64(p uintptr) float64 { return **(**float64)(unsafe.Pointer(&p)) }
-func PtrToBool(p uintptr) bool { return **(**bool)(unsafe.Pointer(&p)) }
-func PtrToBytes(p uintptr) []byte { return **(**[]byte)(unsafe.Pointer(&p)) }
-func PtrToNumber(p uintptr) json.Number { return **(**json.Number)(unsafe.Pointer(&p)) }
-func PtrToString(p uintptr) string { return **(**string)(unsafe.Pointer(&p)) }
-func PtrToSlice(p uintptr) *runtime.SliceHeader { return *(**runtime.SliceHeader)(unsafe.Pointer(&p)) }
-func PtrToPtr(p uintptr) uintptr {
- return uintptr(**(**unsafe.Pointer)(unsafe.Pointer(&p)))
-}
-func PtrToNPtr(p uintptr, ptrNum int) uintptr {
- for i := 0; i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = PtrToPtr(p)
- }
- return p
-}
-
-func PtrToUnsafePtr(p uintptr) unsafe.Pointer {
- return *(*unsafe.Pointer)(unsafe.Pointer(&p))
-}
-func PtrToInterface(code *Opcode, p uintptr) interface{} {
- return *(*interface{})(unsafe.Pointer(&emptyInterface{
+func ErrUnsupportedValue(code *Opcode, ptr unsafe.Pointer) *errors.UnsupportedValueError {
+ v := *(*any)(unsafe.Pointer(&emptyInterface{
typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
- }))
-}
-
-func ErrUnsupportedValue(code *Opcode, ptr uintptr) *errors.UnsupportedValueError {
- v := *(*interface{})(unsafe.Pointer(&emptyInterface{
- typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&ptr)),
+ ptr: ptr,
}))
return &errors.UnsupportedValueError{
Value: reflect.ValueOf(v),
- Str: fmt.Sprintf("encountered a cycle via %s", code.Type),
+ Str: fmt.Sprintf("encountered a cycle via %s", runtime.TypeOfPtr(code.Type)),
}
}
@@ -207,13 +200,13 @@ func ErrUnsupportedFloat(v float64) *errors.UnsupportedValueError {
func ErrMarshalerWithCode(code *Opcode, err error) *errors.MarshalerError {
return &errors.MarshalerError{
- Type: runtime.RType2Type(code.Type),
+ Type: runtime.TypeOfPtr(code.Type),
Err: err,
}
}
type emptyInterface struct {
- typ *runtime.Type
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
@@ -224,92 +217,213 @@ type MapItem struct {
type Mapslice struct {
Items []MapItem
+ // escaped is whether a text was escaped while the entries of a map whose keys are texts were encoded ( see
+ // appendText ): a key, or a text of a value, which tells that a key may have an escape.
+ escaped bool
+}
+
+// Sort sorts the items by their keys, which are the names of the keys as encoding/json sorts them: an encoded
+// key is in the order of its name unless it has an escape, and then the names are decoded to be sorted by.
+// A text which was escaped while the entries were encoded tells that a key may have one ( see appendText ).
+//
+// It is not sort.Sort, which calls Less and Swap through an interface for every comparison:
+// the maps to encode are small in most cases, and the sort was a tenth of the time to encode one.
+func (m *Mapslice) Sort() {
+ items := m.Items
+ if m.escaped {
+ sortMapItemsByNames(items)
+ return
+ }
+ if len(items) > maxItemsOfInsertionSort {
+ slices.SortFunc(items, func(a, b MapItem) int {
+ return bytes.Compare(a.Key, b.Key)
+ })
+ return
+ }
+ insertionSortMapItems(items)
+}
+
+func insertionSortMapItems(items []MapItem) {
+ for i := 1; i < len(items); i++ {
+ if bytes.Compare(items[i-1].Key, items[i].Key) <= 0 {
+ continue
+ }
+ item := items[i]
+ j := i
+ for ; j > 0 && bytes.Compare(items[j-1].Key, item.Key) > 0; j-- {
+ items[j] = items[j-1]
+ }
+ items[j] = item
+ }
+}
+
+// sortMapItemsByNames sorts the items by the names their encoded keys are of, which one of them has an escape
+// for: the escape of a character is not in the order of the character.
+func sortMapItemsByNames(items []MapItem) {
+ type named struct {
+ name string
+ item MapItem
+ }
+ byName := make([]named, len(items))
+ for i, item := range items {
+ byName[i] = named{name: encodedKeyName(item.Key), item: item}
+ }
+ slices.SortStableFunc(byName, func(a, b named) int {
+ return strings.Compare(a.name, b.name)
+ })
+ for i := range byName {
+ items[i] = byName[i].item
+ }
+}
+
+// encodedKeyName returns the name of an encoded key: the string from its first quote, whose escapes are the
+// ones AppendString writes, decoded. What follows the string, and what precedes its quote, as the codes of a
+// color, is not of the name.
+func encodedKeyName(key []byte) string {
+ start := bytes.IndexByte(key, '"')
+ if start < 0 {
+ return string(key)
+ }
+ var name []byte
+ for i := start + 1; i < len(key); i++ {
+ c := key[i]
+ switch {
+ case c == '"':
+ return string(name)
+ case c != '\\' || i+1 == len(key):
+ name = append(name, c)
+ case key[i+1] == 'u' && i+5 < len(key):
+ r, err := strconv.ParseUint(string(key[i+2:i+6]), 16, 16)
+ if err != nil {
+ name = append(name, c)
+ continue
+ }
+ name = utf8.AppendRune(name, rune(r))
+ i += 5
+ default:
+ i++
+ switch e := key[i]; e {
+ case 'n':
+ name = append(name, '\n')
+ case 'r':
+ name = append(name, '\r')
+ case 't':
+ name = append(name, '\t')
+ case 'b':
+ name = append(name, '\b')
+ case 'f':
+ name = append(name, '\f')
+ default:
+ name = append(name, e)
+ }
+ }
+ }
+ return string(name)
}
-func (m *Mapslice) Len() int {
- return len(m.Items)
-}
-
-func (m *Mapslice) Less(i, j int) bool {
- return bytes.Compare(m.Items[i].Key, m.Items[j].Key) < 0
-}
-
-func (m *Mapslice) Swap(i, j int) {
- m.Items[i], m.Items[j] = m.Items[j], m.Items[i]
-}
-
-//nolint:structcheck,unused
-type mapIter struct {
- key unsafe.Pointer
- elem unsafe.Pointer
- t unsafe.Pointer
- h unsafe.Pointer
- buckets unsafe.Pointer
- bptr unsafe.Pointer
- overflow unsafe.Pointer
- oldoverflow unsafe.Pointer
- startBucket uintptr
- offset uint8
- wrapped bool
- B uint8
- i uint8
- bucket uintptr
- checkBucket uintptr
-}
+// maxItemsOfInsertionSort is the number of the items up to which the insertion sort is used.
+// With keys which are random in their content and in their length, it is faster than slices.SortFunc up to
+// 24 items and slower from 32 items ( BenchmarkVariant_MapSort ).
+const maxItemsOfInsertionSort = 16
+// MapContext is what the VM encodes a map from: the entries read from the map ( MapLayout.Collect ), and
+// the state of the entry being encoded.
type MapContext struct {
+ layout *MapLayout
+ // Keys are the keys of the entries, for keys of a string kind; RawKeys are the bytes of the keys of another
+ // kind, keySize each; Values are the bytes of the values, valueSize each. The copies of the values may hold
+ // pointers which the GC doesn't see, as the slots of the VM do: the map holds the values while they are
+ // encoded.
+ Keys []string
+ RawKeys []byte
+ Values []byte
+ // Order is the entries sorted by their keys ( SortKeys ), for keys of a string kind; Sorted is whether
+ // the entries are encoded in that order.
+ Order []int32
+ prefixes []uint64 // the first bytes of the keys as numbers, while they are sorted
+ Sorted bool
+ // DirectEntries is whether the entries of a sorted map are written directly by one call of the VM, up to one
+ // whose value is left to its opcodes, as the entries of a map which is not sorted are written as it is read:
+ // the values are written by one opcode of a scalar, or are of interface{} ( see MapLayout ).
+ DirectEntries bool
+ Len int
+ Idx int
+ // The entries of a sorted map whose keys are not of a string kind are encoded as they come and put in
+ // the order of their encoded keys after: Start is where the key or the value being written starts,
+ // First is where the entries start in the buffer, Slice has the entries and Buf is where they are copied.
Start int
First int
- Idx int
Slice *Mapslice
+ items []MapItem // what Slice.Items is made of, kept between the maps
Buf []byte
- Len int
- Iter mapIter
+ // what the collector by reflect.MapIter works with: here so that nothing is allocated for a map.
+ iter reflect.MapIter
+ keyIface any
+ valueIface any
}
-var mapContextPool = sync.Pool{
- New: func() interface{} {
- return &MapContext{
- Slice: &Mapslice{},
- }
- },
-}
-
-func NewMapContext(mapLen int, unorderedMap bool) *MapContext {
- ctx := mapContextPool.Get().(*MapContext)
- if !unorderedMap {
- if len(ctx.Slice.Items) < mapLen {
- ctx.Slice.Items = make([]MapItem, mapLen)
- } else {
- ctx.Slice.Items = ctx.Slice.Items[:mapLen]
- }
+// NewMapContext returns the context to encode a map: the runtime context has one for each level of the maps
+// nested in each other, kept from a call to the next, and refers to it while the VM has it in a slot, which
+// the GC doesn't see.
+func NewMapContext(rctx *RuntimeContext) *MapContext {
+ if rctx.mapDepth == len(rctx.mapContexts) {
+ rctx.mapContexts = append(rctx.mapContexts, &MapContext{Slice: &Mapslice{}})
}
+ ctx := rctx.mapContexts[rctx.mapDepth]
+ rctx.mapDepth++
ctx.Buf = ctx.Buf[:0]
- ctx.Iter = mapIter{}
ctx.Idx = 0
- ctx.Len = mapLen
+ ctx.Sorted = false
+ ctx.DirectEntries = false
+ // Items is set by SortByEncodedKeys, and tells the VM the entries are put in that order.
+ ctx.Slice.Items = nil
return ctx
}
-func ReleaseMapContext(c *MapContext) {
- mapContextPool.Put(c)
+// ScalarValue is whether the values of the map are written by one opcode of a scalar ( MapLayout.ScalarValue ).
+func (c *MapContext) ScalarValue() bool {
+ return c.layout.ScalarValue
}
-//go:linkname MapIterInit runtime.mapiterinit
-//go:noescape
-func MapIterInit(mapType *runtime.Type, m unsafe.Pointer, it *mapIter)
+// SortByEncodedKeys makes the context put the entries in the order of their encoded keys, for a sorted map
+// whose keys are not of a string kind: the VM records the entries in Slice as it encodes them.
+func (c *MapContext) SortByEncodedKeys() {
+ if cap(c.items) < c.Len {
+ c.items = make([]MapItem, c.Len)
+ }
+ c.Slice.Items = c.items[:c.Len]
+ c.Slice.escaped = false
+}
-//go:linkname MapIterKey reflect.mapiterkey
-//go:noescape
-func MapIterKey(it *mapIter) unsafe.Pointer
+// appendText appends the text of a marshaler or of the key of a map as a string. A text which is escaped is
+// written longer than itself and its quotes: that tells the map being encoded, if any, that its keys are to be
+// sorted by their names ( see Mapslice.Sort ).
+func appendText(ctx *RuntimeContext, b []byte, text string) []byte {
+ n := len(b)
+ b = AppendString(ctx, b, text)
+ if len(b)-n != len(text)+2 {
+ ctx.textEscaped()
+ }
+ return b
+}
-//go:linkname MapIterNext reflect.mapiternext
-//go:noescape
-func MapIterNext(it *mapIter)
+// textEscaped tells the map being encoded, if any, that a text was escaped ( see appendText ).
+func (c *RuntimeContext) textEscaped() {
+ if c.mapDepth == 0 {
+ return
+ }
+ if m := c.mapContexts[c.mapDepth-1]; m.layout != nil && m.layout.KeysMayEscape {
+ m.Slice.escaped = true
+ }
+}
-//go:linkname MapLen reflect.maplen
-//go:noescape
-func MapLen(m unsafe.Pointer) int
+func ReleaseMapContext(rctx *RuntimeContext, c *MapContext) {
+ // a map is always released before the maps it is in.
+ rctx.mapDepth--
+ // the keys refer to the map, which the context must not keep alive.
+ clear(c.Keys)
+ c.Keys = c.Keys[:0]
+}
func AppendByteSlice(_ *RuntimeContext, b []byte, src []byte) []byte {
if src == nil {
@@ -340,7 +454,7 @@ func AppendFloat32(_ *RuntimeContext, b []byte, v float32) []byte {
fmt = 'e'
}
}
- return strconv.AppendFloat(b, f64, fmt, -1, 32)
+ return appendFloatOfFormat(b, f64, fmt, 32)
}
func AppendFloat64(_ *RuntimeContext, b []byte, v float64) []byte {
@@ -352,7 +466,21 @@ func AppendFloat64(_ *RuntimeContext, b []byte, v float64) []byte {
fmt = 'e'
}
}
- return strconv.AppendFloat(b, v, fmt, -1, 64)
+ return appendFloatOfFormat(b, v, fmt, 64)
+}
+
+// appendFloatOfFormat appends the float in the format, as encoding/json does: the exponent of the 'e' format
+// has no leading zero, so 1e-07 is written as 1e-7.
+func appendFloatOfFormat(b []byte, v float64, fmt byte, bits int) []byte {
+ b = strconv.AppendFloat(b, v, fmt, -1, bits)
+ if fmt == 'e' {
+ n := len(b)
+ if n >= 4 && b[n-4] == 'e' && b[n-3] == '-' && b[n-2] == '0' {
+ b[n-2] = b[n-1]
+ b = b[:n-1]
+ }
+ }
+ return b
}
func AppendBool(_ *RuntimeContext, b []byte, v bool) []byte {
@@ -395,16 +523,80 @@ func AppendNumber(_ *RuntimeContext, b []byte, n json.Number) ([]byte, error) {
return b, nil
}
-func AppendMarshalJSON(ctx *RuntimeContext, code *Opcode, b []byte, v interface{}) ([]byte, error) {
+// addrForMarshaler returns the pointer to the value held by v, to call a marshaler with a pointer receiver.
+//
+// The VM makes v from the address of the value, so the data word of v is that address unless the type is
+// stored directly in an interface value. Only a pointer-sized type can be stored directly, so for the other
+// sizes the pointer is made from the data word: the marshaler is called with the original value, as
+// encoding/json does, and nothing is allocated. A pointer-sized value is copied, because its data word
+// may be the value itself.
+func addrForMarshaler(v any, rv reflect.Value) reflect.Value {
+ if rv.CanAddr() {
+ return rv.Addr()
+ }
+ typ := rv.Type()
+ if typ.Size() != unsafe.Sizeof(unsafe.Pointer(nil)) {
+ return reflect.NewAt(typ, (*emptyInterface)(unsafe.Pointer(&v)).ptr)
+ }
+ newV := reflect.New(typ)
+ newV.Elem().Set(rv)
+ return newV
+}
+
+// AppendMarshalJSON appends what MarshalJSON of the value returns, compacted. p is the data word of the
+// interface value of the type of the opcode: the address of the value, or the pointer for a pointer type.
+func AppendMarshalJSON(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ m := code.Marshaler
+ if m == nil {
+ return appendMarshalJSONByInterface(ctx, code, b, interfaceOf(code, p))
+ }
+ if m.nilIsNull && p == nil {
+ return AppendNull(ctx, b), nil
+ }
+ if m.appendOutput != nil {
+ // the output of a type of the standard library is valid and compact: it is written as it is.
+ if out, ok := m.appendOutput(b, p); ok {
+ return out, nil
+ }
+ }
+ var bb []byte
+ var err error
+ if (code.Flags & MarshalerContextFlags) != 0 {
+ stdctx := ctx.marshalerContext()
+ if ctx.Option.Flag&FieldQueryOption != 0 {
+ stdctx = SetFieldQueryToContext(stdctx, code.FieldQuery)
+ }
+ bb, err = m.callContext(p, stdctx)
+ } else {
+ bb, err = m.call(p)
+ }
+ if err != nil {
+ return nil, &errors.MarshalerError{Type: m.recv, Err: err}
+ }
+ escape := (ctx.Option.Flag & HTMLEscapeOption) != 0
+ if out, ok := appendCompactOutput(b, bb, escape, m.trusted); ok {
+ // the output is compact and valid: it is copied as it is.
+ return out, nil
+ }
+ marshalBuf := ctx.MarshalBuf[:0]
+ marshalBuf = append(append(marshalBuf, bb...), nul)
+ compactedBuf, err := compact(b, marshalBuf, escape)
+ if err != nil {
+ return nil, err
+ }
+ ctx.MarshalBuf = marshalBuf
+ return compactedBuf, nil
+}
+
+// interfaceOf returns the interface value of the type of the opcode whose data word is p.
+func interfaceOf(code *Opcode, p unsafe.Pointer) any {
+ return *(*any)(unsafe.Pointer(&emptyInterface{typ: code.Type, ptr: p}))
+}
+
+func appendMarshalJSONByInterface(ctx *RuntimeContext, code *Opcode, b []byte, v any) ([]byte, error) {
rv := reflect.ValueOf(v) // convert by dynamic interface type
if (code.Flags & AddrForMarshalerFlags) != 0 {
- if rv.CanAddr() {
- rv = rv.Addr()
- } else {
- newV := reflect.New(rv.Type())
- newV.Elem().Set(rv)
- rv = newV
- }
+ rv = addrForMarshaler(v, rv)
}
if rv.Kind() == reflect.Ptr && rv.IsNil() {
@@ -418,7 +610,7 @@ func AppendMarshalJSON(ctx *RuntimeContext, code *Opcode, b []byte, v interface{
if !ok {
return AppendNull(ctx, b), nil
}
- stdctx := ctx.Option.Context
+ stdctx := ctx.marshalerContext()
if ctx.Option.Flag&FieldQueryOption != 0 {
stdctx = SetFieldQueryToContext(stdctx, code.FieldQuery)
}
@@ -448,16 +640,42 @@ func AppendMarshalJSON(ctx *RuntimeContext, code *Opcode, b []byte, v interface{
return compactedBuf, nil
}
-func AppendMarshalJSONIndent(ctx *RuntimeContext, code *Opcode, b []byte, v interface{}) ([]byte, error) {
+func AppendMarshalJSONIndent(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ m := code.Marshaler
+ if m == nil {
+ return appendMarshalJSONIndentByInterface(ctx, code, b, interfaceOf(code, p))
+ }
+ if m.nilIsNull && p == nil {
+ return AppendNull(ctx, b), nil
+ }
+ if m.appendOutput != nil {
+ // the output of a type of the standard library is one token, which has nothing to indent.
+ if out, ok := m.appendOutput(b, p); ok {
+ return out, nil
+ }
+ }
+ var bb []byte
+ var err error
+ if (code.Flags & MarshalerContextFlags) != 0 {
+ bb, err = m.callContext(p, ctx.marshalerContext())
+ } else {
+ bb, err = m.call(p)
+ }
+ if err != nil {
+ return nil, &errors.MarshalerError{Type: m.recv, Err: err}
+ }
+ return appendIndentedMarshalJSON(ctx, code, b, bb)
+}
+
+func appendMarshalJSONIndentByInterface(ctx *RuntimeContext, code *Opcode, b []byte, v any) ([]byte, error) {
rv := reflect.ValueOf(v) // convert by dynamic interface type
if (code.Flags & AddrForMarshalerFlags) != 0 {
- if rv.CanAddr() {
- rv = rv.Addr()
- } else {
- newV := reflect.New(rv.Type())
- newV.Elem().Set(rv)
- rv = newV
- }
+ rv = addrForMarshaler(v, rv)
+ }
+ // a nil pointer is null, as encoding/json does. The VM gives the address of the pointer,
+ // so it is not known to be nil until here.
+ if rv.Kind() == reflect.Ptr && rv.IsNil() {
+ return AppendNull(ctx, b), nil
}
v = rv.Interface()
var bb []byte
@@ -466,7 +684,7 @@ func AppendMarshalJSONIndent(ctx *RuntimeContext, code *Opcode, b []byte, v inte
if !ok {
return AppendNull(ctx, b), nil
}
- b, err := marshaler.MarshalJSON(ctx.Option.Context)
+ b, err := marshaler.MarshalJSON(ctx.marshalerContext())
if err != nil {
return nil, &errors.MarshalerError{Type: reflect.TypeOf(v), Err: err}
}
@@ -482,6 +700,10 @@ func AppendMarshalJSONIndent(ctx *RuntimeContext, code *Opcode, b []byte, v inte
}
bb = b
}
+ return appendIndentedMarshalJSON(ctx, code, b, bb)
+}
+
+func appendIndentedMarshalJSON(ctx *RuntimeContext, code *Opcode, b []byte, bb []byte) ([]byte, error) {
marshalBuf := ctx.MarshalBuf[:0]
marshalBuf = append(append(marshalBuf, bb...), nul)
indentedBuf, err := doIndent(
@@ -492,45 +714,58 @@ func AppendMarshalJSONIndent(ctx *RuntimeContext, code *Opcode, b []byte, v inte
(ctx.Option.Flag&HTMLEscapeOption) != 0,
)
if err != nil {
- return nil, &errors.MarshalerError{Type: reflect.TypeOf(v), Err: err}
+ return nil, &errors.MarshalerError{Type: runtime.TypeOfPtr(code.Type), Err: err}
}
ctx.MarshalBuf = marshalBuf
return indentedBuf, nil
}
-func AppendMarshalText(ctx *RuntimeContext, code *Opcode, b []byte, v interface{}) ([]byte, error) {
- rv := reflect.ValueOf(v) // convert by dynamic interface type
- if (code.Flags & AddrForMarshalerFlags) != 0 {
- if rv.CanAddr() {
- rv = rv.Addr()
- } else {
- newV := reflect.New(rv.Type())
- newV.Elem().Set(rv)
- rv = newV
+// AppendMarshalText appends what MarshalText of the value returns, as a string. p is the data word of the
+// interface value of the type of the opcode: the address of the value, or the pointer for a pointer type.
+func AppendMarshalText(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ m := code.Marshaler
+ if m == nil {
+ if code.Flags&InterfaceMapKeyFlags != 0 {
+ return appendInterfaceMapKey(ctx, code, b, p)
+ }
+ return appendMarshalTextByInterface(ctx, code, b, interfaceOf(code, p))
+ }
+ if m.nilIsNull && p == nil {
+ return appendNilText(ctx, code, b), nil
+ }
+ var bytes []byte
+ appended := false
+ if m.appendOutput != nil {
+ // the text of a type of the standard library is appended to a buffer of the context, not allocated.
+ bytes, appended = m.appendOutput(ctx.MarshalBuf[:0], p)
+ if appended {
+ ctx.MarshalBuf = bytes
}
}
- v = rv.Interface()
- marshaler, ok := v.(encoding.TextMarshaler)
- if !ok {
- return AppendNull(ctx, b), nil
+ if !appended {
+ var err error
+ if bytes, err = m.call(p); err != nil {
+ return nil, &errors.MarshalerError{Type: m.recv, Err: err}
+ }
}
- bytes, err := marshaler.MarshalText()
- if err != nil {
- return nil, &errors.MarshalerError{Type: reflect.TypeOf(v), Err: err}
+ // appendText, written here: it is not inlined, and this is the text of the key of most maps of texts.
+ n := len(b)
+ b = AppendString(ctx, b, *(*string)(unsafe.Pointer(&bytes)))
+ if len(b)-n != len(bytes)+2 {
+ ctx.textEscaped()
}
- return AppendString(ctx, b, *(*string)(unsafe.Pointer(&bytes))), nil
+ return b, nil
}
-func AppendMarshalTextIndent(ctx *RuntimeContext, code *Opcode, b []byte, v interface{}) ([]byte, error) {
+func appendMarshalTextByInterface(ctx *RuntimeContext, code *Opcode, b []byte, v any) ([]byte, error) {
rv := reflect.ValueOf(v) // convert by dynamic interface type
if (code.Flags & AddrForMarshalerFlags) != 0 {
- if rv.CanAddr() {
- rv = rv.Addr()
- } else {
- newV := reflect.New(rv.Type())
- newV.Elem().Set(rv)
- rv = newV
- }
+ rv = addrForMarshaler(v, rv)
+ }
+ // a nil pointer is null, or "" as the name of a key, as encoding/json does. The VM gives the address of
+ // the pointer, so it is not known to be nil until here.
+ if rv.Kind() == reflect.Ptr && rv.IsNil() {
+ return appendNilText(ctx, code, b), nil
}
v = rv.Interface()
marshaler, ok := v.(encoding.TextMarshaler)
@@ -541,7 +776,21 @@ func AppendMarshalTextIndent(ctx *RuntimeContext, code *Opcode, b []byte, v inte
if err != nil {
return nil, &errors.MarshalerError{Type: reflect.TypeOf(v), Err: err}
}
- return AppendString(ctx, b, *(*string)(unsafe.Pointer(&bytes))), nil
+ return appendText(ctx, b, *(*string)(unsafe.Pointer(&bytes))), nil
+}
+
+// appendNilText appends the text of a nil pointer: null, or "" as the name of a key of a map, as
+// encoding/json writes them.
+func appendNilText(ctx *RuntimeContext, code *Opcode, b []byte) []byte {
+ if code.Flags&MapKeyFlags != 0 {
+ return append(b, `""`...)
+ }
+ return AppendNull(ctx, b)
+}
+
+// AppendMarshalTextIndent is AppendMarshalText: the text has no indent.
+func AppendMarshalTextIndent(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return AppendMarshalText(ctx, code, b, p)
}
func AppendNull(_ *RuntimeContext, b []byte) []byte {
@@ -579,7 +828,7 @@ func AppendIndent(ctx *RuntimeContext, b []byte, indent uint32) []byte {
return b
}
-func IsNilForMarshaler(v interface{}) bool {
+func IsNilForMarshaler(v any) bool {
rv := reflect.ValueOf(v)
switch rv.Kind() {
case reflect.Bool:
@@ -590,11 +839,10 @@ func IsNilForMarshaler(v interface{}) bool {
return rv.Uint() == 0
case reflect.Float32, reflect.Float64:
return math.Float64bits(rv.Float()) == 0
- case reflect.Interface, reflect.Map, reflect.Ptr, reflect.Func:
+ case reflect.Interface, reflect.Ptr, reflect.Func:
return rv.IsNil()
- case reflect.Slice:
- return rv.IsNil() || rv.Len() == 0
- case reflect.String:
+ case reflect.Array, reflect.Map, reflect.Slice, reflect.String:
+ // the same as encoding/json: they are empty if the length is zero, even if they are not nil.
return rv.Len() == 0
}
return false
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/escape_control.go b/vendor/github.com/goccy/go-json/internal/encoder/escape_control.go
new file mode 100644
index 000000000..c82f360a4
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/escape_control.go
@@ -0,0 +1,10 @@
+//go:build go1.22
+
+package encoder
+
+// backspaceEscape and formFeedEscape are the escapes of the backspace and the form feed: encoding/json since Go
+// 1.22 writes them as \b and \f.
+const (
+ backspaceEscape = `\b`
+ formFeedEscape = `\f`
+)
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/escape_control_legacy.go b/vendor/github.com/goccy/go-json/internal/encoder/escape_control_legacy.go
new file mode 100644
index 000000000..b58b4a62b
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/escape_control_legacy.go
@@ -0,0 +1,10 @@
+//go:build !go1.22
+
+package encoder
+
+// backspaceEscape and formFeedEscape are the escapes of the backspace and the form feed: encoding/json before Go
+// 1.22 writes them as the other control characters, by their code.
+const (
+ backspaceEscape = `\u0008`
+ formFeedEscape = `\u000c`
+)
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/frame.go b/vendor/github.com/goccy/go-json/internal/encoder/frame.go
new file mode 100644
index 000000000..77f84357f
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/frame.go
@@ -0,0 +1,188 @@
+package encoder
+
+import (
+ "slices"
+ "unsafe"
+)
+
+// The frames of the VM.
+//
+// The value held by an interface value and the value of a recursive type are encoded by the opcodes of their
+// own type, in a frame of slots after the frame of the opcodes which reached them. The opcode which ends
+// such a frame has three slots: the opcode to return to, the offset of the previous frame and the indent to
+// restore.
+//
+// Entering and leaving a frame is done here, not in the VM: it needs several calls and many variables, and
+// the VM, which is a large function, has to spill and restore its variables around each of them.
+
+type nonEmptyInterface struct {
+ itab *struct {
+ ityp unsafe.Pointer // static interface type
+ typ unsafe.Pointer // dynamic concrete type
+ // unused fields...
+ }
+ ptr unsafe.Pointer
+}
+
+func storeSlotPtr(base unsafe.Pointer, idx uint32, p unsafe.Pointer) {
+ *(*uintptr)(unsafe.Add(base, idx)) = uintptr(p)
+}
+
+func storeSlotInt(base unsafe.Pointer, idx uint32, v uintptr) {
+ *(*uintptr)(unsafe.Add(base, idx)) = v
+}
+
+func loadSlotPtr(base unsafe.Pointer, idx uint32) unsafe.Pointer {
+ return *(*unsafe.Pointer)(unsafe.Add(base, idx))
+}
+
+func loadSlotInt(base unsafe.Pointer, idx uint32) uintptr {
+ return *(*uintptr)(unsafe.Add(base, idx))
+}
+
+// recordSeen records the value to detect a cycle, after the nesting got deep: a cycle keeps passing the same
+// values, so it is still detected, and the values which are not nested deeply cost nothing.
+func (c *RuntimeContext) recordSeen(code *Opcode, p unsafe.Pointer) error {
+ if p != nil {
+ if slices.Contains(c.SeenPtr, p) {
+ return ErrUnsupportedValue(code, p)
+ }
+ }
+ c.SeenPtr = append(c.SeenPtr, p)
+ return nil
+}
+
+// enterFrame allocates the frame of the code after the current one, stores the value at its first slot and
+// what the end opcode restores, and returns the base of the slots of the new frame.
+func (c *RuntimeContext) enterFrame(first, end, next *Opcode, p unsafe.Pointer, curLen, nextLen uintptr, indent uint32) unsafe.Pointer {
+ oldOffset := c.SlotOffset
+ c.SlotOffset += curLen * slotSize
+ c.ReserveSlots(oldOffset/slotSize + curLen + nextLen)
+ base := unsafe.Add(c.Ptr(), c.SlotOffset)
+ storeSlotPtr(base, first.Idx, p)
+ storeSlotPtr(base, end.Idx, unsafe.Pointer(next))
+ storeSlotInt(base, end.ElemIdx, oldOffset)
+ // the indent and the tail levels of the frame left are in one slot: both are small.
+ storeSlotInt(base, end.Length, uintptr(c.BaseIndent)|uintptr(c.TailLevels)<<32)
+ c.BaseIndent = indent
+ c.TailLevels = 0
+ c.RecursiveLevel++
+ return base
+}
+
+// EnterInterface enters the frame of the value held by the interface value at p, which is the operand of
+// code. It returns the first opcode of the frame and the base of its slots, or a nil opcode if the value is
+// nil, which the caller writes as null.
+//
+// If the value is a scalar, no frame is entered: it returns the opcode of the scalar, the address of the value
+// and true, and the caller encodes the value by the opcode in its own frame. It saves the frame and two
+// dispatches for the values which JSON has in a value of interface{}.
+//
+//go:noinline
+func (c *RuntimeContext) EnterInterface(code *Opcode, p unsafe.Pointer) (*Opcode, unsafe.Pointer, bool, error) {
+ var typ, ifacePtr unsafe.Pointer
+ if code.Flags&NonEmptyInterfaceFlags != 0 {
+ iface := (*nonEmptyInterface)(p)
+ ifacePtr = iface.ptr
+ if iface.itab != nil {
+ typ = iface.itab.typ
+ }
+ } else {
+ iface := (*emptyInterface)(p)
+ ifacePtr = iface.ptr
+ typ = iface.typ
+ }
+ if ifacePtr == nil {
+ isDirectedNil := typ != nil && ShapeOf(typ) == ValueShapeAggregate && !IfaceIndir(typ)
+ if !isDirectedNil {
+ return nil, nil, false, nil
+ }
+ }
+ codeSet := c.RecentCodeSet(uintptr(typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = CompileToGetCodeSet(c, uintptr(typ))
+ if err != nil {
+ return nil, nil, false, err
+ }
+ }
+ if codeSet.Scalar != nil {
+ // a scalar is never stored directly in an interface value: the data word is its address.
+ return codeSet.Scalar, ifacePtr, true, nil
+ }
+ // after every path which doesn't go into the value, so that a record always has its end.
+ if c.RecursiveLevel > StartDetectingCyclesAfter {
+ if err := c.recordSeen(code, p); err != nil {
+ return nil, nil, false, err
+ }
+ }
+ var first *Opcode
+ if (c.Option.Flag & HTMLEscapeOption) != 0 {
+ first = codeSet.InterfaceEscapeKeyCode
+ } else {
+ first = codeSet.InterfaceNoescapeKeyCode
+ }
+ // The opcodes take the address of the value. The data word of the interface value is the address for
+ // most of the types, and the value itself for a type of a pointer shape which is not a pointer, such as a
+ // map: then the address of the data word, in the interface value at p, is the address of the value.
+ value := ifacePtr
+ if !codeSet.DataWordIsAddr {
+ value = unsafe.Add(p, unsafe.Sizeof(uintptr(0)))
+ }
+ base := c.enterFrame(first, codeSet.EndCode, code.Next, value,
+ uintptr(code.Length)+interfaceEndSlots, uintptr(codeSet.CodeLength)+interfaceEndSlots, c.BaseIndent+code.Indent)
+ return first, base, false, nil
+}
+
+// interfaceEndSlots is the number of the slots which a frame of an interface value has after the ones of
+// the code.
+const interfaceEndSlots = 3
+
+// EnterRecursive enters the frame of the value of the recursive type at p, which is the operand of code.
+// It returns the first opcode of the frame and the base of its slots.
+//
+//go:noinline
+func (c *RuntimeContext) EnterRecursive(code *Opcode, p unsafe.Pointer) (*Opcode, unsafe.Pointer, error) {
+ if c.RecursiveLevel > StartDetectingCyclesAfter {
+ if err := c.recordSeen(code, p); err != nil {
+ return nil, nil, err
+ }
+ }
+ first := code.Jmp.Code
+ indentDiffFromTop := first.Indent - 1
+ base := c.enterFrame(first, first.End.Next, code.Next, p,
+ code.Jmp.CurLen, code.Jmp.NextLen, c.BaseIndent+code.Indent-indentDiffFromTop)
+ return first, base, nil
+}
+
+// LeaveFrame leaves the frame which the end opcode ends, and returns the opcode to go on with and the base of
+// the slots of the previous frame.
+//
+//go:noinline
+func (c *RuntimeContext) LeaveFrame(end *Opcode) (*Opcode, unsafe.Pointer) {
+ base := unsafe.Add(c.Ptr(), c.SlotOffset)
+ c.RecursiveLevel--
+ if c.RecursiveLevel > StartDetectingCyclesAfter {
+ c.SeenPtr = c.SeenPtr[:len(c.SeenPtr)-1]
+ }
+ saved := loadSlotInt(base, end.Length)
+ c.BaseIndent = uint32(saved)
+ c.TailLevels = uint32(saved >> 32)
+ c.SlotOffset = loadSlotInt(base, end.ElemIdx)
+ return (*Opcode)(loadSlotPtr(base, end.Idx)), unsafe.Add(c.Ptr(), c.SlotOffset)
+}
+
+// The last field of a value of a recursive type may be a value of the same type: a list. Such a value is
+// encoded in the frame of the value it is the field of ( TailRecursiveFlags ): the slots of that value are not
+// needed any more, and the only thing left to do for it is to close its braces, which the end of the last
+// value of the list does for every value of the list. No frame is entered and left for a value of the list, so
+// the slots, the offsets and the opcode to return to are neither stored nor restored, and the end of a value
+// is not dispatched: that makes a list as cheap as a nest of values of different types. The VM does it inline,
+// as the functions here cost more than the inliner allows into it; the end opcode of the list has what the
+// indent is deeper by for a value of it.
+
+// RecordSeen records the value of a recursive type at p for the detection of cycles: the VM calls it before
+// it begins a value of a list, when the level is deep enough for the detection.
+func (c *RuntimeContext) RecordSeen(code *Opcode, p unsafe.Pointer) error {
+ return c.recordSeen(code, p)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/int.go b/vendor/github.com/goccy/go-json/internal/encoder/int.go
index 8b5febeaa..1296e7337 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/int.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/int.go
@@ -25,22 +25,20 @@
package encoder
import (
+ "math/bits"
+ "slices"
"unsafe"
)
var endianness int
+// init sets endianness by the first byte of 0xABCD in memory: 0xCD on a little-endian machine (0) and 0xAB on a
+// big-endian one (1), the only two orders of the bytes of a word which Go runs on.
func init() {
var b [2]byte
*(*uint16)(unsafe.Pointer(&b)) = uint16(0xABCD)
-
- switch b[0] {
- case 0xCD:
- endianness = 0 // LE
- case 0xAB:
- endianness = 1 // BE
- default:
- panic("could not determine endianness")
+ if b[0] == 0xAB {
+ endianness = 1
}
}
@@ -77,100 +75,193 @@ func numMask(numBitSize uint8) uint64 {
return 1<>(code.NumBitSize-1))&1 == 1
- if !negative {
- if n < 10 {
- return append(out, byte(n+'0'))
- } else if n < 100 {
- u := intLELookup[n]
- return append(out, byte(u), byte(u>>8))
- }
- } else {
- n = -n & mask
- }
-
- lookup := intLookup[endianness]
-
- var b [22]byte
- u := (*[11]uint16)(unsafe.Pointer(&b))
- i := 11
-
- for n >= 100 {
- j := n % 100
- n /= 100
- i--
- u[i] = lookup[j]
- }
-
- i--
- u[i] = lookup[n]
-
- i *= 2 // convert to byte index
- if n < 10 {
- i++ // remove leading zero
- }
if negative {
- i--
- b[i] = '-'
+ n = -n & mask
+ } else if n < 10 {
+ return append(out, byte(n+'0'))
+ } else if n < 100 {
+ u := intLELookup[n]
+ return append(out, byte(u), byte(u>>8))
+ } else if n < 10000 {
+ return appendThreeOrFourDigits(out, n)
}
-
- return append(out, b[i:]...)
+ return appendDecimal(out, n, negative)
}
-func AppendUint(_ *RuntimeContext, out []byte, p uintptr, code *Opcode) []byte {
+func AppendUint(_ *RuntimeContext, out []byte, p unsafe.Pointer, code *Opcode) []byte {
var u64 uint64
switch code.NumBitSize {
case 8:
- u64 = (uint64)(**(**uint8)(unsafe.Pointer(&p)))
+ u64 = uint64(*(*uint8)(p))
case 16:
- u64 = (uint64)(**(**uint16)(unsafe.Pointer(&p)))
+ u64 = uint64(*(*uint16)(p))
case 32:
- u64 = (uint64)(**(**uint32)(unsafe.Pointer(&p)))
+ u64 = uint64(*(*uint32)(p))
case 64:
- u64 = **(**uint64)(unsafe.Pointer(&p))
+ u64 = *(*uint64)(p)
}
- mask := numMask(code.NumBitSize)
- n := u64 & mask
+ n := u64 & numMask(code.NumBitSize)
if n < 10 {
return append(out, byte(n+'0'))
} else if n < 100 {
u := intLELookup[n]
return append(out, byte(u), byte(u>>8))
+ } else if n < 10000 {
+ return appendThreeOrFourDigits(out, n)
}
+ return appendDecimal(out, n, false)
+}
- lookup := intLookup[endianness]
+// appendThreeOrFourDigits appends n, of three or four digits, by the lookups of its digits without a loop: most of
+// the integers of JSON are small.
+func appendThreeOrFourDigits(out []byte, n uint64) []byte {
+ hi, lo := n/100, intLELookup[n%100]
+ if hi < 10 {
+ return append(out, byte(hi+'0'), byte(lo), byte(lo>>8))
+ }
+ u := intLELookup[hi]
+ return append(out, byte(u), byte(u>>8), byte(lo), byte(lo>>8))
+}
- var b [22]byte
- u := (*[11]uint16)(unsafe.Pointer(&b))
- i := 11
+// pow10 are the powers of 10 which an uint64 has, from 10^0.
+var pow10 = [20]uint64{
+ 1, 1e1, 1e2, 1e3, 1e4, 1e5, 1e6, 1e7, 1e8, 1e9,
+ 1e10, 1e11, 1e12, 1e13, 1e14, 1e15, 1e16, 1e17, 1e18, 1e19,
+}
+
+// decimalDigits returns the number of the decimal digits of n: log10 of n by the one of 2, which bits.Len64
+// gives, corrected by the power of 10 it may be short of ( 1233/4096 is log10(2) ).
+func decimalDigits(n uint64) int {
+ n |= 1
+ t := bits.Len64(n) * 1233 >> 12
+ if n < pow10[t] {
+ return t
+ }
+ return t + 1
+}
+
+// appendUpToEightDigits appends n, a positive number of up to eight digits, in decimal.
+func appendUpToEightDigits(out []byte, n uint64) []byte {
+ if n < 10000 {
+ if n < 10 {
+ return append(out, byte(n+'0'))
+ } else if n < 100 {
+ u := intLELookup[n]
+ return append(out, byte(u), byte(u>>8))
+ }
+ return appendThreeOrFourDigits(out, n)
+ }
+ hi, lo := n/10000, n%10000
+ switch {
+ case hi < 10:
+ out = append(out, byte(hi+'0'))
+ case hi < 100:
+ u := intLELookup[hi]
+ out = append(out, byte(u), byte(u>>8))
+ default:
+ out = appendThreeOrFourDigits(out, hi)
+ }
+ a, b := intLELookup[lo/100], intLELookup[lo%100]
+ return append(out, byte(a), byte(a>>8), byte(b), byte(b>>8))
+}
- for n >= 100 {
+// appendDecimal appends n in decimal, after a minus sign if negative: a positive number of five digits or more,
+// or any negative one. A number of up to sixteen digits is written by the lookups of its digits, the one of up to
+// eight digits as appendUpToEightDigits does, without its call; the digits of a larger one are written where they
+// go in out, from the last, so that nothing is copied: the number of the digits is known first.
+func appendDecimal(out []byte, n uint64, negative bool) []byte {
+ if n < 100000000 {
+ if negative {
+ out = append(out, '-')
+ }
+ if n < 10000 {
+ // a negative number of up to four digits: the positive ones are written by their callers.
+ if n < 10 {
+ return append(out, byte(n+'0'))
+ } else if n < 100 {
+ u := intLELookup[n]
+ return append(out, byte(u), byte(u>>8))
+ }
+ return appendThreeOrFourDigits(out, n)
+ }
+ // up to eight digits, as appendUpToEightDigits writes them: the first ones and the last four, of a
+ // division by 10000, by their lookups.
+ hi, lo := n/10000, n%10000
+ switch {
+ case hi < 10:
+ out = append(out, byte(hi+'0'))
+ case hi < 100:
+ u := intLELookup[hi]
+ out = append(out, byte(u), byte(u>>8))
+ default:
+ out = appendThreeOrFourDigits(out, hi)
+ }
+ a, b := intLELookup[lo/100], intLELookup[lo%100]
+ return append(out, byte(a), byte(a>>8), byte(b), byte(b>>8))
+ }
+ if n < 10000000000000000 {
+ // up to sixteen digits: the first ones of a division by 100000000 as a number of up to eight digits,
+ // then the last eight by their lookups.
+ hi, lo := n/100000000, n%100000000
+ if negative {
+ out = append(out, '-')
+ }
+ out = appendUpToEightDigits(out, hi)
+ c, d := lo/10000, lo%10000
+ a, b, e, f := intLELookup[c/100], intLELookup[c%100], intLELookup[d/100], intLELookup[d%100]
+ return append(out, byte(a), byte(a>>8), byte(b), byte(b>>8), byte(e), byte(e>>8), byte(f), byte(f>>8))
+ }
+ d := decimalDigits(n)
+ if negative {
+ d++
+ }
+ l := len(out)
+ if cap(out)-l < d {
+ out = slices.Grow(out, d)
+ }
+ out = out[:l+d]
+ base := unsafe.Pointer(unsafe.SliceData(out))
+ lookup := intLookup[endianness]
+ i := l + d
+ // four digits at a time: a division by 10000 costs what one by 100 does, so there are half as many.
+ for n >= 10000 {
+ q := n / 10000
+ r := n - q*10000
+ n = q
+ i -= 4
+ *(*uint16)(unsafe.Add(base, i)) = lookup[r/100]
+ *(*uint16)(unsafe.Add(base, i+2)) = lookup[r%100]
+ }
+ if n >= 100 {
j := n % 100
n /= 100
+ i -= 2
+ *(*uint16)(unsafe.Add(base, i)) = lookup[j]
+ }
+ if n >= 10 {
+ i -= 2
+ *(*uint16)(unsafe.Add(base, i)) = lookup[n]
+ } else {
i--
- u[i] = lookup[j]
+ *(*byte)(unsafe.Add(base, i)) = byte(n + '0')
}
-
- i--
- u[i] = lookup[n]
-
- i *= 2 // convert to byte index
- if n < 10 {
- i++ // remove leading zero
+ if negative {
+ *(*byte)(unsafe.Add(base, l)) = '-'
}
- return append(out, b[i:]...)
+ return out
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8.go b/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8.go
new file mode 100644
index 000000000..3f0aa8c32
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8.go
@@ -0,0 +1,7 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package encoder
+
+// invalidUTF8 is what a byte of a string which is not valid UTF-8 is replaced by: encoding/json of Go 1.27,
+// which is made of encoding/json/v2, writes the replacement character U+FFFD as it is, without an escape.
+const invalidUTF8 = "\ufffd"
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8_legacy.go b/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8_legacy.go
new file mode 100644
index 000000000..0bd575c1b
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/invalid_utf8_legacy.go
@@ -0,0 +1,7 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package encoder
+
+// invalidUTF8 is what a byte of a string which is not valid UTF-8 is replaced by: encoding/json before Go 1.27,
+// and with GOEXPERIMENT=nojsonv2, writes the replacement character U+FFFD escaped.
+const invalidUTF8 = `\ufffd`
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map112.go b/vendor/github.com/goccy/go-json/internal/encoder/map112.go
deleted file mode 100644
index e96ffadf7..000000000
--- a/vendor/github.com/goccy/go-json/internal/encoder/map112.go
+++ /dev/null
@@ -1,9 +0,0 @@
-//go:build !go1.13
-// +build !go1.13
-
-package encoder
-
-import "unsafe"
-
-//go:linkname MapIterValue reflect.mapitervalue
-func MapIterValue(it *mapIter) unsafe.Pointer
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map113.go b/vendor/github.com/goccy/go-json/internal/encoder/map113.go
deleted file mode 100644
index 9b69dcc36..000000000
--- a/vendor/github.com/goccy/go-json/internal/encoder/map113.go
+++ /dev/null
@@ -1,9 +0,0 @@
-//go:build go1.13
-// +build go1.13
-
-package encoder
-
-import "unsafe"
-
-//go:linkname MapIterValue reflect.mapiterelem
-func MapIterValue(it *mapIter) unsafe.Pointer
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map_collect.go b/vendor/github.com/goccy/go-json/internal/encoder/map_collect.go
new file mode 100644
index 000000000..2807e5790
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/map_collect.go
@@ -0,0 +1,359 @@
+package encoder
+
+import (
+ "encoding/binary"
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// The entries of a map are read into the map context before they are encoded: the keys and the values are
+// copied, so that the VM encodes them from the context, in the order of the map or sorted by the keys.
+//
+// The runtime has no public function which gives the entries of a map of a type known only at run time
+// without an allocation: reflect.MapIter copies a key and a value with a call of ten nanoseconds each, and
+// go-json read them through linknames of the runtime for years. Instead, a map with keys of a string kind is
+// ranged over as a map of the same layout: the layout of a map depends only on the size and the alignment of
+// the key and of the value, and the hash depends only on the key. So map[K]V, with K of a string kind and
+// V of up to 256 bytes, is read as map[string][n]uint64 by the code the compiler makes for a range: no
+// allocation, no call for an entry, and no dependence on the runtime beyond the layout of a map being what
+// its type says. A map of another key is read by reflect.MapIter, which is slower but is the public way.
+
+// MapLayout is how the VM reads the entries of a map of a type, decided when the type is compiled.
+type MapLayout struct {
+ // collect reads the entries of the map at p into the context.
+ collect func(p unsafe.Pointer, c *MapContext)
+ // StringKey is whether the keys are of a string kind: then they are in MapContext.Keys.
+ StringKey bool
+ // A map whose entries are not sorted is written by the VM as it reads the map, when its keys are of a
+ // string kind and the values are written by one opcode of a scalar ( ScalarValue: the map is ranged over
+ // as a map of a value of ValueWords words, appendMapScalarValues ), or when the values are of interface{},
+ // the map of a JSON object as a value of interface{} ( InterfaceValue: the values which hold a scalar are
+ // written, and the others are read into the context, appendMapAsRead ).
+ ScalarValue bool
+ InterfaceValue bool
+ // ValueWords is the number of the words of a value when the map is ranged over as a map of the same layout,
+ // or -1 when it is read by reflect.
+ ValueWords int
+ keySize uintptr
+ valueSize uintptr
+ // KeysMayEscape is whether an encoded key may have an escape, which puts it out of the order of its name
+ // ( see Mapslice.Sort ): the keys of a kind other than a string or an integer are texts.
+ KeysMayEscape bool
+}
+
+// MapScalarValueWords is the largest ValueWords of a value written by one opcode of a scalar: a slice of bytes.
+const MapScalarValueWords = 3
+
+// mapValueWords is the number of the words of a value up to which a map is ranged over as a map of the same
+// layout. A value of more than 128 bytes is stored out of the map by the runtime, but so is the value of the
+// map[string][n]uint64 of its size, so the layouts are still the same. Each size is a function of about a
+// kilobyte of code, so the sizes stop at twice that one of the runtime; a larger value is read by reflect.
+const mapValueWords = 32
+
+// NewMapLayout returns how the VM reads a map of the type.
+func NewMapLayout(typ reflect.Type) *MapLayout {
+ l := &MapLayout{
+ StringKey: typ.Key().Kind() == reflect.String,
+ keySize: typ.Key().Size(),
+ valueSize: typ.Elem().Size(),
+ }
+ switch typ.Key().Kind() {
+ case reflect.String, reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr:
+ // a key of a string kind is sorted by its string, unless it has MarshalText, and an integer has no escape.
+ l.KeysMayEscape = typ.Key().Implements(marshalTextType) || reflect.PointerTo(typ.Key()).Implements(marshalTextType)
+ default:
+ l.KeysMayEscape = true
+ }
+ words := (l.valueSize + 7) / 8
+ if l.StringKey && words <= mapValueWords && (mapValueIsWords || l.valueSize%8 == 0) {
+ l.collect = stringKeyCollectors[words]
+ l.valueSize = words * 8
+ l.ValueWords = int(words)
+ l.InterfaceValue = typ.Elem().Kind() == reflect.Interface && typ.Elem().NumMethod() == 0
+ } else {
+ l.collect = newReflectCollector(typ)
+ l.ValueWords = -1
+ }
+ return l
+}
+
+// collectStringKeys reads the map at p, as a map[string]V, into the context.
+func collectStringKeys[V any](p unsafe.Pointer, c *MapContext) {
+ for k, v := range *(*map[string]V)(unsafe.Pointer(&p)) {
+ c.Keys = append(c.Keys, k)
+ c.Values = append(c.Values, unsafe.Slice((*byte)(unsafe.Pointer(&v)), unsafe.Sizeof(v))...)
+ }
+}
+
+// stringKeyCollectors are the functions which read a map with keys of a string kind, by the words of a value.
+var stringKeyCollectors = [mapValueWords + 1]func(unsafe.Pointer, *MapContext){
+ collectStringKeys[[0]uint64],
+ collectStringKeys[[1]uint64],
+ collectStringKeys[[2]uint64],
+ collectStringKeys[[3]uint64],
+ collectStringKeys[[4]uint64],
+ collectStringKeys[[5]uint64],
+ collectStringKeys[[6]uint64],
+ collectStringKeys[[7]uint64],
+ collectStringKeys[[8]uint64],
+ collectStringKeys[[9]uint64],
+ collectStringKeys[[10]uint64],
+ collectStringKeys[[11]uint64],
+ collectStringKeys[[12]uint64],
+ collectStringKeys[[13]uint64],
+ collectStringKeys[[14]uint64],
+ collectStringKeys[[15]uint64],
+ collectStringKeys[[16]uint64],
+ collectStringKeys[[17]uint64],
+ collectStringKeys[[18]uint64],
+ collectStringKeys[[19]uint64],
+ collectStringKeys[[20]uint64],
+ collectStringKeys[[21]uint64],
+ collectStringKeys[[22]uint64],
+ collectStringKeys[[23]uint64],
+ collectStringKeys[[24]uint64],
+ collectStringKeys[[25]uint64],
+ collectStringKeys[[26]uint64],
+ collectStringKeys[[27]uint64],
+ collectStringKeys[[28]uint64],
+ collectStringKeys[[29]uint64],
+ collectStringKeys[[30]uint64],
+ collectStringKeys[[31]uint64],
+ collectStringKeys[[32]uint64],
+}
+
+// newReflectCollector returns the function which reads a map of the type by reflect.MapIter: the key and the
+// value of an entry are set to interface values, which then refer to them in the map, or hold them if they
+// are of a pointer shape, without an allocation.
+func newReflectCollector(typ reflect.Type) func(unsafe.Pointer, *MapContext) {
+ keyType, valueType := typ.Key(), typ.Elem()
+ if keyType.Kind() == reflect.Interface {
+ return newInterfaceKeyCollector(typ)
+ }
+ stringKey := keyType.Kind() == reflect.String
+ keySize, valueSize := keyType.Size(), valueType.Size()
+ keyDirect, valueDirect := !runtime.IfaceIndir(keyType), !runtime.IfaceIndir(valueType)
+ // a value which is an interface value is copied to the interface value as it is: the value is the words.
+ valueIsIface := valueType.Kind() == reflect.Interface
+ typPtr := runtime.TypePtr(typ)
+ return func(p unsafe.Pointer, c *MapContext) {
+ // the map as a value which is not addressable: SetIterKey copies the key of an addressable map.
+ var mapIface any
+ *(*emptyInterface)(unsafe.Pointer(&mapIface)) = emptyInterface{typ: typPtr, ptr: p}
+ m := reflect.ValueOf(mapIface)
+ key := reflect.ValueOf(&c.keyIface).Elem()
+ value := reflect.ValueOf(&c.valueIface).Elem()
+ it := &c.iter
+ it.Reset(m)
+ for it.Next() {
+ key.SetIterKey(it)
+ value.SetIterValue(it)
+ k := ifaceData(&c.keyIface, keyDirect)
+ if stringKey {
+ c.Keys = append(c.Keys, *(*string)(k))
+ } else {
+ c.RawKeys = append(c.RawKeys, unsafe.Slice((*byte)(k), keySize)...)
+ }
+ v := ifaceData(&c.valueIface, valueDirect)
+ if valueIsIface {
+ v = unsafe.Pointer(&c.valueIface)
+ }
+ c.Values = append(c.Values, unsafe.Slice((*byte)(v), valueSize)...)
+ }
+ it.Reset(reflect.Value{})
+ c.keyIface, c.valueIface = nil, nil
+ }
+}
+
+// newInterfaceKeyCollector is newReflectCollector for a map whose keys are of an interface type: a key is the
+// words of the interface{} it is set to, whatever its interface type is ( see appendInterfaceMapKey ).
+func newInterfaceKeyCollector(typ reflect.Type) func(unsafe.Pointer, *MapContext) {
+ valueType := typ.Elem()
+ valueSize := valueType.Size()
+ valueDirect := !runtime.IfaceIndir(valueType)
+ valueIsIface := valueType.Kind() == reflect.Interface
+ typPtr := runtime.TypePtr(typ)
+ return func(p unsafe.Pointer, c *MapContext) {
+ var mapIface any
+ *(*emptyInterface)(unsafe.Pointer(&mapIface)) = emptyInterface{typ: typPtr, ptr: p}
+ m := reflect.ValueOf(mapIface)
+ key := reflect.ValueOf(&c.keyIface).Elem()
+ value := reflect.ValueOf(&c.valueIface).Elem()
+ it := &c.iter
+ it.Reset(m)
+ for it.Next() {
+ key.SetIterKey(it)
+ value.SetIterValue(it)
+ c.RawKeys = append(c.RawKeys, unsafe.Slice((*byte)(unsafe.Pointer(&c.keyIface)), unsafe.Sizeof(c.keyIface))...)
+ v := ifaceData(&c.valueIface, valueDirect)
+ if valueIsIface {
+ v = unsafe.Pointer(&c.valueIface)
+ }
+ c.Values = append(c.Values, unsafe.Slice((*byte)(v), valueSize)...)
+ }
+ it.Reset(reflect.Value{})
+ c.keyIface, c.valueIface = nil, nil
+ }
+}
+
+// ifaceData returns the address of the value held by the interface value: the data word if the value is stored
+// in it, which is the case for a value of a pointer shape, or what the data word points to.
+func ifaceData(iface *any, direct bool) unsafe.Pointer {
+ data := &(*emptyInterface)(unsafe.Pointer(iface)).ptr
+ if direct {
+ return unsafe.Pointer(data)
+ }
+ return *data
+}
+
+// Reset empties the context for the entries of a map of the layout.
+func (l *MapLayout) Reset(c *MapContext) {
+ c.Keys, c.RawKeys, c.Values = c.Keys[:0], c.RawKeys[:0], c.Values[:0]
+ c.layout = l
+}
+
+// Collect reads the entries of the map at p into the context, and returns their number.
+func (l *MapLayout) Collect(p unsafe.Pointer, c *MapContext) int {
+ l.Reset(c)
+ l.collect(p, c)
+ if l.StringKey {
+ c.Len = len(c.Keys)
+ } else {
+ c.Len = len(c.RawKeys) / int(l.keySize)
+ }
+ return c.Len
+}
+
+// MapLen returns the number of the entries of the map at p. The length of a map is in its header, whatever
+// its type, so the map is read as one of any type.
+func MapLen(p unsafe.Pointer) int {
+ return len(*(*map[struct{}]struct{})(unsafe.Pointer(&p)))
+}
+
+// KeyAt returns the address of the key of the entry: the string in Keys, or the bytes in RawKeys.
+func (c *MapContext) KeyAt(i int) unsafe.Pointer {
+ if c.layout.StringKey {
+ return unsafe.Pointer(&c.Keys[i])
+ }
+ return unsafe.Pointer(&c.RawKeys[uintptr(i)*c.layout.keySize])
+}
+
+// ValueAt returns the address of the value of the entry. A value of no size has an address all the same: the
+// opcode of a struct takes a nil one for a nil pointer.
+func (c *MapContext) ValueAt(i int) unsafe.Pointer {
+ if c.layout.valueSize == 0 {
+ return unsafe.Pointer(&c.Len)
+ }
+ return unsafe.Pointer(&c.Values[uintptr(i)*c.layout.valueSize])
+}
+
+// SortKeys sorts the entries by their keys, which are strings, as encoding/json does: Order is the entries in
+// that order.
+//
+// A comparison of two keys is by their first eight bytes as one number first, which decides it for most of
+// the keys of a JSON object, and by the strings only when those are the same: a comparison of strings is a
+// call which costs more than the rest of a sort of a small map. The sort is written here, so that the
+// comparisons are inlined into it: a sort which takes the comparison as a function, as slices.SortFunc does,
+// calls it for every one.
+func (c *MapContext) SortKeys() {
+ n := len(c.Keys)
+ if cap(c.Order) < n {
+ c.Order = make([]int32, n)
+ c.prefixes = make([]uint64, n)
+ }
+ order, prefixes, keys := c.Order[:n], c.prefixes[:n], c.Keys
+ for i, key := range keys {
+ order[i] = int32(i)
+ prefixes[i] = keyPrefix(key)
+ }
+ if n > maxItemsOfInsertionSort {
+ sortKeyOrder(order, prefixes, keys)
+ } else {
+ insertionSortKeyOrder(order, prefixes, keys)
+ }
+ c.Order = order
+}
+
+// keyLess is whether the key of the entry a comes before the one of b.
+func keyLess(a, b int32, prefixes []uint64, keys []string) bool {
+ if pa, pb := prefixes[a], prefixes[b]; pa != pb {
+ return pa < pb
+ }
+ return keys[a] < keys[b]
+}
+
+// sortKeyOrder sorts the entries of order by their keys: by quicksort, with the median of three entries as the
+// pivot, down to the parts of up to maxItemsOfInsertionSort entries, which are sorted by insertion. The smaller
+// part is sorted first, and the larger one by the loop, so that the depth is logarithmic.
+func sortKeyOrder(order []int32, prefixes []uint64, keys []string) {
+ for len(order) > maxItemsOfInsertionSort {
+ last := len(order) - 1
+ mid := last / 2
+ // the median of the first, the middle and the last entries, at the middle
+ if keyLess(order[mid], order[0], prefixes, keys) {
+ order[0], order[mid] = order[mid], order[0]
+ }
+ if keyLess(order[last], order[mid], prefixes, keys) {
+ order[mid], order[last] = order[last], order[mid]
+ if keyLess(order[mid], order[0], prefixes, keys) {
+ order[0], order[mid] = order[mid], order[0]
+ }
+ }
+ pivot := order[mid]
+ // Hoare's partition: the keys are distinct, so an entry equals the pivot only if it is the pivot.
+ i, j := 0, last
+ for {
+ for keyLess(order[i], pivot, prefixes, keys) {
+ i++
+ }
+ for keyLess(pivot, order[j], prefixes, keys) {
+ j--
+ }
+ if i >= j {
+ break
+ }
+ order[i], order[j] = order[j], order[i]
+ i++
+ j--
+ }
+ if j+1 < len(order)-j-1 {
+ sortKeyOrder(order[:j+1], prefixes, keys)
+ order = order[j+1:]
+ } else {
+ sortKeyOrder(order[j+1:], prefixes, keys)
+ order = order[:j+1]
+ }
+ }
+ insertionSortKeyOrder(order, prefixes, keys)
+}
+
+// insertionSortKeyOrder sorts the entries of order by their keys by insertion, which is the fastest sort of a few
+// entries.
+func insertionSortKeyOrder(order []int32, prefixes []uint64, keys []string) {
+ for i := 1; i < len(order); i++ {
+ e := order[i]
+ if !keyLess(e, order[i-1], prefixes, keys) {
+ continue
+ }
+ j := i
+ for ; j > 0 && keyLess(e, order[j-1], prefixes, keys); j-- {
+ order[j] = order[j-1]
+ }
+ order[j] = e
+ }
+}
+
+// keyPrefix returns the first eight bytes of the key as a number which compares as the bytes do, with zeros
+// after a shorter key: a shorter key compares as less, as it should, unless the other has zeros there, and then
+// the strings are compared.
+func keyPrefix(key string) uint64 {
+ if len(key) >= 8 {
+ return binary.BigEndian.Uint64(unsafe.Slice(unsafe.StringData(key), 8))
+ }
+ var b [8]byte
+ copy(b[:], key)
+ return binary.BigEndian.Uint64(b[:])
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map_collect_buckets.go b/vendor/github.com/goccy/go-json/internal/encoder/map_collect_buckets.go
new file mode 100644
index 000000000..27ddd49dd
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/map_collect_buckets.go
@@ -0,0 +1,6 @@
+//go:build !go1.24
+
+package encoder
+
+// mapValueIsWords: see map_collect_swiss.go.
+const mapValueIsWords = false
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map_collect_swiss.go b/vendor/github.com/goccy/go-json/internal/encoder/map_collect_swiss.go
new file mode 100644
index 000000000..2850a5a7d
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/map_collect_swiss.go
@@ -0,0 +1,8 @@
+//go:build go1.24
+
+package encoder
+
+// mapValueIsWords is whether a map may be ranged over as a map whose values are the words of its values: the
+// maps of Go 1.24 lay a value out at a multiple of a word from its key, so a value of 12 bytes is where one of
+// 16 bytes is. The maps before lay the values of a bucket out one after the other, so the size must be the same.
+const mapValueIsWords = true
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface.go b/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface.go
new file mode 100644
index 000000000..780302d3a
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface.go
@@ -0,0 +1,166 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package encoder
+
+import (
+ "encoding"
+ jsonv1 "encoding/json"
+ jsonv2 "encoding/json/v2"
+ "math"
+ "reflect"
+ "strconv"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// The keys of a map of an interface type, which encoding/json encodes when it is built on encoding/json/v2
+// ( GOEXPERIMENT=jsonv2, the default since Go 1.27; this file uses the API of Go 1.27 ): the name of a key is
+// made from its dynamic value as a value in the place of a name is, and a key whose value is not written as a
+// string is an error.
+//
+// - a string, an integer, a float32 and a float64 are their text; a float64 held by a key of interface{}
+// is not, as interface{} writes it as a number.
+// - a value with AppendText or MarshalText of its value, or of its pointer through a pointer, is its text;
+// MarshalJSON is not called for a name.
+// - a pointer is the name of its value.
+// - nil, a bool, a nil pointer, a struct, an array, a slice or a map is not a name; a complex number, a
+// channel or a function is an unsupported type.
+//
+// The keys are sorted by their names, as the keys of the maps whose keys are not strings are ( see OpMapEnd ).
+
+// interfaceMapKeys is whether a map of an interface type as its key is encoded.
+const interfaceMapKeys = true
+
+var (
+ emptyInterfaceType = reflect.TypeOf((*any)(nil)).Elem()
+ float64Type = reflect.TypeOf(float64(0))
+ textAppenderType = reflect.TypeOf((*encoding.TextAppender)(nil)).Elem()
+ jsonMarshalerType = reflect.TypeOf((*jsonv1.Marshaler)(nil)).Elem()
+ jsonMarshalerToType = reflect.TypeOf((*jsonv2.MarshalerTo)(nil)).Elem()
+)
+
+// appendInterfaceMapKey appends the name of the key of a map of an interface type as a string. p is the address
+// of the key as the map is read into the context: an interface{}, whatever the interface type of the key is
+// ( see newReflectCollector ).
+func appendInterfaceMapKey(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ keyType := runtime.TypeOfPtr(code.Type)
+ name, err := interfaceMapKeyName(keyType, reflect.NewAt(emptyInterfaceType, p).Elem())
+ if err != nil {
+ return nil, err
+ }
+ return appendText(ctx, b, name), nil
+}
+
+// interfaceMapKeyName returns the name of the key, which is a value of the interface type keyType.
+func interfaceMapKeyName(keyType reflect.Type, key reflect.Value) (string, error) {
+ // A key of an interface type with methods is set to the interface{} as the value of its interface type,
+ // which holds the dynamic value.
+ v := key
+ for v.Kind() == reflect.Interface {
+ if v.IsNil() {
+ return "", notStringMapKey(v)
+ }
+ v = v.Elem()
+ }
+ if v.Kind() == reflect.Pointer && v.IsNil() {
+ // The method of the marshaler which the interface type of the key is, if any, is called with the nil
+ // pointer. A MarshalJSON is not called for a name.
+ switch {
+ case keyType.Implements(jsonMarshalerToType), keyType.Implements(jsonMarshalerType):
+ return "", notStringMapKey(v)
+ case keyType.Implements(textAppenderType):
+ return appendTextName(v.Interface().(encoding.TextAppender))
+ case keyType.Implements(marshalTextType):
+ return marshalTextName(v.Interface().(encoding.TextMarshaler))
+ }
+ return "", notStringMapKey(v)
+ }
+ if keyType == emptyInterfaceType && v.Type() == float64Type {
+ // interface{} writes a float64 as a number, which is not a name.
+ if f := v.Float(); math.IsNaN(f) || math.IsInf(f, 0) {
+ return "", nonFiniteMapKey(v, f)
+ }
+ return "", notStringMapKey(v)
+ }
+ return mapKeyNameOf(v, false)
+}
+
+// mapKeyNameOf returns the name of the value of a key. byPointer is whether the value is the one of a pointer,
+// whose methods on the pointer are called.
+func mapKeyNameOf(v reflect.Value, byPointer bool) (string, error) {
+ t := v.Type()
+ if t.Kind() != reflect.Pointer {
+ switch {
+ case t.Implements(textAppenderType):
+ return appendTextName(v.Interface().(encoding.TextAppender))
+ case byPointer && reflect.PointerTo(t).Implements(textAppenderType):
+ return appendTextName(v.Addr().Interface().(encoding.TextAppender))
+ case t.Implements(marshalTextType):
+ return marshalTextName(v.Interface().(encoding.TextMarshaler))
+ case byPointer && reflect.PointerTo(t).Implements(marshalTextType):
+ return marshalTextName(v.Addr().Interface().(encoding.TextMarshaler))
+ }
+ }
+ switch t.Kind() {
+ case reflect.String:
+ return v.String(), nil
+ case reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64:
+ return strconv.FormatInt(v.Int(), 10), nil
+ case reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr:
+ return strconv.FormatUint(v.Uint(), 10), nil
+ case reflect.Float32, reflect.Float64:
+ f := v.Float()
+ if math.IsNaN(f) || math.IsInf(f, 0) {
+ return "", nonFiniteMapKey(v, f)
+ }
+ bits := 64
+ if t.Kind() == reflect.Float32 {
+ bits = 32
+ }
+ return string(appendFloatOfBits(nil, f, bits)), nil
+ case reflect.Pointer:
+ if v.IsNil() {
+ return "", notStringMapKey(v)
+ }
+ return mapKeyNameOf(v.Elem(), true)
+ case reflect.Complex64, reflect.Complex128, reflect.Chan, reflect.Func, reflect.UnsafePointer:
+ return "", &errors.UnsupportedTypeError{Type: t}
+ }
+ return "", notStringMapKey(v)
+}
+
+// appendFloatOfBits appends the float as AppendFloat32 or AppendFloat64 does.
+func appendFloatOfBits(b []byte, f float64, bits int) []byte {
+ if bits == 32 {
+ return AppendFloat32(nil, b, float32(f))
+ }
+ return AppendFloat64(nil, b, f)
+}
+
+func appendTextName(m encoding.TextAppender) (string, error) {
+ b, err := m.AppendText(nil)
+ if err != nil {
+ return "", errors.ErrMarshaler(reflect.TypeOf(m), err, "AppendText")
+ }
+ return string(b), nil
+}
+
+func marshalTextName(m encoding.TextMarshaler) (string, error) {
+ b, err := m.MarshalText()
+ if err != nil {
+ return "", errors.ErrMarshaler(reflect.TypeOf(m), err, "MarshalText")
+ }
+ return string(b), nil
+}
+
+// notStringMapKey is the error of a key whose value is not written as a string, as encoding/json reports it.
+func notStringMapKey(v reflect.Value) error {
+ return &errors.UnsupportedValueError{Value: v, Str: "object member name must be a string"}
+}
+
+// nonFiniteMapKey is the error of a key of a float which is not finite, as encoding/json reports it.
+func nonFiniteMapKey(v reflect.Value, f float64) error {
+ return &errors.UnsupportedValueError{Value: v, Str: strconv.FormatFloat(f, 'g', -1, 64)}
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface_legacy.go b/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface_legacy.go
new file mode 100644
index 000000000..4913b2d3c
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/map_key_interface_legacy.go
@@ -0,0 +1,39 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package encoder
+
+import (
+ "encoding"
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/errors"
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// interfaceMapKeys is whether every map of an interface type as its key is encoded: encoding/json which is not
+// built on encoding/json/v2 refuses the type of such a map, but the one of an interface type which has
+// MarshalText, whose keys are the texts of their values ( see map_key_interface.go ).
+const interfaceMapKeys = false
+
+var emptyInterfaceType = reflect.TypeOf((*any)(nil)).Elem()
+
+// appendInterfaceMapKey appends the name of the key of a map of an interface type which has MarshalText, as a
+// string: the text of its dynamic value, as encoding/json makes it. p is the address of the key as the map is
+// read into the context: an interface{}, whatever the interface type of the key is ( see newReflectCollector ).
+func appendInterfaceMapKey(ctx *RuntimeContext, code *Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ v := reflect.NewAt(emptyInterfaceType, p).Elem()
+ for v.Kind() == reflect.Interface && !v.IsNil() {
+ v = v.Elem()
+ }
+ m, ok := v.Interface().(encoding.TextMarshaler)
+ if !ok {
+ // a nil key, which has no text.
+ return nil, &errors.UnsupportedValueError{Value: v, Str: "nil key of " + runtime.TypeOfPtr(code.Type).String()}
+ }
+ text, err := m.MarshalText()
+ if err != nil {
+ return nil, errors.ErrMarshaler(v.Type(), err, "MarshalText")
+ }
+ return appendText(ctx, b, *(*string)(unsafe.Pointer(&text))), nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/marshaler.go b/vendor/github.com/goccy/go-json/internal/encoder/marshaler.go
new file mode 100644
index 000000000..b871c43ab
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/marshaler.go
@@ -0,0 +1,156 @@
+package encoder
+
+import (
+ "context"
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// A method of a marshaler is called directly, by the code of the method, instead of through the interface:
+// making the interface value, asserting the interface and calling through it cost more than the call.
+//
+// A call through an interface passes the data word of the interface value as the receiver: the value itself
+// if the type is stored directly in an interface value ( a pointer, a map, ... ), or the address of the value.
+// The opcodes of a marshaler carry that very word. The method which takes the word is found by reflect: the
+// method of the type itself for a type stored directly, or the method of the pointer to the type otherwise,
+// which is the method on the pointer or the wrapper of the method on the value. reflect.Value.Pointer gives the
+// code of a function. A func value is a pointer to a closure whose first word is the code, and the first
+// argument of a func value is passed as the receiver of a method is, so the code is called as a func value.
+
+// MarshalerCall is the method of a marshaler, as it is called with the data word of the interface value.
+type MarshalerCall struct {
+ // fn is the code of the method: it is the first word, so that a pointer to MarshalerCall is a func value.
+ fn uintptr
+ // nilIsNull is whether a nil receiver is encoded as null without a call, which is so for a pointer.
+ nilIsNull bool
+ // trusted is whether the output of MarshalJSON is valid and compact, as the one of a type of the standard
+ // library is, or of a type which has it only by embedding one ( see runtime.IsStdMarshalerType and
+ // runtime.PromotedStdMethod ): it is not checked.
+ trusted bool
+ // recv is the type of the receiver, for an error.
+ recv reflect.Type
+ // appendOutput writes what the method of a type of the standard library returns without calling it, by the
+ // appending method of the type: the output of MarshalJSON, valid and compact ( see stdJSONAppender ), or the
+ // text of MarshalText, by AppendText. It returns false, and writes nothing, when the method is to be called,
+ // as for an error, which is then the one of the method.
+ appendOutput func(b []byte, recv unsafe.Pointer) ([]byte, bool)
+}
+
+func (m *MarshalerCall) call(recv unsafe.Pointer) ([]byte, error) {
+ f := *(*func(unsafe.Pointer) ([]byte, error))(unsafe.Pointer(&m))
+ return f(recv)
+}
+
+func (m *MarshalerCall) callContext(recv unsafe.Pointer, ctx context.Context) ([]byte, error) {
+ f := *(*func(unsafe.Pointer, context.Context) ([]byte, error))(unsafe.Pointer(&m))
+ return f(recv, ctx)
+}
+
+// marshalerInterface is an interface of a marshaler, with the lookup of its method by the name of the method as a
+// constant ( see runtime.MethodLookup ): a method is never looked up by a name in a variable, so that the linker can
+// drop the methods which no one calls.
+type marshalerInterface struct {
+ typ reflect.Type
+ method runtime.MethodLookup
+}
+
+var (
+ marshalJSONInterface = &marshalerInterface{typ: marshalJSONType, method: runtime.MarshalJSONMethod}
+ marshalJSONContextInterface = &marshalerInterface{typ: marshalJSONContextType, method: runtime.MarshalJSONMethod}
+ marshalTextInterface = &marshalerInterface{typ: marshalTextType, method: runtime.MarshalTextMethod}
+ appendTextInterface = &marshalerInterface{typ: appendTextType, method: runtime.AppendTextMethod}
+)
+
+// newMarshalerCall returns the call of the method of the type of the receiver, which implements the interface.
+// It is decided when the type is compiled.
+func newMarshalerCall(recv reflect.Type, iface *marshalerInterface) *MarshalerCall {
+ fn, ok := methodCode(recv, iface)
+ if !ok {
+ return nil
+ }
+ m := &MarshalerCall{fn: fn, nilIsNull: recv.Kind() == reflect.Ptr, recv: recv}
+ if runtime.IsStdMarshalerType(recv) {
+ switch iface {
+ case marshalJSONInterface:
+ m.trusted = true
+ m.appendOutput = stdJSONAppender(recv)
+ case marshalTextInterface:
+ m.appendOutput = textAppenderOf(recv)
+ }
+ } else if origin, offset, inline, ok := runtime.PromotedStdMethod(recv, iface.method); ok {
+ // the method is the one of the embedded value of a type of the standard library, which the wrapper of the
+ // type calls: its output is trusted as that of the type, and written by its appending method from the
+ // embedded value if it is in the value, whose address is then the data word: a pointer, or a type which
+ // is not stored directly in an interface value.
+ switch iface {
+ case marshalJSONInterface:
+ m.trusted = true
+ if inline && (recv.Kind() == reflect.Pointer || runtime.IfaceIndir(recv)) {
+ m.appendOutput = embeddedAppender(stdJSONAppender(origin), offset)
+ }
+ case marshalTextInterface:
+ if inline && (recv.Kind() == reflect.Pointer || runtime.IfaceIndir(recv)) {
+ m.appendOutput = embeddedAppender(textAppenderOf(origin), offset)
+ }
+ }
+ }
+ return m
+}
+
+// embeddedAppender returns the appending function of the value embedded at the offset of the receiver, whose data
+// word is the address of the value which embeds it, or nil if the function is.
+func embeddedAppender(appendOutput func([]byte, unsafe.Pointer) ([]byte, bool), offset uintptr) func([]byte, unsafe.Pointer) ([]byte, bool) {
+ if appendOutput == nil {
+ return nil
+ }
+ return func(b []byte, recv unsafe.Pointer) ([]byte, bool) {
+ return appendOutput(b, unsafe.Add(recv, offset))
+ }
+}
+
+// methodCode returns the code of the method of the interface of the receiver type, which takes the data word of
+// the interface value.
+func methodCode(recv reflect.Type, iface *marshalerInterface) (uintptr, bool) {
+ if !recv.Implements(iface.typ) {
+ return 0, false
+ }
+ holder := recv
+ if runtime.IfaceIndir(recv) {
+ // the data word is the address of the value: the method of the pointer takes it.
+ holder = reflect.PointerTo(recv)
+ }
+ method, ok := iface.method(holder)
+ if !ok {
+ return 0, false
+ }
+ return method.Func.Pointer(), true
+}
+
+// textAppender is encoding.TextAppender, which is of Go 1.24: the types of the standard library have it from
+// that release on.
+type textAppender interface {
+ AppendText(b []byte) ([]byte, error)
+}
+
+var appendTextType = reflect.TypeOf((*textAppender)(nil)).Elem()
+
+// textAppenderOf returns the function which appends the text of a value of the type of the standard library by
+// AppendText, which appends what MarshalText returns, or nil if the type has no AppendText. AppendText fails
+// when MarshalText does: MarshalText is then called for its error.
+func textAppenderOf(recv reflect.Type) func([]byte, unsafe.Pointer) ([]byte, bool) {
+ fn, ok := methodCode(recv, appendTextInterface)
+ if !ok {
+ return nil
+ }
+ code := &fn // a func value is a pointer to its code, as MarshalerCall is
+ appendText := *(*func(unsafe.Pointer, []byte) ([]byte, error))(unsafe.Pointer(&code))
+ return func(b []byte, p unsafe.Pointer) ([]byte, bool) {
+ out, err := appendText(p, b)
+ if err != nil {
+ return b, false
+ }
+ return out, true
+ }
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/omit_zero.go b/vendor/github.com/goccy/go-json/internal/encoder/omit_zero.go
new file mode 100644
index 000000000..163482fc4
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/omit_zero.go
@@ -0,0 +1,116 @@
+package encoder
+
+import (
+ "reflect"
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// ZeroKind is what makes the value of a field zero for omitzero, as encoding/json decides it: by the IsZero
+// method of the type if it has one, and else by reflect.Value.IsZero.
+type ZeroKind uint8
+
+const (
+ ZeroNever ZeroKind = iota
+ // ZeroBits8 to ZeroBits64 are a value of 1 to 8 bytes whose bits are all zero: a bool, an integer,
+ // a pointer, a map...
+ ZeroBits8
+ ZeroBits16
+ ZeroBits32
+ ZeroBits64
+ // ZeroFloat32 and ZeroFloat64 are a float which is 0 or -0: reflect.Value.IsZero compares a float by its
+ // value.
+ ZeroFloat32
+ ZeroFloat64
+ ZeroString // a string of no byte
+ ZeroNilSlice // a nil slice
+ ZeroNilInterface // a nil interface value
+ ZeroReflect // a struct, an array or a complex number, as reflect.Value.IsZero decides
+ ZeroMethod // a type which has IsZero, which decides it
+)
+
+type isZeroer interface {
+ IsZero() bool
+}
+
+var isZeroerType = reflect.TypeOf((*isZeroer)(nil)).Elem()
+
+// zeroKindOf returns what makes a value of the type zero.
+func zeroKindOf(typ reflect.Type) ZeroKind {
+ if typ.Implements(isZeroerType) || reflect.PointerTo(typ).Implements(isZeroerType) {
+ return ZeroMethod
+ }
+ switch typ.Kind() {
+ case reflect.Bool, reflect.Int, reflect.Int8, reflect.Int16, reflect.Int32, reflect.Int64,
+ reflect.Uint, reflect.Uint8, reflect.Uint16, reflect.Uint32, reflect.Uint64, reflect.Uintptr,
+ reflect.Ptr, reflect.Map, reflect.Chan, reflect.Func, reflect.UnsafePointer:
+ // the value is zero if and only if its bits are.
+ switch typ.Size() {
+ case 1:
+ return ZeroBits8
+ case 2:
+ return ZeroBits16
+ case 4:
+ return ZeroBits32
+ case 8:
+ return ZeroBits64
+ }
+ case reflect.Float32:
+ return ZeroFloat32
+ case reflect.Float64:
+ return ZeroFloat64
+ case reflect.String:
+ return ZeroString
+ case reflect.Slice:
+ return ZeroNilSlice
+ case reflect.Interface:
+ return ZeroNilInterface
+ }
+ return ZeroReflect
+}
+
+// IsZeroField is whether the value at p, of the field of the opcode, is zero for omitzero.
+func IsZeroField(code *Opcode, p unsafe.Pointer) bool {
+ switch code.ZeroKind {
+ case ZeroBits8:
+ return *(*uint8)(p) == 0
+ case ZeroBits16:
+ return *(*uint16)(p) == 0
+ case ZeroBits32:
+ return *(*uint32)(p) == 0
+ case ZeroBits64:
+ return *(*uint64)(p) == 0
+ case ZeroFloat32:
+ return *(*float32)(p) == 0
+ case ZeroFloat64:
+ return *(*float64)(p) == 0
+ case ZeroString:
+ return len(*(*string)(p)) == 0
+ case ZeroNilSlice:
+ return (*runtime.SliceHeader)(p).Data == nil
+ case ZeroNilInterface:
+ return *(*unsafe.Pointer)(p) == nil
+ case ZeroReflect:
+ return reflect.NewAt(runtime.TypeOfPtr(code.Type), p).Elem().IsZero()
+ case ZeroMethod:
+ return isZeroByMethod(reflect.NewAt(runtime.TypeOfPtr(code.Type), p))
+ }
+ return false
+}
+
+// isZeroByMethod is whether the value which ptr points to is zero by its IsZero method, as encoding/json
+// decides it: a nil pointer, a nil interface value or one which holds a nil pointer is zero without a call.
+func isZeroByMethod(ptr reflect.Value) bool {
+ v := ptr.Elem()
+ typ := v.Type()
+ switch {
+ case typ.Kind() == reflect.Interface && typ.Implements(isZeroerType):
+ return v.IsNil() || (v.Elem().Kind() == reflect.Ptr && v.Elem().IsNil()) || v.Interface().(isZeroer).IsZero()
+ case typ.Kind() == reflect.Ptr && typ.Implements(isZeroerType):
+ return v.IsNil() || v.Interface().(isZeroer).IsZero()
+ case typ.Implements(isZeroerType):
+ return v.Interface().(isZeroer).IsZero()
+ }
+ return ptr.Interface().(isZeroer).IsZero()
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/opcode.go b/vendor/github.com/goccy/go-json/internal/encoder/opcode.go
index df22f5542..f2b95d178 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/opcode.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/opcode.go
@@ -3,6 +3,7 @@ package encoder
import (
"bytes"
"fmt"
+ "reflect"
"sort"
"strings"
"unsafe"
@@ -12,6 +13,17 @@ import (
const uintptrSize = 4 << (^uintptr(0) >> 63)
+// The offsets of the opcodes are in bytes from the head of the frame.
+const (
+ slotSize = 2 * uintptrSize // the size of Slot.
+ slotIntOffset = uintptrSize // the offset of Slot.Int.
+)
+
+var (
+ _ = [1]struct{}{}[unsafe.Sizeof(Slot{})-slotSize]
+ _ = [1]struct{}{}[unsafe.Offsetof(Slot{}.Int)-slotIntOffset]
+)
+
type OpFlags uint16
const (
@@ -25,29 +37,37 @@ const (
IsNilableTypeFlags OpFlags = 1 << 7
MarshalerContextFlags OpFlags = 1 << 8
NonEmptyInterfaceFlags OpFlags = 1 << 9
+ MapStringKeyFlags OpFlags = 1 << 10 // the key of the map is a string, written by OpMapKey itself
+ TailRecursiveFlags OpFlags = 1 << 11 // the recursive value is the last field of a value of its own type, encoded in its frame
+ InterfaceMapKeyFlags OpFlags = 1 << 12 // the key of a map of an interface type, whose name is of its dynamic value ( see appendInterfaceMapKey )
+ MapKeyFlags OpFlags = 1 << 13 // the key of a map, whose name is "" for a nil pointer, while a nil pointer value is null
)
type Opcode struct {
- Op OpType // operation type
- Idx uint32 // offset to access ptr
- Next *Opcode // next opcode
- End *Opcode // array/slice/struct/map end
- NextField *Opcode // next struct field
- Key string // struct field key
- Offset uint32 // offset size from struct header
- PtrNum uint8 // pointer number: e.g. double pointer is 2.
+ Op OpType // operation type
+ EmptyKind EmptyKind // what makes the value of the field empty for omitempty, for the generic field opcode
+ ZeroKind ZeroKind // what makes the value of the field zero for omitzero, for the generic field opcode
+ Idx uint32 // offset to access ptr
+ Next *Opcode // next opcode
+ End *Opcode // array/slice/struct/map end
+ NextField *Opcode // next struct field
+ Key string // struct field key
+ Offset uint32 // offset size from struct header
+ PtrNum uint8 // pointer number: e.g. double pointer is 2.
NumBitSize uint8
Flags OpFlags
- Type *runtime.Type // go type
- Jmp *CompiledCode // for recursive call
- FieldQuery *FieldQuery // field query for Interface / MarshalJSON / MarshalText
- ElemIdx uint32 // offset to access array/slice elem
- Length uint32 // offset to access slice length or array length
- Indent uint32 // indent number
- Size uint32 // array/slice elem size
- DisplayIdx uint32 // opcode index
- DisplayKey string // key text to display
+ Type unsafe.Pointer // pointer to the type descriptor of go type
+ Jmp *CompiledCode // for recursive call
+ Marshaler *MarshalerCall // the method of the marshaler, for MarshalJSON and MarshalText
+ FieldQuery *FieldQuery // field query for Interface / MarshalJSON / MarshalText
+ ElemIdx uint32 // offset to access array/slice elem
+ Length uint32 // offset to access slice length or array length
+ Indent uint32 // indent number
+ Size uint32 // array/slice elem size
+ DisplayIdx uint32 // opcode index
+ KeyChunk *[KeyChunkSize]byte // the key and the padding after it, which the VM copies as a chunk
+ Map *MapLayout // how the entries of the map are read, for the opcode of a map
}
func (c *Opcode) Validate() error {
@@ -87,125 +107,60 @@ func (c *Opcode) IsEnd() bool {
}
func (c *Opcode) MaxIdx() uint32 {
- max := uint32(0)
+ maxIdx := uint32(0)
for _, value := range []uint32{
c.Idx,
c.ElemIdx,
c.Length,
c.Size,
} {
- if max < value {
- max = value
+ if maxIdx < value {
+ maxIdx = value
}
}
- return max
+ return maxIdx
}
-func (c *Opcode) ToHeaderType(isString bool) OpType {
- switch c.Op {
+// ToStringOp returns the opcode which encodes the value of t as a string, for the string option of a field.
+func (t OpType) ToStringOp() OpType {
+ switch t {
case OpInt:
- if isString {
- return OpStructHeadIntString
- }
- return OpStructHeadInt
- case OpIntPtr:
- if isString {
- return OpStructHeadIntPtrString
- }
- return OpStructHeadIntPtr
+ return OpIntString
case OpUint:
- if isString {
- return OpStructHeadUintString
- }
- return OpStructHeadUint
- case OpUintPtr:
- if isString {
- return OpStructHeadUintPtrString
- }
- return OpStructHeadUintPtr
+ return OpUintString
case OpFloat32:
- if isString {
- return OpStructHeadFloat32String
- }
- return OpStructHeadFloat32
- case OpFloat32Ptr:
- if isString {
- return OpStructHeadFloat32PtrString
- }
- return OpStructHeadFloat32Ptr
+ return OpFloat32String
case OpFloat64:
- if isString {
- return OpStructHeadFloat64String
- }
- return OpStructHeadFloat64
- case OpFloat64Ptr:
- if isString {
- return OpStructHeadFloat64PtrString
- }
- return OpStructHeadFloat64Ptr
+ return OpFloat64String
+ case OpBool:
+ return OpBoolString
case OpString:
- if isString {
- return OpStructHeadStringString
- }
- return OpStructHeadString
- case OpStringPtr:
- if isString {
- return OpStructHeadStringPtrString
- }
- return OpStructHeadStringPtr
+ return OpStringString
case OpNumber:
- if isString {
- return OpStructHeadNumberString
- }
- return OpStructHeadNumber
- case OpNumberPtr:
- if isString {
- return OpStructHeadNumberPtrString
- }
- return OpStructHeadNumberPtr
- case OpBool:
- if isString {
- return OpStructHeadBoolString
- }
- return OpStructHeadBool
+ return OpNumberString
+ case OpIntPtr:
+ return OpIntPtrString
+ case OpUintPtr:
+ return OpUintPtrString
+ case OpFloat32Ptr:
+ return OpFloat32PtrString
+ case OpFloat64Ptr:
+ return OpFloat64PtrString
case OpBoolPtr:
- if isString {
- return OpStructHeadBoolPtrString
- }
- return OpStructHeadBoolPtr
- case OpBytes:
- return OpStructHeadBytes
- case OpBytesPtr:
- return OpStructHeadBytesPtr
- case OpMap:
- return OpStructHeadMap
- case OpMapPtr:
- c.Op = OpMap
- return OpStructHeadMapPtr
- case OpArray:
- return OpStructHeadArray
- case OpArrayPtr:
- c.Op = OpArray
- return OpStructHeadArrayPtr
- case OpSlice:
- return OpStructHeadSlice
- case OpSlicePtr:
- c.Op = OpSlice
- return OpStructHeadSlicePtr
- case OpMarshalJSON:
- return OpStructHeadMarshalJSON
- case OpMarshalJSONPtr:
- return OpStructHeadMarshalJSONPtr
- case OpMarshalText:
- return OpStructHeadMarshalText
- case OpMarshalTextPtr:
- return OpStructHeadMarshalTextPtr
+ return OpBoolPtrString
+ case OpStringPtr:
+ return OpStringPtrString
+ case OpNumberPtr:
+ return OpNumberPtrString
}
- return OpStructHead
+ return t
}
func (c *Opcode) ToFieldType(isString bool) OpType {
switch c.Op {
+ case OpInterface:
+ // the string option is not for a value of interface{}.
+ return OpStructFieldInterface
case OpInt:
if isString {
return OpStructFieldIntString
@@ -307,12 +262,18 @@ func (c *Opcode) ToFieldType(isString bool) OpType {
return OpStructField
}
-func newOpCode(ctx *compileContext, typ *runtime.Type, op OpType) *Opcode {
+func newOpCode(ctx *compileContext, typ reflect.Type, op OpType) *Opcode {
return newOpCodeWithNext(ctx, typ, op, newEndOp(ctx, typ))
}
+// opcodeOffset returns the offset of the pointer of the slot.
func opcodeOffset(idx int) uint32 {
- return uint32(idx) * uintptrSize
+ return uint32(idx) * slotSize
+}
+
+// opcodeIntOffset returns the offset of the value of the slot which is not a pointer.
+func opcodeIntOffset(idx int) uint32 {
+ return opcodeOffset(idx) + slotIntOffset
}
func getCodeAddrByIdx(head *Opcode, idx uint32) *Opcode {
@@ -338,12 +299,16 @@ func copyOpcode(code *Opcode) *Opcode {
Type: c.Type,
FieldQuery: c.FieldQuery,
DisplayIdx: c.DisplayIdx,
- DisplayKey: c.DisplayKey,
+ KeyChunk: c.KeyChunk,
+ Map: c.Map,
+ EmptyKind: c.EmptyKind,
+ ZeroKind: c.ZeroKind,
ElemIdx: c.ElemIdx,
Length: c.Length,
Size: c.Size,
Indent: c.Indent,
Jmp: c.Jmp,
+ Marshaler: c.Marshaler,
}
if c.End != nil {
ptr.End = getCodeAddrByIdx(head, c.End.DisplayIdx)
@@ -365,7 +330,8 @@ func copyOpcode(code *Opcode) *Opcode {
func setTotalLengthToInterfaceOp(code *Opcode) {
for c := code; !c.IsEnd(); {
- if c.Op == OpInterface || c.Op == OpInterfacePtr {
+ switch c.Op {
+ case OpInterface, OpInterfacePtr, OpStructFieldInterface, OpStructFieldOmitEmptyInterface:
c.Length = uint32(code.TotalLength())
}
c = c.IterNext()
@@ -384,25 +350,34 @@ func copyToInterfaceOpcode(code *Opcode) *Opcode {
copied := copyOpcode(code)
c := copied
c = ToEndCode(c)
- c.Idx += uintptrSize
- c.ElemIdx = c.Idx + uintptrSize
- c.Length = c.Idx + 2*uintptrSize
+ // the slots to return to the previous frame are after every slot of the code:
+ // the slot of the end code is not the last one, because the fields of a struct share the slots.
+ c.Idx = opcodeOffset(copied.TotalLength())
+ c.setEndSlots()
c.Op = OpInterfaceEnd
return copied
}
-func newOpCodeWithNext(ctx *compileContext, typ *runtime.Type, op OpType, next *Opcode) *Opcode {
+// setEndSlots decides the slots of the opcode which returns to the previous frame from its Idx:
+// Idx is for the opcode to return to, ElemIdx is for the offset of the previous frame and
+// Length is for the indent to restore.
+func (c *Opcode) setEndSlots() {
+ c.ElemIdx = c.Idx + slotSize + slotIntOffset
+ c.Length = c.Idx + 2*slotSize + slotIntOffset
+}
+
+func newOpCodeWithNext(ctx *compileContext, typ reflect.Type, op OpType, next *Opcode) *Opcode {
return &Opcode{
Op: op,
Idx: opcodeOffset(ctx.ptrIndex),
Next: next,
- Type: typ,
+ Type: runtime.TypePtr(typ),
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
}
}
-func newEndOp(ctx *compileContext, typ *runtime.Type) *Opcode {
+func newEndOp(ctx *compileContext, typ reflect.Type) *Opcode {
return newOpCodeWithNext(ctx, typ, OpEnd, nil)
}
@@ -410,7 +385,7 @@ func (c *Opcode) TotalLength() int {
var idx int
code := c
for !code.IsEnd() {
- maxIdx := int(code.MaxIdx() / uintptrSize)
+ maxIdx := int(code.MaxIdx() / slotSize)
if idx < maxIdx {
idx = maxIdx
}
@@ -419,7 +394,7 @@ func (c *Opcode) TotalLength() int {
}
code = code.IterNext()
}
- maxIdx := int(code.MaxIdx() / uintptrSize)
+ maxIdx := int(code.MaxIdx() / slotSize)
if idx < maxIdx {
idx = maxIdx
}
@@ -431,15 +406,15 @@ func (c *Opcode) dumpHead(code *Opcode) string {
if code.Op.CodeType() == CodeArrayHead {
length = code.Length
} else {
- length = code.Length / uintptrSize
+ length = code.Length / slotSize
}
return fmt.Sprintf(
`[%03d]%s%s ([idx:%d][elemIdx:%d][length:%d])`,
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
- code.ElemIdx/uintptrSize,
+ code.Idx/slotSize,
+ code.ElemIdx/slotSize,
length,
)
}
@@ -450,7 +425,7 @@ func (c *Opcode) dumpMapHead(code *Opcode) string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
+ code.Idx/slotSize,
)
}
@@ -460,7 +435,7 @@ func (c *Opcode) dumpMapEnd(code *Opcode) string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
+ code.Idx/slotSize,
)
}
@@ -469,15 +444,15 @@ func (c *Opcode) dumpElem(code *Opcode) string {
if code.Op.CodeType() == CodeArrayElem {
length = code.Length
} else {
- length = code.Length / uintptrSize
+ length = code.Length / slotSize
}
return fmt.Sprintf(
`[%03d]%s%s ([idx:%d][elemIdx:%d][length:%d][size:%d])`,
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
- code.ElemIdx/uintptrSize,
+ code.Idx/slotSize,
+ code.ElemIdx/slotSize,
length,
code.Size,
)
@@ -489,8 +464,8 @@ func (c *Opcode) dumpField(code *Opcode) string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
- code.DisplayKey,
+ code.Idx/slotSize,
+ code.Key,
code.Offset,
)
}
@@ -501,7 +476,7 @@ func (c *Opcode) dumpKey(code *Opcode) string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
+ code.Idx/slotSize,
)
}
@@ -511,7 +486,7 @@ func (c *Opcode) dumpValue(code *Opcode) string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
+ code.Idx/slotSize,
)
}
@@ -549,7 +524,7 @@ func (c *Opcode) Dump() string {
code.DisplayIdx,
strings.Repeat("-", int(code.Indent)),
code.Op,
- code.Idx/uintptrSize,
+ code.Idx/slotSize,
))
code = code.Next
}
@@ -638,15 +613,16 @@ func (c *Opcode) DumpDOT() string {
return b.String()
}
-func newSliceHeaderCode(ctx *compileContext, typ *runtime.Type) *Opcode {
+// newSliceHeaderCode takes two slots: the first one is for the address of the elements and the index,
+// and the next one is for the length.
+func newSliceHeaderCode(ctx *compileContext, typ reflect.Type) *Opcode {
idx := opcodeOffset(ctx.ptrIndex)
+ elemIdx := opcodeIntOffset(ctx.ptrIndex)
ctx.incPtrIndex()
- elemIdx := opcodeOffset(ctx.ptrIndex)
- ctx.incPtrIndex()
- length := opcodeOffset(ctx.ptrIndex)
+ length := opcodeIntOffset(ctx.ptrIndex)
return &Opcode{
Op: OpSlice,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: idx,
DisplayIdx: ctx.opcodeIndex,
ElemIdx: elemIdx,
@@ -655,10 +631,10 @@ func newSliceHeaderCode(ctx *compileContext, typ *runtime.Type) *Opcode {
}
}
-func newSliceElemCode(ctx *compileContext, typ *runtime.Type, head *Opcode, size uintptr) *Opcode {
+func newSliceElemCode(ctx *compileContext, typ reflect.Type, head *Opcode, size uintptr) *Opcode {
return &Opcode{
Op: OpSliceElem,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: head.Idx,
DisplayIdx: ctx.opcodeIndex,
ElemIdx: head.ElemIdx,
@@ -668,13 +644,13 @@ func newSliceElemCode(ctx *compileContext, typ *runtime.Type, head *Opcode, size
}
}
-func newArrayHeaderCode(ctx *compileContext, typ *runtime.Type, alen int) *Opcode {
+// newArrayHeaderCode takes a slot, which is for the address of the array and the index.
+func newArrayHeaderCode(ctx *compileContext, typ reflect.Type, alen int) *Opcode {
idx := opcodeOffset(ctx.ptrIndex)
- ctx.incPtrIndex()
- elemIdx := opcodeOffset(ctx.ptrIndex)
+ elemIdx := opcodeIntOffset(ctx.ptrIndex)
return &Opcode{
Op: OpArray,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: idx,
DisplayIdx: ctx.opcodeIndex,
ElemIdx: elemIdx,
@@ -683,10 +659,10 @@ func newArrayHeaderCode(ctx *compileContext, typ *runtime.Type, alen int) *Opcod
}
}
-func newArrayElemCode(ctx *compileContext, typ *runtime.Type, head *Opcode, length int, size uintptr) *Opcode {
+func newArrayElemCode(ctx *compileContext, typ reflect.Type, head *Opcode, length int, size uintptr) *Opcode {
return &Opcode{
Op: OpArrayElem,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: head.Idx,
DisplayIdx: ctx.opcodeIndex,
ElemIdx: head.ElemIdx,
@@ -696,42 +672,43 @@ func newArrayElemCode(ctx *compileContext, typ *runtime.Type, head *Opcode, leng
}
}
-func newMapHeaderCode(ctx *compileContext, typ *runtime.Type) *Opcode {
+func newMapHeaderCode(ctx *compileContext, typ reflect.Type) *Opcode {
idx := opcodeOffset(ctx.ptrIndex)
ctx.incPtrIndex()
return &Opcode{
Op: OpMap,
- Type: typ,
+ Type: runtime.TypePtr(typ),
+ Map: NewMapLayout(typ),
Idx: idx,
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
}
}
-func newMapKeyCode(ctx *compileContext, typ *runtime.Type, head *Opcode) *Opcode {
+func newMapKeyCode(ctx *compileContext, typ reflect.Type, head *Opcode) *Opcode {
return &Opcode{
Op: OpMapKey,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: head.Idx,
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
}
}
-func newMapValueCode(ctx *compileContext, typ *runtime.Type, head *Opcode) *Opcode {
+func newMapValueCode(ctx *compileContext, typ reflect.Type, head *Opcode) *Opcode {
return &Opcode{
Op: OpMapValue,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: head.Idx,
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
}
}
-func newMapEndCode(ctx *compileContext, typ *runtime.Type, head *Opcode) *Opcode {
+func newMapEndCode(ctx *compileContext, typ reflect.Type, head *Opcode) *Opcode {
return &Opcode{
Op: OpMapEnd,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: head.Idx,
DisplayIdx: ctx.opcodeIndex,
Indent: ctx.indent,
@@ -739,10 +716,10 @@ func newMapEndCode(ctx *compileContext, typ *runtime.Type, head *Opcode) *Opcode
}
}
-func newRecursiveCode(ctx *compileContext, typ *runtime.Type, jmp *CompiledCode) *Opcode {
+func newRecursiveCode(ctx *compileContext, typ reflect.Type, jmp *CompiledCode) *Opcode {
return &Opcode{
Op: OpRecursive,
- Type: typ,
+ Type: runtime.TypePtr(typ),
Idx: opcodeOffset(ctx.ptrIndex),
Next: newEndOp(ctx, typ),
DisplayIdx: ctx.opcodeIndex,
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/option.go b/vendor/github.com/goccy/go-json/internal/encoder/option.go
index 12c58e46c..435c8639b 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/option.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/option.go
@@ -5,7 +5,7 @@ import (
"io"
)
-type OptionFlag uint8
+type OptionFlag uint16
const (
HTMLEscapeOption OptionFlag = 1 << iota
@@ -16,6 +16,10 @@ const (
ContextOption
NormalizeUTF8Option
FieldQueryOption
+ // OptimizeFieldOrderOption lets the encoder order the fields of a struct as it encodes them fastest:
+ // the fields of the same kind together, and a recursive field last. The opcodes of a type are compiled
+ // for it apart from the ones for the order of the struct.
+ OptimizeFieldOrderOption
)
type Option struct {
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/optype.go b/vendor/github.com/goccy/go-json/internal/encoder/optype.go
index 5c1241b47..891231a20 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/optype.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/optype.go
@@ -1,4 +1,4 @@
-// Code generated by internal/cmd/generator. DO NOT EDIT!
+// Code generated by internal/cmd/generator. DO NOT EDIT.
package encoder
import (
@@ -22,7 +22,7 @@ const (
CodeStructEnd CodeType = 11
)
-var opTypeStrings = [400]string{
+var opTypeStrings = [244]string{
"End",
"Interface",
"Ptr",
@@ -79,178 +79,8 @@ var opTypeStrings = [400]string{
"BoolPtrString",
"StringPtrString",
"NumberPtrString",
- "StructHeadInt",
- "StructHeadOmitEmptyInt",
- "StructPtrHeadInt",
- "StructPtrHeadOmitEmptyInt",
- "StructHeadUint",
- "StructHeadOmitEmptyUint",
- "StructPtrHeadUint",
- "StructPtrHeadOmitEmptyUint",
- "StructHeadFloat32",
- "StructHeadOmitEmptyFloat32",
- "StructPtrHeadFloat32",
- "StructPtrHeadOmitEmptyFloat32",
- "StructHeadFloat64",
- "StructHeadOmitEmptyFloat64",
- "StructPtrHeadFloat64",
- "StructPtrHeadOmitEmptyFloat64",
- "StructHeadBool",
- "StructHeadOmitEmptyBool",
- "StructPtrHeadBool",
- "StructPtrHeadOmitEmptyBool",
- "StructHeadString",
- "StructHeadOmitEmptyString",
- "StructPtrHeadString",
- "StructPtrHeadOmitEmptyString",
- "StructHeadBytes",
- "StructHeadOmitEmptyBytes",
- "StructPtrHeadBytes",
- "StructPtrHeadOmitEmptyBytes",
- "StructHeadNumber",
- "StructHeadOmitEmptyNumber",
- "StructPtrHeadNumber",
- "StructPtrHeadOmitEmptyNumber",
- "StructHeadArray",
- "StructHeadOmitEmptyArray",
- "StructPtrHeadArray",
- "StructPtrHeadOmitEmptyArray",
- "StructHeadMap",
- "StructHeadOmitEmptyMap",
- "StructPtrHeadMap",
- "StructPtrHeadOmitEmptyMap",
- "StructHeadSlice",
- "StructHeadOmitEmptySlice",
- "StructPtrHeadSlice",
- "StructPtrHeadOmitEmptySlice",
- "StructHeadStruct",
- "StructHeadOmitEmptyStruct",
- "StructPtrHeadStruct",
- "StructPtrHeadOmitEmptyStruct",
- "StructHeadMarshalJSON",
- "StructHeadOmitEmptyMarshalJSON",
- "StructPtrHeadMarshalJSON",
- "StructPtrHeadOmitEmptyMarshalJSON",
- "StructHeadMarshalText",
- "StructHeadOmitEmptyMarshalText",
- "StructPtrHeadMarshalText",
- "StructPtrHeadOmitEmptyMarshalText",
- "StructHeadIntString",
- "StructHeadOmitEmptyIntString",
- "StructPtrHeadIntString",
- "StructPtrHeadOmitEmptyIntString",
- "StructHeadUintString",
- "StructHeadOmitEmptyUintString",
- "StructPtrHeadUintString",
- "StructPtrHeadOmitEmptyUintString",
- "StructHeadFloat32String",
- "StructHeadOmitEmptyFloat32String",
- "StructPtrHeadFloat32String",
- "StructPtrHeadOmitEmptyFloat32String",
- "StructHeadFloat64String",
- "StructHeadOmitEmptyFloat64String",
- "StructPtrHeadFloat64String",
- "StructPtrHeadOmitEmptyFloat64String",
- "StructHeadBoolString",
- "StructHeadOmitEmptyBoolString",
- "StructPtrHeadBoolString",
- "StructPtrHeadOmitEmptyBoolString",
- "StructHeadStringString",
- "StructHeadOmitEmptyStringString",
- "StructPtrHeadStringString",
- "StructPtrHeadOmitEmptyStringString",
- "StructHeadNumberString",
- "StructHeadOmitEmptyNumberString",
- "StructPtrHeadNumberString",
- "StructPtrHeadOmitEmptyNumberString",
- "StructHeadIntPtr",
- "StructHeadOmitEmptyIntPtr",
- "StructPtrHeadIntPtr",
- "StructPtrHeadOmitEmptyIntPtr",
- "StructHeadUintPtr",
- "StructHeadOmitEmptyUintPtr",
- "StructPtrHeadUintPtr",
- "StructPtrHeadOmitEmptyUintPtr",
- "StructHeadFloat32Ptr",
- "StructHeadOmitEmptyFloat32Ptr",
- "StructPtrHeadFloat32Ptr",
- "StructPtrHeadOmitEmptyFloat32Ptr",
- "StructHeadFloat64Ptr",
- "StructHeadOmitEmptyFloat64Ptr",
- "StructPtrHeadFloat64Ptr",
- "StructPtrHeadOmitEmptyFloat64Ptr",
- "StructHeadBoolPtr",
- "StructHeadOmitEmptyBoolPtr",
- "StructPtrHeadBoolPtr",
- "StructPtrHeadOmitEmptyBoolPtr",
- "StructHeadStringPtr",
- "StructHeadOmitEmptyStringPtr",
- "StructPtrHeadStringPtr",
- "StructPtrHeadOmitEmptyStringPtr",
- "StructHeadBytesPtr",
- "StructHeadOmitEmptyBytesPtr",
- "StructPtrHeadBytesPtr",
- "StructPtrHeadOmitEmptyBytesPtr",
- "StructHeadNumberPtr",
- "StructHeadOmitEmptyNumberPtr",
- "StructPtrHeadNumberPtr",
- "StructPtrHeadOmitEmptyNumberPtr",
- "StructHeadArrayPtr",
- "StructHeadOmitEmptyArrayPtr",
- "StructPtrHeadArrayPtr",
- "StructPtrHeadOmitEmptyArrayPtr",
- "StructHeadMapPtr",
- "StructHeadOmitEmptyMapPtr",
- "StructPtrHeadMapPtr",
- "StructPtrHeadOmitEmptyMapPtr",
- "StructHeadSlicePtr",
- "StructHeadOmitEmptySlicePtr",
- "StructPtrHeadSlicePtr",
- "StructPtrHeadOmitEmptySlicePtr",
- "StructHeadMarshalJSONPtr",
- "StructHeadOmitEmptyMarshalJSONPtr",
- "StructPtrHeadMarshalJSONPtr",
- "StructPtrHeadOmitEmptyMarshalJSONPtr",
- "StructHeadMarshalTextPtr",
- "StructHeadOmitEmptyMarshalTextPtr",
- "StructPtrHeadMarshalTextPtr",
- "StructPtrHeadOmitEmptyMarshalTextPtr",
- "StructHeadInterfacePtr",
- "StructHeadOmitEmptyInterfacePtr",
- "StructPtrHeadInterfacePtr",
- "StructPtrHeadOmitEmptyInterfacePtr",
- "StructHeadIntPtrString",
- "StructHeadOmitEmptyIntPtrString",
- "StructPtrHeadIntPtrString",
- "StructPtrHeadOmitEmptyIntPtrString",
- "StructHeadUintPtrString",
- "StructHeadOmitEmptyUintPtrString",
- "StructPtrHeadUintPtrString",
- "StructPtrHeadOmitEmptyUintPtrString",
- "StructHeadFloat32PtrString",
- "StructHeadOmitEmptyFloat32PtrString",
- "StructPtrHeadFloat32PtrString",
- "StructPtrHeadOmitEmptyFloat32PtrString",
- "StructHeadFloat64PtrString",
- "StructHeadOmitEmptyFloat64PtrString",
- "StructPtrHeadFloat64PtrString",
- "StructPtrHeadOmitEmptyFloat64PtrString",
- "StructHeadBoolPtrString",
- "StructHeadOmitEmptyBoolPtrString",
- "StructPtrHeadBoolPtrString",
- "StructPtrHeadOmitEmptyBoolPtrString",
- "StructHeadStringPtrString",
- "StructHeadOmitEmptyStringPtrString",
- "StructPtrHeadStringPtrString",
- "StructPtrHeadOmitEmptyStringPtrString",
- "StructHeadNumberPtrString",
- "StructHeadOmitEmptyNumberPtrString",
- "StructPtrHeadNumberPtrString",
- "StructPtrHeadOmitEmptyNumberPtrString",
"StructHead",
- "StructHeadOmitEmpty",
"StructPtrHead",
- "StructPtrHeadOmitEmpty",
"StructFieldInt",
"StructFieldOmitEmptyInt",
"StructEndInt",
@@ -419,419 +249,277 @@ var opTypeStrings = [400]string{
"StructFieldOmitEmptyNumberPtrString",
"StructEndNumberPtrString",
"StructEndOmitEmptyNumberPtrString",
+ "StructFieldInterface",
+ "StructFieldOmitEmptyInterface",
+ "StructEndInterface",
+ "StructEndOmitEmptyInterface",
"StructField",
"StructFieldOmitEmpty",
"StructEnd",
"StructEndOmitEmpty",
+ "StructFieldInt3",
+ "StructFieldInt2",
+ "StructFieldUint3",
+ "StructFieldUint2",
+ "StructFieldFloat643",
+ "StructFieldFloat642",
+ "StructFieldString3",
+ "StructFieldString2",
+ "StructFieldBool3",
+ "StructFieldBool2",
}
type OpType uint16
const (
- OpEnd OpType = 0
- OpInterface OpType = 1
- OpPtr OpType = 2
- OpSliceElem OpType = 3
- OpSliceEnd OpType = 4
- OpArrayElem OpType = 5
- OpArrayEnd OpType = 6
- OpMapKey OpType = 7
- OpMapValue OpType = 8
- OpMapEnd OpType = 9
- OpRecursive OpType = 10
- OpRecursivePtr OpType = 11
- OpRecursiveEnd OpType = 12
- OpInterfaceEnd OpType = 13
- OpInt OpType = 14
- OpUint OpType = 15
- OpFloat32 OpType = 16
- OpFloat64 OpType = 17
- OpBool OpType = 18
- OpString OpType = 19
- OpBytes OpType = 20
- OpNumber OpType = 21
- OpArray OpType = 22
- OpMap OpType = 23
- OpSlice OpType = 24
- OpStruct OpType = 25
- OpMarshalJSON OpType = 26
- OpMarshalText OpType = 27
- OpIntString OpType = 28
- OpUintString OpType = 29
- OpFloat32String OpType = 30
- OpFloat64String OpType = 31
- OpBoolString OpType = 32
- OpStringString OpType = 33
- OpNumberString OpType = 34
- OpIntPtr OpType = 35
- OpUintPtr OpType = 36
- OpFloat32Ptr OpType = 37
- OpFloat64Ptr OpType = 38
- OpBoolPtr OpType = 39
- OpStringPtr OpType = 40
- OpBytesPtr OpType = 41
- OpNumberPtr OpType = 42
- OpArrayPtr OpType = 43
- OpMapPtr OpType = 44
- OpSlicePtr OpType = 45
- OpMarshalJSONPtr OpType = 46
- OpMarshalTextPtr OpType = 47
- OpInterfacePtr OpType = 48
- OpIntPtrString OpType = 49
- OpUintPtrString OpType = 50
- OpFloat32PtrString OpType = 51
- OpFloat64PtrString OpType = 52
- OpBoolPtrString OpType = 53
- OpStringPtrString OpType = 54
- OpNumberPtrString OpType = 55
- OpStructHeadInt OpType = 56
- OpStructHeadOmitEmptyInt OpType = 57
- OpStructPtrHeadInt OpType = 58
- OpStructPtrHeadOmitEmptyInt OpType = 59
- OpStructHeadUint OpType = 60
- OpStructHeadOmitEmptyUint OpType = 61
- OpStructPtrHeadUint OpType = 62
- OpStructPtrHeadOmitEmptyUint OpType = 63
- OpStructHeadFloat32 OpType = 64
- OpStructHeadOmitEmptyFloat32 OpType = 65
- OpStructPtrHeadFloat32 OpType = 66
- OpStructPtrHeadOmitEmptyFloat32 OpType = 67
- OpStructHeadFloat64 OpType = 68
- OpStructHeadOmitEmptyFloat64 OpType = 69
- OpStructPtrHeadFloat64 OpType = 70
- OpStructPtrHeadOmitEmptyFloat64 OpType = 71
- OpStructHeadBool OpType = 72
- OpStructHeadOmitEmptyBool OpType = 73
- OpStructPtrHeadBool OpType = 74
- OpStructPtrHeadOmitEmptyBool OpType = 75
- OpStructHeadString OpType = 76
- OpStructHeadOmitEmptyString OpType = 77
- OpStructPtrHeadString OpType = 78
- OpStructPtrHeadOmitEmptyString OpType = 79
- OpStructHeadBytes OpType = 80
- OpStructHeadOmitEmptyBytes OpType = 81
- OpStructPtrHeadBytes OpType = 82
- OpStructPtrHeadOmitEmptyBytes OpType = 83
- OpStructHeadNumber OpType = 84
- OpStructHeadOmitEmptyNumber OpType = 85
- OpStructPtrHeadNumber OpType = 86
- OpStructPtrHeadOmitEmptyNumber OpType = 87
- OpStructHeadArray OpType = 88
- OpStructHeadOmitEmptyArray OpType = 89
- OpStructPtrHeadArray OpType = 90
- OpStructPtrHeadOmitEmptyArray OpType = 91
- OpStructHeadMap OpType = 92
- OpStructHeadOmitEmptyMap OpType = 93
- OpStructPtrHeadMap OpType = 94
- OpStructPtrHeadOmitEmptyMap OpType = 95
- OpStructHeadSlice OpType = 96
- OpStructHeadOmitEmptySlice OpType = 97
- OpStructPtrHeadSlice OpType = 98
- OpStructPtrHeadOmitEmptySlice OpType = 99
- OpStructHeadStruct OpType = 100
- OpStructHeadOmitEmptyStruct OpType = 101
- OpStructPtrHeadStruct OpType = 102
- OpStructPtrHeadOmitEmptyStruct OpType = 103
- OpStructHeadMarshalJSON OpType = 104
- OpStructHeadOmitEmptyMarshalJSON OpType = 105
- OpStructPtrHeadMarshalJSON OpType = 106
- OpStructPtrHeadOmitEmptyMarshalJSON OpType = 107
- OpStructHeadMarshalText OpType = 108
- OpStructHeadOmitEmptyMarshalText OpType = 109
- OpStructPtrHeadMarshalText OpType = 110
- OpStructPtrHeadOmitEmptyMarshalText OpType = 111
- OpStructHeadIntString OpType = 112
- OpStructHeadOmitEmptyIntString OpType = 113
- OpStructPtrHeadIntString OpType = 114
- OpStructPtrHeadOmitEmptyIntString OpType = 115
- OpStructHeadUintString OpType = 116
- OpStructHeadOmitEmptyUintString OpType = 117
- OpStructPtrHeadUintString OpType = 118
- OpStructPtrHeadOmitEmptyUintString OpType = 119
- OpStructHeadFloat32String OpType = 120
- OpStructHeadOmitEmptyFloat32String OpType = 121
- OpStructPtrHeadFloat32String OpType = 122
- OpStructPtrHeadOmitEmptyFloat32String OpType = 123
- OpStructHeadFloat64String OpType = 124
- OpStructHeadOmitEmptyFloat64String OpType = 125
- OpStructPtrHeadFloat64String OpType = 126
- OpStructPtrHeadOmitEmptyFloat64String OpType = 127
- OpStructHeadBoolString OpType = 128
- OpStructHeadOmitEmptyBoolString OpType = 129
- OpStructPtrHeadBoolString OpType = 130
- OpStructPtrHeadOmitEmptyBoolString OpType = 131
- OpStructHeadStringString OpType = 132
- OpStructHeadOmitEmptyStringString OpType = 133
- OpStructPtrHeadStringString OpType = 134
- OpStructPtrHeadOmitEmptyStringString OpType = 135
- OpStructHeadNumberString OpType = 136
- OpStructHeadOmitEmptyNumberString OpType = 137
- OpStructPtrHeadNumberString OpType = 138
- OpStructPtrHeadOmitEmptyNumberString OpType = 139
- OpStructHeadIntPtr OpType = 140
- OpStructHeadOmitEmptyIntPtr OpType = 141
- OpStructPtrHeadIntPtr OpType = 142
- OpStructPtrHeadOmitEmptyIntPtr OpType = 143
- OpStructHeadUintPtr OpType = 144
- OpStructHeadOmitEmptyUintPtr OpType = 145
- OpStructPtrHeadUintPtr OpType = 146
- OpStructPtrHeadOmitEmptyUintPtr OpType = 147
- OpStructHeadFloat32Ptr OpType = 148
- OpStructHeadOmitEmptyFloat32Ptr OpType = 149
- OpStructPtrHeadFloat32Ptr OpType = 150
- OpStructPtrHeadOmitEmptyFloat32Ptr OpType = 151
- OpStructHeadFloat64Ptr OpType = 152
- OpStructHeadOmitEmptyFloat64Ptr OpType = 153
- OpStructPtrHeadFloat64Ptr OpType = 154
- OpStructPtrHeadOmitEmptyFloat64Ptr OpType = 155
- OpStructHeadBoolPtr OpType = 156
- OpStructHeadOmitEmptyBoolPtr OpType = 157
- OpStructPtrHeadBoolPtr OpType = 158
- OpStructPtrHeadOmitEmptyBoolPtr OpType = 159
- OpStructHeadStringPtr OpType = 160
- OpStructHeadOmitEmptyStringPtr OpType = 161
- OpStructPtrHeadStringPtr OpType = 162
- OpStructPtrHeadOmitEmptyStringPtr OpType = 163
- OpStructHeadBytesPtr OpType = 164
- OpStructHeadOmitEmptyBytesPtr OpType = 165
- OpStructPtrHeadBytesPtr OpType = 166
- OpStructPtrHeadOmitEmptyBytesPtr OpType = 167
- OpStructHeadNumberPtr OpType = 168
- OpStructHeadOmitEmptyNumberPtr OpType = 169
- OpStructPtrHeadNumberPtr OpType = 170
- OpStructPtrHeadOmitEmptyNumberPtr OpType = 171
- OpStructHeadArrayPtr OpType = 172
- OpStructHeadOmitEmptyArrayPtr OpType = 173
- OpStructPtrHeadArrayPtr OpType = 174
- OpStructPtrHeadOmitEmptyArrayPtr OpType = 175
- OpStructHeadMapPtr OpType = 176
- OpStructHeadOmitEmptyMapPtr OpType = 177
- OpStructPtrHeadMapPtr OpType = 178
- OpStructPtrHeadOmitEmptyMapPtr OpType = 179
- OpStructHeadSlicePtr OpType = 180
- OpStructHeadOmitEmptySlicePtr OpType = 181
- OpStructPtrHeadSlicePtr OpType = 182
- OpStructPtrHeadOmitEmptySlicePtr OpType = 183
- OpStructHeadMarshalJSONPtr OpType = 184
- OpStructHeadOmitEmptyMarshalJSONPtr OpType = 185
- OpStructPtrHeadMarshalJSONPtr OpType = 186
- OpStructPtrHeadOmitEmptyMarshalJSONPtr OpType = 187
- OpStructHeadMarshalTextPtr OpType = 188
- OpStructHeadOmitEmptyMarshalTextPtr OpType = 189
- OpStructPtrHeadMarshalTextPtr OpType = 190
- OpStructPtrHeadOmitEmptyMarshalTextPtr OpType = 191
- OpStructHeadInterfacePtr OpType = 192
- OpStructHeadOmitEmptyInterfacePtr OpType = 193
- OpStructPtrHeadInterfacePtr OpType = 194
- OpStructPtrHeadOmitEmptyInterfacePtr OpType = 195
- OpStructHeadIntPtrString OpType = 196
- OpStructHeadOmitEmptyIntPtrString OpType = 197
- OpStructPtrHeadIntPtrString OpType = 198
- OpStructPtrHeadOmitEmptyIntPtrString OpType = 199
- OpStructHeadUintPtrString OpType = 200
- OpStructHeadOmitEmptyUintPtrString OpType = 201
- OpStructPtrHeadUintPtrString OpType = 202
- OpStructPtrHeadOmitEmptyUintPtrString OpType = 203
- OpStructHeadFloat32PtrString OpType = 204
- OpStructHeadOmitEmptyFloat32PtrString OpType = 205
- OpStructPtrHeadFloat32PtrString OpType = 206
- OpStructPtrHeadOmitEmptyFloat32PtrString OpType = 207
- OpStructHeadFloat64PtrString OpType = 208
- OpStructHeadOmitEmptyFloat64PtrString OpType = 209
- OpStructPtrHeadFloat64PtrString OpType = 210
- OpStructPtrHeadOmitEmptyFloat64PtrString OpType = 211
- OpStructHeadBoolPtrString OpType = 212
- OpStructHeadOmitEmptyBoolPtrString OpType = 213
- OpStructPtrHeadBoolPtrString OpType = 214
- OpStructPtrHeadOmitEmptyBoolPtrString OpType = 215
- OpStructHeadStringPtrString OpType = 216
- OpStructHeadOmitEmptyStringPtrString OpType = 217
- OpStructPtrHeadStringPtrString OpType = 218
- OpStructPtrHeadOmitEmptyStringPtrString OpType = 219
- OpStructHeadNumberPtrString OpType = 220
- OpStructHeadOmitEmptyNumberPtrString OpType = 221
- OpStructPtrHeadNumberPtrString OpType = 222
- OpStructPtrHeadOmitEmptyNumberPtrString OpType = 223
- OpStructHead OpType = 224
- OpStructHeadOmitEmpty OpType = 225
- OpStructPtrHead OpType = 226
- OpStructPtrHeadOmitEmpty OpType = 227
- OpStructFieldInt OpType = 228
- OpStructFieldOmitEmptyInt OpType = 229
- OpStructEndInt OpType = 230
- OpStructEndOmitEmptyInt OpType = 231
- OpStructFieldUint OpType = 232
- OpStructFieldOmitEmptyUint OpType = 233
- OpStructEndUint OpType = 234
- OpStructEndOmitEmptyUint OpType = 235
- OpStructFieldFloat32 OpType = 236
- OpStructFieldOmitEmptyFloat32 OpType = 237
- OpStructEndFloat32 OpType = 238
- OpStructEndOmitEmptyFloat32 OpType = 239
- OpStructFieldFloat64 OpType = 240
- OpStructFieldOmitEmptyFloat64 OpType = 241
- OpStructEndFloat64 OpType = 242
- OpStructEndOmitEmptyFloat64 OpType = 243
- OpStructFieldBool OpType = 244
- OpStructFieldOmitEmptyBool OpType = 245
- OpStructEndBool OpType = 246
- OpStructEndOmitEmptyBool OpType = 247
- OpStructFieldString OpType = 248
- OpStructFieldOmitEmptyString OpType = 249
- OpStructEndString OpType = 250
- OpStructEndOmitEmptyString OpType = 251
- OpStructFieldBytes OpType = 252
- OpStructFieldOmitEmptyBytes OpType = 253
- OpStructEndBytes OpType = 254
- OpStructEndOmitEmptyBytes OpType = 255
- OpStructFieldNumber OpType = 256
- OpStructFieldOmitEmptyNumber OpType = 257
- OpStructEndNumber OpType = 258
- OpStructEndOmitEmptyNumber OpType = 259
- OpStructFieldArray OpType = 260
- OpStructFieldOmitEmptyArray OpType = 261
- OpStructEndArray OpType = 262
- OpStructEndOmitEmptyArray OpType = 263
- OpStructFieldMap OpType = 264
- OpStructFieldOmitEmptyMap OpType = 265
- OpStructEndMap OpType = 266
- OpStructEndOmitEmptyMap OpType = 267
- OpStructFieldSlice OpType = 268
- OpStructFieldOmitEmptySlice OpType = 269
- OpStructEndSlice OpType = 270
- OpStructEndOmitEmptySlice OpType = 271
- OpStructFieldStruct OpType = 272
- OpStructFieldOmitEmptyStruct OpType = 273
- OpStructEndStruct OpType = 274
- OpStructEndOmitEmptyStruct OpType = 275
- OpStructFieldMarshalJSON OpType = 276
- OpStructFieldOmitEmptyMarshalJSON OpType = 277
- OpStructEndMarshalJSON OpType = 278
- OpStructEndOmitEmptyMarshalJSON OpType = 279
- OpStructFieldMarshalText OpType = 280
- OpStructFieldOmitEmptyMarshalText OpType = 281
- OpStructEndMarshalText OpType = 282
- OpStructEndOmitEmptyMarshalText OpType = 283
- OpStructFieldIntString OpType = 284
- OpStructFieldOmitEmptyIntString OpType = 285
- OpStructEndIntString OpType = 286
- OpStructEndOmitEmptyIntString OpType = 287
- OpStructFieldUintString OpType = 288
- OpStructFieldOmitEmptyUintString OpType = 289
- OpStructEndUintString OpType = 290
- OpStructEndOmitEmptyUintString OpType = 291
- OpStructFieldFloat32String OpType = 292
- OpStructFieldOmitEmptyFloat32String OpType = 293
- OpStructEndFloat32String OpType = 294
- OpStructEndOmitEmptyFloat32String OpType = 295
- OpStructFieldFloat64String OpType = 296
- OpStructFieldOmitEmptyFloat64String OpType = 297
- OpStructEndFloat64String OpType = 298
- OpStructEndOmitEmptyFloat64String OpType = 299
- OpStructFieldBoolString OpType = 300
- OpStructFieldOmitEmptyBoolString OpType = 301
- OpStructEndBoolString OpType = 302
- OpStructEndOmitEmptyBoolString OpType = 303
- OpStructFieldStringString OpType = 304
- OpStructFieldOmitEmptyStringString OpType = 305
- OpStructEndStringString OpType = 306
- OpStructEndOmitEmptyStringString OpType = 307
- OpStructFieldNumberString OpType = 308
- OpStructFieldOmitEmptyNumberString OpType = 309
- OpStructEndNumberString OpType = 310
- OpStructEndOmitEmptyNumberString OpType = 311
- OpStructFieldIntPtr OpType = 312
- OpStructFieldOmitEmptyIntPtr OpType = 313
- OpStructEndIntPtr OpType = 314
- OpStructEndOmitEmptyIntPtr OpType = 315
- OpStructFieldUintPtr OpType = 316
- OpStructFieldOmitEmptyUintPtr OpType = 317
- OpStructEndUintPtr OpType = 318
- OpStructEndOmitEmptyUintPtr OpType = 319
- OpStructFieldFloat32Ptr OpType = 320
- OpStructFieldOmitEmptyFloat32Ptr OpType = 321
- OpStructEndFloat32Ptr OpType = 322
- OpStructEndOmitEmptyFloat32Ptr OpType = 323
- OpStructFieldFloat64Ptr OpType = 324
- OpStructFieldOmitEmptyFloat64Ptr OpType = 325
- OpStructEndFloat64Ptr OpType = 326
- OpStructEndOmitEmptyFloat64Ptr OpType = 327
- OpStructFieldBoolPtr OpType = 328
- OpStructFieldOmitEmptyBoolPtr OpType = 329
- OpStructEndBoolPtr OpType = 330
- OpStructEndOmitEmptyBoolPtr OpType = 331
- OpStructFieldStringPtr OpType = 332
- OpStructFieldOmitEmptyStringPtr OpType = 333
- OpStructEndStringPtr OpType = 334
- OpStructEndOmitEmptyStringPtr OpType = 335
- OpStructFieldBytesPtr OpType = 336
- OpStructFieldOmitEmptyBytesPtr OpType = 337
- OpStructEndBytesPtr OpType = 338
- OpStructEndOmitEmptyBytesPtr OpType = 339
- OpStructFieldNumberPtr OpType = 340
- OpStructFieldOmitEmptyNumberPtr OpType = 341
- OpStructEndNumberPtr OpType = 342
- OpStructEndOmitEmptyNumberPtr OpType = 343
- OpStructFieldArrayPtr OpType = 344
- OpStructFieldOmitEmptyArrayPtr OpType = 345
- OpStructEndArrayPtr OpType = 346
- OpStructEndOmitEmptyArrayPtr OpType = 347
- OpStructFieldMapPtr OpType = 348
- OpStructFieldOmitEmptyMapPtr OpType = 349
- OpStructEndMapPtr OpType = 350
- OpStructEndOmitEmptyMapPtr OpType = 351
- OpStructFieldSlicePtr OpType = 352
- OpStructFieldOmitEmptySlicePtr OpType = 353
- OpStructEndSlicePtr OpType = 354
- OpStructEndOmitEmptySlicePtr OpType = 355
- OpStructFieldMarshalJSONPtr OpType = 356
- OpStructFieldOmitEmptyMarshalJSONPtr OpType = 357
- OpStructEndMarshalJSONPtr OpType = 358
- OpStructEndOmitEmptyMarshalJSONPtr OpType = 359
- OpStructFieldMarshalTextPtr OpType = 360
- OpStructFieldOmitEmptyMarshalTextPtr OpType = 361
- OpStructEndMarshalTextPtr OpType = 362
- OpStructEndOmitEmptyMarshalTextPtr OpType = 363
- OpStructFieldInterfacePtr OpType = 364
- OpStructFieldOmitEmptyInterfacePtr OpType = 365
- OpStructEndInterfacePtr OpType = 366
- OpStructEndOmitEmptyInterfacePtr OpType = 367
- OpStructFieldIntPtrString OpType = 368
- OpStructFieldOmitEmptyIntPtrString OpType = 369
- OpStructEndIntPtrString OpType = 370
- OpStructEndOmitEmptyIntPtrString OpType = 371
- OpStructFieldUintPtrString OpType = 372
- OpStructFieldOmitEmptyUintPtrString OpType = 373
- OpStructEndUintPtrString OpType = 374
- OpStructEndOmitEmptyUintPtrString OpType = 375
- OpStructFieldFloat32PtrString OpType = 376
- OpStructFieldOmitEmptyFloat32PtrString OpType = 377
- OpStructEndFloat32PtrString OpType = 378
- OpStructEndOmitEmptyFloat32PtrString OpType = 379
- OpStructFieldFloat64PtrString OpType = 380
- OpStructFieldOmitEmptyFloat64PtrString OpType = 381
- OpStructEndFloat64PtrString OpType = 382
- OpStructEndOmitEmptyFloat64PtrString OpType = 383
- OpStructFieldBoolPtrString OpType = 384
- OpStructFieldOmitEmptyBoolPtrString OpType = 385
- OpStructEndBoolPtrString OpType = 386
- OpStructEndOmitEmptyBoolPtrString OpType = 387
- OpStructFieldStringPtrString OpType = 388
- OpStructFieldOmitEmptyStringPtrString OpType = 389
- OpStructEndStringPtrString OpType = 390
- OpStructEndOmitEmptyStringPtrString OpType = 391
- OpStructFieldNumberPtrString OpType = 392
- OpStructFieldOmitEmptyNumberPtrString OpType = 393
- OpStructEndNumberPtrString OpType = 394
- OpStructEndOmitEmptyNumberPtrString OpType = 395
- OpStructField OpType = 396
- OpStructFieldOmitEmpty OpType = 397
- OpStructEnd OpType = 398
- OpStructEndOmitEmpty OpType = 399
+ OpEnd OpType = 0
+ OpInterface OpType = 1
+ OpPtr OpType = 2
+ OpSliceElem OpType = 3
+ OpSliceEnd OpType = 4
+ OpArrayElem OpType = 5
+ OpArrayEnd OpType = 6
+ OpMapKey OpType = 7
+ OpMapValue OpType = 8
+ OpMapEnd OpType = 9
+ OpRecursive OpType = 10
+ OpRecursivePtr OpType = 11
+ OpRecursiveEnd OpType = 12
+ OpInterfaceEnd OpType = 13
+ OpInt OpType = 14
+ OpUint OpType = 15
+ OpFloat32 OpType = 16
+ OpFloat64 OpType = 17
+ OpBool OpType = 18
+ OpString OpType = 19
+ OpBytes OpType = 20
+ OpNumber OpType = 21
+ OpArray OpType = 22
+ OpMap OpType = 23
+ OpSlice OpType = 24
+ OpStruct OpType = 25
+ OpMarshalJSON OpType = 26
+ OpMarshalText OpType = 27
+ OpIntString OpType = 28
+ OpUintString OpType = 29
+ OpFloat32String OpType = 30
+ OpFloat64String OpType = 31
+ OpBoolString OpType = 32
+ OpStringString OpType = 33
+ OpNumberString OpType = 34
+ OpIntPtr OpType = 35
+ OpUintPtr OpType = 36
+ OpFloat32Ptr OpType = 37
+ OpFloat64Ptr OpType = 38
+ OpBoolPtr OpType = 39
+ OpStringPtr OpType = 40
+ OpBytesPtr OpType = 41
+ OpNumberPtr OpType = 42
+ OpArrayPtr OpType = 43
+ OpMapPtr OpType = 44
+ OpSlicePtr OpType = 45
+ OpMarshalJSONPtr OpType = 46
+ OpMarshalTextPtr OpType = 47
+ OpInterfacePtr OpType = 48
+ OpIntPtrString OpType = 49
+ OpUintPtrString OpType = 50
+ OpFloat32PtrString OpType = 51
+ OpFloat64PtrString OpType = 52
+ OpBoolPtrString OpType = 53
+ OpStringPtrString OpType = 54
+ OpNumberPtrString OpType = 55
+ OpStructHead OpType = 56
+ OpStructPtrHead OpType = 57
+ OpStructFieldInt OpType = 58
+ OpStructFieldOmitEmptyInt OpType = 59
+ OpStructEndInt OpType = 60
+ OpStructEndOmitEmptyInt OpType = 61
+ OpStructFieldUint OpType = 62
+ OpStructFieldOmitEmptyUint OpType = 63
+ OpStructEndUint OpType = 64
+ OpStructEndOmitEmptyUint OpType = 65
+ OpStructFieldFloat32 OpType = 66
+ OpStructFieldOmitEmptyFloat32 OpType = 67
+ OpStructEndFloat32 OpType = 68
+ OpStructEndOmitEmptyFloat32 OpType = 69
+ OpStructFieldFloat64 OpType = 70
+ OpStructFieldOmitEmptyFloat64 OpType = 71
+ OpStructEndFloat64 OpType = 72
+ OpStructEndOmitEmptyFloat64 OpType = 73
+ OpStructFieldBool OpType = 74
+ OpStructFieldOmitEmptyBool OpType = 75
+ OpStructEndBool OpType = 76
+ OpStructEndOmitEmptyBool OpType = 77
+ OpStructFieldString OpType = 78
+ OpStructFieldOmitEmptyString OpType = 79
+ OpStructEndString OpType = 80
+ OpStructEndOmitEmptyString OpType = 81
+ OpStructFieldBytes OpType = 82
+ OpStructFieldOmitEmptyBytes OpType = 83
+ OpStructEndBytes OpType = 84
+ OpStructEndOmitEmptyBytes OpType = 85
+ OpStructFieldNumber OpType = 86
+ OpStructFieldOmitEmptyNumber OpType = 87
+ OpStructEndNumber OpType = 88
+ OpStructEndOmitEmptyNumber OpType = 89
+ OpStructFieldArray OpType = 90
+ OpStructFieldOmitEmptyArray OpType = 91
+ OpStructEndArray OpType = 92
+ OpStructEndOmitEmptyArray OpType = 93
+ OpStructFieldMap OpType = 94
+ OpStructFieldOmitEmptyMap OpType = 95
+ OpStructEndMap OpType = 96
+ OpStructEndOmitEmptyMap OpType = 97
+ OpStructFieldSlice OpType = 98
+ OpStructFieldOmitEmptySlice OpType = 99
+ OpStructEndSlice OpType = 100
+ OpStructEndOmitEmptySlice OpType = 101
+ OpStructFieldStruct OpType = 102
+ OpStructFieldOmitEmptyStruct OpType = 103
+ OpStructEndStruct OpType = 104
+ OpStructEndOmitEmptyStruct OpType = 105
+ OpStructFieldMarshalJSON OpType = 106
+ OpStructFieldOmitEmptyMarshalJSON OpType = 107
+ OpStructEndMarshalJSON OpType = 108
+ OpStructEndOmitEmptyMarshalJSON OpType = 109
+ OpStructFieldMarshalText OpType = 110
+ OpStructFieldOmitEmptyMarshalText OpType = 111
+ OpStructEndMarshalText OpType = 112
+ OpStructEndOmitEmptyMarshalText OpType = 113
+ OpStructFieldIntString OpType = 114
+ OpStructFieldOmitEmptyIntString OpType = 115
+ OpStructEndIntString OpType = 116
+ OpStructEndOmitEmptyIntString OpType = 117
+ OpStructFieldUintString OpType = 118
+ OpStructFieldOmitEmptyUintString OpType = 119
+ OpStructEndUintString OpType = 120
+ OpStructEndOmitEmptyUintString OpType = 121
+ OpStructFieldFloat32String OpType = 122
+ OpStructFieldOmitEmptyFloat32String OpType = 123
+ OpStructEndFloat32String OpType = 124
+ OpStructEndOmitEmptyFloat32String OpType = 125
+ OpStructFieldFloat64String OpType = 126
+ OpStructFieldOmitEmptyFloat64String OpType = 127
+ OpStructEndFloat64String OpType = 128
+ OpStructEndOmitEmptyFloat64String OpType = 129
+ OpStructFieldBoolString OpType = 130
+ OpStructFieldOmitEmptyBoolString OpType = 131
+ OpStructEndBoolString OpType = 132
+ OpStructEndOmitEmptyBoolString OpType = 133
+ OpStructFieldStringString OpType = 134
+ OpStructFieldOmitEmptyStringString OpType = 135
+ OpStructEndStringString OpType = 136
+ OpStructEndOmitEmptyStringString OpType = 137
+ OpStructFieldNumberString OpType = 138
+ OpStructFieldOmitEmptyNumberString OpType = 139
+ OpStructEndNumberString OpType = 140
+ OpStructEndOmitEmptyNumberString OpType = 141
+ OpStructFieldIntPtr OpType = 142
+ OpStructFieldOmitEmptyIntPtr OpType = 143
+ OpStructEndIntPtr OpType = 144
+ OpStructEndOmitEmptyIntPtr OpType = 145
+ OpStructFieldUintPtr OpType = 146
+ OpStructFieldOmitEmptyUintPtr OpType = 147
+ OpStructEndUintPtr OpType = 148
+ OpStructEndOmitEmptyUintPtr OpType = 149
+ OpStructFieldFloat32Ptr OpType = 150
+ OpStructFieldOmitEmptyFloat32Ptr OpType = 151
+ OpStructEndFloat32Ptr OpType = 152
+ OpStructEndOmitEmptyFloat32Ptr OpType = 153
+ OpStructFieldFloat64Ptr OpType = 154
+ OpStructFieldOmitEmptyFloat64Ptr OpType = 155
+ OpStructEndFloat64Ptr OpType = 156
+ OpStructEndOmitEmptyFloat64Ptr OpType = 157
+ OpStructFieldBoolPtr OpType = 158
+ OpStructFieldOmitEmptyBoolPtr OpType = 159
+ OpStructEndBoolPtr OpType = 160
+ OpStructEndOmitEmptyBoolPtr OpType = 161
+ OpStructFieldStringPtr OpType = 162
+ OpStructFieldOmitEmptyStringPtr OpType = 163
+ OpStructEndStringPtr OpType = 164
+ OpStructEndOmitEmptyStringPtr OpType = 165
+ OpStructFieldBytesPtr OpType = 166
+ OpStructFieldOmitEmptyBytesPtr OpType = 167
+ OpStructEndBytesPtr OpType = 168
+ OpStructEndOmitEmptyBytesPtr OpType = 169
+ OpStructFieldNumberPtr OpType = 170
+ OpStructFieldOmitEmptyNumberPtr OpType = 171
+ OpStructEndNumberPtr OpType = 172
+ OpStructEndOmitEmptyNumberPtr OpType = 173
+ OpStructFieldArrayPtr OpType = 174
+ OpStructFieldOmitEmptyArrayPtr OpType = 175
+ OpStructEndArrayPtr OpType = 176
+ OpStructEndOmitEmptyArrayPtr OpType = 177
+ OpStructFieldMapPtr OpType = 178
+ OpStructFieldOmitEmptyMapPtr OpType = 179
+ OpStructEndMapPtr OpType = 180
+ OpStructEndOmitEmptyMapPtr OpType = 181
+ OpStructFieldSlicePtr OpType = 182
+ OpStructFieldOmitEmptySlicePtr OpType = 183
+ OpStructEndSlicePtr OpType = 184
+ OpStructEndOmitEmptySlicePtr OpType = 185
+ OpStructFieldMarshalJSONPtr OpType = 186
+ OpStructFieldOmitEmptyMarshalJSONPtr OpType = 187
+ OpStructEndMarshalJSONPtr OpType = 188
+ OpStructEndOmitEmptyMarshalJSONPtr OpType = 189
+ OpStructFieldMarshalTextPtr OpType = 190
+ OpStructFieldOmitEmptyMarshalTextPtr OpType = 191
+ OpStructEndMarshalTextPtr OpType = 192
+ OpStructEndOmitEmptyMarshalTextPtr OpType = 193
+ OpStructFieldInterfacePtr OpType = 194
+ OpStructFieldOmitEmptyInterfacePtr OpType = 195
+ OpStructEndInterfacePtr OpType = 196
+ OpStructEndOmitEmptyInterfacePtr OpType = 197
+ OpStructFieldIntPtrString OpType = 198
+ OpStructFieldOmitEmptyIntPtrString OpType = 199
+ OpStructEndIntPtrString OpType = 200
+ OpStructEndOmitEmptyIntPtrString OpType = 201
+ OpStructFieldUintPtrString OpType = 202
+ OpStructFieldOmitEmptyUintPtrString OpType = 203
+ OpStructEndUintPtrString OpType = 204
+ OpStructEndOmitEmptyUintPtrString OpType = 205
+ OpStructFieldFloat32PtrString OpType = 206
+ OpStructFieldOmitEmptyFloat32PtrString OpType = 207
+ OpStructEndFloat32PtrString OpType = 208
+ OpStructEndOmitEmptyFloat32PtrString OpType = 209
+ OpStructFieldFloat64PtrString OpType = 210
+ OpStructFieldOmitEmptyFloat64PtrString OpType = 211
+ OpStructEndFloat64PtrString OpType = 212
+ OpStructEndOmitEmptyFloat64PtrString OpType = 213
+ OpStructFieldBoolPtrString OpType = 214
+ OpStructFieldOmitEmptyBoolPtrString OpType = 215
+ OpStructEndBoolPtrString OpType = 216
+ OpStructEndOmitEmptyBoolPtrString OpType = 217
+ OpStructFieldStringPtrString OpType = 218
+ OpStructFieldOmitEmptyStringPtrString OpType = 219
+ OpStructEndStringPtrString OpType = 220
+ OpStructEndOmitEmptyStringPtrString OpType = 221
+ OpStructFieldNumberPtrString OpType = 222
+ OpStructFieldOmitEmptyNumberPtrString OpType = 223
+ OpStructEndNumberPtrString OpType = 224
+ OpStructEndOmitEmptyNumberPtrString OpType = 225
+ OpStructFieldInterface OpType = 226
+ OpStructFieldOmitEmptyInterface OpType = 227
+ OpStructEndInterface OpType = 228
+ OpStructEndOmitEmptyInterface OpType = 229
+ OpStructField OpType = 230
+ OpStructFieldOmitEmpty OpType = 231
+ OpStructEnd OpType = 232
+ OpStructEndOmitEmpty OpType = 233
+ OpStructFieldInt3 OpType = 234
+ OpStructFieldInt2 OpType = 235
+ OpStructFieldUint3 OpType = 236
+ OpStructFieldUint2 OpType = 237
+ OpStructFieldFloat643 OpType = 238
+ OpStructFieldFloat642 OpType = 239
+ OpStructFieldString3 OpType = 240
+ OpStructFieldString2 OpType = 241
+ OpStructFieldBool3 OpType = 242
+ OpStructFieldBool2 OpType = 243
)
func (t OpType) String() string {
- if int(t) >= 400 {
+ if int(t) >= 244 {
return ""
}
return opTypeStrings[int(t)]
@@ -867,42 +555,15 @@ func (t OpType) CodeType() CodeType {
}
func (t OpType) HeadToPtrHead() OpType {
- if strings.Index(t.String(), "PtrHead") > 0 {
- return t
- }
-
- idx := strings.Index(t.String(), "Head")
- if idx == -1 {
- return t
- }
- suffix := "PtrHead" + t.String()[idx+len("Head"):]
-
- const toPtrOffset = 2
- if strings.Contains(OpType(int(t)+toPtrOffset).String(), suffix) {
- return OpType(int(t) + toPtrOffset)
+ if t == OpStructHead {
+ return OpStructPtrHead
}
return t
}
-func (t OpType) HeadToOmitEmptyHead() OpType {
- const toOmitEmptyOffset = 1
- if strings.Contains(OpType(int(t)+toOmitEmptyOffset).String(), "OmitEmpty") {
- return OpType(int(t) + toOmitEmptyOffset)
- }
-
- return t
-}
-
func (t OpType) PtrHeadToHead() OpType {
- idx := strings.Index(t.String(), "PtrHead")
- if idx == -1 {
- return t
- }
- suffix := t.String()[idx+len("Ptr"):]
-
- const toPtrOffset = 2
- if strings.Contains(OpType(int(t)-toPtrOffset).String(), suffix) {
- return OpType(int(t) - toPtrOffset)
+ if t == OpStructPtrHead {
+ return OpStructHead
}
return t
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/query.go b/vendor/github.com/goccy/go-json/internal/encoder/query.go
index 1e1850cc1..ae8d0cdb1 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/query.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/query.go
@@ -7,8 +7,8 @@ import (
)
var (
- Marshal func(interface{}) ([]byte, error)
- Unmarshal func([]byte, interface{}) error
+ Marshal func(any) ([]byte, error)
+ Unmarshal func([]byte, any) error
)
type FieldQuery struct {
@@ -47,7 +47,7 @@ func (q *FieldQuery) QueryString() (FieldQueryString, error) {
type FieldQueryString string
func (s FieldQueryString) Build() (*FieldQuery, error) {
- var query interface{}
+ var query any
if err := Unmarshal([]byte(s), &query); err != nil {
return nil, err
}
@@ -72,7 +72,7 @@ func (s FieldQueryString) buildString(v reflect.Value) (*FieldQuery, error) {
b := []byte(v.String())
switch b[0] {
case '[', '{':
- var query interface{}
+ var query any
if err := Unmarshal(b, &query); err != nil {
return nil, err
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler.go b/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler.go
new file mode 100644
index 000000000..9ed649699
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler.go
@@ -0,0 +1,43 @@
+//go:build go1.24
+
+package encoder
+
+import (
+ "reflect"
+ "time"
+ "unsafe"
+)
+
+// The output of time.Time.MarshalJSON, time.Time being the type of the standard library which is encoded the
+// most, is known: the text of AppendText quoted. It is written by AppendText, into the buffer, without the
+// allocation of the output. The other types of the standard library are called, and their outputs are not checked
+// ( see MarshalerCall.trusted ).
+//
+// time is the one package of the standard library which is imported for its types ( the others are found by their
+// paths, see runtime.IsStdMarshalerType ): it is linked into every program which uses go-json anyway, as context
+// imports it, and AppendText called directly costs less than called by its code, as a method found by reflect is.
+
+var (
+ timeType = reflect.TypeOf(time.Time{})
+ timePtrType = reflect.PointerTo(timeType)
+)
+
+// stdJSONAppender returns the function which writes the output of MarshalJSON of the type of the standard library,
+// or nil if it is called. The receiver is the data word of the interface value ( see MarshalerCall ): the address
+// of a time.Time, for a time.Time and for a *time.Time alike.
+func stdJSONAppender(recv reflect.Type) func([]byte, unsafe.Pointer) ([]byte, bool) {
+ if recv != timeType && recv != timePtrType {
+ return nil
+ }
+ return appendTimeJSON
+}
+
+// appendTimeJSON writes what time.Time.MarshalJSON returns: the text of AppendText quoted, which has nothing to
+// escape. AppendText fails when MarshalJSON does, whose error is then the one of the call of MarshalJSON.
+func appendTimeJSON(b []byte, p unsafe.Pointer) ([]byte, bool) {
+ out, err := (*time.Time)(p).AppendText(append(b, '"'))
+ if err != nil {
+ return b, false
+ }
+ return append(out, '"'), true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler_legacy.go b/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler_legacy.go
new file mode 100644
index 000000000..7c0653f08
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/std_marshaler_legacy.go
@@ -0,0 +1,13 @@
+//go:build !go1.24
+
+package encoder
+
+import (
+ "reflect"
+ "unsafe"
+)
+
+// stdJSONAppender returns nil: time.Time has AppendText from Go 1.24 on.
+func stdJSONAppender(_ reflect.Type) func([]byte, unsafe.Pointer) ([]byte, bool) {
+ return nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string.go b/vendor/github.com/goccy/go-json/internal/encoder/string.go
index 4abb84165..ae2ddcde2 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/string.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string.go
@@ -25,8 +25,9 @@
package encoder
import (
+ "encoding/binary"
"math/bits"
- "reflect"
+ "unicode/utf8"
"unsafe"
)
@@ -37,148 +38,442 @@ const (
var hex = "0123456789abcdef"
-//nolint:govet
-func stringToUint64Slice(s string) []uint64 {
- return *(*[]uint64)(unsafe.Pointer(&reflect.SliceHeader{
- Data: ((*reflect.StringHeader)(unsafe.Pointer(&s))).Data,
- Len: len(s) / 8,
- Cap: len(s) / 8,
- }))
+// stringEscape is what decides whether a string has a byte to escape, for a combination of the options.
+type stringEscape struct {
+ // chars are three characters to escape in addition to the control characters, '"' and '\\',
+ // repeated in every byte of a word. They are '<', '>' and '&', or '"' for nothing more.
+ chars [3]uint64
+ // high is msb if a byte which is not ASCII is to be looked at, to normalize UTF-8, or 0.
+ high uint64
+ // table is whether a byte may need an escape.
+ table *[256]bool
+ // tables is table as the tables of the scan by SIMD.
+ tables nibbleTables
+ // appendEscaped appends a string which may have a byte to escape.
+ appendEscaped func(buf []byte, s string) []byte
}
-func AppendString(ctx *RuntimeContext, buf []byte, s string) []byte {
- if ctx.Option.Flag&HTMLEscapeOption != 0 {
- if ctx.Option.Flag&NormalizeUTF8Option != 0 {
- return appendNormalizedHTMLString(buf, s)
+const (
+ stringEscapeNormalize = 1 << iota
+ stringEscapeHTML
+)
+
+// stringEscapes is indexed by the combination of stringEscapeNormalize and stringEscapeHTML.
+var stringEscapes = [4]stringEscape{
+ 0: {
+ chars: [3]uint64{lsb * '"', lsb * '"', lsb * '"'},
+ table: &needEscape,
+ appendEscaped: appendString,
+ },
+ stringEscapeNormalize: {
+ chars: [3]uint64{lsb * '"', lsb * '"', lsb * '"'},
+ high: msb,
+ table: &needEscapeNormalizeUTF8,
+ appendEscaped: appendNormalizedString,
+ },
+ stringEscapeHTML: {
+ chars: [3]uint64{lsb * '<', lsb * '>', lsb * '&'},
+ table: &needEscapeHTML,
+ appendEscaped: appendHTMLString,
+ },
+ stringEscapeHTML | stringEscapeNormalize: {
+ chars: [3]uint64{lsb * '<', lsb * '>', lsb * '&'},
+ high: msb,
+ table: &needEscapeHTMLNormalizeUTF8,
+ appendEscaped: appendNormalizedHTMLString,
+ },
+}
+
+// escapeSequences are the escapes of the bytes which the loop of the escapes by SIMD writes ( see
+// appendEscapedSIMD ): the bytes of the escape of a byte, in the order of a little-endian word, and its length in
+// the top byte. They are the ones of the appendString functions. A byte which is not ASCII is 0: it is left to
+// the caller, which escapes it if UTF-8 is normalized.
+var escapeSequences = func() [256]uint64 {
+ var seqs [256]uint64
+ for c := 0; c < 0x80; c++ {
+ var seq string
+ switch c {
+ case '"', '\\':
+ seq = string([]byte{'\\', byte(c)})
+ case '\n':
+ seq = `\n`
+ case '\r':
+ seq = `\r`
+ case '\t':
+ seq = `\t`
+ case '\b':
+ seq = backspaceEscape
+ case '\f':
+ seq = formFeedEscape
+ case '<', '>', '&':
+ seq = `\u00` + string([]byte{hex[c>>4], hex[c&0xF]})
+ default:
+ if c < 0x20 {
+ seq = `\u00` + string([]byte{hex[c>>4], hex[c&0xF]})
+ }
+ }
+ var w uint64
+ for i := len(seq) - 1; i >= 0; i-- {
+ w = w<<8 | uint64(seq[i])
}
- return appendHTMLString(buf, s)
+ seqs[c] = w | uint64(len(seq))<<56
}
- if ctx.Option.Flag&NormalizeUTF8Option != 0 {
- return appendNormalizedString(buf, s)
+ return seqs
+}()
+
+// escapeTables are the tables of stringEscapes, which the functions of the escapes refer to by this array:
+// stringEscapes refers to the functions, so they can't refer to it.
+var escapeTables [4]*nibbleTables
+
+func init() {
+ for i := range stringEscapes {
+ stringEscapes[i].tables = newNibbleTables(stringEscapes[i].table)
+ escapeTables[i] = &stringEscapes[i].tables
}
- return appendString(buf, s)
}
-func appendNormalizedHTMLString(buf []byte, s string) []byte {
- valLen := len(s)
- if valLen == 0 {
- return append(buf, `""`...)
+// The functions below return the mask of the bytes of a word which may need an escape: the most significant bit
+// of such a byte is set. A byte after one to escape may be set too, because of the borrow of the subtractions.
+// A mask is made of parts, each of which is small enough to be inlined: a call for every word costs more than
+// the mask itself.
+//
+// `x - lsb` sets the most significant bit of a byte of x which is zero, and of one which already has it.
+// If UTF-8 is normalized, a byte which is not ASCII is looked at anyway, so the latter doesn't matter and the
+// loose masks are enough. Otherwise `&^ x` leaves only the former, so that a string which is not ASCII is not
+// taken for one to escape.
+
+// looseCommonMask is the mask of the control characters, '"', '\\' and the bytes which are not ASCII.
+func looseCommonMask(n uint64) uint64 {
+ return n | (n - lsb*0x20) | ((n ^ (lsb * '"')) - lsb) | ((n ^ (lsb * '\\')) - lsb)
+}
+
+// looseCharsMask is the mask of chars, and of the bytes which are not ASCII.
+func (e *stringEscape) looseCharsMask(n uint64) uint64 {
+ return ((n ^ e.chars[0]) - lsb) | ((n ^ e.chars[1]) - lsb) | ((n ^ e.chars[2]) - lsb)
+}
+
+// exactCommonMask is the mask of the control characters, '"' and '\\'.
+func exactCommonMask(n uint64) uint64 {
+ quote := n ^ (lsb * '"')
+ backslash := n ^ (lsb * '\\')
+ return ((n - lsb*0x20) &^ n) | ((quote - lsb) &^ quote) | ((backslash - lsb) &^ backslash)
+}
+
+// exactCharsMask is the mask of chars.
+func (e *stringEscape) exactCharsMask(n uint64) uint64 {
+ c0, c1, c2 := n^e.chars[0], n^e.chars[1], n^e.chars[2]
+ return ((c0 - lsb) &^ c0) | ((c1 - lsb) &^ c1) | ((c2 - lsb) &^ c2)
+}
+
+// hasExactEscape is whether a word of the string has a byte to escape, not counting the bytes which are not
+// ASCII. The string is 8 bytes or longer.
+func (e *stringEscape) hasExactEscape(src unsafe.Pointer, n int) bool {
+ i := 0
+ for ; i+8 <= n; i += 8 {
+ if w := *(*uint64)(unsafe.Add(src, i)); (exactCommonMask(w)|e.exactCharsMask(w))&msb != 0 {
+ return true
+ }
}
- buf = append(buf, '"')
- var (
- i, j int
- )
- if valLen >= 8 {
- chunks := stringToUint64Slice(s)
- for _, n := range chunks {
- // combine masks before checking for the MSB of each byte. We include
- // `n` in the mask to check whether any of the *input* byte MSBs were
- // set (i.e. the byte was outside the ASCII range).
- mask := n | (n - (lsb * 0x20)) |
- ((n ^ (lsb * '"')) - lsb) |
- ((n ^ (lsb * '\\')) - lsb) |
- ((n ^ (lsb * '<')) - lsb) |
- ((n ^ (lsb * '>')) - lsb) |
- ((n ^ (lsb * '&')) - lsb)
- if (mask & msb) != 0 {
- j = bits.TrailingZeros64(mask&msb) / 8
- goto ESCAPE_END
+ if i < n {
+ w := *(*uint64)(unsafe.Add(src, n-8))
+ return (exactCommonMask(w)|e.exactCharsMask(w))&msb != 0
+ }
+ return false
+}
+
+// hasLooseEscape is whether a word of the string may have a byte to escape, or has a byte which is not ASCII.
+// The string is 8 bytes or longer. It is cheaper than hasExactEscape, and it is exact for a string of ASCII,
+// which most of the strings are.
+func (e *stringEscape) hasLooseEscape(src unsafe.Pointer, n int) bool {
+ i := 0
+ for ; i+8 <= n; i += 8 {
+ if w := *(*uint64)(unsafe.Add(src, i)); (looseCommonMask(w)|e.looseCharsMask(w))&msb != 0 {
+ return true
+ }
+ }
+ if i < n {
+ // the last word overlaps the previous one.
+ w := *(*uint64)(unsafe.Add(src, n-8))
+ return (looseCommonMask(w)|e.looseCharsMask(w))&msb != 0
+ }
+ return false
+}
+
+// maxInlineCopySize is the size of the longest string which is copied without calling memmove.
+const maxInlineCopySize = 16
+
+// growForString returns buf which has the capacity to append n bytes, growing as append does.
+//
+//go:noinline
+func growForString(buf []byte, n int) []byte {
+ grown := make([]byte, len(buf), 2*cap(buf)+n)
+ copy(grown, buf)
+ return grown
+}
+
+// AppendString appends the string as a JSON string.
+//
+// Most of the strings have nothing to escape and are short, so that case is handled here. A string of up to
+// maxOnePassLength bytes is looked at and written to the capacity of the buffer in one pass, by bytes, by the
+// halves of a word or by words, and nothing is called; a longer one is looked at by SIMD ( or by words ) and
+// then copied. A string which may have a byte to escape is left to the function for the options, and what was
+// written for it is left out of the buffer.
+func AppendString(ctx *RuntimeContext, buf []byte, s string) []byte {
+ n := len(s)
+ if n == 0 {
+ // no byte to escape: the options are not looked at.
+ return append(buf, '"', '"')
+ }
+ index := 0
+ if ctx.Option.Flag&HTMLEscapeOption != 0 {
+ index = stringEscapeHTML
+ }
+ if ctx.Option.Flag&NormalizeUTF8Option != 0 {
+ index |= stringEscapeNormalize
+ }
+ escape := &stringEscapes[index]
+
+ src := unsafe.Pointer(unsafe.StringData(s))
+ if n < 4 {
+ table := escape.table
+ for i := 0; i < n; i++ {
+ if table[*(*byte)(unsafe.Add(src, i))] {
+ return escape.appendEscaped(buf, s)
}
}
- for i := len(chunks) * 8; i < valLen; i++ {
- if needEscapeHTMLNormalizeUTF8[s[i]] {
- j = i
- goto ESCAPE_END
+ if l := len(buf); cap(buf)-l >= n+2 {
+ // the first, the middle and the last byte are every byte of 1 to 3 bytes.
+ buf = buf[:l+n+2]
+ p := unsafe.Pointer(unsafe.SliceData(buf))
+ *(*byte)(unsafe.Add(p, l)) = '"'
+ *(*byte)(unsafe.Add(p, l+1)) = *(*byte)(src)
+ *(*byte)(unsafe.Add(p, l+1+(n>>1))) = *(*byte)(unsafe.Add(src, n>>1))
+ *(*byte)(unsafe.Add(p, l+n)) = *(*byte)(unsafe.Add(src, n-1))
+ *(*byte)(unsafe.Add(p, l+n+1)) = '"'
+ return buf
+ }
+ } else if n < 8 {
+ // the two halves overlap, so that the word has every byte of the string and nothing else.
+ w := uint64(*(*uint32)(src)) | uint64(*(*uint32)(unsafe.Add(src, n-4)))<<32
+ if (looseCommonMask(w)|escape.looseCharsMask(w))&msb != 0 &&
+ (escape.high != 0 || (exactCommonMask(w)|escape.exactCharsMask(w))&msb != 0) {
+ return escape.appendEscaped(buf, s)
+ }
+ if l := len(buf); cap(buf)-l >= n+2 {
+ // the halves of the word are written where they were read from.
+ buf = buf[:l+n+2]
+ p := unsafe.Pointer(unsafe.SliceData(buf))
+ *(*byte)(unsafe.Add(p, l)) = '"'
+ *(*uint32)(unsafe.Add(p, l+1)) = uint32(w)
+ *(*uint32)(unsafe.Add(p, l+n-3)) = uint32(w >> 32)
+ *(*byte)(unsafe.Add(p, l+n+1)) = '"'
+ return buf
+ }
+ } else if l := len(buf); n <= maxOnePassLength && cap(buf)-l >= n+2 {
+ // the first and the last word and the ones between them, which overlap: 8 to maxOnePassLength bytes, 31
+ // at most, are 2 to 4 words. A buffer without the capacity is grown below.
+ dst := unsafe.Add(unsafe.Pointer(unsafe.SliceData(buf)), l+1)
+ first, last := *(*uint64)(src), *(*uint64)(unsafe.Add(src, n-8))
+ *(*uint64)(dst) = first
+ *(*uint64)(unsafe.Add(dst, n-8)) = last
+ mask := looseCommonMask(first) | escape.looseCharsMask(first) | looseCommonMask(last) | escape.looseCharsMask(last)
+ if n > 16 {
+ w := *(*uint64)(unsafe.Add(src, 8))
+ *(*uint64)(unsafe.Add(dst, 8)) = w
+ mask |= looseCommonMask(w) | escape.looseCharsMask(w)
+ if n > 24 {
+ w := *(*uint64)(unsafe.Add(src, 16))
+ *(*uint64)(unsafe.Add(dst, 16)) = w
+ mask |= looseCommonMask(w) | escape.looseCharsMask(w)
}
}
- // no found any escape characters.
- return append(append(buf, s...), '"')
+ if mask&msb != 0 && (escape.high != 0 || escape.hasExactEscape(src, n)) {
+ // a byte which is not ASCII is to be looked at only if UTF-8 is normalized.
+ return escape.appendEscaped(buf, s)
+ }
+ // the position is taken from buf again, which is kept across the call above, so that nothing more is.
+ l := len(buf)
+ buf = buf[:l+n+2]
+ p := unsafe.Pointer(unsafe.SliceData(buf))
+ *(*byte)(unsafe.Add(p, l)) = '"'
+ *(*byte)(unsafe.Add(p, l+n+1)) = '"'
+ return buf
+ } else if found, ok := scanBytesSIMD(src, n, &escape.tables); ok {
+ if found {
+ return escape.appendEscaped(buf, s)
+ }
+ } else if escape.hasLooseEscape(src, n) && (escape.high != 0 || escape.hasExactEscape(src, n)) {
+ // a byte which is not ASCII is to be looked at only if UTF-8 is normalized.
+ return escape.appendEscaped(buf, s)
}
-ESCAPE_END:
- for j < valLen {
- c := s[j]
- if !needEscapeHTMLNormalizeUTF8[c] {
- // fast path: most of the time, printable ascii characters are used
+ l := len(buf)
+ if cap(buf)-l < n+2 {
+ buf = growForString(buf, n+2)
+ }
+ buf = buf[:l+n+2]
+ dst := unsafe.Pointer(unsafe.SliceData(buf[l:]))
+ *(*byte)(dst) = '"'
+ dst = unsafe.Add(dst, 1)
+ switch {
+ case n > maxInlineCopySize:
+ copy(buf[l+1:], s)
+ case n >= 8:
+ // the two words overlap.
+ *(*uint64)(dst) = *(*uint64)(src)
+ *(*uint64)(unsafe.Add(dst, n-8)) = *(*uint64)(unsafe.Add(src, n-8))
+ case n >= 4:
+ *(*uint32)(dst) = *(*uint32)(src)
+ *(*uint32)(unsafe.Add(dst, n-4)) = *(*uint32)(unsafe.Add(src, n-4))
+ case n > 0:
+ // the first, the middle and the last byte are every byte of 1 to 3 bytes.
+ *(*byte)(dst) = *(*byte)(src)
+ *(*byte)(unsafe.Add(dst, n>>1)) = *(*byte)(unsafe.Add(src, n>>1))
+ *(*byte)(unsafe.Add(dst, n-1)) = *(*byte)(unsafe.Add(src, n-1))
+ }
+ *(*byte)(unsafe.Add(dst, n)) = '"'
+ return buf
+}
+
+// skipPlainRunes returns the index of the first byte of s from j which may need an escape by table, or len(s),
+// taking the characters of commonRuneSize as bytes which need none: the characters of a text of CJK are skipped by
+// this loop, called once for a run of them, and not one by one by the loop of the escapes, which then keeps its
+// layout for the bytes of ASCII. The loop of the escapes passes s up to its limit, so that it gives the rest of a
+// long string back to the loop by SIMD as before.
+//
+//go:noinline
+func skipPlainRunes(s string, j int, table *[256]bool) int {
+ for j < len(s) {
+ c := s[j]
+ if !table[c] {
j++
continue
}
+ size := commonRuneSize(s, j)
+ if size == 0 {
+ break
+ }
+ j += size
+ }
+ return j
+}
- switch c {
- case '\\', '"':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', c)
- i = j + 1
- j = j + 1
- continue
-
- case '\n':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'n')
- i = j + 1
- j = j + 1
- continue
-
- case '\r':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'r')
- i = j + 1
- j = j + 1
- continue
-
- case '\t':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 't')
- i = j + 1
- j = j + 1
- continue
+// commonRuneSize returns the size of the character at s[j] if it is one of two bytes, or one of three bytes whose
+// first byte is 0xE3 to 0xEC, 0xEE or 0xEF, as the characters of CJK are, and its next bytes are continuation
+// bytes, or 0. Such a character is valid UTF-8 and is not escaped whatever its continuation bytes are, so it is
+// written as it is without decodeRuneInString, which is not inlined.
+func commonRuneSize(s string, j int) int {
+ c := s[j]
+ if c-0xc2 < 0xe0-0xc2 {
+ if j+1 < len(s) && s[j+1]^0x80 < 0x40 {
+ return 2
+ }
+ } else if c-0xe3 < 0xed-0xe3 || c-0xee < 2 {
+ if j+2 < len(s) && (s[j+1]^0x80)|(s[j+2]^0x80) < 0x40 {
+ return 3
+ }
+ }
+ return 0
+}
- case '<', '>', '&':
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
+func appendNormalizedHTMLString(buf []byte, s string) []byte {
+ valLen := len(s)
+ if valLen == 0 {
+ return append(buf, `""`...)
+ }
+ buf = append(buf, '"')
+ var i int
+ // the bytes up to the first one which may need an escape are skipped by SIMD, or by words.
+ j := 0
+ // limit is where the loop of the bytes gives the rest of a long string back to the loop of the escapes by
+ // SIMD, which stops at a block of 32 bytes with invalid UTF-8, U+2028 or U+2029: the loop of the bytes
+ // escapes that block, so that the loop by SIMD is called once for 32 bytes at most.
+ limit := valLen
+ if valLen >= 32 && hasEscapeLoop {
+ // a long string is escaped by SIMD, up to a byte which is left to this loop
+ buf, j = appendEscapedSIMD(buf, s, escapeTables[stringEscapeHTML], true)
+ i = j
+ limit = min(valLen, j+32)
+ } else if valLen >= 8 {
+ // the last word overlaps the one before it: the first byte which may need an escape is in the word at
+ // k, or it is none if the mask of the last word is 0, and j is then valLen.
+ k := 0
+ m := maskNormalizedHTML(wordAt(s, 0))
+ for m == 0 && k+16 <= valLen {
+ k += 8
+ m = maskNormalizedHTML(wordAt(s, k))
+ }
+ if m == 0 && k+8 < valLen {
+ k = valLen - 8
+ m = maskNormalizedHTML(wordAt(s, k))
+ }
+ j = k + bits.TrailingZeros64(m)/8
+ }
+ for {
+ for j < limit {
+ c := s[j]
+
+ if !needEscapeHTMLNormalizeUTF8[c] {
+ // fast path: most of the time, printable ascii characters are used
+ j++
+ continue
+ }
- case 0x00, 0x01, 0x02, 0x03, 0x04, 0x05, 0x06, 0x07, 0x08, 0x0B, 0x0C, 0x0E, 0x0F, // 0x00-0x0F
- 0x10, 0x11, 0x12, 0x13, 0x14, 0x15, 0x16, 0x17, 0x18, 0x19, 0x1A, 0x1B, 0x1C, 0x1D, 0x1E, 0x1F: // 0x10-0x1F
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
+ if seq := escapeSequences[c]; seq != 0 {
+ // a byte of ASCII, escaped by its sequence ( see escapeSequences ): the bytes of the word after
+ // its length are written over by what follows.
+ buf = append(buf, s[i:j]...)
+ l := len(buf)
+ buf = binary.LittleEndian.AppendUint64(buf, seq)[:l+int(seq>>56)]
+ i = j + 1
+ j = j + 1
+ continue
+ }
+ if c >= utf8.RuneSelf {
+ if k := skipPlainRunes(s[:limit], j, &needEscapeHTMLNormalizeUTF8); k != j {
+ j = k
+ continue
+ }
+ }
+ state, size := decodeRuneInString(s[j:])
+ switch state {
+ case runeErrorState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, invalidUTF8...)
+ i = j + 1
+ j = j + 1
+ continue
+ // U+2028 is LINE SEPARATOR.
+ // U+2029 is PARAGRAPH SEPARATOR.
+ // They are both technically valid characters in JSON strings,
+ // but don't work in JSONP, which has to be evaluated as JavaScript,
+ // and can lead to security holes there. It is valid JSON to
+ // escape them, so we do so unconditionally.
+ // See http://timelessrepo.com/json-isnt-a-javascript-subset for discussion.
+ case lineSepState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, `\u2028`...)
+ i = j + 3
+ j = j + 3
+ continue
+ case paragraphSepState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, `\u2029`...)
+ i = j + 3
+ j = j + 3
+ continue
+ }
+ j += size
}
- state, size := decodeRuneInString(s[j:])
- switch state {
- case runeErrorState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\ufffd`...)
- i = j + 1
- j = j + 1
- continue
- // U+2028 is LINE SEPARATOR.
- // U+2029 is PARAGRAPH SEPARATOR.
- // They are both technically valid characters in JSON strings,
- // but don't work in JSONP, which has to be evaluated as JavaScript,
- // and can lead to security holes there. It is valid JSON to
- // escape them, so we do so unconditionally.
- // See http://timelessrepo.com/json-isnt-a-javascript-subset for discussion.
- case lineSepState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u2028`...)
- i = j + 3
- j = j + 3
- continue
- case paragraphSepState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u2029`...)
- i = j + 3
- j = j + 3
- continue
+ if j >= valLen {
+ break
}
- j += size
+ buf = append(buf, s[i:j]...)
+ var n int
+ buf, n = appendEscapedSIMD(buf, s[j:], escapeTables[stringEscapeHTML], true)
+ j += n
+ i = j
+ limit = min(valLen, j+32)
}
return append(append(buf, s[i:]...), '"')
@@ -190,36 +485,28 @@ func appendHTMLString(buf []byte, s string) []byte {
return append(buf, `""`...)
}
buf = append(buf, '"')
- var (
- i, j int
- )
- if valLen >= 8 {
- chunks := stringToUint64Slice(s)
- for _, n := range chunks {
- // combine masks before checking for the MSB of each byte. We include
- // `n` in the mask to check whether any of the *input* byte MSBs were
- // set (i.e. the byte was outside the ASCII range).
- mask := n | (n - (lsb * 0x20)) |
- ((n ^ (lsb * '"')) - lsb) |
- ((n ^ (lsb * '\\')) - lsb) |
- ((n ^ (lsb * '<')) - lsb) |
- ((n ^ (lsb * '>')) - lsb) |
- ((n ^ (lsb * '&')) - lsb)
- if (mask & msb) != 0 {
- j = bits.TrailingZeros64(mask&msb) / 8
- goto ESCAPE_END
- }
+ var i int
+ // the bytes up to the first one which may need an escape are skipped by SIMD, or by words.
+ j := 0
+ if valLen >= 32 && hasEscapeLoop {
+ // a long string is escaped by SIMD, up to a byte which is left to this loop
+ buf, j = appendEscapedSIMD(buf, s, escapeTables[stringEscapeHTML], false)
+ i = j
+ } else if valLen >= 8 {
+ // the last word overlaps the one before it: the first byte which may need an escape is in the word at
+ // k, or it is none if the mask of the last word is 0, and j is then valLen.
+ k := 0
+ m := maskNormalizedHTML(wordAt(s, 0))
+ for m == 0 && k+16 <= valLen {
+ k += 8
+ m = maskNormalizedHTML(wordAt(s, k))
}
- for i := len(chunks) * 8; i < valLen; i++ {
- if needEscapeHTML[s[i]] {
- j = i
- goto ESCAPE_END
- }
+ if m == 0 && k+8 < valLen {
+ k = valLen - 8
+ m = maskNormalizedHTML(wordAt(s, k))
}
- // no found any escape characters.
- return append(append(buf, s...), '"')
+ j = k + bits.TrailingZeros64(m)/8
}
-ESCAPE_END:
for j < valLen {
c := s[j]
@@ -229,53 +516,14 @@ ESCAPE_END:
continue
}
- switch c {
- case '\\', '"':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', c)
- i = j + 1
- j = j + 1
- continue
-
- case '\n':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'n')
- i = j + 1
- j = j + 1
- continue
-
- case '\r':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'r')
- i = j + 1
- j = j + 1
- continue
-
- case '\t':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 't')
- i = j + 1
- j = j + 1
- continue
-
- case '<', '>', '&':
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
-
- case 0x00, 0x01, 0x02, 0x03, 0x04, 0x05, 0x06, 0x07, 0x08, 0x0B, 0x0C, 0x0E, 0x0F, // 0x00-0x0F
- 0x10, 0x11, 0x12, 0x13, 0x14, 0x15, 0x16, 0x17, 0x18, 0x19, 0x1A, 0x1B, 0x1C, 0x1D, 0x1E, 0x1F: // 0x10-0x1F
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
- }
- j++
+ // a byte of ASCII, escaped by its sequence ( see escapeSequences ): the bytes of the word after its
+ // length are written over by what follows.
+ seq := escapeSequences[c]
+ buf = append(buf, s[i:j]...)
+ l := len(buf)
+ buf = binary.LittleEndian.AppendUint64(buf, seq)[:l+int(seq>>56)]
+ i = j + 1
+ j = j + 1
}
return append(append(buf, s[i:]...), '"')
@@ -287,110 +535,98 @@ func appendNormalizedString(buf []byte, s string) []byte {
return append(buf, `""`...)
}
buf = append(buf, '"')
- var (
- i, j int
- )
- if valLen >= 8 {
- chunks := stringToUint64Slice(s)
- for _, n := range chunks {
- // combine masks before checking for the MSB of each byte. We include
- // `n` in the mask to check whether any of the *input* byte MSBs were
- // set (i.e. the byte was outside the ASCII range).
- mask := n | (n - (lsb * 0x20)) |
- ((n ^ (lsb * '"')) - lsb) |
- ((n ^ (lsb * '\\')) - lsb)
- if (mask & msb) != 0 {
- j = bits.TrailingZeros64(mask&msb) / 8
- goto ESCAPE_END
- }
+ var i int
+ // the bytes up to the first one which may need an escape are skipped by SIMD, or by words.
+ j := 0
+ // limit is where the loop of the bytes gives the rest of a long string back to the loop of the escapes by
+ // SIMD, which stops at a block of 32 bytes with invalid UTF-8, U+2028 or U+2029: the loop of the bytes
+ // escapes that block, so that the loop by SIMD is called once for 32 bytes at most.
+ limit := valLen
+ if valLen >= 32 && hasEscapeLoop {
+ // a long string is escaped by SIMD, up to a byte which is left to this loop
+ buf, j = appendEscapedSIMD(buf, s, escapeTables[0], true)
+ i = j
+ limit = min(valLen, j+32)
+ } else if valLen >= 8 {
+ // the last word overlaps the one before it: the first byte which may need an escape is in the word at
+ // k, or it is none if the mask of the last word is 0, and j is then valLen.
+ k := 0
+ m := maskNormalized(wordAt(s, 0))
+ for m == 0 && k+16 <= valLen {
+ k += 8
+ m = maskNormalized(wordAt(s, k))
}
- valLen := len(s)
- for i := len(chunks) * 8; i < valLen; i++ {
- if needEscapeNormalizeUTF8[s[i]] {
- j = i
- goto ESCAPE_END
- }
+ if m == 0 && k+8 < valLen {
+ k = valLen - 8
+ m = maskNormalized(wordAt(s, k))
}
- return append(append(buf, s...), '"')
+ j = k + bits.TrailingZeros64(m)/8
}
-ESCAPE_END:
- for j < valLen {
- c := s[j]
-
- if !needEscapeNormalizeUTF8[c] {
- // fast path: most of the time, printable ascii characters are used
- j++
- continue
- }
-
- switch c {
- case '\\', '"':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', c)
- i = j + 1
- j = j + 1
- continue
-
- case '\n':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'n')
- i = j + 1
- j = j + 1
- continue
-
- case '\r':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'r')
- i = j + 1
- j = j + 1
- continue
-
- case '\t':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 't')
- i = j + 1
- j = j + 1
- continue
+ for {
+ for j < limit {
+ c := s[j]
+
+ if !needEscapeNormalizeUTF8[c] {
+ // fast path: most of the time, printable ascii characters are used
+ j++
+ continue
+ }
- case 0x00, 0x01, 0x02, 0x03, 0x04, 0x05, 0x06, 0x07, 0x08, 0x0B, 0x0C, 0x0E, 0x0F, // 0x00-0x0F
- 0x10, 0x11, 0x12, 0x13, 0x14, 0x15, 0x16, 0x17, 0x18, 0x19, 0x1A, 0x1B, 0x1C, 0x1D, 0x1E, 0x1F: // 0x10-0x1F
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
+ if seq := escapeSequences[c]; seq != 0 {
+ // a byte of ASCII, escaped by its sequence ( see escapeSequences ): the bytes of the word after
+ // its length are written over by what follows.
+ buf = append(buf, s[i:j]...)
+ l := len(buf)
+ buf = binary.LittleEndian.AppendUint64(buf, seq)[:l+int(seq>>56)]
+ i = j + 1
+ j = j + 1
+ continue
+ }
+ if c >= utf8.RuneSelf {
+ if k := skipPlainRunes(s[:limit], j, &needEscapeNormalizeUTF8); k != j {
+ j = k
+ continue
+ }
+ }
+ state, size := decodeRuneInString(s[j:])
+ switch state {
+ case runeErrorState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, invalidUTF8...)
+ i = j + 1
+ j = j + 1
+ continue
+ // U+2028 is LINE SEPARATOR.
+ // U+2029 is PARAGRAPH SEPARATOR.
+ // They are both technically valid characters in JSON strings,
+ // but don't work in JSONP, which has to be evaluated as JavaScript,
+ // and can lead to security holes there. It is valid JSON to
+ // escape them, so we do so unconditionally.
+ // See http://timelessrepo.com/json-isnt-a-javascript-subset for discussion.
+ case lineSepState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, `\u2028`...)
+ i = j + 3
+ j = j + 3
+ continue
+ case paragraphSepState:
+ buf = append(buf, s[i:j]...)
+ buf = append(buf, `\u2029`...)
+ i = j + 3
+ j = j + 3
+ continue
+ }
+ j += size
}
-
- state, size := decodeRuneInString(s[j:])
- switch state {
- case runeErrorState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\ufffd`...)
- i = j + 1
- j = j + 1
- continue
- // U+2028 is LINE SEPARATOR.
- // U+2029 is PARAGRAPH SEPARATOR.
- // They are both technically valid characters in JSON strings,
- // but don't work in JSONP, which has to be evaluated as JavaScript,
- // and can lead to security holes there. It is valid JSON to
- // escape them, so we do so unconditionally.
- // See http://timelessrepo.com/json-isnt-a-javascript-subset for discussion.
- case lineSepState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u2028`...)
- i = j + 3
- j = j + 3
- continue
- case paragraphSepState:
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u2029`...)
- i = j + 3
- j = j + 3
- continue
+ if j >= valLen {
+ break
}
- j += size
+ buf = append(buf, s[i:j]...)
+ var n int
+ buf, n = appendEscapedSIMD(buf, s[j:], escapeTables[0], true)
+ j += n
+ i = j
+ limit = min(valLen, j+32)
}
return append(append(buf, s[i:]...), '"')
@@ -402,33 +638,28 @@ func appendString(buf []byte, s string) []byte {
return append(buf, `""`...)
}
buf = append(buf, '"')
- var (
- i, j int
- )
- if valLen >= 8 {
- chunks := stringToUint64Slice(s)
- for _, n := range chunks {
- // combine masks before checking for the MSB of each byte. We include
- // `n` in the mask to check whether any of the *input* byte MSBs were
- // set (i.e. the byte was outside the ASCII range).
- mask := n | (n - (lsb * 0x20)) |
- ((n ^ (lsb * '"')) - lsb) |
- ((n ^ (lsb * '\\')) - lsb)
- if (mask & msb) != 0 {
- j = bits.TrailingZeros64(mask&msb) / 8
- goto ESCAPE_END
- }
+ var i int
+ // the bytes up to the first one which may need an escape are skipped by SIMD, or by words.
+ j := 0
+ if valLen >= 32 && hasEscapeLoop {
+ // a long string is escaped by SIMD, up to a byte which is left to this loop
+ buf, j = appendEscapedSIMD(buf, s, escapeTables[0], false)
+ i = j
+ } else if valLen >= 8 {
+ // the last word overlaps the one before it: the first byte which may need an escape is in the word at
+ // k, or it is none if the mask of the last word is 0, and j is then valLen.
+ k := 0
+ m := maskPlain(wordAt(s, 0))
+ for m == 0 && k+16 <= valLen {
+ k += 8
+ m = maskPlain(wordAt(s, k))
}
- valLen := len(s)
- for i := len(chunks) * 8; i < valLen; i++ {
- if needEscape[s[i]] {
- j = i
- goto ESCAPE_END
- }
+ if m == 0 && k+8 < valLen {
+ k = valLen - 8
+ m = maskPlain(wordAt(s, k))
}
- return append(append(buf, s...), '"')
+ j = k + bits.TrailingZeros64(m)/8
}
-ESCAPE_END:
for j < valLen {
c := s[j]
@@ -438,46 +669,37 @@ ESCAPE_END:
continue
}
- switch c {
- case '\\', '"':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', c)
- i = j + 1
- j = j + 1
- continue
+ // a byte of ASCII, escaped by its sequence ( see escapeSequences ): the bytes of the word after its
+ // length are written over by what follows.
+ seq := escapeSequences[c]
+ buf = append(buf, s[i:j]...)
+ l := len(buf)
+ buf = binary.LittleEndian.AppendUint64(buf, seq)[:l+int(seq>>56)]
+ i = j + 1
+ j = j + 1
+ }
- case '\n':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'n')
- i = j + 1
- j = j + 1
- continue
+ return append(append(buf, s[i:]...), '"')
+}
- case '\r':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 'r')
- i = j + 1
- j = j + 1
- continue
+// The masks of a word of the options: the top bit of the first byte which may need an escape is set, and maybe
+// the ones of the bytes after it ( see looseCommonMask ). They are small enough to be inlined. The masks of HTML
+// are loose even if UTF-8 is not normalized: the exact one costs more for every word than it saves by skipping
+// the bytes which are not ASCII, which the loop of appendHTMLString goes over one by one instead.
- case '\t':
- buf = append(buf, s[i:j]...)
- buf = append(buf, '\\', 't')
- i = j + 1
- j = j + 1
- continue
+func maskNormalizedHTML(w uint64) uint64 {
+ return (looseCommonMask(w) | ((w ^ (lsb * '<')) - lsb) | ((w ^ (lsb * '>')) - lsb) | ((w ^ (lsb * '&')) - lsb)) & msb
+}
- case 0x00, 0x01, 0x02, 0x03, 0x04, 0x05, 0x06, 0x07, 0x08, 0x0B, 0x0C, 0x0E, 0x0F, // 0x00-0x0F
- 0x10, 0x11, 0x12, 0x13, 0x14, 0x15, 0x16, 0x17, 0x18, 0x19, 0x1A, 0x1B, 0x1C, 0x1D, 0x1E, 0x1F: // 0x10-0x1F
- buf = append(buf, s[i:j]...)
- buf = append(buf, `\u00`...)
- buf = append(buf, hex[c>>4], hex[c&0xF])
- i = j + 1
- j = j + 1
- continue
- }
- j++
- }
+func maskNormalized(w uint64) uint64 {
+ return looseCommonMask(w) & msb
+}
- return append(append(buf, s[i:]...), '"')
+func maskPlain(w uint64) uint64 {
+ return exactCommonMask(w) & msb
+}
+
+// wordAt returns the eight bytes of the string at k as a little-endian word: the string has k+8 bytes or more.
+func wordAt(s string, k int) uint64 {
+ return binary.LittleEndian.Uint64(unsafe.Slice((*byte)(unsafe.Add(unsafe.Pointer(unsafe.StringData(s)), k)), 8))
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.go b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.go
new file mode 100644
index 000000000..de5fa330a
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.go
@@ -0,0 +1,73 @@
+package encoder
+
+import (
+ "unsafe"
+
+ "github.com/goccy/go-json/internal/runtime"
+)
+
+// The scan of a string for a byte to escape by AVX2, 32 bytes at a time.
+
+//go:noescape
+func scanStringAVX2(p unsafe.Pointer, n int, tables *nibbleTables) int
+
+//go:noescape
+func escapeStringAVX2(dst, src unsafe.Pointer, n int, tables *nibbleTables, seqs *[256]uint64) (consumed, written int)
+
+//go:noescape
+func escapeUTF8AVX2(dst, src unsafe.Pointer, n int, tables *nibbleTables, seqs *[256]uint64, utf8 *utf8Tables) (consumed, written int)
+
+// hasEscapeLoop is whether appendEscapedSIMD escapes: whether the CPU has AVX2.
+var hasEscapeLoop = runtime.HasAVX2
+
+// escapeSegmentLength is the number of the bytes of a string which appendEscapedSIMD escapes by one call of the
+// loop, which has room for 6 bytes of every byte: it bounds the growth of the buffer for a long string.
+const escapeSegmentLength = 1024
+
+// appendEscapedSIMD appends the string escaped, 32 bytes at a time, as the appendString functions do by the
+// tables of their options, and returns the number of the bytes of the string it appended. It stops at a byte
+// which the caller escapes or when fewer than 32 bytes remain. If UTF-8 is normalized, tables are the ones of
+// the bytes of ASCII to escape, and the bytes which are not ASCII are validated: it stops at the start of a
+// character in a block of 32 bytes with invalid UTF-8, U+2028 or U+2029. The CPU has AVX2.
+func appendEscapedSIMD(buf []byte, s string, tables *nibbleTables, normalizeUTF8 bool) ([]byte, int) {
+ consumed := 0
+ for len(s)-consumed >= 32 {
+ n := min(len(s)-consumed, escapeSegmentLength)
+ if need := 6*n + 32; cap(buf)-len(buf) < need {
+ buf = growForString(buf, need)
+ }
+ dst := unsafe.Add(unsafe.Pointer(unsafe.SliceData(buf)), len(buf))
+ src := unsafe.Add(unsafe.Pointer(unsafe.StringData(s)), consumed)
+ var c, w int
+ if normalizeUTF8 {
+ c, w = escapeUTF8AVX2(dst, src, n, tables, &escapeSequences, &utf8ValidationTables)
+ } else {
+ c, w = escapeStringAVX2(dst, src, n, tables, &escapeSequences)
+ }
+ buf = buf[:len(buf)+w]
+ consumed += c
+ if c+32 <= n {
+ // stopped at a byte which the caller escapes
+ break
+ }
+ }
+ return buf, consumed
+}
+
+// minSIMDScanLength is the length from which a string is scanned by SIMD: the setup of the registers costs
+// about as much as a few words of the scalar scan.
+const minSIMDScanLength = 32
+
+// maxOnePassLength is the length of the longest string which AppendString looks at and copies in one pass:
+// a longer one is looked at by SIMD, which then costs less, and copied after.
+const maxOnePassLength = minSIMDScanLength - 1
+
+// scanBytesSIMD is whether a byte of the n bytes at src is in the tables, by SIMD. The second result is false
+// if the CPU doesn't support it or n is small, and the bytes are not looked at. It is inlined, so that
+// AppendString calls the scan itself.
+func scanBytesSIMD(src unsafe.Pointer, n int, tables *nibbleTables) (bool, bool) {
+ if !runtime.HasAVX2 || n < minSIMDScanLength {
+ return false, false
+ }
+ return scanStringAVX2(src, n, tables) != 0, true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.s b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.s
new file mode 100644
index 000000000..674e25435
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_amd64.s
@@ -0,0 +1,467 @@
+#include "textflag.h"
+
+// MASK computes into Yd the mask of the bytes of Yx which may need an escape, using Yt as a temporary:
+// the lane of such a byte is not zero. See nibbleTables: Y8 is the table of the low nibbles in both halves,
+// Y9 the one of the high nibbles and Y10 has 0x0f in every lane.
+//
+// Only VEX instructions are used: a legacy SSE instruction, such as a move from a general register to an XMM
+// register, mixed with them cost about 500 ns per call.
+#define MASK(Yx, Yt, Yd) \
+ VPAND Y10, Yx, Yt \
+ VPSRLW $4, Yx, Yd \
+ VPAND Y10, Yd, Yd \
+ VPSHUFB Yt, Y8, Yt \
+ VPSHUFB Yd, Y9, Yd \
+ VPAND Yt, Yd, Yd
+
+// func scanStringAVX2(p unsafe.Pointer, n int, tables *nibbleTables) int
+//
+// It returns 1 if a byte of the n bytes at p may need an escape by the tables, or 0. n is 32 or more.
+// The blocks of 128 bytes are looked at first, then the blocks of 32 bytes, and the last block overlaps the
+// previous one.
+TEXT ·scanStringAVX2(SB), NOSPLIT, $0-32
+ MOVQ p+0(FP), SI
+ MOVQ n+8(FP), CX
+ MOVQ tables+16(FP), AX
+
+ VBROADCASTI128 (AX), Y8
+ VBROADCASTI128 16(AX), Y9
+ VPBROADCASTB c0f<>(SB), Y10
+
+ MOVQ SI, DI // the address of the block
+ LEAQ -128(SI)(CX*1), R11 // the address of the last block of 128 bytes
+ CMPQ DI, R11
+ JGT small
+loop128:
+ VMOVDQU (DI), Y0
+ VMOVDQU 32(DI), Y1
+ VMOVDQU 64(DI), Y2
+ VMOVDQU 96(DI), Y3
+ MASK(Y0, Y4, Y5)
+ MASK(Y1, Y4, Y6)
+ VPOR Y6, Y5, Y5
+ MASK(Y2, Y4, Y6)
+ VPOR Y6, Y5, Y5
+ MASK(Y3, Y4, Y6)
+ VPOR Y6, Y5, Y5
+ VPTEST Y5, Y5
+ JNE found
+ ADDQ $128, DI
+ CMPQ DI, R11
+ JLE loop128
+small:
+ LEAQ -32(SI)(CX*1), R11 // the address of the last block of 32 bytes
+ CMPQ DI, R11
+ JGT last
+loop32:
+ VMOVDQU (DI), Y0
+ MASK(Y0, Y4, Y5)
+ VPTEST Y5, Y5
+ JNE found
+ ADDQ $32, DI
+ CMPQ DI, R11
+ JLE loop32
+last:
+ // the last block, which overlaps the previous one unless the blocks ended exactly at n.
+ LEAQ (SI)(CX*1), DX
+ CMPQ DI, DX
+ JEQ none
+ VMOVDQU (R11), Y0
+ MASK(Y0, Y4, Y5)
+ VPTEST Y5, Y5
+ JNE found
+none:
+ VZEROUPPER
+ MOVQ $0, ret+24(FP)
+ RET
+found:
+ VZEROUPPER
+ MOVQ $1, ret+24(FP)
+ RET
+
+// func escapeStringAVX2(dst, src unsafe.Pointer, n int, tables *nibbleTables, seqs *[256]uint64) (consumed, written int)
+//
+// It appends the n bytes at src to dst, escaped, 32 bytes at a time: a block is stored to dst as it is, and the
+// bytes of it which may need an escape by the tables are found by one mask. For each of them in order, dst is
+// advanced to it, its escape, the sequence of seqs of the byte ( see escapeSequences ), is stored, and the rest of
+// the block is stored again after it from src, 32 bytes, which is why that is done only while 32 bytes of src
+// remain from there. It stops at a byte whose sequence is 0, which the caller escapes, or when fewer than 32 bytes
+// remain, and returns the numbers of the bytes it read and wrote. dst has room for 6*n+32 bytes: a byte is
+// escaped in 6 bytes at most, and 32 bytes are stored at a time.
+TEXT ·escapeStringAVX2(SB), NOSPLIT, $0-56
+ MOVQ dst+0(FP), DI
+ MOVQ src+8(FP), SI
+ MOVQ n+16(FP), CX
+ MOVQ tables+24(FP), AX
+ MOVQ seqs+32(FP), R9
+
+ VBROADCASTI128 (AX), Y8
+ VBROADCASTI128 16(AX), Y9
+ VPBROADCASTB c0f<>(SB), Y10
+ VPXOR Y11, Y11, Y11
+
+ MOVQ SI, R12 // the start of src
+ MOVQ DI, R13 // the start of dst
+ LEAQ (SI)(CX*1), R11 // the end of src
+eloop:
+ LEAQ 32(SI), R10 // the end of the block
+ CMPQ R10, R11
+ JGT edone
+ VMOVDQU (SI), Y0
+ VMOVDQU Y0, (DI)
+ MASK(Y0, Y4, Y5)
+ // the lanes which are zero are the ones of the bytes which need no escape.
+ VPCMPEQB Y11, Y5, Y5
+ VPMOVMSKB Y5, DX
+ NOTL DX
+ TESTL DX, DX
+ JNE eescape
+ MOVQ R10, SI
+ ADDQ $32, DI
+ JMP eloop
+eescape:
+ MOVQ SI, R14 // the address of the bit 0 of the mask
+ebyte:
+ // dst is advanced over the bytes before the one to escape, which are stored already.
+ BSFL DX, CX
+ LEAQ (R14)(CX*1), AX
+ MOVQ AX, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ AX, SI
+ MOVBLZX (SI), AX
+ MOVQ (R9)(AX*8), BX
+ TESTQ BX, BX
+ JEQ edone
+ // the sequence, whose length is in the top byte: the bytes after it are written over.
+ MOVQ BX, (DI)
+ SHRQ $56, BX
+ ADDQ BX, DI
+ INCQ SI
+ // the rest of the block is stored again after the escape, from src, if 32 bytes of src remain.
+ LEAQ 32(SI), AX
+ CMPQ AX, R11
+ JGT edone
+ VMOVDQU (SI), Y1
+ VMOVDQU Y1, (DI)
+ LEAL -1(DX), AX
+ ANDL AX, DX
+ JNE ebyte
+ // the rest of the block needs no escape.
+ MOVQ R10, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ R10, SI
+ JMP eloop
+edone:
+ VZEROUPPER
+ SUBQ R12, SI
+ MOVQ SI, consumed+40(FP)
+ SUBQ R13, DI
+ MOVQ DI, written+48(FP)
+ RET
+
+// func escapeUTF8AVX2(dst, src unsafe.Pointer, n int, tables *nibbleTables, seqs *[256]uint64, utf8 *utf8Tables) (consumed, written int)
+//
+// It is escapeStringAVX2 for the options which normalize UTF-8: the tables are the ones of the bytes of ASCII to
+// escape, and a block with a byte which is not ASCII is validated as UTF-8 by the tables of utf8 ( see utf8Tables ).
+//
+// The blocks follow each other by 32 bytes, and the bytes before each byte of a block are taken from the previous
+// block ( Y11 ), so that a character which goes on after a block is validated with the next block. A block of
+// ASCII is taken as zeros, which are validated as it is: the loop of the blocks after a block of ASCII ( uloop )
+// neither keeps the previous block nor looks at R8, which is 0 there, as the loop of escapeStringAVX2 does, and the
+// one after a block with a byte which is not ASCII ( unext ) keeps it and has R8 = 1. Then the number of the bytes
+// of the character which that block leaves to the next one, 0 to 3, is counted from its last bytes where it is
+// needed, which is rarely:
+// - a block with invalid UTF-8, or with U+2028 or U+2029, which are escaped, stops the loop at the start of that
+// character, or else at its first byte which is not ASCII, the start of a character, which the caller escapes;
+// - a block of ASCII after such a character stops the loop at the start of the character, which is invalid;
+// - the loop ends before such a character in its last block.
+// So the loop always stops at the start of a character, and the bytes after it which are in dst are written over
+// by the caller.
+TEXT ·escapeUTF8AVX2(SB), NOSPLIT, $0-64
+ MOVQ dst+0(FP), DI
+ MOVQ src+8(FP), SI
+ MOVQ n+16(FP), CX
+ MOVQ tables+24(FP), AX
+ MOVQ seqs+32(FP), R9
+ MOVQ utf8+40(FP), R8
+
+ VBROADCASTI128 (AX), Y8
+ VBROADCASTI128 16(AX), Y9
+ VPBROADCASTB c0f<>(SB), Y10
+ VBROADCASTI128 (R8), Y12 // the errors by the high nibble of the first byte
+ VBROADCASTI128 16(R8), Y13 // by its low nibble
+ VBROADCASTI128 32(R8), Y14 // by the high nibble of the second byte
+ VPXOR Y15, Y15, Y15
+ XORL R8, R8
+
+ MOVQ SI, R12 // the start of src
+ MOVQ DI, R13 // the start of dst
+ LEAQ (SI)(CX*1), R11 // the end of src
+uloop:
+ LEAQ 32(SI), R10 // the end of the block
+ CMPQ R10, R11
+ JGT uend
+ VMOVDQU (SI), Y0
+ VMOVDQU Y0, (DI)
+ MASK(Y0, Y4, Y5)
+ VPCMPEQB Y15, Y5, Y5
+ VPMOVMSKB Y5, DX
+ NOTL DX // the bytes of ASCII to escape
+ VPMOVMSKB Y0, BX // the bytes which are not ASCII
+ TESTL BX, BX
+ JNE uutf8first
+ublock:
+ TESTL DX, DX
+ JNE uescape
+ ADDQ $32, SI
+ ADDQ $32, DI
+ JMP uloop
+uutf8first:
+ // the previous block, if there is one, is of ASCII, which is validated as zeros are.
+ VPXOR Y11, Y11, Y11
+ JMP uutf8
+uascii:
+ // a block of ASCII after a block with a byte which is not ASCII: a character which that block leaves to this
+ // one is invalid.
+ XORL R8, R8
+ MOVBLZX -1(SI), AX
+ CMPL AX, $0xc0
+ JAE uasciileft1
+ MOVBLZX -2(SI), AX
+ CMPL AX, $0xe0
+ JAE uasciileft2
+ MOVBLZX -3(SI), AX
+ CMPL AX, $0xf0
+ JB uasciiok
+ INCQ R8
+uasciileft2:
+ INCQ R8
+uasciileft1:
+ INCQ R8
+ JMP uincomplete
+uasciiok:
+ JMP ublock
+uutf8:
+ // the bytes one, two and three before every byte, with the previous block before the block.
+ VPERM2I128 $0x03, Y11, Y0, Y1
+ VPALIGNR $15, Y1, Y0, Y2
+ VPALIGNR $14, Y1, Y0, Y3
+ VPALIGNR $13, Y1, Y0, Y6
+ // the errors of every two bytes in a row.
+ VPSRLW $4, Y2, Y7
+ VPAND Y10, Y7, Y7
+ VPSHUFB Y7, Y12, Y7
+ VPAND Y10, Y2, Y4
+ VPSHUFB Y4, Y13, Y4
+ VPAND Y4, Y7, Y7
+ VPSRLW $4, Y0, Y4
+ VPAND Y10, Y4, Y4
+ VPSHUFB Y4, Y14, Y4
+ VPAND Y4, Y7, Y7
+ // the third and the fourth bytes of a character must be continuation bytes, which the lookups take as errors
+ // of two continuation bytes in a row: the bit of that error is flipped there.
+ // The constants are operands in memory, of 32 bytes: a broadcast would take the port of the shuffles, which
+ // the lookups above need.
+ VPSUBUSB c60x32<>(SB), Y3, Y4 // 0x80 or more if the byte two before is 111_____
+ VPSUBUSB c70x32<>(SB), Y6, Y6 // 0x80 or more if the byte three before is 1111____
+ VPOR Y6, Y4, Y4
+ VPAND c80x32<>(SB), Y4, Y4
+ VPXOR Y4, Y7, Y7
+ // U+2028 and U+2029: E2 80 A8 and E2 80 A9, looked for only if a byte two before a byte is E2, as few are.
+ VPCMPEQB cE2x32<>(SB), Y3, Y4
+ VPMOVMSKB Y4, AX
+ TESTL AX, AX
+ JEQ uvalid
+ VPCMPEQB c80x32<>(SB), Y2, Y6
+ VPAND Y6, Y4, Y4
+ VPAND cFEx32<>(SB), Y0, Y6
+ VPCMPEQB cA8x32<>(SB), Y6, Y6
+ VPAND Y6, Y4, Y4
+ VPOR Y4, Y7, Y7
+uvalid:
+ VPTEST Y7, Y7
+ JNE uproblem
+ MOVL $1, R8
+ TESTL DX, DX
+ JNE uescape8
+ // the next block, which is likely to have bytes which are not ASCII too: the loop goes on from here, with one
+ // jump for a block.
+ ADDQ $32, SI
+ ADDQ $32, DI
+unext:
+ LEAQ 32(SI), R10
+ CMPQ R10, R11
+ JGT uend
+ VMOVDQA Y0, Y11
+ VMOVDQU (SI), Y0
+ VMOVDQU Y0, (DI)
+ MASK(Y0, Y4, Y5)
+ VPCMPEQB Y15, Y5, Y5
+ VPMOVMSKB Y5, DX
+ NOTL DX
+ VPMOVMSKB Y0, BX
+ TESTL BX, BX
+ JNE uutf8
+ JMP uascii
+uproblem:
+ // the loop stops at the start of the character which the previous block leaves to this one, if there is one,
+ // or else at the first byte which is not ASCII, as at a byte to escape whose sequence is 0.
+ TESTQ R8, R8
+ JEQ ufirst
+ XORL R8, R8
+ MOVBLZX -1(SI), AX
+ CMPL AX, $0xc0
+ JAE uproblemleft1
+ MOVBLZX -2(SI), AX
+ CMPL AX, $0xe0
+ JAE uproblemleft2
+ MOVBLZX -3(SI), AX
+ CMPL AX, $0xf0
+ JB ufirst
+ INCQ R8
+uproblemleft2:
+ INCQ R8
+uproblemleft1:
+ INCQ R8
+ JMP uincomplete
+ufirst:
+ BSFL BX, CX
+ MOVL $1, AX
+ SHLL CX, AX
+ ORL AX, DX
+ JMP ublock
+uescape:
+ MOVQ SI, R14 // the address of the bit 0 of the mask
+ubyte:
+ // dst is advanced over the bytes before the one to escape, which are stored already.
+ BSFL DX, CX
+ LEAQ (R14)(CX*1), AX
+ MOVQ AX, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ AX, SI
+ MOVBLZX (SI), AX
+ MOVQ (R9)(AX*8), BX
+ TESTQ BX, BX
+ JEQ udone
+ // the sequence, whose length is in the top byte: the bytes after it are written over.
+ MOVQ BX, (DI)
+ SHRQ $56, BX
+ ADDQ BX, DI
+ INCQ SI
+ // the rest of the block is stored again after the escape, from src, if 32 bytes of src remain.
+ LEAQ 32(SI), AX
+ CMPQ AX, R11
+ JGT udone
+ VMOVDQU (SI), Y1
+ VMOVDQU Y1, (DI)
+ LEAL -1(DX), AX
+ ANDL AX, DX
+ JNE ubyte
+ // the rest of the block needs no escape.
+ MOVQ R10, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ R10, SI
+ JMP uloop
+uescape8:
+ // the escapes of a block of the loop after a block with a byte which is not ASCII, which goes on in that loop.
+ MOVQ SI, R14 // the address of the bit 0 of the mask
+ubyte8:
+ // dst is advanced over the bytes before the one to escape, which are stored already.
+ BSFL DX, CX
+ LEAQ (R14)(CX*1), AX
+ MOVQ AX, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ AX, SI
+ MOVBLZX (SI), AX
+ MOVQ (R9)(AX*8), BX
+ TESTQ BX, BX
+ JEQ udone
+ // the sequence, whose length is in the top byte: the bytes after it are written over.
+ MOVQ BX, (DI)
+ SHRQ $56, BX
+ ADDQ BX, DI
+ INCQ SI
+ // the rest of the block is stored again after the escape, from src, if 32 bytes of src remain.
+ LEAQ 32(SI), AX
+ CMPQ AX, R11
+ JGT udone
+ VMOVDQU (SI), Y1
+ VMOVDQU Y1, (DI)
+ LEAL -1(DX), AX
+ ANDL AX, DX
+ JNE ubyte8
+ // the rest of the block needs no escape.
+ MOVQ R10, BX
+ SUBQ SI, BX
+ ADDQ BX, DI
+ MOVQ R10, SI
+ JMP unext
+uend:
+ // the loop ends before the character which the last block leaves to the next one, which the caller validates.
+ TESTQ R8, R8
+ JEQ udone
+ XORL R8, R8
+ MOVBLZX -1(SI), AX
+ CMPL AX, $0xc0
+ JAE uendleft1
+ MOVBLZX -2(SI), AX
+ CMPL AX, $0xe0
+ JAE uendleft2
+ MOVBLZX -3(SI), AX
+ CMPL AX, $0xf0
+ JB udone
+ INCQ R8
+uendleft2:
+ INCQ R8
+uendleft1:
+ INCQ R8
+uincomplete:
+ SUBQ R8, SI
+ SUBQ R8, DI
+udone:
+ VZEROUPPER
+ SUBQ R12, SI
+ MOVQ SI, consumed+48(FP)
+ SUBQ R13, DI
+ MOVQ DI, written+56(FP)
+ RET
+
+DATA c0f<>+0(SB)/1, $0x0f
+GLOBL c0f<>(SB), RODATA|NOPTR, $1
+
+// the constants of the check of UTF-8, repeated in the 32 bytes of a register.
+DATA c60x32<>+0(SB)/8, $0x6060606060606060
+DATA c60x32<>+8(SB)/8, $0x6060606060606060
+DATA c60x32<>+16(SB)/8, $0x6060606060606060
+DATA c60x32<>+24(SB)/8, $0x6060606060606060
+GLOBL c60x32<>(SB), RODATA|NOPTR, $32
+DATA c70x32<>+0(SB)/8, $0x7070707070707070
+DATA c70x32<>+8(SB)/8, $0x7070707070707070
+DATA c70x32<>+16(SB)/8, $0x7070707070707070
+DATA c70x32<>+24(SB)/8, $0x7070707070707070
+GLOBL c70x32<>(SB), RODATA|NOPTR, $32
+DATA c80x32<>+0(SB)/8, $0x8080808080808080
+DATA c80x32<>+8(SB)/8, $0x8080808080808080
+DATA c80x32<>+16(SB)/8, $0x8080808080808080
+DATA c80x32<>+24(SB)/8, $0x8080808080808080
+GLOBL c80x32<>(SB), RODATA|NOPTR, $32
+DATA cE2x32<>+0(SB)/8, $0xe2e2e2e2e2e2e2e2
+DATA cE2x32<>+8(SB)/8, $0xe2e2e2e2e2e2e2e2
+DATA cE2x32<>+16(SB)/8, $0xe2e2e2e2e2e2e2e2
+DATA cE2x32<>+24(SB)/8, $0xe2e2e2e2e2e2e2e2
+GLOBL cE2x32<>(SB), RODATA|NOPTR, $32
+DATA cFEx32<>+0(SB)/8, $0xfefefefefefefefe
+DATA cFEx32<>+8(SB)/8, $0xfefefefefefefefe
+DATA cFEx32<>+16(SB)/8, $0xfefefefefefefefe
+DATA cFEx32<>+24(SB)/8, $0xfefefefefefefefe
+GLOBL cFEx32<>(SB), RODATA|NOPTR, $32
+DATA cA8x32<>+0(SB)/8, $0xa8a8a8a8a8a8a8a8
+DATA cA8x32<>+8(SB)/8, $0xa8a8a8a8a8a8a8a8
+DATA cA8x32<>+16(SB)/8, $0xa8a8a8a8a8a8a8a8
+DATA cA8x32<>+24(SB)/8, $0xa8a8a8a8a8a8a8a8
+GLOBL cA8x32<>(SB), RODATA|NOPTR, $32
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.go b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.go
new file mode 100644
index 000000000..b6b016dce
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.go
@@ -0,0 +1,34 @@
+package encoder
+
+import (
+ "unsafe"
+)
+
+// The scan of a string for a byte to escape by NEON, 16 bytes at a time.
+
+//go:noescape
+func scanStringNEON(p unsafe.Pointer, n int, tables *nibbleTables) int
+
+// minSIMDScanLength is the length from which a string is scanned by SIMD.
+const minSIMDScanLength = 16
+
+// maxOnePassLength is the length of the longest string which AppendString looks at and copies in one pass:
+// a longer one is looked at by SIMD, which then costs less, and copied after.
+const maxOnePassLength = minSIMDScanLength - 1
+
+// scanBytesSIMD is whether a byte of the n bytes at src is in the tables, by SIMD. The second result is false
+// if n is small, and the bytes are not looked at. It is inlined, so that AppendString calls the scan itself.
+func scanBytesSIMD(src unsafe.Pointer, n int, tables *nibbleTables) (bool, bool) {
+ if n < minSIMDScanLength {
+ return false, false
+ }
+ return scanStringNEON(src, n, tables) != 0, true
+}
+
+// hasEscapeLoop is false: the loop of the escapes by SIMD is of amd64 only ( see string_scan_amd64.go ).
+const hasEscapeLoop = false
+
+// appendEscapedSIMD appends nothing: it is never called on this architecture.
+func appendEscapedSIMD(buf []byte, _ string, _ *nibbleTables, _ bool) ([]byte, int) {
+ return buf, 0
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.s b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.s
new file mode 100644
index 000000000..fcce24981
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_arm64.s
@@ -0,0 +1,78 @@
+#include "textflag.h"
+
+// MASK computes into Vd the mask of the bytes of Vx which may need an escape, using Vt as a temporary:
+// the lane of such a byte is not zero. See nibbleTables: V8 is the table of the low nibbles, V9 the one of
+// the high nibbles and V10 has 0x0f in every lane.
+#define MASK(Vx, Vt, Vd) \
+ VAND V10.B16, Vx.B16, Vt.B16 \
+ VUSHR $4, Vx.B16, Vd.B16 \
+ VTBL Vt.B16, [V8.B16], Vt.B16 \
+ VTBL Vd.B16, [V9.B16], Vd.B16 \
+ VAND Vt.B16, Vd.B16, Vd.B16
+
+// ANY sets R8 to a value which is not zero if a lane of Vd is not zero.
+#define ANY(Vd) \
+ VUADDLV Vd.B16, V15 \
+ VMOV V15.H[0], R8
+
+// func scanStringNEON(p unsafe.Pointer, n int, tables *nibbleTables) int
+//
+// It returns 1 if a byte of the n bytes at p may need an escape by the tables, or 0. n is 16 or more.
+// The blocks of 64 bytes are looked at first, then the blocks of 16 bytes, and the last block overlaps the
+// previous one.
+TEXT ·scanStringNEON(SB), NOSPLIT, $0-32
+ MOVD p+0(FP), R0
+ MOVD n+8(FP), R1
+ MOVD tables+16(FP), R2
+
+ VLD1 (R2), [V8.B16, V9.B16]
+ MOVD $0x0f, R4
+ VMOV R4, V10.B16
+
+ MOVD R0, R7 // the address of the block
+ SUB $64, R1, R6
+ ADD R0, R6, R6 // the address of the last block of 64 bytes
+ CMP R6, R7
+ BGT small
+loop64:
+ VLD1.P 64(R7), [V0.B16, V1.B16, V2.B16, V3.B16]
+ MASK(V0, V4, V5)
+ MASK(V1, V4, V6)
+ VORR V6.B16, V5.B16, V5.B16
+ MASK(V2, V4, V6)
+ VORR V6.B16, V5.B16, V5.B16
+ MASK(V3, V4, V6)
+ VORR V6.B16, V5.B16, V5.B16
+ ANY(V5)
+ CBNZ R8, found
+ CMP R6, R7
+ BLE loop64
+small:
+ SUB $16, R1, R6
+ ADD R0, R6, R6 // the address of the last block of 16 bytes
+ CMP R6, R7
+ BGT last
+loop16:
+ VLD1.P 16(R7), [V0.B16]
+ MASK(V0, V4, V5)
+ ANY(V5)
+ CBNZ R8, found
+ CMP R6, R7
+ BLE loop16
+last:
+ // the last block, which overlaps the previous one unless the blocks ended exactly at n.
+ ADD R0, R1, R4
+ CMP R4, R7
+ BEQ none
+ VLD1 (R6), [V0.B16]
+ MASK(V0, V4, V5)
+ ANY(V5)
+ CBNZ R8, found
+none:
+ MOVD $0, R8
+ MOVD R8, ret+24(FP)
+ RET
+found:
+ MOVD $1, R8
+ MOVD R8, ret+24(FP)
+ RET
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_other.go b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_other.go
new file mode 100644
index 000000000..193d20eba
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_other.go
@@ -0,0 +1,24 @@
+//go:build !amd64 && !arm64
+
+package encoder
+
+import (
+ "unsafe"
+)
+
+// maxOnePassLength is the length of the longest string which AppendString looks at and copies in one pass, of
+// up to four words: a longer one is looked at by words, and copied after.
+const maxOnePassLength = 31
+
+// scanBytesSIMD is not available: the bytes are scanned one by one.
+func scanBytesSIMD(_ unsafe.Pointer, _ int, _ *nibbleTables) (bool, bool) {
+ return false, false
+}
+
+// hasEscapeLoop is false: the loop of the escapes by SIMD is of amd64 only ( see string_scan_amd64.go ).
+const hasEscapeLoop = false
+
+// appendEscapedSIMD appends nothing: it is never called on this architecture.
+func appendEscapedSIMD(buf []byte, _ string, _ *nibbleTables, _ bool) ([]byte, int) {
+ return buf, 0
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/string_scan_table.go b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_table.go
new file mode 100644
index 000000000..d10b66834
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/encoder/string_scan_table.go
@@ -0,0 +1,118 @@
+package encoder
+
+// nibbleTables are two tables of 16 bytes for the scan of a string by SIMD: a byte b may need an escape if
+// Lo[b&0xf] & Hi[b>>4] is not zero. The bytes of a high nibble which need an escape are a set of low
+// nibbles; every distinct set gets a bit, which Hi has for the high nibbles of the set and Lo has for the
+// low nibbles in the set. Two lookups of a byte per lane replace a compare per character to escape.
+type nibbleTables struct {
+ Lo [16]byte
+ Hi [16]byte
+}
+
+// newNibbleTables returns the tables for the bytes which need an escape. It panics if more than 8 distinct
+// sets of low nibbles are needed, which the tables of the encoder never need.
+func newNibbleTables(need *[256]bool) nibbleTables {
+ var t nibbleTables
+ bits := map[uint16]byte{} // the set of the low nibbles, as a bit set -> the bit of the set
+ next := byte(1)
+ for hi := 0; hi < 16; hi++ {
+ var set uint16
+ for lo := 0; lo < 16; lo++ {
+ if need[hi<<4|lo] {
+ set |= 1 << lo
+ }
+ }
+ if set == 0 {
+ continue
+ }
+ bit, ok := bits[set]
+ if !ok {
+ if next == 0 {
+ panic("too many sets of the low nibbles for the tables of the scan")
+ }
+ bit = next
+ next <<= 1
+ bits[set] = bit
+ for lo := 0; lo < 16; lo++ {
+ if set&(1<> 63)
-
+// The functions which the template calls as appendInt, appendString and so on are the ones of the encoder
+// package here, and the generator makes the VM call them directly: a call through a function variable is a load
+// and an indirect call, for every value the VM appends. appendScalar has them as variables for its own calls.
var (
appendInt = encoder.AppendInt
appendUint = encoder.AppendUint
- appendFloat32 = encoder.AppendFloat32
appendFloat64 = encoder.AppendFloat64
appendString = encoder.AppendString
appendByteSlice = encoder.AppendByteSlice
appendNumber = encoder.AppendNumber
- errUnsupportedValue = encoder.ErrUnsupportedValue
errUnsupportedFloat = encoder.ErrUnsupportedFloat
- mapiterinit = encoder.MapIterInit
- mapiterkey = encoder.MapIterKey
- mapitervalue = encoder.MapIterValue
- mapiternext = encoder.MapIterNext
- maplen = encoder.MapLen
)
type emptyInterface struct {
- typ *runtime.Type
- ptr unsafe.Pointer
-}
-
-type nonEmptyInterface struct {
- itab *struct {
- ityp *runtime.Type // static interface type
- typ *runtime.Type // dynamic concrete type
- // unused fields...
- }
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
@@ -46,68 +32,75 @@ func errUnimplementedOp(op encoder.OpType) error {
return fmt.Errorf("encoder: opcode %s has not been implemented", op)
}
-func load(base uintptr, idx uint32) uintptr {
- addr := base + uintptr(idx)
- return **(**uintptr)(unsafe.Pointer(&addr))
+// load / store are for the half of a slot for a pointer, and loadInt / storeInt are for the other half.
+// A pointer is stored as uintptr, which needs no write barrier: see encoder.Slot.
+
+func load(base unsafe.Pointer, idx uint32) unsafe.Pointer {
+ return *(*unsafe.Pointer)(unsafe.Add(base, idx))
}
-func store(base uintptr, idx uint32, p uintptr) {
- addr := base + uintptr(idx)
- **(**uintptr)(unsafe.Pointer(&addr)) = p
+func store(base unsafe.Pointer, idx uint32, p unsafe.Pointer) {
+ *(*uintptr)(unsafe.Add(base, idx)) = uintptr(p)
}
-func loadNPtr(base uintptr, idx uint32, ptrNum uint8) uintptr {
- addr := base + uintptr(idx)
- p := **(**uintptr)(unsafe.Pointer(&addr))
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
- }
- return p
+func loadInt(base unsafe.Pointer, idx uint32) uintptr {
+ return *(*uintptr)(unsafe.Add(base, idx))
+}
+
+func storeInt(base unsafe.Pointer, idx uint32, v uintptr) {
+ *(*uintptr)(unsafe.Add(base, idx)) = v
}
-func ptrToUint64(p uintptr, bitSize uint8) uint64 {
+func ptrToUint64(p unsafe.Pointer, bitSize uint8) uint64 {
switch bitSize {
case 8:
- return (uint64)(**(**uint8)(unsafe.Pointer(&p)))
+ return uint64(*(*uint8)(p))
case 16:
- return (uint64)(**(**uint16)(unsafe.Pointer(&p)))
+ return uint64(*(*uint16)(p))
case 32:
- return (uint64)(**(**uint32)(unsafe.Pointer(&p)))
+ return uint64(*(*uint32)(p))
case 64:
- return **(**uint64)(unsafe.Pointer(&p))
+ return *(*uint64)(p)
}
return 0
}
-func ptrToFloat32(p uintptr) float32 { return **(**float32)(unsafe.Pointer(&p)) }
-func ptrToFloat64(p uintptr) float64 { return **(**float64)(unsafe.Pointer(&p)) }
-func ptrToBool(p uintptr) bool { return **(**bool)(unsafe.Pointer(&p)) }
-func ptrToBytes(p uintptr) []byte { return **(**[]byte)(unsafe.Pointer(&p)) }
-func ptrToNumber(p uintptr) json.Number { return **(**json.Number)(unsafe.Pointer(&p)) }
-func ptrToString(p uintptr) string { return **(**string)(unsafe.Pointer(&p)) }
-func ptrToSlice(p uintptr) *runtime.SliceHeader { return *(**runtime.SliceHeader)(unsafe.Pointer(&p)) }
-func ptrToPtr(p uintptr) uintptr {
- return uintptr(**(**unsafe.Pointer)(unsafe.Pointer(&p)))
-}
-func ptrToNPtr(p uintptr, ptrNum uint8) uintptr {
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
+func ptrToFloat32(p unsafe.Pointer) float32 { return *(*float32)(p) }
+
+// isInfOrNaN is whether the float is not finite, which encoding/json refuses: the exponent is all ones.
+// math.IsInf is not inlined into Run, which is a big function to the inliner; this is.
+func isInfOrNaN(v float64) bool {
+ const exponent = 0x7ff << 52
+ return math.Float64bits(v)&exponent == exponent
+}
+
+// appendFloat32 appends the float, or returns the error for one which is not finite as encoding/json does.
+func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) ([]byte, error) {
+ if isInfOrNaN(float64(v)) {
+ return nil, errUnsupportedFloat(float64(v))
+ }
+ return encoder.AppendFloat32(ctx, b, v), nil
+}
+func ptrToFloat64(p unsafe.Pointer) float64 { return *(*float64)(p) }
+func ptrToBool(p unsafe.Pointer) bool { return *(*bool)(p) }
+func ptrToBytes(p unsafe.Pointer) []byte { return *(*[]byte)(p) }
+func ptrToNumber(p unsafe.Pointer) json.Number { return *(*json.Number)(p) }
+func ptrToString(p unsafe.Pointer) string { return *(*string)(p) }
+func ptrToSlice(p unsafe.Pointer) *runtime.SliceHeader { return (*runtime.SliceHeader)(p) }
+func ptrToPtr(p unsafe.Pointer) unsafe.Pointer { return *(*unsafe.Pointer)(p) }
+
+// ptrToNPtr follows the pointer ptrNum times, or up to a nil one. It is written to be inlined into Run,
+// which is a big function: only a function whose cost is 20 or less is inlined into it.
+func ptrToNPtr(p unsafe.Pointer, ptrNum uint8) unsafe.Pointer {
+ for ; ptrNum > 0 && p != nil; ptrNum-- {
+ p = *(*unsafe.Pointer)(p)
}
return p
}
-func ptrToUnsafePtr(p uintptr) unsafe.Pointer {
- return *(*unsafe.Pointer)(unsafe.Pointer(&p))
-}
-func ptrToInterface(code *encoder.Opcode, p uintptr) interface{} {
- return *(*interface{})(unsafe.Pointer(&emptyInterface{
+func ptrToInterface(code *encoder.Opcode, p unsafe.Pointer) any {
+ return *(*any)(unsafe.Pointer(&emptyInterface{
typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
+ ptr: p,
}))
}
@@ -148,12 +141,12 @@ func appendMapEnd(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte
return b
}
-func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalJSON(ctx, code, b, v)
+func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalJSON(ctx, code, b, p)
}
-func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalText(ctx, code, b, v)
+func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalText(ctx, code, b, p)
}
func appendArrayHead(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte {
@@ -184,7 +177,20 @@ func appendStructHead(_ *encoder.RuntimeContext, b []byte) []byte {
return append(b, '{')
}
+// appendStructKey appends a key which is up to a chunk long, by two copies of a half chunk each: the key is
+// followed by its padding in memory ( encoder.PaddedKey ), and the length is cut back to the key after.
+// A copy of a half chunk is inlined by the compiler on amd64 and arm64; a call of memmove, or of this
+// function, makes the VM spill and restore its registers, which costs more than the copy of a key.
+//
+// Run is a big function to the inliner, which inlines into it only a function whose cost is 20 or less:
+// this one costs 19. A key longer than a chunk is written by appendLongStructKey, by the generic field opcode.
func appendStructKey(_ *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
+ const half = encoder.KeyChunkSize / 2
+ return append(append(b, code.KeyChunk[:half]...), code.KeyChunk[half:]...)[:len(b)+len(code.Key)]
+}
+
+// appendLongStructKey appends a key of any length.
+func appendLongStructKey(_ *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
return append(b, code.Key...)
}
@@ -192,16 +198,55 @@ func appendStructEnd(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []b
return append(b, '}', ',')
}
-func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
- last := len(b) - 1
- if b[last] == ',' {
- b[last] = '}'
- return appendComma(ctx, b)
- }
- return appendStructEnd(ctx, code, b)
+// commaAtEnd is 1 for a comma: what appendStructEndSkipLast cuts from the end.
+var commaAtEnd = [256]uint8{',': 1}
+
+// appendStructEndSkipLast ends the struct, over the comma after its last field if there is one: there is none
+// after an empty struct or when every field is omitted. The comma is cut by a table, not a branch, so that
+// the function costs 18 to the inliner and is inlined into Run ( see appendStructKey ).
+func appendStructEndSkipLast(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte {
+ return append(b[:len(b)-int(commaAtEnd[b[len(b)-1]])], '}', ',')
}
-func restoreIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, _ uintptr) {}
-func storeIndent(_ uintptr, _ *encoder.Opcode, _ uintptr) {}
func appendMapKeyIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte { return b }
func appendArrayElemIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte { return b }
+
+// appendScalar appends the value at p by the opcode of a scalar, with the comma: what the VM does for the opcode.
+// It is for a scalar held by an interface value, which is encoded without a frame.
+//
+//go:noinline
+func appendScalar(ctx *encoder.RuntimeContext, b []byte, code *encoder.Opcode, p unsafe.Pointer) ([]byte, error) {
+ switch code.Op {
+ case encoder.OpInt:
+ b = appendInt(ctx, b, p, code)
+ case encoder.OpUint:
+ b = appendUint(ctx, b, p, code)
+ case encoder.OpFloat32:
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ case encoder.OpFloat64:
+ v := ptrToFloat64(p)
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ case encoder.OpString:
+ b = appendString(ctx, b, ptrToString(p))
+ case encoder.OpBool:
+ b = appendBool(ctx, b, ptrToBool(p))
+ case encoder.OpBytes:
+ b = appendByteSlice(ctx, b, ptrToBytes(p))
+ case encoder.OpNumber:
+ bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ default:
+ return nil, errUnimplementedOp(code.Op)
+ }
+ return appendComma(ctx, b), nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm/vm.go b/vendor/github.com/goccy/go-json/internal/encoder/vm/vm.go
index 645d20f9f..72e04e99d 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm/vm.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm/vm.go
@@ -1,19 +1,13 @@
-// Code generated by internal/cmd/generator. DO NOT EDIT!
+// Code generated by internal/cmd/generator. DO NOT EDIT.
package vm
import (
- "math"
- "reflect"
- "sort"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
- "github.com/goccy/go-json/internal/runtime"
)
func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]byte, error) {
- recursiveLevel := 0
- ptrOffset := uintptr(0)
ctxptr := ctx.Ptr()
var code *encoder.Opcode
if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
@@ -26,13 +20,245 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
switch code.Op {
default:
return nil, errUnimplementedOp(code.Op)
+ // The opcodes of a value of interface{} and of a map are first: the position of a case in the switch
+ // changes the layout of the code of the VM, and these were the ones to suffer from it.
+ case encoder.OpInterfacePtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpInterface:
+ p := load(ctxptr, code.Idx)
+ // An interface value which holds nothing is null: its first word, the type or the itab, is nil.
+ // It is decided here, as a call costs more than the check: the fields of interface{} of a struct
+ // are nil in many a value.
+ if p == nil || *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpInterfaceEnd:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructFieldInterface:
+ // The field of a value of interface{}: the key, and then what OpInterface does for the value. A field
+ // of interface{} is nil in many a value, and it is null then, without a call. The cases are here, with
+ // the ones of a value of interface{}, not with the other fields: there they cost the small structs 3%.
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ b = appendStructKey(ctx, code, b)
+ if *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpStructFieldOmitEmptyInterface:
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ if *(*unsafe.Pointer)(p) == nil {
+ code = code.NextField
+ break
+ }
+ b = appendStructKey(ctx, code, b)
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpMapPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpMap:
+ p := load(ctxptr, code.Idx)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ // The entries are read from the map into the context first ( encoder.MapLayout ), and encoded from
+ // there: in the order of the map, or sorted by their keys when they are strings. A sorted map whose
+ // keys are not strings is encoded as it comes and its entries are put in the order of their encoded
+ // keys at OpMapEnd.
+ mapCtx := encoder.NewMapContext(ctx)
+ if code.Flags&encoder.MapStringKeyFlags != 0 && (code.Map.ScalarValue || code.Map.InterfaceValue) && ctx.Option.Flag&encoder.UnorderedMapOption != 0 {
+ // the entries are written as the map is read: all of them when the values are scalars, and the
+ // ones which hold a scalar when the values are of interface{}, and the context gets the others.
+ if encoder.MapLen(p) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ }
+ bb, err := appendMapAsRead(ctx, code, appendStructHead(ctx, b), p, mapCtx)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ } else if code.Map.Collect(p, mapCtx) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ } else {
+ b = appendStructHead(ctx, b)
+ if (ctx.Option.Flag & encoder.UnorderedMapOption) == 0 {
+ if code.Flags&encoder.MapStringKeyFlags != 0 {
+ mapCtx.SortKeys()
+ mapCtx.Sorted = true
+ mapCtx.DirectEntries = code.Map.ScalarValue || code.Map.InterfaceValue
+ } else {
+ mapCtx.SortByEncodedKeys()
+ mapCtx.First = len(b)
+ }
+ }
+ }
+ store(ctxptr, code.Idx, unsafe.Pointer(mapCtx))
+ // the first entry is begun as the others are, by the header: it has the next opcode and the flags
+ // of the key opcode.
+ mapCtx.Idx = -1
+ fallthrough
+ case encoder.OpMapKey:
+ // After an entry, or at the start with Idx -1: the next entry is begun, or the map is ended.
+ // A key of a string is written here, and the value of the entry is given to the opcode of the
+ // value: that saves the opcodes of the key and of the value for every entry. The key of another
+ // kind is given to its opcode, which OpMapValue follows.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ byEncodedKeys := mapCtx.Slice.Items != nil
+ idx := mapCtx.Idx
+ if byEncodedKeys && idx >= 0 {
+ mapCtx.Slice.Items[idx].Value = b[mapCtx.Start:]
+ }
+ idx++
+ if mapCtx.DirectEntries && idx < mapCtx.Len {
+ // the entries from here are written by one call, up to one whose value is left to its opcodes.
+ bb, next, err := appendSortedMapEntries(ctx, code, b, mapCtx, idx)
+ if err != nil {
+ return nil, err
+ }
+ b, idx = bb, next
+ }
+ if idx == mapCtx.Len {
+ if byEncodedKeys {
+ code = code.End
+ } else {
+ b = appendObjectEnd(ctx, code, b)
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.End.Next
+ }
+ break
+ }
+ mapCtx.Idx = idx
+ if byEncodedKeys {
+ mapCtx.Start = len(b)
+ } else {
+ b = appendMapKeyIndent(ctx, code, b)
+ }
+ if code.Flags&encoder.MapStringKeyFlags == 0 {
+ store(ctxptr, code.Next.Idx, mapCtx.KeyAt(idx))
+ code = code.Next
+ break
+ }
+ if mapCtx.Sorted {
+ idx = int(mapCtx.Order[idx])
+ }
+ b = encoder.AppendString(ctx, b, mapCtx.Keys[idx])
+ b = appendComma(ctx, b)
+ b = appendColon(ctx, b)
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(idx))
+ code = code.Next
+ case encoder.OpMapValue:
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ if mapCtx.Slice.Items != nil {
+ mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:]
+ mapCtx.Start = len(b)
+ } else {
+ b = appendColon(ctx, b)
+ }
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(mapCtx.Idx))
+ code = code.Next
+ case encoder.OpMapEnd:
+ // the entries of a sorted map whose keys are not strings, in the order of their encoded keys.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ mapCtx.Slice.Sort()
+ buf := mapCtx.Buf
+ for _, item := range mapCtx.Slice.Items {
+ buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
+ }
+ buf = appendMapEnd(ctx, code, buf)
+ b = b[:mapCtx.First]
+ b = append(b, buf...)
+ mapCtx.Buf = buf
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.Next
case encoder.OpPtr:
p := load(ctxptr, code.Idx)
code = code.Next
store(ctxptr, code.Idx, ptrToPtr(p))
case encoder.OpIntPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -40,12 +266,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpInt:
- b = appendInt(ctx, b, load(ctxptr, code.Idx), code)
+ b = encoder.AppendInt(ctx, b, load(ctxptr, code.Idx), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpUintPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -53,24 +279,128 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpUint:
- b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
+ b = encoder.AppendUint(ctx, b, load(ctxptr, code.Idx), code)
b = appendComma(ctx, b)
code = code.Next
+ // The values as strings, for the keys of a map and for the string option of a field whose key is longer
+ // than a chunk: such a field is encoded by the generic field opcode and the opcode of its value.
+ case encoder.OpIntPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpIntString:
b = append(b, '"')
- b = appendInt(ctx, b, load(ctxptr, code.Idx), code)
+ b = encoder.AppendInt(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpUintPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpUintString:
b = append(b, '"')
- b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
+ b = encoder.AppendUint(ctx, b, load(ctxptr, code.Idx), code)
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpFloat32PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat32String:
+ b = append(b, '"')
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpFloat64PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat64String:
+ v := ptrToFloat64(load(ctxptr, code.Idx))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = append(b, '"')
+ b = encoder.AppendFloat64(ctx, b, v)
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpBoolPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpBoolString:
+ b = append(b, '"')
+ b = appendBool(ctx, b, ptrToBool(load(ctxptr, code.Idx)))
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpStringPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpStringString:
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, ptrToString(load(ctxptr, code.Idx)))))
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpNumberPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpNumberString:
b = append(b, '"')
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = append(bb, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpFloat32Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendComma(ctx, b)
code = code.Next
@@ -79,12 +409,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpFloat32:
- b = appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpFloat64Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -93,15 +427,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
fallthrough
case encoder.OpFloat64:
v := ptrToFloat64(load(ctxptr, code.Idx))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStringPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -109,12 +443,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpString:
- b = appendString(ctx, b, ptrToString(load(ctxptr, code.Idx)))
+ b = encoder.AppendString(ctx, b, ptrToString(load(ctxptr, code.Idx)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBoolPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -126,8 +460,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBytesPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -135,12 +469,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpBytes:
- b = appendByteSlice(ctx, b, ptrToBytes(load(ctxptr, code.Idx)))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(load(ctxptr, code.Idx)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpNumberPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -148,119 +482,24 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpNumber:
- bb, err := appendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
if err != nil {
return nil, err
}
b = appendComma(ctx, bb)
code = code.Next
- case encoder.OpInterfacePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpInterface:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if p == seen {
- return nil, errUnsupportedValue(code, p)
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, p)
- var (
- typ *runtime.Type
- ifacePtr unsafe.Pointer
- )
- up := ptrToUnsafePtr(p)
- if code.Flags&encoder.NonEmptyInterfaceFlags != 0 {
- iface := (*nonEmptyInterface)(up)
- ifacePtr = iface.ptr
- if iface.itab != nil {
- typ = iface.itab.typ
- }
- } else {
- iface := (*emptyInterface)(up)
- ifacePtr = iface.ptr
- typ = iface.typ
- }
- if ifacePtr == nil {
- isDirectedNil := typ != nil && typ.Kind() == reflect.Struct && !runtime.IfaceIndir(typ)
- if !isDirectedNil {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- }
- ctx.KeepRefs = append(ctx.KeepRefs, up)
- ifaceCodeSet, err := encoder.CompileToGetCodeSet(ctx, uintptr(unsafe.Pointer(typ)))
- if err != nil {
- return nil, err
- }
-
- totalLength := uintptr(code.Length) + 3
- nextTotalLength := uintptr(ifaceCodeSet.CodeLength) + 3
-
- var c *encoder.Opcode
- if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
- c = ifaceCodeSet.InterfaceEscapeKeyCode
- } else {
- c = ifaceCodeSet.InterfaceNoescapeKeyCode
- }
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += totalLength * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- ctx.BaseIndent += code.Indent
-
- newLen := offsetNum + totalLength + nextTotalLength
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- end := ifaceCodeSet.EndCode
- store(ctxptr, c.Idx, uintptr(ifacePtr))
- store(ctxptr, end.Idx, oldOffset)
- store(ctxptr, end.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, end, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpInterfaceEnd:
- recursiveLevel--
-
- // restore ctxptr
- offset := load(ctxptr, code.Idx)
- restoreIndent(ctx, code, ctxptr)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
case encoder.OpMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalJSON:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -268,7 +507,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -276,33 +515,38 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpMarshalTextPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalText:
p := load(ctxptr, code.Idx)
- if p == 0 {
- b = append(b, `""`...)
- b = appendComma(ctx, b)
+ if p == nil {
+ if (code.Flags & encoder.MapKeyFlags) != 0 {
+ // the name of a key which is a nil pointer is "", as encoding/json names it
+ b = appendComma(ctx, append(b, `""`...))
+ } else {
+ // a nil pointer value is null, as with encoding/json and as OpMarshalJSON writes it
+ b = appendNullComma(ctx, b)
+ }
code = code.Next
break
}
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
b = appendComma(ctx, bb)
code = code.Next
case encoder.OpSlicePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
@@ -312,2916 +556,123 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpSlice:
p := load(ctxptr, code.Idx)
slice := ptrToSlice(p)
- if p == 0 || slice.Data == nil {
+ if p == nil || slice.Data == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- store(ctxptr, code.ElemIdx, 0)
- store(ctxptr, code.Length, uintptr(slice.Len))
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ storeInt(ctxptr, code.ElemIdx, 0)
+ storeInt(ctxptr, code.Length, uintptr(slice.Len))
+ store(ctxptr, code.Idx, slice.Data)
if slice.Len > 0 {
b = appendArrayHead(ctx, code, b)
code = code.Next
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ store(ctxptr, code.Idx, slice.Data)
} else {
b = appendEmptyArray(ctx, b)
code = code.End.Next
}
case encoder.OpSliceElem:
- idx := load(ctxptr, code.ElemIdx)
- length := load(ctxptr, code.Length)
+ idx := loadInt(ctxptr, code.ElemIdx)
+ length := loadInt(ctxptr, code.Length)
idx++
if idx < length {
- b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
- data := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, data+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpArrayPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- if code.Length > 0 {
- b = appendArrayHead(ctx, code, b)
- store(ctxptr, code.ElemIdx, 0)
- code = code.Next
- store(ctxptr, code.Idx, p)
- } else {
- b = appendEmptyArray(ctx, b)
- code = code.End.Next
- }
- case encoder.OpArrayElem:
- idx := load(ctxptr, code.ElemIdx)
- idx++
- if idx < uintptr(code.Length) {
- b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
- p := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, p+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpMapPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- uptr := ptrToUnsafePtr(p)
- mlen := maplen(uptr)
- if mlen <= 0 {
- b = appendEmptyObject(ctx, b)
- code = code.End.Next
- break
- }
- b = appendStructHead(ctx, b)
- unorderedMap := (ctx.Option.Flag & encoder.UnorderedMapOption) != 0
- mapCtx := encoder.NewMapContext(mlen, unorderedMap)
- mapiterinit(code.Type, uptr, &mapCtx.Iter)
- store(ctxptr, code.Idx, uintptr(unsafe.Pointer(mapCtx)))
- ctx.KeepRefs = append(ctx.KeepRefs, unsafe.Pointer(mapCtx))
- if unorderedMap {
- b = appendMapKeyIndent(ctx, code.Next, b)
- } else {
- mapCtx.Start = len(b)
- mapCtx.First = len(b)
- }
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- case encoder.OpMapKey:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- idx := mapCtx.Idx
- idx++
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- if idx < mapCtx.Len {
- b = appendMapKeyIndent(ctx, code, b)
- mapCtx.Idx = int(idx)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- b = appendObjectEnd(ctx, code, b)
- encoder.ReleaseMapContext(mapCtx)
- code = code.End.Next
- }
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Value = b[mapCtx.Start:len(b)]
- if idx < mapCtx.Len {
- mapCtx.Idx = int(idx)
- mapCtx.Start = len(b)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- code = code.End
- }
- }
- case encoder.OpMapValue:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- b = appendColon(ctx, b)
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:len(b)]
- mapCtx.Start = len(b)
- }
- value := mapitervalue(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(value))
- mapiternext(&mapCtx.Iter)
- code = code.Next
- case encoder.OpMapEnd:
- // this operation only used by sorted map.
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- sort.Sort(mapCtx.Slice)
- buf := mapCtx.Buf
- for _, item := range mapCtx.Slice.Items {
- buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
- }
- buf = appendMapEnd(ctx, code, buf)
- b = b[:mapCtx.First]
- b = append(b, buf...)
- mapCtx.Buf = buf
- encoder.ReleaseMapContext(mapCtx)
- code = code.Next
- case encoder.OpRecursivePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpRecursive:
- ptr := load(ctxptr, code.Idx)
- if ptr != 0 {
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if ptr == seen {
- return nil, errUnsupportedValue(code, ptr)
- }
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, ptr)
- c := code.Jmp.Code
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += code.Jmp.CurLen * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- indentDiffFromTop := c.Indent - 1
- ctx.BaseIndent += code.Indent - indentDiffFromTop
-
- newLen := offsetNum + code.Jmp.CurLen + code.Jmp.NextLen
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- store(ctxptr, c.Idx, ptr)
- store(ctxptr, c.End.Next.Idx, oldOffset)
- store(ctxptr, c.End.Next.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, c.End.Next, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpRecursiveEnd:
- recursiveLevel--
-
- // restore ctxptr
- restoreIndent(ctx, code, ctxptr)
- offset := load(ctxptr, code.Idx)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
- case encoder.OpStructPtrHead:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHead:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if len(code.Key) > 0 {
- if (code.Flags&encoder.IsTaggedKeyFlags) != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
- }
- }
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if p == 0 || (ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- u64 := ptrToUint64(p, code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendInt(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendUint(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNull(ctx, b)
- b = appendComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p+uintptr(code.Offset)))))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, ptrToString(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendBool(ctx, b, ptrToBool(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBytes(p + uintptr(code.Offset))
- if len(v) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadArray, encoder.OpStructPtrHeadSlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadArray, encoder.OpStructHeadSlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyArray:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptySlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptySlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- slice := ptrToSlice(p)
- if slice.Len == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadArrayPtr, encoder.OpStructPtrHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadArrayPtr, encoder.OpStructHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyArrayPtr, encoder.OpStructPtrHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyArrayPtr, encoder.OpStructHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- if maplen(ptrToUnsafePtr(p)) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- iface := ptrToInterface(code, p)
- if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
+ b = appendArrayElemIndent(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, idx)
+ data := load(ctxptr, code.Idx)
+ size := uintptr(code.Size)
+ code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(data, idx*size))
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ case encoder.OpArrayPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
+ store(ctxptr, code.Idx, p)
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalText:
+ case encoder.OpArray:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- code = code.NextField
+ if code.Length > 0 {
+ b = appendArrayHead(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, 0)
+ code = code.Next
+ store(ctxptr, code.Idx, p)
} else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
+ b = appendEmptyArray(ctx, b)
+ code = code.End.Next
+ }
+ case encoder.OpArrayElem:
+ idx := loadInt(ctxptr, code.ElemIdx)
+ idx++
+ if idx < uintptr(code.Length) {
+ b = appendArrayElemIndent(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, idx)
+ p := load(ctxptr, code.Idx)
+ size := uintptr(code.Size)
code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(p, idx*size))
+ } else {
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- case encoder.OpStructPtrHeadMarshalTextPtr:
+ case encoder.OpRecursivePtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
+ if p == nil {
+ code = code.Next
break
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadMarshalTextPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
+ case encoder.OpRecursive:
+ if code.Flags&encoder.TailRecursiveFlags != 0 {
+ // a value of a list, the last field of a value of the same type: encoded in this frame, with
+ // the braces of the value it is the field of closed at OpRecursiveEnd.
+ p := load(ctxptr, code.Idx)
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ if err := ctx.RecordSeen(code, p); err != nil {
+ return nil, err
+ }
}
- code = code.End.Next
+ first := code.Jmp.Code
+ store(ctxptr, first.Idx, p)
+ // the end of the struct is next, then OpRecursiveEnd, which has what the indent is deeper by.
+ ctx.BaseIndent += code.Next.Next.Indent
+ ctx.TailLevels++
+ ctx.RecursiveLevel++
+ code = first
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ first, base, err := ctx.EnterRecursive(code, load(ctxptr, code.Idx))
+ if err != nil {
+ return nil, err
}
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
+ code = first
+ ctxptr = base
+ case encoder.OpRecursiveEnd:
+ // the braces of the values of a list this value was the last field of, from the innermost.
+ for ; ctx.TailLevels > 0; ctx.TailLevels-- {
+ ctx.RecursiveLevel--
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
}
- b = bb
+ ctx.BaseIndent -= code.Indent
+ b = appendStructEndSkipLast(ctx, code.Next, b)
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalTextPtr:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructPtrHead:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
@@ -3230,63 +681,74 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalTextPtr:
+ case encoder.OpStructHead:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
+ if p == nil && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendStructHead(ctx, b)
}
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
+ code = code.Next
case encoder.OpStructField:
+ // the generic field: the value is encoded by its own opcode, and the key may be longer than a chunk.
if code.Flags&encoder.IsTaggedKeyFlags != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
}
- p := load(ctxptr, code.Idx) + uintptr(code.Offset)
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmpty:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if encoder.IsEmptyField(code.EmptyKind, code.NumBitSize, p) || (code.ZeroKind != encoder.ZeroNever && encoder.IsZeroField(code, p)) {
code = code.NextField
} else {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
code = code.Next
store(ctxptr, code.Idx, p)
}
+ case encoder.OpStructFieldInt3:
+ // Three fields of the kind in a row, then two: the fields after the first are encoded without
+ // a dispatch, by falling through to the case of the field. The same for the other kinds below.
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldInt2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3294,79 +756,93 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldUint3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldUint2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3374,62 +850,62 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = append(b, '"')
b = appendComma(ctx, b)
}
@@ -3437,15 +913,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
@@ -3453,254 +937,328 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldFloat643:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = encoder.AppendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldFloat642:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = encoder.AppendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldFloat64:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldString3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldString2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = encoder.AppendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = encoder.AppendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
+ b = encoder.AppendString(ctx, b, v)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldStringString:
p := load(ctxptr, code.Idx)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, s)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, v)))
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendString(ctx, b, ptrToString(p))
+ b = encoder.AppendString(ctx, b, ptrToString(p))
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
+ b = encoder.AppendString(ctx, b, ptrToString(p))
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, ptrToString(p))))
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, ptrToString(p))))
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldBool3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldBool2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -3711,13 +1269,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3728,9 +1286,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -3739,8 +1297,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendComma(ctx, b)
@@ -3748,9 +1306,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3761,8 +1319,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -3773,42 +1331,42 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
+ b = encoder.AppendByteSlice(ctx, b, v)
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(p))
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(p))
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3816,10 +1374,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
+ bb, err := encoder.AppendNumber(ctx, b, v)
if err != nil {
return nil, err
}
@@ -3830,7 +1388,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3839,11 +1397,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
+ bb, err := encoder.AppendNumber(ctx, b, v)
if err != nil {
return nil, err
}
@@ -3853,12 +1411,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -3868,10 +1426,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -3880,13 +1438,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -3896,11 +1454,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -3911,14 +1469,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSON:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3928,11 +1486,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSON:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
code = code.NextField
break
}
@@ -3942,7 +1500,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3951,11 +1509,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSONPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3965,10 +1523,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3978,14 +1536,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalText:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3995,16 +1553,21 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalText:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
+ code = code.NextField
+ break
+ }
+ iface := ptrToInterface(code, p)
+ if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
code = code.NextField
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4013,11 +1576,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalTextPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4027,10 +1590,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalTextPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4040,25 +1603,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldArrayPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArrayPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4068,12 +1631,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlice:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlice:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
slice := ptrToSlice(p)
if slice.Len == 0 {
code = code.NextField
@@ -4085,13 +1648,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlicePtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlicePtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4101,13 +1664,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMap:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMap:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 || maplen(ptrToUnsafePtr(p)) == 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p == nil || encoder.MapLen(p) == 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4117,19 +1680,19 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMapPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMapPtr:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
- if p != 0 {
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4139,13 +1702,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldStruct:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyStruct:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if ptrToPtr(p) == nil && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4158,16 +1721,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4177,18 +1740,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4198,20 +1761,20 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4220,23 +1783,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p, code)
+ b = encoder.AppendInt(ctx, b, p, code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4246,16 +1809,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4265,18 +1828,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = encoder.AppendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4286,20 +1849,20 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4308,23 +1871,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p, code)
+ b = encoder.AppendUint(ctx, b, p, code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4334,15 +1897,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4352,17 +1923,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4372,20 +1951,28 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4394,23 +1981,31 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4419,23 +2014,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4443,26 +2038,26 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4472,30 +2067,30 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendStructEnd(ctx, code, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4504,31 +2099,31 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
- b = appendFloat64(ctx, b, v)
+ b = encoder.AppendFloat64(ctx, b, v)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4538,15 +2133,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = encoder.AppendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
+ b = encoder.AppendString(ctx, b, v)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4555,16 +2150,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- s := ptrToString(p + uintptr(code.Offset))
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
+ s := ptrToString(unsafe.Add(p, code.Offset))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, s)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, v)))
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4573,20 +2168,20 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendString(ctx, b, ptrToString(p))
+ b = encoder.AppendString(ctx, b, ptrToString(p))
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
+ b = encoder.AppendString(ctx, b, ptrToString(p))
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4595,20 +2190,20 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, ptrToString(p))))
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
+ b = encoder.AppendString(ctx, b, string(encoder.AppendString(ctx, []byte{}, ptrToString(p))))
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4617,12 +2212,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -4635,13 +2230,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4655,8 +2250,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -4665,8 +2260,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendStructEnd(ctx, code, b)
@@ -4677,8 +2272,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4689,8 +2284,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -4703,15 +2298,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
+ b = encoder.AppendByteSlice(ctx, b, v)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4720,20 +2315,20 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytesPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(p))
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
+ b = encoder.AppendByteSlice(ctx, b, ptrToBytes(p))
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4742,7 +2337,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4750,10 +2345,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
+ bb, err := encoder.AppendNumber(ctx, b, v)
if err != nil {
return nil, err
}
@@ -4766,7 +2361,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4775,11 +2370,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
+ bb, err := encoder.AppendNumber(ctx, b, v)
if err != nil {
return nil, err
}
@@ -4792,11 +2387,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -4806,10 +2401,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -4821,12 +2416,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -4836,11 +2431,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ bb, err := encoder.AppendNumber(ctx, b, ptrToNumber(p))
if err != nil {
return nil, err
}
@@ -4857,3 +2452,142 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
END:
return b, nil
}
+
+// appendMapAsRead writes the entries of the map at p, whose keys are of a string kind, as the map is read: the
+// map is not sorted, so the order of its entries is not specified, and an entry written here costs neither a
+// copy to the context nor the opcodes of an entry. When the values are written by one opcode of a scalar,
+// every entry is written. When the values are of interface{}, the ones which hold a scalar or nothing are
+// written, and the others are given to the context, to be encoded by the opcodes of their values from
+// OpMapKey on: they come after the scalars, which are most of the entries of a JSON object held by a value of
+// interface{}.
+//
+//go:noinline
+func appendMapAsRead(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer, mapCtx *encoder.MapContext) ([]byte, error) {
+ code.Map.Reset(mapCtx)
+ if code.Map.ScalarValue {
+ mapCtx.Len = 0
+ return mapScalarValueWriters[code.Map.ValueWords](ctx, code, b, p)
+ }
+ for k, v := range *(*map[string]any)(unsafe.Pointer(&p)) {
+ iface := (*emptyInterface)(unsafe.Pointer(&v))
+ var scalar *encoder.Opcode
+ // A value of interface{} which holds nothing is null. What holds a value whose data word is nil, such
+ // as a nil pointer, is left to OpInterface, which knows what is null and what is not.
+ if iface.typ != nil && iface.ptr != nil {
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, err
+ }
+ }
+ scalar = codeSet.Scalar
+ }
+ if iface.typ != nil && scalar == nil {
+ mapCtx.Keys = append(mapCtx.Keys, k)
+ mapCtx.Values = append(mapCtx.Values, unsafe.Slice((*byte)(unsafe.Pointer(&v)), unsafe.Sizeof(v))...)
+ continue
+ }
+ b = appendMapKey(ctx, code, b, k)
+ if scalar == nil {
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ // the data word of the interface value is the address of the scalar, or the pointer to it.
+ bb, err := appendScalar(ctx, b, scalar, iface.ptr)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ mapCtx.Len = len(mapCtx.Keys)
+ return b, nil
+}
+
+// appendSortedMapEntries writes the entries of a sorted map with keys of a string kind directly, as
+// appendMapAsRead does for a map which is not sorted, from the one at idx in the order of the keys, as the
+// opcodes of the entries would: every value when the values are written by one opcode of a scalar
+// ( MapLayout.ScalarValue ), and a value of interface{} which holds a scalar or nothing
+// ( MapLayout.InterfaceValue ). It returns the index of the first entry it doesn't write, whose value is left to
+// its opcodes, or the number of the entries. code is the opcode of the keys, followed by the one of the values.
+//
+//go:noinline
+func appendSortedMapEntries(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, mapCtx *encoder.MapContext, idx int) ([]byte, int, error) {
+ scalarValue := mapCtx.ScalarValue()
+ for ; idx < mapCtx.Len; idx++ {
+ i := int(mapCtx.Order[idx])
+ p := mapCtx.ValueAt(i)
+ scalar := code.Next
+ if !scalarValue {
+ // as appendMapAsRead does for a value of interface{}.
+ iface := (*emptyInterface)(p)
+ if iface.typ == nil {
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ if iface.ptr == nil {
+ return b, idx, nil
+ }
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, 0, err
+ }
+ }
+ if codeSet.Scalar == nil {
+ return b, idx, nil
+ }
+ scalar = codeSet.Scalar
+ p = iface.ptr
+ }
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ bb, err := appendScalar(ctx, b, scalar, p)
+ if err != nil {
+ return nil, 0, err
+ }
+ b = bb
+ }
+ return b, idx, nil
+}
+
+// appendMapKey writes the key of an entry of a map, as OpMapKey does.
+func appendMapKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, k string) []byte {
+ b = appendMapKeyIndent(ctx, code, b)
+ b = encoder.AppendString(ctx, b, k)
+ b = appendComma(ctx, b)
+ return appendColon(ctx, b)
+}
+
+// appendMapScalarValues writes the entries of the map at p, whose values are written by the opcode of a
+// scalar which follows the header, as the map is ranged over as a map of values of V: the layout of a map
+// depends only on the sizes of the key and of the value ( encoder.MapLayout ).
+func appendMapScalarValues[V any](ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ value := code.Next
+ // v is declared out of the loop: its address is given to appendScalar, so it lives on the heap, and a
+ // variable of the loop would be allocated for each entry.
+ var (
+ k string
+ v V
+ )
+ for k, v = range *(*map[string]V)(unsafe.Pointer(&p)) {
+ b = appendMapKey(ctx, code, b, k)
+ bb, err := appendScalar(ctx, b, value, unsafe.Pointer(&v))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ return b, nil
+}
+
+// mapScalarValueWriters are appendMapScalarValues by the words of a value.
+var mapScalarValueWriters = [encoder.MapScalarValueWords + 1]func(*encoder.RuntimeContext, *encoder.Opcode, []byte, unsafe.Pointer) ([]byte, error){
+ appendMapScalarValues[[0]uint64],
+ appendMapScalarValues[[1]uint64],
+ appendMapScalarValues[[2]uint64],
+ appendMapScalarValues[[3]uint64],
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_color/util.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_color/util.go
index 33f29aee4..fad591334 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_color/util.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_color/util.go
@@ -3,35 +3,19 @@ package vm_color
import (
"encoding/json"
"fmt"
+ "math"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
"github.com/goccy/go-json/internal/runtime"
)
-const uintptrSize = 4 << (^uintptr(0) >> 63)
-
var (
- errUnsupportedValue = encoder.ErrUnsupportedValue
errUnsupportedFloat = encoder.ErrUnsupportedFloat
- mapiterinit = encoder.MapIterInit
- mapiterkey = encoder.MapIterKey
- mapitervalue = encoder.MapIterValue
- mapiternext = encoder.MapIterNext
- maplen = encoder.MapLen
)
type emptyInterface struct {
- typ *runtime.Type
- ptr unsafe.Pointer
-}
-
-type nonEmptyInterface struct {
- itab *struct {
- ityp *runtime.Type // static interface type
- typ *runtime.Type // dynamic concrete type
- // unused fields...
- }
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
@@ -39,90 +23,93 @@ func errUnimplementedOp(op encoder.OpType) error {
return fmt.Errorf("encoder: opcode %s has not been implemented", op)
}
-func load(base uintptr, idx uint32) uintptr {
- addr := base + uintptr(idx)
- return **(**uintptr)(unsafe.Pointer(&addr))
+// load / store are for the half of a slot for a pointer, and loadInt / storeInt are for the other half.
+// A pointer is stored as uintptr, which needs no write barrier: see encoder.Slot.
+
+func load(base unsafe.Pointer, idx uint32) unsafe.Pointer {
+ return *(*unsafe.Pointer)(unsafe.Add(base, idx))
+}
+
+func store(base unsafe.Pointer, idx uint32, p unsafe.Pointer) {
+ *(*uintptr)(unsafe.Add(base, idx)) = uintptr(p)
}
-func store(base uintptr, idx uint32, p uintptr) {
- addr := base + uintptr(idx)
- **(**uintptr)(unsafe.Pointer(&addr)) = p
+func loadInt(base unsafe.Pointer, idx uint32) uintptr {
+ return *(*uintptr)(unsafe.Add(base, idx))
}
-func loadNPtr(base uintptr, idx uint32, ptrNum uint8) uintptr {
- addr := base + uintptr(idx)
- p := **(**uintptr)(unsafe.Pointer(&addr))
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
- }
- return p
+func storeInt(base unsafe.Pointer, idx uint32, v uintptr) {
+ *(*uintptr)(unsafe.Add(base, idx)) = v
}
-func ptrToUint64(p uintptr, bitSize uint8) uint64 {
+func ptrToUint64(p unsafe.Pointer, bitSize uint8) uint64 {
switch bitSize {
case 8:
- return (uint64)(**(**uint8)(unsafe.Pointer(&p)))
+ return uint64(*(*uint8)(p))
case 16:
- return (uint64)(**(**uint16)(unsafe.Pointer(&p)))
+ return uint64(*(*uint16)(p))
case 32:
- return (uint64)(**(**uint32)(unsafe.Pointer(&p)))
+ return uint64(*(*uint32)(p))
case 64:
- return **(**uint64)(unsafe.Pointer(&p))
+ return *(*uint64)(p)
}
return 0
}
-func ptrToFloat32(p uintptr) float32 { return **(**float32)(unsafe.Pointer(&p)) }
-func ptrToFloat64(p uintptr) float64 { return **(**float64)(unsafe.Pointer(&p)) }
-func ptrToBool(p uintptr) bool { return **(**bool)(unsafe.Pointer(&p)) }
-func ptrToBytes(p uintptr) []byte { return **(**[]byte)(unsafe.Pointer(&p)) }
-func ptrToNumber(p uintptr) json.Number { return **(**json.Number)(unsafe.Pointer(&p)) }
-func ptrToString(p uintptr) string { return **(**string)(unsafe.Pointer(&p)) }
-func ptrToSlice(p uintptr) *runtime.SliceHeader { return *(**runtime.SliceHeader)(unsafe.Pointer(&p)) }
-func ptrToPtr(p uintptr) uintptr {
- return uintptr(**(**unsafe.Pointer)(unsafe.Pointer(&p)))
-}
-func ptrToNPtr(p uintptr, ptrNum uint8) uintptr {
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
+func ptrToFloat32(p unsafe.Pointer) float32 { return *(*float32)(p) }
+
+// isInfOrNaN is whether the float is not finite, which encoding/json refuses: the exponent is all ones.
+// math.IsInf is not inlined into Run, which is a big function to the inliner; this is.
+func isInfOrNaN(v float64) bool {
+ const exponent = 0x7ff << 52
+ return math.Float64bits(v)&exponent == exponent
+}
+func ptrToFloat64(p unsafe.Pointer) float64 { return *(*float64)(p) }
+func ptrToBool(p unsafe.Pointer) bool { return *(*bool)(p) }
+func ptrToBytes(p unsafe.Pointer) []byte { return *(*[]byte)(p) }
+func ptrToNumber(p unsafe.Pointer) json.Number { return *(*json.Number)(p) }
+func ptrToString(p unsafe.Pointer) string { return *(*string)(p) }
+func ptrToSlice(p unsafe.Pointer) *runtime.SliceHeader { return (*runtime.SliceHeader)(p) }
+func ptrToPtr(p unsafe.Pointer) unsafe.Pointer { return *(*unsafe.Pointer)(p) }
+
+// ptrToNPtr follows the pointer ptrNum times, or up to a nil one. It is written to be inlined into Run,
+// which is a big function: only a function whose cost is 20 or less is inlined into it.
+func ptrToNPtr(p unsafe.Pointer, ptrNum uint8) unsafe.Pointer {
+ for ; ptrNum > 0 && p != nil; ptrNum-- {
+ p = *(*unsafe.Pointer)(p)
}
return p
}
-func ptrToUnsafePtr(p uintptr) unsafe.Pointer {
- return *(*unsafe.Pointer)(unsafe.Pointer(&p))
-}
-func ptrToInterface(code *encoder.Opcode, p uintptr) interface{} {
- return *(*interface{})(unsafe.Pointer(&emptyInterface{
+func ptrToInterface(code *encoder.Opcode, p unsafe.Pointer) any {
+ return *(*any)(unsafe.Pointer(&emptyInterface{
typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
+ ptr: p,
}))
}
-func appendInt(ctx *encoder.RuntimeContext, b []byte, p uintptr, code *encoder.Opcode) []byte {
+func appendInt(ctx *encoder.RuntimeContext, b []byte, p unsafe.Pointer, code *encoder.Opcode) []byte {
format := ctx.Option.ColorScheme.Int
b = append(b, format.Header...)
b = encoder.AppendInt(ctx, b, p, code)
return append(b, format.Footer...)
}
-func appendUint(ctx *encoder.RuntimeContext, b []byte, p uintptr, code *encoder.Opcode) []byte {
+func appendUint(ctx *encoder.RuntimeContext, b []byte, p unsafe.Pointer, code *encoder.Opcode) []byte {
format := ctx.Option.ColorScheme.Uint
b = append(b, format.Header...)
b = encoder.AppendUint(ctx, b, p, code)
return append(b, format.Footer...)
}
-func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) []byte {
+// appendFloat32 appends the float, or returns the error for one which is not finite as encoding/json does.
+func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) ([]byte, error) {
+ if isInfOrNaN(float64(v)) {
+ return nil, errUnsupportedFloat(float64(v))
+ }
format := ctx.Option.ColorScheme.Float
b = append(b, format.Header...)
b = encoder.AppendFloat32(ctx, b, v)
- return append(b, format.Footer...)
+ return append(b, format.Footer...), nil
}
func appendFloat64(ctx *encoder.RuntimeContext, b []byte, v float64) []byte {
@@ -204,14 +191,14 @@ func appendMapEnd(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte
return b
}
-func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalJSON(ctx, code, b, v)
+func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalJSON(ctx, code, b, p)
}
-func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
+func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
format := ctx.Option.ColorScheme.String
b = append(b, format.Header...)
- bb, err := encoder.AppendMarshalText(ctx, code, b, v)
+ bb, err := encoder.AppendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -259,6 +246,11 @@ func appendStructEnd(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []b
return append(b, '}', ',')
}
+// appendLongStructKey appends a key of any length: every key is written by appendStructKey here.
+func appendLongStructKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
+ return appendStructKey(ctx, code, b)
+}
+
func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
last := len(b) - 1
if b[last] == ',' {
@@ -268,7 +260,45 @@ func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode,
return appendStructEnd(ctx, code, b)
}
-func restoreIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, _ uintptr) {}
-func storeIndent(_ uintptr, _ *encoder.Opcode, _ uintptr) {}
func appendMapKeyIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte { return b }
func appendArrayElemIndent(_ *encoder.RuntimeContext, _ *encoder.Opcode, b []byte) []byte { return b }
+
+// appendScalar appends the value at p by the opcode of a scalar, with the comma: what the VM does for the opcode.
+// It is for a scalar held by an interface value, which is encoded without a frame.
+//
+//go:noinline
+func appendScalar(ctx *encoder.RuntimeContext, b []byte, code *encoder.Opcode, p unsafe.Pointer) ([]byte, error) {
+ switch code.Op {
+ case encoder.OpInt:
+ b = appendInt(ctx, b, p, code)
+ case encoder.OpUint:
+ b = appendUint(ctx, b, p, code)
+ case encoder.OpFloat32:
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ case encoder.OpFloat64:
+ v := ptrToFloat64(p)
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ case encoder.OpString:
+ b = appendString(ctx, b, ptrToString(p))
+ case encoder.OpBool:
+ b = appendBool(ctx, b, ptrToBool(p))
+ case encoder.OpBytes:
+ b = appendByteSlice(ctx, b, ptrToBytes(p))
+ case encoder.OpNumber:
+ bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ default:
+ return nil, errUnimplementedOp(code.Op)
+ }
+ return appendComma(ctx, b), nil
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_color/vm.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_color/vm.go
index a63e83e55..b624d6d1f 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_color/vm.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_color/vm.go
@@ -1,19 +1,13 @@
-// Code generated by internal/cmd/generator. DO NOT EDIT!
+// Code generated by internal/cmd/generator. DO NOT EDIT.
package vm_color
import (
- "math"
- "reflect"
- "sort"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
- "github.com/goccy/go-json/internal/runtime"
)
func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]byte, error) {
- recursiveLevel := 0
- ptrOffset := uintptr(0)
ctxptr := ctx.Ptr()
var code *encoder.Opcode
if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
@@ -26,13 +20,245 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
switch code.Op {
default:
return nil, errUnimplementedOp(code.Op)
+ // The opcodes of a value of interface{} and of a map are first: the position of a case in the switch
+ // changes the layout of the code of the VM, and these were the ones to suffer from it.
+ case encoder.OpInterfacePtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpInterface:
+ p := load(ctxptr, code.Idx)
+ // An interface value which holds nothing is null: its first word, the type or the itab, is nil.
+ // It is decided here, as a call costs more than the check: the fields of interface{} of a struct
+ // are nil in many a value.
+ if p == nil || *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpInterfaceEnd:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructFieldInterface:
+ // The field of a value of interface{}: the key, and then what OpInterface does for the value. A field
+ // of interface{} is nil in many a value, and it is null then, without a call. The cases are here, with
+ // the ones of a value of interface{}, not with the other fields: there they cost the small structs 3%.
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ b = appendStructKey(ctx, code, b)
+ if *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpStructFieldOmitEmptyInterface:
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ if *(*unsafe.Pointer)(p) == nil {
+ code = code.NextField
+ break
+ }
+ b = appendStructKey(ctx, code, b)
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpMapPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpMap:
+ p := load(ctxptr, code.Idx)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ // The entries are read from the map into the context first ( encoder.MapLayout ), and encoded from
+ // there: in the order of the map, or sorted by their keys when they are strings. A sorted map whose
+ // keys are not strings is encoded as it comes and its entries are put in the order of their encoded
+ // keys at OpMapEnd.
+ mapCtx := encoder.NewMapContext(ctx)
+ if code.Flags&encoder.MapStringKeyFlags != 0 && (code.Map.ScalarValue || code.Map.InterfaceValue) && ctx.Option.Flag&encoder.UnorderedMapOption != 0 {
+ // the entries are written as the map is read: all of them when the values are scalars, and the
+ // ones which hold a scalar when the values are of interface{}, and the context gets the others.
+ if encoder.MapLen(p) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ }
+ bb, err := appendMapAsRead(ctx, code, appendStructHead(ctx, b), p, mapCtx)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ } else if code.Map.Collect(p, mapCtx) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ } else {
+ b = appendStructHead(ctx, b)
+ if (ctx.Option.Flag & encoder.UnorderedMapOption) == 0 {
+ if code.Flags&encoder.MapStringKeyFlags != 0 {
+ mapCtx.SortKeys()
+ mapCtx.Sorted = true
+ mapCtx.DirectEntries = code.Map.ScalarValue || code.Map.InterfaceValue
+ } else {
+ mapCtx.SortByEncodedKeys()
+ mapCtx.First = len(b)
+ }
+ }
+ }
+ store(ctxptr, code.Idx, unsafe.Pointer(mapCtx))
+ // the first entry is begun as the others are, by the header: it has the next opcode and the flags
+ // of the key opcode.
+ mapCtx.Idx = -1
+ fallthrough
+ case encoder.OpMapKey:
+ // After an entry, or at the start with Idx -1: the next entry is begun, or the map is ended.
+ // A key of a string is written here, and the value of the entry is given to the opcode of the
+ // value: that saves the opcodes of the key and of the value for every entry. The key of another
+ // kind is given to its opcode, which OpMapValue follows.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ byEncodedKeys := mapCtx.Slice.Items != nil
+ idx := mapCtx.Idx
+ if byEncodedKeys && idx >= 0 {
+ mapCtx.Slice.Items[idx].Value = b[mapCtx.Start:]
+ }
+ idx++
+ if mapCtx.DirectEntries && idx < mapCtx.Len {
+ // the entries from here are written by one call, up to one whose value is left to its opcodes.
+ bb, next, err := appendSortedMapEntries(ctx, code, b, mapCtx, idx)
+ if err != nil {
+ return nil, err
+ }
+ b, idx = bb, next
+ }
+ if idx == mapCtx.Len {
+ if byEncodedKeys {
+ code = code.End
+ } else {
+ b = appendObjectEnd(ctx, code, b)
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.End.Next
+ }
+ break
+ }
+ mapCtx.Idx = idx
+ if byEncodedKeys {
+ mapCtx.Start = len(b)
+ } else {
+ b = appendMapKeyIndent(ctx, code, b)
+ }
+ if code.Flags&encoder.MapStringKeyFlags == 0 {
+ store(ctxptr, code.Next.Idx, mapCtx.KeyAt(idx))
+ code = code.Next
+ break
+ }
+ if mapCtx.Sorted {
+ idx = int(mapCtx.Order[idx])
+ }
+ b = appendString(ctx, b, mapCtx.Keys[idx])
+ b = appendComma(ctx, b)
+ b = appendColon(ctx, b)
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(idx))
+ code = code.Next
+ case encoder.OpMapValue:
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ if mapCtx.Slice.Items != nil {
+ mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:]
+ mapCtx.Start = len(b)
+ } else {
+ b = appendColon(ctx, b)
+ }
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(mapCtx.Idx))
+ code = code.Next
+ case encoder.OpMapEnd:
+ // the entries of a sorted map whose keys are not strings, in the order of their encoded keys.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ mapCtx.Slice.Sort()
+ buf := mapCtx.Buf
+ for _, item := range mapCtx.Slice.Items {
+ buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
+ }
+ buf = appendMapEnd(ctx, code, buf)
+ b = b[:mapCtx.First]
+ b = append(b, buf...)
+ mapCtx.Buf = buf
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.Next
case encoder.OpPtr:
p := load(ctxptr, code.Idx)
code = code.Next
store(ctxptr, code.Idx, ptrToPtr(p))
case encoder.OpIntPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -44,8 +270,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpUintPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -56,21 +282,125 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = appendComma(ctx, b)
code = code.Next
+ // The values as strings, for the keys of a map and for the string option of a field whose key is longer
+ // than a chunk: such a field is encoded by the generic field opcode and the opcode of its value.
+ case encoder.OpIntPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpIntString:
b = append(b, '"')
b = appendInt(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpUintPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpUintString:
b = append(b, '"')
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpFloat32PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat32String:
+ b = append(b, '"')
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpFloat64PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat64String:
+ v := ptrToFloat64(load(ctxptr, code.Idx))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = append(b, '"')
+ b = appendFloat64(ctx, b, v)
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpBoolPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpBoolString:
+ b = append(b, '"')
+ b = appendBool(ctx, b, ptrToBool(load(ctxptr, code.Idx)))
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpStringPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpStringString:
+ b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(load(ctxptr, code.Idx)))))
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpNumberPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpNumberString:
+ b = append(b, '"')
+ bb, err := appendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = append(bb, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
case encoder.OpFloat32Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendComma(ctx, b)
code = code.Next
@@ -79,12 +409,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpFloat32:
- b = appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpFloat64Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -93,15 +427,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
fallthrough
case encoder.OpFloat64:
v := ptrToFloat64(load(ctxptr, code.Idx))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStringPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -113,8 +447,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBoolPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -126,8 +460,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBytesPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -139,8 +473,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpNumberPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -154,113 +488,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
b = appendComma(ctx, bb)
code = code.Next
- case encoder.OpInterfacePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpInterface:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if p == seen {
- return nil, errUnsupportedValue(code, p)
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, p)
- var (
- typ *runtime.Type
- ifacePtr unsafe.Pointer
- )
- up := ptrToUnsafePtr(p)
- if code.Flags&encoder.NonEmptyInterfaceFlags != 0 {
- iface := (*nonEmptyInterface)(up)
- ifacePtr = iface.ptr
- if iface.itab != nil {
- typ = iface.itab.typ
- }
- } else {
- iface := (*emptyInterface)(up)
- ifacePtr = iface.ptr
- typ = iface.typ
- }
- if ifacePtr == nil {
- isDirectedNil := typ != nil && typ.Kind() == reflect.Struct && !runtime.IfaceIndir(typ)
- if !isDirectedNil {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- }
- ctx.KeepRefs = append(ctx.KeepRefs, up)
- ifaceCodeSet, err := encoder.CompileToGetCodeSet(ctx, uintptr(unsafe.Pointer(typ)))
- if err != nil {
- return nil, err
- }
-
- totalLength := uintptr(code.Length) + 3
- nextTotalLength := uintptr(ifaceCodeSet.CodeLength) + 3
-
- var c *encoder.Opcode
- if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
- c = ifaceCodeSet.InterfaceEscapeKeyCode
- } else {
- c = ifaceCodeSet.InterfaceNoescapeKeyCode
- }
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += totalLength * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- ctx.BaseIndent += code.Indent
-
- newLen := offsetNum + totalLength + nextTotalLength
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- end := ifaceCodeSet.EndCode
- store(ctxptr, c.Idx, uintptr(ifacePtr))
- store(ctxptr, end.Idx, oldOffset)
- store(ctxptr, end.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, end, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpInterfaceEnd:
- recursiveLevel--
-
- // restore ctxptr
- offset := load(ctxptr, code.Idx)
- restoreIndent(ctx, code, ctxptr)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
case encoder.OpMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalJSON:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -268,7 +507,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -276,33 +515,38 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpMarshalTextPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalText:
p := load(ctxptr, code.Idx)
- if p == 0 {
- b = append(b, `""`...)
- b = appendComma(ctx, b)
+ if p == nil {
+ if (code.Flags & encoder.MapKeyFlags) != 0 {
+ // the name of a key which is a nil pointer is "", as encoding/json names it
+ b = appendComma(ctx, append(b, `""`...))
+ } else {
+ // a nil pointer value is null, as with encoding/json and as OpMarshalJSON writes it
+ b = appendNullComma(ctx, b)
+ }
code = code.Next
break
}
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
b = appendComma(ctx, bb)
code = code.Next
case encoder.OpSlicePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
@@ -312,2916 +556,123 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpSlice:
p := load(ctxptr, code.Idx)
slice := ptrToSlice(p)
- if p == 0 || slice.Data == nil {
+ if p == nil || slice.Data == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- store(ctxptr, code.ElemIdx, 0)
- store(ctxptr, code.Length, uintptr(slice.Len))
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ storeInt(ctxptr, code.ElemIdx, 0)
+ storeInt(ctxptr, code.Length, uintptr(slice.Len))
+ store(ctxptr, code.Idx, slice.Data)
if slice.Len > 0 {
b = appendArrayHead(ctx, code, b)
code = code.Next
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ store(ctxptr, code.Idx, slice.Data)
} else {
b = appendEmptyArray(ctx, b)
code = code.End.Next
}
case encoder.OpSliceElem:
- idx := load(ctxptr, code.ElemIdx)
- length := load(ctxptr, code.Length)
+ idx := loadInt(ctxptr, code.ElemIdx)
+ length := loadInt(ctxptr, code.Length)
idx++
if idx < length {
b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
+ storeInt(ctxptr, code.ElemIdx, idx)
data := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, data+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpArrayPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- if code.Length > 0 {
- b = appendArrayHead(ctx, code, b)
- store(ctxptr, code.ElemIdx, 0)
- code = code.Next
- store(ctxptr, code.Idx, p)
- } else {
- b = appendEmptyArray(ctx, b)
- code = code.End.Next
- }
- case encoder.OpArrayElem:
- idx := load(ctxptr, code.ElemIdx)
- idx++
- if idx < uintptr(code.Length) {
- b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
- p := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, p+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpMapPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- uptr := ptrToUnsafePtr(p)
- mlen := maplen(uptr)
- if mlen <= 0 {
- b = appendEmptyObject(ctx, b)
- code = code.End.Next
- break
- }
- b = appendStructHead(ctx, b)
- unorderedMap := (ctx.Option.Flag & encoder.UnorderedMapOption) != 0
- mapCtx := encoder.NewMapContext(mlen, unorderedMap)
- mapiterinit(code.Type, uptr, &mapCtx.Iter)
- store(ctxptr, code.Idx, uintptr(unsafe.Pointer(mapCtx)))
- ctx.KeepRefs = append(ctx.KeepRefs, unsafe.Pointer(mapCtx))
- if unorderedMap {
- b = appendMapKeyIndent(ctx, code.Next, b)
- } else {
- mapCtx.Start = len(b)
- mapCtx.First = len(b)
- }
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- case encoder.OpMapKey:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- idx := mapCtx.Idx
- idx++
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- if idx < mapCtx.Len {
- b = appendMapKeyIndent(ctx, code, b)
- mapCtx.Idx = int(idx)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- b = appendObjectEnd(ctx, code, b)
- encoder.ReleaseMapContext(mapCtx)
- code = code.End.Next
- }
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Value = b[mapCtx.Start:len(b)]
- if idx < mapCtx.Len {
- mapCtx.Idx = int(idx)
- mapCtx.Start = len(b)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- code = code.End
- }
- }
- case encoder.OpMapValue:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- b = appendColon(ctx, b)
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:len(b)]
- mapCtx.Start = len(b)
- }
- value := mapitervalue(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(value))
- mapiternext(&mapCtx.Iter)
- code = code.Next
- case encoder.OpMapEnd:
- // this operation only used by sorted map.
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- sort.Sort(mapCtx.Slice)
- buf := mapCtx.Buf
- for _, item := range mapCtx.Slice.Items {
- buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
- }
- buf = appendMapEnd(ctx, code, buf)
- b = b[:mapCtx.First]
- b = append(b, buf...)
- mapCtx.Buf = buf
- encoder.ReleaseMapContext(mapCtx)
- code = code.Next
- case encoder.OpRecursivePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpRecursive:
- ptr := load(ctxptr, code.Idx)
- if ptr != 0 {
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if ptr == seen {
- return nil, errUnsupportedValue(code, ptr)
- }
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, ptr)
- c := code.Jmp.Code
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += code.Jmp.CurLen * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- indentDiffFromTop := c.Indent - 1
- ctx.BaseIndent += code.Indent - indentDiffFromTop
-
- newLen := offsetNum + code.Jmp.CurLen + code.Jmp.NextLen
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- store(ctxptr, c.Idx, ptr)
- store(ctxptr, c.End.Next.Idx, oldOffset)
- store(ctxptr, c.End.Next.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, c.End.Next, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpRecursiveEnd:
- recursiveLevel--
-
- // restore ctxptr
- restoreIndent(ctx, code, ctxptr)
- offset := load(ctxptr, code.Idx)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
- case encoder.OpStructPtrHead:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHead:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if len(code.Key) > 0 {
- if (code.Flags&encoder.IsTaggedKeyFlags) != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
- }
- }
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if p == 0 || (ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- u64 := ptrToUint64(p, code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendInt(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendUint(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNull(ctx, b)
- b = appendComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p+uintptr(code.Offset)))))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, ptrToString(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendBool(ctx, b, ptrToBool(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBytes(p + uintptr(code.Offset))
- if len(v) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadArray, encoder.OpStructPtrHeadSlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadArray, encoder.OpStructHeadSlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyArray:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptySlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptySlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- slice := ptrToSlice(p)
- if slice.Len == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadArrayPtr, encoder.OpStructPtrHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadArrayPtr, encoder.OpStructHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyArrayPtr, encoder.OpStructPtrHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyArrayPtr, encoder.OpStructHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- if maplen(ptrToUnsafePtr(p)) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- iface := ptrToInterface(code, p)
- if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
+ size := uintptr(code.Size)
+ code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(data, idx*size))
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ case encoder.OpArrayPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
+ store(ctxptr, code.Idx, p)
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalText:
+ case encoder.OpArray:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- code = code.NextField
+ if code.Length > 0 {
+ b = appendArrayHead(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, 0)
+ code = code.Next
+ store(ctxptr, code.Idx, p)
} else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
+ b = appendEmptyArray(ctx, b)
+ code = code.End.Next
+ }
+ case encoder.OpArrayElem:
+ idx := loadInt(ctxptr, code.ElemIdx)
+ idx++
+ if idx < uintptr(code.Length) {
+ b = appendArrayElemIndent(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, idx)
+ p := load(ctxptr, code.Idx)
+ size := uintptr(code.Size)
code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(p, idx*size))
+ } else {
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- case encoder.OpStructPtrHeadMarshalTextPtr:
+ case encoder.OpRecursivePtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
+ if p == nil {
+ code = code.Next
break
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadMarshalTextPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
+ case encoder.OpRecursive:
+ if code.Flags&encoder.TailRecursiveFlags != 0 {
+ // a value of a list, the last field of a value of the same type: encoded in this frame, with
+ // the braces of the value it is the field of closed at OpRecursiveEnd.
+ p := load(ctxptr, code.Idx)
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ if err := ctx.RecordSeen(code, p); err != nil {
+ return nil, err
+ }
}
- code = code.End.Next
+ first := code.Jmp.Code
+ store(ctxptr, first.Idx, p)
+ // the end of the struct is next, then OpRecursiveEnd, which has what the indent is deeper by.
+ ctx.BaseIndent += code.Next.Next.Indent
+ ctx.TailLevels++
+ ctx.RecursiveLevel++
+ code = first
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ first, base, err := ctx.EnterRecursive(code, load(ctxptr, code.Idx))
+ if err != nil {
+ return nil, err
}
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
+ code = first
+ ctxptr = base
+ case encoder.OpRecursiveEnd:
+ // the braces of the values of a list this value was the last field of, from the innermost.
+ for ; ctx.TailLevels > 0; ctx.TailLevels-- {
+ ctx.RecursiveLevel--
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
}
- b = bb
+ ctx.BaseIndent -= code.Indent
+ b = appendStructEndSkipLast(ctx, code.Next, b)
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalTextPtr:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructPtrHead:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
@@ -3230,63 +681,74 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalTextPtr:
+ case encoder.OpStructHead:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
+ if p == nil && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendStructHead(ctx, b)
}
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
+ code = code.Next
case encoder.OpStructField:
+ // the generic field: the value is encoded by its own opcode, and the key may be longer than a chunk.
if code.Flags&encoder.IsTaggedKeyFlags != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
}
- p := load(ctxptr, code.Idx) + uintptr(code.Offset)
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmpty:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if encoder.IsEmptyField(code.EmptyKind, code.NumBitSize, p) || (code.ZeroKind != encoder.ZeroNever && encoder.IsZeroField(code, p)) {
code = code.NextField
} else {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
code = code.Next
store(ctxptr, code.Idx, p)
}
+ case encoder.OpStructFieldInt3:
+ // Three fields of the kind in a row, then two: the fields after the first are encoded without
+ // a dispatch, by falling through to the case of the field. The same for the other kinds below.
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldInt2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3294,27 +756,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -3323,8 +785,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3332,9 +794,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3345,8 +807,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -3354,19 +816,33 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldUint3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldUint2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3374,27 +850,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -3403,8 +879,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3412,9 +888,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3425,8 +901,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -3437,15 +913,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
@@ -3453,70 +937,116 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldFloat643:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldFloat642:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldFloat64:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3524,9 +1054,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3536,8 +1066,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3548,9 +1078,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3562,15 +1092,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3578,11 +1108,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3591,13 +1121,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -3608,12 +1138,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3621,15 +1151,29 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldString3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldString2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -3638,14 +1182,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringString:
p := load(ctxptr, code.Idx)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -3654,9 +1198,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -3665,8 +1209,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendComma(ctx, b)
@@ -3674,9 +1218,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -3685,22 +1229,36 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldBool3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldBool2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -3711,13 +1269,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3728,9 +1286,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -3739,8 +1297,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendComma(ctx, b)
@@ -3748,9 +1306,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3761,8 +1319,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -3773,12 +1331,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -3787,9 +1345,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -3798,8 +1356,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendComma(ctx, b)
@@ -3808,7 +1366,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3816,7 +1374,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -3830,7 +1388,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3839,7 +1397,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3853,9 +1411,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3868,8 +1426,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -3880,9 +1438,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3896,8 +1454,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3911,14 +1469,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSON:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3928,11 +1486,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSON:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
code = code.NextField
break
}
@@ -3942,7 +1500,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3951,11 +1509,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSONPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3965,10 +1523,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3978,14 +1536,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalText:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3995,16 +1553,21 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalText:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
+ code = code.NextField
+ break
+ }
+ iface := ptrToInterface(code, p)
+ if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
code = code.NextField
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4013,11 +1576,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalTextPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4027,10 +1590,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalTextPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4040,25 +1603,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldArrayPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArrayPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4068,12 +1631,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlice:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlice:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
slice := ptrToSlice(p)
if slice.Len == 0 {
code = code.NextField
@@ -4085,13 +1648,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlicePtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlicePtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4101,13 +1664,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMap:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMap:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 || maplen(ptrToUnsafePtr(p)) == 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p == nil || encoder.MapLen(p) == 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4117,19 +1680,19 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMapPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMapPtr:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
- if p != 0 {
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4139,13 +1702,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldStruct:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyStruct:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if ptrToPtr(p) == nil && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4158,16 +1721,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4177,18 +1740,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4198,8 +1761,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -4208,8 +1771,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4220,8 +1783,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4232,8 +1795,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -4246,16 +1809,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4265,18 +1828,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4286,8 +1849,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -4296,8 +1859,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4308,8 +1871,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4320,8 +1883,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -4334,15 +1897,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4352,17 +1923,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4372,20 +1951,28 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4394,23 +1981,31 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4419,8 +2014,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4429,9 +2024,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4443,8 +2038,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4455,9 +2050,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4472,15 +2067,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendStructEnd(ctx, code, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4488,11 +2083,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4504,13 +2099,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4520,11 +2115,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -4538,12 +2133,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -4555,13 +2150,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -4573,8 +2168,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -4583,8 +2178,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendStructEnd(ctx, code, b)
@@ -4595,8 +2190,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -4605,8 +2200,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendStructEnd(ctx, code, b)
@@ -4617,12 +2212,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -4635,13 +2230,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4655,8 +2250,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -4665,8 +2260,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendStructEnd(ctx, code, b)
@@ -4677,8 +2272,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4689,8 +2284,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -4703,12 +2298,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -4720,8 +2315,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytesPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -4730,8 +2325,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendStructEnd(ctx, code, b)
@@ -4742,7 +2337,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4750,7 +2345,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -4766,7 +2361,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4775,7 +2370,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4792,8 +2387,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4806,8 +2401,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -4821,8 +2416,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4836,8 +2431,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4857,3 +2452,142 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
END:
return b, nil
}
+
+// appendMapAsRead writes the entries of the map at p, whose keys are of a string kind, as the map is read: the
+// map is not sorted, so the order of its entries is not specified, and an entry written here costs neither a
+// copy to the context nor the opcodes of an entry. When the values are written by one opcode of a scalar,
+// every entry is written. When the values are of interface{}, the ones which hold a scalar or nothing are
+// written, and the others are given to the context, to be encoded by the opcodes of their values from
+// OpMapKey on: they come after the scalars, which are most of the entries of a JSON object held by a value of
+// interface{}.
+//
+//go:noinline
+func appendMapAsRead(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer, mapCtx *encoder.MapContext) ([]byte, error) {
+ code.Map.Reset(mapCtx)
+ if code.Map.ScalarValue {
+ mapCtx.Len = 0
+ return mapScalarValueWriters[code.Map.ValueWords](ctx, code, b, p)
+ }
+ for k, v := range *(*map[string]any)(unsafe.Pointer(&p)) {
+ iface := (*emptyInterface)(unsafe.Pointer(&v))
+ var scalar *encoder.Opcode
+ // A value of interface{} which holds nothing is null. What holds a value whose data word is nil, such
+ // as a nil pointer, is left to OpInterface, which knows what is null and what is not.
+ if iface.typ != nil && iface.ptr != nil {
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, err
+ }
+ }
+ scalar = codeSet.Scalar
+ }
+ if iface.typ != nil && scalar == nil {
+ mapCtx.Keys = append(mapCtx.Keys, k)
+ mapCtx.Values = append(mapCtx.Values, unsafe.Slice((*byte)(unsafe.Pointer(&v)), unsafe.Sizeof(v))...)
+ continue
+ }
+ b = appendMapKey(ctx, code, b, k)
+ if scalar == nil {
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ // the data word of the interface value is the address of the scalar, or the pointer to it.
+ bb, err := appendScalar(ctx, b, scalar, iface.ptr)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ mapCtx.Len = len(mapCtx.Keys)
+ return b, nil
+}
+
+// appendSortedMapEntries writes the entries of a sorted map with keys of a string kind directly, as
+// appendMapAsRead does for a map which is not sorted, from the one at idx in the order of the keys, as the
+// opcodes of the entries would: every value when the values are written by one opcode of a scalar
+// ( MapLayout.ScalarValue ), and a value of interface{} which holds a scalar or nothing
+// ( MapLayout.InterfaceValue ). It returns the index of the first entry it doesn't write, whose value is left to
+// its opcodes, or the number of the entries. code is the opcode of the keys, followed by the one of the values.
+//
+//go:noinline
+func appendSortedMapEntries(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, mapCtx *encoder.MapContext, idx int) ([]byte, int, error) {
+ scalarValue := mapCtx.ScalarValue()
+ for ; idx < mapCtx.Len; idx++ {
+ i := int(mapCtx.Order[idx])
+ p := mapCtx.ValueAt(i)
+ scalar := code.Next
+ if !scalarValue {
+ // as appendMapAsRead does for a value of interface{}.
+ iface := (*emptyInterface)(p)
+ if iface.typ == nil {
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ if iface.ptr == nil {
+ return b, idx, nil
+ }
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, 0, err
+ }
+ }
+ if codeSet.Scalar == nil {
+ return b, idx, nil
+ }
+ scalar = codeSet.Scalar
+ p = iface.ptr
+ }
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ bb, err := appendScalar(ctx, b, scalar, p)
+ if err != nil {
+ return nil, 0, err
+ }
+ b = bb
+ }
+ return b, idx, nil
+}
+
+// appendMapKey writes the key of an entry of a map, as OpMapKey does.
+func appendMapKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, k string) []byte {
+ b = appendMapKeyIndent(ctx, code, b)
+ b = appendString(ctx, b, k)
+ b = appendComma(ctx, b)
+ return appendColon(ctx, b)
+}
+
+// appendMapScalarValues writes the entries of the map at p, whose values are written by the opcode of a
+// scalar which follows the header, as the map is ranged over as a map of values of V: the layout of a map
+// depends only on the sizes of the key and of the value ( encoder.MapLayout ).
+func appendMapScalarValues[V any](ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ value := code.Next
+ // v is declared out of the loop: its address is given to appendScalar, so it lives on the heap, and a
+ // variable of the loop would be allocated for each entry.
+ var (
+ k string
+ v V
+ )
+ for k, v = range *(*map[string]V)(unsafe.Pointer(&p)) {
+ b = appendMapKey(ctx, code, b, k)
+ bb, err := appendScalar(ctx, b, value, unsafe.Pointer(&v))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ return b, nil
+}
+
+// mapScalarValueWriters are appendMapScalarValues by the words of a value.
+var mapScalarValueWriters = [encoder.MapScalarValueWords + 1]func(*encoder.RuntimeContext, *encoder.Opcode, []byte, unsafe.Pointer) ([]byte, error){
+ appendMapScalarValues[[0]uint64],
+ appendMapScalarValues[[1]uint64],
+ appendMapScalarValues[[2]uint64],
+ appendMapScalarValues[[3]uint64],
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/util.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/util.go
index 2395abec9..ddad2fcc8 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/util.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/util.go
@@ -3,37 +3,21 @@ package vm_color_indent
import (
"encoding/json"
"fmt"
+ "math"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
"github.com/goccy/go-json/internal/runtime"
)
-const uintptrSize = 4 << (^uintptr(0) >> 63)
-
var (
appendIndent = encoder.AppendIndent
appendStructEnd = encoder.AppendStructEndIndent
- errUnsupportedValue = encoder.ErrUnsupportedValue
errUnsupportedFloat = encoder.ErrUnsupportedFloat
- mapiterinit = encoder.MapIterInit
- mapiterkey = encoder.MapIterKey
- mapitervalue = encoder.MapIterValue
- mapiternext = encoder.MapIterNext
- maplen = encoder.MapLen
)
type emptyInterface struct {
- typ *runtime.Type
- ptr unsafe.Pointer
-}
-
-type nonEmptyInterface struct {
- itab *struct {
- ityp *runtime.Type // static interface type
- typ *runtime.Type // dynamic concrete type
- // unused fields...
- }
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
@@ -41,91 +25,93 @@ func errUnimplementedOp(op encoder.OpType) error {
return fmt.Errorf("encoder (indent): opcode %s has not been implemented", op)
}
-func load(base uintptr, idx uint32) uintptr {
- addr := base + uintptr(idx)
- return **(**uintptr)(unsafe.Pointer(&addr))
+// load / store are for the half of a slot for a pointer, and loadInt / storeInt are for the other half.
+// A pointer is stored as uintptr, which needs no write barrier: see encoder.Slot.
+
+func load(base unsafe.Pointer, idx uint32) unsafe.Pointer {
+ return *(*unsafe.Pointer)(unsafe.Add(base, idx))
}
-func store(base uintptr, idx uint32, p uintptr) {
- addr := base + uintptr(idx)
- **(**uintptr)(unsafe.Pointer(&addr)) = p
+func store(base unsafe.Pointer, idx uint32, p unsafe.Pointer) {
+ *(*uintptr)(unsafe.Add(base, idx)) = uintptr(p)
}
-func loadNPtr(base uintptr, idx uint32, ptrNum uint8) uintptr {
- addr := base + uintptr(idx)
- p := **(**uintptr)(unsafe.Pointer(&addr))
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
- }
- return p
+func loadInt(base unsafe.Pointer, idx uint32) uintptr {
+ return *(*uintptr)(unsafe.Add(base, idx))
+}
+
+func storeInt(base unsafe.Pointer, idx uint32, v uintptr) {
+ *(*uintptr)(unsafe.Add(base, idx)) = v
}
-func ptrToUint64(p uintptr, bitSize uint8) uint64 {
+func ptrToUint64(p unsafe.Pointer, bitSize uint8) uint64 {
switch bitSize {
case 8:
- return (uint64)(**(**uint8)(unsafe.Pointer(&p)))
+ return uint64(*(*uint8)(p))
case 16:
- return (uint64)(**(**uint16)(unsafe.Pointer(&p)))
+ return uint64(*(*uint16)(p))
case 32:
- return (uint64)(**(**uint32)(unsafe.Pointer(&p)))
+ return uint64(*(*uint32)(p))
case 64:
- return **(**uint64)(unsafe.Pointer(&p))
+ return *(*uint64)(p)
}
return 0
}
-
-func ptrToFloat32(p uintptr) float32 { return **(**float32)(unsafe.Pointer(&p)) }
-func ptrToFloat64(p uintptr) float64 { return **(**float64)(unsafe.Pointer(&p)) }
-func ptrToBool(p uintptr) bool { return **(**bool)(unsafe.Pointer(&p)) }
-func ptrToBytes(p uintptr) []byte { return **(**[]byte)(unsafe.Pointer(&p)) }
-func ptrToNumber(p uintptr) json.Number { return **(**json.Number)(unsafe.Pointer(&p)) }
-func ptrToString(p uintptr) string { return **(**string)(unsafe.Pointer(&p)) }
-func ptrToSlice(p uintptr) *runtime.SliceHeader { return *(**runtime.SliceHeader)(unsafe.Pointer(&p)) }
-func ptrToPtr(p uintptr) uintptr {
- return uintptr(**(**unsafe.Pointer)(unsafe.Pointer(&p)))
-}
-func ptrToNPtr(p uintptr, ptrNum uint8) uintptr {
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
+func ptrToFloat32(p unsafe.Pointer) float32 { return *(*float32)(p) }
+
+// isInfOrNaN is whether the float is not finite, which encoding/json refuses: the exponent is all ones.
+// math.IsInf is not inlined into Run, which is a big function to the inliner; this is.
+func isInfOrNaN(v float64) bool {
+ const exponent = 0x7ff << 52
+ return math.Float64bits(v)&exponent == exponent
+}
+func ptrToFloat64(p unsafe.Pointer) float64 { return *(*float64)(p) }
+func ptrToBool(p unsafe.Pointer) bool { return *(*bool)(p) }
+func ptrToBytes(p unsafe.Pointer) []byte { return *(*[]byte)(p) }
+func ptrToNumber(p unsafe.Pointer) json.Number { return *(*json.Number)(p) }
+func ptrToString(p unsafe.Pointer) string { return *(*string)(p) }
+func ptrToSlice(p unsafe.Pointer) *runtime.SliceHeader { return (*runtime.SliceHeader)(p) }
+func ptrToPtr(p unsafe.Pointer) unsafe.Pointer { return *(*unsafe.Pointer)(p) }
+
+// ptrToNPtr follows the pointer ptrNum times, or up to a nil one. It is written to be inlined into Run,
+// which is a big function: only a function whose cost is 20 or less is inlined into it.
+func ptrToNPtr(p unsafe.Pointer, ptrNum uint8) unsafe.Pointer {
+ for ; ptrNum > 0 && p != nil; ptrNum-- {
+ p = *(*unsafe.Pointer)(p)
}
return p
}
-func ptrToUnsafePtr(p uintptr) unsafe.Pointer {
- return *(*unsafe.Pointer)(unsafe.Pointer(&p))
-}
-func ptrToInterface(code *encoder.Opcode, p uintptr) interface{} {
- return *(*interface{})(unsafe.Pointer(&emptyInterface{
+func ptrToInterface(code *encoder.Opcode, p unsafe.Pointer) any {
+ return *(*any)(unsafe.Pointer(&emptyInterface{
typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
+ ptr: p,
}))
}
-func appendInt(ctx *encoder.RuntimeContext, b []byte, p uintptr, code *encoder.Opcode) []byte {
+func appendInt(ctx *encoder.RuntimeContext, b []byte, p unsafe.Pointer, code *encoder.Opcode) []byte {
format := ctx.Option.ColorScheme.Int
b = append(b, format.Header...)
b = encoder.AppendInt(ctx, b, p, code)
return append(b, format.Footer...)
}
-func appendUint(ctx *encoder.RuntimeContext, b []byte, p uintptr, code *encoder.Opcode) []byte {
+func appendUint(ctx *encoder.RuntimeContext, b []byte, p unsafe.Pointer, code *encoder.Opcode) []byte {
format := ctx.Option.ColorScheme.Uint
b = append(b, format.Header...)
b = encoder.AppendUint(ctx, b, p, code)
return append(b, format.Footer...)
}
-func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) []byte {
+// appendFloat32 appends the float, or returns the error for one which is not finite as encoding/json does.
+func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) ([]byte, error) {
+ if isInfOrNaN(float64(v)) {
+ return nil, errUnsupportedFloat(float64(v))
+ }
format := ctx.Option.ColorScheme.Float
b = append(b, format.Header...)
b = encoder.AppendFloat32(ctx, b, v)
- return append(b, format.Footer...)
+ return append(b, format.Footer...), nil
}
func appendFloat64(ctx *encoder.RuntimeContext, b []byte, v float64) []byte {
@@ -235,14 +221,14 @@ func appendObjectEnd(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte
return append(b, '}', ',', '\n')
}
-func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalJSONIndent(ctx, code, b, v)
+func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalJSONIndent(ctx, code, b, p)
}
-func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
+func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
format := ctx.Option.ColorScheme.String
b = append(b, format.Header...)
- bb, err := encoder.AppendMarshalTextIndent(ctx, code, b, v)
+ bb, err := encoder.AppendMarshalTextIndent(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -264,6 +250,11 @@ func appendStructKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte
return append(b, ':', ' ')
}
+// appendLongStructKey appends a key of any length: every key is written by appendStructKey here.
+func appendLongStructKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
+ return appendStructKey(ctx, code, b)
+}
+
func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
last := len(b) - 1
if b[last-1] == '{' {
@@ -280,18 +271,52 @@ func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode,
return appendComma(ctx, b)
}
-func restoreIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, ctxptr uintptr) {
- ctx.BaseIndent = uint32(load(ctxptr, code.Length))
-}
-
-func storeIndent(ctxptr uintptr, code *encoder.Opcode, indent uintptr) {
- store(ctxptr, code.Length, indent)
-}
-
func appendArrayElemIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
return appendIndent(ctx, b, code.Indent+1)
}
+// appendMapKeyIndent indents an entry of a map, whose opcode is the one of the map or of its key: one deeper
+// than the braces of the map, which appendObjectEnd indents by the same opcode.
func appendMapKeyIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
- return appendIndent(ctx, b, code.Indent)
+ return appendIndent(ctx, b, code.Indent+1)
+}
+
+// appendScalar appends the value at p by the opcode of a scalar, with the comma: what the VM does for the opcode.
+// It is for a scalar held by an interface value, which is encoded without a frame.
+//
+//go:noinline
+func appendScalar(ctx *encoder.RuntimeContext, b []byte, code *encoder.Opcode, p unsafe.Pointer) ([]byte, error) {
+ switch code.Op {
+ case encoder.OpInt:
+ b = appendInt(ctx, b, p, code)
+ case encoder.OpUint:
+ b = appendUint(ctx, b, p, code)
+ case encoder.OpFloat32:
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ case encoder.OpFloat64:
+ v := ptrToFloat64(p)
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ case encoder.OpString:
+ b = appendString(ctx, b, ptrToString(p))
+ case encoder.OpBool:
+ b = appendBool(ctx, b, ptrToBool(p))
+ case encoder.OpBytes:
+ b = appendByteSlice(ctx, b, ptrToBytes(p))
+ case encoder.OpNumber:
+ bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ default:
+ return nil, errUnimplementedOp(code.Op)
+ }
+ return appendComma(ctx, b), nil
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/vm.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/vm.go
index 3b4e22e5d..70c6bc549 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/vm.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_color_indent/vm.go
@@ -1,19 +1,13 @@
-// Code generated by internal/cmd/generator. DO NOT EDIT!
+// Code generated by internal/cmd/generator. DO NOT EDIT.
package vm_color_indent
import (
- "math"
- "reflect"
- "sort"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
- "github.com/goccy/go-json/internal/runtime"
)
func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]byte, error) {
- recursiveLevel := 0
- ptrOffset := uintptr(0)
ctxptr := ctx.Ptr()
var code *encoder.Opcode
if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
@@ -26,13 +20,245 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
switch code.Op {
default:
return nil, errUnimplementedOp(code.Op)
+ // The opcodes of a value of interface{} and of a map are first: the position of a case in the switch
+ // changes the layout of the code of the VM, and these were the ones to suffer from it.
+ case encoder.OpInterfacePtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpInterface:
+ p := load(ctxptr, code.Idx)
+ // An interface value which holds nothing is null: its first word, the type or the itab, is nil.
+ // It is decided here, as a call costs more than the check: the fields of interface{} of a struct
+ // are nil in many a value.
+ if p == nil || *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpInterfaceEnd:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructFieldInterface:
+ // The field of a value of interface{}: the key, and then what OpInterface does for the value. A field
+ // of interface{} is nil in many a value, and it is null then, without a call. The cases are here, with
+ // the ones of a value of interface{}, not with the other fields: there they cost the small structs 3%.
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ b = appendStructKey(ctx, code, b)
+ if *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpStructFieldOmitEmptyInterface:
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ if *(*unsafe.Pointer)(p) == nil {
+ code = code.NextField
+ break
+ }
+ b = appendStructKey(ctx, code, b)
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpMapPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpMap:
+ p := load(ctxptr, code.Idx)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ // The entries are read from the map into the context first ( encoder.MapLayout ), and encoded from
+ // there: in the order of the map, or sorted by their keys when they are strings. A sorted map whose
+ // keys are not strings is encoded as it comes and its entries are put in the order of their encoded
+ // keys at OpMapEnd.
+ mapCtx := encoder.NewMapContext(ctx)
+ if code.Flags&encoder.MapStringKeyFlags != 0 && (code.Map.ScalarValue || code.Map.InterfaceValue) && ctx.Option.Flag&encoder.UnorderedMapOption != 0 {
+ // the entries are written as the map is read: all of them when the values are scalars, and the
+ // ones which hold a scalar when the values are of interface{}, and the context gets the others.
+ if encoder.MapLen(p) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ }
+ bb, err := appendMapAsRead(ctx, code, appendStructHead(ctx, b), p, mapCtx)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ } else if code.Map.Collect(p, mapCtx) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ } else {
+ b = appendStructHead(ctx, b)
+ if (ctx.Option.Flag & encoder.UnorderedMapOption) == 0 {
+ if code.Flags&encoder.MapStringKeyFlags != 0 {
+ mapCtx.SortKeys()
+ mapCtx.Sorted = true
+ mapCtx.DirectEntries = code.Map.ScalarValue || code.Map.InterfaceValue
+ } else {
+ mapCtx.SortByEncodedKeys()
+ mapCtx.First = len(b)
+ }
+ }
+ }
+ store(ctxptr, code.Idx, unsafe.Pointer(mapCtx))
+ // the first entry is begun as the others are, by the header: it has the next opcode and the flags
+ // of the key opcode.
+ mapCtx.Idx = -1
+ fallthrough
+ case encoder.OpMapKey:
+ // After an entry, or at the start with Idx -1: the next entry is begun, or the map is ended.
+ // A key of a string is written here, and the value of the entry is given to the opcode of the
+ // value: that saves the opcodes of the key and of the value for every entry. The key of another
+ // kind is given to its opcode, which OpMapValue follows.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ byEncodedKeys := mapCtx.Slice.Items != nil
+ idx := mapCtx.Idx
+ if byEncodedKeys && idx >= 0 {
+ mapCtx.Slice.Items[idx].Value = b[mapCtx.Start:]
+ }
+ idx++
+ if mapCtx.DirectEntries && idx < mapCtx.Len {
+ // the entries from here are written by one call, up to one whose value is left to its opcodes.
+ bb, next, err := appendSortedMapEntries(ctx, code, b, mapCtx, idx)
+ if err != nil {
+ return nil, err
+ }
+ b, idx = bb, next
+ }
+ if idx == mapCtx.Len {
+ if byEncodedKeys {
+ code = code.End
+ } else {
+ b = appendObjectEnd(ctx, code, b)
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.End.Next
+ }
+ break
+ }
+ mapCtx.Idx = idx
+ if byEncodedKeys {
+ mapCtx.Start = len(b)
+ } else {
+ b = appendMapKeyIndent(ctx, code, b)
+ }
+ if code.Flags&encoder.MapStringKeyFlags == 0 {
+ store(ctxptr, code.Next.Idx, mapCtx.KeyAt(idx))
+ code = code.Next
+ break
+ }
+ if mapCtx.Sorted {
+ idx = int(mapCtx.Order[idx])
+ }
+ b = appendString(ctx, b, mapCtx.Keys[idx])
+ b = appendComma(ctx, b)
+ b = appendColon(ctx, b)
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(idx))
+ code = code.Next
+ case encoder.OpMapValue:
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ if mapCtx.Slice.Items != nil {
+ mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:]
+ mapCtx.Start = len(b)
+ } else {
+ b = appendColon(ctx, b)
+ }
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(mapCtx.Idx))
+ code = code.Next
+ case encoder.OpMapEnd:
+ // the entries of a sorted map whose keys are not strings, in the order of their encoded keys.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ mapCtx.Slice.Sort()
+ buf := mapCtx.Buf
+ for _, item := range mapCtx.Slice.Items {
+ buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
+ }
+ buf = appendMapEnd(ctx, code, buf)
+ b = b[:mapCtx.First]
+ b = append(b, buf...)
+ mapCtx.Buf = buf
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.Next
case encoder.OpPtr:
p := load(ctxptr, code.Idx)
code = code.Next
store(ctxptr, code.Idx, ptrToPtr(p))
case encoder.OpIntPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -44,8 +270,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpUintPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -56,21 +282,125 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = appendComma(ctx, b)
code = code.Next
+ // The values as strings, for the keys of a map and for the string option of a field whose key is longer
+ // than a chunk: such a field is encoded by the generic field opcode and the opcode of its value.
+ case encoder.OpIntPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpIntString:
b = append(b, '"')
b = appendInt(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpUintPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpUintString:
b = append(b, '"')
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpFloat32PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat32String:
+ b = append(b, '"')
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpFloat64PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat64String:
+ v := ptrToFloat64(load(ctxptr, code.Idx))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = append(b, '"')
+ b = appendFloat64(ctx, b, v)
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpBoolPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpBoolString:
+ b = append(b, '"')
+ b = appendBool(ctx, b, ptrToBool(load(ctxptr, code.Idx)))
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpStringPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpStringString:
+ b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(load(ctxptr, code.Idx)))))
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpNumberPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpNumberString:
+ b = append(b, '"')
+ bb, err := appendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = append(bb, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
case encoder.OpFloat32Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendComma(ctx, b)
code = code.Next
@@ -79,12 +409,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpFloat32:
- b = appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpFloat64Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -93,15 +427,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
fallthrough
case encoder.OpFloat64:
v := ptrToFloat64(load(ctxptr, code.Idx))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStringPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -113,8 +447,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBoolPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -126,8 +460,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBytesPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -139,8 +473,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpNumberPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -154,113 +488,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
b = appendComma(ctx, bb)
code = code.Next
- case encoder.OpInterfacePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpInterface:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if p == seen {
- return nil, errUnsupportedValue(code, p)
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, p)
- var (
- typ *runtime.Type
- ifacePtr unsafe.Pointer
- )
- up := ptrToUnsafePtr(p)
- if code.Flags&encoder.NonEmptyInterfaceFlags != 0 {
- iface := (*nonEmptyInterface)(up)
- ifacePtr = iface.ptr
- if iface.itab != nil {
- typ = iface.itab.typ
- }
- } else {
- iface := (*emptyInterface)(up)
- ifacePtr = iface.ptr
- typ = iface.typ
- }
- if ifacePtr == nil {
- isDirectedNil := typ != nil && typ.Kind() == reflect.Struct && !runtime.IfaceIndir(typ)
- if !isDirectedNil {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- }
- ctx.KeepRefs = append(ctx.KeepRefs, up)
- ifaceCodeSet, err := encoder.CompileToGetCodeSet(ctx, uintptr(unsafe.Pointer(typ)))
- if err != nil {
- return nil, err
- }
-
- totalLength := uintptr(code.Length) + 3
- nextTotalLength := uintptr(ifaceCodeSet.CodeLength) + 3
-
- var c *encoder.Opcode
- if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
- c = ifaceCodeSet.InterfaceEscapeKeyCode
- } else {
- c = ifaceCodeSet.InterfaceNoescapeKeyCode
- }
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += totalLength * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- ctx.BaseIndent += code.Indent
-
- newLen := offsetNum + totalLength + nextTotalLength
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- end := ifaceCodeSet.EndCode
- store(ctxptr, c.Idx, uintptr(ifacePtr))
- store(ctxptr, end.Idx, oldOffset)
- store(ctxptr, end.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, end, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpInterfaceEnd:
- recursiveLevel--
-
- // restore ctxptr
- offset := load(ctxptr, code.Idx)
- restoreIndent(ctx, code, ctxptr)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
case encoder.OpMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalJSON:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -268,7 +507,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -276,33 +515,38 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpMarshalTextPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalText:
p := load(ctxptr, code.Idx)
- if p == 0 {
- b = append(b, `""`...)
- b = appendComma(ctx, b)
+ if p == nil {
+ if (code.Flags & encoder.MapKeyFlags) != 0 {
+ // the name of a key which is a nil pointer is "", as encoding/json names it
+ b = appendComma(ctx, append(b, `""`...))
+ } else {
+ // a nil pointer value is null, as with encoding/json and as OpMarshalJSON writes it
+ b = appendNullComma(ctx, b)
+ }
code = code.Next
break
}
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
b = appendComma(ctx, bb)
code = code.Next
case encoder.OpSlicePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
@@ -312,2916 +556,123 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpSlice:
p := load(ctxptr, code.Idx)
slice := ptrToSlice(p)
- if p == 0 || slice.Data == nil {
+ if p == nil || slice.Data == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- store(ctxptr, code.ElemIdx, 0)
- store(ctxptr, code.Length, uintptr(slice.Len))
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ storeInt(ctxptr, code.ElemIdx, 0)
+ storeInt(ctxptr, code.Length, uintptr(slice.Len))
+ store(ctxptr, code.Idx, slice.Data)
if slice.Len > 0 {
b = appendArrayHead(ctx, code, b)
code = code.Next
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ store(ctxptr, code.Idx, slice.Data)
} else {
b = appendEmptyArray(ctx, b)
code = code.End.Next
}
case encoder.OpSliceElem:
- idx := load(ctxptr, code.ElemIdx)
- length := load(ctxptr, code.Length)
+ idx := loadInt(ctxptr, code.ElemIdx)
+ length := loadInt(ctxptr, code.Length)
idx++
if idx < length {
b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
+ storeInt(ctxptr, code.ElemIdx, idx)
data := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, data+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpArrayPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- if code.Length > 0 {
- b = appendArrayHead(ctx, code, b)
- store(ctxptr, code.ElemIdx, 0)
- code = code.Next
- store(ctxptr, code.Idx, p)
- } else {
- b = appendEmptyArray(ctx, b)
- code = code.End.Next
- }
- case encoder.OpArrayElem:
- idx := load(ctxptr, code.ElemIdx)
- idx++
- if idx < uintptr(code.Length) {
- b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
- p := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, p+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpMapPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- uptr := ptrToUnsafePtr(p)
- mlen := maplen(uptr)
- if mlen <= 0 {
- b = appendEmptyObject(ctx, b)
- code = code.End.Next
- break
- }
- b = appendStructHead(ctx, b)
- unorderedMap := (ctx.Option.Flag & encoder.UnorderedMapOption) != 0
- mapCtx := encoder.NewMapContext(mlen, unorderedMap)
- mapiterinit(code.Type, uptr, &mapCtx.Iter)
- store(ctxptr, code.Idx, uintptr(unsafe.Pointer(mapCtx)))
- ctx.KeepRefs = append(ctx.KeepRefs, unsafe.Pointer(mapCtx))
- if unorderedMap {
- b = appendMapKeyIndent(ctx, code.Next, b)
- } else {
- mapCtx.Start = len(b)
- mapCtx.First = len(b)
- }
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- case encoder.OpMapKey:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- idx := mapCtx.Idx
- idx++
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- if idx < mapCtx.Len {
- b = appendMapKeyIndent(ctx, code, b)
- mapCtx.Idx = int(idx)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- b = appendObjectEnd(ctx, code, b)
- encoder.ReleaseMapContext(mapCtx)
- code = code.End.Next
- }
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Value = b[mapCtx.Start:len(b)]
- if idx < mapCtx.Len {
- mapCtx.Idx = int(idx)
- mapCtx.Start = len(b)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- code = code.End
- }
- }
- case encoder.OpMapValue:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- b = appendColon(ctx, b)
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:len(b)]
- mapCtx.Start = len(b)
- }
- value := mapitervalue(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(value))
- mapiternext(&mapCtx.Iter)
- code = code.Next
- case encoder.OpMapEnd:
- // this operation only used by sorted map.
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- sort.Sort(mapCtx.Slice)
- buf := mapCtx.Buf
- for _, item := range mapCtx.Slice.Items {
- buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
- }
- buf = appendMapEnd(ctx, code, buf)
- b = b[:mapCtx.First]
- b = append(b, buf...)
- mapCtx.Buf = buf
- encoder.ReleaseMapContext(mapCtx)
- code = code.Next
- case encoder.OpRecursivePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpRecursive:
- ptr := load(ctxptr, code.Idx)
- if ptr != 0 {
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if ptr == seen {
- return nil, errUnsupportedValue(code, ptr)
- }
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, ptr)
- c := code.Jmp.Code
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += code.Jmp.CurLen * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- indentDiffFromTop := c.Indent - 1
- ctx.BaseIndent += code.Indent - indentDiffFromTop
-
- newLen := offsetNum + code.Jmp.CurLen + code.Jmp.NextLen
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- store(ctxptr, c.Idx, ptr)
- store(ctxptr, c.End.Next.Idx, oldOffset)
- store(ctxptr, c.End.Next.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, c.End.Next, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpRecursiveEnd:
- recursiveLevel--
-
- // restore ctxptr
- restoreIndent(ctx, code, ctxptr)
- offset := load(ctxptr, code.Idx)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
- case encoder.OpStructPtrHead:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHead:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if len(code.Key) > 0 {
- if (code.Flags&encoder.IsTaggedKeyFlags) != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
- }
- }
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if p == 0 || (ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- u64 := ptrToUint64(p, code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendInt(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendUint(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNull(ctx, b)
- b = appendComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p+uintptr(code.Offset)))))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, ptrToString(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendBool(ctx, b, ptrToBool(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBytes(p + uintptr(code.Offset))
- if len(v) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadArray, encoder.OpStructPtrHeadSlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadArray, encoder.OpStructHeadSlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyArray:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptySlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptySlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- slice := ptrToSlice(p)
- if slice.Len == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadArrayPtr, encoder.OpStructPtrHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadArrayPtr, encoder.OpStructHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyArrayPtr, encoder.OpStructPtrHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyArrayPtr, encoder.OpStructHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- if maplen(ptrToUnsafePtr(p)) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- iface := ptrToInterface(code, p)
- if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
+ size := uintptr(code.Size)
+ code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(data, idx*size))
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ case encoder.OpArrayPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
+ store(ctxptr, code.Idx, p)
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalText:
+ case encoder.OpArray:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- code = code.NextField
+ if code.Length > 0 {
+ b = appendArrayHead(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, 0)
+ code = code.Next
+ store(ctxptr, code.Idx, p)
} else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
+ b = appendEmptyArray(ctx, b)
+ code = code.End.Next
+ }
+ case encoder.OpArrayElem:
+ idx := loadInt(ctxptr, code.ElemIdx)
+ idx++
+ if idx < uintptr(code.Length) {
+ b = appendArrayElemIndent(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, idx)
+ p := load(ctxptr, code.Idx)
+ size := uintptr(code.Size)
code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(p, idx*size))
+ } else {
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- case encoder.OpStructPtrHeadMarshalTextPtr:
+ case encoder.OpRecursivePtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
+ if p == nil {
+ code = code.Next
break
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadMarshalTextPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
+ case encoder.OpRecursive:
+ if code.Flags&encoder.TailRecursiveFlags != 0 {
+ // a value of a list, the last field of a value of the same type: encoded in this frame, with
+ // the braces of the value it is the field of closed at OpRecursiveEnd.
+ p := load(ctxptr, code.Idx)
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ if err := ctx.RecordSeen(code, p); err != nil {
+ return nil, err
+ }
}
- code = code.End.Next
+ first := code.Jmp.Code
+ store(ctxptr, first.Idx, p)
+ // the end of the struct is next, then OpRecursiveEnd, which has what the indent is deeper by.
+ ctx.BaseIndent += code.Next.Next.Indent
+ ctx.TailLevels++
+ ctx.RecursiveLevel++
+ code = first
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ first, base, err := ctx.EnterRecursive(code, load(ctxptr, code.Idx))
+ if err != nil {
+ return nil, err
}
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
+ code = first
+ ctxptr = base
+ case encoder.OpRecursiveEnd:
+ // the braces of the values of a list this value was the last field of, from the innermost.
+ for ; ctx.TailLevels > 0; ctx.TailLevels-- {
+ ctx.RecursiveLevel--
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
}
- b = bb
+ ctx.BaseIndent -= code.Indent
+ b = appendStructEndSkipLast(ctx, code.Next, b)
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalTextPtr:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructPtrHead:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
@@ -3230,63 +681,74 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalTextPtr:
+ case encoder.OpStructHead:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
+ if p == nil && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendStructHead(ctx, b)
}
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
+ code = code.Next
case encoder.OpStructField:
+ // the generic field: the value is encoded by its own opcode, and the key may be longer than a chunk.
if code.Flags&encoder.IsTaggedKeyFlags != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
}
- p := load(ctxptr, code.Idx) + uintptr(code.Offset)
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmpty:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if encoder.IsEmptyField(code.EmptyKind, code.NumBitSize, p) || (code.ZeroKind != encoder.ZeroNever && encoder.IsZeroField(code, p)) {
code = code.NextField
} else {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
code = code.Next
store(ctxptr, code.Idx, p)
}
+ case encoder.OpStructFieldInt3:
+ // Three fields of the kind in a row, then two: the fields after the first are encoded without
+ // a dispatch, by falling through to the case of the field. The same for the other kinds below.
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldInt2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3294,27 +756,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -3323,8 +785,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3332,9 +794,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3345,8 +807,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -3354,19 +816,33 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldUint3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldUint2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3374,27 +850,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -3403,8 +879,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3412,9 +888,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3425,8 +901,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -3437,15 +913,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
@@ -3453,70 +937,116 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldFloat643:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldFloat642:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldFloat64:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3524,9 +1054,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3536,8 +1066,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3548,9 +1078,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3562,15 +1092,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3578,11 +1108,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3591,13 +1121,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -3608,12 +1138,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3621,15 +1151,29 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldString3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldString2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -3638,14 +1182,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringString:
p := load(ctxptr, code.Idx)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -3654,9 +1198,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -3665,8 +1209,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendComma(ctx, b)
@@ -3674,9 +1218,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -3685,22 +1229,36 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldBool3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldBool2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -3711,13 +1269,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3728,9 +1286,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -3739,8 +1297,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendComma(ctx, b)
@@ -3748,9 +1306,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3761,8 +1319,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -3773,12 +1331,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -3787,9 +1345,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -3798,8 +1356,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendComma(ctx, b)
@@ -3808,7 +1366,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3816,7 +1374,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -3830,7 +1388,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3839,7 +1397,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3853,9 +1411,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3868,8 +1426,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -3880,9 +1438,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3896,8 +1454,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3911,14 +1469,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSON:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3928,11 +1486,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSON:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
code = code.NextField
break
}
@@ -3942,7 +1500,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3951,11 +1509,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSONPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3965,10 +1523,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3978,14 +1536,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalText:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3995,16 +1553,21 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalText:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
+ code = code.NextField
+ break
+ }
+ iface := ptrToInterface(code, p)
+ if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
code = code.NextField
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4013,11 +1576,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalTextPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4027,10 +1590,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalTextPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4040,25 +1603,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldArrayPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArrayPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4068,12 +1631,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlice:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlice:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
slice := ptrToSlice(p)
if slice.Len == 0 {
code = code.NextField
@@ -4085,13 +1648,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlicePtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlicePtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4101,13 +1664,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMap:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMap:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 || maplen(ptrToUnsafePtr(p)) == 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p == nil || encoder.MapLen(p) == 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4117,19 +1680,19 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMapPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMapPtr:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
- if p != 0 {
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4139,13 +1702,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldStruct:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyStruct:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if ptrToPtr(p) == nil && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4158,16 +1721,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4177,18 +1740,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4198,8 +1761,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -4208,8 +1771,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4220,8 +1783,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4232,8 +1795,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -4246,16 +1809,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4265,18 +1828,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4286,8 +1849,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -4296,8 +1859,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4308,8 +1871,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4320,8 +1883,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -4334,15 +1897,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4352,17 +1923,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4372,20 +1951,28 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4394,23 +1981,31 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4419,8 +2014,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4429,9 +2024,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4443,8 +2038,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4455,9 +2050,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4472,15 +2067,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendStructEnd(ctx, code, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4488,11 +2083,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4504,13 +2099,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4520,11 +2115,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -4538,12 +2133,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -4555,13 +2150,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -4573,8 +2168,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -4583,8 +2178,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendStructEnd(ctx, code, b)
@@ -4595,8 +2190,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -4605,8 +2200,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendStructEnd(ctx, code, b)
@@ -4617,12 +2212,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -4635,13 +2230,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4655,8 +2250,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -4665,8 +2260,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendStructEnd(ctx, code, b)
@@ -4677,8 +2272,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4689,8 +2284,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -4703,12 +2298,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -4720,8 +2315,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytesPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -4730,8 +2325,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendStructEnd(ctx, code, b)
@@ -4742,7 +2337,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4750,7 +2345,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -4766,7 +2361,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4775,7 +2370,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4792,8 +2387,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4806,8 +2401,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -4821,8 +2416,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4836,8 +2431,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4857,3 +2452,142 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
END:
return b, nil
}
+
+// appendMapAsRead writes the entries of the map at p, whose keys are of a string kind, as the map is read: the
+// map is not sorted, so the order of its entries is not specified, and an entry written here costs neither a
+// copy to the context nor the opcodes of an entry. When the values are written by one opcode of a scalar,
+// every entry is written. When the values are of interface{}, the ones which hold a scalar or nothing are
+// written, and the others are given to the context, to be encoded by the opcodes of their values from
+// OpMapKey on: they come after the scalars, which are most of the entries of a JSON object held by a value of
+// interface{}.
+//
+//go:noinline
+func appendMapAsRead(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer, mapCtx *encoder.MapContext) ([]byte, error) {
+ code.Map.Reset(mapCtx)
+ if code.Map.ScalarValue {
+ mapCtx.Len = 0
+ return mapScalarValueWriters[code.Map.ValueWords](ctx, code, b, p)
+ }
+ for k, v := range *(*map[string]any)(unsafe.Pointer(&p)) {
+ iface := (*emptyInterface)(unsafe.Pointer(&v))
+ var scalar *encoder.Opcode
+ // A value of interface{} which holds nothing is null. What holds a value whose data word is nil, such
+ // as a nil pointer, is left to OpInterface, which knows what is null and what is not.
+ if iface.typ != nil && iface.ptr != nil {
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, err
+ }
+ }
+ scalar = codeSet.Scalar
+ }
+ if iface.typ != nil && scalar == nil {
+ mapCtx.Keys = append(mapCtx.Keys, k)
+ mapCtx.Values = append(mapCtx.Values, unsafe.Slice((*byte)(unsafe.Pointer(&v)), unsafe.Sizeof(v))...)
+ continue
+ }
+ b = appendMapKey(ctx, code, b, k)
+ if scalar == nil {
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ // the data word of the interface value is the address of the scalar, or the pointer to it.
+ bb, err := appendScalar(ctx, b, scalar, iface.ptr)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ mapCtx.Len = len(mapCtx.Keys)
+ return b, nil
+}
+
+// appendSortedMapEntries writes the entries of a sorted map with keys of a string kind directly, as
+// appendMapAsRead does for a map which is not sorted, from the one at idx in the order of the keys, as the
+// opcodes of the entries would: every value when the values are written by one opcode of a scalar
+// ( MapLayout.ScalarValue ), and a value of interface{} which holds a scalar or nothing
+// ( MapLayout.InterfaceValue ). It returns the index of the first entry it doesn't write, whose value is left to
+// its opcodes, or the number of the entries. code is the opcode of the keys, followed by the one of the values.
+//
+//go:noinline
+func appendSortedMapEntries(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, mapCtx *encoder.MapContext, idx int) ([]byte, int, error) {
+ scalarValue := mapCtx.ScalarValue()
+ for ; idx < mapCtx.Len; idx++ {
+ i := int(mapCtx.Order[idx])
+ p := mapCtx.ValueAt(i)
+ scalar := code.Next
+ if !scalarValue {
+ // as appendMapAsRead does for a value of interface{}.
+ iface := (*emptyInterface)(p)
+ if iface.typ == nil {
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ if iface.ptr == nil {
+ return b, idx, nil
+ }
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, 0, err
+ }
+ }
+ if codeSet.Scalar == nil {
+ return b, idx, nil
+ }
+ scalar = codeSet.Scalar
+ p = iface.ptr
+ }
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ bb, err := appendScalar(ctx, b, scalar, p)
+ if err != nil {
+ return nil, 0, err
+ }
+ b = bb
+ }
+ return b, idx, nil
+}
+
+// appendMapKey writes the key of an entry of a map, as OpMapKey does.
+func appendMapKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, k string) []byte {
+ b = appendMapKeyIndent(ctx, code, b)
+ b = appendString(ctx, b, k)
+ b = appendComma(ctx, b)
+ return appendColon(ctx, b)
+}
+
+// appendMapScalarValues writes the entries of the map at p, whose values are written by the opcode of a
+// scalar which follows the header, as the map is ranged over as a map of values of V: the layout of a map
+// depends only on the sizes of the key and of the value ( encoder.MapLayout ).
+func appendMapScalarValues[V any](ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ value := code.Next
+ // v is declared out of the loop: its address is given to appendScalar, so it lives on the heap, and a
+ // variable of the loop would be allocated for each entry.
+ var (
+ k string
+ v V
+ )
+ for k, v = range *(*map[string]V)(unsafe.Pointer(&p)) {
+ b = appendMapKey(ctx, code, b, k)
+ bb, err := appendScalar(ctx, b, value, unsafe.Pointer(&v))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ return b, nil
+}
+
+// mapScalarValueWriters are appendMapScalarValues by the words of a value.
+var mapScalarValueWriters = [encoder.MapScalarValueWords + 1]func(*encoder.RuntimeContext, *encoder.Opcode, []byte, unsafe.Pointer) ([]byte, error){
+ appendMapScalarValues[[0]uint64],
+ appendMapScalarValues[[1]uint64],
+ appendMapScalarValues[[2]uint64],
+ appendMapScalarValues[[3]uint64],
+}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/util.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/util.go
index 6cb745e39..942b74afb 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/util.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/util.go
@@ -3,44 +3,27 @@ package vm_indent
import (
"encoding/json"
"fmt"
+ "math"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
"github.com/goccy/go-json/internal/runtime"
)
-const uintptrSize = 4 << (^uintptr(0) >> 63)
-
var (
appendInt = encoder.AppendInt
appendUint = encoder.AppendUint
- appendFloat32 = encoder.AppendFloat32
appendFloat64 = encoder.AppendFloat64
appendString = encoder.AppendString
appendByteSlice = encoder.AppendByteSlice
appendNumber = encoder.AppendNumber
appendStructEnd = encoder.AppendStructEndIndent
appendIndent = encoder.AppendIndent
- errUnsupportedValue = encoder.ErrUnsupportedValue
errUnsupportedFloat = encoder.ErrUnsupportedFloat
- mapiterinit = encoder.MapIterInit
- mapiterkey = encoder.MapIterKey
- mapitervalue = encoder.MapIterValue
- mapiternext = encoder.MapIterNext
- maplen = encoder.MapLen
)
type emptyInterface struct {
- typ *runtime.Type
- ptr unsafe.Pointer
-}
-
-type nonEmptyInterface struct {
- itab *struct {
- ityp *runtime.Type // static interface type
- typ *runtime.Type // dynamic concrete type
- // unused fields...
- }
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
@@ -48,68 +31,75 @@ func errUnimplementedOp(op encoder.OpType) error {
return fmt.Errorf("encoder (indent): opcode %s has not been implemented", op)
}
-func load(base uintptr, idx uint32) uintptr {
- addr := base + uintptr(idx)
- return **(**uintptr)(unsafe.Pointer(&addr))
+// load / store are for the half of a slot for a pointer, and loadInt / storeInt are for the other half.
+// A pointer is stored as uintptr, which needs no write barrier: see encoder.Slot.
+
+func load(base unsafe.Pointer, idx uint32) unsafe.Pointer {
+ return *(*unsafe.Pointer)(unsafe.Add(base, idx))
}
-func store(base uintptr, idx uint32, p uintptr) {
- addr := base + uintptr(idx)
- **(**uintptr)(unsafe.Pointer(&addr)) = p
+func store(base unsafe.Pointer, idx uint32, p unsafe.Pointer) {
+ *(*uintptr)(unsafe.Add(base, idx)) = uintptr(p)
}
-func loadNPtr(base uintptr, idx uint32, ptrNum uint8) uintptr {
- addr := base + uintptr(idx)
- p := **(**uintptr)(unsafe.Pointer(&addr))
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
- }
- return p
+func loadInt(base unsafe.Pointer, idx uint32) uintptr {
+ return *(*uintptr)(unsafe.Add(base, idx))
+}
+
+func storeInt(base unsafe.Pointer, idx uint32, v uintptr) {
+ *(*uintptr)(unsafe.Add(base, idx)) = v
}
-func ptrToUint64(p uintptr, bitSize uint8) uint64 {
+func ptrToUint64(p unsafe.Pointer, bitSize uint8) uint64 {
switch bitSize {
case 8:
- return (uint64)(**(**uint8)(unsafe.Pointer(&p)))
+ return uint64(*(*uint8)(p))
case 16:
- return (uint64)(**(**uint16)(unsafe.Pointer(&p)))
+ return uint64(*(*uint16)(p))
case 32:
- return (uint64)(**(**uint32)(unsafe.Pointer(&p)))
+ return uint64(*(*uint32)(p))
case 64:
- return **(**uint64)(unsafe.Pointer(&p))
+ return *(*uint64)(p)
}
return 0
}
-func ptrToFloat32(p uintptr) float32 { return **(**float32)(unsafe.Pointer(&p)) }
-func ptrToFloat64(p uintptr) float64 { return **(**float64)(unsafe.Pointer(&p)) }
-func ptrToBool(p uintptr) bool { return **(**bool)(unsafe.Pointer(&p)) }
-func ptrToBytes(p uintptr) []byte { return **(**[]byte)(unsafe.Pointer(&p)) }
-func ptrToNumber(p uintptr) json.Number { return **(**json.Number)(unsafe.Pointer(&p)) }
-func ptrToString(p uintptr) string { return **(**string)(unsafe.Pointer(&p)) }
-func ptrToSlice(p uintptr) *runtime.SliceHeader { return *(**runtime.SliceHeader)(unsafe.Pointer(&p)) }
-func ptrToPtr(p uintptr) uintptr {
- return uintptr(**(**unsafe.Pointer)(unsafe.Pointer(&p)))
-}
-func ptrToNPtr(p uintptr, ptrNum uint8) uintptr {
- for i := uint8(0); i < ptrNum; i++ {
- if p == 0 {
- return 0
- }
- p = ptrToPtr(p)
+func ptrToFloat32(p unsafe.Pointer) float32 { return *(*float32)(p) }
+
+// isInfOrNaN is whether the float is not finite, which encoding/json refuses: the exponent is all ones.
+// math.IsInf is not inlined into Run, which is a big function to the inliner; this is.
+func isInfOrNaN(v float64) bool {
+ const exponent = 0x7ff << 52
+ return math.Float64bits(v)&exponent == exponent
+}
+
+// appendFloat32 appends the float, or returns the error for one which is not finite as encoding/json does.
+func appendFloat32(ctx *encoder.RuntimeContext, b []byte, v float32) ([]byte, error) {
+ if isInfOrNaN(float64(v)) {
+ return nil, errUnsupportedFloat(float64(v))
+ }
+ return encoder.AppendFloat32(ctx, b, v), nil
+}
+func ptrToFloat64(p unsafe.Pointer) float64 { return *(*float64)(p) }
+func ptrToBool(p unsafe.Pointer) bool { return *(*bool)(p) }
+func ptrToBytes(p unsafe.Pointer) []byte { return *(*[]byte)(p) }
+func ptrToNumber(p unsafe.Pointer) json.Number { return *(*json.Number)(p) }
+func ptrToString(p unsafe.Pointer) string { return *(*string)(p) }
+func ptrToSlice(p unsafe.Pointer) *runtime.SliceHeader { return (*runtime.SliceHeader)(p) }
+func ptrToPtr(p unsafe.Pointer) unsafe.Pointer { return *(*unsafe.Pointer)(p) }
+
+// ptrToNPtr follows the pointer ptrNum times, or up to a nil one. It is written to be inlined into Run,
+// which is a big function: only a function whose cost is 20 or less is inlined into it.
+func ptrToNPtr(p unsafe.Pointer, ptrNum uint8) unsafe.Pointer {
+ for ; ptrNum > 0 && p != nil; ptrNum-- {
+ p = *(*unsafe.Pointer)(p)
}
return p
}
-func ptrToUnsafePtr(p uintptr) unsafe.Pointer {
- return *(*unsafe.Pointer)(unsafe.Pointer(&p))
-}
-func ptrToInterface(code *encoder.Opcode, p uintptr) interface{} {
- return *(*interface{})(unsafe.Pointer(&emptyInterface{
+func ptrToInterface(code *encoder.Opcode, p unsafe.Pointer) any {
+ return *(*any)(unsafe.Pointer(&emptyInterface{
typ: code.Type,
- ptr: *(*unsafe.Pointer)(unsafe.Pointer(&p)),
+ ptr: p,
}))
}
@@ -179,12 +169,12 @@ func appendObjectEnd(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte
return append(b, '}', ',', '\n')
}
-func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalJSONIndent(ctx, code, b, v)
+func appendMarshalJSON(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalJSONIndent(ctx, code, b, p)
}
-func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, v interface{}) ([]byte, error) {
- return encoder.AppendMarshalTextIndent(ctx, code, b, v)
+func appendMarshalText(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ return encoder.AppendMarshalTextIndent(ctx, code, b, p)
}
func appendStructHead(_ *encoder.RuntimeContext, b []byte) []byte {
@@ -197,6 +187,11 @@ func appendStructKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte
return append(b, ' ')
}
+// appendLongStructKey appends a key of any length: every key is written by appendStructKey here.
+func appendLongStructKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
+ return appendStructKey(ctx, code, b)
+}
+
func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
last := len(b) - 1
if b[last-1] == '{' {
@@ -213,18 +208,52 @@ func appendStructEndSkipLast(ctx *encoder.RuntimeContext, code *encoder.Opcode,
return appendComma(ctx, b)
}
-func restoreIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, ctxptr uintptr) {
- ctx.BaseIndent = uint32(load(ctxptr, code.Length))
-}
-
-func storeIndent(ctxptr uintptr, code *encoder.Opcode, indent uintptr) {
- store(ctxptr, code.Length, indent)
-}
-
func appendArrayElemIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
return appendIndent(ctx, b, code.Indent+1)
}
+// appendMapKeyIndent indents an entry of a map, whose opcode is the one of the map or of its key: one deeper
+// than the braces of the map, which appendObjectEnd indents by the same opcode.
func appendMapKeyIndent(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte) []byte {
- return appendIndent(ctx, b, code.Indent)
+ return appendIndent(ctx, b, code.Indent+1)
+}
+
+// appendScalar appends the value at p by the opcode of a scalar, with the comma: what the VM does for the opcode.
+// It is for a scalar held by an interface value, which is encoded without a frame.
+//
+//go:noinline
+func appendScalar(ctx *encoder.RuntimeContext, b []byte, code *encoder.Opcode, p unsafe.Pointer) ([]byte, error) {
+ switch code.Op {
+ case encoder.OpInt:
+ b = appendInt(ctx, b, p, code)
+ case encoder.OpUint:
+ b = appendUint(ctx, b, p, code)
+ case encoder.OpFloat32:
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ case encoder.OpFloat64:
+ v := ptrToFloat64(p)
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ case encoder.OpString:
+ b = appendString(ctx, b, ptrToString(p))
+ case encoder.OpBool:
+ b = appendBool(ctx, b, ptrToBool(p))
+ case encoder.OpBytes:
+ b = appendByteSlice(ctx, b, ptrToBytes(p))
+ case encoder.OpNumber:
+ bb, err := appendNumber(ctx, b, ptrToNumber(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ default:
+ return nil, errUnimplementedOp(code.Op)
+ }
+ return appendComma(ctx, b), nil
}
diff --git a/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/vm.go b/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/vm.go
index 836c5c8a8..5f8bbe165 100644
--- a/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/vm.go
+++ b/vendor/github.com/goccy/go-json/internal/encoder/vm_indent/vm.go
@@ -1,19 +1,13 @@
-// Code generated by internal/cmd/generator. DO NOT EDIT!
+// Code generated by internal/cmd/generator. DO NOT EDIT.
package vm_indent
import (
- "math"
- "reflect"
- "sort"
"unsafe"
"github.com/goccy/go-json/internal/encoder"
- "github.com/goccy/go-json/internal/runtime"
)
func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]byte, error) {
- recursiveLevel := 0
- ptrOffset := uintptr(0)
ctxptr := ctx.Ptr()
var code *encoder.Opcode
if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
@@ -26,13 +20,245 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
switch code.Op {
default:
return nil, errUnimplementedOp(code.Op)
+ // The opcodes of a value of interface{} and of a map are first: the position of a case in the switch
+ // changes the layout of the code of the VM, and these were the ones to suffer from it.
+ case encoder.OpInterfacePtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpInterface:
+ p := load(ctxptr, code.Idx)
+ // An interface value which holds nothing is null: its first word, the type or the itab, is nil.
+ // It is decided here, as a call costs more than the check: the fields of interface{} of a struct
+ // are nil in many a value.
+ if p == nil || *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpInterfaceEnd:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructFieldInterface:
+ // The field of a value of interface{}: the key, and then what OpInterface does for the value. A field
+ // of interface{} is nil in many a value, and it is null then, without a call. The cases are here, with
+ // the ones of a value of interface{}, not with the other fields: there they cost the small structs 3%.
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ b = appendStructKey(ctx, code, b)
+ if *(*unsafe.Pointer)(p) == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpStructFieldOmitEmptyInterface:
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
+ if *(*unsafe.Pointer)(p) == nil {
+ code = code.NextField
+ break
+ }
+ b = appendStructKey(ctx, code, b)
+ first, base, scalar, err := ctx.EnterInterface(code, p)
+ if err != nil {
+ return nil, err
+ }
+ if first == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ if scalar {
+ bb, err := appendScalar(ctx, b, first, base)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ code = code.Next
+ break
+ }
+ code = first
+ ctxptr = base
+ case encoder.OpMapPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpMap:
+ p := load(ctxptr, code.Idx)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.End.Next
+ break
+ }
+ // The entries are read from the map into the context first ( encoder.MapLayout ), and encoded from
+ // there: in the order of the map, or sorted by their keys when they are strings. A sorted map whose
+ // keys are not strings is encoded as it comes and its entries are put in the order of their encoded
+ // keys at OpMapEnd.
+ mapCtx := encoder.NewMapContext(ctx)
+ if code.Flags&encoder.MapStringKeyFlags != 0 && (code.Map.ScalarValue || code.Map.InterfaceValue) && ctx.Option.Flag&encoder.UnorderedMapOption != 0 {
+ // the entries are written as the map is read: all of them when the values are scalars, and the
+ // ones which hold a scalar when the values are of interface{}, and the context gets the others.
+ if encoder.MapLen(p) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ }
+ bb, err := appendMapAsRead(ctx, code, appendStructHead(ctx, b), p, mapCtx)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ } else if code.Map.Collect(p, mapCtx) == 0 {
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ b = appendEmptyObject(ctx, b)
+ code = code.End.Next
+ break
+ } else {
+ b = appendStructHead(ctx, b)
+ if (ctx.Option.Flag & encoder.UnorderedMapOption) == 0 {
+ if code.Flags&encoder.MapStringKeyFlags != 0 {
+ mapCtx.SortKeys()
+ mapCtx.Sorted = true
+ mapCtx.DirectEntries = code.Map.ScalarValue || code.Map.InterfaceValue
+ } else {
+ mapCtx.SortByEncodedKeys()
+ mapCtx.First = len(b)
+ }
+ }
+ }
+ store(ctxptr, code.Idx, unsafe.Pointer(mapCtx))
+ // the first entry is begun as the others are, by the header: it has the next opcode and the flags
+ // of the key opcode.
+ mapCtx.Idx = -1
+ fallthrough
+ case encoder.OpMapKey:
+ // After an entry, or at the start with Idx -1: the next entry is begun, or the map is ended.
+ // A key of a string is written here, and the value of the entry is given to the opcode of the
+ // value: that saves the opcodes of the key and of the value for every entry. The key of another
+ // kind is given to its opcode, which OpMapValue follows.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ byEncodedKeys := mapCtx.Slice.Items != nil
+ idx := mapCtx.Idx
+ if byEncodedKeys && idx >= 0 {
+ mapCtx.Slice.Items[idx].Value = b[mapCtx.Start:]
+ }
+ idx++
+ if mapCtx.DirectEntries && idx < mapCtx.Len {
+ // the entries from here are written by one call, up to one whose value is left to its opcodes.
+ bb, next, err := appendSortedMapEntries(ctx, code, b, mapCtx, idx)
+ if err != nil {
+ return nil, err
+ }
+ b, idx = bb, next
+ }
+ if idx == mapCtx.Len {
+ if byEncodedKeys {
+ code = code.End
+ } else {
+ b = appendObjectEnd(ctx, code, b)
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.End.Next
+ }
+ break
+ }
+ mapCtx.Idx = idx
+ if byEncodedKeys {
+ mapCtx.Start = len(b)
+ } else {
+ b = appendMapKeyIndent(ctx, code, b)
+ }
+ if code.Flags&encoder.MapStringKeyFlags == 0 {
+ store(ctxptr, code.Next.Idx, mapCtx.KeyAt(idx))
+ code = code.Next
+ break
+ }
+ if mapCtx.Sorted {
+ idx = int(mapCtx.Order[idx])
+ }
+ b = appendString(ctx, b, mapCtx.Keys[idx])
+ b = appendComma(ctx, b)
+ b = appendColon(ctx, b)
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(idx))
+ code = code.Next
+ case encoder.OpMapValue:
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ if mapCtx.Slice.Items != nil {
+ mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:]
+ mapCtx.Start = len(b)
+ } else {
+ b = appendColon(ctx, b)
+ }
+ store(ctxptr, code.Next.Idx, mapCtx.ValueAt(mapCtx.Idx))
+ code = code.Next
+ case encoder.OpMapEnd:
+ // the entries of a sorted map whose keys are not strings, in the order of their encoded keys.
+ mapCtx := (*encoder.MapContext)(load(ctxptr, code.Idx))
+ mapCtx.Slice.Sort()
+ buf := mapCtx.Buf
+ for _, item := range mapCtx.Slice.Items {
+ buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
+ }
+ buf = appendMapEnd(ctx, code, buf)
+ b = b[:mapCtx.First]
+ b = append(b, buf...)
+ mapCtx.Buf = buf
+ encoder.ReleaseMapContext(ctx, mapCtx)
+ code = code.Next
case encoder.OpPtr:
p := load(ctxptr, code.Idx)
code = code.Next
store(ctxptr, code.Idx, ptrToPtr(p))
case encoder.OpIntPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -44,8 +270,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpUintPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -56,21 +282,125 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = appendComma(ctx, b)
code = code.Next
+ // The values as strings, for the keys of a map and for the string option of a field whose key is longer
+ // than a chunk: such a field is encoded by the generic field opcode and the opcode of its value.
+ case encoder.OpIntPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpIntString:
b = append(b, '"')
b = appendInt(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpUintPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
case encoder.OpUintString:
b = append(b, '"')
b = appendUint(ctx, b, load(ctxptr, code.Idx), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
+ case encoder.OpFloat32PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat32String:
+ b = append(b, '"')
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpFloat64PtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpFloat64String:
+ v := ptrToFloat64(load(ctxptr, code.Idx))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = append(b, '"')
+ b = appendFloat64(ctx, b, v)
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpBoolPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpBoolString:
+ b = append(b, '"')
+ b = appendBool(ctx, b, ptrToBool(load(ctxptr, code.Idx)))
+ b = append(b, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpStringPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpStringString:
+ b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(load(ctxptr, code.Idx)))))
+ b = appendComma(ctx, b)
+ code = code.Next
+ case encoder.OpNumberPtrString:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
+ code = code.Next
+ break
+ }
+ store(ctxptr, code.Idx, p)
+ fallthrough
+ case encoder.OpNumberString:
+ b = append(b, '"')
+ bb, err := appendNumber(ctx, b, ptrToNumber(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = append(bb, '"')
+ b = appendComma(ctx, b)
+ code = code.Next
case encoder.OpFloat32Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendComma(ctx, b)
code = code.Next
@@ -79,12 +409,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
store(ctxptr, code.Idx, p)
fallthrough
case encoder.OpFloat32:
- b = appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(load(ctxptr, code.Idx)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpFloat64Ptr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -93,15 +427,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
fallthrough
case encoder.OpFloat64:
v := ptrToFloat64(load(ctxptr, code.Idx))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStringPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -113,8 +447,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBoolPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -126,8 +460,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpBytesPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -139,8 +473,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
code = code.Next
case encoder.OpNumberPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -154,113 +488,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
b = appendComma(ctx, bb)
code = code.Next
- case encoder.OpInterfacePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpInterface:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if p == seen {
- return nil, errUnsupportedValue(code, p)
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, p)
- var (
- typ *runtime.Type
- ifacePtr unsafe.Pointer
- )
- up := ptrToUnsafePtr(p)
- if code.Flags&encoder.NonEmptyInterfaceFlags != 0 {
- iface := (*nonEmptyInterface)(up)
- ifacePtr = iface.ptr
- if iface.itab != nil {
- typ = iface.itab.typ
- }
- } else {
- iface := (*emptyInterface)(up)
- ifacePtr = iface.ptr
- typ = iface.typ
- }
- if ifacePtr == nil {
- isDirectedNil := typ != nil && typ.Kind() == reflect.Struct && !runtime.IfaceIndir(typ)
- if !isDirectedNil {
- b = appendNullComma(ctx, b)
- code = code.Next
- break
- }
- }
- ctx.KeepRefs = append(ctx.KeepRefs, up)
- ifaceCodeSet, err := encoder.CompileToGetCodeSet(ctx, uintptr(unsafe.Pointer(typ)))
- if err != nil {
- return nil, err
- }
-
- totalLength := uintptr(code.Length) + 3
- nextTotalLength := uintptr(ifaceCodeSet.CodeLength) + 3
-
- var c *encoder.Opcode
- if (ctx.Option.Flag & encoder.HTMLEscapeOption) != 0 {
- c = ifaceCodeSet.InterfaceEscapeKeyCode
- } else {
- c = ifaceCodeSet.InterfaceNoescapeKeyCode
- }
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += totalLength * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- ctx.BaseIndent += code.Indent
-
- newLen := offsetNum + totalLength + nextTotalLength
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- end := ifaceCodeSet.EndCode
- store(ctxptr, c.Idx, uintptr(ifacePtr))
- store(ctxptr, end.Idx, oldOffset)
- store(ctxptr, end.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, end, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpInterfaceEnd:
- recursiveLevel--
-
- // restore ctxptr
- offset := load(ctxptr, code.Idx)
- restoreIndent(ctx, code, ctxptr)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
case encoder.OpMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalJSON:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
@@ -268,7 +507,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -276,33 +515,38 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpMarshalTextPtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
- store(ctxptr, code.Idx, ptrToPtr(p))
+ store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
case encoder.OpMarshalText:
p := load(ctxptr, code.Idx)
- if p == 0 {
- b = append(b, `""`...)
- b = appendComma(ctx, b)
+ if p == nil {
+ if (code.Flags & encoder.MapKeyFlags) != 0 {
+ // the name of a key which is a nil pointer is "", as encoding/json names it
+ b = appendComma(ctx, append(b, `""`...))
+ } else {
+ // a nil pointer value is null, as with encoding/json and as OpMarshalJSON writes it
+ b = appendNullComma(ctx, b)
+ }
code = code.Next
break
}
if (code.Flags&encoder.IsNilableTypeFlags) != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
p = ptrToPtr(p)
}
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
b = appendComma(ctx, bb)
code = code.Next
case encoder.OpSlicePtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
@@ -312,2916 +556,123 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpSlice:
p := load(ctxptr, code.Idx)
slice := ptrToSlice(p)
- if p == 0 || slice.Data == nil {
+ if p == nil || slice.Data == nil {
b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- store(ctxptr, code.ElemIdx, 0)
- store(ctxptr, code.Length, uintptr(slice.Len))
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ storeInt(ctxptr, code.ElemIdx, 0)
+ storeInt(ctxptr, code.Length, uintptr(slice.Len))
+ store(ctxptr, code.Idx, slice.Data)
if slice.Len > 0 {
b = appendArrayHead(ctx, code, b)
code = code.Next
- store(ctxptr, code.Idx, uintptr(slice.Data))
+ store(ctxptr, code.Idx, slice.Data)
} else {
b = appendEmptyArray(ctx, b)
code = code.End.Next
}
case encoder.OpSliceElem:
- idx := load(ctxptr, code.ElemIdx)
- length := load(ctxptr, code.Length)
+ idx := loadInt(ctxptr, code.ElemIdx)
+ length := loadInt(ctxptr, code.Length)
idx++
if idx < length {
b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
+ storeInt(ctxptr, code.ElemIdx, idx)
data := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, data+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpArrayPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- if code.Length > 0 {
- b = appendArrayHead(ctx, code, b)
- store(ctxptr, code.ElemIdx, 0)
- code = code.Next
- store(ctxptr, code.Idx, p)
- } else {
- b = appendEmptyArray(ctx, b)
- code = code.End.Next
- }
- case encoder.OpArrayElem:
- idx := load(ctxptr, code.ElemIdx)
- idx++
- if idx < uintptr(code.Length) {
- b = appendArrayElemIndent(ctx, code, b)
- store(ctxptr, code.ElemIdx, idx)
- p := load(ctxptr, code.Idx)
- size := uintptr(code.Size)
- code = code.Next
- store(ctxptr, code.Idx, p+idx*size)
- } else {
- b = appendArrayEnd(ctx, code, b)
- code = code.End.Next
- }
- case encoder.OpMapPtr:
- p := loadNPtr(ctxptr, code.Idx, code.PtrNum)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, p)
- fallthrough
- case encoder.OpMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.End.Next
- break
- }
- uptr := ptrToUnsafePtr(p)
- mlen := maplen(uptr)
- if mlen <= 0 {
- b = appendEmptyObject(ctx, b)
- code = code.End.Next
- break
- }
- b = appendStructHead(ctx, b)
- unorderedMap := (ctx.Option.Flag & encoder.UnorderedMapOption) != 0
- mapCtx := encoder.NewMapContext(mlen, unorderedMap)
- mapiterinit(code.Type, uptr, &mapCtx.Iter)
- store(ctxptr, code.Idx, uintptr(unsafe.Pointer(mapCtx)))
- ctx.KeepRefs = append(ctx.KeepRefs, unsafe.Pointer(mapCtx))
- if unorderedMap {
- b = appendMapKeyIndent(ctx, code.Next, b)
- } else {
- mapCtx.Start = len(b)
- mapCtx.First = len(b)
- }
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- case encoder.OpMapKey:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- idx := mapCtx.Idx
- idx++
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- if idx < mapCtx.Len {
- b = appendMapKeyIndent(ctx, code, b)
- mapCtx.Idx = int(idx)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- b = appendObjectEnd(ctx, code, b)
- encoder.ReleaseMapContext(mapCtx)
- code = code.End.Next
- }
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Value = b[mapCtx.Start:len(b)]
- if idx < mapCtx.Len {
- mapCtx.Idx = int(idx)
- mapCtx.Start = len(b)
- key := mapiterkey(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(key))
- code = code.Next
- } else {
- code = code.End
- }
- }
- case encoder.OpMapValue:
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- if (ctx.Option.Flag & encoder.UnorderedMapOption) != 0 {
- b = appendColon(ctx, b)
- } else {
- mapCtx.Slice.Items[mapCtx.Idx].Key = b[mapCtx.Start:len(b)]
- mapCtx.Start = len(b)
- }
- value := mapitervalue(&mapCtx.Iter)
- store(ctxptr, code.Next.Idx, uintptr(value))
- mapiternext(&mapCtx.Iter)
- code = code.Next
- case encoder.OpMapEnd:
- // this operation only used by sorted map.
- mapCtx := (*encoder.MapContext)(ptrToUnsafePtr(load(ctxptr, code.Idx)))
- sort.Sort(mapCtx.Slice)
- buf := mapCtx.Buf
- for _, item := range mapCtx.Slice.Items {
- buf = appendMapKeyValue(ctx, code, buf, item.Key, item.Value)
- }
- buf = appendMapEnd(ctx, code, buf)
- b = b[:mapCtx.First]
- b = append(b, buf...)
- mapCtx.Buf = buf
- encoder.ReleaseMapContext(mapCtx)
- code = code.Next
- case encoder.OpRecursivePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- code = code.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpRecursive:
- ptr := load(ctxptr, code.Idx)
- if ptr != 0 {
- if recursiveLevel > encoder.StartDetectingCyclesAfter {
- for _, seen := range ctx.SeenPtr {
- if ptr == seen {
- return nil, errUnsupportedValue(code, ptr)
- }
- }
- }
- }
- ctx.SeenPtr = append(ctx.SeenPtr, ptr)
- c := code.Jmp.Code
- curlen := uintptr(len(ctx.Ptrs))
- offsetNum := ptrOffset / uintptrSize
- oldOffset := ptrOffset
- ptrOffset += code.Jmp.CurLen * uintptrSize
- oldBaseIndent := ctx.BaseIndent
- indentDiffFromTop := c.Indent - 1
- ctx.BaseIndent += code.Indent - indentDiffFromTop
-
- newLen := offsetNum + code.Jmp.CurLen + code.Jmp.NextLen
- if curlen < newLen {
- ctx.Ptrs = append(ctx.Ptrs, make([]uintptr, newLen-curlen)...)
- }
- ctxptr = ctx.Ptr() + ptrOffset // assign new ctxptr
-
- store(ctxptr, c.Idx, ptr)
- store(ctxptr, c.End.Next.Idx, oldOffset)
- store(ctxptr, c.End.Next.ElemIdx, uintptr(unsafe.Pointer(code.Next)))
- storeIndent(ctxptr, c.End.Next, uintptr(oldBaseIndent))
- code = c
- recursiveLevel++
- case encoder.OpRecursiveEnd:
- recursiveLevel--
-
- // restore ctxptr
- restoreIndent(ctx, code, ctxptr)
- offset := load(ctxptr, code.Idx)
- ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
-
- codePtr := load(ctxptr, code.ElemIdx)
- code = (*encoder.Opcode)(ptrToUnsafePtr(codePtr))
- ctxptr = ctx.Ptr() + offset
- ptrOffset = offset
- case encoder.OpStructPtrHead:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHead:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if len(code.Key) > 0 {
- if (code.Flags&encoder.IsTaggedKeyFlags) != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
- }
- }
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmpty:
- p := load(ctxptr, code.Idx)
- if p == 0 && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if p == 0 || (ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyInt:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyInt:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- u64 := ptrToUint64(p, code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendInt(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyIntPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendInt(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUint:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUint:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
- v := u64 & ((1 << code.NumBitSize) - 1)
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendUint(ctx, b, p, code)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p, code)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyUintPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendUint(ctx, b, p, code)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat32(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat32PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64String:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64String:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToFloat64(p + uintptr(code.Offset))
- if v == 0 {
- code = code.NextField
- } else {
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64Ptr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyFloat64PtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
- return nil, errUnsupportedFloat(v)
- }
- b = appendFloat64(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNull(ctx, b)
- b = appendComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p+uintptr(code.Offset)))))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToString(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, ptrToString(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyStringPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBool:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBool:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBool(p + uintptr(code.Offset))
- if v {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, v)
- b = append(b, '"')
- b = appendComma(ctx, b)
- code = code.Next
- } else {
- code = code.NextField
- }
- case encoder.OpStructPtrHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendBool(ctx, b, ptrToBool(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBoolPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p))
- b = append(b, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytes:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytes:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToBytes(p + uintptr(code.Offset))
- if len(v) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, v)
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyBytesPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p))
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumber:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumber:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberString:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- v := ptrToNumber(p + uintptr(code.Offset))
- if v == "" {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, v)
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = appendComma(ctx, bb)
- }
- code = code.Next
- case encoder.OpStructPtrHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyNumberPtrString:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p != 0 {
- b = appendStructKey(ctx, code, b)
- b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p))
- if err != nil {
- return nil, err
- }
- b = append(bb, '"')
- b = appendComma(ctx, b)
- }
- code = code.Next
- case encoder.OpStructPtrHeadArray, encoder.OpStructPtrHeadSlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadArray, encoder.OpStructHeadSlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyArray:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyArray:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptySlice:
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptySlice:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- slice := ptrToSlice(p)
- if slice.Len == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadArrayPtr, encoder.OpStructPtrHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadArrayPtr, encoder.OpStructHeadSlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyArrayPtr, encoder.OpStructPtrHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyArrayPtr, encoder.OpStructHeadOmitEmptySlicePtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- case encoder.OpStructPtrHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMap:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p != 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- p = ptrToPtr(p + uintptr(code.Offset))
- }
- if maplen(ptrToUnsafePtr(p)) == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- b = appendNullComma(ctx, b)
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMapPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- break
- }
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 {
- code = code.NextField
- } else {
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p, code.PtrNum)
- }
- b = appendStructKey(ctx, code, b)
- code = code.Next
- store(ctxptr, code.Idx, p)
- }
- case encoder.OpStructPtrHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSON:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalJSON {
- p = ptrToPtr(p)
- }
- }
- iface := ptrToInterface(code, p)
- if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- }
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalJSONPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
- case encoder.OpStructPtrHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
- fallthrough
- case encoder.OpStructHeadMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
- break
- }
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- b = appendNull(ctx, b)
+ size := uintptr(code.Size)
+ code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(data, idx*size))
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalText:
- p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ case encoder.OpArrayPtr:
+ p := ptrToNPtr(load(ctxptr, code.Idx), code.PtrNum)
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
- }
+ store(ctxptr, code.Idx, p)
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalText:
+ case encoder.OpArray:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
+ if p == nil {
+ b = appendNullComma(ctx, b)
code = code.End.Next
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- p += uintptr(code.Offset)
- if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
- if (code.Flags&encoder.IndirectFlags) != 0 || code.Op == encoder.OpStructPtrHeadOmitEmptyMarshalText {
- p = ptrToPtr(p)
- }
- }
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
- code = code.NextField
+ if code.Length > 0 {
+ b = appendArrayHead(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, 0)
+ code = code.Next
+ store(ctxptr, code.Idx, p)
} else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
+ b = appendEmptyArray(ctx, b)
+ code = code.End.Next
+ }
+ case encoder.OpArrayElem:
+ idx := loadInt(ctxptr, code.ElemIdx)
+ idx++
+ if idx < uintptr(code.Length) {
+ b = appendArrayElemIndent(ctx, code, b)
+ storeInt(ctxptr, code.ElemIdx, idx)
+ p := load(ctxptr, code.Idx)
+ size := uintptr(code.Size)
code = code.Next
+ store(ctxptr, code.Idx, unsafe.Add(p, idx*size))
+ } else {
+ b = appendArrayEnd(ctx, code, b)
+ code = code.End.Next
}
- case encoder.OpStructPtrHeadMarshalTextPtr:
+ case encoder.OpRecursivePtr:
p := load(ctxptr, code.Idx)
- if p == 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
- }
- code = code.End.Next
+ if p == nil {
+ code = code.Next
break
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadMarshalTextPtr:
- p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendNullComma(ctx, b)
+ case encoder.OpRecursive:
+ if code.Flags&encoder.TailRecursiveFlags != 0 {
+ // a value of a list, the last field of a value of the same type: encoded in this frame, with
+ // the braces of the value it is the field of closed at OpRecursiveEnd.
+ p := load(ctxptr, code.Idx)
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ if err := ctx.RecordSeen(code, p); err != nil {
+ return nil, err
+ }
}
- code = code.End.Next
+ first := code.Jmp.Code
+ store(ctxptr, first.Idx, p)
+ // the end of the struct is next, then OpRecursiveEnd, which has what the indent is deeper by.
+ ctx.BaseIndent += code.Next.Next.Indent
+ ctx.TailLevels++
+ ctx.RecursiveLevel++
+ code = first
break
}
- if code.Flags&encoder.AnonymousHeadFlags == 0 {
- b = appendStructHead(ctx, b)
- }
- b = appendStructKey(ctx, code, b)
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ first, base, err := ctx.EnterRecursive(code, load(ctxptr, code.Idx))
+ if err != nil {
+ return nil, err
}
- if p == 0 {
- b = appendNull(ctx, b)
- } else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
+ code = first
+ ctxptr = base
+ case encoder.OpRecursiveEnd:
+ // the braces of the values of a list this value was the last field of, from the innermost.
+ for ; ctx.TailLevels > 0; ctx.TailLevels-- {
+ ctx.RecursiveLevel--
+ if ctx.RecursiveLevel > encoder.StartDetectingCyclesAfter {
+ ctx.SeenPtr = ctx.SeenPtr[:len(ctx.SeenPtr)-1]
}
- b = bb
+ ctx.BaseIndent -= code.Indent
+ b = appendStructEndSkipLast(ctx, code.Next, b)
}
- b = appendComma(ctx, b)
- code = code.Next
- case encoder.OpStructPtrHeadOmitEmptyMarshalTextPtr:
+ code, ctxptr = ctx.LeaveFrame(code)
+ case encoder.OpStructPtrHead:
p := load(ctxptr, code.Idx)
- if p == 0 {
+ if p == nil {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
@@ -3230,63 +681,74 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
}
store(ctxptr, code.Idx, ptrToNPtr(p, code.PtrNum))
fallthrough
- case encoder.OpStructHeadOmitEmptyMarshalTextPtr:
+ case encoder.OpStructHead:
p := load(ctxptr, code.Idx)
- if p == 0 && (code.Flags&encoder.IndirectFlags) != 0 {
+ if p == nil && ((code.Flags&encoder.IndirectFlags) != 0 || code.Next.Op == encoder.OpStructEnd) {
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendNullComma(ctx, b)
}
code = code.End.Next
break
}
- if (code.Flags & encoder.IndirectFlags) != 0 {
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- }
if code.Flags&encoder.AnonymousHeadFlags == 0 {
b = appendStructHead(ctx, b)
}
- if p == 0 {
- code = code.NextField
- } else {
- b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
- if err != nil {
- return nil, err
- }
- b = bb
- b = appendComma(ctx, b)
- code = code.Next
- }
+ code = code.Next
case encoder.OpStructField:
+ // the generic field: the value is encoded by its own opcode, and the key may be longer than a chunk.
if code.Flags&encoder.IsTaggedKeyFlags != 0 || code.Flags&encoder.AnonymousKeyFlags == 0 {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
}
- p := load(ctxptr, code.Idx) + uintptr(code.Offset)
+ p := unsafe.Add(load(ctxptr, code.Idx), code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmpty:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if encoder.IsEmptyField(code.EmptyKind, code.NumBitSize, p) || (code.ZeroKind != encoder.ZeroNever && encoder.IsZeroField(code, p)) {
code = code.NextField
} else {
- b = appendStructKey(ctx, code, b)
+ if len(code.Key) <= encoder.KeyChunkSize {
+ b = appendStructKey(ctx, code, b)
+ } else {
+ b = appendLongStructKey(ctx, code, b)
+ }
code = code.Next
store(ctxptr, code.Idx, p)
}
+ case encoder.OpStructFieldInt3:
+ // Three fields of the kind in a row, then two: the fields after the first are encoded without
+ // a dispatch, by falling through to the case of the field. The same for the other kinds below.
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldInt2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3294,27 +756,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -3323,8 +785,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3332,9 +794,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3345,8 +807,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -3354,19 +816,33 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldUint3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldUint2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendComma(ctx, b)
}
code = code.Next
@@ -3374,27 +850,27 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -3403,8 +879,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendComma(ctx, b)
@@ -3412,9 +888,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3425,8 +901,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -3437,15 +913,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
@@ -3453,70 +937,116 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendComma(ctx, b)
}
code = code.Next
case encoder.OpStructFieldFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldFloat643:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldFloat642:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
+ return nil, errUnsupportedFloat(v)
+ }
+ b = appendFloat64(ctx, b, v)
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldFloat64:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3524,9 +1054,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3536,8 +1066,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3548,9 +1078,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -3562,15 +1092,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNullComma(ctx, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3578,11 +1108,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3591,13 +1121,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -3608,12 +1138,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -3621,15 +1151,29 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldString3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldString2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -3638,14 +1182,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringString:
p := load(ctxptr, code.Idx)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -3654,9 +1198,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -3665,8 +1209,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendComma(ctx, b)
@@ -3674,9 +1218,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -3685,22 +1229,36 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendComma(ctx, b)
}
code = code.Next
+ case encoder.OpStructFieldBool3:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
+ case encoder.OpStructFieldBool2:
+ p := load(ctxptr, code.Idx)
+ b = appendStructKey(ctx, code, b)
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
+ b = appendComma(ctx, b)
+ code = code.Next
+ fallthrough
case encoder.OpStructFieldBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -3711,13 +1269,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3728,9 +1286,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -3739,8 +1297,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendComma(ctx, b)
@@ -3748,9 +1306,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3761,8 +1319,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -3773,12 +1331,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendComma(ctx, b)
code = code.Next
case encoder.OpStructFieldOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -3787,9 +1345,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -3798,8 +1356,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendComma(ctx, b)
@@ -3808,7 +1366,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3816,7 +1374,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -3830,7 +1388,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -3839,7 +1397,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -3853,9 +1411,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3868,8 +1426,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -3880,9 +1438,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
b = appendStructKey(ctx, code, b)
- if p == 0 {
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -3896,8 +1454,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -3911,14 +1469,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSON:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3928,11 +1486,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSON:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
code = code.NextField
break
}
@@ -3942,7 +1500,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, iface)
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3951,11 +1509,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalJSONPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3965,10 +1523,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalJSONPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalJSON(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalJSON(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3978,14 +1536,14 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalText:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -3995,16 +1553,21 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalText:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
if (code.Flags & encoder.IsNilableTypeFlags) != 0 {
p = ptrToPtr(p)
}
- if p == 0 && (code.Flags&encoder.NilCheckFlags) != 0 {
+ if p == nil && (code.Flags&encoder.NilCheckFlags) != 0 {
+ code = code.NextField
+ break
+ }
+ iface := ptrToInterface(code, p)
+ if (code.Flags&encoder.NilCheckFlags) != 0 && encoder.IsNilForMarshaler(iface) {
code = code.NextField
break
}
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4013,11 +1576,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMarshalTextPtr:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4027,10 +1590,10 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructFieldOmitEmptyMarshalTextPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- bb, err := appendMarshalText(ctx, code, b, ptrToInterface(code, p))
+ bb, err := appendMarshalText(ctx, code, b, p)
if err != nil {
return nil, err
}
@@ -4040,25 +1603,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArray:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldArrayPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyArrayPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4068,12 +1631,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlice:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlice:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
slice := ptrToSlice(p)
if slice.Len == 0 {
code = code.NextField
@@ -4085,13 +1648,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldSlicePtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptySlicePtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4101,13 +1664,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMap:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMap:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p == 0 || maplen(ptrToUnsafePtr(p)) == 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p == nil || encoder.MapLen(p) == 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4117,19 +1680,19 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldMapPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyMapPtr:
p := load(ctxptr, code.Idx)
- p = ptrToPtr(p + uintptr(code.Offset))
- if p != 0 {
+ p = ptrToPtr(unsafe.Add(p, code.Offset))
+ if p != nil {
p = ptrToNPtr(p, code.PtrNum)
}
- if p != 0 {
+ if p != nil {
b = appendStructKey(ctx, code, b)
code = code.Next
store(ctxptr, code.Idx, p)
@@ -4139,13 +1702,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructFieldStruct:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
+ p = unsafe.Add(p, code.Offset)
code = code.Next
store(ctxptr, code.Idx, p)
case encoder.OpStructFieldOmitEmptyStruct:
p := load(ctxptr, code.Idx)
- p += uintptr(code.Offset)
- if ptrToPtr(p) == 0 && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
+ p = unsafe.Add(p, code.Offset)
+ if ptrToPtr(p) == nil && (code.Flags&encoder.IsNextOpPtrTypeFlags) != 0 {
code = code.NextField
} else {
b = appendStructKey(ctx, code, b)
@@ -4158,16 +1721,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndInt:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyInt:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4177,18 +1740,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyIntString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendInt(ctx, b, p+uintptr(code.Offset), code)
+ b = appendInt(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4198,8 +1761,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendInt(ctx, b, p, code)
@@ -4208,8 +1771,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendInt(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4220,8 +1783,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndIntPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4232,8 +1795,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyIntPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendInt(ctx, b, p, code)
@@ -4246,16 +1809,16 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUint:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUint:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4265,18 +1828,18 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyUintString:
p := load(ctxptr, code.Idx)
- u64 := ptrToUint64(p+uintptr(code.Offset), code.NumBitSize)
+ u64 := ptrToUint64(unsafe.Add(p, code.Offset), code.NumBitSize)
v := u64 & ((1 << code.NumBitSize) - 1)
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendUint(ctx, b, p+uintptr(code.Offset), code)
+ b = appendUint(ctx, b, unsafe.Add(p, code.Offset), code)
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4286,8 +1849,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendUint(ctx, b, p, code)
@@ -4296,8 +1859,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendUint(ctx, b, p, code)
b = appendStructEnd(ctx, code, b)
@@ -4308,8 +1871,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndUintPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4320,8 +1883,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyUintPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendUint(ctx, b, p, code)
@@ -4334,15 +1897,23 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4352,17 +1923,25 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p+uintptr(code.Offset)))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(unsafe.Add(p, code.Offset)))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat32(p + uintptr(code.Offset))
+ v := ptrToFloat32(unsafe.Add(p, code.Offset))
if v != 0 {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, v)
+ bb, err := appendFloat32(ctx, b, v)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4372,20 +1951,28 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = appendStructEnd(ctx, code, b)
} else {
b = appendStructEndSkipLast(ctx, code, b)
@@ -4394,23 +1981,31 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat32PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
}
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyFloat32PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendFloat32(ctx, b, ptrToFloat32(p))
+ bb, err := appendFloat32(ctx, b, ptrToFloat32(p))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
} else {
@@ -4419,8 +2014,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4429,9 +2024,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4443,8 +2038,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4455,9 +2050,9 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64String:
p := load(ctxptr, code.Idx)
- v := ptrToFloat64(p + uintptr(code.Offset))
+ v := ptrToFloat64(unsafe.Add(p, code.Offset))
if v != 0 {
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendStructKey(ctx, code, b)
@@ -4472,15 +2067,15 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64Ptr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
b = appendStructEnd(ctx, code, b)
code = code.Next
break
}
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4488,11 +2083,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64Ptr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4504,13 +2099,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndFloat64PtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = appendFloat64(ctx, b, v)
@@ -4520,11 +2115,11 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyFloat64PtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
v := ptrToFloat64(p)
- if math.IsInf(v, 0) || math.IsNaN(v) {
+ if isInfOrNaN(v) {
return nil, errUnsupportedFloat(v)
}
b = append(b, '"')
@@ -4538,12 +2133,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendString(ctx, b, ptrToString(p+uintptr(code.Offset)))
+ b = appendString(ctx, b, ptrToString(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, v)
@@ -4555,13 +2150,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringString:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- s := ptrToString(p + uintptr(code.Offset))
+ s := ptrToString(unsafe.Add(p, code.Offset))
b = appendString(ctx, b, string(appendString(ctx, []byte{}, s)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyStringString:
p := load(ctxptr, code.Idx)
- v := ptrToString(p + uintptr(code.Offset))
+ v := ptrToString(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, v)))
@@ -4573,8 +2168,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, ptrToString(p))
@@ -4583,8 +2178,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, ptrToString(p))
b = appendStructEnd(ctx, code, b)
@@ -4595,8 +2190,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndStringPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
@@ -4605,8 +2200,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyStringPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendString(ctx, b, string(appendString(ctx, []byte{}, ptrToString(p))))
b = appendStructEnd(ctx, code, b)
@@ -4617,12 +2212,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBool:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBool:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, v)
@@ -4635,13 +2230,13 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- b = appendBool(ctx, b, ptrToBool(p+uintptr(code.Offset)))
+ b = appendBool(ctx, b, ptrToBool(unsafe.Add(p, code.Offset)))
b = append(b, '"')
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBoolString:
p := load(ctxptr, code.Idx)
- v := ptrToBool(p + uintptr(code.Offset))
+ v := ptrToBool(unsafe.Add(p, code.Offset))
if v {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4655,8 +2250,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendBool(ctx, b, ptrToBool(p))
@@ -4665,8 +2260,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendBool(ctx, b, ptrToBool(p))
b = appendStructEnd(ctx, code, b)
@@ -4677,8 +2272,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBoolPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4689,8 +2284,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBoolPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
b = appendBool(ctx, b, ptrToBool(p))
@@ -4703,12 +2298,12 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytes:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- b = appendByteSlice(ctx, b, ptrToBytes(p+uintptr(code.Offset)))
+ b = appendByteSlice(ctx, b, ptrToBytes(unsafe.Add(p, code.Offset)))
b = appendStructEnd(ctx, code, b)
code = code.Next
case encoder.OpStructEndOmitEmptyBytes:
p := load(ctxptr, code.Idx)
- v := ptrToBytes(p + uintptr(code.Offset))
+ v := ptrToBytes(unsafe.Add(p, code.Offset))
if len(v) > 0 {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, v)
@@ -4720,8 +2315,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndBytesPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = appendByteSlice(ctx, b, ptrToBytes(p))
@@ -4730,8 +2325,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyBytesPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = appendByteSlice(ctx, b, ptrToBytes(p))
b = appendStructEnd(ctx, code, b)
@@ -4742,7 +2337,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumber:
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4750,7 +2345,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumber:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, v)
@@ -4766,7 +2361,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
p := load(ctxptr, code.Idx)
b = appendStructKey(ctx, code, b)
b = append(b, '"')
- bb, err := appendNumber(ctx, b, ptrToNumber(p+uintptr(code.Offset)))
+ bb, err := appendNumber(ctx, b, ptrToNumber(unsafe.Add(p, code.Offset)))
if err != nil {
return nil, err
}
@@ -4775,7 +2370,7 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberString:
p := load(ctxptr, code.Idx)
- v := ptrToNumber(p + uintptr(code.Offset))
+ v := ptrToNumber(unsafe.Add(p, code.Offset))
if v != "" {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
@@ -4792,8 +2387,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtr:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4806,8 +2401,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtr:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
bb, err := appendNumber(ctx, b, ptrToNumber(p))
if err != nil {
@@ -4821,8 +2416,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
case encoder.OpStructEndNumberPtrString:
b = appendStructKey(ctx, code, b)
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p == 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p == nil {
b = appendNull(ctx, b)
} else {
b = append(b, '"')
@@ -4836,8 +2431,8 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
code = code.Next
case encoder.OpStructEndOmitEmptyNumberPtrString:
p := load(ctxptr, code.Idx)
- p = ptrToNPtr(p+uintptr(code.Offset), code.PtrNum)
- if p != 0 {
+ p = ptrToNPtr(unsafe.Add(p, code.Offset), code.PtrNum)
+ if p != nil {
b = appendStructKey(ctx, code, b)
b = append(b, '"')
bb, err := appendNumber(ctx, b, ptrToNumber(p))
@@ -4857,3 +2452,142 @@ func Run(ctx *encoder.RuntimeContext, b []byte, codeSet *encoder.OpcodeSet) ([]b
END:
return b, nil
}
+
+// appendMapAsRead writes the entries of the map at p, whose keys are of a string kind, as the map is read: the
+// map is not sorted, so the order of its entries is not specified, and an entry written here costs neither a
+// copy to the context nor the opcodes of an entry. When the values are written by one opcode of a scalar,
+// every entry is written. When the values are of interface{}, the ones which hold a scalar or nothing are
+// written, and the others are given to the context, to be encoded by the opcodes of their values from
+// OpMapKey on: they come after the scalars, which are most of the entries of a JSON object held by a value of
+// interface{}.
+//
+//go:noinline
+func appendMapAsRead(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer, mapCtx *encoder.MapContext) ([]byte, error) {
+ code.Map.Reset(mapCtx)
+ if code.Map.ScalarValue {
+ mapCtx.Len = 0
+ return mapScalarValueWriters[code.Map.ValueWords](ctx, code, b, p)
+ }
+ for k, v := range *(*map[string]any)(unsafe.Pointer(&p)) {
+ iface := (*emptyInterface)(unsafe.Pointer(&v))
+ var scalar *encoder.Opcode
+ // A value of interface{} which holds nothing is null. What holds a value whose data word is nil, such
+ // as a nil pointer, is left to OpInterface, which knows what is null and what is not.
+ if iface.typ != nil && iface.ptr != nil {
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, err
+ }
+ }
+ scalar = codeSet.Scalar
+ }
+ if iface.typ != nil && scalar == nil {
+ mapCtx.Keys = append(mapCtx.Keys, k)
+ mapCtx.Values = append(mapCtx.Values, unsafe.Slice((*byte)(unsafe.Pointer(&v)), unsafe.Sizeof(v))...)
+ continue
+ }
+ b = appendMapKey(ctx, code, b, k)
+ if scalar == nil {
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ // the data word of the interface value is the address of the scalar, or the pointer to it.
+ bb, err := appendScalar(ctx, b, scalar, iface.ptr)
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ mapCtx.Len = len(mapCtx.Keys)
+ return b, nil
+}
+
+// appendSortedMapEntries writes the entries of a sorted map with keys of a string kind directly, as
+// appendMapAsRead does for a map which is not sorted, from the one at idx in the order of the keys, as the
+// opcodes of the entries would: every value when the values are written by one opcode of a scalar
+// ( MapLayout.ScalarValue ), and a value of interface{} which holds a scalar or nothing
+// ( MapLayout.InterfaceValue ). It returns the index of the first entry it doesn't write, whose value is left to
+// its opcodes, or the number of the entries. code is the opcode of the keys, followed by the one of the values.
+//
+//go:noinline
+func appendSortedMapEntries(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, mapCtx *encoder.MapContext, idx int) ([]byte, int, error) {
+ scalarValue := mapCtx.ScalarValue()
+ for ; idx < mapCtx.Len; idx++ {
+ i := int(mapCtx.Order[idx])
+ p := mapCtx.ValueAt(i)
+ scalar := code.Next
+ if !scalarValue {
+ // as appendMapAsRead does for a value of interface{}.
+ iface := (*emptyInterface)(p)
+ if iface.typ == nil {
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ b = appendNullComma(ctx, b)
+ continue
+ }
+ if iface.ptr == nil {
+ return b, idx, nil
+ }
+ codeSet := ctx.RecentCodeSet(uintptr(iface.typ))
+ if codeSet == nil {
+ var err error
+ codeSet, err = encoder.CompileToGetCodeSet(ctx, uintptr(iface.typ))
+ if err != nil {
+ return nil, 0, err
+ }
+ }
+ if codeSet.Scalar == nil {
+ return b, idx, nil
+ }
+ scalar = codeSet.Scalar
+ p = iface.ptr
+ }
+ b = appendMapKey(ctx, code, b, mapCtx.Keys[i])
+ bb, err := appendScalar(ctx, b, scalar, p)
+ if err != nil {
+ return nil, 0, err
+ }
+ b = bb
+ }
+ return b, idx, nil
+}
+
+// appendMapKey writes the key of an entry of a map, as OpMapKey does.
+func appendMapKey(ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, k string) []byte {
+ b = appendMapKeyIndent(ctx, code, b)
+ b = appendString(ctx, b, k)
+ b = appendComma(ctx, b)
+ return appendColon(ctx, b)
+}
+
+// appendMapScalarValues writes the entries of the map at p, whose values are written by the opcode of a
+// scalar which follows the header, as the map is ranged over as a map of values of V: the layout of a map
+// depends only on the sizes of the key and of the value ( encoder.MapLayout ).
+func appendMapScalarValues[V any](ctx *encoder.RuntimeContext, code *encoder.Opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
+ value := code.Next
+ // v is declared out of the loop: its address is given to appendScalar, so it lives on the heap, and a
+ // variable of the loop would be allocated for each entry.
+ var (
+ k string
+ v V
+ )
+ for k, v = range *(*map[string]V)(unsafe.Pointer(&p)) {
+ b = appendMapKey(ctx, code, b, k)
+ bb, err := appendScalar(ctx, b, value, unsafe.Pointer(&v))
+ if err != nil {
+ return nil, err
+ }
+ b = bb
+ }
+ return b, nil
+}
+
+// mapScalarValueWriters are appendMapScalarValues by the words of a value.
+var mapScalarValueWriters = [encoder.MapScalarValueWords + 1]func(*encoder.RuntimeContext, *encoder.Opcode, []byte, unsafe.Pointer) ([]byte, error){
+ appendMapScalarValues[[0]uint64],
+ appendMapScalarValues[[1]uint64],
+ appendMapScalarValues[[2]uint64],
+ appendMapScalarValues[[3]uint64],
+}
diff --git a/vendor/github.com/goccy/go-json/internal/errors/error.go b/vendor/github.com/goccy/go-json/internal/errors/error.go
index 9207d0ff2..875e92450 100644
--- a/vendor/github.com/goccy/go-json/internal/errors/error.go
+++ b/vendor/github.com/goccy/go-json/internal/errors/error.go
@@ -51,6 +51,12 @@ func (e *MarshalerError) Unwrap() error { return e.Err }
type SyntaxError struct {
msg string // description of error
Offset int64 // error occurred after reading Offset bytes
+ // atEnd is whether the error is the end of the input, where more of it would have been read: a stream
+ // reports it as io.ErrUnexpectedEOF.
+ atEnd bool
+ // valueAt is the position of the byte of the error, which is not the start of a value where one is waited
+ // for, plus one, or 0 for any other error ( see ValueStartAt ).
+ valueAt int64
}
func (e *SyntaxError) Error() string { return e.msg }
@@ -77,17 +83,18 @@ type UnmarshalTypeError struct {
Value string // description of JSON value - "bool", "array", "number -5"
Type reflect.Type // type of Go value it could not be assigned to
Offset int64 // error occurred after reading Offset bytes
- Struct string // name of the struct type containing the field
+ Struct string // name of the struct type containing the field, or of the root type ( see Error )
Field string // the full path from root node to the field
+ Err error // the cause of the error, which encoding/json of Go 1.27 reports, or nil
}
+// Error returns the message of encoding/json of the Go version ( see typeErrorMessage ).
func (e *UnmarshalTypeError) Error() string {
- if e.Struct != "" || e.Field != "" {
- return fmt.Sprintf("json: cannot unmarshal %s into Go struct field %s.%s of type %s",
- e.Value, e.Struct, e.Field, e.Type,
- )
- }
- return fmt.Sprintf("json: cannot unmarshal %s into Go value of type %s", e.Value, e.Type)
+ return typeErrorMessage(e)
+}
+
+func (e *UnmarshalTypeError) Unwrap() error {
+ return e.Err
}
// An UnsupportedTypeError is returned by Marshal when attempting
@@ -113,6 +120,34 @@ func ErrSyntax(msg string, offset int64) *SyntaxError {
return &SyntaxError{msg: msg, Offset: offset}
}
+// ErrSyntaxAtEnd is ErrSyntax for the end of the input, where more of it would have been read.
+func ErrSyntaxAtEnd(msg string, offset int64) *SyntaxError {
+ return &SyntaxError{msg: msg, Offset: offset, atEnd: true}
+}
+
+// WithValueStartAt marks e as the error of the byte at cursor, which is not the start of a value where one is
+// waited for, and returns it.
+func WithValueStartAt(e *SyntaxError, cursor int64) *SyntaxError {
+ e.valueAt = cursor + 1
+ return e
+}
+
+// ValueStartAt returns the position of the byte of err, if it is the syntax error of a byte which is not the start
+// of a value where one is waited for ( see WithValueStartAt ).
+func ValueStartAt(err error) (int64, bool) {
+ e, ok := err.(*SyntaxError)
+ if !ok || e.valueAt == 0 {
+ return 0, false
+ }
+ return e.valueAt - 1, true
+}
+
+// IsAtEnd reports whether err is a syntax error of the end of the input ( see ErrSyntaxAtEnd ).
+func IsAtEnd(err error) bool {
+ e, ok := err.(*SyntaxError)
+ return ok && e.atEnd
+}
+
func ErrMarshaler(typ reflect.Type, err error, msg string) *MarshalerError {
return &MarshalerError{
Type: typ,
@@ -171,7 +206,7 @@ func (e *PathError) Error() string {
return fmt.Sprintf("json: invalid path format: %s", e.msg)
}
-func ErrInvalidPath(msg string, args ...interface{}) *PathError {
+func ErrInvalidPath(msg string, args ...any) *PathError {
if len(args) != 0 {
return &PathError{msg: fmt.Sprintf(msg, args...)}
}
diff --git a/vendor/github.com/goccy/go-json/internal/errors/type_error.go b/vendor/github.com/goccy/go-json/internal/errors/type_error.go
new file mode 100644
index 000000000..a91d791d2
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/errors/type_error.go
@@ -0,0 +1,26 @@
+//go:build go1.27 && goexperiment.jsonv2
+
+package errors
+
+import "strings"
+
+// typeErrorMessage is the message of encoding/json of Go 1.27, which is made of encoding/json/v2: Struct is the
+// root type, and Field the path from it to the value, whose array elements are their indices. A path which ends
+// with an index is not called a struct field, and the cause of the error, Err, follows the message.
+func typeErrorMessage(e *UnmarshalTypeError) string {
+ var s string
+ if e.Struct != "" || e.Field != "" {
+ intoWhat := "Go struct field "
+ last := e.Field[strings.LastIndexByte(e.Field, '.')+1:]
+ if last != "" && strings.TrimRight(last, "0123456789") == "" {
+ intoWhat = ""
+ }
+ s = "json: cannot unmarshal " + e.Value + " into " + intoWhat + e.Struct + "." + e.Field + " of type " + e.Type.String()
+ } else {
+ s = "json: cannot unmarshal " + e.Value + " into Go value of type " + e.Type.String()
+ }
+ if e.Err != nil {
+ s += ": " + e.Err.Error()
+ }
+ return s
+}
diff --git a/vendor/github.com/goccy/go-json/internal/errors/type_error_legacy.go b/vendor/github.com/goccy/go-json/internal/errors/type_error_legacy.go
new file mode 100644
index 000000000..4a30e229d
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/errors/type_error_legacy.go
@@ -0,0 +1,14 @@
+//go:build !go1.27 || !goexperiment.jsonv2
+
+package errors
+
+import "fmt"
+
+// typeErrorMessage is the message of encoding/json before Go 1.27, and with GOEXPERIMENT=nojsonv2: Struct is the
+// struct type which contains the field, and Field the names of the fields from the root to it.
+func typeErrorMessage(e *UnmarshalTypeError) string {
+ if e.Struct != "" || e.Field != "" {
+ return fmt.Sprintf("json: cannot unmarshal %s into Go struct field %s.%s of type %s", e.Value, e.Struct, e.Field, e.Type)
+ }
+ return fmt.Sprintf("json: cannot unmarshal %s into Go value of type %s", e.Value, e.Type)
+}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.go b/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.go
new file mode 100644
index 000000000..04c3dc888
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.go
@@ -0,0 +1,26 @@
+package runtime
+
+func cpuid(eaxArg, ecxArg uint32) (eax, ebx, ecx, edx uint32)
+func xgetbv() (eax, edx uint32)
+
+// HasAVX2 is whether the CPU and the OS support AVX2.
+var HasAVX2 = detectAVX2()
+
+func detectAVX2() bool {
+ maxID, _, _, _ := cpuid(0, 0)
+ if maxID < 7 {
+ return false
+ }
+ _, _, ecx1, _ := cpuid(1, 0)
+ const osxsave, avx = 1 << 27, 1 << 28
+ if ecx1&osxsave == 0 || ecx1&avx == 0 {
+ return false
+ }
+ // the OS saves the YMM registers.
+ if eax, _ := xgetbv(); eax&6 != 6 {
+ return false
+ }
+ _, ebx7, _, _ := cpuid(7, 0)
+ const avx2 = 1 << 5
+ return ebx7&avx2 != 0
+}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.s b/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.s
new file mode 100644
index 000000000..1da73f901
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/cpu_amd64.s
@@ -0,0 +1,20 @@
+#include "textflag.h"
+
+// func cpuid(eaxArg, ecxArg uint32) (eax, ebx, ecx, edx uint32)
+TEXT ·cpuid(SB), NOSPLIT, $0-24
+ MOVL eaxArg+0(FP), AX
+ MOVL ecxArg+4(FP), CX
+ CPUID
+ MOVL AX, eax+8(FP)
+ MOVL BX, ebx+12(FP)
+ MOVL CX, ecx+16(FP)
+ MOVL DX, edx+20(FP)
+ RET
+
+// func xgetbv() (eax, edx uint32)
+TEXT ·xgetbv(SB), NOSPLIT, $0-8
+ MOVL $0, CX
+ XGETBV
+ MOVL AX, eax+0(FP)
+ MOVL DX, edx+4(FP)
+ RET
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/cpu_other.go b/vendor/github.com/goccy/go-json/internal/runtime/cpu_other.go
new file mode 100644
index 000000000..6af818ca7
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/cpu_other.go
@@ -0,0 +1,6 @@
+//go:build !amd64
+
+package runtime
+
+// HasAVX2 is whether the CPU and the OS support AVX2: never, on this architecture.
+const HasAVX2 = false
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/method.go b/vendor/github.com/goccy/go-json/internal/runtime/method.go
new file mode 100644
index 000000000..5740e8db3
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/method.go
@@ -0,0 +1,32 @@
+package runtime
+
+import "reflect"
+
+// MethodLookup looks the method of one name up in a type, by reflect.Type.MethodByName with the name as a constant.
+//
+// The compiler tells the linker which names the calls of Method and MethodByName of reflect look up when it sees
+// them as constants, and the linker keeps the methods of those names only. A call with any other argument makes
+// the linker keep every exported method of every type of the program ( cmd/compile/internal/walk.usemethod ), so
+// the methods are looked up by these functions, each with its name in its code, and never by a name in a
+// variable.
+type MethodLookup func(reflect.Type) (reflect.Method, bool)
+
+// MarshalJSONMethod looks MarshalJSON up.
+func MarshalJSONMethod(typ reflect.Type) (reflect.Method, bool) {
+ return typ.MethodByName("MarshalJSON")
+}
+
+// MarshalTextMethod looks MarshalText up.
+func MarshalTextMethod(typ reflect.Type) (reflect.Method, bool) {
+ return typ.MethodByName("MarshalText")
+}
+
+// AppendTextMethod looks AppendText up.
+func AppendTextMethod(typ reflect.Type) (reflect.Method, bool) {
+ return typ.MethodByName("AppendText")
+}
+
+// UnmarshalJSONMethod looks UnmarshalJSON up.
+func UnmarshalJSONMethod(typ reflect.Type) (reflect.Method, bool) {
+ return typ.MethodByName("UnmarshalJSON")
+}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/omit_zero.go b/vendor/github.com/goccy/go-json/internal/runtime/omit_zero.go
new file mode 100644
index 000000000..5458b0762
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/omit_zero.go
@@ -0,0 +1,6 @@
+//go:build go1.24
+
+package runtime
+
+// omitZeroOption is whether the omitzero option of a field is honored: encoding/json has it from Go 1.24.
+const omitZeroOption = true
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/omit_zero_legacy.go b/vendor/github.com/goccy/go-json/internal/runtime/omit_zero_legacy.go
new file mode 100644
index 000000000..f866ac0c0
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/omit_zero_legacy.go
@@ -0,0 +1,7 @@
+//go:build !go1.24
+
+package runtime
+
+// omitZeroOption is whether the omitzero option of a field is honored: encoding/json of a Go older than 1.24
+// ignores it.
+const omitZeroOption = false
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/rtype.go b/vendor/github.com/goccy/go-json/internal/runtime/rtype.go
index 37cfe35a1..6d7f65635 100644
--- a/vendor/github.com/goccy/go-json/internal/runtime/rtype.go
+++ b/vendor/github.com/goccy/go-json/internal/runtime/rtype.go
@@ -5,258 +5,39 @@ import (
"unsafe"
)
-// Type representing reflect.rtype for noescape trick
-type Type struct{}
-
-//go:linkname rtype_Align reflect.(*rtype).Align
-//go:noescape
-func rtype_Align(*Type) int
-
-func (t *Type) Align() int {
- return rtype_Align(t)
-}
-
-//go:linkname rtype_FieldAlign reflect.(*rtype).FieldAlign
-//go:noescape
-func rtype_FieldAlign(*Type) int
-
-func (t *Type) FieldAlign() int {
- return rtype_FieldAlign(t)
-}
-
-//go:linkname rtype_Method reflect.(*rtype).Method
-//go:noescape
-func rtype_Method(*Type, int) reflect.Method
-
-func (t *Type) Method(a0 int) reflect.Method {
- return rtype_Method(t, a0)
-}
-
-//go:linkname rtype_MethodByName reflect.(*rtype).MethodByName
-//go:noescape
-func rtype_MethodByName(*Type, string) (reflect.Method, bool)
-
-func (t *Type) MethodByName(a0 string) (reflect.Method, bool) {
- return rtype_MethodByName(t, a0)
-}
-
-//go:linkname rtype_NumMethod reflect.(*rtype).NumMethod
-//go:noescape
-func rtype_NumMethod(*Type) int
-
-func (t *Type) NumMethod() int {
- return rtype_NumMethod(t)
-}
-
-//go:linkname rtype_Name reflect.(*rtype).Name
-//go:noescape
-func rtype_Name(*Type) string
-
-func (t *Type) Name() string {
- return rtype_Name(t)
-}
-
-//go:linkname rtype_PkgPath reflect.(*rtype).PkgPath
-//go:noescape
-func rtype_PkgPath(*Type) string
-
-func (t *Type) PkgPath() string {
- return rtype_PkgPath(t)
-}
-
-//go:linkname rtype_Size reflect.(*rtype).Size
-//go:noescape
-func rtype_Size(*Type) uintptr
-
-func (t *Type) Size() uintptr {
- return rtype_Size(t)
-}
-
-//go:linkname rtype_String reflect.(*rtype).String
-//go:noescape
-func rtype_String(*Type) string
-
-func (t *Type) String() string {
- return rtype_String(t)
-}
-
-//go:linkname rtype_Kind reflect.(*rtype).Kind
-//go:noescape
-func rtype_Kind(*Type) reflect.Kind
-
-func (t *Type) Kind() reflect.Kind {
- return rtype_Kind(t)
-}
-
-//go:linkname rtype_Implements reflect.(*rtype).Implements
-//go:noescape
-func rtype_Implements(*Type, reflect.Type) bool
-
-func (t *Type) Implements(u reflect.Type) bool {
- return rtype_Implements(t, u)
-}
-
-//go:linkname rtype_AssignableTo reflect.(*rtype).AssignableTo
-//go:noescape
-func rtype_AssignableTo(*Type, reflect.Type) bool
-
-func (t *Type) AssignableTo(u reflect.Type) bool {
- return rtype_AssignableTo(t, u)
-}
-
-//go:linkname rtype_ConvertibleTo reflect.(*rtype).ConvertibleTo
-//go:noescape
-func rtype_ConvertibleTo(*Type, reflect.Type) bool
-
-func (t *Type) ConvertibleTo(u reflect.Type) bool {
- return rtype_ConvertibleTo(t, u)
-}
-
-//go:linkname rtype_Comparable reflect.(*rtype).Comparable
-//go:noescape
-func rtype_Comparable(*Type) bool
-
-func (t *Type) Comparable() bool {
- return rtype_Comparable(t)
-}
-
-//go:linkname rtype_Bits reflect.(*rtype).Bits
-//go:noescape
-func rtype_Bits(*Type) int
-
-func (t *Type) Bits() int {
- return rtype_Bits(t)
-}
-
-//go:linkname rtype_ChanDir reflect.(*rtype).ChanDir
-//go:noescape
-func rtype_ChanDir(*Type) reflect.ChanDir
-
-func (t *Type) ChanDir() reflect.ChanDir {
- return rtype_ChanDir(t)
-}
-
-//go:linkname rtype_IsVariadic reflect.(*rtype).IsVariadic
-//go:noescape
-func rtype_IsVariadic(*Type) bool
-
-func (t *Type) IsVariadic() bool {
- return rtype_IsVariadic(t)
-}
-
-//go:linkname rtype_Elem reflect.(*rtype).Elem
-//go:noescape
-func rtype_Elem(*Type) reflect.Type
-
-func (t *Type) Elem() *Type {
- return Type2RType(rtype_Elem(t))
-}
-
-//go:linkname rtype_Field reflect.(*rtype).Field
-//go:noescape
-func rtype_Field(*Type, int) reflect.StructField
-
-func (t *Type) Field(i int) reflect.StructField {
- return rtype_Field(t, i)
-}
-
-//go:linkname rtype_FieldByIndex reflect.(*rtype).FieldByIndex
-//go:noescape
-func rtype_FieldByIndex(*Type, []int) reflect.StructField
-
-func (t *Type) FieldByIndex(index []int) reflect.StructField {
- return rtype_FieldByIndex(t, index)
-}
-
-//go:linkname rtype_FieldByName reflect.(*rtype).FieldByName
-//go:noescape
-func rtype_FieldByName(*Type, string) (reflect.StructField, bool)
-
-func (t *Type) FieldByName(name string) (reflect.StructField, bool) {
- return rtype_FieldByName(t, name)
-}
-
-//go:linkname rtype_FieldByNameFunc reflect.(*rtype).FieldByNameFunc
-//go:noescape
-func rtype_FieldByNameFunc(*Type, func(string) bool) (reflect.StructField, bool)
-
-func (t *Type) FieldByNameFunc(match func(string) bool) (reflect.StructField, bool) {
- return rtype_FieldByNameFunc(t, match)
-}
-
-//go:linkname rtype_In reflect.(*rtype).In
-//go:noescape
-func rtype_In(*Type, int) reflect.Type
-
-func (t *Type) In(i int) reflect.Type {
- return rtype_In(t, i)
-}
-
-//go:linkname rtype_Key reflect.(*rtype).Key
-//go:noescape
-func rtype_Key(*Type) reflect.Type
-
-func (t *Type) Key() *Type {
- return Type2RType(rtype_Key(t))
-}
-
-//go:linkname rtype_Len reflect.(*rtype).Len
-//go:noescape
-func rtype_Len(*Type) int
-
-func (t *Type) Len() int {
- return rtype_Len(t)
-}
-
-//go:linkname rtype_NumField reflect.(*rtype).NumField
-//go:noescape
-func rtype_NumField(*Type) int
-
-func (t *Type) NumField() int {
- return rtype_NumField(t)
-}
-
-//go:linkname rtype_NumIn reflect.(*rtype).NumIn
-//go:noescape
-func rtype_NumIn(*Type) int
-
-func (t *Type) NumIn() int {
- return rtype_NumIn(t)
-}
-
-//go:linkname rtype_NumOut reflect.(*rtype).NumOut
-//go:noescape
-func rtype_NumOut(*Type) int
-
-func (t *Type) NumOut() int {
- return rtype_NumOut(t)
-}
-
-//go:linkname rtype_Out reflect.(*rtype).Out
-//go:noescape
-func rtype_Out(*Type, int) reflect.Type
-
-//go:linkname PtrTo reflect.(*rtype).ptrTo
-//go:noescape
-func PtrTo(*Type) *Type
-
-func (t *Type) Out(i int) reflect.Type {
- return rtype_Out(t, i)
-}
-
-//go:linkname IfaceIndir reflect.ifaceIndir
-//go:noescape
-func IfaceIndir(*Type) bool
-
-//go:linkname RType2Type reflect.toType
-//go:noescape
-func RType2Type(t *Type) reflect.Type
-
type emptyInterface struct {
- _ *Type
+ typ unsafe.Pointer
ptr unsafe.Pointer
}
-func Type2RType(t reflect.Type) *Type {
- return (*Type)(((*emptyInterface)(unsafe.Pointer(&t))).ptr)
+// TypePtr returns the pointer to the type descriptor of the type.
+// It is the type word of an interface value which holds a value of the type,
+// and it is what the functions of the runtime package take as a type.
+func TypePtr(t reflect.Type) unsafe.Pointer {
+ return (*emptyInterface)(unsafe.Pointer(&t)).ptr
+}
+
+// TypeOfPtr converts the pointer to the type descriptor to reflect.Type.
+// reflect.TypeOf reads only the type word of the interface value, so the data word is left nil.
+func TypeOfPtr(typ unsafe.Pointer) reflect.Type {
+ return reflect.TypeOf(*(*any)(unsafe.Pointer(&emptyInterface{typ: typ})))
+}
+
+// IfaceIndir reports whether a value of the type is stored indirectly in an interface value:
+// the data word of the interface points to a copy of the value, instead of being the value itself.
+//
+// Which types are stored directly is decided by the compiler and the rule depends on the Go version
+// ( e.g. a struct of a zero-sized field and a pointer is direct since Go 1.26 ), so the rule is not
+// reimplemented here. Instead, a value whose first word is a known pointer is converted to an interface
+// value, and the data word tells how it was stored.
+func IfaceIndir(typ reflect.Type) bool {
+ if typ.Size() != unsafe.Sizeof(unsafe.Pointer(nil)) {
+ // only a pointer-sized value fits in the data word.
+ return true
+ }
+ probe := unsafe.Pointer(new(uintptr))
+ v := reflect.New(typ)
+ *(*unsafe.Pointer)(v.UnsafePointer()) = probe
+ iface := v.Elem().Interface()
+ return (*emptyInterface)(unsafe.Pointer(&iface)).ptr != probe
}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/std_package.go b/vendor/github.com/goccy/go-json/internal/runtime/std_package.go
new file mode 100644
index 000000000..7bd782e29
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/std_package.go
@@ -0,0 +1,111 @@
+package runtime
+
+import (
+ "reflect"
+ goruntime "runtime"
+)
+
+// stdMarshalerPackages are the packages of the standard library which have types with marshalers or unmarshalers,
+// by their paths, which a package of another module can't have: the go command resolves the path of a package of
+// the standard library to it, and reports the import as ambiguous when a module has the same path, and GOPATH
+// mode finds the package of GOROOT first. A path is here only from the release of Go which has the package ( see
+// std_package_go127.go ): a program built with an earlier release may have a package of its own at that path.
+// The packages of encoding/json are not here: json.RawMessage and jsontext.Value hold the JSON of the user.
+var stdMarshalerPackages = map[string]bool{
+ "crypto/x509": true,
+ "log/slog": true,
+ "math/big": true,
+ "net": true,
+ "net/netip": true,
+ "regexp": true,
+ "time": true,
+}
+
+// IsStdMarshalerType is whether the type, or the type it points to, is a named type of a package of the standard
+// library whose marshalers are trusted: what MarshalJSON returns is valid and compact, AppendText appends what
+// MarshalText returns, and UnmarshalJSON and UnmarshalText keep nothing of the bytes they are given.
+func IsStdMarshalerType(typ reflect.Type) bool {
+ if typ.Kind() == reflect.Pointer && typ.Name() == "" {
+ typ = typ.Elem()
+ }
+ return typ.Name() != "" && stdMarshalerPackages[typ.PkgPath()]
+}
+
+// PromotedStdMethod reports whether the method of the type which the lookup finds, or the one of the type it points to,
+// is the method of a type of the standard library whose marshalers are trusted ( see IsStdMarshalerType ), which the
+// type has by embedding it and doesn't declare itself: a call of the method then runs the method of that type, on the
+// embedded value. It returns that type and, if the embedded value is in the value of the type ( embedded by value at
+// every depth ), its offset in it, and whether it is so ( inline ), and whether the method is such a method. A type
+// which declares the method, or which has it from more than one embedded type at one depth, is not such a type.
+func PromotedStdMethod(typ reflect.Type, method MethodLookup) (reflect.Type, uintptr, bool, bool) {
+ if typ.Kind() == reflect.Pointer && typ.Name() == "" {
+ typ = typ.Elem()
+ }
+ if typ.Kind() != reflect.Struct || !isPromotedMethod(typ, method) {
+ return nil, 0, false, false
+ }
+ var field reflect.StructField
+ found := false
+ for i := 0; i < typ.NumField(); i++ {
+ f := typ.Field(i)
+ if f.Anonymous && hasMethod(f.Type, method) {
+ if found {
+ // the depth of the method is not looked for: it is not trusted.
+ return nil, 0, false, false
+ }
+ field, found = f, true
+ }
+ }
+ if !found {
+ return nil, 0, false, false
+ }
+ if IsStdMarshalerType(field.Type) {
+ return field.Type, field.Offset, field.Type.Kind() != reflect.Pointer, true
+ }
+ origin, offset, inline, ok := PromotedStdMethod(field.Type, method)
+ return origin, field.Offset + offset, inline && field.Type.Kind() != reflect.Pointer, ok
+}
+
+// hasMethod is whether the type, or the pointer to it, has the method.
+func hasMethod(typ reflect.Type, method MethodLookup) bool {
+ if typ.Kind() != reflect.Pointer {
+ typ = reflect.PointerTo(typ)
+ }
+ _, ok := method(typ)
+ return ok
+}
+
+// isPromotedMethod is whether the method of the struct type which the lookup finds is promoted from an embedded field:
+// the method of the type and the one of the pointer to it, those which it has, are the wrappers which the compiler
+// makes for a promoted method. A declared method is not a wrapper, although the method of the pointer to the type of a
+// method declared on the value is.
+func isPromotedMethod(typ reflect.Type, method MethodLookup) bool {
+ has := false
+ for _, holder := range []reflect.Type{typ, reflect.PointerTo(typ)} {
+ m, ok := method(holder)
+ if !ok {
+ continue
+ }
+ if !isGeneratedCode(m.Func.Pointer()) {
+ return false
+ }
+ has = true
+ }
+ return has
+}
+
+// generatedFile is the file of the code which the compiler makes, as runtime.Func.FileLine reports it.
+const generatedFile = ""
+
+// isGeneratedCode is whether the code is made by the compiler, as the wrapper of a promoted method is: the runtime
+// has no other way to tell it than the file of the code, which the compiler names generatedFile ( this is the
+// text of the runtime, not one of this package ). A code in any other file, or of no function, is not: its method
+// is then called and its output checked.
+func isGeneratedCode(pc uintptr) bool {
+ f := goruntime.FuncForPC(pc)
+ if f == nil {
+ return false
+ }
+ file, _ := f.FileLine(pc)
+ return file == generatedFile
+}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/std_package_go127.go b/vendor/github.com/goccy/go-json/internal/runtime/std_package_go127.go
new file mode 100644
index 000000000..4bd1abae1
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/std_package_go127.go
@@ -0,0 +1,8 @@
+//go:build go1.27
+
+package runtime
+
+func init() {
+ // uuid is of Go 1.27.
+ stdMarshalerPackages["uuid"] = true
+}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/struct_field.go b/vendor/github.com/goccy/go-json/internal/runtime/struct_field.go
index baab0c597..d0fb9f2c4 100644
--- a/vendor/github.com/goccy/go-json/internal/runtime/struct_field.go
+++ b/vendor/github.com/goccy/go-json/internal/runtime/struct_field.go
@@ -33,8 +33,11 @@ type StructTag struct {
Key string
IsTaggedKey bool
IsOmitEmpty bool
- IsString bool
- Field reflect.StructField
+ // IsOmitZero is whether the field has the omitzero option, which encoding/json has from Go 1.24: it is
+ // false with an older Go, whose encoding/json ignores the option.
+ IsOmitZero bool
+ IsString bool
+ Field reflect.StructField
}
type StructTags []*StructTag
@@ -82,6 +85,8 @@ func StructTagFromField(field reflect.StructField) *StructTag {
switch opt {
case "omitempty":
st.IsOmitEmpty = true
+ case "omitzero":
+ st.IsOmitZero = omitZeroOption
case "string":
st.IsString = true
}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/type.go b/vendor/github.com/goccy/go-json/internal/runtime/type.go
index 4b693cb0b..c3badcddc 100644
--- a/vendor/github.com/goccy/go-json/internal/runtime/type.go
+++ b/vendor/github.com/goccy/go-json/internal/runtime/type.go
@@ -1,8 +1,6 @@
package runtime
import (
- "reflect"
- "sync"
"unsafe"
)
@@ -11,88 +9,3 @@ type SliceHeader struct {
Len int
Cap int
}
-
-const (
- maxAcceptableTypeAddrRange = 1024 * 1024 * 2 // 2 Mib
-)
-
-type TypeAddr struct {
- BaseTypeAddr uintptr
- MaxTypeAddr uintptr
- AddrRange uintptr
- AddrShift uintptr
-}
-
-var (
- typeAddr *TypeAddr
- once sync.Once
-)
-
-//go:linkname typelinks reflect.typelinks
-func typelinks() ([]unsafe.Pointer, [][]int32)
-
-//go:linkname rtypeOff reflect.rtypeOff
-func rtypeOff(unsafe.Pointer, int32) unsafe.Pointer
-
-func AnalyzeTypeAddr() *TypeAddr {
- once.Do(func() {
- sections, offsets := typelinks()
- if len(sections) != 1 {
- return
- }
- if len(offsets) != 1 {
- return
- }
- section := sections[0]
- offset := offsets[0]
- var (
- min uintptr = uintptr(^uint(0))
- max uintptr = 0
- isAligned64 = true
- isAligned32 = true
- )
- for i := 0; i < len(offset); i++ {
- typ := (*Type)(rtypeOff(section, offset[i]))
- addr := uintptr(unsafe.Pointer(typ))
- if min > addr {
- min = addr
- }
- if max < addr {
- max = addr
- }
- if typ.Kind() == reflect.Ptr {
- addr = uintptr(unsafe.Pointer(typ.Elem()))
- if min > addr {
- min = addr
- }
- if max < addr {
- max = addr
- }
- }
- isAligned64 = isAligned64 && (addr-min)&63 == 0
- isAligned32 = isAligned32 && (addr-min)&31 == 0
- }
- addrRange := max - min
- if addrRange == 0 {
- return
- }
- var addrShift uintptr
- if isAligned64 {
- addrShift = 6
- } else if isAligned32 {
- addrShift = 5
- }
- cacheSize := addrRange >> addrShift
- if cacheSize > maxAcceptableTypeAddrRange {
- return
- }
- typeAddr = &TypeAddr{
- BaseTypeAddr: min,
- MaxTypeAddr: max,
- AddrRange: addrRange,
- AddrShift: addrShift,
- }
- })
-
- return typeAddr
-}
diff --git a/vendor/github.com/goccy/go-json/internal/runtime/type_cache.go b/vendor/github.com/goccy/go-json/internal/runtime/type_cache.go
new file mode 100644
index 000000000..9f3934a55
--- /dev/null
+++ b/vendor/github.com/goccy/go-json/internal/runtime/type_cache.go
@@ -0,0 +1,125 @@
+package runtime
+
+import (
+ "sync"
+ "sync/atomic"
+ "unsafe"
+)
+
+// TypeCache is a table of the values for the types, which is looked up by the address of a type
+// without a lock.
+//
+// It is a hash table with open addressing. It used to be an array which had a slot for every address a type of
+// the program can be at, which was found from the type links of the runtime: that needed a linkname, a scan of
+// every type at the start, memory in proportion to the size of the program, and a fallback for the types which
+// are not in the type links. A lookup of this table costs about the same, and it has none of them.
+//
+// The zero value is ready to use.
+type TypeCache[T any] struct {
+ table atomic.Pointer[typeTable[T]]
+ // mu is for the writers. A value is stored only when a type is compiled.
+ mu sync.Mutex
+}
+
+type typeTable[T any] struct {
+ entries []typeEntry[T]
+ // shift makes an index of entries from the hash.
+ shift uint
+ // count is the number of the entries in use. It is guarded by TypeCache.mu.
+ count int
+}
+
+// typeEntry is written once: the value, and then the type, which makes it visible.
+type typeEntry[T any] struct {
+ typ atomic.Uintptr
+ value atomic.Pointer[T]
+}
+
+const (
+ minTypeTableBits = 6
+)
+
+// TypeHashMultiplier is the multiplier of the Fibonacci hashing of the address of a type: the top bits of the
+// product spread the addresses, which are aligned and close to each other, over a table.
+const TypeHashMultiplier = 0x9E3779B97F4A7C15
+
+func newTypeTable[T any](bits uint) *typeTable[T] {
+ return &typeTable[T]{
+ entries: make([]typeEntry[T], 1<> t.shift)
+}
+
+// entry returns the entry of the index, which is always less than the length:
+// the check of the bounds is not worth its cost on this path, which every Marshal and Unmarshal takes.
+func (t *typeTable[T]) entry(index uintptr) *typeEntry[T] {
+ return (*typeEntry[T])(unsafe.Add(unsafe.Pointer(unsafe.SliceData(t.entries)), index*unsafe.Sizeof(typeEntry[T]{})))
+}
+
+// Load returns the value for the type, or nil.
+func (c *TypeCache[T]) Load(typ uintptr) *T {
+ t := c.table.Load()
+ if t == nil {
+ return nil
+ }
+ mask := uintptr(len(t.entries) - 1)
+ for i := t.index(typ); ; i = (i + 1) & mask {
+ e := t.entry(i)
+ switch e.typ.Load() {
+ case typ:
+ return e.value.Load()
+ case 0:
+ return nil
+ }
+ }
+}
+
+// Store sets the value for the type, and returns the value which the table has for the type:
+// it is the value which was stored first if the type was compiled by more than one goroutine at a time.
+func (c *TypeCache[T]) Store(typ uintptr, v *T) *T {
+ c.mu.Lock()
+ defer c.mu.Unlock()
+
+ t := c.table.Load()
+ if t == nil {
+ t = newTypeTable[T](minTypeTableBits)
+ c.table.Store(t)
+ }
+ if existing := c.Load(typ); existing != nil {
+ return existing
+ }
+ // the table is at most half full, so a lookup ends after a few entries.
+ if (t.count+1)*2 > len(t.entries) {
+ grown := newTypeTable[T](64 - t.shift + 1)
+ for i := range t.entries {
+ e := &t.entries[i]
+ if typ := e.typ.Load(); typ != 0 {
+ grown.insert(typ, e.value.Load())
+ }
+ }
+ grown.insert(typ, v)
+ // the table gets visible after it has every value.
+ c.table.Store(grown)
+ return v
+ }
+ t.insert(typ, v)
+ return v
+}
+
+func (t *typeTable[T]) insert(typ uintptr, v *T) {
+ mask := uintptr(len(t.entries) - 1)
+ for i := t.index(typ); ; i = (i + 1) & mask {
+ e := t.entry(i)
+ if e.typ.Load() == 0 {
+ // the value is set before the entry gets visible by the type.
+ e.value.Store(v)
+ e.typ.Store(typ)
+ t.count++
+ return
+ }
+ }
+}
diff --git a/vendor/github.com/goccy/go-json/json.go b/vendor/github.com/goccy/go-json/json.go
index fb18065a2..0f3e22c6a 100644
--- a/vendor/github.com/goccy/go-json/json.go
+++ b/vendor/github.com/goccy/go-json/json.go
@@ -5,6 +5,7 @@ import (
"context"
"encoding/json"
+ "github.com/goccy/go-json/internal/decoder"
"github.com/goccy/go-json/internal/encoder"
)
@@ -166,34 +167,38 @@ type UnmarshalerContext interface {
// JSON cannot represent cyclic data structures and Marshal does not
// handle them. Passing cyclic structures to Marshal will result in
// an infinite recursion.
-func Marshal(v interface{}) ([]byte, error) {
+func Marshal(v any) ([]byte, error) {
return MarshalWithOption(v)
}
-// MarshalNoEscape returns the JSON encoding of v and doesn't escape v.
-func MarshalNoEscape(v interface{}) ([]byte, error) {
- return marshalNoEscape(v)
+// MarshalNoEscape returns the JSON encoding of v.
+//
+// Deprecated: Use Marshal. MarshalNoEscape used to keep v from escaping to the heap, but the encoder refers to v
+// by its address, which is not updated when the stack of the goroutine is copied while v is being encoded.
+// A value left on the stack was then read from the freed stack, so MarshalNoEscape is now the same as Marshal.
+func MarshalNoEscape(v any) ([]byte, error) {
+ return marshal(v)
}
// MarshalContext returns the JSON encoding of v with context.Context and EncodeOption.
-func MarshalContext(ctx context.Context, v interface{}, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func MarshalContext(ctx context.Context, v any, optFuncs ...EncodeOptionFunc) ([]byte, error) {
return marshalContext(ctx, v, optFuncs...)
}
// MarshalWithOption returns the JSON encoding of v with EncodeOption.
-func MarshalWithOption(v interface{}, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func MarshalWithOption(v any, optFuncs ...EncodeOptionFunc) ([]byte, error) {
return marshal(v, optFuncs...)
}
// MarshalIndent is like Marshal but applies Indent to format the output.
// Each JSON element in the output will begin on a new line beginning with prefix
// followed by one or more copies of indent according to the indentation nesting.
-func MarshalIndent(v interface{}, prefix, indent string) ([]byte, error) {
+func MarshalIndent(v any, prefix, indent string) ([]byte, error) {
return MarshalIndentWithOption(v, prefix, indent)
}
// MarshalIndentWithOption is like Marshal but applies Indent to format the output with EncodeOption.
-func MarshalIndentWithOption(v interface{}, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error) {
+func MarshalIndentWithOption(v any, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error) {
return marshalIndent(v, prefix, indent, optFuncs...)
}
@@ -270,23 +275,29 @@ func MarshalIndentWithOption(v interface{}, prefix, indent string, optFuncs ...E
// invalid UTF-16 surrogate pairs are not treated as an error.
// Instead, they are replaced by the Unicode replacement
// character U+FFFD.
-func Unmarshal(data []byte, v interface{}) error {
+func Unmarshal(data []byte, v any) error {
return unmarshal(data, v)
}
// UnmarshalContext parses the JSON-encoded data and stores the result
// in the value pointed to by v. If you implement the UnmarshalerContext interface,
// call it with ctx as an argument.
-func UnmarshalContext(ctx context.Context, data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
- return unmarshalContext(ctx, data, v)
+func UnmarshalContext(ctx context.Context, data []byte, v any, optFuncs ...DecodeOptionFunc) error {
+ return unmarshalContext(ctx, data, v, optFuncs...)
}
-func UnmarshalWithOption(data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
+func UnmarshalWithOption(data []byte, v any, optFuncs ...DecodeOptionFunc) error {
return unmarshal(data, v, optFuncs...)
}
-func UnmarshalNoEscape(data []byte, v interface{}, optFuncs ...DecodeOptionFunc) error {
- return unmarshalNoEscape(data, v, optFuncs...)
+// UnmarshalNoEscape parses the JSON-encoded data and stores the result in the value pointed to by v.
+//
+// Deprecated: Use UnmarshalOf, which lets the value stay on the stack of the caller. UnmarshalNoEscape used to
+// keep v from escaping to the heap, but the decoder refers to v by its address, which is not updated when the
+// stack of the goroutine is copied while v is being decoded, so UnmarshalNoEscape is now the same as
+// UnmarshalWithOption.
+func UnmarshalNoEscape(data []byte, v any, optFuncs ...DecodeOptionFunc) error {
+ return unmarshal(data, v, optFuncs...)
}
// A Token holds a value of one of these types:
@@ -338,7 +349,7 @@ func Indent(dst *bytes.Buffer, src []byte, prefix, indent string) error {
// escaping within